voice-ai-workbench 0.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- voice_ai_workbench-0.2.0/LICENSE +202 -0
- voice_ai_workbench-0.2.0/MANIFEST.in +4 -0
- voice_ai_workbench-0.2.0/NOTICE +7 -0
- voice_ai_workbench-0.2.0/PKG-INFO +199 -0
- voice_ai_workbench-0.2.0/README.md +147 -0
- voice_ai_workbench-0.2.0/presets/cosmos-reason.yaml +67 -0
- voice_ai_workbench-0.2.0/presets/nvidia-open-models-realtime-speech-jetson.yaml +61 -0
- voice_ai_workbench-0.2.0/presets/nvidia-open-models-speech-jetson.yaml +59 -0
- voice_ai_workbench-0.2.0/presets/openai-realtime.yaml +47 -0
- voice_ai_workbench-0.2.0/presets/speaches-jetson.yaml +58 -0
- voice_ai_workbench-0.2.0/presets/speaches-realtime-asr-jetson.yaml +59 -0
- voice_ai_workbench-0.2.0/presets/tensorrt-edge-cosmos.yaml +68 -0
- voice_ai_workbench-0.2.0/presets/text-only.yaml +39 -0
- voice_ai_workbench-0.2.0/presets/voice-only.yaml +53 -0
- voice_ai_workbench-0.2.0/pyproject.toml +104 -0
- voice_ai_workbench-0.2.0/setup.cfg +4 -0
- voice_ai_workbench-0.2.0/setup.py +19 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/__init__.py +48 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/__main__.py +12 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/__init__.py +29 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/asr/__init__.py +13 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/asr/diagnostics.py +89 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/asr/energy_vad.py +127 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/asr/language.py +15 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/asr/openai_realtime.py +257 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/asr/openai_rest.py +498 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/asr/riva.py +406 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/base.py +423 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/llm/__init__.py +7 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/llm/openai.py +702 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/realtime/__init__.py +17 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/realtime/client.py +504 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/tts/__init__.py +9 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/tts/openai_realtime.py +136 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/tts/openai_rest.py +247 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/tts/riva.py +458 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/vision/__init__.py +9 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/vision/frame_broker.py +230 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/vision/frame_capture.py +311 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/backends/vision/local_video_feeder.py +102 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/cli/__init__.py +3 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/cli/main.py +263 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/config/__init__.py +21 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/config/presets.py +42 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/config/schema.py +687 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/core/__init__.py +16 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/core/session.py +504 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/core/timeline.py +521 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/devices/__init__.py +15 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/devices/capture.py +518 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/devices/local.py +286 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/devices/playback.py +142 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/server/__init__.py +3 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/utils/__init__.py +3 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/camera_webrtc.py +331 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/server.py +1727 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/speech_models.py +83 -0
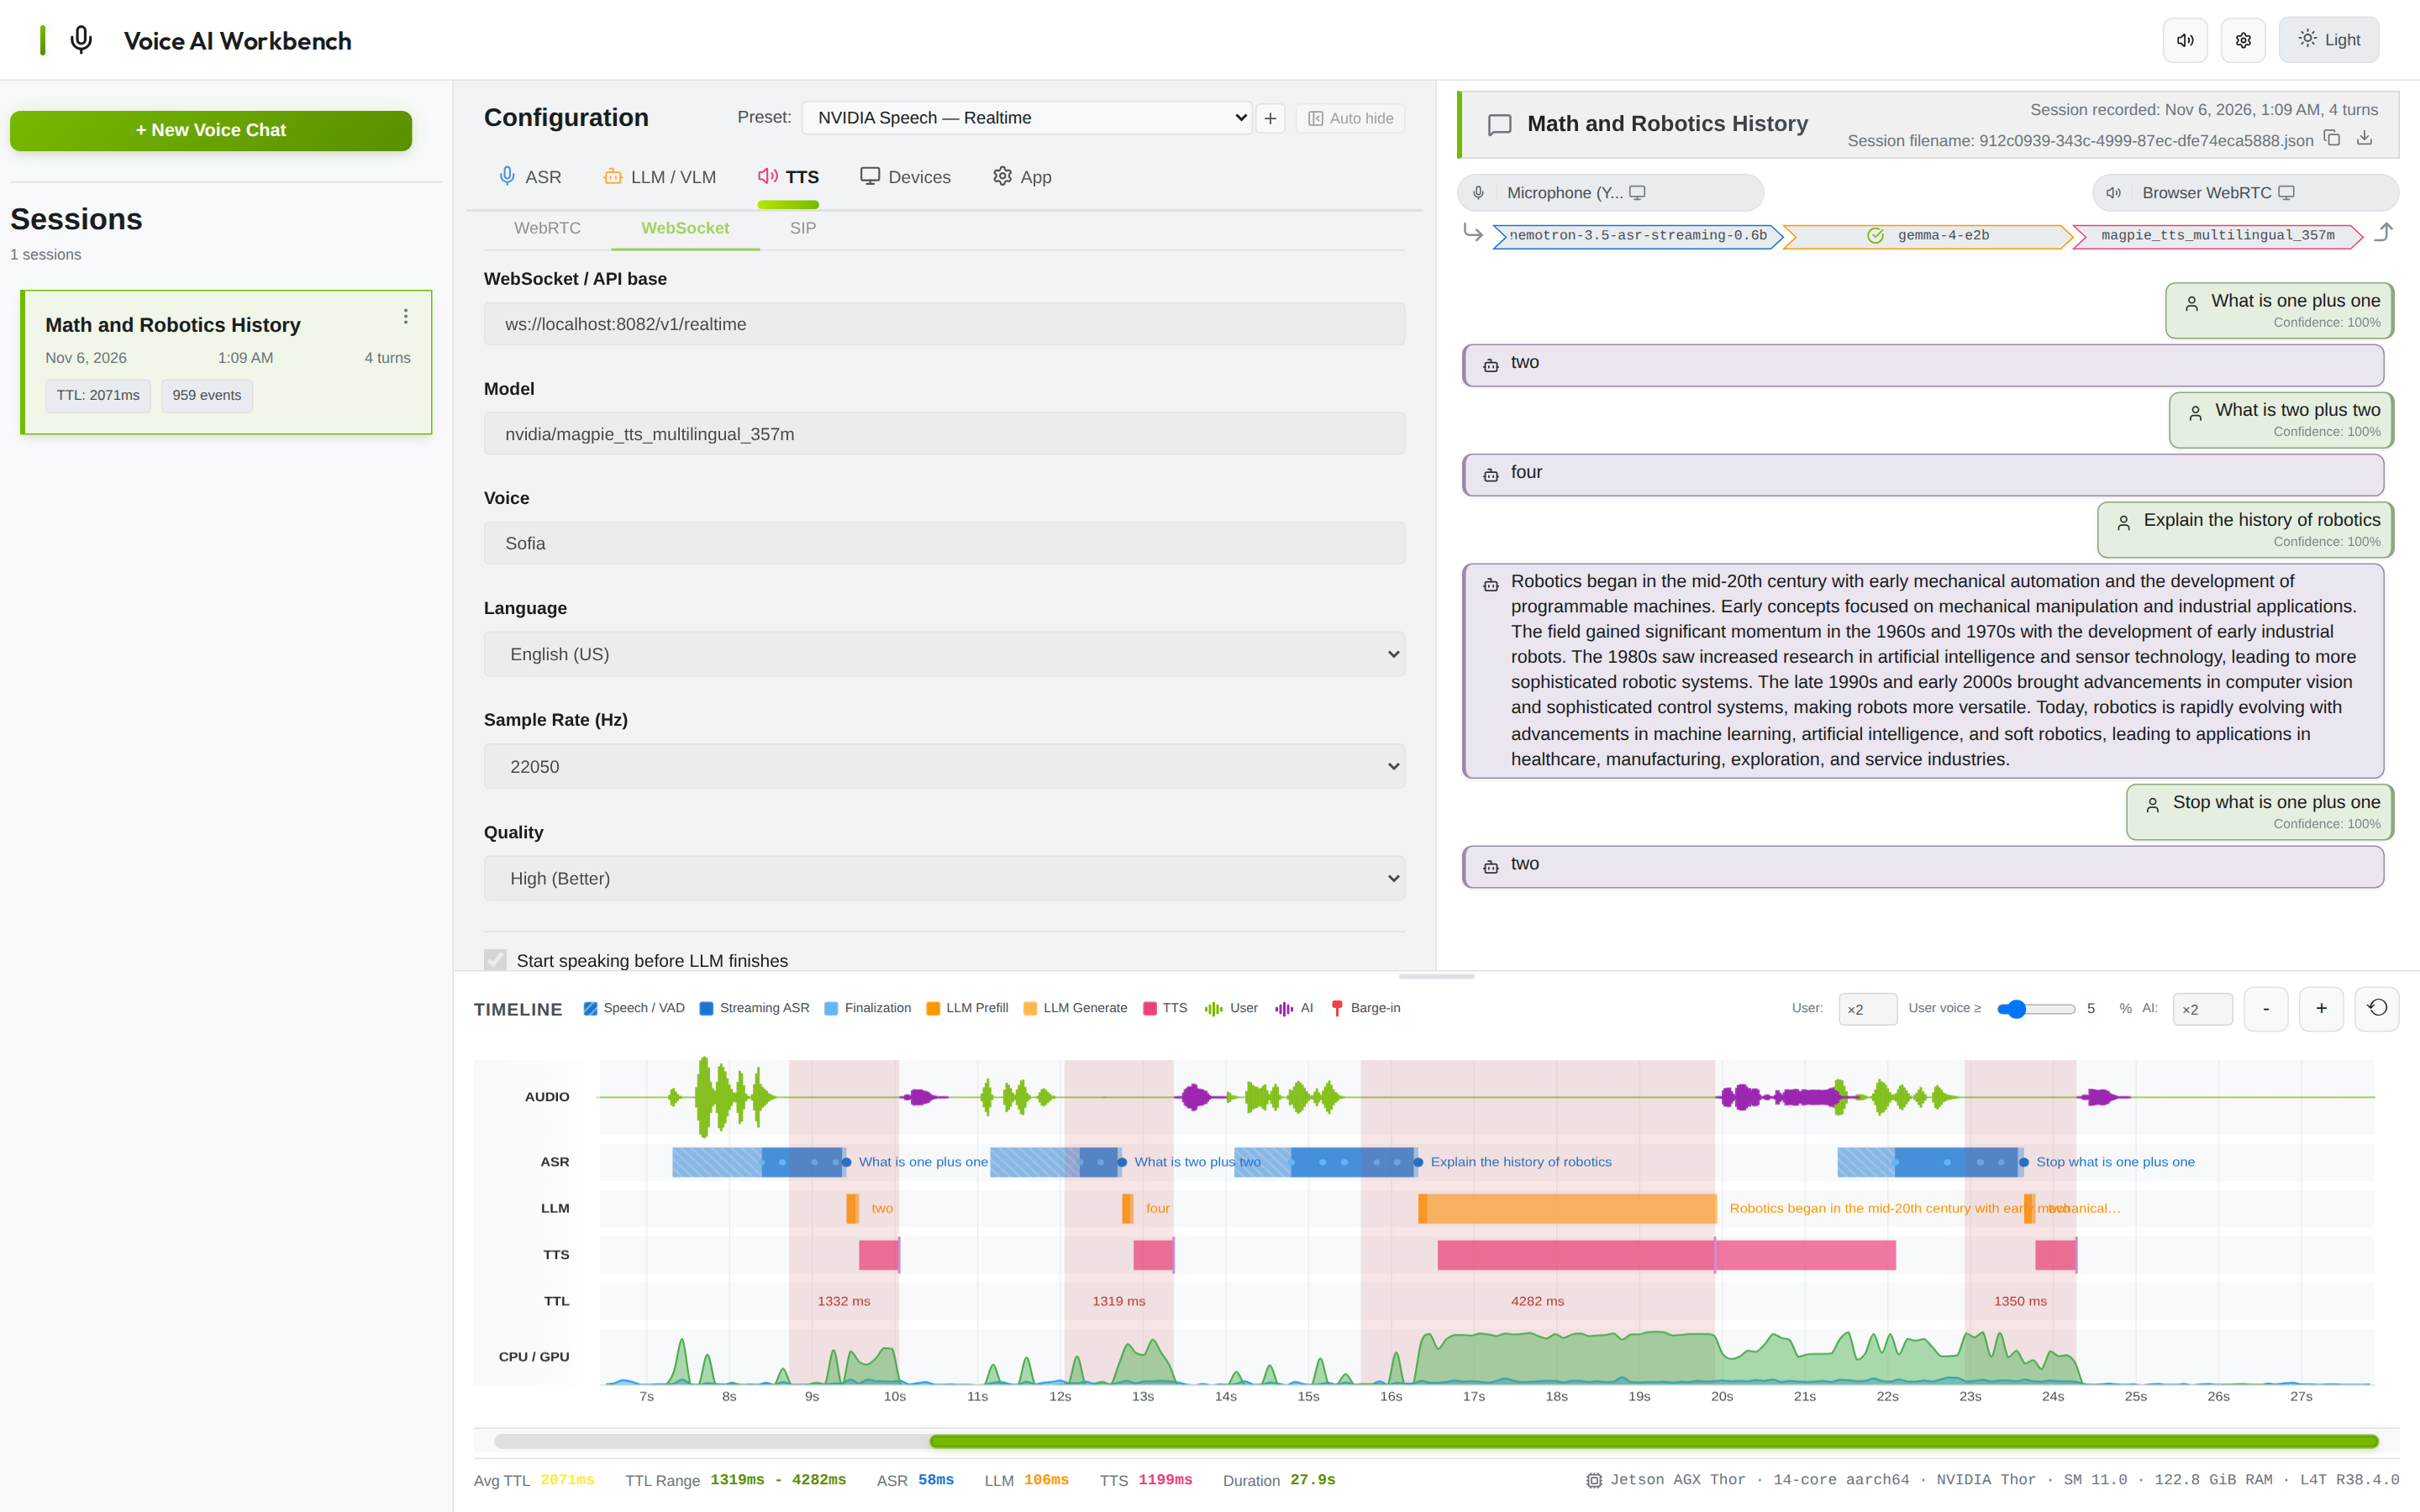
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/static/app.js +10016 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/static/config_helpers.js +231 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/static/index.html +516 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/static/nvidia-theme.css +1273 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/static/styles.css +4394 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/static/timeline_helpers.js +723 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/system_stats.py +320 -0
- voice_ai_workbench-0.2.0/src/multi_modal_ai_studio/webui/voice_pipeline.py +3704 -0
- voice_ai_workbench-0.2.0/src/voice_ai_workbench.egg-info/PKG-INFO +199 -0
- voice_ai_workbench-0.2.0/src/voice_ai_workbench.egg-info/SOURCES.txt +69 -0
- voice_ai_workbench-0.2.0/src/voice_ai_workbench.egg-info/dependency_links.txt +1 -0
- voice_ai_workbench-0.2.0/src/voice_ai_workbench.egg-info/entry_points.txt +3 -0
- voice_ai_workbench-0.2.0/src/voice_ai_workbench.egg-info/requires.txt +34 -0
- voice_ai_workbench-0.2.0/src/voice_ai_workbench.egg-info/top_level.txt +1 -0
|
@@ -0,0 +1,202 @@
|
|
|
1
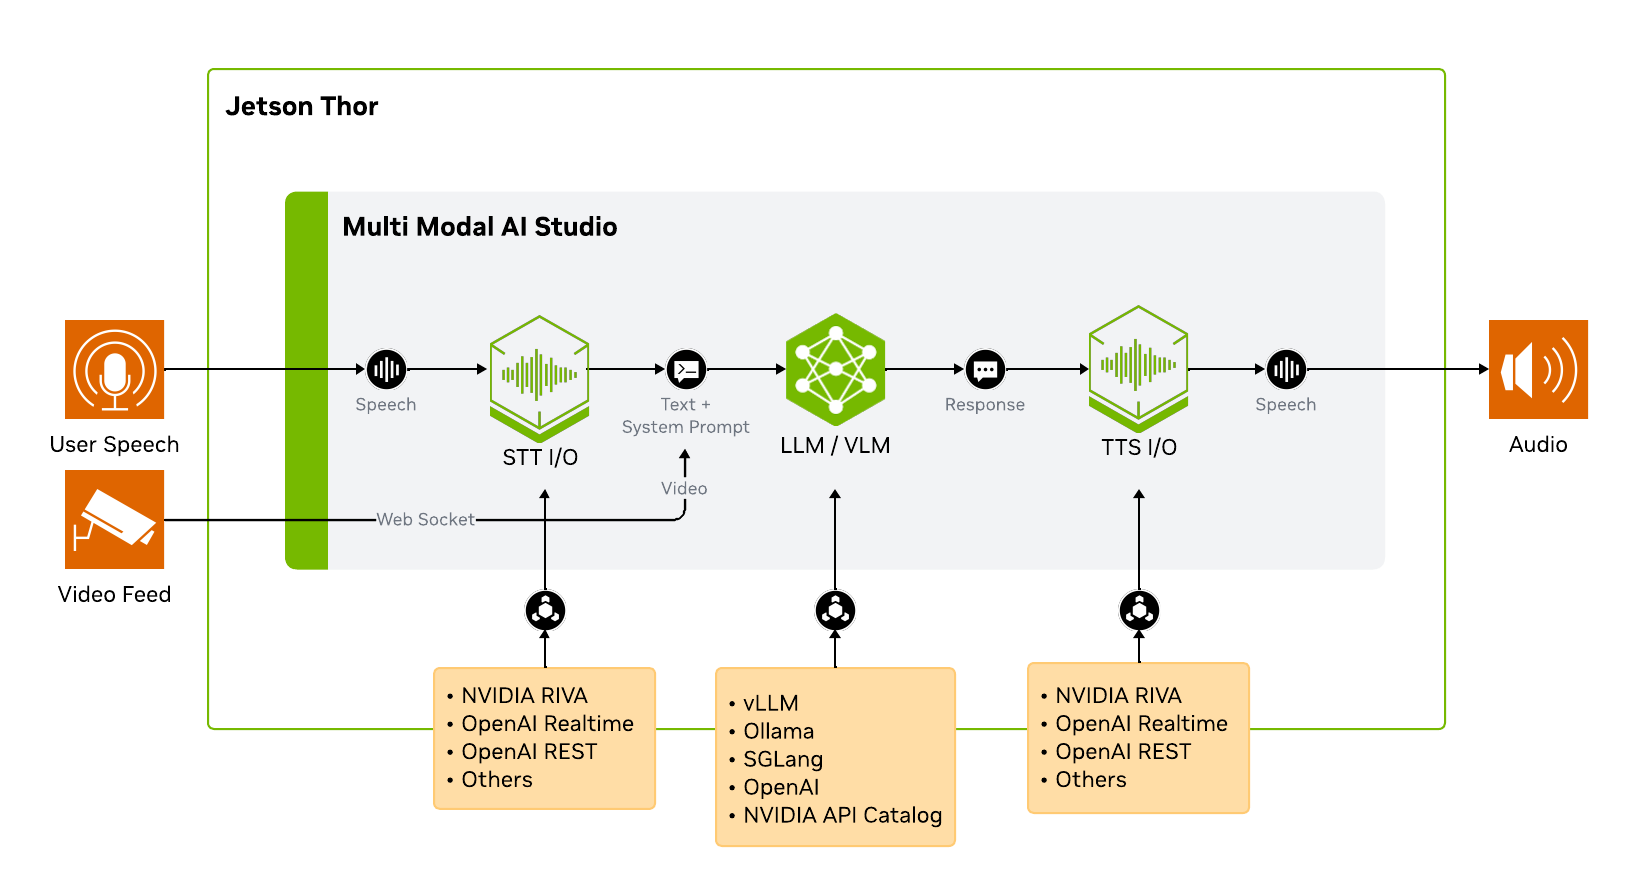
|
+
|
|
2
|
+
Apache License
|
|
3
|
+
Version 2.0, January 2004
|
|
4
|
+
http://www.apache.org/licenses/
|
|
5
|
+
|
|
6
|
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
|
7
|
+
|
|
8
|
+
1. Definitions.
|
|
9
|
+
|
|
10
|
+
"License" shall mean the terms and conditions for use, reproduction,
|
|
11
|
+
and distribution as defined by Sections 1 through 9 of this document.
|
|
12
|
+
|
|
13
|
+
"Licensor" shall mean the copyright owner or entity authorized by
|
|
14
|
+
the copyright owner that is granting the License.
|
|
15
|
+
|
|
16
|
+
"Legal Entity" shall mean the union of the acting entity and all
|
|
17
|
+
other entities that control, are controlled by, or are under common
|
|
18
|
+
control with that entity. For the purposes of this definition,
|
|
19
|
+
"control" means (i) the power, direct or indirect, to cause the
|
|
20
|
+
direction or management of such entity, whether by contract or
|
|
21
|
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
|
22
|
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
|
23
|
+
|
|
24
|
+
"You" (or "Your") shall mean an individual or Legal Entity
|
|
25
|
+
exercising permissions granted by this License.
|
|
26
|
+
|
|
27
|
+
"Source" form shall mean the preferred form for making modifications,
|
|
28
|
+
including but not limited to software source code, documentation
|
|
29
|
+
source, and configuration files.
|
|
30
|
+
|
|
31
|
+
"Object" form shall mean any form resulting from mechanical
|
|
32
|
+
transformation or translation of a Source form, including but
|
|
33
|
+
not limited to compiled object code, generated documentation,
|
|
34
|
+
and conversions to other media types.
|
|
35
|
+
|
|
36
|
+
"Work" shall mean the work of authorship, whether in Source or
|
|
37
|
+
Object form, made available under the License, as indicated by a
|
|
38
|
+
copyright notice that is included in or attached to the work
|
|
39
|
+
(an example is provided in the Appendix below).
|
|
40
|
+
|
|
41
|
+
"Derivative Works" shall mean any work, whether in Source or Object
|
|
42
|
+
form, that is based on (or derived from) the Work and for which the
|
|
43
|
+
editorial revisions, annotations, elaborations, or other modifications
|
|
44
|
+
represent, as a whole, an original work of authorship. For the purposes
|
|
45
|
+
of this License, Derivative Works shall not include works that remain
|
|
46
|
+
separable from, or merely link (or bind by name) to the interfaces of,
|
|
47
|
+
the Work and Derivative Works thereof.
|
|
48
|
+
|
|
49
|
+
"Contribution" shall mean any work of authorship, including
|
|
50
|
+
the original version of the Work and any modifications or additions
|
|
51
|
+
to that Work or Derivative Works thereof, that is intentionally
|
|
52
|
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
|
53
|
+
or by an individual or Legal Entity authorized to submit on behalf of
|
|
54
|
+
the copyright owner. For the purposes of this definition, "submitted"
|
|
55
|
+
means any form of electronic, verbal, or written communication sent
|
|
56
|
+
to the Licensor or its representatives, including but not limited to
|
|
57
|
+
communication on electronic mailing lists, source code control systems,
|
|
58
|
+
and issue tracking systems that are managed by, or on behalf of, the
|
|
59
|
+
Licensor for the purpose of discussing and improving the Work, but
|
|
60
|
+
excluding communication that is conspicuously marked or otherwise
|
|
61
|
+
designated in writing by the copyright owner as "Not a Contribution."
|
|
62
|
+
|
|
63
|
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
|
64
|
+
on behalf of whom a Contribution has been received by Licensor and
|
|
65
|
+
subsequently incorporated within the Work.
|
|
66
|
+
|
|
67
|
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
|
68
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
69
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
70
|
+
copyright license to reproduce, prepare Derivative Works of,
|
|
71
|
+
publicly display, publicly perform, sublicense, and distribute the
|
|
72
|
+
Work and such Derivative Works in Source or Object form.
|
|
73
|
+
|
|
74
|
+
3. Grant of Patent License. Subject to the terms and conditions of
|
|
75
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
76
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
77
|
+
(except as stated in this section) patent license to make, have made,
|
|
78
|
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
|
79
|
+
where such license applies only to those patent claims licensable
|
|
80
|
+
by such Contributor that are necessarily infringed by their
|
|
81
|
+
Contribution(s) alone or by combination of their Contribution(s)
|
|
82
|
+
with the Work to which such Contribution(s) was submitted. If You
|
|
83
|
+
institute patent litigation against any entity (including a
|
|
84
|
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
|
85
|
+
or a Contribution incorporated within the Work constitutes direct
|
|
86
|
+
or contributory patent infringement, then any patent licenses
|
|
87
|
+
granted to You under this License for that Work shall terminate
|
|
88
|
+
as of the date such litigation is filed.
|
|
89
|
+
|
|
90
|
+
4. Redistribution. You may reproduce and distribute copies of the
|
|
91
|
+
Work or Derivative Works thereof in any medium, with or without
|
|
92
|
+
modifications, and in Source or Object form, provided that You
|
|
93
|
+
meet the following conditions:
|
|
94
|
+
|
|
95
|
+
(a) You must give any other recipients of the Work or
|
|
96
|
+
Derivative Works a copy of this License; and
|
|
97
|
+
|
|
98
|
+
(b) You must cause any modified files to carry prominent notices
|
|
99
|
+
stating that You changed the files; and
|
|
100
|
+
|
|
101
|
+
(c) You must retain, in the Source form of any Derivative Works
|
|
102
|
+
that You distribute, all copyright, patent, trademark, and
|
|
103
|
+
attribution notices from the Source form of the Work,
|
|
104
|
+
excluding those notices that do not pertain to any part of
|
|
105
|
+
the Derivative Works; and
|
|
106
|
+
|
|
107
|
+
(d) If the Work includes a "NOTICE" text file as part of its
|
|
108
|
+
distribution, then any Derivative Works that You distribute must
|
|
109
|
+
include a readable copy of the attribution notices contained
|
|
110
|
+
within such NOTICE file, excluding those notices that do not
|
|
111
|
+
pertain to any part of the Derivative Works, in at least one
|
|
112
|
+
of the following places: within a NOTICE text file distributed
|
|
113
|
+
as part of the Derivative Works; within the Source form or
|
|
114
|
+
documentation, if provided along with the Derivative Works; or,
|
|
115
|
+
within a display generated by the Derivative Works, if and
|
|
116
|
+
wherever such third-party notices normally appear. The contents
|
|
117
|
+
of the NOTICE file are for informational purposes only and
|
|
118
|
+
do not modify the License. You may add Your own attribution
|
|
119
|
+
notices within Derivative Works that You distribute, alongside
|
|
120
|
+
or as an addendum to the NOTICE text from the Work, provided
|
|
121
|
+
that such additional attribution notices cannot be construed
|
|
122
|
+
as modifying the License.
|
|
123
|
+
|
|
124
|
+
You may add Your own copyright statement to Your modifications and
|
|
125
|
+
may provide additional or different license terms and conditions
|
|
126
|
+
for use, reproduction, or distribution of Your modifications, or
|
|
127
|
+
for any such Derivative Works as a whole, provided Your use,
|
|
128
|
+
reproduction, and distribution of the Work otherwise complies with
|
|
129
|
+
the conditions stated in this License.
|
|
130
|
+
|
|
131
|
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
|
132
|
+
any Contribution intentionally submitted for inclusion in the Work
|
|
133
|
+
by You to the Licensor shall be under the terms and conditions of
|
|
134
|
+
this License, without any additional terms or conditions.
|
|
135
|
+
Notwithstanding the above, nothing herein shall supersede or modify
|
|
136
|
+
the terms of any separate license agreement you may have executed
|
|
137
|
+
with Licensor regarding such Contributions.
|
|
138
|
+
|
|
139
|
+
6. Trademarks. This License does not grant permission to use the trade
|
|
140
|
+
names, trademarks, service marks, or product names of the Licensor,
|
|
141
|
+
except as required for reasonable and customary use in describing the
|
|
142
|
+
origin of the Work and reproducing the content of the NOTICE file.
|
|
143
|
+
|
|
144
|
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
|
145
|
+
agreed to in writing, Licensor provides the Work (and each
|
|
146
|
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
|
147
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
|
148
|
+
implied, including, without limitation, any warranties or conditions
|
|
149
|
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
|
150
|
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
|
151
|
+
appropriateness of using or redistributing the Work and assume any
|
|
152
|
+
risks associated with Your exercise of permissions under this License.
|
|
153
|
+
|
|
154
|
+
8. Limitation of Liability. In no event and under no legal theory,
|
|
155
|
+
whether in tort (including negligence), contract, or otherwise,
|
|
156
|
+
unless required by applicable law (such as deliberate and grossly
|
|
157
|
+
negligent acts) or agreed to in writing, shall any Contributor be
|
|
158
|
+
liable to You for damages, including any direct, indirect, special,
|
|
159
|
+
incidental, or consequential damages of any character arising as a
|
|
160
|
+
result of this License or out of the use or inability to use the
|
|
161
|
+
Work (including but not limited to damages for loss of goodwill,
|
|
162
|
+
work stoppage, computer failure or malfunction, or any and all
|
|
163
|
+
other commercial damages or losses), even if such Contributor
|
|
164
|
+
has been advised of the possibility of such damages.
|
|
165
|
+
|
|
166
|
+
9. Accepting Warranty or Additional Liability. While redistributing
|
|
167
|
+
the Work or Derivative Works thereof, You may choose to offer,
|
|
168
|
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
|
169
|
+
or other liability obligations and/or rights consistent with this
|
|
170
|
+
License. However, in accepting such obligations, You may act only
|
|
171
|
+
on Your own behalf and on Your sole responsibility, not on behalf
|
|
172
|
+
of any other Contributor, and only if You agree to indemnify,
|
|
173
|
+
defend, and hold each Contributor harmless for any liability
|
|
174
|
+
incurred by, or claims asserted against, such Contributor by reason
|
|
175
|
+
of your accepting any such warranty or additional liability.
|
|
176
|
+
|
|
177
|
+
END OF TERMS AND CONDITIONS
|
|
178
|
+
|
|
179
|
+
APPENDIX: How to apply the Apache License to your work.
|
|
180
|
+
|
|
181
|
+
To apply the Apache License to your work, attach the following
|
|
182
|
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
|
183
|
+
replaced with your own identifying information. (Don't include
|
|
184
|
+
the brackets!) The text should be enclosed in the appropriate
|
|
185
|
+
comment syntax for the file format. We also recommend that a
|
|
186
|
+
file or class name and description of purpose be included on the
|
|
187
|
+
same "printed page" as the copyright notice for easier
|
|
188
|
+
identification within third-party archives.
|
|
189
|
+
|
|
190
|
+
Copyright [yyyy] [name of copyright owner]
|
|
191
|
+
|
|
192
|
+
Licensed under the Apache License, Version 2.0 (the "License");
|
|
193
|
+
you may not use this file except in compliance with the License.
|
|
194
|
+
You may obtain a copy of the License at
|
|
195
|
+
|
|
196
|
+
http://www.apache.org/licenses/LICENSE-2.0
|
|
197
|
+
|
|
198
|
+
Unless required by applicable law or agreed to in writing, software
|
|
199
|
+
distributed under the License is distributed on an "AS IS" BASIS,
|
|
200
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
|
201
|
+
See the License for the specific language governing permissions and
|
|
202
|
+
limitations under the License.
|
|
@@ -0,0 +1,7 @@
|
|
|
1
|
+
Multi-modal AI Studio
|
|
2
|
+
Copyright 2026 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
|
|
3
|
+
|
|
4
|
+
This product includes software developed by Multi-modal AI Studio contributors.
|
|
5
|
+
|
|
6
|
+
Third-party dependencies and their licenses are documented in
|
|
7
|
+
docs/third_party_dependencies.md.
|
|
@@ -0,0 +1,199 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: voice-ai-workbench
|
|
3
|
+
Version: 0.2.0
|
|
4
|
+
Summary: A developer workbench for voice and optional vision AI, with interchangeable models and conversation latency analysis
|
|
5
|
+
Author-email: "Chitoku YATO (tokk-nv)" <cyato@nvidia.com>, "Aditya Sahu (adsahu-nv)" <adsahu@nvidia.com>, kbenkhaled <kbenkhaled@nvidia.com>
|
|
6
|
+
License: Apache-2.0
|
|
7
|
+
Project-URL: Homepage, https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio
|
|
8
|
+
Project-URL: Documentation, https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/tree/main/docs
|
|
9
|
+
Project-URL: Repository, https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio
|
|
10
|
+
Project-URL: Issues, https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/issues
|
|
11
|
+
Keywords: ai,voice,multimodal,riva,nvidia,openai,conversational-ai
|
|
12
|
+
Classifier: Development Status :: 4 - Beta
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: License :: OSI Approved :: Apache Software License
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
18
|
+
Requires-Python: >=3.11
|
|
19
|
+
Description-Content-Type: text/markdown
|
|
20
|
+
License-File: LICENSE
|
|
21
|
+
License-File: NOTICE
|
|
22
|
+
Requires-Dist: aiohttp>=3.14.5
|
|
23
|
+
Requires-Dist: psutil>=5.9.0
|
|
24
|
+
Requires-Dist: grpcio>=1.56.2
|
|
25
|
+
Requires-Dist: nvidia-riva-client>=2.28.0
|
|
26
|
+
Requires-Dist: protobuf>=7.36.2
|
|
27
|
+
Requires-Dist: openai>=1.0.0
|
|
28
|
+
Requires-Dist: pyyaml>=6.0
|
|
29
|
+
Requires-Dist: python-dotenv>=1.2.2
|
|
30
|
+
Requires-Dist: numpy>=1.23.2
|
|
31
|
+
Requires-Dist: websockets>=11.0
|
|
32
|
+
Provides-Extra: dev
|
|
33
|
+
Requires-Dist: pytest>=9.0.3; extra == "dev"
|
|
34
|
+
Requires-Dist: pytest-asyncio>=1.3.0; extra == "dev"
|
|
35
|
+
Requires-Dist: pytest-cov>=7.0.0; extra == "dev"
|
|
36
|
+
Requires-Dist: black>=26.10.1; extra == "dev"
|
|
37
|
+
Requires-Dist: ruff>=0.17.2; extra == "dev"
|
|
38
|
+
Requires-Dist: mypy>=2.4.0; extra == "dev"
|
|
39
|
+
Requires-Dist: uv>=0.13.5; extra == "dev"
|
|
40
|
+
Provides-Extra: audio
|
|
41
|
+
Requires-Dist: pyaudio>=0.2.13; extra == "audio"
|
|
42
|
+
Provides-Extra: camera
|
|
43
|
+
Requires-Dist: opencv-python-headless>=4.8.1.78; extra == "camera"
|
|
44
|
+
Provides-Extra: video-input
|
|
45
|
+
Requires-Dist: av>=10.0.0; extra == "video-input"
|
|
46
|
+
Requires-Dist: Pillow>=13.0.0; extra == "video-input"
|
|
47
|
+
Provides-Extra: webrtc-camera
|
|
48
|
+
Requires-Dist: aiortc>=1.6.0; extra == "webrtc-camera"
|
|
49
|
+
Requires-Dist: av>=10.0.0; extra == "webrtc-camera"
|
|
50
|
+
Requires-Dist: opencv-python-headless>=4.8.1.78; extra == "webrtc-camera"
|
|
51
|
+
Dynamic: license-file
|
|
52
|
+
|
|
53
|
+
# Voice AI Workbench
|
|
54
|
+
|
|
55
|
+
**Give your robot a voice. Compare models, shape its character, and measure the conversation.**
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
Recorded on Jetson AGX Thor: Nemotron 3.5 ASR → Gemma 4 E2B → Magpie TTS, using the NVIDIA Speech — Realtime preset. The waveforms, partial transcripts, latency bands, and CPU/GPU traces come from a real session; the internal hostname and IP addresses are omitted from this public screenshot. These timings illustrate one conversation, not a controlled benchmark.
|
|
60
|
+
|
|
61
|
+
Voice AI Workbench is a developer tool for building and tuning conversational AI. Connect independent speech recognition (ASR), language model (LLM), and text-to-speech (TTS) services; adjust the LLM system prompt; and compare recognition, response latency, playback, and interruptions on a shared timeline. Optional camera input lets you evaluate vision-language models too.
|
|
62
|
+
|
|
63
|
+
Start with your browser's microphone and speaker for a quick test. Then select a microphone and speaker attached to the Jetson, save the configuration, and evaluate the same conversation pipeline with server-local USB audio. Headless operation is experimental; this is a conversation workbench, not a robot motion-control framework.
|
|
64
|
+
|
|
65
|
+
Formerly **Multi-modal AI Studio (MMAS)**. Starting with 0.2.0, the distribution and recommended CLI are `voice-ai-workbench`. The GitHub repository, Python import `multi_modal_ai_studio`, existing settings/session formats, and legacy `multi-modal-ai-studio` CLI remain compatible. See the [upgrade instructions](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/development/releasing.md#upgrading-an-earlier-mmas-installation) before replacing an earlier MMAS wheel.
|
|
66
|
+
|
|
67
|
+
## What you can do
|
|
68
|
+
|
|
69
|
+
- **Compare speech services:** Speaches Faster-Whisper/Kokoro, NVIDIA Nemotron ASR/Magpie reference services, and NVIDIA Riva gRPC. REST and Realtime API support and streaming behavior depend on the provider.
|
|
70
|
+
- **Choose an independent LLM:** Connect an OpenAI-compatible Chat Completions endpoint from llama.cpp, vLLM, Ollama, or a hosted service. Change the system prompt to tune your assistant's character and responses.
|
|
71
|
+
- **Tune the conversation:** Discover models and voices, preview a voice, adjust speech speed where supported, and save reusable presets.
|
|
72
|
+
- **Inspect each turn:** View audio waveforms, VAD/ASR, LLM, TTS, barge-in, and CPU/GPU utilization alongside latency measurements. Save sessions with configuration/device snapshots and review or download the session JSON.
|
|
73
|
+
- **Choose your devices:** Use browser microphone/speaker over WebRTC, or Linux server-local USB audio. Camera/VLM support is optional and installed separately.
|
|
74
|
+
|
|
75
|
+
## Architecture
|
|
76
|
+
|
|
77
|
+
|
|
78
|
+
|
|
79
|
+
The workbench connects to model services; it does not bundle their weights or inference runtimes in the Python package.
|
|
80
|
+
|
|
81
|
+
## Quick Start
|
|
82
|
+
|
|
83
|
+
### 1. Install the application
|
|
84
|
+
|
|
85
|
+
Use **Python 3.11+** and a virtual environment. The commands below target 0.2.0; check [GitHub Releases](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/releases) for publication status. Before PyPI publication, install the verified candidate wheel instead of using the package-name command.
|
|
86
|
+
|
|
87
|
+
```bash
|
|
88
|
+
python3 -m venv .venv
|
|
89
|
+
source .venv/bin/activate
|
|
90
|
+
python -m pip install voice-ai-workbench==0.2.0
|
|
91
|
+
voice-ai-workbench --version
|
|
92
|
+
```
|
|
93
|
+
|
|
94
|
+
On Windows, activate with `.venv\Scripts\activate` instead. On Ubuntu, if virtual-environment creation fails because `venv` or `ensurepip` is missing, install `python3-venv` or the matching version package (for example, `python3.12-venv`).
|
|
95
|
+
|
|
96
|
+
The wheel includes the Web UI and built-in presets. To open the UI and inspect saved sessions without starting model services:
|
|
97
|
+
|
|
98
|
+
```bash
|
|
99
|
+
voice-ai-workbench --port 8092
|
|
100
|
+
```
|
|
101
|
+
|
|
102
|
+
Open `https://localhost:8092`, or `https://JETSON_IP:8092` from another computer. The default certificate is self-signed; verify that you are connecting to your device before accepting it. Microphone access requires HTTPS and browser permission. Stop the foreground application with **Ctrl+C** before restarting it with a preset.
|
|
103
|
+
|
|
104
|
+
### Recommended quick start on Jetson
|
|
105
|
+
|
|
106
|
+
The recommended conversation path is **Faster-Whisper tiny.en → Gemma 4 E2B → Kokoro**, using the **Speaches on Jetson — REST** preset. It has been exercised on Jetson Orin Nano and AGX Thor. No separate Ollama installation, Riva server setup, NGC entitlement, or hosted inference key is required.
|
|
107
|
+
|
|
108
|
+
The backend launch scripts are **repository tools, not part of the wheel**. After the release is published, obtain a matching checkout for those scripts; keep using the pip-installed application:
|
|
109
|
+
|
|
110
|
+
```bash
|
|
111
|
+
git clone --branch v0.2.0 --depth 1 \
|
|
112
|
+
https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio.git
|
|
113
|
+
cd multi_modal_ai_studio
|
|
114
|
+
|
|
115
|
+
# Check the Jetson host, then start ASR/TTS and download the starter models.
|
|
116
|
+
./scripts/speaches_speech.sh doctor
|
|
117
|
+
./scripts/speaches_speech.sh start
|
|
118
|
+
./scripts/speaches_speech.sh verify
|
|
119
|
+
|
|
120
|
+
# Start text-only Gemma 4 E2B with the appropriate Orin or Thor container.
|
|
121
|
+
./scripts/gemma4_llm.sh start
|
|
122
|
+
./scripts/gemma4_llm.sh verify
|
|
123
|
+
|
|
124
|
+
# Start the installed application from outside the source checkout.
|
|
125
|
+
cd ..
|
|
126
|
+
voice-ai-workbench --preset speaches-jetson --port 8092
|
|
127
|
+
```
|
|
128
|
+
|
|
129
|
+
Docker, the NVIDIA container runtime, and a host GPU driver compatible with **CUDA 13 containers** are required for these launchers. Do not assume every JetPack release supports this image. See [Speaches on Jetson](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_speaches_jetson.md) for prerequisites, model-cache storage, ports, memory considerations, and overrides.
|
|
130
|
+
|
|
131
|
+
The launcher pins **Speaches 0.9.0-rc.3**, a backend release candidate independent of the workbench's version. **Use REST for the public quick start:** the pinned image's Realtime ASR path has known concurrent-load failures on Nano. A corrected local backend passed follow-up tests but is not yet in that published image; installing this Python package alone does not apply that backend fix. See the [qualification record](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/releases/v0.2.0-qualification.md#realtime-concurrent-load-follow-up--november-5-2026).
|
|
132
|
+
|
|
133
|
+
### NVIDIA open speech models
|
|
134
|
+
|
|
135
|
+
To compare **Nemotron 3.5 ASR and Magpie TTS** without setting up a Riva server, run these commands from the matching repository checkout:
|
|
136
|
+
|
|
137
|
+
```bash
|
|
138
|
+
./scripts/nvidia_open_models_speech.sh build
|
|
139
|
+
./scripts/nvidia_open_models_speech.sh start
|
|
140
|
+
./scripts/nvidia_open_models_speech.sh verify
|
|
141
|
+
```
|
|
142
|
+
|
|
143
|
+
This launcher manages **only ASR and TTS**, not the LLM. Keep a separately managed OpenAI-compatible LLM running, then select **NVIDIA Speech — REST** or **NVIDIA Speech — Realtime** in the UI. See [NVIDIA open speech models on Jetson](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_open_models_jetson.md) for exact models, requirements, and streaming limits. Existing Riva users can instead connect their gRPC server using the [Riva setup guide](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_riva.md).
|
|
144
|
+
|
|
145
|
+
### Optional devices and vision
|
|
146
|
+
|
|
147
|
+
Install only the features you use:
|
|
148
|
+
|
|
149
|
+
```bash
|
|
150
|
+
python -m pip install 'voice-ai-workbench[audio]==0.2.0' # PyAudio devices
|
|
151
|
+
python -m pip install 'voice-ai-workbench[camera]==0.2.0' # server USB camera
|
|
152
|
+
python -m pip install 'voice-ai-workbench[video-input]==0.2.0' # video files for VLMs
|
|
153
|
+
python -m pip install 'voice-ai-workbench[webrtc-camera]==0.2.0'
|
|
154
|
+
```
|
|
155
|
+
|
|
156
|
+
Linux ALSA USB audio uses `arecord`/`aplay` from `alsa-utils`; it does not require the PyAudio extra. PyAudio needs PortAudio system dependencies. See [installation and device setup](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/INSTALL.md).
|
|
157
|
+
|
|
158
|
+
### Development installation
|
|
159
|
+
|
|
160
|
+
For source changes, use a separate environment and an editable install instead of the release wheel:
|
|
161
|
+
|
|
162
|
+
```bash
|
|
163
|
+
git clone https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio.git
|
|
164
|
+
cd multi_modal_ai_studio
|
|
165
|
+
python3 -m venv .venv
|
|
166
|
+
source .venv/bin/activate
|
|
167
|
+
python -m pip install -e .
|
|
168
|
+
```
|
|
169
|
+
|
|
170
|
+
Alternatively, `./scripts/setup_dev.sh` prepares a development environment. Sample sessions in `mock_sessions/` are available in the repository checkout; run with `--session-dir mock_sessions` to review them. New sessions are stored in `sessions/` relative to the working directory unless `--session-dir` is specified.
|
|
171
|
+
|
|
172
|
+
## Scope and limitations
|
|
173
|
+
|
|
174
|
+
- **Streaming depends on the backend.** A Realtime WebSocket API does not guarantee model-native incremental recognition or synthesis. Speaches Faster-Whisper uses VAD-delimited utterances and may not emit partial transcripts.
|
|
175
|
+
- **Early TTS uses text chunks.** “Start speaking before LLM finishes” can reduce waiting, but short chunks affect prosody and shared GPU load can cause playback gaps. Disable it for a baseline quality comparison.
|
|
176
|
+
- **Small devices need memory headroom.** Stop unrelated GPU services and start with the small preset. Cold model loading can delay the first response; swap does not increase GPU memory.
|
|
177
|
+
- **USB/headless validation is narrower than browser validation.** Speaker placement and hardware echo cancellation affect self-transcription and barge-in. Validate your own microphone/speaker setup before robot integration.
|
|
178
|
+
- **Use a trusted development network.** Do not expose the unauthenticated UI or model endpoints directly to the public internet. Functional tests do not substitute for dependency/security review.
|
|
179
|
+
|
|
180
|
+
## Documentation
|
|
181
|
+
|
|
182
|
+
| Guide | Description |
|
|
183
|
+
| --- | --- |
|
|
184
|
+
| [Installation](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/INSTALL.md) | Package installation, devices, and troubleshooting |
|
|
185
|
+
| [Speaches on Jetson](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_speaches_jetson.md) | Recommended Faster-Whisper + Gemma 4 E2B + Kokoro setup |
|
|
186
|
+
| [NVIDIA open speech models](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_open_models_jetson.md) | Nemotron ASR + Magpie TTS reference services |
|
|
187
|
+
| [Speech API backends](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/api_backends.md) | REST, Realtime, and Riva contracts |
|
|
188
|
+
| [Realtime speech](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/realtime_speech.md) | Transcription and response-audio integration |
|
|
189
|
+
| [VLM guide](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/vlm_guide.md) | Vision-language models and frame capture |
|
|
190
|
+
| [Architecture](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/development/architecture.md) | System design and components |
|
|
191
|
+
| [0.2.0 release notes](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/releases/v0.2.0.md) | Changes, compatibility, and validation scope |
|
|
192
|
+
|
|
193
|
+
## Contributing
|
|
194
|
+
|
|
195
|
+
Issues, pull requests, and feedback are welcome. Start with the [repository](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio) and describe your device, model services, preset, and reproduction steps.
|
|
196
|
+
|
|
197
|
+
## License
|
|
198
|
+
|
|
199
|
+
Apache License 2.0. See [LICENSE](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/LICENSE). Model weights and backend containers have their own licenses and requirements.
|
|
@@ -0,0 +1,147 @@
|
|
|
1
|
+
# Voice AI Workbench
|
|
2
|
+
|
|
3
|
+
**Give your robot a voice. Compare models, shape its character, and measure the conversation.**
|
|
4
|
+
|
|
5
|
+

|
|
6
|
+
|
|
7
|
+
Recorded on Jetson AGX Thor: Nemotron 3.5 ASR → Gemma 4 E2B → Magpie TTS, using the NVIDIA Speech — Realtime preset. The waveforms, partial transcripts, latency bands, and CPU/GPU traces come from a real session; the internal hostname and IP addresses are omitted from this public screenshot. These timings illustrate one conversation, not a controlled benchmark.
|
|
8
|
+
|
|
9
|
+
Voice AI Workbench is a developer tool for building and tuning conversational AI. Connect independent speech recognition (ASR), language model (LLM), and text-to-speech (TTS) services; adjust the LLM system prompt; and compare recognition, response latency, playback, and interruptions on a shared timeline. Optional camera input lets you evaluate vision-language models too.
|
|
10
|
+
|
|
11
|
+
Start with your browser's microphone and speaker for a quick test. Then select a microphone and speaker attached to the Jetson, save the configuration, and evaluate the same conversation pipeline with server-local USB audio. Headless operation is experimental; this is a conversation workbench, not a robot motion-control framework.
|
|
12
|
+
|
|
13
|
+
Formerly **Multi-modal AI Studio (MMAS)**. Starting with 0.2.0, the distribution and recommended CLI are `voice-ai-workbench`. The GitHub repository, Python import `multi_modal_ai_studio`, existing settings/session formats, and legacy `multi-modal-ai-studio` CLI remain compatible. See the [upgrade instructions](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/development/releasing.md#upgrading-an-earlier-mmas-installation) before replacing an earlier MMAS wheel.
|
|
14
|
+
|
|
15
|
+
## What you can do
|
|
16
|
+
|
|
17
|
+
- **Compare speech services:** Speaches Faster-Whisper/Kokoro, NVIDIA Nemotron ASR/Magpie reference services, and NVIDIA Riva gRPC. REST and Realtime API support and streaming behavior depend on the provider.
|
|
18
|
+
- **Choose an independent LLM:** Connect an OpenAI-compatible Chat Completions endpoint from llama.cpp, vLLM, Ollama, or a hosted service. Change the system prompt to tune your assistant's character and responses.
|
|
19
|
+
- **Tune the conversation:** Discover models and voices, preview a voice, adjust speech speed where supported, and save reusable presets.
|
|
20
|
+
- **Inspect each turn:** View audio waveforms, VAD/ASR, LLM, TTS, barge-in, and CPU/GPU utilization alongside latency measurements. Save sessions with configuration/device snapshots and review or download the session JSON.
|
|
21
|
+
- **Choose your devices:** Use browser microphone/speaker over WebRTC, or Linux server-local USB audio. Camera/VLM support is optional and installed separately.
|
|
22
|
+
|
|
23
|
+
## Architecture
|
|
24
|
+
|
|
25
|
+

|
|
26
|
+
|
|
27
|
+
The workbench connects to model services; it does not bundle their weights or inference runtimes in the Python package.
|
|
28
|
+
|
|
29
|
+
## Quick Start
|
|
30
|
+
|
|
31
|
+
### 1. Install the application
|
|
32
|
+
|
|
33
|
+
Use **Python 3.11+** and a virtual environment. The commands below target 0.2.0; check [GitHub Releases](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/releases) for publication status. Before PyPI publication, install the verified candidate wheel instead of using the package-name command.
|
|
34
|
+
|
|
35
|
+
```bash
|
|
36
|
+
python3 -m venv .venv
|
|
37
|
+
source .venv/bin/activate
|
|
38
|
+
python -m pip install voice-ai-workbench==0.2.0
|
|
39
|
+
voice-ai-workbench --version
|
|
40
|
+
```
|
|
41
|
+
|
|
42
|
+
On Windows, activate with `.venv\Scripts\activate` instead. On Ubuntu, if virtual-environment creation fails because `venv` or `ensurepip` is missing, install `python3-venv` or the matching version package (for example, `python3.12-venv`).
|
|
43
|
+
|
|
44
|
+
The wheel includes the Web UI and built-in presets. To open the UI and inspect saved sessions without starting model services:
|
|
45
|
+
|
|
46
|
+
```bash
|
|
47
|
+
voice-ai-workbench --port 8092
|
|
48
|
+
```
|
|
49
|
+
|
|
50
|
+
Open `https://localhost:8092`, or `https://JETSON_IP:8092` from another computer. The default certificate is self-signed; verify that you are connecting to your device before accepting it. Microphone access requires HTTPS and browser permission. Stop the foreground application with **Ctrl+C** before restarting it with a preset.
|
|
51
|
+
|
|
52
|
+
### Recommended quick start on Jetson
|
|
53
|
+
|
|
54
|
+
The recommended conversation path is **Faster-Whisper tiny.en → Gemma 4 E2B → Kokoro**, using the **Speaches on Jetson — REST** preset. It has been exercised on Jetson Orin Nano and AGX Thor. No separate Ollama installation, Riva server setup, NGC entitlement, or hosted inference key is required.
|
|
55
|
+
|
|
56
|
+
The backend launch scripts are **repository tools, not part of the wheel**. After the release is published, obtain a matching checkout for those scripts; keep using the pip-installed application:
|
|
57
|
+
|
|
58
|
+
```bash
|
|
59
|
+
git clone --branch v0.2.0 --depth 1 \
|
|
60
|
+
https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio.git
|
|
61
|
+
cd multi_modal_ai_studio
|
|
62
|
+
|
|
63
|
+
# Check the Jetson host, then start ASR/TTS and download the starter models.
|
|
64
|
+
./scripts/speaches_speech.sh doctor
|
|
65
|
+
./scripts/speaches_speech.sh start
|
|
66
|
+
./scripts/speaches_speech.sh verify
|
|
67
|
+
|
|
68
|
+
# Start text-only Gemma 4 E2B with the appropriate Orin or Thor container.
|
|
69
|
+
./scripts/gemma4_llm.sh start
|
|
70
|
+
./scripts/gemma4_llm.sh verify
|
|
71
|
+
|
|
72
|
+
# Start the installed application from outside the source checkout.
|
|
73
|
+
cd ..
|
|
74
|
+
voice-ai-workbench --preset speaches-jetson --port 8092
|
|
75
|
+
```
|
|
76
|
+
|
|
77
|
+
Docker, the NVIDIA container runtime, and a host GPU driver compatible with **CUDA 13 containers** are required for these launchers. Do not assume every JetPack release supports this image. See [Speaches on Jetson](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_speaches_jetson.md) for prerequisites, model-cache storage, ports, memory considerations, and overrides.
|
|
78
|
+
|
|
79
|
+
The launcher pins **Speaches 0.9.0-rc.3**, a backend release candidate independent of the workbench's version. **Use REST for the public quick start:** the pinned image's Realtime ASR path has known concurrent-load failures on Nano. A corrected local backend passed follow-up tests but is not yet in that published image; installing this Python package alone does not apply that backend fix. See the [qualification record](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/releases/v0.2.0-qualification.md#realtime-concurrent-load-follow-up--november-5-2026).
|
|
80
|
+
|
|
81
|
+
### NVIDIA open speech models
|
|
82
|
+
|
|
83
|
+
To compare **Nemotron 3.5 ASR and Magpie TTS** without setting up a Riva server, run these commands from the matching repository checkout:
|
|
84
|
+
|
|
85
|
+
```bash
|
|
86
|
+
./scripts/nvidia_open_models_speech.sh build
|
|
87
|
+
./scripts/nvidia_open_models_speech.sh start
|
|
88
|
+
./scripts/nvidia_open_models_speech.sh verify
|
|
89
|
+
```
|
|
90
|
+
|
|
91
|
+
This launcher manages **only ASR and TTS**, not the LLM. Keep a separately managed OpenAI-compatible LLM running, then select **NVIDIA Speech — REST** or **NVIDIA Speech — Realtime** in the UI. See [NVIDIA open speech models on Jetson](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_open_models_jetson.md) for exact models, requirements, and streaming limits. Existing Riva users can instead connect their gRPC server using the [Riva setup guide](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_riva.md).
|
|
92
|
+
|
|
93
|
+
### Optional devices and vision
|
|
94
|
+
|
|
95
|
+
Install only the features you use:
|
|
96
|
+
|
|
97
|
+
```bash
|
|
98
|
+
python -m pip install 'voice-ai-workbench[audio]==0.2.0' # PyAudio devices
|
|
99
|
+
python -m pip install 'voice-ai-workbench[camera]==0.2.0' # server USB camera
|
|
100
|
+
python -m pip install 'voice-ai-workbench[video-input]==0.2.0' # video files for VLMs
|
|
101
|
+
python -m pip install 'voice-ai-workbench[webrtc-camera]==0.2.0'
|
|
102
|
+
```
|
|
103
|
+
|
|
104
|
+
Linux ALSA USB audio uses `arecord`/`aplay` from `alsa-utils`; it does not require the PyAudio extra. PyAudio needs PortAudio system dependencies. See [installation and device setup](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/INSTALL.md).
|
|
105
|
+
|
|
106
|
+
### Development installation
|
|
107
|
+
|
|
108
|
+
For source changes, use a separate environment and an editable install instead of the release wheel:
|
|
109
|
+
|
|
110
|
+
```bash
|
|
111
|
+
git clone https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio.git
|
|
112
|
+
cd multi_modal_ai_studio
|
|
113
|
+
python3 -m venv .venv
|
|
114
|
+
source .venv/bin/activate
|
|
115
|
+
python -m pip install -e .
|
|
116
|
+
```
|
|
117
|
+
|
|
118
|
+
Alternatively, `./scripts/setup_dev.sh` prepares a development environment. Sample sessions in `mock_sessions/` are available in the repository checkout; run with `--session-dir mock_sessions` to review them. New sessions are stored in `sessions/` relative to the working directory unless `--session-dir` is specified.
|
|
119
|
+
|
|
120
|
+
## Scope and limitations
|
|
121
|
+
|
|
122
|
+
- **Streaming depends on the backend.** A Realtime WebSocket API does not guarantee model-native incremental recognition or synthesis. Speaches Faster-Whisper uses VAD-delimited utterances and may not emit partial transcripts.
|
|
123
|
+
- **Early TTS uses text chunks.** “Start speaking before LLM finishes” can reduce waiting, but short chunks affect prosody and shared GPU load can cause playback gaps. Disable it for a baseline quality comparison.
|
|
124
|
+
- **Small devices need memory headroom.** Stop unrelated GPU services and start with the small preset. Cold model loading can delay the first response; swap does not increase GPU memory.
|
|
125
|
+
- **USB/headless validation is narrower than browser validation.** Speaker placement and hardware echo cancellation affect self-transcription and barge-in. Validate your own microphone/speaker setup before robot integration.
|
|
126
|
+
- **Use a trusted development network.** Do not expose the unauthenticated UI or model endpoints directly to the public internet. Functional tests do not substitute for dependency/security review.
|
|
127
|
+
|
|
128
|
+
## Documentation
|
|
129
|
+
|
|
130
|
+
| Guide | Description |
|
|
131
|
+
| --- | --- |
|
|
132
|
+
| [Installation](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/INSTALL.md) | Package installation, devices, and troubleshooting |
|
|
133
|
+
| [Speaches on Jetson](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_speaches_jetson.md) | Recommended Faster-Whisper + Gemma 4 E2B + Kokoro setup |
|
|
134
|
+
| [NVIDIA open speech models](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/setup_open_models_jetson.md) | Nemotron ASR + Magpie TTS reference services |
|
|
135
|
+
| [Speech API backends](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/api_backends.md) | REST, Realtime, and Riva contracts |
|
|
136
|
+
| [Realtime speech](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/realtime_speech.md) | Transcription and response-audio integration |
|
|
137
|
+
| [VLM guide](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/vlm_guide.md) | Vision-language models and frame capture |
|
|
138
|
+
| [Architecture](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/development/architecture.md) | System design and components |
|
|
139
|
+
| [0.2.0 release notes](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/docs/releases/v0.2.0.md) | Changes, compatibility, and validation scope |
|
|
140
|
+
|
|
141
|
+
## Contributing
|
|
142
|
+
|
|
143
|
+
Issues, pull requests, and feedback are welcome. Start with the [repository](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio) and describe your device, model services, preset, and reproduction steps.
|
|
144
|
+
|
|
145
|
+
## License
|
|
146
|
+
|
|
147
|
+
Apache License 2.0. See [LICENSE](https://github.com/NVIDIA-AI-IOT/multi_modal_ai_studio/blob/main/LICENSE). Model weights and backend containers have their own licenses and requirements.
|
|
@@ -0,0 +1,67 @@
|
|
|
1
|
+
# SPDX-FileCopyrightText: Copyright (c) 2026 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
|
|
2
|
+
# SPDX-License-Identifier: Apache-2.0
|
|
3
|
+
#
|
|
4
|
+
# Cosmos-Reason2 VLM served by vLLM — vision + chain-of-thought reasoning.
|
|
5
|
+
# Flagship Jetson configuration: Riva ASR → vLLM (Cosmos-Reason2) → Riva TTS.
|
|
6
|
+
#
|
|
7
|
+
# Prerequisites:
|
|
8
|
+
# - Riva ASR/TTS server on localhost:50051
|
|
9
|
+
# - vLLM serving Cosmos-Reason2 on localhost:8010
|
|
10
|
+
|
|
11
|
+
name: "Cosmos-Reason2 VLM (vLLM)"
|
|
12
|
+
description: "Riva ASR/TTS + Cosmos-Reason2 via vLLM with vision and reasoning"
|
|
13
|
+
app_version: "0.1.0"
|
|
14
|
+
|
|
15
|
+
asr:
|
|
16
|
+
scheme: riva
|
|
17
|
+
server: localhost:50051
|
|
18
|
+
model: parakeet-1.1b-en-US-asr-streaming-silero-vad-sortformer
|
|
19
|
+
language: en-US
|
|
20
|
+
vad_start_threshold: 0.5
|
|
21
|
+
vad_stop_threshold: 0.3
|
|
22
|
+
speech_pad_ms: 600
|
|
23
|
+
speech_timeout_ms: 1200
|
|
24
|
+
|
|
25
|
+
llm:
|
|
26
|
+
scheme: openai
|
|
27
|
+
api_base: http://localhost:8010/v1
|
|
28
|
+
model: nvidia/cosmos-reason2-8b-fp8
|
|
29
|
+
temperature: 0.3
|
|
30
|
+
max_tokens: 512
|
|
31
|
+
history_turns: 0
|
|
32
|
+
include_conversation_history: false
|
|
33
|
+
system_prompt: >-
|
|
34
|
+
You are a helpful voice AI assistant.
|
|
35
|
+
Plain text only, no markdown, no bullet points, no emojis.
|
|
36
|
+
enable_vision: true
|
|
37
|
+
vision_system_prompt: >-
|
|
38
|
+
You are a helpful voice and vision assistant.
|
|
39
|
+
Give ONE short sentence answers only. Be direct.
|
|
40
|
+
Plain text only, no markdown, no bullet points, no emojis.
|
|
41
|
+
vision_frames: 30
|
|
42
|
+
vision_detail: auto
|
|
43
|
+
vision_quality: 0.8
|
|
44
|
+
vision_max_width: 768
|
|
45
|
+
vision_buffer_fps: 5.0
|
|
46
|
+
vision_video_encode: true
|
|
47
|
+
vision_api_format: openai
|
|
48
|
+
vision_omit_last_assistant: true
|
|
49
|
+
enable_reasoning_through_user_prompt: true
|
|
50
|
+
|
|
51
|
+
tts:
|
|
52
|
+
scheme: riva
|
|
53
|
+
server: localhost:50051
|
|
54
|
+
voice: ""
|
|
55
|
+
sample_rate: 22050
|
|
56
|
+
stream_tts: true
|
|
57
|
+
|
|
58
|
+
devices:
|
|
59
|
+
video_source: browser
|
|
60
|
+
audio_input_source: browser
|
|
61
|
+
audio_output_source: browser
|
|
62
|
+
|
|
63
|
+
app:
|
|
64
|
+
barge_in_enabled: true
|
|
65
|
+
timeline_position: right
|
|
66
|
+
session_auto_save: true
|
|
67
|
+
session_output_dir: ./sessions
|