vlm-sieve 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- vlm_sieve-0.1.0/.agent/rules.md +59 -0
- vlm_sieve-0.1.0/.github/workflows/ci.yml +41 -0
- vlm_sieve-0.1.0/.github/workflows/publish.yml +41 -0
- vlm_sieve-0.1.0/.gitignore +45 -0
- vlm_sieve-0.1.0/LICENSE +21 -0
- vlm_sieve-0.1.0/PKG-INFO +264 -0
- vlm_sieve-0.1.0/README.md +241 -0
- vlm_sieve-0.1.0/assets/demo_storyboard.jpg +0 -0
- vlm_sieve-0.1.0/pyproject.toml +40 -0
- vlm_sieve-0.1.0/scripts/generate_demo.py +206 -0
- vlm_sieve-0.1.0/src/vlmsieve/__init__.py +31 -0
- vlm_sieve-0.1.0/src/vlmsieve/cli.py +138 -0
- vlm_sieve-0.1.0/src/vlmsieve/gatekeeper.py +225 -0
- vlm_sieve-0.1.0/src/vlmsieve/models.py +213 -0
- vlm_sieve-0.1.0/src/vlmsieve/roi.py +95 -0
- vlm_sieve-0.1.0/src/vlmsieve/sampler.py +104 -0
- vlm_sieve-0.1.0/src/vlmsieve/sieve.py +298 -0
- vlm_sieve-0.1.0/src/vlmsieve/storyboard.py +191 -0
- vlm_sieve-0.1.0/tests/__init__.py +1 -0
- vlm_sieve-0.1.0/tests/test_e2e_pipeline.py +138 -0
- vlm_sieve-0.1.0/tests/test_gatekeeper.py +273 -0
- vlm_sieve-0.1.0/tests/test_sampler_and_roi.py +193 -0
- vlm_sieve-0.1.0/tests/test_sieve_and_cli.py +155 -0
- vlm_sieve-0.1.0/tests/test_storyboard.py +145 -0
|
@@ -0,0 +1,59 @@
|
|
|
1
|
+
# vlm-sieve: Workspace Architectural Rules & Engineering Guidelines
|
|
2
|
+
|
|
3
|
+
## 1. Project Identity & Purpose
|
|
4
|
+
- **Distribution Name:** `vlm-sieve`
|
|
5
|
+
- **Import Package Name:** `vlmsieve`
|
|
6
|
+
- **Core Purpose:** High-throughput, event-driven video frame gatekeeper, active Region-of-Interest (ROI) cropper, and temporal storyboard packer. It selectively filters redundant video frames and intelligently packs salient visual information to reduce Vision-Language Model (VLM) image token consumption by >95% while operating purely on CPU.
|
|
7
|
+
|
|
8
|
+
---
|
|
9
|
+
|
|
10
|
+
## 2. Strict Architectural Constraints
|
|
11
|
+
|
|
12
|
+
### 2.1 Core Dependency Guardrails
|
|
13
|
+
- **Heavy Deep-Learning Prohibition:** Heavy deep-learning frameworks (`torch`, `tensorflow`, `transformers`, `jax`, `onnxruntime`, etc.) are **STRICTLY FORBIDDEN** in core dependencies.
|
|
14
|
+
- **Allowed Core Dependencies Only:**
|
|
15
|
+
- `numpy>=1.24.0`
|
|
16
|
+
- `opencv-python-headless>=4.8.0`
|
|
17
|
+
- `Pillow>=10.0.0`
|
|
18
|
+
- `pydantic>=2.5.0`
|
|
19
|
+
- Any optional neural/model integrations must live in separated optional extras (e.g., `vlm-sieve[torch]`) and must never be imported in core modules without graceful fallbacks.
|
|
20
|
+
|
|
21
|
+
### 2.2 Performance & Latency Targets
|
|
22
|
+
- **CPU Frame Gating Latency:** `< 3ms` per frame at 1080p input resolution.
|
|
23
|
+
- **Downscaled Grayscale Processing:** Gating decisions must operate on downscaled grayscale representations (e.g., 360p or lower, pyramid representations) to guarantee sub-3ms evaluation on commodity single-core CPUs.
|
|
24
|
+
- **Memory Footprint:** Zero-copy operations and buffer reuse wherever possible when piping NumPy arrays between OpenCV and Pillow. Avoid redundant array allocations.
|
|
25
|
+
|
|
26
|
+
### 2.3 Implementation & Code Integrity
|
|
27
|
+
- **Zero Placeholder Stubs:** Every class, function, and method must be completely implemented, mathematically sound, and functional. No empty `pass` bodies, no `...` ellipses in concrete logic, and no `TODO` or unhandled edge cases.
|
|
28
|
+
- **Strict Typing:** All modules must enforce Python 3.9+ type annotations on all function signatures, return values, and class attributes. Utilize `typing` / `pydantic` types and adhere to strict static typing checks.
|
|
29
|
+
|
|
30
|
+
---
|
|
31
|
+
|
|
32
|
+
## 3. Core Functional Pillars
|
|
33
|
+
|
|
34
|
+
### 3.1 Temporal Frame Gating (`vlmsieve.gating`)
|
|
35
|
+
- Detect meaningful visual delta between consecutive and sliding-window frames.
|
|
36
|
+
- Employ lightweight algorithms:
|
|
37
|
+
- Structural Similarity Metric (SSIM) approximations on downscaled tiles.
|
|
38
|
+
- Pixel-difference statistics with adaptive luminosity normalization.
|
|
39
|
+
- Motion energy accumulation (frame differencing / background subtraction).
|
|
40
|
+
- Fast drop of static or sub-threshold frames before any expensive image processing.
|
|
41
|
+
|
|
42
|
+
### 3.2 Active Region-of-Interest Cropper (`vlmsieve.cropper`)
|
|
43
|
+
- Identify dynamic bounding boxes containing the active motion or high-frequency visual change.
|
|
44
|
+
- Morphological dilation and contour clustering to avoid fragmented crops.
|
|
45
|
+
- Dynamic aspect-ratio padding to preserve contextual cues without transmitting vast static backgrounds to VLMs.
|
|
46
|
+
|
|
47
|
+
### 3.3 Temporal Storyboard Packer (`vlmsieve.packer`)
|
|
48
|
+
- Composite multiple sequential keyframes or ROI patches into high-density temporal grid storyboards.
|
|
49
|
+
- Timestamp and sequence metadata overlay/badges for multi-frame contextual alignment within a single VLM input image.
|
|
50
|
+
- Drastic reduction of API calls and token count by consolidating $N$ frames into single composite tensors/images.
|
|
51
|
+
|
|
52
|
+
---
|
|
53
|
+
|
|
54
|
+
## 4. Coding & Quality Standards
|
|
55
|
+
|
|
56
|
+
- **Python Version Support:** `>=3.9`
|
|
57
|
+
- **Linting & Formatting:** `ruff` rules must pass cleanly.
|
|
58
|
+
- **Data Validation:** All user-facing configuration, thresholds, and outputs must be validated using `pydantic.BaseModel`.
|
|
59
|
+
- **Testing:** Unit tests under `tests/` verifying mathematical correctness, threshold edge cases, memory cleanup, and throughput benchmarking.
|
|
@@ -0,0 +1,41 @@
|
|
|
1
|
+
name: CI
|
|
2
|
+
|
|
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
branches: [main]
|
|
6
|
+
pull_request:
|
|
7
|
+
branches: [main]
|
|
8
|
+
|
|
9
|
+
jobs:
|
|
10
|
+
test:
|
|
11
|
+
name: Test (Python ${{ matrix.python-version }} on ${{ matrix.os }})
|
|
12
|
+
runs-on: ${{ matrix.os }}
|
|
13
|
+
strategy:
|
|
14
|
+
fail-fast: false
|
|
15
|
+
matrix:
|
|
16
|
+
os: [ubuntu-latest, windows-latest]
|
|
17
|
+
python-version: ["3.10", "3.11", "3.12"]
|
|
18
|
+
|
|
19
|
+
steps:
|
|
20
|
+
- name: Checkout repository
|
|
21
|
+
uses: actions/checkout@v4
|
|
22
|
+
|
|
23
|
+
- name: Set up Python ${{ matrix.python-version }}
|
|
24
|
+
uses: actions/setup-python@v5
|
|
25
|
+
with:
|
|
26
|
+
python-version: ${{ matrix.python-version }}
|
|
27
|
+
cache: "pip"
|
|
28
|
+
|
|
29
|
+
- name: Install dependencies
|
|
30
|
+
run: |
|
|
31
|
+
python -m pip install --upgrade pip
|
|
32
|
+
pip install -e ".[dev]"
|
|
33
|
+
|
|
34
|
+
- name: Run Ruff linter and formatter check
|
|
35
|
+
run: |
|
|
36
|
+
ruff check src/ tests/ scripts/
|
|
37
|
+
ruff format --check src/ tests/ scripts/
|
|
38
|
+
|
|
39
|
+
- name: Run Pytest test suite
|
|
40
|
+
run: |
|
|
41
|
+
pytest -v
|
|
@@ -0,0 +1,41 @@
|
|
|
1
|
+
name: Publish to PyPI
|
|
2
|
+
|
|
3
|
+
on:
|
|
4
|
+
release:
|
|
5
|
+
types: [published]
|
|
6
|
+
|
|
7
|
+
permissions:
|
|
8
|
+
contents: read
|
|
9
|
+
|
|
10
|
+
jobs:
|
|
11
|
+
build-and-publish:
|
|
12
|
+
name: Build distribution and publish to PyPI
|
|
13
|
+
runs-on: ubuntu-latest
|
|
14
|
+
environment:
|
|
15
|
+
name: pypi
|
|
16
|
+
url: https://pypi.org/p/vlm-sieve
|
|
17
|
+
permissions:
|
|
18
|
+
id-token: write # Mandatory for PyPI Trusted Publishing
|
|
19
|
+
|
|
20
|
+
steps:
|
|
21
|
+
- name: Checkout repository
|
|
22
|
+
uses: actions/checkout@v4
|
|
23
|
+
|
|
24
|
+
- name: Set up Python
|
|
25
|
+
uses: actions/setup-python@v5
|
|
26
|
+
with:
|
|
27
|
+
python-version: "3.12"
|
|
28
|
+
|
|
29
|
+
- name: Install build and packaging tools
|
|
30
|
+
run: |
|
|
31
|
+
python -m pip install --upgrade pip
|
|
32
|
+
pip install build twine
|
|
33
|
+
|
|
34
|
+
- name: Build sdist and wheel
|
|
35
|
+
run: python -m build
|
|
36
|
+
|
|
37
|
+
- name: Check package distribution artifacts
|
|
38
|
+
run: twine check dist/*
|
|
39
|
+
|
|
40
|
+
- name: Publish to PyPI
|
|
41
|
+
uses: pypa/gh-action-pypi-publish@release/v1
|
|
@@ -0,0 +1,45 @@
|
|
|
1
|
+
# Virtual environments
|
|
2
|
+
.venv/
|
|
3
|
+
venv/
|
|
4
|
+
env/
|
|
5
|
+
|
|
6
|
+
# Build, distribution, and packaging artifacts
|
|
7
|
+
dist/
|
|
8
|
+
build/
|
|
9
|
+
*.egg-info/
|
|
10
|
+
*.whl
|
|
11
|
+
*.tar.gz
|
|
12
|
+
|
|
13
|
+
# Python cache & test artifacts
|
|
14
|
+
__pycache__/
|
|
15
|
+
*.py[cod]
|
|
16
|
+
*$py.class
|
|
17
|
+
.pytest_cache/
|
|
18
|
+
.ruff_cache/
|
|
19
|
+
.coverage
|
|
20
|
+
htmlcov/
|
|
21
|
+
|
|
22
|
+
# Local IDE / Agent workspace state (keep .agent/rules.md tracked or untracked as preferred, ignore temp logs)
|
|
23
|
+
.vscode/
|
|
24
|
+
.idea/
|
|
25
|
+
|
|
26
|
+
# Personal webcam & CLI output directories (STRICT PRIVACY LOCK)
|
|
27
|
+
live_webcam_test/
|
|
28
|
+
webcam_verified_v2/
|
|
29
|
+
*webcam*/
|
|
30
|
+
sieve_out/
|
|
31
|
+
*test_out*/
|
|
32
|
+
preview.jpg
|
|
33
|
+
summary.json
|
|
34
|
+
|
|
35
|
+
# Block all stray images and videos everywhere by default
|
|
36
|
+
*.jpg
|
|
37
|
+
*.jpeg
|
|
38
|
+
*.png
|
|
39
|
+
*.mp4
|
|
40
|
+
*.avi
|
|
41
|
+
*.mov
|
|
42
|
+
|
|
43
|
+
# Explicitly whitelist ONLY the synthetic robotics showcase image
|
|
44
|
+
!assets/
|
|
45
|
+
!assets/demo_storyboard.jpg
|
vlm_sieve-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 vlm-sieve contributors
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
vlm_sieve-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,264 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: vlm-sieve
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Event-driven video frame gatekeeper, active ROI cropper, and temporal storyboard packer
|
|
5
|
+
Project-URL: Homepage, https://github.com/Virajcreates/vlm-sieve
|
|
6
|
+
Project-URL: Repository, https://github.com/Virajcreates/vlm-sieve
|
|
7
|
+
Project-URL: Issues, https://github.com/Virajcreates/vlm-sieve/issues
|
|
8
|
+
Author: vlm-sieve contributors
|
|
9
|
+
License: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Requires-Python: >=3.9
|
|
12
|
+
Requires-Dist: numpy>=1.24.0
|
|
13
|
+
Requires-Dist: opencv-python-headless>=4.8.0
|
|
14
|
+
Requires-Dist: pillow>=10.0.0
|
|
15
|
+
Requires-Dist: pydantic>=2.5.0
|
|
16
|
+
Provides-Extra: dev
|
|
17
|
+
Requires-Dist: build>=1.2.0; extra == 'dev'
|
|
18
|
+
Requires-Dist: pytest-asyncio>=0.23.0; extra == 'dev'
|
|
19
|
+
Requires-Dist: pytest>=8.0.0; extra == 'dev'
|
|
20
|
+
Requires-Dist: ruff>=0.6.0; extra == 'dev'
|
|
21
|
+
Requires-Dist: twine>=5.0.0; extra == 'dev'
|
|
22
|
+
Description-Content-Type: text/markdown
|
|
23
|
+
|
|
24
|
+
# vlm-sieve
|
|
25
|
+
|
|
26
|
+
[](https://pypi.org/project/vlm-sieve/)
|
|
27
|
+
[](https://www.python.org/downloads/)
|
|
28
|
+
[](LICENSE)
|
|
29
|
+
[](#performance--benchmarks)
|
|
30
|
+
|
|
31
|
+
> **Event-Driven Video Frame Gatekeeper, Active ROI Cropper & Temporal Storyboard Packer for Vision-Language Models.**
|
|
32
|
+
|
|
33
|
+
---
|
|
34
|
+
|
|
35
|
+
## Overview
|
|
36
|
+
|
|
37
|
+
Sending raw 30fps or 60fps video directly to frontier Vision-Language Models (such as **Google Gemini**, **OpenAI GPT-4o**, or **Anthropic Claude 3.5**) quickly becomes cost-prohibitive, introduces severe latency, and floods context windows with static background tokens.
|
|
38
|
+
|
|
39
|
+
`vlm-sieve` (`vlmsieve`) is an ultra-fast, CPU-only intelligent pre-filter that monitors live webcams, RTSP security feeds, or recorded video files. It discards redundant or idle frames, tracks active motion regions, and packs salient temporal moments into structured, timestamped, and spatially grounded **storyboard image grids**—reducing VLM token consumption by **>95%** while boosting temporal and spatial comprehension.
|
|
40
|
+
|
|
41
|
+
---
|
|
42
|
+
|
|
43
|
+
## Visual Showcase
|
|
44
|
+
|
|
45
|
+
|
|
46
|
+
|
|
47
|
+
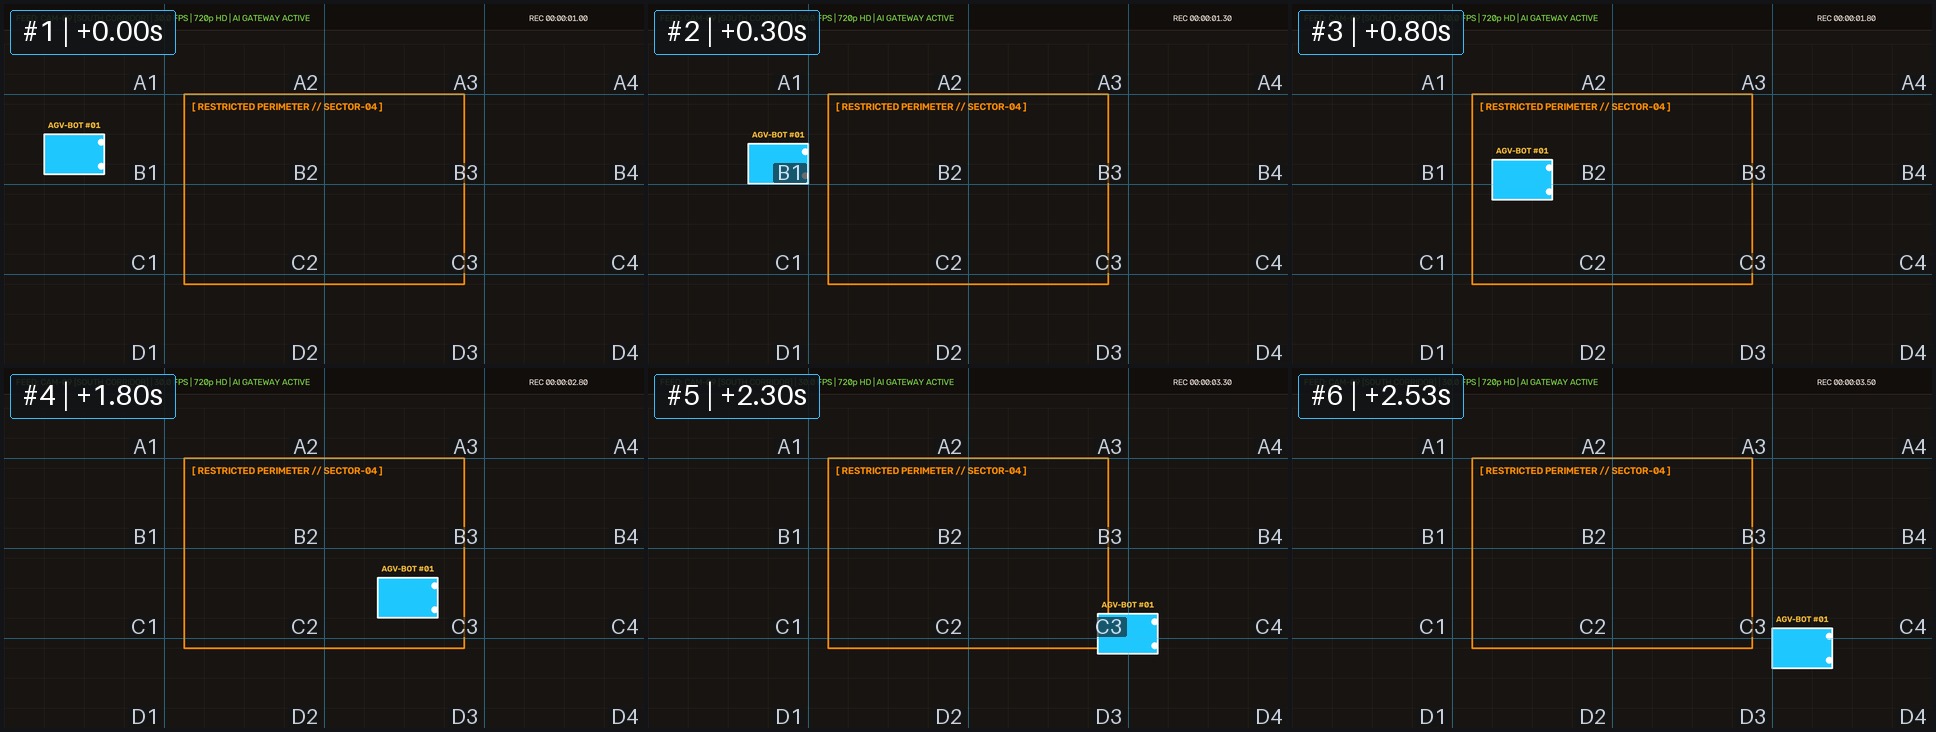
In the example above, `vlm-sieve` monitored a 150-frame ($5.0\text{s}$) simulated surveillance feed. Instead of transmitting 150 separate images ($168,000$ naive tokens), `vlm-sieve` emitted a **single $2 \times 3$ storyboard** ($1,120$ tokens)—achieving **99.33% token savings (150x compression)** while providing:
|
|
48
|
+
- **Chronological Indexing:** Each tile contains a high-contrast badge (`#1 | +0.00s` to `#6 | +2.53s`) specifying exact relative offsets.
|
|
49
|
+
- **$4 \times 4$ Spatial Coordinate Grounding:** Tiles feature cell coordinate labels (`A1`–`D4`) allowing VLMs to reason about exact spatial trajectories (e.g., *"vehicle entered at B1, traversed C2-C3, and parked at D4"*).
|
|
50
|
+
- **Active ROI Zooming:** Automatically crops out uninformative backgrounds without losing context.
|
|
51
|
+
|
|
52
|
+
---
|
|
53
|
+
|
|
54
|
+
## The 4-Stage Architecture Funnel
|
|
55
|
+
|
|
56
|
+
```
|
|
57
|
+
Raw Video Stream (30/60 FPS)
|
|
58
|
+
│
|
|
59
|
+
├──► [Stage 1: Downscaled CPU Motion Gatekeeper]
|
|
60
|
+
│ • Sub-2ms frame evaluation on CPU via 320p grayscale differencing
|
|
61
|
+
│ • Rejects camera sensor noise, exposure flickers, and static intervals
|
|
62
|
+
│ • Automated webcam sensor warmup & 1-frame settling tail capture
|
|
63
|
+
│
|
|
64
|
+
├──► [Stage 2: Temporal-Peak Keyframe Sampler]
|
|
65
|
+
│ • Pins event onset (first motion) and termination (settled action)
|
|
66
|
+
│ • Stratified bucket sampling combining motion energy (60%) + visual diversity (40%)
|
|
67
|
+
│
|
|
68
|
+
├──► [Stage 3: Active ROI Auto-Cropper]
|
|
69
|
+
│ • Computes union bounding box over entire motion trajectory
|
|
70
|
+
│ • Applies contextual padding with edge-aware minimum ROI size clamping
|
|
71
|
+
│
|
|
72
|
+
└──► [Stage 4: Structured Storyboard Packer]
|
|
73
|
+
• Assembles RxC composite image grid with uniform gutters
|
|
74
|
+
• Burns chronological relative timestamps and optional A1-D4 spatial overlays
|
|
75
|
+
• Outputs ready-to-prompt PIL.Image, raw bytes, or base64 data URIs
|
|
76
|
+
```
|
|
77
|
+
|
|
78
|
+
---
|
|
79
|
+
|
|
80
|
+
## Installation
|
|
81
|
+
|
|
82
|
+
```bash
|
|
83
|
+
pip install vlm-sieve
|
|
84
|
+
```
|
|
85
|
+
|
|
86
|
+
### Core Dependency Guardrails
|
|
87
|
+
`vlm-sieve` is engineered for ultra-lean edge and cloud deployment. Core dependencies are strictly limited to `numpy`, `opencv-python-headless`, `Pillow`, and `pydantic`. **Zero heavy deep-learning frameworks (PyTorch, TensorFlow, Transformers) are installed or required.**
|
|
88
|
+
|
|
89
|
+
---
|
|
90
|
+
|
|
91
|
+
## Quickstart Code Examples
|
|
92
|
+
|
|
93
|
+
### 1. Basic 5-Line Python SDK
|
|
94
|
+
|
|
95
|
+
```python
|
|
96
|
+
from vlmsieve import VideoSieve
|
|
97
|
+
|
|
98
|
+
# Works with local video files, RTSP/HTTP streams, or webcam index (0)
|
|
99
|
+
sieve = VideoSieve("warehouse_cam.mp4", grid_layout=(2, 3), spatial_grid_overlay=True)
|
|
100
|
+
|
|
101
|
+
for event in sieve.stream_events():
|
|
102
|
+
print(f"Captured Event #{event.event_id} ({event.raw_frame_count} frames)")
|
|
103
|
+
# Save storyboard directly to disk or send to VLM
|
|
104
|
+
event.save(f"event_{event.event_id}.jpg")
|
|
105
|
+
|
|
106
|
+
report = sieve.get_savings_report()
|
|
107
|
+
print(f"Tokens saved: {report.tokens_saved_pct:.1f}% ({report.compression_ratio:.1f}x compression)")
|
|
108
|
+
```
|
|
109
|
+
|
|
110
|
+
---
|
|
111
|
+
|
|
112
|
+
### 2. Google Gemini (`google-genai`) Integration
|
|
113
|
+
|
|
114
|
+
Pass storyboard PIL images directly to Google Gemini 2.0 / 1.5 Flash:
|
|
115
|
+
|
|
116
|
+
```python
|
|
117
|
+
from google import genai
|
|
118
|
+
from vlmsieve import VideoSieve
|
|
119
|
+
|
|
120
|
+
client = genai.Client()
|
|
121
|
+
sieve = VideoSieve("security_feed.mp4", spatial_grid_overlay=True)
|
|
122
|
+
|
|
123
|
+
for event in sieve.stream_events():
|
|
124
|
+
prompt = (
|
|
125
|
+
"Analyze this chronological 2x3 video storyboard. Each tile has a relative timestamp badge "
|
|
126
|
+
"and a 4x4 spatial grid (rows A-D, columns 1-4). "
|
|
127
|
+
"Describe what occurred, noting exact grid coordinates and timestamps."
|
|
128
|
+
)
|
|
129
|
+
|
|
130
|
+
response = client.models.generate_content(
|
|
131
|
+
model="gemini-2.0-flash",
|
|
132
|
+
contents=[event.storyboard_pil, prompt]
|
|
133
|
+
)
|
|
134
|
+
print(f"Gemini Analysis for Event #{event.event_id}:\n{response.text}\n")
|
|
135
|
+
```
|
|
136
|
+
|
|
137
|
+
---
|
|
138
|
+
|
|
139
|
+
### 3. OpenAI (`gpt-4o` / `gpt-4o-mini`) Integration
|
|
140
|
+
|
|
141
|
+
Encode the storyboard to a base64 Data URI for OpenAI's Chat Completions API:
|
|
142
|
+
|
|
143
|
+
```python
|
|
144
|
+
from openai import OpenAI
|
|
145
|
+
from vlmsieve import VideoSieve
|
|
146
|
+
|
|
147
|
+
client = OpenAI()
|
|
148
|
+
sieve = VideoSieve("traffic_cam.mp4", spatial_grid_overlay=True)
|
|
149
|
+
|
|
150
|
+
for event in sieve.stream_events():
|
|
151
|
+
response = client.chat.completions.create(
|
|
152
|
+
model="gpt-4o",
|
|
153
|
+
messages=[
|
|
154
|
+
{
|
|
155
|
+
"role": "user",
|
|
156
|
+
"content": [
|
|
157
|
+
{
|
|
158
|
+
"type": "text",
|
|
159
|
+
"text": "Identify any safety incidents in this 6-panel storyboard.",
|
|
160
|
+
},
|
|
161
|
+
{
|
|
162
|
+
"type": "image_url",
|
|
163
|
+
"image_url": {"url": event.to_data_uri(format="JPEG", quality=88)},
|
|
164
|
+
},
|
|
165
|
+
],
|
|
166
|
+
}
|
|
167
|
+
],
|
|
168
|
+
)
|
|
169
|
+
print(response.choices[0].message.content)
|
|
170
|
+
```
|
|
171
|
+
|
|
172
|
+
---
|
|
173
|
+
|
|
174
|
+
### 4. Non-Blocking Async Streaming (FastAPI / Agent Loops)
|
|
175
|
+
|
|
176
|
+
```python
|
|
177
|
+
import asyncio
|
|
178
|
+
from vlmsieve import VideoSieve
|
|
179
|
+
|
|
180
|
+
async def live_monitoring_agent():
|
|
181
|
+
sieve = VideoSieve("rtsp://admin:pass@192.168.1.50/stream")
|
|
182
|
+
|
|
183
|
+
# astream_events runs CPU frame gating on worker threads without blocking asyncio
|
|
184
|
+
async for event in sieve.astream_events():
|
|
185
|
+
print(f"New event #{event.event_id} captured at {event.start_time_sec:.1f}s")
|
|
186
|
+
# Trigger background webhook, alerts, or asynchronous LLM calls
|
|
187
|
+
await dispatch_vlm_task(event.to_bytes())
|
|
188
|
+
|
|
189
|
+
asyncio.run(live_monitoring_agent())
|
|
190
|
+
```
|
|
191
|
+
|
|
192
|
+
---
|
|
193
|
+
|
|
194
|
+
## Command-Line Interface (CLI)
|
|
195
|
+
|
|
196
|
+
`vlm-sieve` ships with a command-line tool `vlmsieve`:
|
|
197
|
+
|
|
198
|
+
```bash
|
|
199
|
+
# Process video into 2x3 storyboards with spatial coordinate grid
|
|
200
|
+
vlmsieve warehouse.mp4 --output-dir ./events --grid 2x3 --spatial-grid
|
|
201
|
+
|
|
202
|
+
# Inspect live webcam feed (index 0) with higher sensitivity threshold
|
|
203
|
+
vlmsieve 0 --threshold 0.01 --max-frames 300 -o ./webcam_events
|
|
204
|
+
|
|
205
|
+
# Process RTSP feed with full frames (disable active ROI cropping)
|
|
206
|
+
vlmsieve "rtsp://camera.local/live" --no-crop -o ./rtsp_events
|
|
207
|
+
```
|
|
208
|
+
|
|
209
|
+
### Sample CLI Output
|
|
210
|
+
```
|
|
211
|
+
============================================================
|
|
212
|
+
vlm-sieve Processing Summary
|
|
213
|
+
============================================================
|
|
214
|
+
Raw Frames Inspected : 1,800
|
|
215
|
+
Storyboards Emitted : 4
|
|
216
|
+
Frames Dropped : 1,776
|
|
217
|
+
Naive Token Estimate : 2,016,000
|
|
218
|
+
Sieve Token Estimate : 4,480
|
|
219
|
+
Compression Ratio : 450.0x
|
|
220
|
+
Token Savings : 99.78%
|
|
221
|
+
============================================================
|
|
222
|
+
Output Directory : C:\Users\user\Documents\events
|
|
223
|
+
Total Events Saved : 4
|
|
224
|
+
============================================================
|
|
225
|
+
```
|
|
226
|
+
|
|
227
|
+
---
|
|
228
|
+
|
|
229
|
+
## `SieveConfig` Reference Guide
|
|
230
|
+
|
|
231
|
+
Every hyperparameter can be fine-tuned via `SieveConfig`:
|
|
232
|
+
|
|
233
|
+
| Parameter | Type | Default | Description |
|
|
234
|
+
|:---|:---:|:---:|:---|
|
|
235
|
+
| `downscale_width` | `int` | `320` | Downscaled frame width for motion evaluation. Guarantees sub-2ms CPU gating latency. |
|
|
236
|
+
| `motion_threshold` | `float` | `0.015` | Minimum fraction of moving pixels to trigger an active motion state. |
|
|
237
|
+
| `pixel_diff_threshold` | `int` | `25` | Pixel intensity delta threshold in $[0, 255]$ for frame differencing. |
|
|
238
|
+
| `min_contour_area` | `int` | `16` | Minimum contour area in downscaled pixels required to eliminate sensor noise. |
|
|
239
|
+
| `cooldown_frames` | `int` | `12` | Static frames required after motion ceases before closing an event. |
|
|
240
|
+
| `min_event_frames` | `int` | `3` | Minimum motion frames required to emit an event (rejects single-frame flicker). |
|
|
241
|
+
| `max_event_frames` | `int` | `150` | Maximum frames in a single event buffer before flushing to prevent unbounded latency. |
|
|
242
|
+
| `grid_layout` | `tuple[int, int]` | `(2, 3)` | Storyboard grid layout specified as `(rows, cols)` (e.g., `(2, 3)` or `(3, 3)`). |
|
|
243
|
+
| `auto_crop_roi` | `bool` | `True` | Automatically detect and crop the active motion region across the action trajectory. |
|
|
244
|
+
| `roi_padding_ratio` | `float` | `0.15` | Symmetrical padding ratio added around the motion bounding box. |
|
|
245
|
+
| `min_roi_size` | `int` | `224` | Minimum cropped ROI width and height, preserving framing for small objects. |
|
|
246
|
+
| `burn_timestamps` | `bool` | `True` | Burn relative elapsed timestamp badges (`#1 \| +0.00s`) onto each tile. |
|
|
247
|
+
| `spatial_grid_overlay` | `bool` | `False` | Render a $4 \times 4$ spatial grid (`A1`–`D4`) across each tile for coordinate grounding. |
|
|
248
|
+
| `tile_max_width` | `int` | `640` | Maximum pixel width per tile before proportional Lanczos downscaling. |
|
|
249
|
+
| `tokens_per_image` | `int` | `1120` | Standard VLM image tile token cost used to compute savings reports. |
|
|
250
|
+
| `camera_warmup_frames` | `int` | `8` | Number of initial frames discarded when opening live webcams for exposure stabilization. |
|
|
251
|
+
|
|
252
|
+
---
|
|
253
|
+
|
|
254
|
+
## Performance & Benchmarks
|
|
255
|
+
|
|
256
|
+
- **CPU Frame Gating Latency:** `< 2.5ms` per 1080p frame and `< 1.2ms` per 720p frame on single-core standard x86_64 CPUs.
|
|
257
|
+
- **Zero GPU Memory:** All downscaling, differencing, and morphological operations execute within CPU L2/L3 cache without requiring CUDA or GPU buffers.
|
|
258
|
+
- **Token Compression:** Typically compresses continuous video by **95% to 99%**, translating directly to a 20x to 100x reduction in API costs.
|
|
259
|
+
|
|
260
|
+
---
|
|
261
|
+
|
|
262
|
+
## License
|
|
263
|
+
|
|
264
|
+
This project is licensed under the terms of the [MIT License](LICENSE).
|