videoxplainer 0.3.3__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- videoxplainer-0.3.3/.github/ISSUE_TEMPLATE/bug_report.md +12 -0
- videoxplainer-0.3.3/.github/workflows/ci.yml +32 -0
- videoxplainer-0.3.3/.github/workflows/publish.yml +21 -0
- videoxplainer-0.3.3/.gitignore +11 -0
- videoxplainer-0.3.3/CHANGELOG.md +42 -0
- videoxplainer-0.3.3/CONTRIBUTING.md +13 -0
- videoxplainer-0.3.3/LICENSE +21 -0
- videoxplainer-0.3.3/PKG-INFO +172 -0
- videoxplainer-0.3.3/README.md +147 -0
- videoxplainer-0.3.3/SECURITY.md +8 -0
- videoxplainer-0.3.3/docs/brand/logo-icon-1024.png +0 -0
- videoxplainer-0.3.3/docs/brand/logo-icon-128.png +0 -0
- videoxplainer-0.3.3/docs/brand/logo-icon-512.png +0 -0
- videoxplainer-0.3.3/docs/brand/logo-icon.svg +22 -0
- videoxplainer-0.3.3/docs/brand/logo-lockup-dark.png +0 -0
- videoxplainer-0.3.3/docs/brand/logo-lockup-light.png +0 -0
- videoxplainer-0.3.3/docs/brand/social-preview.png +0 -0
- videoxplainer-0.3.3/docs/demo.gif +0 -0
- videoxplainer-0.3.3/pyproject.toml +43 -0
- videoxplainer-0.3.3/src/videoxplainer/__init__.py +3 -0
- videoxplainer-0.3.3/src/videoxplainer/__main__.py +3 -0
- videoxplainer-0.3.3/src/videoxplainer/budget.py +198 -0
- videoxplainer-0.3.3/src/videoxplainer/captions.py +132 -0
- videoxplainer-0.3.3/src/videoxplainer/chapters.py +126 -0
- videoxplainer-0.3.3/src/videoxplainer/cli.py +303 -0
- videoxplainer-0.3.3/src/videoxplainer/data/SKILL.md +19 -0
- videoxplainer-0.3.3/src/videoxplainer/fetch.py +91 -0
- videoxplainer-0.3.3/src/videoxplainer/ids.py +31 -0
- videoxplainer-0.3.3/src/videoxplainer/localfile.py +90 -0
- videoxplainer-0.3.3/src/videoxplainer/model.py +62 -0
- videoxplainer-0.3.3/src/videoxplainer/normalize.py +86 -0
- videoxplainer-0.3.3/src/videoxplainer/pipeline.py +21 -0
- videoxplainer-0.3.3/src/videoxplainer/render.py +83 -0
- videoxplainer-0.3.3/src/videoxplainer/selfcheck.py +82 -0
- videoxplainer-0.3.3/src/videoxplainer/store.py +114 -0
- videoxplainer-0.3.3/src/videoxplainer/textutil.py +23 -0
- videoxplainer-0.3.3/src/videoxplainer/verify.py +76 -0
- videoxplainer-0.3.3/tests/conftest.py +21 -0
- videoxplainer-0.3.3/tests/test_chapters.py +248 -0
- videoxplainer-0.3.3/tests/test_fetch_cli.py +121 -0
- videoxplainer-0.3.3/tests/test_ids_captions.py +78 -0
- videoxplainer-0.3.3/tests/test_local_skill.py +94 -0
- videoxplainer-0.3.3/tests/test_normalize_budget.py +80 -0
- videoxplainer-0.3.3/tests/test_robustness.py +140 -0
- videoxplainer-0.3.3/tests/test_store_verify_render.py +89 -0
|
@@ -0,0 +1,12 @@
|
|
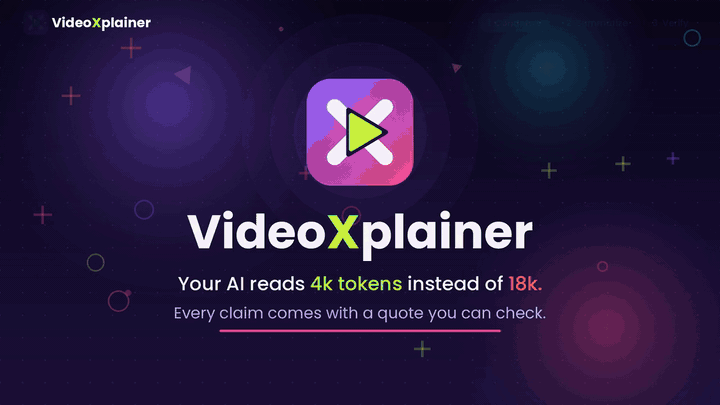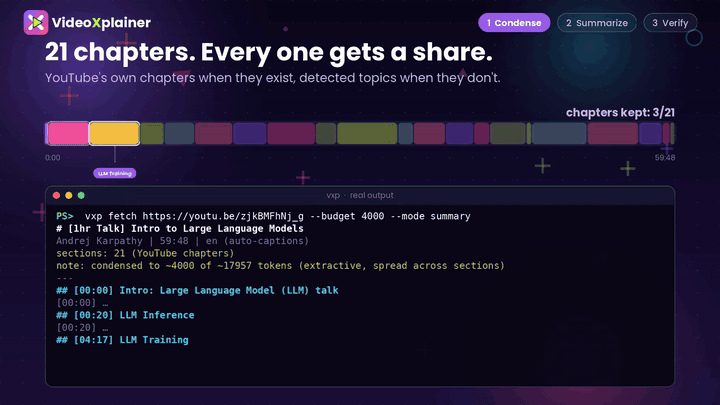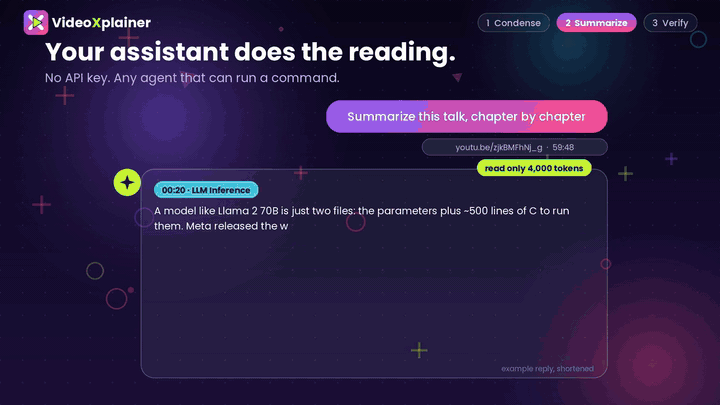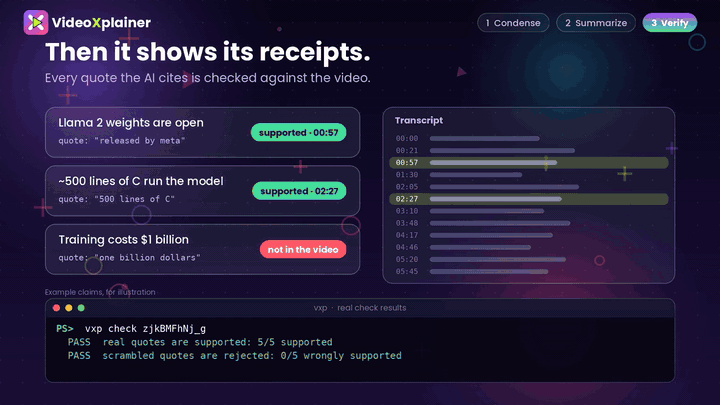
|
1
|
+
---
|
|
2
|
+
name: Bug report
|
|
3
|
+
about: Something failed or looks wrong
|
|
4
|
+
---
|
|
5
|
+
|
|
6
|
+
**Command you ran**
|
|
7
|
+
|
|
8
|
+
**What you expected / what happened** (paste the error text)
|
|
9
|
+
|
|
10
|
+
**`videoxplainer doctor` output**
|
|
11
|
+
|
|
12
|
+
**Video type** (chaptered? auto-captions or uploaded? language? Shorts/live?)
|
|
@@ -0,0 +1,32 @@
|
|
|
1
|
+
name: ci
|
|
2
|
+
on: [push, pull_request]
|
|
3
|
+
jobs:
|
|
4
|
+
test:
|
|
5
|
+
runs-on: ${{ matrix.os }}
|
|
6
|
+
strategy:
|
|
7
|
+
fail-fast: false
|
|
8
|
+
matrix:
|
|
9
|
+
os: [ubuntu-latest, windows-latest, macos-latest]
|
|
10
|
+
python: ["3.11", "3.12", "3.14"]
|
|
11
|
+
steps:
|
|
12
|
+
- uses: actions/checkout@v4
|
|
13
|
+
- uses: actions/setup-python@v5
|
|
14
|
+
with:
|
|
15
|
+
python-version: ${{ matrix.python }}
|
|
16
|
+
- run: python -m pip install -e ".[dev]"
|
|
17
|
+
- run: python -m pytest -q
|
|
18
|
+
- run: python -m videoxplainer --version
|
|
19
|
+
package:
|
|
20
|
+
runs-on: ubuntu-latest
|
|
21
|
+
steps:
|
|
22
|
+
- uses: actions/checkout@v4
|
|
23
|
+
- uses: actions/setup-python@v5
|
|
24
|
+
with:
|
|
25
|
+
python-version: "3.12"
|
|
26
|
+
- run: python -m pip install build twine
|
|
27
|
+
- run: python -m build
|
|
28
|
+
- run: twine check dist/*
|
|
29
|
+
- name: smoke-test the built wheel
|
|
30
|
+
run: |
|
|
31
|
+
python -m pip install dist/*.whl
|
|
32
|
+
videoxplainer doctor
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
name: publish
|
|
2
|
+
# One-time setup: on pypi.org add a "trusted publisher" for this repo + workflow
|
|
3
|
+
# (project name, owner, repo, workflow "publish.yml", environment "pypi").
|
|
4
|
+
on:
|
|
5
|
+
push:
|
|
6
|
+
tags: ["v*"]
|
|
7
|
+
jobs:
|
|
8
|
+
pypi:
|
|
9
|
+
runs-on: ubuntu-latest
|
|
10
|
+
environment: pypi
|
|
11
|
+
permissions:
|
|
12
|
+
id-token: write
|
|
13
|
+
contents: read
|
|
14
|
+
steps:
|
|
15
|
+
- uses: actions/checkout@v4
|
|
16
|
+
- uses: actions/setup-python@v5
|
|
17
|
+
with:
|
|
18
|
+
python-version: "3.12"
|
|
19
|
+
- run: python -m pip install build
|
|
20
|
+
- run: python -m build
|
|
21
|
+
- uses: pypa/gh-action-pypi-publish@release/v1
|
|
@@ -0,0 +1,42 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
## 0.3.3
|
|
4
|
+
- Requires Python 3.11 or newer. Current yt-dlp needs 3.11+, and older Pythons would be stuck on a frozen, outdated yt-dlp that YouTube changes will break.
|
|
5
|
+
- README: corrected the language-support note (real vs synthetic test data).
|
|
6
|
+
|
|
7
|
+
## 0.3.2
|
|
8
|
+
- Cleaner auto-detected section headings (no contractions or conversational filler).
|
|
9
|
+
- `check` prints full error messages (including the list of available caption languages).
|
|
10
|
+
|
|
11
|
+
## 0.3.1
|
|
12
|
+
- New: `fetch --no-chapters` ignores YouTube's chapters and detects topics from the text.
|
|
13
|
+
- `check` also benchmarks topic auto-detection against a video's real chapters (information only).
|
|
14
|
+
|
|
15
|
+
## 0.3.0
|
|
16
|
+
- New: `videoxplainer install-skill` installs the Claude Code skill in one command (`--dir`, `--force`, `--print`).
|
|
17
|
+
- New: local transcript files (`.srt .vtt .json3 .txt .md`) work with `fetch`, `verify` and `check`; plain text without timestamps gets estimated ones.
|
|
18
|
+
- New: `vxp` is a short alias for the `videoxplainer` command.
|
|
19
|
+
- `--lang` is now strict: you never silently get another language or a machine translation; the error lists what is available. The library re-fetches when you ask for a different language than the one stored.
|
|
20
|
+
- Library upgrades itself automatically (new column), no action needed.
|
|
21
|
+
- Topic auto-detection only cuts at significant shifts, so long topics aren't split in pieces and a uniform talk stays whole.
|
|
22
|
+
|
|
23
|
+
## 0.2.2
|
|
24
|
+
- Fix: section detection, passage ranking and `verify` only understood Latin letters, so Hindi/Tamil/other non-Latin captions were handled poorly. Now Unicode-aware.
|
|
25
|
+
- Token estimates are conservative for non-Latin scripts, so budgets aren't overshot.
|
|
26
|
+
- New: `videoxplainer check <url>...` self-tests the pipeline on real videos.
|
|
27
|
+
- `videoxplainer doctor` warns when yt-dlp is more than 90 days old.
|
|
28
|
+
- CI also builds the package and smoke-tests the installed command.
|
|
29
|
+
|
|
30
|
+
## 0.2.1
|
|
31
|
+
- Fix: condensed briefs no longer include meaningless fragments; a section with nothing worth quoting is dropped instead of padded.
|
|
32
|
+
|
|
33
|
+
## 0.2.0
|
|
34
|
+
- Chapter-aware condensing: every YouTube chapter (or auto-detected topic) gets a share of the token budget.
|
|
35
|
+
- Views: `--view chapters|excerpts|raw`. Modes: `--mode text|summary|actions`.
|
|
36
|
+
- Library now stores chapter markers (older libraries upgrade automatically; use `--refresh` once per video).
|
|
37
|
+
|
|
38
|
+
## 0.1.1
|
|
39
|
+
- Fix: tiny fragments selected on small budgets; timeline coverage kept on small budgets.
|
|
40
|
+
|
|
41
|
+
## 0.1.0
|
|
42
|
+
- First release: token-budgeted briefs, `verify` (quote check), local full-text search, Windows/macOS/Linux CI.
|
|
@@ -0,0 +1,13 @@
|
|
|
1
|
+
# Contributing
|
|
2
|
+
|
|
3
|
+
Small, focused PRs are welcome.
|
|
4
|
+
|
|
5
|
+
```bash
|
|
6
|
+
git clone https://github.com/narayan-govindaraj/videoXplainer && cd videoXplainer
|
|
7
|
+
python -m pip install -e ".[dev]"
|
|
8
|
+
python -m pytest -q
|
|
9
|
+
```
|
|
10
|
+
|
|
11
|
+
- Tests must not touch the network (see `tests/test_fetch_cli.py` for the fake yt-dlp pattern).
|
|
12
|
+
- Keep dependencies at zero beyond yt-dlp; that is a feature.
|
|
13
|
+
- Bug reports: include the output of `videoxplainer doctor` and the exact command. For caption-download failures, say whether you used cookies.
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Narayan Govindaraj
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,172 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: videoxplainer
|
|
3
|
+
Version: 0.3.3
|
|
4
|
+
Summary: Turn YouTube videos into token-budgeted, evidence-checked action briefs for LLMs.
|
|
5
|
+
Project-URL: Homepage, https://github.com/narayan-govindaraj/videoXplainer
|
|
6
|
+
Project-URL: Issues, https://github.com/narayan-govindaraj/videoXplainer/issues
|
|
7
|
+
Project-URL: Changelog, https://github.com/narayan-govindaraj/videoXplainer/blob/main/CHANGELOG.md
|
|
8
|
+
Author: Narayan Govindaraj
|
|
9
|
+
License-Expression: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Keywords: chapters,claude,llm,mcp,summary,token,transcript,youtube,yt-dlp
|
|
12
|
+
Classifier: Development Status :: 4 - Beta
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
15
|
+
Classifier: Operating System :: MacOS
|
|
16
|
+
Classifier: Operating System :: Microsoft :: Windows
|
|
17
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
18
|
+
Classifier: Programming Language :: Python :: 3
|
|
19
|
+
Classifier: Topic :: Multimedia :: Video
|
|
20
|
+
Requires-Python: >=3.11
|
|
21
|
+
Requires-Dist: yt-dlp>=2025.1.1
|
|
22
|
+
Provides-Extra: dev
|
|
23
|
+
Requires-Dist: pytest>=7; extra == 'dev'
|
|
24
|
+
Description-Content-Type: text/markdown
|
|
25
|
+
|
|
26
|
+
<p align="center">
|
|
27
|
+
<picture>
|
|
28
|
+
<source media="(prefers-color-scheme: dark)" srcset="https://raw.githubusercontent.com/narayan-govindaraj/videoXplainer/main/docs/brand/logo-lockup-dark.png">
|
|
29
|
+
<img src="https://raw.githubusercontent.com/narayan-govindaraj/videoXplainer/main/docs/brand/logo-lockup-light.png" alt="VideoXplainer" width="440">
|
|
30
|
+
</picture>
|
|
31
|
+
</p>
|
|
32
|
+
|
|
33
|
+
**Your AI reads 4k tokens instead of 18k, and every claim comes with a quote you can check.**
|
|
34
|
+
|
|
35
|
+
[](https://github.com/narayan-govindaraj/videoXplainer/actions)
|
|
36
|
+

|
|
37
|
+

|
|
38
|
+
|
|
39
|
+
Most "YouTube summarizer" tools paste the whole transcript into your chat. That burns your context window, and nothing stops the model from inventing points the video never made.
|
|
40
|
+
|
|
41
|
+
videoxplainer sits between the video and your assistant (Claude Code, Claude Desktop, any agent that can run a command):
|
|
42
|
+
|
|
43
|
+
- **Condenses by chapter, to a token budget you choose.** Every chapter keeps a share, so the end of the video isn't dropped.
|
|
44
|
+
- **Makes claims checkable.** Ask for actions *with verbatim quotes*, then `videoxplainer verify` confirms each quote really appears in the video, and where.
|
|
45
|
+
- **Needs no API key and no LLM of its own.** Your assistant does the reading; videoxplainer does the plumbing. One `pipx install`, no Node, no compiler.
|
|
46
|
+
|
|
47
|
+
|
|
48
|
+
|
|
49
|
+
## See it work
|
|
50
|
+
|
|
51
|
+
The animation above wraps motion graphics around this real run on a public 1-hour talk (59:48). Transcript passages are elided, and the assistant reply and claim cards in the animation are illustrative examples:
|
|
52
|
+
|
|
53
|
+
```text
|
|
54
|
+
$ videoxplainer fetch zjkBMFhNj_g --budget 4000 --mode summary
|
|
55
|
+
|
|
56
|
+
# [1hr Talk] Intro to Large Language Models
|
|
57
|
+
Andrej Karpathy | 59:48 | en (auto-captions)
|
|
58
|
+
sections: 21 (YouTube chapters)
|
|
59
|
+
note: condensed to ~3994 of ~17957 tokens (extractive, spread across sections)
|
|
60
|
+
---
|
|
61
|
+
## [00:20] LLM Inference
|
|
62
|
+
[00:29] ...
|
|
63
|
+
## [25:43] LLM Scaling Laws
|
|
64
|
+
[25:44] ...
|
|
65
|
+
## [46:14] Jailbreaks
|
|
66
|
+
[46:33] ...
|
|
67
|
+
---
|
|
68
|
+
TASK: for each "##" heading above write 1-2 sentences on its main point ...
|
|
69
|
+
```
|
|
70
|
+
|
|
71
|
+
About 17.9k tokens become about 4k, spread over all 21 chapters. Your assistant reads that and writes the chapter-by-chapter summary. No chapters on the video? videoxplainer detects topic shifts from the text instead.
|
|
72
|
+
|
|
73
|
+
Then check the model's work (illustrative output):
|
|
74
|
+
|
|
75
|
+
```text
|
|
76
|
+
$ videoxplainer verify VIDEO_ID claims.json
|
|
77
|
+
{ "checked": 3, "supported": 2, "weak": 0, "unsupported": 1,
|
|
78
|
+
"items": [
|
|
79
|
+
{ "index": 0, "status": "supported", "matched_at": "01:05", "link": "https://youtu.be/VIDEO_ID?t=65" },
|
|
80
|
+
{ "index": 1, "status": "supported", "matched_at": "02:10", "link": "https://youtu.be/VIDEO_ID?t=130" },
|
|
81
|
+
{ "index": 2, "status": "unsupported" } ] }
|
|
82
|
+
```
|
|
83
|
+
|
|
84
|
+
Unsupported means the quote the model cited isn't in the video: drop or fix that point.
|
|
85
|
+
|
|
86
|
+
## How it compares
|
|
87
|
+
|
|
88
|
+
| | **videoxplainer** | [youtube-summarize](https://pypi.org/project/youtube-summarize/) (MCP) | [didntwatch](https://github.com/ewro/didntwatch) | [fabric](https://github.com/danielmiessler/fabric) | [martino-summarize](https://pypi.org/project/martino-summarize/) |
|
|
89
|
+
|---|---|---|---|---|---|
|
|
90
|
+
| Needs an LLM API key | **No** | No | No | Yes | Yes (bring your own) |
|
|
91
|
+
| You set a token budget | **Yes** | - | - | - | Yes (optional LLM prefilter) |
|
|
92
|
+
| Chapter-aware condensing | **Yes** | metadata only | - | - | - |
|
|
93
|
+
| Checks the model's quotes against the video | **Yes** | - | - | - | - |
|
|
94
|
+
| Windows install documented | Yes | Yes | no (Linux/macOS) | Yes | Yes |
|
|
95
|
+
| Sources beyond YouTube | local subtitle/transcript files | - | - | articles, files, audio/video files | **11+** |
|
|
96
|
+
| Speech-to-text fallback | - (roadmap) | - | - | Yes (OpenAI API) | **Whisper** |
|
|
97
|
+
| Runtime | Python 3.11+ | Python 3.13+, uv | Claude Code skill | Go binary | Python or Docker |
|
|
98
|
+
|
|
99
|
+
`-` means I found nothing in the README or code (I read each project's repository in November 2026). Found a mistake? Please open an issue.
|
|
100
|
+
|
|
101
|
+
Notes on the table:
|
|
102
|
+
- The closest thing to a token budget elsewhere is martino-summarize's optional prefilter (default: keep 35% of each chunk, scored by an LLM). fabric's `--maxTokens` and martino's `max-tokens` cap the *output*, not what your assistant has to read.
|
|
103
|
+
- didntwatch tells the model to stay grounded in the transcript (a prompt rule); nothing checks it afterwards. martino's "Fact Checker" prompt checks claims against outside sources, not quotes against the video.
|
|
104
|
+
|
|
105
|
+
Pick **martino-summarize** if you want a full self-hosted pipeline that calls its own LLM and covers many platforms. Pick **fabric** if you live in prompt "patterns". Pick **videoxplainer** if you want your own assistant to do the reading with the fewest tokens and verifiable claims.
|
|
106
|
+
|
|
107
|
+
## Install
|
|
108
|
+
|
|
109
|
+
```bash
|
|
110
|
+
pipx install videoxplainer
|
|
111
|
+
videoxplainer doctor # checks your setup (`vxp` is a short alias for the same command)
|
|
112
|
+
```
|
|
113
|
+
|
|
114
|
+
Windows: `py -m pip install videoxplainer`, then run it as `py -m videoxplainer ...` if `videoxplainer` isn't on your PATH.
|
|
115
|
+
Until the first PyPI release: `pipx install git+https://github.com/narayan-govindaraj/videoXplainer`.
|
|
116
|
+
|
|
117
|
+
With Claude Code, run `videoxplainer install-skill` (it writes one file, `~/.claude/skills/videoxplainer/SKILL.md`, and tells you where), restart Claude Code, then paste a video link. Other agents: `videoxplainer install-skill --print` shows the instructions to paste into theirs. Claude Desktop needs an MCP server, which is on the roadmap.
|
|
118
|
+
|
|
119
|
+
## Use
|
|
120
|
+
|
|
121
|
+
Choose **what you see** with `--view`, and **what the assistant should do** with `--mode`:
|
|
122
|
+
|
|
123
|
+
| `--view` | You get |
|
|
124
|
+
|---|---|
|
|
125
|
+
| `chapters` (default) | condensed passages grouped under chapter / topic headings |
|
|
126
|
+
| `excerpts` | condensed key passages only, flat |
|
|
127
|
+
| `raw` | captions exactly as downloaded, unfiltered |
|
|
128
|
+
|
|
129
|
+
| `--mode` | Task appended for the assistant |
|
|
130
|
+
|---|---|
|
|
131
|
+
| `text` (default) | none, just the content |
|
|
132
|
+
| `summary` | a summary (one per chapter in the chapters view) |
|
|
133
|
+
| `actions` | evidence-backed actions, checkable with `videoxplainer verify` |
|
|
134
|
+
|
|
135
|
+
```bash
|
|
136
|
+
videoxplainer fetch "https://youtu.be/VIDEO_ID" --view chapters --mode summary --budget 4000
|
|
137
|
+
videoxplainer fetch VIDEO_ID --mode actions # then: videoxplainer verify VIDEO_ID claims.json
|
|
138
|
+
videoxplainer fetch VIDEO_ID --view raw # everything, untouched
|
|
139
|
+
videoxplainer search "pricing advice" # across everything you've fetched
|
|
140
|
+
videoxplainer fetch weekly-sync.vtt --mode summary # a meeting or podcast transcript on disk
|
|
141
|
+
```
|
|
142
|
+
|
|
143
|
+
**Your own transcripts.** Point `fetch` (and `verify`, `check`) at a `.srt`, `.vtt`, `.json3`, `.txt` or `.md` file: meeting exports, podcast transcripts, subtitles you downloaded. Text files with leading timestamps (`[00:12:30] ...`) keep them; files with none get timestamps estimated from word count, and the output says so. Nothing leaves your machine.
|
|
144
|
+
|
|
145
|
+
`--full` gives the complete cleaned transcript with no limit. `--refresh` re-downloads (once per video fetched before v0.2, to pick up chapter markers).
|
|
146
|
+
|
|
147
|
+
Something off on a video? Run `videoxplainer check <url>`: it tests the whole pipeline on that video (budget respected, every section represented, quotes verifiable) and its output makes a great bug report.
|
|
148
|
+
|
|
149
|
+
If YouTube asks you to prove you're not a bot: `--cookies-from-browser firefox` (Chrome/Edge cookie import is unreliable on Windows) or `--cookies-file cookies.txt`.
|
|
150
|
+
|
|
151
|
+
## Limits, honestly
|
|
152
|
+
|
|
153
|
+
- Online sources: YouTube only for now, and the video needs captions (no speech-to-text yet). Local files must already be text.
|
|
154
|
+
- Condensing is extractive and lossy by design. Use `--full` or `--view raw` when every word matters.
|
|
155
|
+
- Auto-detected sections are a heuristic. YouTube's own chapters are used whenever they exist. On two real talks with known chapters, detection from the text alone put 6 of 11 cuts within a minute of a real chapter start and recovered 7 of 25 real chapter starts; its headings are keyword lists (summary mode asks your assistant to rename them). Run `videoxplainer check <url>` to see how it does on your video.
|
|
156
|
+
- `verify` proves a quote exists in the video. It can't tell you the advice is good.
|
|
157
|
+
- Token counts are conservative estimates (about 4 characters per token for Latin text, heavier for other scripts).
|
|
158
|
+
- Tested on real English, Bengali, Arabic and Bulgarian captions, and on synthetic Hindi and Tamil text. Chinese, Japanese and Thai aren't word-segmented, so section detection and quote matching may be weaker there.
|
|
159
|
+
- YouTube changes things; if caption downloads break, update yt-dlp first (`pip install -U yt-dlp`).
|
|
160
|
+
- Use it for your own research and respect creators' rights and YouTube's terms.
|
|
161
|
+
|
|
162
|
+
## Roadmap
|
|
163
|
+
|
|
164
|
+
- [x] v0.1 budgeted briefs, `verify`, local search
|
|
165
|
+
- [x] v0.2 chapter-aware condensing, three views, summary mode
|
|
166
|
+
- [x] v0.3 `install-skill`, local transcript files
|
|
167
|
+
- [ ] v0.4 `videoxplainer channel <url> --since 7d` digests, MCP server (Claude Desktop, Cursor)
|
|
168
|
+
- [ ] v0.5 ask your library with receipts, cross-video agreements/disagreements, optional free local speech-to-text (faster-whisper), more platforms via yt-dlp
|
|
169
|
+
|
|
170
|
+
## Credits and license
|
|
171
|
+
|
|
172
|
+
MIT. Built on [yt-dlp](https://github.com/yt-dlp/yt-dlp) (Unlicense) for caption retrieval. Developed with AI assistance (Claude).
|
|
@@ -0,0 +1,147 @@
|
|
|
1
|
+
<p align="center">
|
|
2
|
+
<picture>
|
|
3
|
+
<source media="(prefers-color-scheme: dark)" srcset="https://raw.githubusercontent.com/narayan-govindaraj/videoXplainer/main/docs/brand/logo-lockup-dark.png">
|
|
4
|
+
<img src="https://raw.githubusercontent.com/narayan-govindaraj/videoXplainer/main/docs/brand/logo-lockup-light.png" alt="VideoXplainer" width="440">
|
|
5
|
+
</picture>
|
|
6
|
+
</p>
|
|
7
|
+
|
|
8
|
+
**Your AI reads 4k tokens instead of 18k, and every claim comes with a quote you can check.**
|
|
9
|
+
|
|
10
|
+
[](https://github.com/narayan-govindaraj/videoXplainer/actions)
|
|
11
|
+

|
|
12
|
+

|
|
13
|
+
|
|
14
|
+
Most "YouTube summarizer" tools paste the whole transcript into your chat. That burns your context window, and nothing stops the model from inventing points the video never made.
|
|
15
|
+
|
|
16
|
+
videoxplainer sits between the video and your assistant (Claude Code, Claude Desktop, any agent that can run a command):
|
|
17
|
+
|
|
18
|
+
- **Condenses by chapter, to a token budget you choose.** Every chapter keeps a share, so the end of the video isn't dropped.
|
|
19
|
+
- **Makes claims checkable.** Ask for actions *with verbatim quotes*, then `videoxplainer verify` confirms each quote really appears in the video, and where.
|
|
20
|
+
- **Needs no API key and no LLM of its own.** Your assistant does the reading; videoxplainer does the plumbing. One `pipx install`, no Node, no compiler.
|
|
21
|
+
|
|
22
|
+

|
|
23
|
+
|
|
24
|
+
## See it work
|
|
25
|
+
|
|
26
|
+
The animation above wraps motion graphics around this real run on a public 1-hour talk (59:48). Transcript passages are elided, and the assistant reply and claim cards in the animation are illustrative examples:
|
|
27
|
+
|
|
28
|
+
```text
|
|
29
|
+
$ videoxplainer fetch zjkBMFhNj_g --budget 4000 --mode summary
|
|
30
|
+
|
|
31
|
+
# [1hr Talk] Intro to Large Language Models
|
|
32
|
+
Andrej Karpathy | 59:48 | en (auto-captions)
|
|
33
|
+
sections: 21 (YouTube chapters)
|
|
34
|
+
note: condensed to ~3994 of ~17957 tokens (extractive, spread across sections)
|
|
35
|
+
---
|
|
36
|
+
## [00:20] LLM Inference
|
|
37
|
+
[00:29] ...
|
|
38
|
+
## [25:43] LLM Scaling Laws
|
|
39
|
+
[25:44] ...
|
|
40
|
+
## [46:14] Jailbreaks
|
|
41
|
+
[46:33] ...
|
|
42
|
+
---
|
|
43
|
+
TASK: for each "##" heading above write 1-2 sentences on its main point ...
|
|
44
|
+
```
|
|
45
|
+
|
|
46
|
+
About 17.9k tokens become about 4k, spread over all 21 chapters. Your assistant reads that and writes the chapter-by-chapter summary. No chapters on the video? videoxplainer detects topic shifts from the text instead.
|
|
47
|
+
|
|
48
|
+
Then check the model's work (illustrative output):
|
|
49
|
+
|
|
50
|
+
```text
|
|
51
|
+
$ videoxplainer verify VIDEO_ID claims.json
|
|
52
|
+
{ "checked": 3, "supported": 2, "weak": 0, "unsupported": 1,
|
|
53
|
+
"items": [
|
|
54
|
+
{ "index": 0, "status": "supported", "matched_at": "01:05", "link": "https://youtu.be/VIDEO_ID?t=65" },
|
|
55
|
+
{ "index": 1, "status": "supported", "matched_at": "02:10", "link": "https://youtu.be/VIDEO_ID?t=130" },
|
|
56
|
+
{ "index": 2, "status": "unsupported" } ] }
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
Unsupported means the quote the model cited isn't in the video: drop or fix that point.
|
|
60
|
+
|
|
61
|
+
## How it compares
|
|
62
|
+
|
|
63
|
+
| | **videoxplainer** | [youtube-summarize](https://pypi.org/project/youtube-summarize/) (MCP) | [didntwatch](https://github.com/ewro/didntwatch) | [fabric](https://github.com/danielmiessler/fabric) | [martino-summarize](https://pypi.org/project/martino-summarize/) |
|
|
64
|
+
|---|---|---|---|---|---|
|
|
65
|
+
| Needs an LLM API key | **No** | No | No | Yes | Yes (bring your own) |
|
|
66
|
+
| You set a token budget | **Yes** | - | - | - | Yes (optional LLM prefilter) |
|
|
67
|
+
| Chapter-aware condensing | **Yes** | metadata only | - | - | - |
|
|
68
|
+
| Checks the model's quotes against the video | **Yes** | - | - | - | - |
|
|
69
|
+
| Windows install documented | Yes | Yes | no (Linux/macOS) | Yes | Yes |
|
|
70
|
+
| Sources beyond YouTube | local subtitle/transcript files | - | - | articles, files, audio/video files | **11+** |
|
|
71
|
+
| Speech-to-text fallback | - (roadmap) | - | - | Yes (OpenAI API) | **Whisper** |
|
|
72
|
+
| Runtime | Python 3.11+ | Python 3.13+, uv | Claude Code skill | Go binary | Python or Docker |
|
|
73
|
+
|
|
74
|
+
`-` means I found nothing in the README or code (I read each project's repository in November 2026). Found a mistake? Please open an issue.
|
|
75
|
+
|
|
76
|
+
Notes on the table:
|
|
77
|
+
- The closest thing to a token budget elsewhere is martino-summarize's optional prefilter (default: keep 35% of each chunk, scored by an LLM). fabric's `--maxTokens` and martino's `max-tokens` cap the *output*, not what your assistant has to read.
|
|
78
|
+
- didntwatch tells the model to stay grounded in the transcript (a prompt rule); nothing checks it afterwards. martino's "Fact Checker" prompt checks claims against outside sources, not quotes against the video.
|
|
79
|
+
|
|
80
|
+
Pick **martino-summarize** if you want a full self-hosted pipeline that calls its own LLM and covers many platforms. Pick **fabric** if you live in prompt "patterns". Pick **videoxplainer** if you want your own assistant to do the reading with the fewest tokens and verifiable claims.
|
|
81
|
+
|
|
82
|
+
## Install
|
|
83
|
+
|
|
84
|
+
```bash
|
|
85
|
+
pipx install videoxplainer
|
|
86
|
+
videoxplainer doctor # checks your setup (`vxp` is a short alias for the same command)
|
|
87
|
+
```
|
|
88
|
+
|
|
89
|
+
Windows: `py -m pip install videoxplainer`, then run it as `py -m videoxplainer ...` if `videoxplainer` isn't on your PATH.
|
|
90
|
+
Until the first PyPI release: `pipx install git+https://github.com/narayan-govindaraj/videoXplainer`.
|
|
91
|
+
|
|
92
|
+
With Claude Code, run `videoxplainer install-skill` (it writes one file, `~/.claude/skills/videoxplainer/SKILL.md`, and tells you where), restart Claude Code, then paste a video link. Other agents: `videoxplainer install-skill --print` shows the instructions to paste into theirs. Claude Desktop needs an MCP server, which is on the roadmap.
|
|
93
|
+
|
|
94
|
+
## Use
|
|
95
|
+
|
|
96
|
+
Choose **what you see** with `--view`, and **what the assistant should do** with `--mode`:
|
|
97
|
+
|
|
98
|
+
| `--view` | You get |
|
|
99
|
+
|---|---|
|
|
100
|
+
| `chapters` (default) | condensed passages grouped under chapter / topic headings |
|
|
101
|
+
| `excerpts` | condensed key passages only, flat |
|
|
102
|
+
| `raw` | captions exactly as downloaded, unfiltered |
|
|
103
|
+
|
|
104
|
+
| `--mode` | Task appended for the assistant |
|
|
105
|
+
|---|---|
|
|
106
|
+
| `text` (default) | none, just the content |
|
|
107
|
+
| `summary` | a summary (one per chapter in the chapters view) |
|
|
108
|
+
| `actions` | evidence-backed actions, checkable with `videoxplainer verify` |
|
|
109
|
+
|
|
110
|
+
```bash
|
|
111
|
+
videoxplainer fetch "https://youtu.be/VIDEO_ID" --view chapters --mode summary --budget 4000
|
|
112
|
+
videoxplainer fetch VIDEO_ID --mode actions # then: videoxplainer verify VIDEO_ID claims.json
|
|
113
|
+
videoxplainer fetch VIDEO_ID --view raw # everything, untouched
|
|
114
|
+
videoxplainer search "pricing advice" # across everything you've fetched
|
|
115
|
+
videoxplainer fetch weekly-sync.vtt --mode summary # a meeting or podcast transcript on disk
|
|
116
|
+
```
|
|
117
|
+
|
|
118
|
+
**Your own transcripts.** Point `fetch` (and `verify`, `check`) at a `.srt`, `.vtt`, `.json3`, `.txt` or `.md` file: meeting exports, podcast transcripts, subtitles you downloaded. Text files with leading timestamps (`[00:12:30] ...`) keep them; files with none get timestamps estimated from word count, and the output says so. Nothing leaves your machine.
|
|
119
|
+
|
|
120
|
+
`--full` gives the complete cleaned transcript with no limit. `--refresh` re-downloads (once per video fetched before v0.2, to pick up chapter markers).
|
|
121
|
+
|
|
122
|
+
Something off on a video? Run `videoxplainer check <url>`: it tests the whole pipeline on that video (budget respected, every section represented, quotes verifiable) and its output makes a great bug report.
|
|
123
|
+
|
|
124
|
+
If YouTube asks you to prove you're not a bot: `--cookies-from-browser firefox` (Chrome/Edge cookie import is unreliable on Windows) or `--cookies-file cookies.txt`.
|
|
125
|
+
|
|
126
|
+
## Limits, honestly
|
|
127
|
+
|
|
128
|
+
- Online sources: YouTube only for now, and the video needs captions (no speech-to-text yet). Local files must already be text.
|
|
129
|
+
- Condensing is extractive and lossy by design. Use `--full` or `--view raw` when every word matters.
|
|
130
|
+
- Auto-detected sections are a heuristic. YouTube's own chapters are used whenever they exist. On two real talks with known chapters, detection from the text alone put 6 of 11 cuts within a minute of a real chapter start and recovered 7 of 25 real chapter starts; its headings are keyword lists (summary mode asks your assistant to rename them). Run `videoxplainer check <url>` to see how it does on your video.
|
|
131
|
+
- `verify` proves a quote exists in the video. It can't tell you the advice is good.
|
|
132
|
+
- Token counts are conservative estimates (about 4 characters per token for Latin text, heavier for other scripts).
|
|
133
|
+
- Tested on real English, Bengali, Arabic and Bulgarian captions, and on synthetic Hindi and Tamil text. Chinese, Japanese and Thai aren't word-segmented, so section detection and quote matching may be weaker there.
|
|
134
|
+
- YouTube changes things; if caption downloads break, update yt-dlp first (`pip install -U yt-dlp`).
|
|
135
|
+
- Use it for your own research and respect creators' rights and YouTube's terms.
|
|
136
|
+
|
|
137
|
+
## Roadmap
|
|
138
|
+
|
|
139
|
+
- [x] v0.1 budgeted briefs, `verify`, local search
|
|
140
|
+
- [x] v0.2 chapter-aware condensing, three views, summary mode
|
|
141
|
+
- [x] v0.3 `install-skill`, local transcript files
|
|
142
|
+
- [ ] v0.4 `videoxplainer channel <url> --since 7d` digests, MCP server (Claude Desktop, Cursor)
|
|
143
|
+
- [ ] v0.5 ask your library with receipts, cross-video agreements/disagreements, optional free local speech-to-text (faster-whisper), more platforms via yt-dlp
|
|
144
|
+
|
|
145
|
+
## Credits and license
|
|
146
|
+
|
|
147
|
+
MIT. Built on [yt-dlp](https://github.com/yt-dlp/yt-dlp) (Unlicense) for caption retrieval. Developed with AI assistance (Claude).
|
|
@@ -0,0 +1,8 @@
|
|
|
1
|
+
# Security
|
|
2
|
+
|
|
3
|
+
videoxplainer runs locally. It sends no telemetry and has no server. Network access is yt-dlp talking to YouTube.
|
|
4
|
+
|
|
5
|
+
- Browser cookies are read only if you pass `--cookies-from-browser` / `--cookies-file`, and are handed to yt-dlp, never stored by videoxplainer.
|
|
6
|
+
- Fetched captions are cached in a local SQLite file (`videoxplainer doctor` prints the path).
|
|
7
|
+
|
|
8
|
+
Report vulnerabilities privately via GitHub "Report a vulnerability" on this repository's Security tab.
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 1024 1024" width="1024" height="1024">
|
|
2
|
+
<defs>
|
|
3
|
+
<linearGradient id="bg" x1="0" y1="0" x2="1" y2="1">
|
|
4
|
+
<stop offset="0" stop-color="#7C3AED"/>
|
|
5
|
+
<stop offset="1" stop-color="#FF4D8D"/>
|
|
6
|
+
</linearGradient>
|
|
7
|
+
<radialGradient id="shine" cx="0.25" cy="0.2" r="0.7">
|
|
8
|
+
<stop offset="0" stop-color="#FFFFFF" stop-opacity="0.28"/>
|
|
9
|
+
<stop offset="1" stop-color="#FFFFFF" stop-opacity="0"/>
|
|
10
|
+
</radialGradient>
|
|
11
|
+
</defs>
|
|
12
|
+
<rect width="1024" height="1024" rx="232" fill="url(#bg)"/>
|
|
13
|
+
<rect width="1024" height="1024" rx="232" fill="url(#shine)"/>
|
|
14
|
+
<g stroke="#FFFFFF" stroke-width="150" stroke-linecap="round" fill="none">
|
|
15
|
+
<line x1="270" y1="270" x2="754" y2="754"/>
|
|
16
|
+
<line x1="754" y1="270" x2="270" y2="754"/>
|
|
17
|
+
</g>
|
|
18
|
+
<g stroke-linejoin="round" stroke-width="44">
|
|
19
|
+
<polygon points="402,300 402,724 758,512" fill="#1B0F3C" stroke="#1B0F3C" transform="translate(512 512) scale(1.0) translate(-512 -512)"/>
|
|
20
|
+
<polygon points="428,350 428,674 700,512" fill="#C6F432" stroke="#C6F432"/>
|
|
21
|
+
</g>
|
|
22
|
+
</svg>
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
@@ -0,0 +1,43 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["hatchling"]
|
|
3
|
+
build-backend = "hatchling.build"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "videoxplainer"
|
|
7
|
+
version = "0.3.3"
|
|
8
|
+
description = "Turn YouTube videos into token-budgeted, evidence-checked action briefs for LLMs."
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
license = "MIT"
|
|
11
|
+
authors = [{ name = "Narayan Govindaraj" }]
|
|
12
|
+
keywords = ["youtube", "transcript", "summary", "llm", "claude", "mcp", "token", "yt-dlp", "chapters"]
|
|
13
|
+
requires-python = ">=3.11"
|
|
14
|
+
dependencies = ["yt-dlp>=2025.1.1"]
|
|
15
|
+
classifiers = [
|
|
16
|
+
"Development Status :: 4 - Beta",
|
|
17
|
+
"Intended Audience :: Developers",
|
|
18
|
+
"License :: OSI Approved :: MIT License",
|
|
19
|
+
"Topic :: Multimedia :: Video",
|
|
20
|
+
"Programming Language :: Python :: 3",
|
|
21
|
+
"Operating System :: Microsoft :: Windows",
|
|
22
|
+
"Operating System :: MacOS",
|
|
23
|
+
"Operating System :: POSIX :: Linux",
|
|
24
|
+
]
|
|
25
|
+
|
|
26
|
+
[project.optional-dependencies]
|
|
27
|
+
dev = ["pytest>=7"]
|
|
28
|
+
|
|
29
|
+
[project.scripts]
|
|
30
|
+
videoxplainer = "videoxplainer.cli:main"
|
|
31
|
+
vxp = "videoxplainer.cli:main"
|
|
32
|
+
|
|
33
|
+
[tool.hatch.build.targets.wheel]
|
|
34
|
+
packages = ["src/videoxplainer"]
|
|
35
|
+
|
|
36
|
+
[tool.pytest.ini_options]
|
|
37
|
+
testpaths = ["tests"]
|
|
38
|
+
pythonpath = ["src"]
|
|
39
|
+
|
|
40
|
+
[project.urls]
|
|
41
|
+
Homepage = "https://github.com/narayan-govindaraj/videoXplainer"
|
|
42
|
+
Issues = "https://github.com/narayan-govindaraj/videoXplainer/issues"
|
|
43
|
+
Changelog = "https://github.com/narayan-govindaraj/videoXplainer/blob/main/CHANGELOG.md"
|