vhotseat 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- vhotseat-0.1.0/.gitignore +9 -0
- vhotseat-0.1.0/LICENSE +21 -0
- vhotseat-0.1.0/PKG-INFO +152 -0
- vhotseat-0.1.0/README.md +128 -0
- vhotseat-0.1.0/comfy-render +12 -0
- vhotseat-0.1.0/config.example.yaml +101 -0
- vhotseat-0.1.0/docs/comfyui-updates.md +99 -0
- vhotseat-0.1.0/docs/examples/vram-leak-tts-audio-suite.md +80 -0
- vhotseat-0.1.0/docs/guides/driver-authoring.md +205 -0
- vhotseat-0.1.0/docs/guides/proxy-gate.md +264 -0
- vhotseat-0.1.0/docs/guides/quickstart-strata-pi-comfyui.md +249 -0
- vhotseat-0.1.0/docs/how-it-works.md +468 -0
- vhotseat-0.1.0/docs/reference.md +220 -0
- vhotseat-0.1.0/examples/README.md +15 -0
- vhotseat-0.1.0/examples/comfyui.yaml +22 -0
- vhotseat-0.1.0/examples/ollama-proxy.yaml +28 -0
- vhotseat-0.1.0/examples/strata.yaml +32 -0
- vhotseat-0.1.0/integrations/comfyui/smoke_job.py +45 -0
- vhotseat-0.1.0/integrations/comfyui/vhotseat_guard/LICENSE +21 -0
- vhotseat-0.1.0/integrations/comfyui/vhotseat_guard/README.md +25 -0
- vhotseat-0.1.0/integrations/comfyui/vhotseat_guard/__init__.py +118 -0
- vhotseat-0.1.0/integrations/comfyui/vhotseat_guard/pyproject.toml +16 -0
- vhotseat-0.1.0/kit/README.md +38 -0
- vhotseat-0.1.0/kit/skills/comfyui-batching/SKILL.md +134 -0
- vhotseat-0.1.0/kit/skills/vhotseat-add-workload/SKILL.md +119 -0
- vhotseat-0.1.0/kit/skills/vhotseat-comfyui-update/SKILL.md +68 -0
- vhotseat-0.1.0/kit/skills/vhotseat-setup/SKILL.md +139 -0
- vhotseat-0.1.0/kit/skills/vhotseat-vram-leak/SKILL.md +102 -0
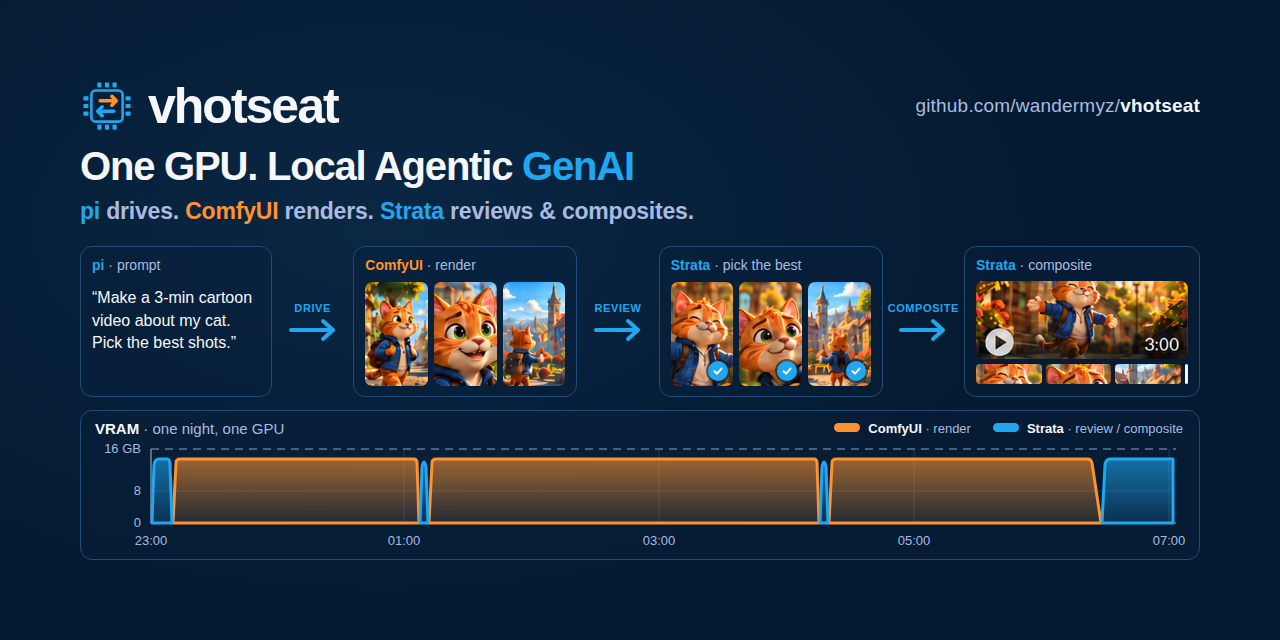
- vhotseat-0.1.0/pyproject.toml +71 -0
- vhotseat-0.1.0/src/vhotseat/__init__.py +16 -0
- vhotseat-0.1.0/src/vhotseat/api.py +89 -0
- vhotseat-0.1.0/src/vhotseat/arbiter.py +365 -0
- vhotseat-0.1.0/src/vhotseat/cli.py +130 -0
- vhotseat-0.1.0/src/vhotseat/config.py +231 -0
- vhotseat-0.1.0/src/vhotseat/doctor.py +254 -0
- vhotseat-0.1.0/src/vhotseat/drivers/__init__.py +6 -0
- vhotseat-0.1.0/src/vhotseat/drivers/base.py +134 -0
- vhotseat-0.1.0/src/vhotseat/drivers/comfyui.py +141 -0
- vhotseat-0.1.0/src/vhotseat/drivers/http.py +147 -0
- vhotseat-0.1.0/src/vhotseat/errors.py +19 -0
- vhotseat-0.1.0/src/vhotseat/events.py +35 -0
- vhotseat-0.1.0/src/vhotseat/gpu.py +216 -0
- vhotseat-0.1.0/src/vhotseat/host.py +95 -0
- vhotseat-0.1.0/src/vhotseat/kit/__init__.py +0 -0
- vhotseat-0.1.0/src/vhotseat/kit/comfy_render.py +580 -0
- vhotseat-0.1.0/src/vhotseat/lock.py +104 -0
- vhotseat-0.1.0/src/vhotseat/setup.py +50 -0
- vhotseat-0.1.0/src/vhotseat/telemetry.py +201 -0
- vhotseat-0.1.0/src/vhotseat/util.py +56 -0
- vhotseat-0.1.0/src/vhotseat/web-icon.svg +25 -0
- vhotseat-0.1.0/src/vhotseat/web.html +820 -0
- vhotseat-0.1.0/src/vhotseat/web.py +166 -0
- vhotseat-0.1.0/tests/conftest.py +50 -0
- vhotseat-0.1.0/tests/fakes.py +378 -0
- vhotseat-0.1.0/tests/run_cli.py +53 -0
- vhotseat-0.1.0/tests/test_api.py +128 -0
- vhotseat-0.1.0/tests/test_comfy_render.py +208 -0
- vhotseat-0.1.0/tests/test_examples.py +28 -0
- vhotseat-0.1.0/tests/test_handover.py +421 -0
- vhotseat-0.1.0/tests/test_phase2.py +148 -0
- vhotseat-0.1.0/tests/test_vhotseat.py +335 -0
- vhotseat-0.1.0/tests/test_web.py +174 -0
- vhotseat-0.1.0/vhotseat +13 -0
vhotseat-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 wandermyz
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
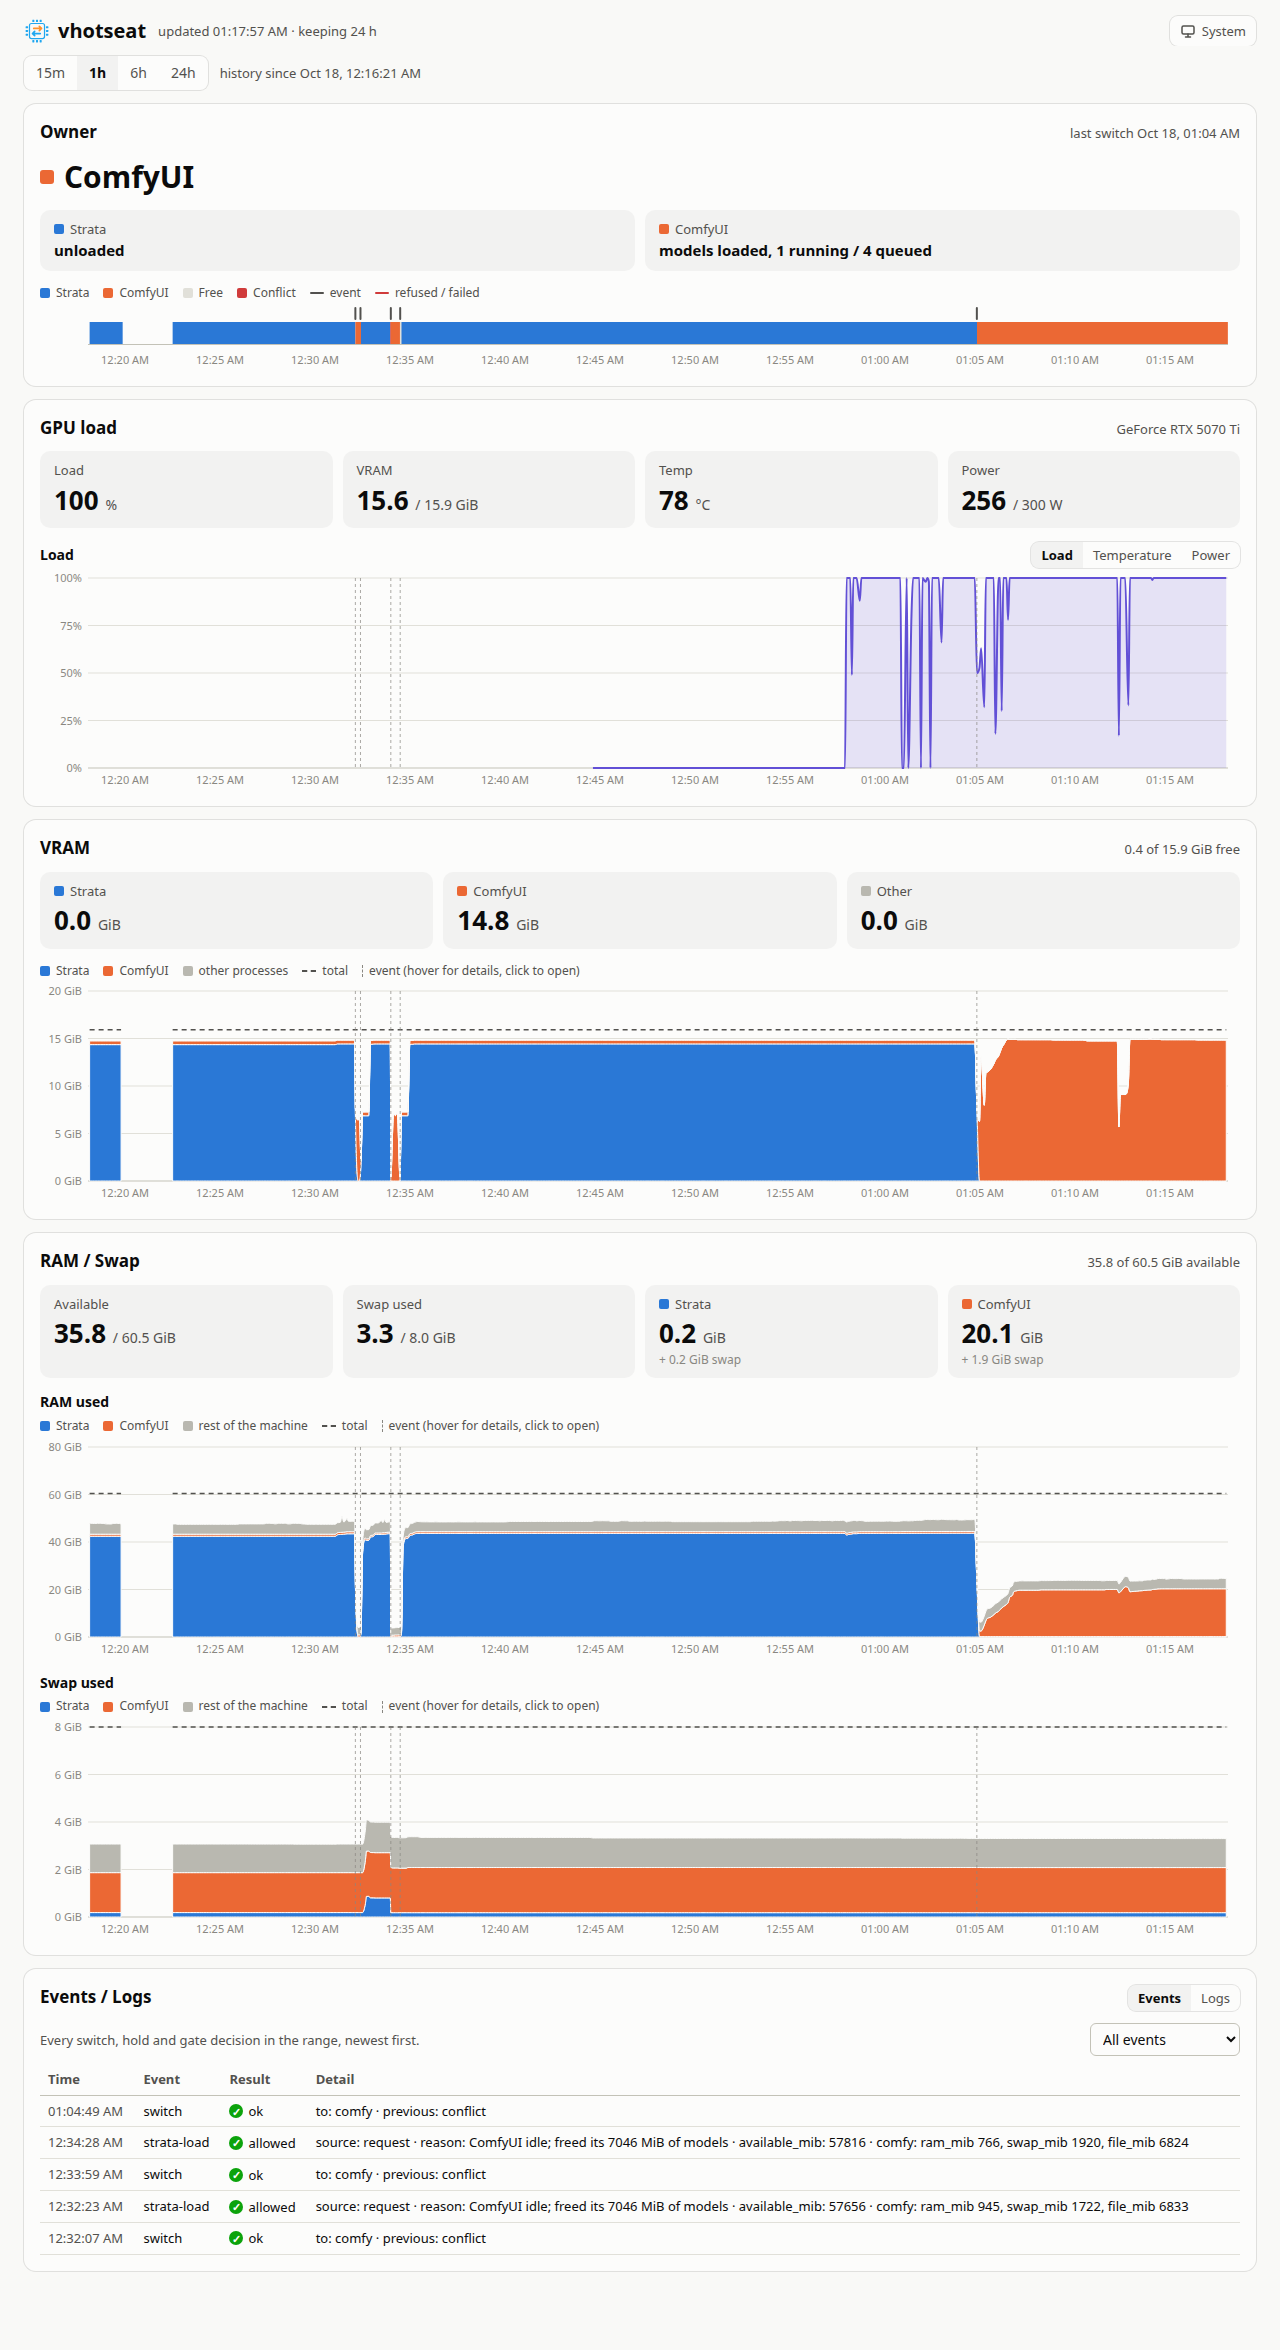
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
vhotseat-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,152 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: vhotseat
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Take turns on one GPU: hand it between a local LLM (e.g. Strata, driven by an agent like pi), ComfyUI and any other workload, never interrupting running work.
|
|
5
|
+
Project-URL: Homepage, https://github.com/wandermyz/vhotseat
|
|
6
|
+
Project-URL: Issues, https://github.com/wandermyz/vhotseat/issues
|
|
7
|
+
Author: wandermyz
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: comfyui,gpu,llm,local-llm,minimax-h3,pi-agent,scheduler,strata,vram
|
|
11
|
+
Classifier: Environment :: Console
|
|
12
|
+
Classifier: Intended Audience :: Developers
|
|
13
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
14
|
+
Classifier: Programming Language :: Python :: 3
|
|
15
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
19
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
20
|
+
Classifier: Topic :: System :: Hardware
|
|
21
|
+
Requires-Python: >=3.10
|
|
22
|
+
Requires-Dist: pyyaml>=6
|
|
23
|
+
Description-Content-Type: text/markdown
|
|
24
|
+
|
|
25
|
+
# vhotseat
|
|
26
|
+
|
|
27
|
+
[](https://github.com/wandermyz/vhotseat/actions/workflows/ci.yml)
|
|
28
|
+
[](https://github.com/wandermyz/vhotseat/releases/latest)
|
|
29
|
+
|
|
30
|
+
**Want your local LLM agent to drive ComfyUI on the same consumer graphics
|
|
31
|
+
card?** Without coordination, the first video render lands on top of the
|
|
32
|
+
loaded LLM, and something runs out of memory. **Boom, OOM!**
|
|
33
|
+
|
|
34
|
+
vhotseat makes [Strata](https://github.com/Niko1221/Strata) and
|
|
35
|
+
[ComfyUI](https://github.com/comfyanonymous/ComfyUI) take turns on VRAM *and*
|
|
36
|
+
RAM: when the agent queues a render, the LLM is unloaded; when it asks the LLM
|
|
37
|
+
its next question, ComfyUI is freed. Neither ever loads on top of the other,
|
|
38
|
+
and **running work is never interrupted**: not an answer the LLM is writing,
|
|
39
|
+
not a render in progress.
|
|
40
|
+
|
|
41
|
+
> v-hotseat: VRAM hotseat. Hot-seat multiplayer: one device, players take
|
|
42
|
+
> turns, nobody is kicked out mid-turn.
|
|
43
|
+
|
|
44
|
+
|
|
45
|
+
|
|
46
|
+
**Tested on:**
|
|
47
|
+
|
|
48
|
+
| Part | Tested with |
|
|
49
|
+
| --- | --- |
|
|
50
|
+
| GPU / RAM | RTX 5070 Ti (16 GB VRAM), 64 GB RAM |
|
|
51
|
+
| LLM | Strata serving Qwen3.8-Flash-Next IQ3_XXS (128K context) |
|
|
52
|
+
| Agent | [pi](https://github.com/earendil-works/pi) |
|
|
53
|
+
| ComfyUI | MiniMax H3 video (int8 `fl2va` / `ref2va`) |
|
|
54
|
+
|
|
55
|
+
With this setup, pi drove long-running video workflows unattended, over
|
|
56
|
+
several rounds of render → review → render, overnight.
|
|
57
|
+
|
|
58
|
+
Status: Linux, NVIDIA. Windows is designed for and planned. MIT licence.
|
|
59
|
+
|
|
60
|
+
**→ [Quick start for this exact setup](https://github.com/wandermyz/vhotseat/blob/main/docs/guides/quickstart-strata-pi-comfyui.md)**:
|
|
61
|
+
a step-by-step guide that you, or your coding agent, can follow. Or just
|
|
62
|
+
prompt your coding agent to set up the whole workflow:
|
|
63
|
+
|
|
64
|
+
> Set up vhotseat so my local LLM agent can drive ComfyUI on this GPU without
|
|
65
|
+
> running out of memory. Follow
|
|
66
|
+
> https://github.com/wandermyz/vhotseat/blob/main/docs/guides/quickstart-strata-pi-comfyui.md,
|
|
67
|
+
> adapting it to the servers and paths on this machine, and run each step's
|
|
68
|
+
> check before going on.
|
|
69
|
+
|
|
70
|
+
## How it works
|
|
71
|
+
|
|
72
|
+
The servers stay as they are, and every client is covered: the agent, its
|
|
73
|
+
scripts, a web UI, curl. Nobody calls vhotseat; each workload asks for the GPU
|
|
74
|
+
through a **gate** right before it loads, and vhotseat makes room by releasing
|
|
75
|
+
the others:
|
|
76
|
+
|
|
77
|
+
- **The LLM** runs `vhotseat gate` from its pre-load hook. While ComfyUI has
|
|
78
|
+
work queued the load is refused (a 503 the agent's harness retries).
|
|
79
|
+
- **ComfyUI** runs `vhotseat switch` before every job through a small custom
|
|
80
|
+
node, the guard. It waits for any answer the LLM is writing, then unloads it.
|
|
81
|
+
- **Admission** checks there's enough free VRAM and RAM before a load, and
|
|
82
|
+
restarts an idle ComfyUI if its leftover RAM is what's in the way.
|
|
83
|
+
- **[comfy-render](https://github.com/wandermyz/vhotseat/blob/main/kit/README.md#comfy-render)** lets the agent run a batch of
|
|
84
|
+
workflows in one call, so a batch costs two handovers instead of two per job.
|
|
85
|
+
|
|
86
|
+
Strata and ComfyUI are just the built-in examples: anything that uses the GPU
|
|
87
|
+
(another LLM server, a TTS server, a training run) can join through a config
|
|
88
|
+
entry or a small driver, with a hook, plugin, proxy or `hold` as its gate.
|
|
89
|
+
|
|
90
|
+
**How it differs.** [llama-swap](https://github.com/mostlygeek/llama-swap) and
|
|
91
|
+
Ollama's scheduler swap models between LLM servers they control; they don't
|
|
92
|
+
take turns with a non-LLM app like ComfyUI, and don't wait for a running job.
|
|
93
|
+
vhotseat arbitrates between *different* servers, of any kind, and can sit on
|
|
94
|
+
top of either (they can be one of its workloads).
|
|
95
|
+
|
|
96
|
+
## Install
|
|
97
|
+
|
|
98
|
+
```sh
|
|
99
|
+
uv tool install vhotseat # or: pipx install vhotseat
|
|
100
|
+
```
|
|
101
|
+
|
|
102
|
+
That installs two commands, `vhotseat` and `comfy-render`, with one dependency
|
|
103
|
+
(PyYAML). From a checkout, `./vhotseat` and `./comfy-render` run as they are;
|
|
104
|
+
symlink them into `~/.local/bin`.
|
|
105
|
+
|
|
106
|
+
Then set it up for your servers: follow the
|
|
107
|
+
[quick start](https://github.com/wandermyz/vhotseat/blob/main/docs/guides/quickstart-strata-pi-comfyui.md), or let a coding
|
|
108
|
+
agent do it with the [vhotseat-setup skill](https://github.com/wandermyz/vhotseat/blob/main/kit/skills/vhotseat-setup/SKILL.md).
|
|
109
|
+
[config.example.yaml](https://github.com/wandermyz/vhotseat/blob/main/config.example.yaml) is commented key by key, and
|
|
110
|
+
[examples/](https://github.com/wandermyz/vhotseat/blob/main/examples/) has configs for other servers.
|
|
111
|
+
|
|
112
|
+
```sh
|
|
113
|
+
vhotseat doctor # check the config, the GPU, every workload and gate
|
|
114
|
+
vhotseat status # who owns the GPU and what each workload holds
|
|
115
|
+
vhotseat web # dashboard: RAM and VRAM over time, handovers, events, logs
|
|
116
|
+
```
|
|
117
|
+
|
|
118
|
+
|
|
119
|
+
|
|
120
|
+
## Documentation
|
|
121
|
+
|
|
122
|
+
- [Quick start](https://github.com/wandermyz/vhotseat/blob/main/docs/guides/quickstart-strata-pi-comfyui.md): Strata + pi +
|
|
123
|
+
ComfyUI on one 16 GB card, step by step.
|
|
124
|
+
- [How it works](https://github.com/wandermyz/vhotseat/blob/main/docs/how-it-works.md): a full agent → ComfyUI → agent flow,
|
|
125
|
+
the races and deadlocks, and how often the GPU changes hands.
|
|
126
|
+
- [Reference](https://github.com/wandermyz/vhotseat/blob/main/docs/reference.md): commands, gates, admission, the ComfyUI
|
|
127
|
+
guard, `comfy-render`, the dashboard and telemetry.
|
|
128
|
+
- [Agent kit](https://github.com/wandermyz/vhotseat/blob/main/kit/README.md): `comfy-render` and
|
|
129
|
+
[Agent Skills](https://agentskills.io) for the agent that renders, and for
|
|
130
|
+
the coding agent that sets vhotseat up and keeps it working.
|
|
131
|
+
- [Writing a driver](https://github.com/wandermyz/vhotseat/blob/main/docs/guides/driver-authoring.md) for another server, and
|
|
132
|
+
[building a proxy gate](https://github.com/wandermyz/vhotseat/blob/main/docs/guides/proxy-gate.md) for one with no pre-load
|
|
133
|
+
hook.
|
|
134
|
+
- [After a ComfyUI update](https://github.com/wandermyz/vhotseat/blob/main/docs/comfyui-updates.md): checking the guard still
|
|
135
|
+
works. [Fixing a VRAM leak](https://github.com/wandermyz/vhotseat/blob/main/docs/examples/vram-leak-tts-audio-suite.md) in a
|
|
136
|
+
custom node is a worked example.
|
|
137
|
+
|
|
138
|
+
## Development
|
|
139
|
+
|
|
140
|
+
```sh
|
|
141
|
+
uv run --group dev pytest # ~2 min; fake LLM and ComfyUI servers, no GPU needed
|
|
142
|
+
uvx ruff check .
|
|
143
|
+
```
|
|
144
|
+
|
|
145
|
+
The tests run the real CLI and arbiter against fake servers over HTTP on
|
|
146
|
+
localhost; the config they use is [config.example.yaml](https://github.com/wandermyz/vhotseat/blob/main/config.example.yaml),
|
|
147
|
+
and every file in [examples/](https://github.com/wandermyz/vhotseat/blob/main/examples/) is validated. CI runs both on Python
|
|
148
|
+
3.10 to 3.13.
|
|
149
|
+
|
|
150
|
+
## Licence
|
|
151
|
+
|
|
152
|
+
MIT. See [LICENSE](https://github.com/wandermyz/vhotseat/blob/main/LICENSE).
|
vhotseat-0.1.0/README.md
ADDED
|
@@ -0,0 +1,128 @@
|
|
|
1
|
+
# vhotseat
|
|
2
|
+
|
|
3
|
+
[](https://github.com/wandermyz/vhotseat/actions/workflows/ci.yml)
|
|
4
|
+
[](https://github.com/wandermyz/vhotseat/releases/latest)
|
|
5
|
+
|
|
6
|
+
**Want your local LLM agent to drive ComfyUI on the same consumer graphics
|
|
7
|
+
card?** Without coordination, the first video render lands on top of the
|
|
8
|
+
loaded LLM, and something runs out of memory. **Boom, OOM!**
|
|
9
|
+
|
|
10
|
+
vhotseat makes [Strata](https://github.com/Niko1221/Strata) and
|
|
11
|
+
[ComfyUI](https://github.com/comfyanonymous/ComfyUI) take turns on VRAM *and*
|
|
12
|
+
RAM: when the agent queues a render, the LLM is unloaded; when it asks the LLM
|
|
13
|
+
its next question, ComfyUI is freed. Neither ever loads on top of the other,
|
|
14
|
+
and **running work is never interrupted**: not an answer the LLM is writing,
|
|
15
|
+
not a render in progress.
|
|
16
|
+
|
|
17
|
+
> v-hotseat: VRAM hotseat. Hot-seat multiplayer: one device, players take
|
|
18
|
+
> turns, nobody is kicked out mid-turn.
|
|
19
|
+
|
|
20
|
+

|
|
21
|
+
|
|
22
|
+
**Tested on:**
|
|
23
|
+
|
|
24
|
+
| Part | Tested with |
|
|
25
|
+
| --- | --- |
|
|
26
|
+
| GPU / RAM | RTX 5070 Ti (16 GB VRAM), 64 GB RAM |
|
|
27
|
+
| LLM | Strata serving Qwen3.8-Flash-Next IQ3_XXS (128K context) |
|
|
28
|
+
| Agent | [pi](https://github.com/earendil-works/pi) |
|
|
29
|
+
| ComfyUI | MiniMax H3 video (int8 `fl2va` / `ref2va`) |
|
|
30
|
+
|
|
31
|
+
With this setup, pi drove long-running video workflows unattended, over
|
|
32
|
+
several rounds of render → review → render, overnight.
|
|
33
|
+
|
|
34
|
+
Status: Linux, NVIDIA. Windows is designed for and planned. MIT licence.
|
|
35
|
+
|
|
36
|
+
**→ [Quick start for this exact setup](docs/guides/quickstart-strata-pi-comfyui.md)**:
|
|
37
|
+
a step-by-step guide that you, or your coding agent, can follow. Or just
|
|
38
|
+
prompt your coding agent to set up the whole workflow:
|
|
39
|
+
|
|
40
|
+
> Set up vhotseat so my local LLM agent can drive ComfyUI on this GPU without
|
|
41
|
+
> running out of memory. Follow
|
|
42
|
+
> https://github.com/wandermyz/vhotseat/blob/main/docs/guides/quickstart-strata-pi-comfyui.md,
|
|
43
|
+
> adapting it to the servers and paths on this machine, and run each step's
|
|
44
|
+
> check before going on.
|
|
45
|
+
|
|
46
|
+
## How it works
|
|
47
|
+
|
|
48
|
+
The servers stay as they are, and every client is covered: the agent, its
|
|
49
|
+
scripts, a web UI, curl. Nobody calls vhotseat; each workload asks for the GPU
|
|
50
|
+
through a **gate** right before it loads, and vhotseat makes room by releasing
|
|
51
|
+
the others:
|
|
52
|
+
|
|
53
|
+
- **The LLM** runs `vhotseat gate` from its pre-load hook. While ComfyUI has
|
|
54
|
+
work queued the load is refused (a 503 the agent's harness retries).
|
|
55
|
+
- **ComfyUI** runs `vhotseat switch` before every job through a small custom
|
|
56
|
+
node, the guard. It waits for any answer the LLM is writing, then unloads it.
|
|
57
|
+
- **Admission** checks there's enough free VRAM and RAM before a load, and
|
|
58
|
+
restarts an idle ComfyUI if its leftover RAM is what's in the way.
|
|
59
|
+
- **[comfy-render](kit/README.md#comfy-render)** lets the agent run a batch of
|
|
60
|
+
workflows in one call, so a batch costs two handovers instead of two per job.
|
|
61
|
+
|
|
62
|
+
Strata and ComfyUI are just the built-in examples: anything that uses the GPU
|
|
63
|
+
(another LLM server, a TTS server, a training run) can join through a config
|
|
64
|
+
entry or a small driver, with a hook, plugin, proxy or `hold` as its gate.
|
|
65
|
+
|
|
66
|
+
**How it differs.** [llama-swap](https://github.com/mostlygeek/llama-swap) and
|
|
67
|
+
Ollama's scheduler swap models between LLM servers they control; they don't
|
|
68
|
+
take turns with a non-LLM app like ComfyUI, and don't wait for a running job.
|
|
69
|
+
vhotseat arbitrates between *different* servers, of any kind, and can sit on
|
|
70
|
+
top of either (they can be one of its workloads).
|
|
71
|
+
|
|
72
|
+
## Install
|
|
73
|
+
|
|
74
|
+
```sh
|
|
75
|
+
uv tool install vhotseat # or: pipx install vhotseat
|
|
76
|
+
```
|
|
77
|
+
|
|
78
|
+
That installs two commands, `vhotseat` and `comfy-render`, with one dependency
|
|
79
|
+
(PyYAML). From a checkout, `./vhotseat` and `./comfy-render` run as they are;
|
|
80
|
+
symlink them into `~/.local/bin`.
|
|
81
|
+
|
|
82
|
+
Then set it up for your servers: follow the
|
|
83
|
+
[quick start](docs/guides/quickstart-strata-pi-comfyui.md), or let a coding
|
|
84
|
+
agent do it with the [vhotseat-setup skill](kit/skills/vhotseat-setup/SKILL.md).
|
|
85
|
+
[config.example.yaml](config.example.yaml) is commented key by key, and
|
|
86
|
+
[examples/](examples/) has configs for other servers.
|
|
87
|
+
|
|
88
|
+
```sh
|
|
89
|
+
vhotseat doctor # check the config, the GPU, every workload and gate
|
|
90
|
+
vhotseat status # who owns the GPU and what each workload holds
|
|
91
|
+
vhotseat web # dashboard: RAM and VRAM over time, handovers, events, logs
|
|
92
|
+
```
|
|
93
|
+
|
|
94
|
+

|
|
95
|
+
|
|
96
|
+
## Documentation
|
|
97
|
+
|
|
98
|
+
- [Quick start](docs/guides/quickstart-strata-pi-comfyui.md): Strata + pi +
|
|
99
|
+
ComfyUI on one 16 GB card, step by step.
|
|
100
|
+
- [How it works](docs/how-it-works.md): a full agent → ComfyUI → agent flow,
|
|
101
|
+
the races and deadlocks, and how often the GPU changes hands.
|
|
102
|
+
- [Reference](docs/reference.md): commands, gates, admission, the ComfyUI
|
|
103
|
+
guard, `comfy-render`, the dashboard and telemetry.
|
|
104
|
+
- [Agent kit](kit/README.md): `comfy-render` and
|
|
105
|
+
[Agent Skills](https://agentskills.io) for the agent that renders, and for
|
|
106
|
+
the coding agent that sets vhotseat up and keeps it working.
|
|
107
|
+
- [Writing a driver](docs/guides/driver-authoring.md) for another server, and
|
|
108
|
+
[building a proxy gate](docs/guides/proxy-gate.md) for one with no pre-load
|
|
109
|
+
hook.
|
|
110
|
+
- [After a ComfyUI update](docs/comfyui-updates.md): checking the guard still
|
|
111
|
+
works. [Fixing a VRAM leak](docs/examples/vram-leak-tts-audio-suite.md) in a
|
|
112
|
+
custom node is a worked example.
|
|
113
|
+
|
|
114
|
+
## Development
|
|
115
|
+
|
|
116
|
+
```sh
|
|
117
|
+
uv run --group dev pytest # ~2 min; fake LLM and ComfyUI servers, no GPU needed
|
|
118
|
+
uvx ruff check .
|
|
119
|
+
```
|
|
120
|
+
|
|
121
|
+
The tests run the real CLI and arbiter against fake servers over HTTP on
|
|
122
|
+
localhost; the config they use is [config.example.yaml](config.example.yaml),
|
|
123
|
+
and every file in [examples/](examples/) is validated. CI runs both on Python
|
|
124
|
+
3.10 to 3.13.
|
|
125
|
+
|
|
126
|
+
## Licence
|
|
127
|
+
|
|
128
|
+
MIT. See [LICENSE](LICENSE).
|
|
@@ -0,0 +1,12 @@
|
|
|
1
|
+
#!/usr/bin/env python3
|
|
2
|
+
"""comfy-render from a checkout (installed as a symlink, like ./vhotseat). See src/vhotseat/kit/comfy_render.py."""
|
|
3
|
+
|
|
4
|
+
import sys
|
|
5
|
+
from pathlib import Path
|
|
6
|
+
|
|
7
|
+
sys.path.insert(0, str(Path(__file__).resolve().parent / "src"))
|
|
8
|
+
|
|
9
|
+
from vhotseat.kit.comfy_render import main # noqa: E402
|
|
10
|
+
|
|
11
|
+
if __name__ == "__main__":
|
|
12
|
+
sys.exit(main())
|
|
@@ -0,0 +1,101 @@
|
|
|
1
|
+
# vhotseat config: ~/.config/vhotseat/config.yaml (or $VHOTSEAT_CONFIG).
|
|
2
|
+
# Two workloads on one 16 GB card: Strata (a local LLM server) and ComfyUI.
|
|
3
|
+
# Every key is commented. Change the paths, units and figures to your machine,
|
|
4
|
+
# then run `vhotseat doctor`. examples/ has one snippet per workload.
|
|
5
|
+
|
|
6
|
+
gpu:
|
|
7
|
+
index: 0
|
|
8
|
+
backend: auto # nvml (no subprocess per read), nvidia-smi, or auto (nvml, else nvidia-smi)
|
|
9
|
+
|
|
10
|
+
workloads:
|
|
11
|
+
# A workload is named here; that name is what `vhotseat switch NAME` takes.
|
|
12
|
+
strata:
|
|
13
|
+
driver: http # described entirely by HTTP requests below
|
|
14
|
+
label: Strata
|
|
15
|
+
url: http://127.0.0.1:2335
|
|
16
|
+
service: {systemd-user: strata} # started when stopped; restarted when allow_restart
|
|
17
|
+
# Its VRAM is found by the systemd unit its processes run in. Without
|
|
18
|
+
# `vram:`, the service's unit is used; {process: SUBSTRING} matches the
|
|
19
|
+
# command line instead.
|
|
20
|
+
resident: {get: /health, path: loaded} # true while its model is in VRAM
|
|
21
|
+
release:
|
|
22
|
+
post: /unload?wait={wait} # {wait}: seconds to let a running answer finish
|
|
23
|
+
always: true # ask even when it looks unloaded: a load may be under way
|
|
24
|
+
busy_when: [{status: 409}, {path: status, in: [busy]}]
|
|
25
|
+
ok_when: [{status: 200, path: status, in: [unloaded, not loaded]}]
|
|
26
|
+
# timeout: 30 # seconds the request may take on top of {wait} (default 30)
|
|
27
|
+
# pre: {post: …} # a request first, e.g. a proxy's drain (docs/guides/proxy-gate.md)
|
|
28
|
+
confirm: {vram_at_most: 0} # released once its VRAM is down to this
|
|
29
|
+
load: {post: /load, timeout: 300} # `switch strata` leaves it loaded
|
|
30
|
+
model: {get: /health, path: model} # which model it serves; picks the admission below
|
|
31
|
+
gate:
|
|
32
|
+
kind: hook # Strata runs `vhotseat gate strata` before every load
|
|
33
|
+
config: ~/Strata/strata.json # its config file, checked by doctor
|
|
34
|
+
timeout: 90 # Strata's before_load_timeout_s: the hook must fit in it
|
|
35
|
+
admission:
|
|
36
|
+
# RAM the machine must be able to give Strata before it may load: its
|
|
37
|
+
# experts plus working memory, with some headroom. Compared with
|
|
38
|
+
# *available* RAM (MemAvailable), which counts page cache the kernel can
|
|
39
|
+
# drop on demand; *free* RAM is always small on a busy machine. When
|
|
40
|
+
# other workloads still hold too much after releasing their models, idle
|
|
41
|
+
# ones with allow_restart are restarted; if that still isn't enough, the
|
|
42
|
+
# load is refused and the event log says RAM was short.
|
|
43
|
+
# This default is for a model not listed under by_model (or when Strata
|
|
44
|
+
# doesn't say which it serves): the largest one, to stay safe.
|
|
45
|
+
min_available_ram_mib: 46000
|
|
46
|
+
# VRAM that must be free on the card before Strata may load. Other
|
|
47
|
+
# workloads always release the GPU first, whatever this says; this
|
|
48
|
+
# catches what vhotseat doesn't manage (the desktop, a game, a release
|
|
49
|
+
# that left VRAM behind).
|
|
50
|
+
min_free_vram_mib: 14000
|
|
51
|
+
# Per model, as /health reports it. For example, loading from idle,
|
|
52
|
+
# IQ3_XXS took 44.5 GiB of available RAM (42.5 GiB resident, 56 GiB at the peak)
|
|
53
|
+
# IQ2_XS took 38.2 GiB (35.6 GiB resident, 47 GiB at the peak)
|
|
54
|
+
# Both use ~14.7 GB of VRAM. To measure a model: load it (`vhotseat switch
|
|
55
|
+
# strata` from idle), note how much MemAvailable dropped, add ~1.5 GiB.
|
|
56
|
+
by_model:
|
|
57
|
+
qwen3.8-flash-next-iq3_xxs: {min_available_ram_mib: 46000}
|
|
58
|
+
qwen3.8-flash-next-iq2_xs: {min_available_ram_mib: 40000}
|
|
59
|
+
allow_restart: true
|
|
60
|
+
|
|
61
|
+
comfy:
|
|
62
|
+
driver: comfyui # built-in: /queue, /free, restart when /free isn't enough
|
|
63
|
+
label: ComfyUI
|
|
64
|
+
url: http://127.0.0.1:8188
|
|
65
|
+
service: {systemd-user: comfyui}
|
|
66
|
+
idle_vram_mib: 1500 # its CUDA context and caches; above this it holds models
|
|
67
|
+
gate:
|
|
68
|
+
kind: plugin # the guard node takes the GPU before every job
|
|
69
|
+
custom_nodes: ~/ComfyUI/custom_nodes # where the guard is installed; checked by doctor
|
|
70
|
+
timeout: 300 # how long a job waits for an answer Strata is writing
|
|
71
|
+
# No admission: what ComfyUI needs depends on the workflow, and it manages
|
|
72
|
+
# its own memory. Other workloads still release the GPU before every job.
|
|
73
|
+
# Restarted when its release leaves VRAM behind, or when another
|
|
74
|
+
# workload's admission needs RAM its idle process still holds (6-15 GiB
|
|
75
|
+
# after a video render). Only when its queue is empty and its last result
|
|
76
|
+
# finished at least history_settle_s ago (a restart wipes /history).
|
|
77
|
+
allow_restart: true
|
|
78
|
+
|
|
79
|
+
# Local patches to other projects' code that a handover depends on. An update
|
|
80
|
+
# of that project drops a patch silently, and the symptom shows up far away
|
|
81
|
+
# (a release that leaves VRAM behind, so every handover is refused). `vhotseat
|
|
82
|
+
# doctor` checks each marker is still in its file, and says when the installed
|
|
83
|
+
# version has the fix upstream so the patch can go. An entry looks like:
|
|
84
|
+
#
|
|
85
|
+
# - name: TTS Audio Suite IndexTTS unload
|
|
86
|
+
# file: ~/ComfyUI/custom_nodes/TTS-Audio-Suite/engines/index_tts/indextts/infer_v2_5.py
|
|
87
|
+
# marker: "LOCAL PATCH (vhotseat)" # a comment you put next to your change
|
|
88
|
+
# doc: ~/.config/vhotseat/patches/tts-audio-suite.md # optional: what and why
|
|
89
|
+
# fixed_upstream_in: {version: 5.10.4, version_file: ~/ComfyUI/custom_nodes/TTS-Audio-Suite/pyproject.toml}
|
|
90
|
+
patches: []
|
|
91
|
+
|
|
92
|
+
events:
|
|
93
|
+
keep: 500 # ~/.local/state/vhotseat/events.jsonl
|
|
94
|
+
|
|
95
|
+
# RAM and VRAM over time, events and log lines, for `vhotseat web`. Every
|
|
96
|
+
# vhotseat command records as it runs (~/.local/state/vhotseat/telemetry.db);
|
|
97
|
+
# `vhotseat record` (or `vhotseat web`) samples between commands too.
|
|
98
|
+
telemetry:
|
|
99
|
+
# enabled: true
|
|
100
|
+
retention_hours: 24 # ~6 MiB on disk with two workloads; ~0.8 MiB a day more per further workload
|
|
101
|
+
interval_s: 5 # between samples while something samples continuously
|
|
@@ -0,0 +1,99 @@
|
|
|
1
|
+
# Handling ComfyUI updates
|
|
2
|
+
|
|
3
|
+
The guard node, `integrations/comfyui/vhotseat_guard`, makes each ComfyUI job
|
|
4
|
+
take the GPU from the other workloads before it runs. It does that by wrapping
|
|
5
|
+
a **private** ComfyUI method, `execution.PromptExecutor.execute_async`.
|
|
6
|
+
ComfyUI doesn't promise to keep that method stable, so an update can break the
|
|
7
|
+
guard. The `vhotseat-comfyui-update` skill walks an agent through this page.
|
|
8
|
+
|
|
9
|
+
Below, `$COMFY` is ComfyUI's folder and the service is a systemd user unit
|
|
10
|
+
named `comfyui`; adjust both to your setup.
|
|
11
|
+
|
|
12
|
+
## What breaks, and how you'd notice
|
|
13
|
+
|
|
14
|
+
| Change in ComfyUI | What happens | Visible as |
|
|
15
|
+
| --- | --- | --- |
|
|
16
|
+
| `execution.PromptExecutor` or `execute_async` renamed or removed | Guard turns itself **off**; ComfyUI keeps working, unguarded | `vhotseat_guard: OFF, ComfyUI internals changed` in the log at startup |
|
|
17
|
+
| `execute_async` gets new parameters | Guard is on, but every job fails with a `TypeError` | Every job errors right after you queue it |
|
|
18
|
+
| The worker stops calling `execute_async` once per job | Guard is on but never runs | Jobs run while the LLM is loaded; most likely an out-of-memory error |
|
|
19
|
+
| Fields read by `_fail_job` change (`status_messages`, `history_result`, `add_message`) | Only the failure path breaks: a refused job crashes instead of failing cleanly | Test 4 below |
|
|
20
|
+
|
|
21
|
+
The first row is the safe one. The others are why you should check after every
|
|
22
|
+
update rather than wait to notice.
|
|
23
|
+
|
|
24
|
+
## After every ComfyUI update
|
|
25
|
+
|
|
26
|
+
1. **Note the current commit, update, then restart:**
|
|
27
|
+
```sh
|
|
28
|
+
cd $COMFY && git rev-parse --short HEAD # to roll back to, if needed
|
|
29
|
+
git pull && systemctl --user restart comfyui
|
|
30
|
+
```
|
|
31
|
+
|
|
32
|
+
2. **Confirm the guard loaded and is on:**
|
|
33
|
+
```sh
|
|
34
|
+
journalctl --user -u comfyui --since "-5min" | grep vhotseat_guard
|
|
35
|
+
```
|
|
36
|
+
Expect `vhotseat_guard: on (…/vhotseat, wait 300s)`. If you see `OFF` or
|
|
37
|
+
an import error, stop here and go to *Fixing it* below.
|
|
38
|
+
|
|
39
|
+
3. **Check that the method's signature hasn't changed.** The guard mirrors it:
|
|
40
|
+
```sh
|
|
41
|
+
grep -n "async def execute_async" $COMFY/execution.py
|
|
42
|
+
```
|
|
43
|
+
Expect `async def execute_async(self, prompt, prompt_id, extra_data={}, execute_outputs=[]):`.
|
|
44
|
+
Also check that the worker still calls it once per job: `main.py` →
|
|
45
|
+
`prompt_worker` → `e.execute(...)` → `asyncio.run(self.execute_async(...))`.
|
|
46
|
+
|
|
47
|
+
4. **Run the smoke tests.** These take a couple of minutes and need a few GB
|
|
48
|
+
of VRAM. `integrations/comfyui/smoke_job.py` queues a 1-step SDXL job that
|
|
49
|
+
ends in `PreviewImage`, so nothing is written to `output/`; pass a
|
|
50
|
+
checkpoint you have with `--ckpt NAME.safetensors`. It prints
|
|
51
|
+
`success in 9.0s`, or `error in 2.5s: GPU busy, job not run: …`. The tests
|
|
52
|
+
use Strata as the LLM; for another LLM, send it the same kind of requests.
|
|
53
|
+
|
|
54
|
+
| # | Do | Expect |
|
|
55
|
+
| --- | --- | --- |
|
|
56
|
+
| 1 | `vhotseat switch strata`, then queue a job | Job succeeds; `vhotseat status` shows `comfy`, Strata unloaded |
|
|
57
|
+
| 2 | Start a long Strata answer, queue a job 2–3 s later | Strata's answer completes; job runs after it and succeeds |
|
|
58
|
+
| 3 | Queue a job, send a Strata request, queue another | Both jobs succeed; each Strata request frees ComfyUI first |
|
|
59
|
+
| 4 | `systemctl --user set-environment VHOTSEAT_GUARD_WAIT_S=2`, restart ComfyUI, start a long Strata answer, queue a job | Job ends `status: error` with `GPU busy, job not run: …` in `/history/<id>`; Strata's answer completes. Then `systemctl --user unset-environment VHOTSEAT_GUARD_WAIT_S` and restart ComfyUI |
|
|
60
|
+
| 5 | `comfy-render` a batch of 2–3 small jobs (a `{"base": …, "jobs": [seeds]}` file ending in `SaveImage`) | Progress lines while it runs, one `ok` line per job with its file, exit code 0 |
|
|
61
|
+
|
|
62
|
+
For a long Strata answer:
|
|
63
|
+
```sh
|
|
64
|
+
curl -s localhost:2335/v1/chat/completions -H 'Content-Type: application/json' \
|
|
65
|
+
-d '{"messages":[{"role":"user","content":"Count from 1 to 400."}],"max_tokens":1500}' >/dev/null &
|
|
66
|
+
```
|
|
67
|
+
|
|
68
|
+
Test 5 checks comfy-render, which reads ComfyUI's public `/history` and
|
|
69
|
+
websocket formats rather than private methods, so it breaks less often than
|
|
70
|
+
the guard, but it does depend on them.
|
|
71
|
+
|
|
72
|
+
5. **Record the commit** you verified (step 1's `git rev-parse` after the
|
|
73
|
+
pull), so the next rollback has a known-good target.
|
|
74
|
+
|
|
75
|
+
## Fixing it
|
|
76
|
+
|
|
77
|
+
- **Method renamed:** find what `prompt_worker` in `main.py` now calls per job,
|
|
78
|
+
and wrap that instead. The requirements are:
|
|
79
|
+
- it runs on the worker thread (blocking is fine there; the web server's
|
|
80
|
+
thread must never block);
|
|
81
|
+
- it runs once per job, before any model loads;
|
|
82
|
+
- you can still report a failure that shows up in `/history`.
|
|
83
|
+
- **Do not move the guard into `PromptServer.add_on_prompt_handler`.** That
|
|
84
|
+
runs at submit time, on the web server's event loop. Blocking there for up
|
|
85
|
+
to 300 s would freeze ComfyUI's UI and API.
|
|
86
|
+
- **To run unguarded until it's fixed:** set `VHOTSEAT_GUARD=0` in the
|
|
87
|
+
unit's environment (`systemctl --user edit comfyui`). Then queue ComfyUI
|
|
88
|
+
work only after running `vhotseat switch comfy` by hand.
|
|
89
|
+
|
|
90
|
+
## Rolling back ComfyUI
|
|
91
|
+
|
|
92
|
+
When a fix isn't quick, go back to the last commit the guard was verified on:
|
|
93
|
+
|
|
94
|
+
```sh
|
|
95
|
+
cd $COMFY && git log --oneline -5 # find the previous commit
|
|
96
|
+
git checkout <commit> && systemctl --user restart comfyui
|
|
97
|
+
```
|
|
98
|
+
|
|
99
|
+
The guard was last verified by the vhotseat project on ComfyUI v0.39.0.
|
|
@@ -0,0 +1,80 @@
|
|
|
1
|
+
# Example: a VRAM leak in TTS Audio Suite, from symptom to upstream fix
|
|
2
|
+
|
|
3
|
+
A worked example of the `vhotseat-vram-leak` skill. The machine shared one
|
|
4
|
+
16 GB GPU between a local LLM (Strata) and ComfyUI, with the
|
|
5
|
+
[TTS Audio Suite](https://github.com/diodiogod/TTS-Audio-Suite) custom node
|
|
6
|
+
pack rendering speech with IndexTTS-2.5. Fixed upstream in **5.10.4**
|
|
7
|
+
([PR #373](https://github.com/diodiogod/TTS-Audio-Suite/pull/373)); suite
|
|
8
|
+
versions up to 5.10.3 have the leak.
|
|
9
|
+
|
|
10
|
+
## Symptom
|
|
11
|
+
|
|
12
|
+
After an IndexTTS render, ComfyUI's `POST /free` reported "freed 4804MB", but
|
|
13
|
+
ComfyUI still held about 2 GB, above its `idle_vram_mib` of 1500. Every LLM
|
|
14
|
+
load after a TTS render was refused:
|
|
15
|
+
|
|
16
|
+
```
|
|
17
|
+
strata-load (allowed=False, reason=could not free ComfyUI's 2066 MiB:
|
|
18
|
+
timed out after 20s waiting for ComfyUI to release VRAM (below 1500 MiB))
|
|
19
|
+
```
|
|
20
|
+
|
|
21
|
+
With `allow_restart: true` vhotseat restarts ComfyUI instead, which works but
|
|
22
|
+
adds ~20 s to that handover, and the leak still costs ComfyUI 2 GB whenever its
|
|
23
|
+
own model manager swaps the TTS model out for another one.
|
|
24
|
+
|
|
25
|
+
## Diagnosis
|
|
26
|
+
|
|
27
|
+
Reproduced standalone: load IndexTTS2 the way the suite does, render once
|
|
28
|
+
under `torch.inference_mode()` (as ComfyUI does), call the suite's unload,
|
|
29
|
+
then list the `gc.get_objects()` tensors still `is_cuda`.
|
|
30
|
+
|
|
31
|
+
The suite wraps the IndexTTS2 engine (`engines/index_tts/indextts/infer_v2_5.py`)
|
|
32
|
+
for ComfyUI's model manager. On unload, the wrapper calls `model.to("cpu")` if
|
|
33
|
+
the object has a `to()`, and otherwise moves each `nn.Module` attribute one by
|
|
34
|
+
one. `IndexTTS2` had no `to()`, so only those modules moved. Left on the GPU:
|
|
35
|
+
|
|
36
|
+
| Left behind | Size |
|
|
37
|
+
| --- | --- |
|
|
38
|
+
| `qwen_emo` (QwenEmotion, a Qwen 0.6B text-to-emotion model held in a plain attribute, so never moved) | 1137 MiB |
|
|
39
|
+
| Plain tensor attributes inside modules, which `Module.to()` skips: old-style `weight_norm` weights, a `causal_mask` (64 MiB), `freqs_cis` | ~180 MiB |
|
|
40
|
+
| Cached reference-voice conditioning, emotion and speaker matrices | ~8 MiB |
|
|
41
|
+
| Allocator cache held because of the above | the rest |
|
|
42
|
+
|
|
43
|
+
## Fix
|
|
44
|
+
|
|
45
|
+
A `to(device)` method on `IndexTTS2`, which the wrapper then uses for both
|
|
46
|
+
unload and reload. It moves every model module plus the plain tensor
|
|
47
|
+
attributes inside them, QwenEmotion if loaded, and the emotion and speaker
|
|
48
|
+
matrices, and drops the cached reference-voice conditioning (rebuilt on the
|
|
49
|
+
next render).
|
|
50
|
+
|
|
51
|
+
| After a render and unload | ComfyUI VRAM |
|
|
52
|
+
| --- | --- |
|
|
53
|
+
| Before | 2066 MiB: LLM refused |
|
|
54
|
+
| **Patched** | **~340 MiB** standalone, ~500 MiB in ComfyUI |
|
|
55
|
+
| Floor: any process that has used CUDA | ~270 MiB |
|
|
56
|
+
|
|
57
|
+
## Recording it until upstream shipped it
|
|
58
|
+
|
|
59
|
+
While the fix was local, every changed spot carried `LOCAL PATCH (vhotseat)`,
|
|
60
|
+
and the config had:
|
|
61
|
+
|
|
62
|
+
```yaml
|
|
63
|
+
patches:
|
|
64
|
+
- name: TTS Audio Suite IndexTTS unload
|
|
65
|
+
file: <ComfyUI>/custom_nodes/TTS-Audio-Suite/engines/index_tts/indextts/infer_v2_5.py
|
|
66
|
+
marker: "LOCAL PATCH (vhotseat)"
|
|
67
|
+
doc: ~/.config/vhotseat/patches/tts-audio-suite.md
|
|
68
|
+
fixed_upstream_in: {version: 5.10.4, version_file: <ComfyUI>/custom_nodes/TTS-Audio-Suite/pyproject.toml}
|
|
69
|
+
```
|
|
70
|
+
|
|
71
|
+
When the suite updated to 5.10.4, `vhotseat doctor` reported that the
|
|
72
|
+
installed version had the fix upstream and the patch could go, before anyone
|
|
73
|
+
looked; the entry was then removed.
|
|
74
|
+
|
|
75
|
+
## If it comes back
|
|
76
|
+
|
|
77
|
+
Other engines in the suite are wrapped the same way, so each needs a `to()`
|
|
78
|
+
that moves everything. The symptom is the same: ComfyUI above `idle_vram_mib`
|
|
79
|
+
after `/free`, or the event log showing ComfyUI restarted because it kept VRAM
|
|
80
|
+
after `/free`, right after renders with that engine. Diagnose it the same way.
|