tunarag-python 0.3.1__tar.gz → 0.4.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/.gitignore +1 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/CHANGELOG.md +41 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/PKG-INFO +109 -49
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/README.md +107 -47
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/pyproject.toml +7 -2
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/__init__.py +1 -1
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/dataset.py +19 -3
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/domain.py +5 -2
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/engine.py +134 -151
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/evaluators.py +18 -9
- tunarag_python-0.4.0/src/tunarag/integrations/google_adk.py +233 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/integrations/mlflow.py +24 -7
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/integrations/runnables.py +162 -31
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/objective.py +12 -2
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/result.py +23 -7
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/retry.py +50 -5
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/search.py +3 -1
- tunarag_python-0.4.0/src/tunarag/serialization.py +177 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/stopping.py +9 -2
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/store.py +3 -2
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/synthetic.py +36 -3
- tunarag_python-0.3.1/src/tunarag/integrations/google_adk.py +0 -144
- tunarag_python-0.3.1/src/tunarag/serialization.py +0 -78
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/LICENSE +0 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/cache.py +0 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/config.py +0 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/contracts.py +0 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/errors.py +0 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/integrations/__init__.py +0 -0
- {tunarag_python-0.3.1 → tunarag_python-0.4.0}/src/tunarag/py.typed +0 -0
|
@@ -1,5 +1,46 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## 0.4.0 - 2026-11-21
|
|
4
|
+
|
|
5
|
+
### Fixed
|
|
6
|
+
|
|
7
|
+
- Code audit fixes (`docs/audit-2026-11-21/`), each covered by `tests/test_audit_regressions.py`:
|
|
8
|
+
- A NaN or infinite metric or cost fails only its trial instead of crashing the study.
|
|
9
|
+
- Ctrl-C/cancelled and crashed (failed) studies can be resumed; interrupted trials re-run.
|
|
10
|
+
- Token usage is captured from every chat-model call (LangChain usage callback), including
|
|
11
|
+
string-output chains such as `create_retrieval_chain`; new `token_prices` option on all
|
|
12
|
+
adapters gives an estimated cost so `CostBudget` works.
|
|
13
|
+
- Unknown cost is reported as `unavailable`, not an exact $0.
|
|
14
|
+
- Usage from failed, timed-out, and cancelled attempts is recorded.
|
|
15
|
+
- Provider timeouts, connection errors, rate limits (429), and 408/5xx errors are retryable,
|
|
16
|
+
including OpenAI, httpx, LiteLLM, and Google GenAI exceptions and wrapped causes.
|
|
17
|
+
- Without an explicit `identity`, evaluator and adapter identities include digests of
|
|
18
|
+
scorer, factory, mapper, wrapped function, graph node, and ADK agent code, and adapters
|
|
19
|
+
warn. An explicit `identity` (now also accepted by `MetricEvaluator`) is the declared
|
|
20
|
+
version and replaces the code digests.
|
|
21
|
+
- RAGAS evaluations use per-call metric copies, fixing a race that silently dropped samples.
|
|
22
|
+
- Objectives mark partial-coverage metrics `estimated`; new `ObjectiveTerm.min_coverage`.
|
|
23
|
+
- Google ADK output includes `tool_responses` (retrieval evidence); new `events_mapper`;
|
|
24
|
+
error events keep their error code.
|
|
25
|
+
- MLflow reuses one run per study across processes and reopens it on resume.
|
|
26
|
+
- Custom search-space parameters (sample/accepts/describe) work with the optimizer.
|
|
27
|
+
- `TimeBudget` counts active time across resumes; consecutive `MaxFailures` ignores
|
|
28
|
+
cancelled trials; LLMSearch replay matches a live run's history.
|
|
29
|
+
- Dataset versions ignore row order; duplicate rows report their record numbers.
|
|
30
|
+
- Synthetic generation reports every failed document; `allow_partial=True` keeps the rest.
|
|
31
|
+
- Floats and numeric strings no longer share a hash.
|
|
32
|
+
- Failed attempts log their underlying cause to the `tunarag` logger.
|
|
33
|
+
- Documentation builds require `mkdocstrings` 1.x; 0.x fails with `pymdown-extensions` 13
|
|
34
|
+
(`Highlight.__init__() missing 'md'`).
|
|
35
|
+
|
|
36
|
+
### Migration
|
|
37
|
+
|
|
38
|
+
- The audit fixes change identity hashes (dataset versions, float encoding, adapter and evaluator
|
|
39
|
+
fingerprints). Studies started with earlier versions cannot be resumed (resume raises
|
|
40
|
+
`ResumeError`), and earlier evaluation-cache entries are not reused. Completed studies and
|
|
41
|
+
reports remain readable.
|
|
42
|
+
- Pass `identity=` to every adapter to silence the new warning and version your pipeline.
|
|
43
|
+
|
|
3
44
|
## 0.3.1 - 2026-10-09
|
|
4
45
|
|
|
5
46
|
- Replace both raw Mermaid README blocks with pre-rendered PNG diagrams compatible with PyPI.
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: tunarag-python
|
|
3
|
-
Version: 0.
|
|
3
|
+
Version: 0.4.0
|
|
4
4
|
Summary: Tune LangChain, LangGraph, and Google ADK RAG pipelines
|
|
5
5
|
Project-URL: Documentation, https://shivamshinde123.github.io/tunarag-python/
|
|
6
6
|
Project-URL: Repository, https://github.com/shivamshinde123/tunarag-python
|
|
@@ -37,7 +37,7 @@ Provides-Extra: docs
|
|
|
37
37
|
Requires-Dist: mkdocs-include-markdown-plugin<8,>=7; extra == 'docs'
|
|
38
38
|
Requires-Dist: mkdocs-material<10,>=9.5; extra == 'docs'
|
|
39
39
|
Requires-Dist: mkdocs<2,>=1.6; extra == 'docs'
|
|
40
|
-
Requires-Dist: mkdocstrings[python]<1
|
|
40
|
+
Requires-Dist: mkdocstrings[python]<2,>=1; extra == 'docs'
|
|
41
41
|
Provides-Extra: frameworks
|
|
42
42
|
Requires-Dist: google-adk<3,>=2; extra == 'frameworks'
|
|
43
43
|
Requires-Dist: langchain<2,>=1; extra == 'frameworks'
|
|
@@ -102,24 +102,19 @@ indexes, provider clients, and credentials; TunaRAG owns the optimization workfl
|
|
|
102
102
|
|
|
103
103
|
**Documentation:** [shivamshinde123.github.io/tunarag-python](https://shivamshinde123.github.io/tunarag-python/)
|
|
104
104
|
|
|
105
|
+
**Usage handbook:** [Download the editable DOCX handbook](https://shivamshinde123.github.io/tunarag-python/TunaRAG_Python_Usage_Handbook.docx).
|
|
106
|
+
Start with RAG basics, then follow practical code examples for integrating your framework pipeline
|
|
107
|
+
and using advanced tuning features.
|
|
108
|
+
|
|
105
109
|
**Lightweight distribution:** pip installs runtime code and metadata, not tests, datasets,
|
|
106
110
|
or documentation images. Framework dependencies are optional extras. See
|
|
107
111
|
[package contents and release checks](https://shivamshinde123.github.io/tunarag-python/package-distribution/).
|
|
108
112
|
|
|
109
|
-
**
|
|
110
|
-
|
|
111
|
-
|
|
112
|
-
|
|
113
|
-
|
|
114
|
-
These opt-in tests include spending safeguards; normal tests never make paid calls.
|
|
115
|
-
|
|
116
|
-
**Google ADK validation:** [Real OpenRouter RAG tuning, RAGAS scoring, SQLite resume,
|
|
117
|
-
and MLflow checks](https://shivamshinde123.github.io/tunarag-python/live-google-adk-testing/).
|
|
118
|
-
|
|
119
|
-
**Quality and reliability:** [Ordered validation plan](https://shivamshinde123.github.io/tunarag-python/quality-validation-plan/)
|
|
120
|
-
and [bounded repeated tuning, ADK tools, billing and recovery checks](https://shivamshinde123.github.io/tunarag-python/reliability-validation/).
|
|
121
|
-
See [mixed-topic validation](https://shivamshinde123.github.io/tunarag-python/multicorpus-validation/) for cross-model QA,
|
|
122
|
-
simulated faults/load, and the unresolved adversarial-prompt failure.
|
|
113
|
+
**Contributor verification:** Test plans and campaign evidence remain in the
|
|
114
|
+
[repository documentation](https://github.com/shivamshinde123/tunarag-python/tree/main/docs).
|
|
115
|
+
Paid tests are explicit opt-ins; ordinary CI never makes paid provider calls.
|
|
116
|
+
The [mixed-topic validation report](https://github.com/shivamshinde123/tunarag-python/blob/main/docs/multicorpus-validation.md)
|
|
117
|
+
records known adversarial-prompt failures; tuning does not guarantee document safety.
|
|
123
118
|
|
|
124
119
|
## Comprehensive Usage Guide
|
|
125
120
|
|
|
@@ -241,7 +236,9 @@ dataset = EvaluationDataset.from_records(
|
|
|
241
236
|
)
|
|
242
237
|
optimizer = Optimizer(
|
|
243
238
|
adapter=LangChainAdapter(
|
|
244
|
-
factory=build_chain,
|
|
239
|
+
factory=build_chain,
|
|
240
|
+
input_mapper=lambda example, candidate: example.query,
|
|
241
|
+
identity={"quickstart": "offline-langchain", "revision": 1},
|
|
245
242
|
),
|
|
246
243
|
strategy=RandomSearch(SearchSpace({"top_k": IntegerRange(1, 2)}), seed=7),
|
|
247
244
|
evaluators=(
|
|
@@ -282,7 +279,7 @@ from langchain_core.runnables import RunnableLambda
|
|
|
282
279
|
from tunarag import LangChainAdapter
|
|
283
280
|
|
|
284
281
|
chain = RunnableLambda(lambda inputs: {"answer": inputs["question"]})
|
|
285
|
-
adapter = LangChainAdapter(chain)
|
|
282
|
+
adapter = LangChainAdapter(chain, identity={"chain": "echo", "revision": 1})
|
|
286
283
|
```
|
|
287
284
|
|
|
288
285
|
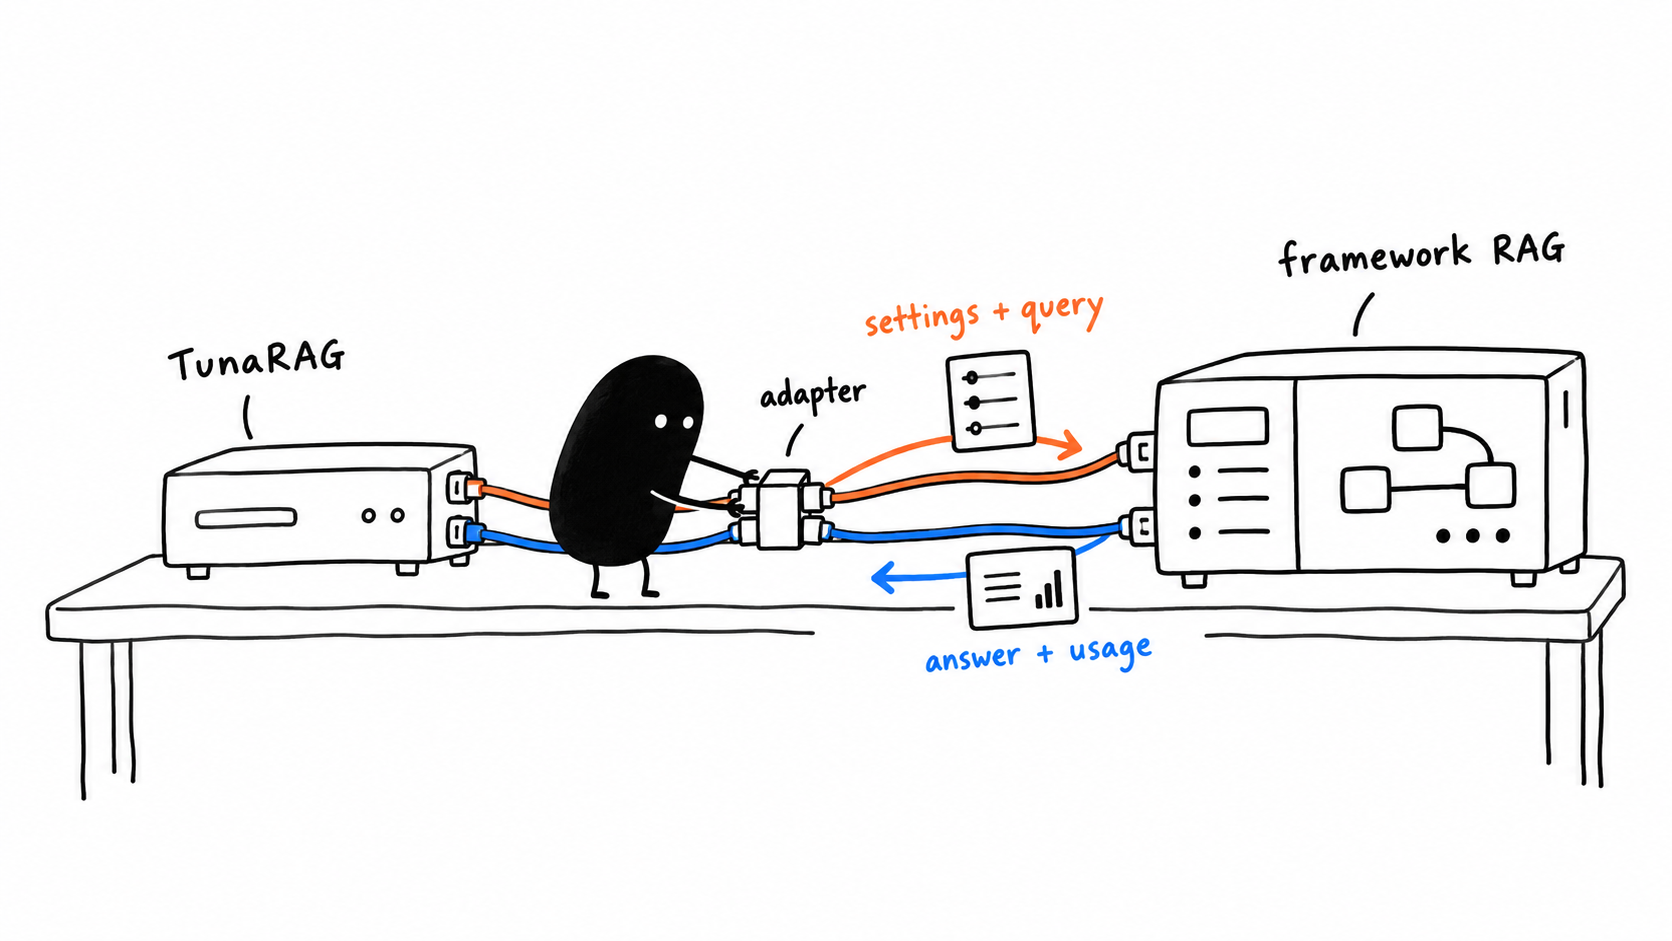
|
|
@@ -306,8 +303,14 @@ adapter = LangChainAdapter(
|
|
|
306
303
|
```
|
|
307
304
|
|
|
308
305
|
Include stable corpus, index, model, prompt, and mapper revisions in `identity` for cache and resume
|
|
309
|
-
compatibility. Never include credentials.
|
|
310
|
-
|
|
306
|
+
compatibility. Never include credentials. When you pass `identity`, it is the pipeline's
|
|
307
|
+
declared version: TunaRAG uses it (plus the names of your factory and mappers) and does not
|
|
308
|
+
fingerprint code, so bump it whenever behavior changes. An adapter without `identity` emits a
|
|
309
|
+
`UserWarning` and is identified by code structure instead (factory and mapper code, wrapped
|
|
310
|
+
`RunnableLambda` functions, LangGraph node functions, chain steps, ADK agent instruction, model and
|
|
311
|
+
tools), which cannot see prompt-text, index, or model-setting changes. Framework factories and
|
|
312
|
+
mapping callbacks remain normal Python configuration code; retrieval and generation execute through
|
|
313
|
+
the framework.
|
|
311
314
|
|
|
312
315
|
## LangChain integration
|
|
313
316
|
|
|
@@ -378,14 +381,26 @@ adapter = LangChainAdapter(
|
|
|
378
381
|
output_tokens=output["usage"]["output_tokens"],
|
|
379
382
|
),
|
|
380
383
|
),
|
|
384
|
+
identity={"chain": "support-rag", "version": 2},
|
|
381
385
|
)
|
|
382
386
|
```
|
|
383
387
|
|
|
384
|
-
|
|
385
|
-
|
|
388
|
+
By default the adapter attaches LangChain's `UsageMetadataCallbackHandler` to the run, so token
|
|
389
|
+
usage is captured from every chat-model call inside the runnable, including chains such as
|
|
390
|
+
`create_retrieval_chain` whose answer is a plain string. If no callback usage is seen (for example
|
|
391
|
+
nested calls on Python 3.10 without an explicit `config`), it falls back to discovering standard
|
|
392
|
+
`usage_metadata` in mappings, sequences, and message objects. Token records keep the component
|
|
393
|
+
name `langchain.message` (`langgraph.message` for graphs); the reported model name is used to look
|
|
394
|
+
up `token_prices`. The adapter always adds `langchain.runnable` latency. Set
|
|
386
395
|
`capture_message_usage=False` to disable automatic token extraction. A custom `usage_mapper` takes
|
|
387
396
|
precedence.
|
|
388
397
|
|
|
398
|
+
Providers do not report dollar cost to LangChain, so cost is **unavailable** unless you price it.
|
|
399
|
+
Pass `token_prices={"<model name>": (usd_per_1m_input, usd_per_1m_output)}` (keys match the
|
|
400
|
+
model name the provider reports, e.g. `"openai/gpt-4.1-mini"` through OpenRouter); priced records
|
|
401
|
+
get an `estimated` cost, which `CostBudget` counts. The same option exists on
|
|
402
|
+
`LangGraphAdapter` and `GoogleADKAdapter`.
|
|
403
|
+
|
|
389
404
|
For a complete provider-backed pipeline—from documents and embeddings through optimization and
|
|
390
405
|
reports—run
|
|
391
406
|
[`examples/langchain_full_rag.py`](https://github.com/shivamshinde123/tunarag-python/blob/main/examples/langchain_full_rag.py).
|
|
@@ -437,6 +452,7 @@ adapter = LangGraphAdapter(
|
|
|
437
452
|
},
|
|
438
453
|
config_mapper=lambda candidate: None,
|
|
439
454
|
output_mapper=lambda state: state["answer"],
|
|
455
|
+
identity={"graph": "qa", "revision": 2},
|
|
440
456
|
)
|
|
441
457
|
```
|
|
442
458
|
|
|
@@ -452,10 +468,14 @@ agent tools, corpus retrieval, and runner ownership remain with the application.
|
|
|
452
468
|
|
|
453
469
|
Use `factory=lambda candidate: build_runner(candidate)` when tuning settings such as a model or
|
|
454
470
|
retrieval tool that require constructing an agent. `state_mapper` can map candidates to agent state;
|
|
455
|
-
|
|
456
|
-
|
|
457
|
-
|
|
458
|
-
|
|
471
|
+
By default the output is `{"answer": final_text, "tool_responses": [{"name": ..., "response": ...}]}`:
|
|
472
|
+
tool results such as retrieved passages are collected from the whole run, so retrieval metrics and
|
|
473
|
+
RAGAS can see the evidence. `output_mapper` receives only the final ADK event; `events_mapper`
|
|
474
|
+
receives every event of the run (use one or the other) for custom outputs. Usage captures reported
|
|
475
|
+
model token counts and runner latency; pass `token_prices` (keyed by the event's `model_version`)
|
|
476
|
+
for an estimated cost. Missing final responses and ADK error events fail the trial rather than
|
|
477
|
+
becoming empty answers; the trial records the ADK error code, and the provider's error message is
|
|
478
|
+
logged to the console (not persisted).
|
|
459
479
|
|
|
460
480
|
See the executable [ADK example](https://github.com/shivamshinde123/tunarag-python/blob/main/examples/google_adk_tuning.py)
|
|
461
481
|
and [integration reference](https://github.com/shivamshinde123/tunarag-python/blob/main/docs/reference/integrations.md).
|
|
@@ -511,8 +531,10 @@ csv_dataset = EvaluationDataset.from_csv("evaluation.csv")
|
|
|
511
531
|
```
|
|
512
532
|
|
|
513
533
|
JSON contains an array; JSONL contains one object per nonblank line. CSV collection and metadata
|
|
514
|
-
cells are JSON-encoded. Missing IDs are deterministically derived
|
|
515
|
-
|
|
534
|
+
cells are JSON-encoded. Missing IDs are deterministically derived from the record's content, so two
|
|
535
|
+
identical rows without IDs are reported as a duplicate (with both record numbers). Every
|
|
536
|
+
`EvaluationDataset` has a content-derived `version` used by caches and resume validation; it does
|
|
537
|
+
not depend on row order.
|
|
516
538
|
|
|
517
539
|
### Deterministic splitting
|
|
518
540
|
|
|
@@ -599,7 +621,10 @@ generation_usage = generated.usage
|
|
|
599
621
|
|
|
600
622
|
`SourceSpan` is a zero-based half-open range. TunaRAG validates spans, confidence, cardinality,
|
|
601
623
|
source IDs, and usage. Generated examples carry provenance and `synthetic=True`. Review them before
|
|
602
|
-
using them as gold data. Generation usage is separate from optimization usage.
|
|
624
|
+
using them as gold data. Generation usage is separate from optimization usage. Every document is
|
|
625
|
+
attempted; if some fail, the error lists each failed document and its cause. Pass
|
|
626
|
+
`allow_partial=True` to keep the successful documents instead (failed IDs are in
|
|
627
|
+
`generated.failed_document_ids`).
|
|
603
628
|
|
|
604
629
|
## Search spaces and strategies
|
|
605
630
|
|
|
@@ -714,7 +739,13 @@ class RetrievalEvaluator:
|
|
|
714
739
|
|
|
715
740
|
`MetricEvaluator` accepts sync or async scorers. `None`, NaN, and infinity become unavailable;
|
|
716
741
|
nonnumeric values raise `EvaluationError`. Coverage must be `[0, 1]`. `tunarag.objective` is a
|
|
717
|
-
reserved metric name.
|
|
742
|
+
reserved metric name. `MetricValue` rejects NaN and infinity, so a custom evaluator that produces
|
|
743
|
+
one fails that trial (the study continues); return `None` for "no value".
|
|
744
|
+
|
|
745
|
+
Without `identity=`, a `MetricEvaluator`'s identity includes a digest of its scorer's code, so
|
|
746
|
+
editing a scorer, or swapping one lambda for another, invalidates cached scores. Pass `identity=`
|
|
747
|
+
to declare the scorer's version yourself, for example when its behavior depends on outside state
|
|
748
|
+
(files, models, thresholds read at call time); the code digest is then not used.
|
|
718
749
|
|
|
719
750
|
### RAGAS
|
|
720
751
|
|
|
@@ -737,9 +768,12 @@ ragas_evaluator = RagasEvaluator(
|
|
|
737
768
|
)
|
|
738
769
|
```
|
|
739
770
|
|
|
740
|
-
TunaRAG constructs one RAGAS `SingleTurnSample` and calls the async evaluation API.
|
|
741
|
-
the
|
|
742
|
-
|
|
771
|
+
TunaRAG constructs one RAGAS `SingleTurnSample` and calls the async evaluation API. Each call uses
|
|
772
|
+
its own copies of the metric objects, so concurrent samples cannot detach each other's judge LLM.
|
|
773
|
+
Names receive the configured prefix. Mapping and RAGAS failures become `EvaluationError`; with
|
|
774
|
+
`raise_exceptions=False`, a sample RAGAS could not score becomes unavailable and lowers the
|
|
775
|
+
metric's coverage. Use `ObjectiveTerm(..., min_coverage=1.0)` for judge metrics that must cover
|
|
776
|
+
every sample. Credentials and provider configuration remain owned by your RAGAS components.
|
|
743
777
|
|
|
744
778
|
## Objectives
|
|
745
779
|
|
|
@@ -775,7 +809,10 @@ objective = Objective(
|
|
|
775
809
|
Bounded metrics are normalized and clamped to `[0, 1]`; bounded minimize terms become
|
|
776
810
|
`1 - normalized`. Unbounded maximize terms use raw values and unbounded minimize terms use negative
|
|
777
811
|
values. Weights are contributions and are not automatically normalized. A missing or unavailable
|
|
778
|
-
required metric makes the objective unavailable
|
|
812
|
+
required metric makes the objective unavailable, and so does a metric whose coverage (the fraction
|
|
813
|
+
of samples that produced it) is below the term's `min_coverage` (default `0.0`). A metric measured
|
|
814
|
+
on only some samples makes the objective `estimated`. An unavailable objective fails the trial, not
|
|
815
|
+
the study.
|
|
779
816
|
|
|
780
817
|
Usage does not automatically become an objective metric. Emit `cost_usd` or `latency_seconds` from
|
|
781
818
|
an evaluator when you want those values in the objective.
|
|
@@ -826,6 +863,12 @@ cache_policy = "read_write"
|
|
|
826
863
|
|
|
827
864
|
Cache policies: `off`, `read_only`, `write_only`, `read_write`. Settings contain no provider keys.
|
|
828
865
|
|
|
866
|
+
`Optimizer` reads the limits, concurrency, retry, timeout, and cache-policy settings. The path
|
|
867
|
+
settings and `seed` are resolved values for your application to use: TunaRAG does not open
|
|
868
|
+
`db_path` or `cache_dir` by itself (pass `SQLiteStore(settings.db_path)` and a `SQLiteCache`, as
|
|
869
|
+
below), does not write to `artifact_dir`, and does not seed strategies from `seed` (pass
|
|
870
|
+
`RandomSearch(space, seed=settings.seed)`).
|
|
871
|
+
|
|
829
872
|
## Running optimization
|
|
830
873
|
|
|
831
874
|
Use async in async programs:
|
|
@@ -912,14 +955,16 @@ Stop conditions are OR-composed:
|
|
|
912
955
|
|---|---|
|
|
913
956
|
| `MaxTrials(limit)` | Completed trial count reaches the limit |
|
|
914
957
|
| `CostBudget(limit, count_estimated=True)` | Exact plus optional estimated cost reaches limit |
|
|
915
|
-
| `TimeBudget(seconds)` |
|
|
958
|
+
| `TimeBudget(seconds)` | Active run time (summed across resumes) reaches limit |
|
|
916
959
|
| `TargetScore(target)` | Any benefit-oriented objective reaches target |
|
|
917
960
|
| `MaxFailures(limit, consecutive=False)` | Total or trailing consecutive failures reach limit |
|
|
918
961
|
| `NoImprovement(patience, min_delta=0, warmup_trials=1)` | Best score stops improving |
|
|
919
962
|
|
|
920
963
|
Always include a hard bound. Conditions are checked between trial batches, so active trials can
|
|
921
964
|
finish after a cost, time, score, failure, or stagnation threshold is reached. Use `concurrency=1`
|
|
922
|
-
for strict between-trial stopping.
|
|
965
|
+
for strict between-trial stopping. `CostBudget` only sees priced usage: give your adapter
|
|
966
|
+
`token_prices` (or a `usage_mapper` that sets `cost`), otherwise cost is unavailable and the budget
|
|
967
|
+
never triggers. Usage from attempts that fail or time out still counts.
|
|
923
968
|
|
|
924
969
|
```python
|
|
925
970
|
from tunarag import RetryPolicy
|
|
@@ -933,9 +978,14 @@ policy = RetryPolicy(
|
|
|
933
978
|
)
|
|
934
979
|
```
|
|
935
980
|
|
|
936
|
-
Three retries means four total attempts. Timeouts
|
|
937
|
-
|
|
938
|
-
|
|
981
|
+
Three retries means four total attempts. Timeouts, connection errors, rate limits (HTTP 429), and
|
|
982
|
+
transient server errors (408 and 5xx) are retryable, including provider SDK exceptions (OpenAI,
|
|
983
|
+
httpx, LiteLLM, Google GenAI, ...) recognized by type name or HTTP status without importing those
|
|
984
|
+
SDKs, and wrapped causes. A `TunaRAGError` retries when `retryable=True` or when it wraps such a
|
|
985
|
+
transient cause; other exceptions fail that trial. Backoff is deterministic and capped. Attempt
|
|
986
|
+
usage is append-only, including failed, timed-out, and cancelled attempts. Each failed attempt is
|
|
987
|
+
logged to the `tunarag` logger with its underlying cause; persisted errors keep only the stage and
|
|
988
|
+
exception type (plus TunaRAG's own message), so third-party text never lands in SQLite or reports.
|
|
939
989
|
|
|
940
990
|
`concurrency` bounds simultaneous trials; `sample_concurrency` bounds samples inside each trial.
|
|
941
991
|
Their product approximates maximum concurrent adapter calls. Completion may be concurrent, but
|
|
@@ -961,8 +1011,9 @@ optimizer = Optimizer(
|
|
|
961
1011
|
)
|
|
962
1012
|
```
|
|
963
1013
|
|
|
964
|
-
Identity includes dataset version, candidate, adapter, and evaluators
|
|
965
|
-
|
|
1014
|
+
Identity includes dataset version, candidate, adapter, and evaluators (including digests of
|
|
1015
|
+
factory, mapper, and scorer code; see `identity` above). A hit skips adapter and evaluator execution
|
|
1016
|
+
but still calculates the objective and records the trial.
|
|
966
1017
|
|
|
967
1018
|
Direct API:
|
|
968
1019
|
|
|
@@ -1005,8 +1056,11 @@ resumed = await resumed_optimizer.aresume(dataset, study_id=result.study_id)
|
|
|
1005
1056
|
|
|
1006
1057
|
Resume validates semantic configuration and dataset identity, returns completed studies without
|
|
1007
1058
|
provider execution, abandons expired leases, replays committed strategy history, continues
|
|
1008
|
-
unfinished work, and schedules new candidates.
|
|
1009
|
-
|
|
1059
|
+
unfinished work, and schedules new candidates. Interrupted (Ctrl-C/cancelled) and crashed (failed)
|
|
1060
|
+
studies resume too: their in-flight trials are re-run. A cancellation releases its attempts at
|
|
1061
|
+
once; after a hard process kill, attempts stay leased until `trial_timeout_seconds + 60` passes,
|
|
1062
|
+
and resuming earlier raises a retryable `ResumeError`. Unknown or incompatible studies raise
|
|
1063
|
+
`ResumeError`.
|
|
1010
1064
|
|
|
1011
1065
|
Read persisted state:
|
|
1012
1066
|
|
|
@@ -1067,9 +1121,10 @@ optimizer = Optimizer(
|
|
|
1067
1121
|
)
|
|
1068
1122
|
```
|
|
1069
1123
|
|
|
1070
|
-
One MLflow run is created per study
|
|
1124
|
+
One MLflow run is created per study, also across processes: a resumed study finds its run by the
|
|
1125
|
+
`tunarag.study_id` tag and reopens it. Candidate parameters, committed metrics, statuses, and event
|
|
1071
1126
|
position are mirrored. An MLflow outage does not invalidate local results. Automatic external
|
|
1072
|
-
reconciliation is not included
|
|
1127
|
+
reconciliation of missed events is not included.
|
|
1073
1128
|
|
|
1074
1129
|
## Results and reports
|
|
1075
1130
|
|
|
@@ -1116,8 +1171,11 @@ result.write_json("artifacts/result.json")
|
|
|
1116
1171
|
result.write_csv("artifacts/trials.csv")
|
|
1117
1172
|
```
|
|
1118
1173
|
|
|
1119
|
-
Reports are deterministic and redacted. Usage separates exact and estimated cost.
|
|
1120
|
-
|
|
1174
|
+
Reports are deterministic and redacted. Usage separates exact and estimated cost; `usage.status`
|
|
1175
|
+
says how well cost is known: `exact` (every model call has an exact cost), `estimated` (some are
|
|
1176
|
+
estimated or unpriced), or `unavailable` (no cost reported, never shown as an exact $0). A
|
|
1177
|
+
completed result may have no best candidate if every trial failed or every objective was
|
|
1178
|
+
unavailable.
|
|
1121
1179
|
|
|
1122
1180
|
## Errors, privacy, and secrets
|
|
1123
1181
|
|
|
@@ -1193,7 +1251,9 @@ class EvenInteger:
|
|
|
1193
1251
|
}
|
|
1194
1252
|
```
|
|
1195
1253
|
|
|
1196
|
-
|
|
1254
|
+
Custom parameters are identified for cache and resume by their type and `describe()` output, so
|
|
1255
|
+
keep `describe()` complete and deterministic. Provider descriptions and component fingerprints must
|
|
1256
|
+
not expose secrets.
|
|
1197
1257
|
|
|
1198
1258
|
## Production checklist
|
|
1199
1259
|
|
|
@@ -1212,7 +1272,7 @@ Provider descriptions and component fingerprints must not expose secrets.
|
|
|
1212
1272
|
|
|
1213
1273
|
## Limitations and glossary
|
|
1214
1274
|
|
|
1215
|
-
V0.
|
|
1275
|
+
V0.4 does not provide a hosted service/dashboard, automatic RAG construction, vector-database
|
|
1216
1276
|
provisioning, distributed workers, Pareto optimization, Bayesian/evolutionary search, encrypted
|
|
1217
1277
|
payloads, MLflow reconciliation, provider pricing management, or a TypeScript implementation.
|
|
1218
1278
|
LangChain, LangGraph, and Google ADK 2.x are official integrations. Additional frameworks require a future first-party integration; custom RAG adapters are unsupported.
|