tuieval 0.2.0.dev35__tar.gz → 0.2.0.dev43__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/CHANGELOG.md +2 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/PKG-INFO +10 -1
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/README.md +9 -0
- tuieval-0.2.0.dev43/docs/images/tui-answer-reasoning.png +0 -0
- tuieval-0.2.0.dev43/docs/images/tui-run-reasoning.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/models.md +11 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/_version.py +2 -2
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/cli.py +2 -1
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/client.py +11 -1
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/engine.py +3 -0
- tuieval-0.2.0.dev43/src/tuieval/pta.py +185 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/run_evals.py +50 -2
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/tui.py +65 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/tests/mock_server.py +4 -1
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/tests/test_tuieval.py +158 -2
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/.gitignore +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/LICENSE +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/RELEASING.md +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/README.md +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/favicon.ico +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/readme-header.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/social-preview.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-1024.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-128.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-16.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-16.svg +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-256.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-32.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-48.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-512.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-64.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon-animated.svg +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/brand/tuieval-icon.svg +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/images/tui-setup.png +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/docs/writing-packs.md +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/pyproject.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/__init__.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/__main__.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/builtin.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/compare.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/doctor.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/export.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/graders/__init__.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/graders/answer.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/graders/code.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/graders/rag.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/graders/reply.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/graders/tool_call.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/machines.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/onboard.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/packs.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/profiles.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/remove.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/scaffold.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/selftest.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/models.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/answer/pack.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/answer/system.txt +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/answer/tests.yaml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/code/pack.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/code/system.txt +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/code/tests.yaml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/rag/pack.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/rag/system.txt +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/rag/tests.yaml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/reply/pack.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/reply/system.txt +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/reply/tests.yaml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/tool_call/pack.toml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/tool_call/system.txt +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/tool_call/tests.yaml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/tool_call/tools.yaml +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/tune.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/verdict.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/watch_proxy.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/workspace.py +0 -0
- {tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/yamlout.py +0 -0
|
@@ -2,6 +2,8 @@
|
|
|
2
2
|
|
|
3
3
|
## Unreleased
|
|
4
4
|
|
|
5
|
+
- A model a server won't serve (HTTP 401-404, e.g. OpenRouter's "No endpoints found") is never judged on it: those answers don't count, and the model stops at once instead of failing every question.
|
|
6
|
+
- PTA index: privacy, time (total, relative to the fastest) and accuracy per model, as a triangle in Results, `tuieval pta` and the report.
|
|
5
7
|
- Run several models at a time: `parallel_models` per machine, **Models at a time** in the TUI, or `tuieval run --parallel N` (default 1). Models wait for memory to fit, and answers note what ran alongside them.
|
|
6
8
|
- More evals during a run: `n` opens Setup, and Start adds them to the run going (same tier) or queues them after it.
|
|
7
9
|
- A new workspace's `models.toml` is 23 lines: the llama, local and OpenRouter servers and the defaults are built in (docs/models.md lists them in full; a server defined in `models.toml` replaces the built-in one with that name). Existing workspaces keep their settings; built-in servers they don't define become available, and adding a model still prefers the workspace's own servers.
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: tuieval
|
|
3
|
-
Version: 0.2.0.
|
|
3
|
+
Version: 0.2.0.dev43
|
|
4
4
|
Summary: Evaluate local and frontier LLMs on your own questions: accuracy, speed, tokens and PASS/FAIL verdicts, in the terminal.
|
|
5
5
|
Project-URL: Homepage, https://github.com/ashe-wb/tuieval
|
|
6
6
|
Project-URL: Issues, https://github.com/ashe-wb/tuieval/issues
|
|
@@ -62,6 +62,14 @@ Once you've added your own packs and models, the setup screen looks like this (p
|
|
|
62
62
|
|
|
63
63
|
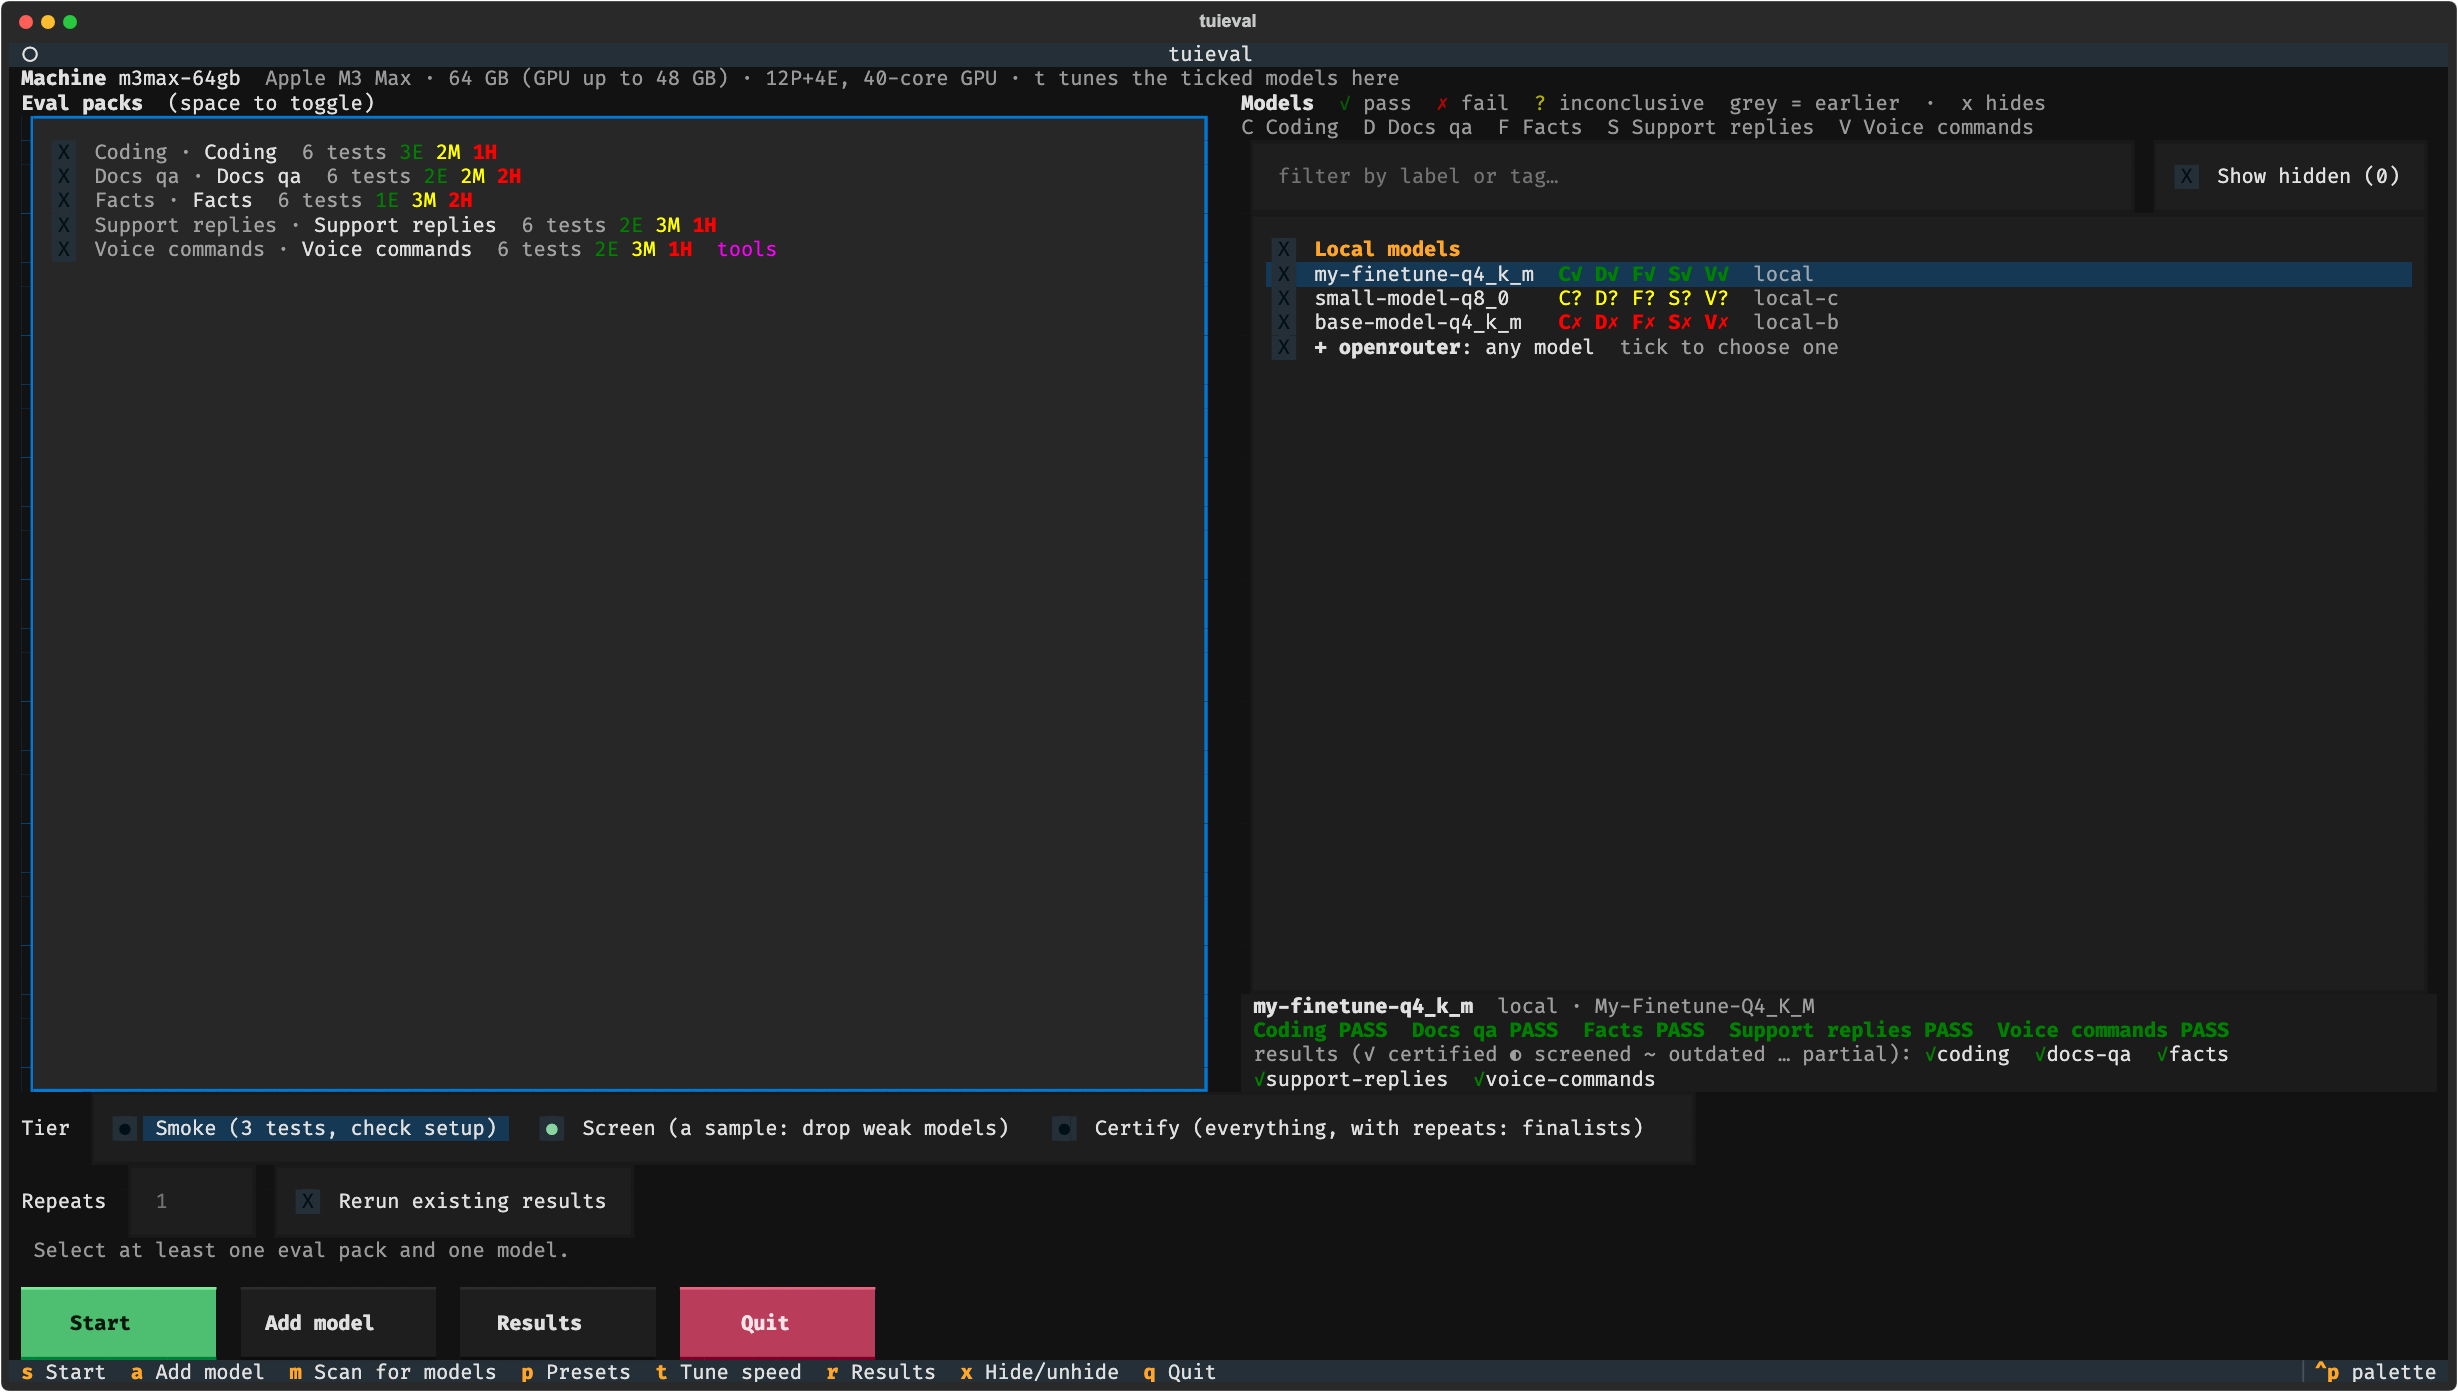
|
|
64
64
|
|
|
65
|
+
While a run goes, you watch each question's reasoning and answer stream in:
|
|
66
|
+
|
|
67
|
+
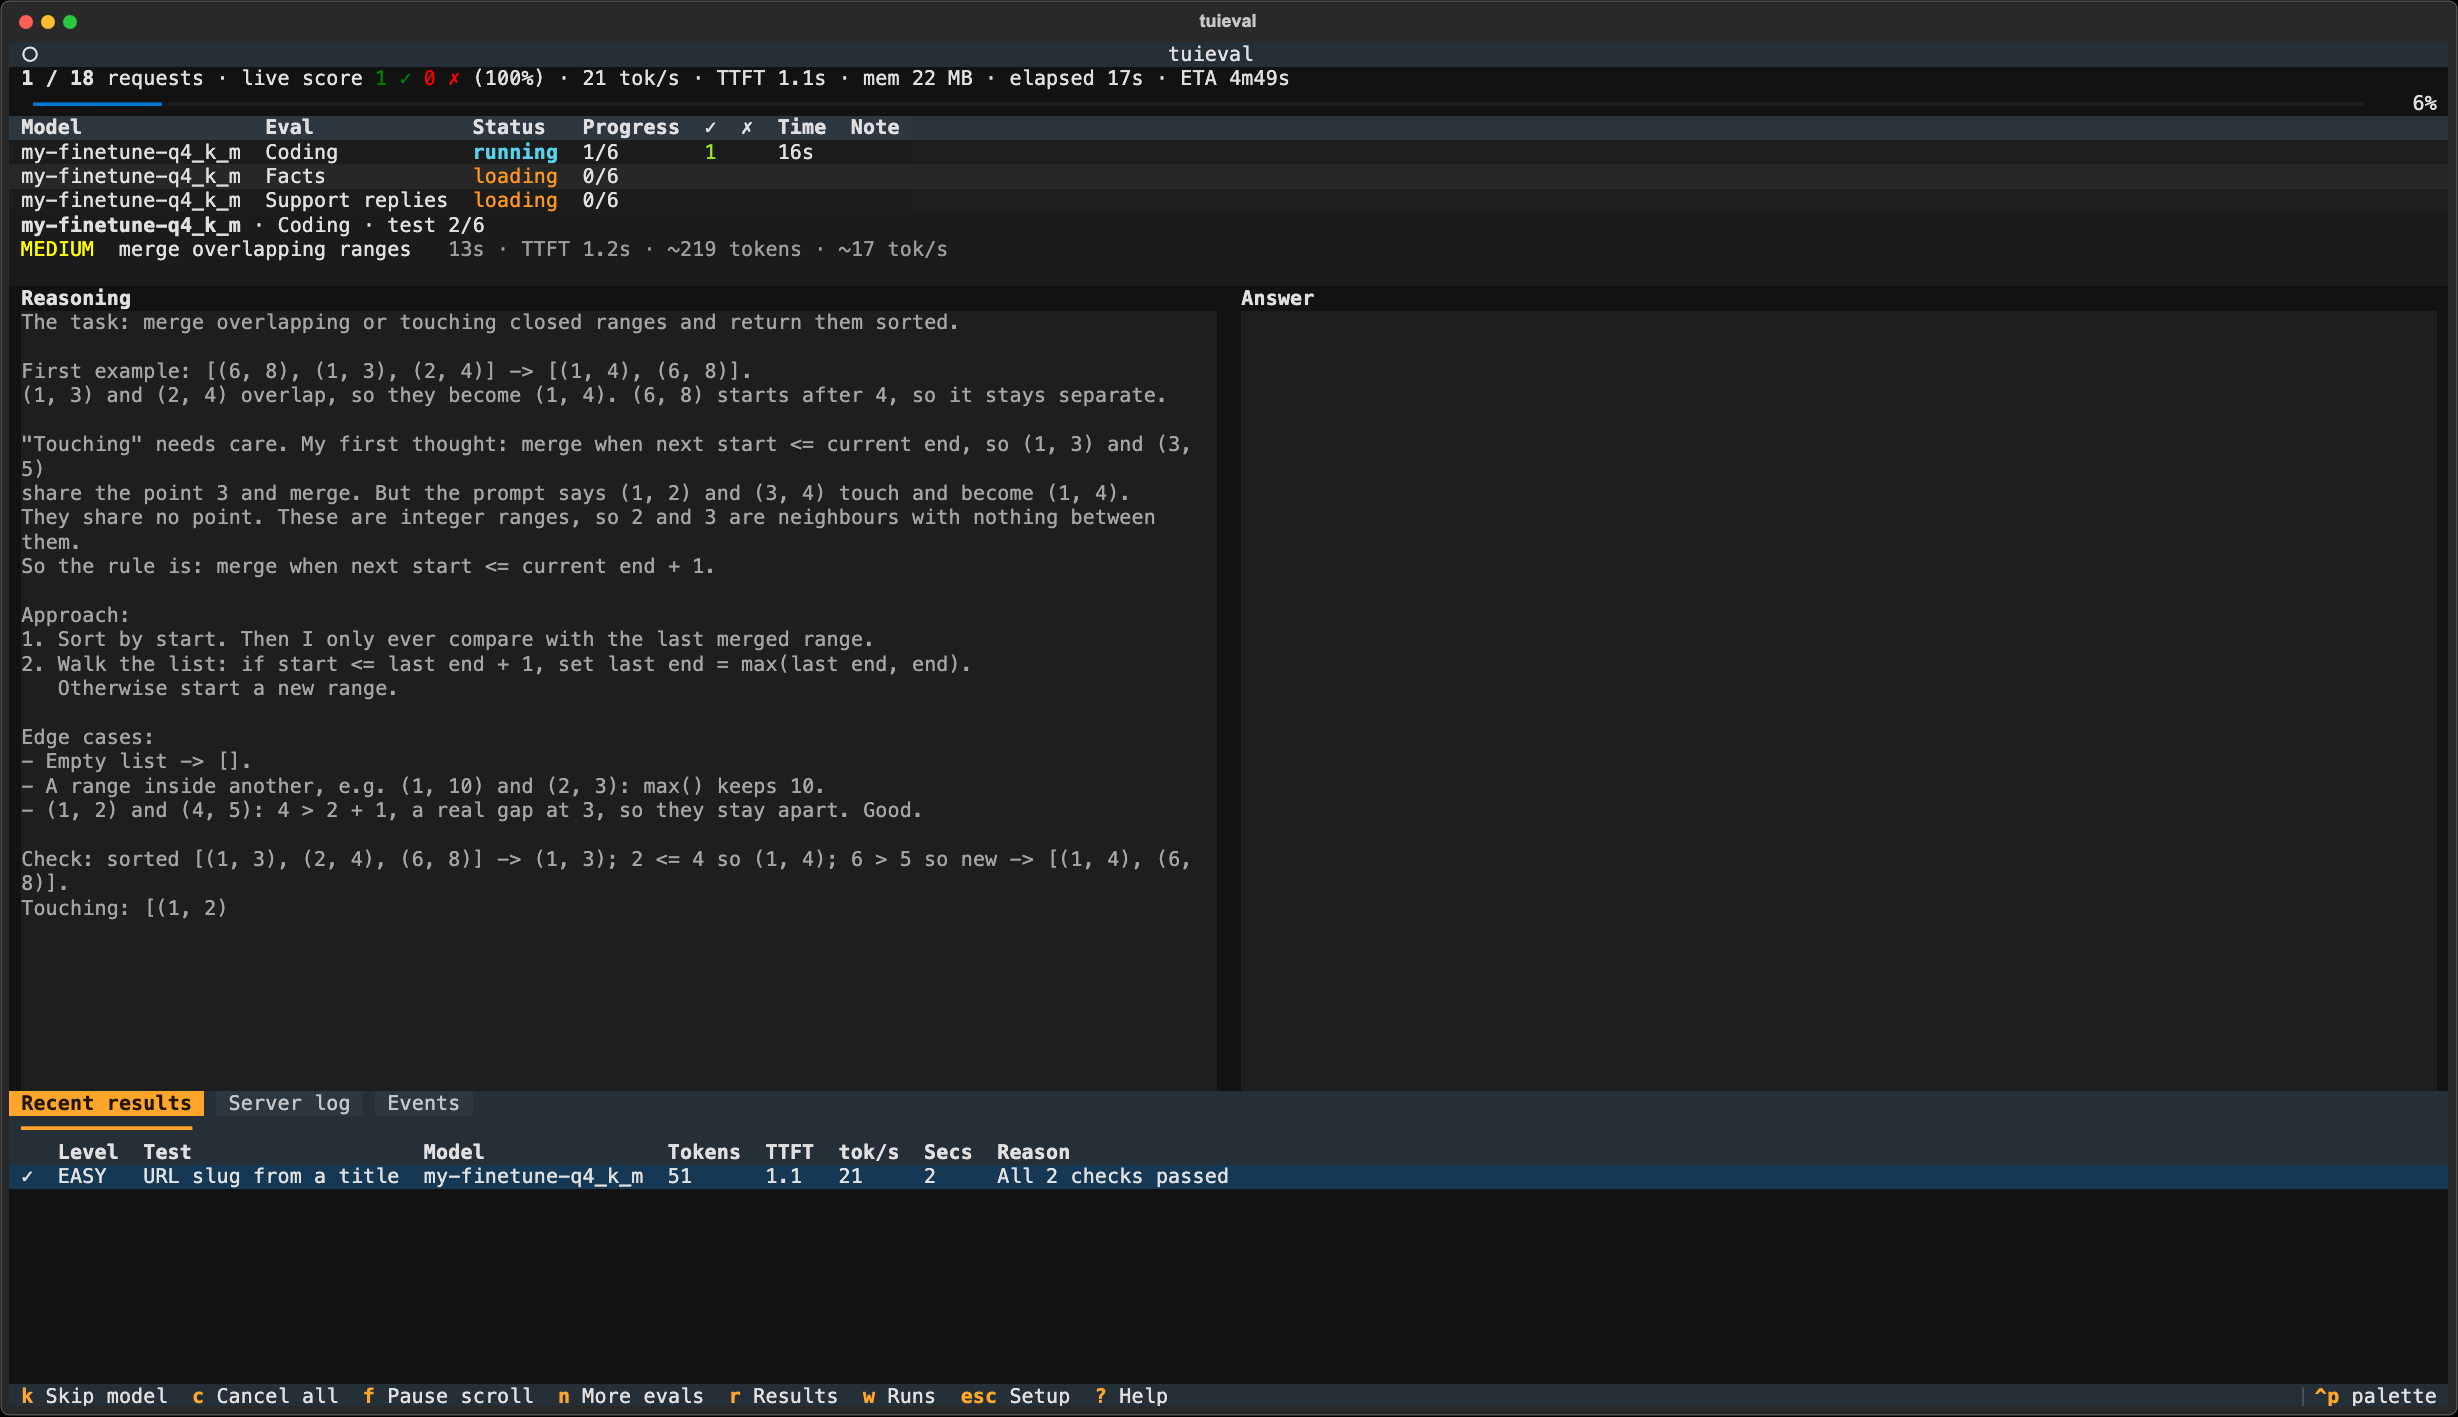
|
|
68
|
+
|
|
69
|
+
Afterwards, every answer keeps its reasoning. Enter on a result opens it with the grade and each check, the full reasoning and the answer; `[` and `]` step through the others:
|
|
70
|
+
|
|
71
|
+
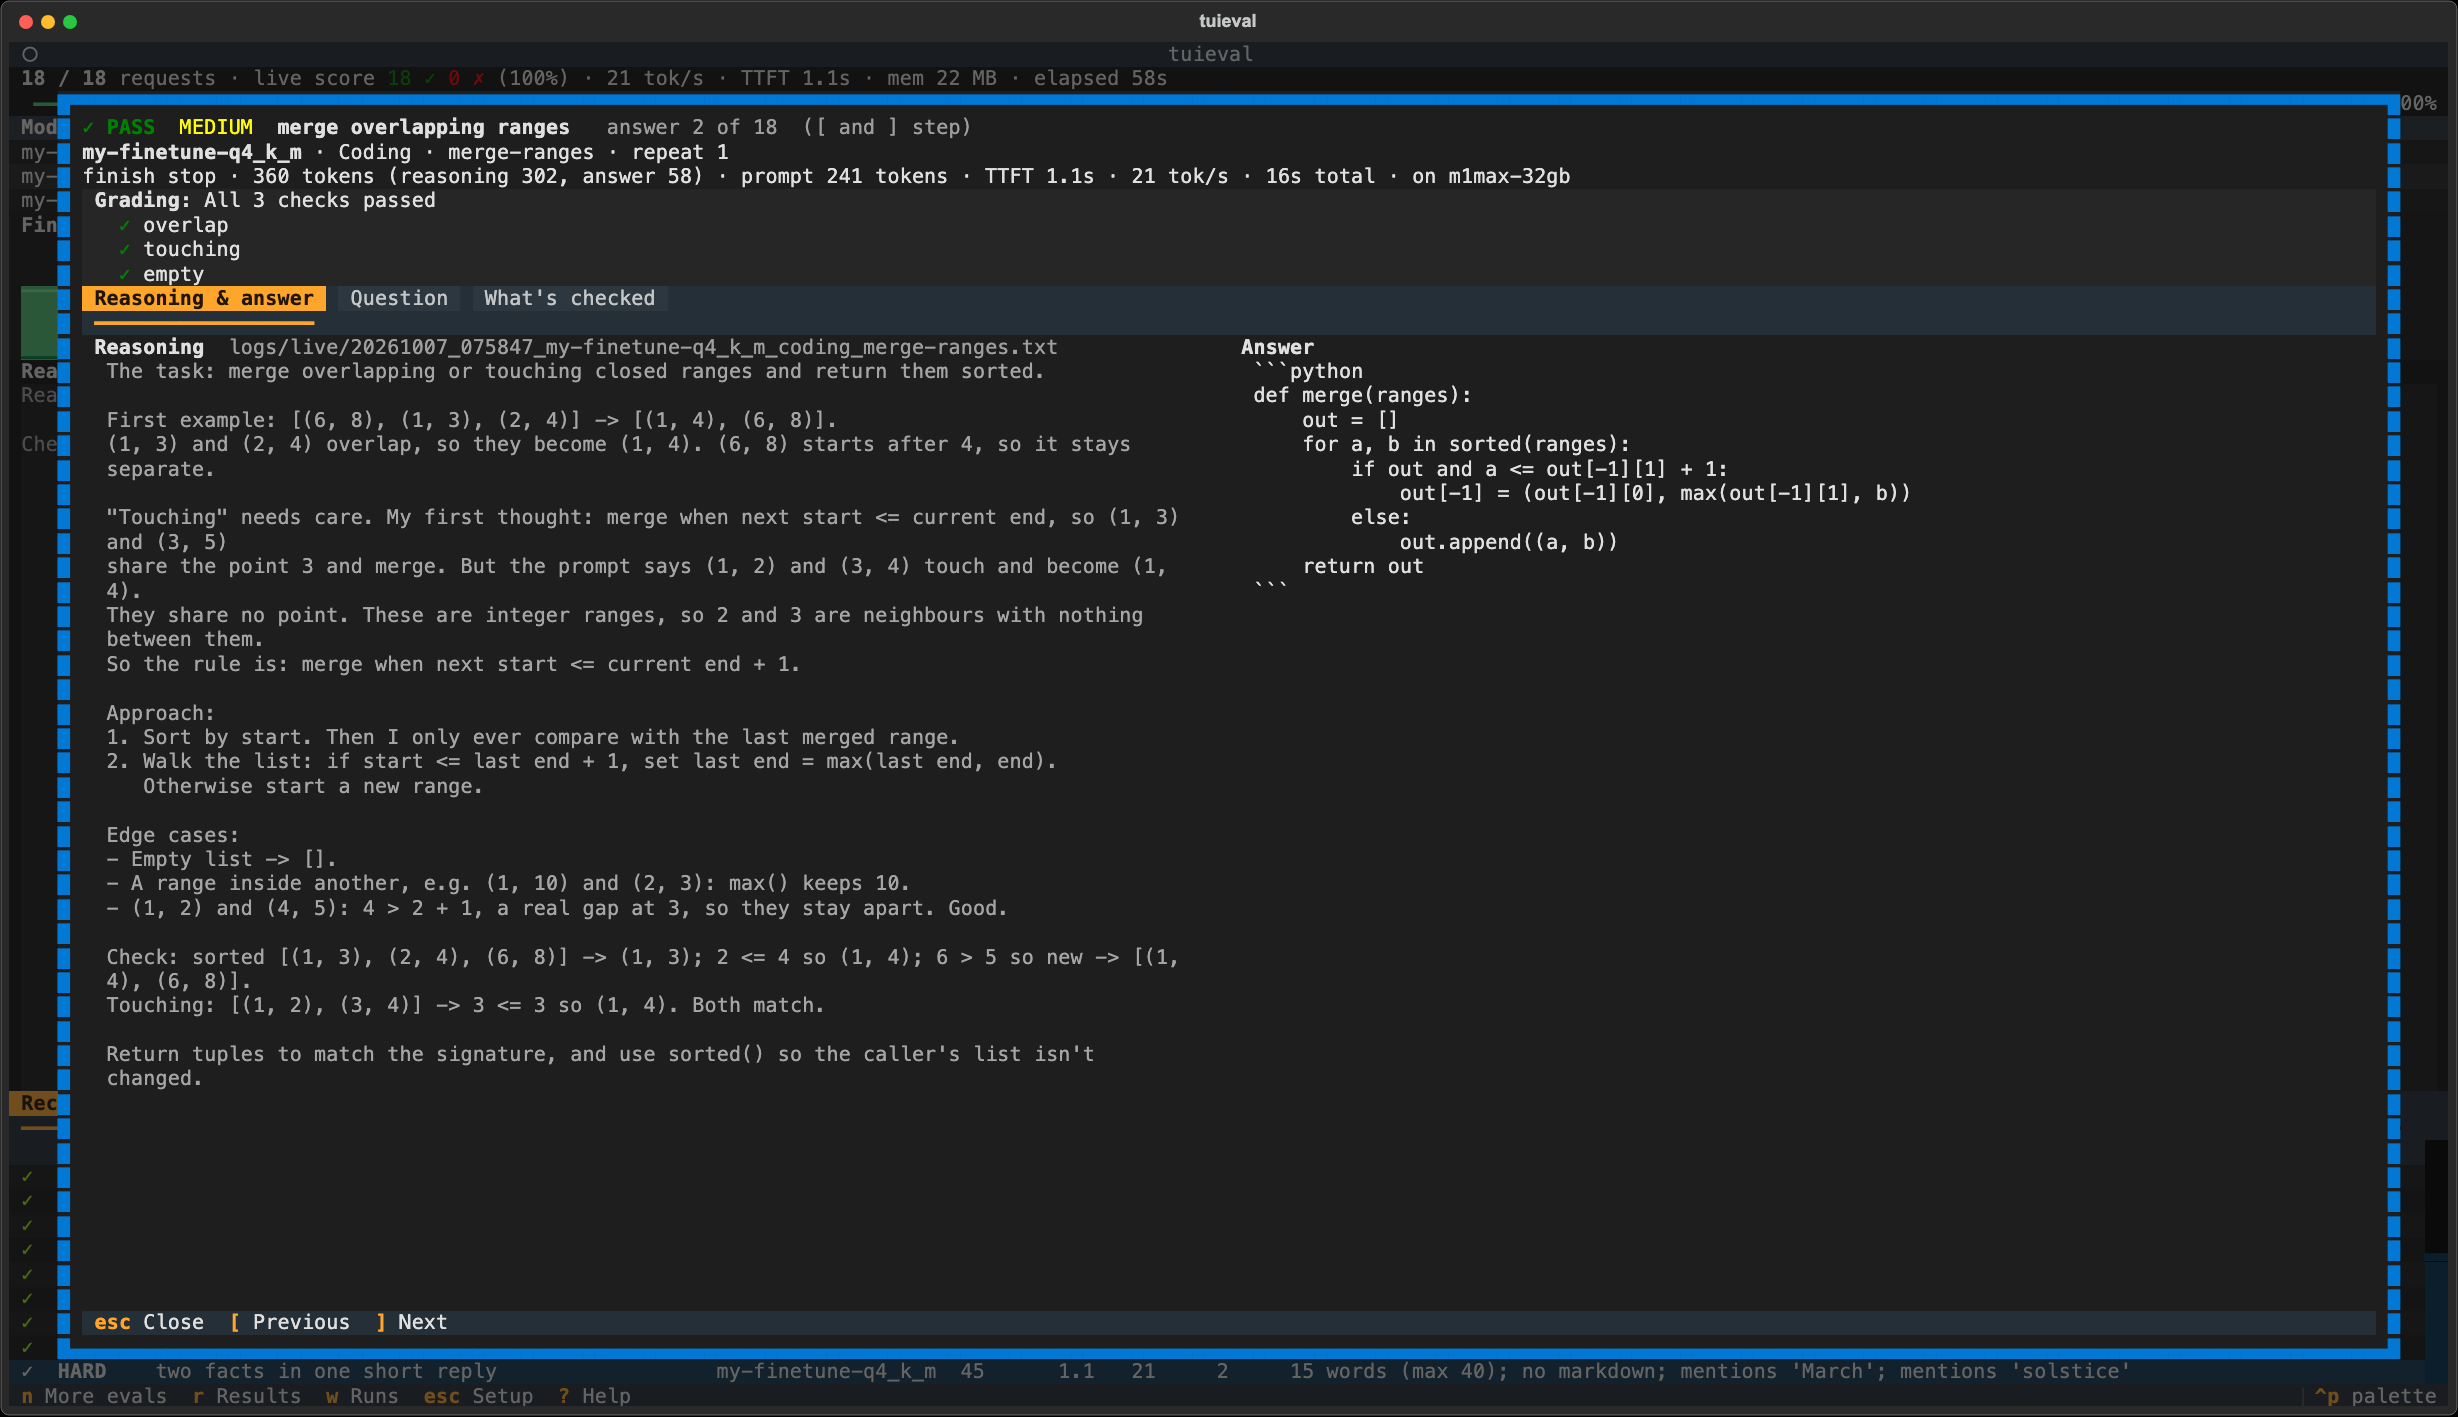
|
|
72
|
+
|
|
65
73
|
## What you get
|
|
66
74
|
|
|
67
75
|
- **A TUI** to pick packs and models, watch reasoning and answers stream live with TTFT, tokens/s, memory and a running score, and browse results.
|
|
@@ -156,6 +164,7 @@ tuieval selftest # check every test's reference and
|
|
|
156
164
|
tuieval items # tests that don't separate models or look broken
|
|
157
165
|
tuieval capture logs/live/<file> --pack X # turn a real failure into a new test
|
|
158
166
|
tuieval regrade # re-score stored answers after changing a grader
|
|
167
|
+
tuieval regrade --only <model> --packs X # just one model's results (and packs)
|
|
159
168
|
tuieval machines # this machine and others, fit and tuning per model
|
|
160
169
|
tuieval tune <model> # fastest speed flags for a model on this machine
|
|
161
170
|
tuieval export pi <model> # serve it in the pi coding agent with those flags
|
|
@@ -36,6 +36,14 @@ Once you've added your own packs and models, the setup screen looks like this (p
|
|
|
36
36
|
|
|
37
37
|

|
|
38
38
|
|
|
39
|
+
While a run goes, you watch each question's reasoning and answer stream in:
|
|
40
|
+
|
|
41
|
+

|
|
42
|
+
|
|
43
|
+
Afterwards, every answer keeps its reasoning. Enter on a result opens it with the grade and each check, the full reasoning and the answer; `[` and `]` step through the others:
|
|
44
|
+
|
|
45
|
+

|
|
46
|
+
|
|
39
47
|
## What you get
|
|
40
48
|
|
|
41
49
|
- **A TUI** to pick packs and models, watch reasoning and answers stream live with TTFT, tokens/s, memory and a running score, and browse results.
|
|
@@ -130,6 +138,7 @@ tuieval selftest # check every test's reference and
|
|
|
130
138
|
tuieval items # tests that don't separate models or look broken
|
|
131
139
|
tuieval capture logs/live/<file> --pack X # turn a real failure into a new test
|
|
132
140
|
tuieval regrade # re-score stored answers after changing a grader
|
|
141
|
+
tuieval regrade --only <model> --packs X # just one model's results (and packs)
|
|
133
142
|
tuieval machines # this machine and others, fit and tuning per model
|
|
134
143
|
tuieval tune <model> # fastest speed flags for a model on this machine
|
|
135
144
|
tuieval export pi <model> # serve it in the pi coding agent with those flags
|
|
Binary file
|
|
Binary file
|
|
@@ -84,6 +84,16 @@ By default a run serves one model at a time. On a machine with room for more, se
|
|
|
84
84
|
- In the TUI, one model's answers stream at a time: `v` switches to the next, `k` skips the one streaming. `tuieval run` prints one line per answer instead of streaming.
|
|
85
85
|
- Only one run uses the machine at a time across tuieval windows; models at a time applies within a run.
|
|
86
86
|
|
|
87
|
+
## PTA index
|
|
88
|
+
|
|
89
|
+
The **PTA index** puts privacy, time and accuracy side by side, 0-100 each, as a radar triangle (Results → PTA index, `tuieval pta`, and a section in `tuieval report`). Each model is a triangle reaching each corner as far as its score: bigger means better all round. There's no combined number; verdicts and critical failures stay in Production readiness.
|
|
90
|
+
|
|
91
|
+
- **P privacy**: 100 when prompts stay on machines you control (tuieval starts the server, its `url` is this machine, or the server has `private = true`, e.g. your own box on the network); 0 for a hosted API.
|
|
92
|
+
- **T time**: the total time to answer every question compared (each question at its median over repeats), relative to the fastest model: `100 × fastest total ÷ this model's total`. Adding a faster model lowers the others.
|
|
93
|
+
- **A accuracy**: the share of answers to those questions that passed.
|
|
94
|
+
|
|
95
|
+
Models are compared on the questions all of them answered, so one that skipped some never looks faster. Pick the models and pack to compare in the TUI, or use `--only` and `--packs`.
|
|
96
|
+
|
|
87
97
|
## Tuning
|
|
88
98
|
|
|
89
99
|
`tuieval tune <model>` (or `t` on the setup screen, for the ticked models) finds the fastest speed flags for a model on this machine:
|
|
@@ -130,6 +140,7 @@ On Apple Silicon Macs, once the system's GPU allocations pass about half of RAM,
|
|
|
130
140
|
|---|---|
|
|
131
141
|
| `cmd` | command that starts the server (no `cmd` = an already-running server at `url`). Placeholders: `{model}`, `{served_name}`, `{port}`, `{mmproj}`, `{ctx}`, `{kv_type}`, `{root}` (the workspace), and the tune placeholders. An argument `env:NAME=value` sets an environment variable instead. |
|
|
132
142
|
| `url` | an already-running server's base URL |
|
|
143
|
+
| `private` | `true` for a server on a machine you control (e.g. your own box on the network): its models score 100 for privacy in the PTA index |
|
|
133
144
|
| `port` | the port `cmd` serves on |
|
|
134
145
|
| `cwd` | folder to start `cmd` in |
|
|
135
146
|
| `model_is_path` | `model` is a file or folder: check it exists before starting |
|
|
@@ -18,7 +18,7 @@ version_tuple: tuple[int | str, ...]
|
|
|
18
18
|
commit_id: str | None
|
|
19
19
|
__commit_id__: str | None
|
|
20
20
|
|
|
21
|
-
__version__ = version = '0.2.0.
|
|
22
|
-
__version_tuple__ = version_tuple = (0, 2, 0, '
|
|
21
|
+
__version__ = version = '0.2.0.dev43'
|
|
22
|
+
__version_tuple__ = version_tuple = (0, 2, 0, 'dev43')
|
|
23
23
|
|
|
24
24
|
__commit_id__ = commit_id = None
|
|
@@ -14,11 +14,12 @@ Start here
|
|
|
14
14
|
|
|
15
15
|
Day to day
|
|
16
16
|
tuieval compare [...] scorecards (--speed, --pairwise, --failures)
|
|
17
|
+
tuieval pta the PTA index: privacy, time and accuracy per model, as a triangle
|
|
17
18
|
tuieval report the verdicts with their evidence, as a markdown file
|
|
18
19
|
tuieval history every verdict change, newest first
|
|
19
20
|
tuieval items tests that don't separate models or look broken
|
|
20
21
|
tuieval capture LOG --pack turn a real failure (logs/live/*.txt) into a new test
|
|
21
|
-
tuieval regrade re-score stored answers after changing a grader
|
|
22
|
+
tuieval regrade re-score stored answers after changing a grader (--only, --packs)
|
|
22
23
|
tuieval list the models tuieval knows, hidden ones separately (--packs: the packs)
|
|
23
24
|
tuieval remove MODEL remove models, or every hidden one (--hidden); archived in removed/
|
|
24
25
|
|
|
@@ -17,6 +17,10 @@ import time
|
|
|
17
17
|
import urllib.parse
|
|
18
18
|
|
|
19
19
|
SERVER_ERROR_PREFIXES = ("server returned HTTP 5", "server returned HTTP 429", "server error", "connection error")
|
|
20
|
+
# the model can't be reached there at all (a bad key, no credits, or a hosted API with no provider serving it, e.g.
|
|
21
|
+
# OpenRouter's 404 "No endpoints found"): not the model's answer either, and waiting won't fix it
|
|
22
|
+
UNAVAILABLE_PREFIXES = ("server returned HTTP 401", "server returned HTTP 402", "server returned HTTP 403",
|
|
23
|
+
"server returned HTTP 404")
|
|
20
24
|
|
|
21
25
|
|
|
22
26
|
def is_server_error(error):
|
|
@@ -27,9 +31,15 @@ def is_server_error(error):
|
|
|
27
31
|
and "timeout" not in error.lower()
|
|
28
32
|
|
|
29
33
|
|
|
34
|
+
def is_unavailable(error):
|
|
35
|
+
"""True for an error saying the model isn't available on that server at all: HTTP 401, 402, 403 or
|
|
36
|
+
404. Never the model's answer, and not worth retrying."""
|
|
37
|
+
return bool(error) and error.startswith(UNAVAILABLE_PREFIXES)
|
|
38
|
+
|
|
39
|
+
|
|
30
40
|
def server_error_row(rec):
|
|
31
41
|
"""A stored answer that was really a server failure (never a judgement of the model)."""
|
|
32
|
-
return not rec.get("pass") and is_server_error(rec.get("reason"))
|
|
42
|
+
return not rec.get("pass") and (is_server_error(rec.get("reason")) or is_unavailable(rec.get("reason")))
|
|
33
43
|
|
|
34
44
|
|
|
35
45
|
class Cancelled(Exception):
|
|
@@ -2105,6 +2105,9 @@ class Engine:
|
|
|
2105
2105
|
self._check()
|
|
2106
2106
|
if res["error"] and not alive():
|
|
2107
2107
|
raise ModelFailed(f"the server stopped: {res['error']}")
|
|
2108
|
+
if client.is_unavailable(res["error"]): # never an answer; retrying won't help
|
|
2109
|
+
raise ModelFailed(f"the model isn't available there (not counted against it): "
|
|
2110
|
+
f"{res['error'][:300]}")
|
|
2108
2111
|
if not client.is_server_error(res["error"]):
|
|
2109
2112
|
break
|
|
2110
2113
|
# the server failed, not the model: never recorded as an answer
|
|
@@ -0,0 +1,185 @@
|
|
|
1
|
+
"""PTA index: privacy, time and accuracy per model, 0-100 each, drawn as a radar triangle.
|
|
2
|
+
|
|
3
|
+
P privacy 100 when prompts stay on machines you control: tuieval starts the server, its URL
|
|
4
|
+
is this machine, or the server is marked private = true in models.toml. 0 otherwise
|
|
5
|
+
(a hosted API: there's no partial privacy once prompts leave).
|
|
6
|
+
T time the total time to answer every question compared (each question at its median over
|
|
7
|
+
repeats), relative to the fastest model: 100 x fastest total / this model's total.
|
|
8
|
+
A accuracy the share of answers to those questions that passed.
|
|
9
|
+
|
|
10
|
+
Models are compared on the questions all of them answered, so one that skipped some never looks
|
|
11
|
+
faster. There's no combined number: the three stay side by side, and verdicts and critical
|
|
12
|
+
failures stay where they are (verdict.py).
|
|
13
|
+
"""
|
|
14
|
+
import urllib.parse
|
|
15
|
+
|
|
16
|
+
from . import compare
|
|
17
|
+
|
|
18
|
+
LOCAL_HOSTS = {"localhost", "127.0.0.1", "::1", "0.0.0.0"}
|
|
19
|
+
# one colour per model on the triangle; more models than colours are listed but not drawn
|
|
20
|
+
COLORS = ["cyan", "magenta", "yellow", "green", "red", "blue", "bright_white", "bright_cyan"]
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def privacy(cfg, label):
|
|
24
|
+
"""100 if a model's prompts stay on machines you control, else 0 (see the module docstring);
|
|
25
|
+
None for a model that's no longer in models.toml (where it ran isn't known)."""
|
|
26
|
+
m = next((m for m in cfg["models"] if m["label"] == label), None)
|
|
27
|
+
server = cfg["servers"].get(m["server"], {}) if m else {}
|
|
28
|
+
if not server:
|
|
29
|
+
return None
|
|
30
|
+
if server.get("cmd") or server.get("private"):
|
|
31
|
+
return 100
|
|
32
|
+
host = urllib.parse.urlparse(server.get("url", "")).hostname or ""
|
|
33
|
+
return 100 if host.lower() in LOCAL_HOSTS else 0
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
def index(rows, privacy_of, models=None):
|
|
37
|
+
"""{"questions": n shared, "models": [{model, P, T, A, total_s, passed, answers, alongside}]},
|
|
38
|
+
best accuracy first. models: the ones to compare (default: every model in rows)."""
|
|
39
|
+
tests = compare.per_question(rows)
|
|
40
|
+
models = sorted(models or {m for t in tests for m in t["cells"]})
|
|
41
|
+
shared = [t for t in tests if models and all(m in t["cells"] for m in models)]
|
|
42
|
+
out = []
|
|
43
|
+
for m in models:
|
|
44
|
+
cells = [t["cells"][m] for t in shared]
|
|
45
|
+
answers = sum(c["n"] for c in cells)
|
|
46
|
+
out.append({"model": m, "P": privacy_of(m), "total_s": sum(c["secs"] or 0 for c in cells),
|
|
47
|
+
"passed": sum(c["passed"] for c in cells), "answers": answers,
|
|
48
|
+
"A": 100 * sum(c["passed"] for c in cells) / answers if answers else None,
|
|
49
|
+
# answers that ran while other models were served shared the machine's speed
|
|
50
|
+
"alongside": any(r.get("alongside") for c in cells for r in c["rows"])})
|
|
51
|
+
fastest = min((x["total_s"] for x in out if x["total_s"] > 0), default=None)
|
|
52
|
+
for x in out:
|
|
53
|
+
x["T"] = 100 * fastest / x["total_s"] if fastest and x["total_s"] > 0 else None
|
|
54
|
+
out.sort(key=lambda x: (-(x["A"] or 0), -(x["T"] or 0), x["model"]))
|
|
55
|
+
return {"questions": len(shared), "models": out}
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
# ---------------------------------------------------------------- the triangle (braille, no dependencies)
|
|
59
|
+
_DOTS = ((0x01, 0x08), (0x02, 0x10), (0x04, 0x20), (0x40, 0x80)) # braille dot bits by (row, column)
|
|
60
|
+
|
|
61
|
+
|
|
62
|
+
class _Canvas:
|
|
63
|
+
"""Braille cells, 2 dots wide and 4 tall each; every cell takes the colour of the last line through it."""
|
|
64
|
+
def __init__(self, cols, rows):
|
|
65
|
+
self.cols, self.rows = cols, rows
|
|
66
|
+
self.bits = [[0] * cols for _ in range(rows)]
|
|
67
|
+
self.color = [[None] * cols for _ in range(rows)]
|
|
68
|
+
|
|
69
|
+
def dot(self, x, y, color):
|
|
70
|
+
cx, cy = int(x) // 2, int(y) // 4
|
|
71
|
+
if 0 <= cx < self.cols and 0 <= cy < self.rows:
|
|
72
|
+
self.bits[cy][cx] |= _DOTS[int(y) % 4][int(x) % 2]
|
|
73
|
+
self.color[cy][cx] = color
|
|
74
|
+
|
|
75
|
+
def line(self, a, b, color, dotted=False):
|
|
76
|
+
steps = int(max(abs(b[0] - a[0]), abs(b[1] - a[1]))) or 1
|
|
77
|
+
for i in range(steps + 1):
|
|
78
|
+
if dotted and i % 3:
|
|
79
|
+
continue
|
|
80
|
+
self.dot(a[0] + (b[0] - a[0]) * i / steps, a[1] + (b[1] - a[1]) * i / steps, color)
|
|
81
|
+
|
|
82
|
+
def text(self):
|
|
83
|
+
lines = []
|
|
84
|
+
for bits, colors in zip(self.bits, self.color):
|
|
85
|
+
out = []
|
|
86
|
+
for b, c in zip(bits, colors):
|
|
87
|
+
ch = chr(0x2800 + b) if b else " "
|
|
88
|
+
out.append(f"[{c}]{ch}[/]" if b and c else ch)
|
|
89
|
+
lines.append("".join(out).rstrip())
|
|
90
|
+
return lines
|
|
91
|
+
|
|
92
|
+
|
|
93
|
+
def triangle(result, width=60):
|
|
94
|
+
"""The radar triangle as Rich markup lines: P at the top, T bottom left, A bottom right; a
|
|
95
|
+
model's triangle reaches each corner as far as its score (bigger = better all round)."""
|
|
96
|
+
cols = max(20, width)
|
|
97
|
+
w = cols * 2 - 2 # dots across
|
|
98
|
+
h = int(w * 0.866) # an equilateral triangle (braille dots are about square)
|
|
99
|
+
rows = h // 4 + 1
|
|
100
|
+
top, left, right = (w / 2, 0), (0, h), (w, h)
|
|
101
|
+
center = (w / 2, h * 2 / 3)
|
|
102
|
+
c = _Canvas(cols, rows)
|
|
103
|
+
|
|
104
|
+
def at(corner, score):
|
|
105
|
+
return (center[0] + (corner[0] - center[0]) * score / 100, center[1] + (corner[1] - center[1]) * score / 100)
|
|
106
|
+
|
|
107
|
+
for corner in (top, left, right): # axes, the 50% ring, then the frame
|
|
108
|
+
c.line(center, corner, "grey37", dotted=True)
|
|
109
|
+
half = [at(k, 50) for k in (top, left, right)]
|
|
110
|
+
for a, b in zip(half, half[1:] + half[:1]):
|
|
111
|
+
c.line(a, b, "grey37", dotted=True)
|
|
112
|
+
for a, b in ((top, left), (left, right), (right, top)):
|
|
113
|
+
c.line(a, b, "grey70")
|
|
114
|
+
for i, x in enumerate(result["models"][:len(COLORS)][::-1]): # the best ends on top
|
|
115
|
+
color = COLORS[len(result["models"][:len(COLORS)]) - 1 - i]
|
|
116
|
+
pts = [at(k, s or 0) for k, s in ((top, x["P"]), (left, x["T"]), (right, x["A"]))]
|
|
117
|
+
for a, b in zip(pts, pts[1:] + pts[:1]):
|
|
118
|
+
c.line(a, b, color)
|
|
119
|
+
lines = c.text()
|
|
120
|
+
pad = " " * max(0, cols // 2 - 5)
|
|
121
|
+
return ([f"{pad}[b]P[/b] privacy"] + lines
|
|
122
|
+
+ [f"[b]T[/b] time{' ' * max(1, cols - 15)}[b]A[/b] accuracy"])
|
|
123
|
+
|
|
124
|
+
|
|
125
|
+
def legend(result):
|
|
126
|
+
"""One Rich markup line per model: its colour on the triangle and its three scores."""
|
|
127
|
+
out = []
|
|
128
|
+
for i, x in enumerate(result["models"]):
|
|
129
|
+
mark = f"[{COLORS[i]}]■[/]" if i < len(COLORS) else " "
|
|
130
|
+
out.append(f"{mark} {x['model']} P {_score(x['P'])} · T {_score(x['T'])} · A {_score(x['A'])}"
|
|
131
|
+
+ (" [yellow](some answers ran alongside other models)[/yellow]" if x["alongside"] else ""))
|
|
132
|
+
return out
|
|
133
|
+
|
|
134
|
+
|
|
135
|
+
def _score(v):
|
|
136
|
+
return "-" if v is None else f"{v:.0f}"
|
|
137
|
+
|
|
138
|
+
|
|
139
|
+
def table(result):
|
|
140
|
+
"""(header, rows) for a plain table of the index."""
|
|
141
|
+
header = ["model", "P privacy", "T time", "A accuracy", "total time", "answers right"]
|
|
142
|
+
rows = [[x["model"], _score(x["P"]), _score(x["T"]), _score(x["A"]), fmt_total(x["total_s"]),
|
|
143
|
+
f"{x['passed']}/{x['answers']}"] for x in result["models"]]
|
|
144
|
+
return header, rows
|
|
145
|
+
|
|
146
|
+
|
|
147
|
+
def fmt_total(secs):
|
|
148
|
+
if not secs:
|
|
149
|
+
return "-"
|
|
150
|
+
if secs < 60:
|
|
151
|
+
return f"{secs:.1f}s"
|
|
152
|
+
secs = round(secs)
|
|
153
|
+
h, rem = divmod(secs, 3600)
|
|
154
|
+
return f"{h}h{rem // 60:02d}m" if h else f"{rem // 60}m{rem % 60:02d}s" if rem >= 60 else f"{rem}s"
|
|
155
|
+
|
|
156
|
+
|
|
157
|
+
def scope_note(result, models):
|
|
158
|
+
"""What the scores compare, in a sentence."""
|
|
159
|
+
if not result["questions"]:
|
|
160
|
+
return "These models have no question in common yet, so there's nothing to compare."
|
|
161
|
+
return (f"Compared on the {result['questions']} questions all {len(models)} model(s) answered. "
|
|
162
|
+
"T is relative to the fastest total, so adding a faster model lowers the others.")
|
|
163
|
+
|
|
164
|
+
|
|
165
|
+
def for_engine(e, labels=None, packs=None, results_dir=None):
|
|
166
|
+
"""(result, models) from a workspace's finished results (results on their way out excluded)."""
|
|
167
|
+
paths = [p for p in compare.default_paths(results_dir or e.results_dir) if not e.superseded(p)]
|
|
168
|
+
rows, _ = compare.load(paths) if paths else ([], [])
|
|
169
|
+
if packs:
|
|
170
|
+
rows = [r for r in rows if r["suite"] in packs]
|
|
171
|
+
models = sorted({r["model"] for r in rows} & set(labels) if labels else {r["model"] for r in rows})
|
|
172
|
+
return index(rows, lambda m: privacy(e.cfg, m), models), models
|
|
173
|
+
|
|
174
|
+
|
|
175
|
+
def markdown(result, models):
|
|
176
|
+
"""The index as a markdown section (tuieval report)."""
|
|
177
|
+
lines = ["## PTA index", "", scope_note(result, models), ""]
|
|
178
|
+
if not result["questions"]:
|
|
179
|
+
return lines
|
|
180
|
+
header, rows = table(result)
|
|
181
|
+
lines += ["| " + " | ".join(header) + " |", "|" + "---|" * len(header)]
|
|
182
|
+
lines += ["| " + " | ".join(r) + " |" for r in rows]
|
|
183
|
+
if any(x["alongside"] for x in result["models"]):
|
|
184
|
+
lines += ["", "Some answers ran alongside other models, which shared the machine's speed."]
|
|
185
|
+
return lines
|
|
@@ -21,6 +21,7 @@
|
|
|
21
21
|
tuieval list # the models tuieval knows; hidden ones listed separately
|
|
22
22
|
tuieval remove --hidden # clean up hidden models (archived in removed/)
|
|
23
23
|
tuieval regrade # re-score stored answers with the current graders
|
|
24
|
+
tuieval regrade --only my-model --packs coding # just one model's results (and packs)
|
|
24
25
|
tuieval machines # this machine, known machines, fit and tuning per model
|
|
25
26
|
tuieval tune my-model # find the fastest speed flags for a model on this machine
|
|
26
27
|
tuieval tune --untuned # tune every model that has no profile here yet
|
|
@@ -270,9 +271,22 @@ def cmd_remove(argv):
|
|
|
270
271
|
def cmd_regrade(argv):
|
|
271
272
|
p = argparse.ArgumentParser(prog="tuieval regrade", description="Re-score stored answers with current graders.")
|
|
272
273
|
p.add_argument("paths", nargs="*", help="result files (default: all in results/)")
|
|
274
|
+
p.add_argument("--only", help="comma-separated model labels")
|
|
275
|
+
p.add_argument("--packs", help="comma-separated packs")
|
|
273
276
|
a = p.parse_args(argv)
|
|
274
277
|
from . import compare
|
|
275
|
-
|
|
278
|
+
paths = a.paths or compare.default_paths()
|
|
279
|
+
for flag, value, part in (("--only", a.only, lambda q: os.path.basename(os.path.dirname(q))),
|
|
280
|
+
("--packs", a.packs, lambda q: os.path.basename(q)[:-len(".json")])):
|
|
281
|
+
if not value:
|
|
282
|
+
continue
|
|
283
|
+
wanted = [v.strip() for v in value.split(",") if v.strip()]
|
|
284
|
+
known = sorted({part(q) for q in paths})
|
|
285
|
+
missing = [v for v in wanted if v not in known]
|
|
286
|
+
if missing:
|
|
287
|
+
sys.exit(f"{flag}: no results for {', '.join(missing)}. With results: {', '.join(known) or 'none'}")
|
|
288
|
+
paths = [q for q in paths if part(q) in wanted]
|
|
289
|
+
for path in paths:
|
|
276
290
|
try:
|
|
277
291
|
before, after = engine.regrade(path)
|
|
278
292
|
print(f"{os.path.relpath(path)}: {before} -> {after} passed")
|
|
@@ -368,9 +382,43 @@ def report_markdown(e, labels=None):
|
|
|
368
382
|
lines.append(" - by difficulty: " + ", ".join(levels))
|
|
369
383
|
for ex in ev.get("critical_examples", []):
|
|
370
384
|
lines.append(f" - critical: {ex}")
|
|
385
|
+
from . import pta
|
|
386
|
+
lines += [""] + pta.markdown(*pta.for_engine(e, labels))
|
|
371
387
|
return "\n".join(lines) + "\n"
|
|
372
388
|
|
|
373
389
|
|
|
390
|
+
def cmd_pta(argv):
|
|
391
|
+
p = argparse.ArgumentParser(prog="tuieval pta",
|
|
392
|
+
description="The PTA index: privacy, time and accuracy per model (0-100 each), as a "
|
|
393
|
+
"triangle and a table, over the questions all the models answered.")
|
|
394
|
+
p.add_argument("--only", help="comma-separated model labels (default: every model with results)")
|
|
395
|
+
p.add_argument("--packs", help="comma-separated packs (default: all)")
|
|
396
|
+
p.add_argument("--width", type=int, default=48, help="triangle width in characters (default 48)")
|
|
397
|
+
p.add_argument("--models")
|
|
398
|
+
p.add_argument("--results-dir")
|
|
399
|
+
a = p.parse_args(argv)
|
|
400
|
+
from rich.console import Console
|
|
401
|
+
from . import pta
|
|
402
|
+
e = engine.Engine(models_path=a.models, results_dir=a.results_dir)
|
|
403
|
+
labels = [x.strip() for x in a.only.split(",")] if a.only else None
|
|
404
|
+
packs = [x.strip() for x in a.packs.split(",")] if a.packs else None
|
|
405
|
+
result, models = pta.for_engine(e, labels, packs)
|
|
406
|
+
out = Console(highlight=False)
|
|
407
|
+
if not models:
|
|
408
|
+
sys.exit("no finished results to compare" + (" for those models or packs" if labels or packs else ""))
|
|
409
|
+
out.print(pta.scope_note(result, models))
|
|
410
|
+
if not result["questions"]:
|
|
411
|
+
return
|
|
412
|
+
out.print()
|
|
413
|
+
for line in pta.triangle(result, a.width) + [""] + pta.legend(result):
|
|
414
|
+
out.print(line)
|
|
415
|
+
header, rows = pta.table(result)
|
|
416
|
+
widths = [max(len(h), *(len(r[i]) for r in rows)) for i, h in enumerate(header)]
|
|
417
|
+
out.print()
|
|
418
|
+
for line in [header] + rows:
|
|
419
|
+
out.print(" ".join(c.ljust(w) for c, w in zip(line, widths)).rstrip(), markup=False)
|
|
420
|
+
|
|
421
|
+
|
|
374
422
|
def cmd_report(argv):
|
|
375
423
|
p = argparse.ArgumentParser(prog="tuieval report", description="Write the readiness report as markdown.")
|
|
376
424
|
p.add_argument("-o", "--output", help="default: reports/readiness-<date>.md")
|
|
@@ -652,7 +700,7 @@ def cmd_export(argv):
|
|
|
652
700
|
COMMANDS = {"add": cmd_add, "list": cmd_list, "scan": cmd_scan, "regrade": cmd_regrade,
|
|
653
701
|
"verdict": cmd_verdict, "report": cmd_report, "items": cmd_items, "selftest": cmd_selftest,
|
|
654
702
|
"capture": cmd_capture, "history": cmd_history, "machines": cmd_machines, "tune": cmd_tune,
|
|
655
|
-
"export": cmd_export, "remove": cmd_remove}
|
|
703
|
+
"export": cmd_export, "remove": cmd_remove, "pta": cmd_pta}
|
|
656
704
|
|
|
657
705
|
|
|
658
706
|
def parse_tests(text, pack_names, known):
|
|
@@ -335,6 +335,7 @@ Opens on [b]Per question[/b]. [b]Production readiness[/b] gives one verdict per
|
|
|
335
335
|
and what's missing when it's INCONCLUSIVE. The other tabs are the evidence:
|
|
336
336
|
Scorecard accuracy, critical failures and truncation per model and pack
|
|
337
337
|
Speed & tokens time and tokens per answer (★ = nothing beats it on both accuracy and time)
|
|
338
|
+
PTA index privacy, total time and accuracy per model (0-100 each), as a triangle
|
|
338
339
|
Per question every question, model by model
|
|
339
340
|
Is the difference real? whether one model is really better than another, or it's noise
|
|
340
341
|
Tests that separate the questions that tell models apart
|
|
@@ -2365,6 +2366,19 @@ class ResultsScreen(Screen):
|
|
|
2365
2366
|
"On another machine, times are measured there if the model ran there, otherwise "
|
|
2366
2367
|
"projected from each answer's token counts and that machine's tuned speeds.[/dim]")
|
|
2367
2368
|
yield DataTable(id="speed", zebra_stripes=True)
|
|
2369
|
+
with TabPane("PTA index", id="tab-pta"):
|
|
2370
|
+
with Horizontal(id="pta-controls"):
|
|
2371
|
+
yield Select([("All packs", "")], id="pta-pack", allow_blank=False, value="")
|
|
2372
|
+
yield Button("Models: all", id="pta-models")
|
|
2373
|
+
yield Static("[dim]P privacy: 100 when prompts stay on machines you control (local, or a server "
|
|
2374
|
+
"marked private = true), 0 for a hosted API. T time: total time for every question "
|
|
2375
|
+
"compared, relative to the fastest model (100). A accuracy: answers right. Bigger "
|
|
2376
|
+
"triangle = better all round; verdicts and critical failures are in Production "
|
|
2377
|
+
"readiness.[/dim]")
|
|
2378
|
+
yield Static(id="pta-note")
|
|
2379
|
+
with Horizontal(id="pta-body"):
|
|
2380
|
+
yield Static(id="pta-triangle")
|
|
2381
|
+
yield DataTable(id="pta", zebra_stripes=True, cursor_type="none")
|
|
2368
2382
|
with TabPane("Per question", id="tab-per-question"):
|
|
2369
2383
|
with Horizontal(id="pq-controls"):
|
|
2370
2384
|
yield Select([("All packs", "")], id="pq-pack", allow_blank=False, value="")
|
|
@@ -2460,6 +2474,7 @@ class ResultsScreen(Screen):
|
|
|
2460
2474
|
info.update("No results yet. Run an eval first." + banner)
|
|
2461
2475
|
self.rows, self.infos = [], []
|
|
2462
2476
|
self.fill_per_question()
|
|
2477
|
+
self.fill_pta()
|
|
2463
2478
|
return
|
|
2464
2479
|
rows, infos = compare.load(paths)
|
|
2465
2480
|
notes = compare.settings_notes(infos)
|
|
@@ -2501,6 +2516,7 @@ class ResultsScreen(Screen):
|
|
|
2501
2516
|
for test, flags, rates in compare.items(rows):
|
|
2502
2517
|
qt.add_row(", ".join(flags), test, *[f"{100 * rates[m]:.0f}%" if m in rates else "-" for m in models])
|
|
2503
2518
|
self.fill_per_question()
|
|
2519
|
+
self.fill_pta()
|
|
2504
2520
|
self.fill_readiness(results_dir)
|
|
2505
2521
|
|
|
2506
2522
|
@on(DataTable.RowSelected, "#failures")
|
|
@@ -2524,6 +2540,7 @@ class ResultsScreen(Screen):
|
|
|
2524
2540
|
self.fill_per_question()
|
|
2525
2541
|
|
|
2526
2542
|
@on(Button.Pressed, "#pq-models")
|
|
2543
|
+
@on(Button.Pressed, "#pta-models")
|
|
2527
2544
|
def pick_models(self):
|
|
2528
2545
|
counts = {}
|
|
2529
2546
|
for t in getattr(self, "pq_all_tests", []):
|
|
@@ -2541,8 +2558,51 @@ class ResultsScreen(Screen):
|
|
|
2541
2558
|
self.query_one("#pq-shared", Checkbox).value = True
|
|
2542
2559
|
# after the picker has closed: a table rebuilt under a modal keeps its header-only widths
|
|
2543
2560
|
self.call_after_refresh(self.fill_per_question)
|
|
2561
|
+
self.call_after_refresh(self.fill_pta)
|
|
2544
2562
|
self.app.push_screen(ModelPickScreen(models, counts, self.app.pq_models), picked)
|
|
2545
2563
|
|
|
2564
|
+
@on(Select.Changed, "#pta-pack")
|
|
2565
|
+
def pta_changed(self):
|
|
2566
|
+
if getattr(self, "rows", None) is not None:
|
|
2567
|
+
self.fill_pta()
|
|
2568
|
+
|
|
2569
|
+
def fill_pta(self):
|
|
2570
|
+
"""The PTA index (pta.py) of the picked models (Models button, shared with Per question) on
|
|
2571
|
+
the finished results, over the questions all of them answered."""
|
|
2572
|
+
from . import pta
|
|
2573
|
+
e = self.app.engine
|
|
2574
|
+
rows = [r for r in self.rows if r.get("path") not in self.superseded]
|
|
2575
|
+
packs = sorted({r["suite"] for r in rows})
|
|
2576
|
+
sel = self.query_one("#pta-pack", Select)
|
|
2577
|
+
options = [("All packs", "")] + [(e.packs[p].label if p in e.packs else p, p) for p in packs]
|
|
2578
|
+
if [v for _, v in options] != getattr(self, "pta_pack_values", None):
|
|
2579
|
+
self.pta_pack_values = [v for _, v in options]
|
|
2580
|
+
current = sel.value
|
|
2581
|
+
with sel.prevent(Select.Changed):
|
|
2582
|
+
sel.set_options(options)
|
|
2583
|
+
sel.value = current if current in self.pta_pack_values else ""
|
|
2584
|
+
if sel.value:
|
|
2585
|
+
rows = [r for r in rows if r["suite"] == sel.value]
|
|
2586
|
+
present = {r["model"] for r in rows}
|
|
2587
|
+
chosen = {m for m in self.app.pq_models if m in present}
|
|
2588
|
+
self.query_one("#pta-models", Button).label = f"Models: {len(chosen)} picked" if chosen else "Models: all"
|
|
2589
|
+
models = sorted(chosen or present)
|
|
2590
|
+
t = self.query_one("#pta", DataTable)
|
|
2591
|
+
t.clear(columns=True)
|
|
2592
|
+
if not models:
|
|
2593
|
+
self.query_one("#pta-note", Static).update("No finished results to compare yet.")
|
|
2594
|
+
self.query_one("#pta-triangle", Static).update("")
|
|
2595
|
+
return
|
|
2596
|
+
result = pta.index(rows, lambda m: pta.privacy(e.cfg, m), models)
|
|
2597
|
+
extra = (f" [yellow]{len(pta.COLORS)} models are drawn at most; pick fewer with Models.[/yellow]"
|
|
2598
|
+
if len(models) > len(pta.COLORS) else "")
|
|
2599
|
+
self.query_one("#pta-note", Static).update(pta.scope_note(result, models) + extra)
|
|
2600
|
+
self.query_one("#pta-triangle", Static).update(
|
|
2601
|
+
"\n".join(pta.triangle(result, 48) + [""] + pta.legend(result)) if result["questions"] else "")
|
|
2602
|
+
header, table = pta.table(result)
|
|
2603
|
+
t.add_columns(*header)
|
|
2604
|
+
t.add_rows(table)
|
|
2605
|
+
|
|
2546
2606
|
def fill_per_question(self):
|
|
2547
2607
|
# a pack being rerun under new questions or settings: its old result file is on its way out,
|
|
2548
2608
|
# so it isn't compared (it moves to history/ when the new run of that pack finishes)
|
|
@@ -2846,6 +2906,11 @@ class EvalsApp(App):
|
|
|
2846
2906
|
#results-info { width: 1fr; height: auto; }
|
|
2847
2907
|
#toggle-smoke { width: auto; min-width: 32; }
|
|
2848
2908
|
#pq-controls { height: 3; }
|
|
2909
|
+
#pta-controls { height: 3; }
|
|
2910
|
+
#pta-controls Select { width: 28; margin-right: 1; }
|
|
2911
|
+
#pta-body { height: auto; }
|
|
2912
|
+
#pta-triangle { width: auto; padding: 1 2 0 0; }
|
|
2913
|
+
#pta { width: 1fr; height: auto; margin-top: 1; }
|
|
2849
2914
|
#pq-controls Checkbox { width: auto; }
|
|
2850
2915
|
#pq-controls Select { width: 28; margin-right: 1; }
|
|
2851
2916
|
#pq-models { margin-right: 1; min-width: 20; }
|
|
@@ -6,6 +6,7 @@ oracle answers each question with its test's `reference` (or the expected tool
|
|
|
6
6
|
correct grader passes it
|
|
7
7
|
wrong answers with the test's first `wrong` entry (or "ANSWER: 0")
|
|
8
8
|
fixed always "ANSWER: 42"
|
|
9
|
+
unavailable HTTP 404 "No endpoints found" for every chat request
|
|
9
10
|
|
|
10
11
|
Streams like llama.cpp: reasoning_content then content deltas, usage and timings at the end.
|
|
11
12
|
"""
|
|
@@ -77,6 +78,8 @@ class Handler(BaseHTTPRequestHandler):
|
|
|
77
78
|
if isinstance(content, list):
|
|
78
79
|
content = " ".join(p.get("text", "") for p in content if isinstance(p, dict))
|
|
79
80
|
test = self.answers.get(" ".join(str(content).split()))
|
|
81
|
+
if self.mode == "unavailable": # like OpenRouter with no provider serving the model
|
|
82
|
+
return self._json({"error": {"message": f"No endpoints found for {self.model}.", "code": 404}}, 404)
|
|
80
83
|
text, calls = reply_for(test, self.mode)
|
|
81
84
|
self.send_response(200)
|
|
82
85
|
self.send_header("Content-Type", "text/event-stream")
|
|
@@ -105,7 +108,7 @@ def main(argv=None):
|
|
|
105
108
|
p = argparse.ArgumentParser()
|
|
106
109
|
p.add_argument("--port", type=int, default=18090)
|
|
107
110
|
p.add_argument("--packs", required=True)
|
|
108
|
-
p.add_argument("--mode", choices=("oracle", "wrong", "fixed"), default="oracle")
|
|
111
|
+
p.add_argument("--mode", choices=("oracle", "wrong", "fixed", "unavailable"), default="oracle")
|
|
109
112
|
p.add_argument("--model", default="mock")
|
|
110
113
|
p.add_argument("--delay", type=float, default=0.0, help="seconds each answer takes")
|
|
111
114
|
a, _ = p.parse_known_args(argv) # other flags (e.g. speed knobs under test) are accepted and ignored
|
|
@@ -46,10 +46,10 @@ def free_port():
|
|
|
46
46
|
|
|
47
47
|
|
|
48
48
|
class Mock:
|
|
49
|
-
def __init__(self, packs, mode, port=None):
|
|
49
|
+
def __init__(self, packs, mode, port=None, delay=0.0):
|
|
50
50
|
self.port = port or free_port()
|
|
51
51
|
self.proc = subprocess.Popen([sys.executable, os.path.join(HERE, "mock_server.py"), "--port", str(self.port),
|
|
52
|
-
"--packs", packs, "--mode", mode], stdout=subprocess.DEVNULL)
|
|
52
|
+
"--packs", packs, "--mode", mode, "--delay", str(delay)], stdout=subprocess.DEVNULL)
|
|
53
53
|
for _ in range(100):
|
|
54
54
|
try:
|
|
55
55
|
urllib.request.urlopen(f"http://127.0.0.1:{self.port}/v1/models", timeout=1)
|
|
@@ -198,6 +198,16 @@ class WorkspaceGraders(unittest.TestCase):
|
|
|
198
198
|
|
|
199
199
|
|
|
200
200
|
class Units(unittest.TestCase):
|
|
201
|
+
def test_server_errors_never_judge_the_model(self):
|
|
202
|
+
from tuieval import client
|
|
203
|
+
no_endpoints = 'server returned HTTP 404: {"error":{"message":"No endpoints found for some/model."}}'
|
|
204
|
+
for reason, retry, unavailable in ((no_endpoints, False, True), ("server returned HTTP 402: no credits", False, True),
|
|
205
|
+
("server returned HTTP 503: busy", True, False),
|
|
206
|
+
("server returned HTTP 400: bad request", False, False),
|
|
207
|
+
("connection error: timed out", False, False)): # the model too slow
|
|
208
|
+
self.assertEqual((client.is_server_error(reason), client.is_unavailable(reason)), (retry, unavailable), reason)
|
|
209
|
+
self.assertEqual(client.server_error_row({"pass": False, "reason": reason}), retry or unavailable, reason)
|
|
210
|
+
|
|
201
211
|
def test_tune_workload_needs_no_packs(self):
|
|
202
212
|
from tuieval import tune
|
|
203
213
|
work = tune.workload(None, 65536)
|
|
@@ -412,6 +422,21 @@ class Parallel(unittest.TestCase):
|
|
|
412
422
|
self.assertFalse(any("ran_alongside" in r for r in data["results"]))
|
|
413
423
|
self.assertNotIn("loaded_alongside", data["run"])
|
|
414
424
|
|
|
425
|
+
def test_regrade_one_model(self):
|
|
426
|
+
tuieval(self.ws, "run", "--only", "a,b", "--tier", "certify")
|
|
427
|
+
tests = os.path.join(self.ws, "packs", "apps", "tests.yaml")
|
|
428
|
+
write(tests, read(tests).replace("expected: 1", "expected: 2")) # a grader change: every answer now wrong
|
|
429
|
+
out = tuieval(self.ws, "regrade", "--only", "a", "--packs", "apps").stdout
|
|
430
|
+
self.assertIn("6 -> 0 passed", out)
|
|
431
|
+
self.assertNotIn(os.path.join("b", "apps.json"), out)
|
|
432
|
+
self.assertEqual(sum(r["pass"] for r in self.results("a")["results"]), 0)
|
|
433
|
+
self.assertEqual(sum(r["pass"] for r in self.results("b")["results"]), 6) # left as it was
|
|
434
|
+
for args, name in ((["--only", "a,nope"], "nope"), (["--packs", "nope"], "nope")):
|
|
435
|
+
p = tuieval(self.ws, "regrade", *args, check=False)
|
|
436
|
+
self.assertNotEqual(p.returncode, 0)
|
|
437
|
+
self.assertIn(f"no results for {name}", p.stderr)
|
|
438
|
+
self.assertEqual(sum(r["pass"] for r in self.results("b")["results"]), 6) # a typo regrades nothing
|
|
439
|
+
|
|
415
440
|
def test_side_by_side_on_their_own_ports(self):
|
|
416
441
|
out = tuieval(self.ws, "run", "--only", "a,b", "--tier", "certify", "--parallel", "2").stdout
|
|
417
442
|
self.assertIn("up to 2 models at a time", out)
|
|
@@ -676,6 +701,137 @@ class AddToRun(unittest.TestCase):
|
|
|
676
701
|
self.assertEqual(out["second"], [["a/other", "done"]]) # queued: its own run after
|
|
677
702
|
|
|
678
703
|
|
|
704
|
+
class PTAIndex(unittest.TestCase):
|
|
705
|
+
"""The PTA index: privacy from where a model runs, time relative to the fastest total, accuracy,
|
|
706
|
+
all over the questions every compared model answered."""
|
|
707
|
+
|
|
708
|
+
def test_privacy(self):
|
|
709
|
+
from tuieval import pta
|
|
710
|
+
cfg = {"servers": {"llama": {"cmd": ["llama-server"]}, "lm": {"url": "http://localhost:1234/v1"},
|
|
711
|
+
"box": {"url": "http://192.168.1.20:8000/v1"}, "mine": {"url": "http://192.168.1.20:8000/v1",
|
|
712
|
+
"private": True},
|
|
713
|
+
"or": {"url": "https://openrouter.ai/api/v1"}},
|
|
714
|
+
"models": [{"label": l, "server": l} for l in ("llama", "lm", "box", "mine", "or")]}
|
|
715
|
+
self.assertEqual([pta.privacy(cfg, l) for l in ("llama", "lm", "box", "mine", "or", "gone")],
|
|
716
|
+
[100, 100, 0, 100, 0, None])
|
|
717
|
+
|
|
718
|
+
def test_index_compares_shared_questions(self):
|
|
719
|
+
from tuieval import pta
|
|
720
|
+
|
|
721
|
+
def row(model, test, ok, secs, repeat=0):
|
|
722
|
+
return {"model": model, "suite": "p", "test": f"p: {test}", "ok": ok, "latency": secs * 1000,
|
|
723
|
+
"tokens": 10, "truncated": False, "gen_tps": None, "repeat": repeat}
|
|
724
|
+
rows = [row("fast", "q1", True, 2), row("fast", "q2", False, 2),
|
|
725
|
+
row("slow", "q1", True, 8), row("slow", "q2", True, 4), row("slow", "q2", True, 6, repeat=1),
|
|
726
|
+
row("slow", "q3", True, 100)] # only slow answered q3: not compared
|
|
727
|
+
res = pta.index(rows, lambda m: 100 if m == "slow" else 0)
|
|
728
|
+
self.assertEqual(res["questions"], 2)
|
|
729
|
+
by = {x["model"]: x for x in res["models"]}
|
|
730
|
+
self.assertEqual(by["fast"]["total_s"], 4)
|
|
731
|
+
self.assertEqual(by["slow"]["total_s"], 13) # q1 8 + q2 median of 4 and 6
|
|
732
|
+
self.assertEqual(by["fast"]["T"], 100)
|
|
733
|
+
self.assertAlmostEqual(by["slow"]["T"], 100 * 4 / 13)
|
|
734
|
+
self.assertEqual((by["fast"]["A"], by["slow"]["A"]), (50, 100))
|
|
735
|
+
self.assertEqual([x["model"] for x in res["models"]], ["slow", "fast"]) # best accuracy first
|
|
736
|
+
lines = pta.triangle(res, 40)
|
|
737
|
+
self.assertIn("P[/b] privacy", lines[0])
|
|
738
|
+
self.assertTrue(any("[cyan]" in l for l in lines) and any("[magenta]" in l for l in lines))
|
|
739
|
+
|
|
740
|
+
def test_cli_report_and_tui(self):
|
|
741
|
+
with tempfile.TemporaryDirectory() as tmp:
|
|
742
|
+
ws = os.path.join(tmp, "ws")
|
|
743
|
+
tuieval(tmp, "init", ws)
|
|
744
|
+
d = os.path.join(ws, "packs", "apps")
|
|
745
|
+
os.makedirs(d)
|
|
746
|
+
write(os.path.join(d, "pack.toml"), 'label = "apps"\n[certify]\nrepeat = 1\n[gate]\nmin_accuracy = 0.1\n')
|
|
747
|
+
write(os.path.join(d, "tests.yaml"), "".join(
|
|
748
|
+
f"- {{id: {t}, input: question {t}, expected: 1, reference: 'ANSWER: 1', wrong: ['ANSWER: 2'], "
|
|
749
|
+
"difficulty: easy}\n" for t in "abcd"))
|
|
750
|
+
right = Mock(os.path.join(ws, "packs"), "oracle")
|
|
751
|
+
wrong = Mock(os.path.join(ws, "packs"), "wrong", delay=0.3)
|
|
752
|
+
try:
|
|
753
|
+
with open(os.path.join(ws, "models.toml"), "a") as f:
|
|
754
|
+
f.write(f'\n[servers.here]\nurl = "http://127.0.0.1:{right.port}"\n'
|
|
755
|
+
f'\n[servers.there]\nurl = "http://127.0.0.1:{wrong.port}"\n')
|
|
756
|
+
tuieval(ws, "add", "mock", "--server", "here", "--label", "good")
|
|
757
|
+
tuieval(ws, "add", "mock", "--server", "there", "--label", "hosted")
|
|
758
|
+
tuieval(ws, "run", "--tier", "certify")
|
|
759
|
+
finally:
|
|
760
|
+
right.stop()
|
|
761
|
+
wrong.stop()
|
|
762
|
+
path = os.path.join(ws, "models.toml") # as if "there" were a hosted API
|
|
763
|
+
write(path, read(path).replace(f"http://127.0.0.1:{wrong.port}", "https://api.example.com/v1"))
|
|
764
|
+
out = tuieval(ws, "pta").stdout
|
|
765
|
+
self.assertIn("Compared on the 4 questions all 2 model(s) answered", out)
|
|
766
|
+
table = {l.split()[0]: l.split()[1:4] for l in out.splitlines() if l.startswith(("good ", "hosted "))}
|
|
767
|
+
self.assertEqual(table["good"], ["100", "100", "100"])
|
|
768
|
+
self.assertEqual(table["hosted"][0], "0")
|
|
769
|
+
self.assertLess(int(table["hosted"][1]), 100) # slower in total
|
|
770
|
+
self.assertEqual(table["hosted"][2], "0")
|
|
771
|
+
self.assertIn("P privacy", out)
|
|
772
|
+
self.assertIn("4/4", tuieval(ws, "pta", "--only", "good").stdout)
|
|
773
|
+
report = os.path.join(tmp, "r.md")
|
|
774
|
+
tuieval(ws, "report", "-o", report)
|
|
775
|
+
self.assertIn("## PTA index", read(report))
|
|
776
|
+
code = textwrap.dedent("""
|
|
777
|
+
import asyncio, json
|
|
778
|
+
from tuieval.tui import EvalsApp, ResultsScreen
|
|
779
|
+
from textual.widgets import DataTable, Static
|
|
780
|
+
async def go():
|
|
781
|
+
app = EvalsApp({})
|
|
782
|
+
async with app.run_test(size=(180, 60)) as pilot:
|
|
783
|
+
await pilot.pause()
|
|
784
|
+
app.push_screen(ResultsScreen())
|
|
785
|
+
await pilot.pause(0.5)
|
|
786
|
+
t = app.screen.query_one("#pta", DataTable)
|
|
787
|
+
rows = [[str(c) for c in t.get_row_at(i)] for i in range(t.row_count)]
|
|
788
|
+
tri = str(app.screen.query_one("#pta-triangle", Static).render())
|
|
789
|
+
print(json.dumps({"rows": rows, "triangle": "P privacy" in tri}))
|
|
790
|
+
asyncio.run(go())
|
|
791
|
+
""")
|
|
792
|
+
p = subprocess.run([sys.executable, "-c", code], capture_output=True, text=True, timeout=300,
|
|
793
|
+
env=dict(os.environ, TUIEVAL_HOME=ws, TUIEVAL_DETECT_PORTS=""))
|
|
794
|
+
got = json.loads(p.stdout.strip().splitlines()[-1]) if p.stdout.strip() else p.stderr
|
|
795
|
+
self.assertIsInstance(got, dict, got)
|
|
796
|
+
self.assertTrue(got["triangle"])
|
|
797
|
+
self.assertEqual([r[:4] for r in got["rows"]][0], ["good", "100", "100", "100"])
|
|
798
|
+
|
|
799
|
+
|
|
800
|
+
class Unavailable(unittest.TestCase):
|
|
801
|
+
"""A model no server will serve (OpenRouter's 404 "No endpoints found", a bad key, no credits) stops at
|
|
802
|
+
once and is never judged on it; the other models run as usual."""
|
|
803
|
+
|
|
804
|
+
def test_unavailable_model_stops_and_isnt_judged(self):
|
|
805
|
+
with tempfile.TemporaryDirectory() as tmp:
|
|
806
|
+
ws = os.path.join(tmp, "ws")
|
|
807
|
+
tuieval(tmp, "init", ws)
|
|
808
|
+
d = os.path.join(ws, "packs", "apps")
|
|
809
|
+
os.makedirs(d)
|
|
810
|
+
write(os.path.join(d, "pack.toml"), 'label = "apps"\n[certify]\nrepeat = 1\n[gate]\nmin_accuracy = 0.1\n')
|
|
811
|
+
write(os.path.join(d, "tests.yaml"), "".join(
|
|
812
|
+
f"- {{id: {t}, input: question {t}, expected: 1, reference: 'ANSWER: 1', difficulty: easy}}\n"
|
|
813
|
+
for t in "abc"))
|
|
814
|
+
up, down = Mock(os.path.join(ws, "packs"), "oracle"), Mock(os.path.join(ws, "packs"), "unavailable")
|
|
815
|
+
try:
|
|
816
|
+
with open(os.path.join(ws, "models.toml"), "a") as f:
|
|
817
|
+
f.write(f'\n[servers.up]\nurl = "http://127.0.0.1:{up.port}"\n'
|
|
818
|
+
f'\n[servers.down]\nurl = "http://127.0.0.1:{down.port}"\n')
|
|
819
|
+
tuieval(ws, "add", "mock", "--server", "up", "--label", "works")
|
|
820
|
+
tuieval(ws, "add", "mock", "--server", "down", "--label", "gone")
|
|
821
|
+
t = time.time()
|
|
822
|
+
out = tuieval(ws, "run", "--tier", "certify", check=False).stdout
|
|
823
|
+
finally:
|
|
824
|
+
up.stop()
|
|
825
|
+
down.stop()
|
|
826
|
+
self.assertLess(time.time() - t, 60) # no retrying for minutes
|
|
827
|
+
self.assertIn("isn't available there", out)
|
|
828
|
+
verdict = tuieval(ws, "verdict", check=False).stdout
|
|
829
|
+
self.assertNotIn("0% right", verdict) # never judged on the 404s
|
|
830
|
+
rows = [l for l in verdict.splitlines() if "gone" in l]
|
|
831
|
+
self.assertFalse(any("FAIL" in l for l in rows), rows)
|
|
832
|
+
self.assertIn("works", tuieval(ws, "pta").stdout)
|
|
833
|
+
|
|
834
|
+
|
|
679
835
|
class FirstRun(unittest.TestCase):
|
|
680
836
|
"""A new user's first run fails fast with the fix, never hangs or shows a bare Python error."""
|
|
681
837
|
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/tool_call/system.txt
RENAMED
|
File without changes
|
{tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/tool_call/tests.yaml
RENAMED
|
File without changes
|
{tuieval-0.2.0.dev35 → tuieval-0.2.0.dev43}/src/tuieval/templates/packs/tool_call/tools.yaml
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|