tuieval 0.2.0.dev1__tar.gz → 0.2.0.dev2__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/CHANGELOG.md +3 -1
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/PKG-INFO +2 -2
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/README.md +1 -1
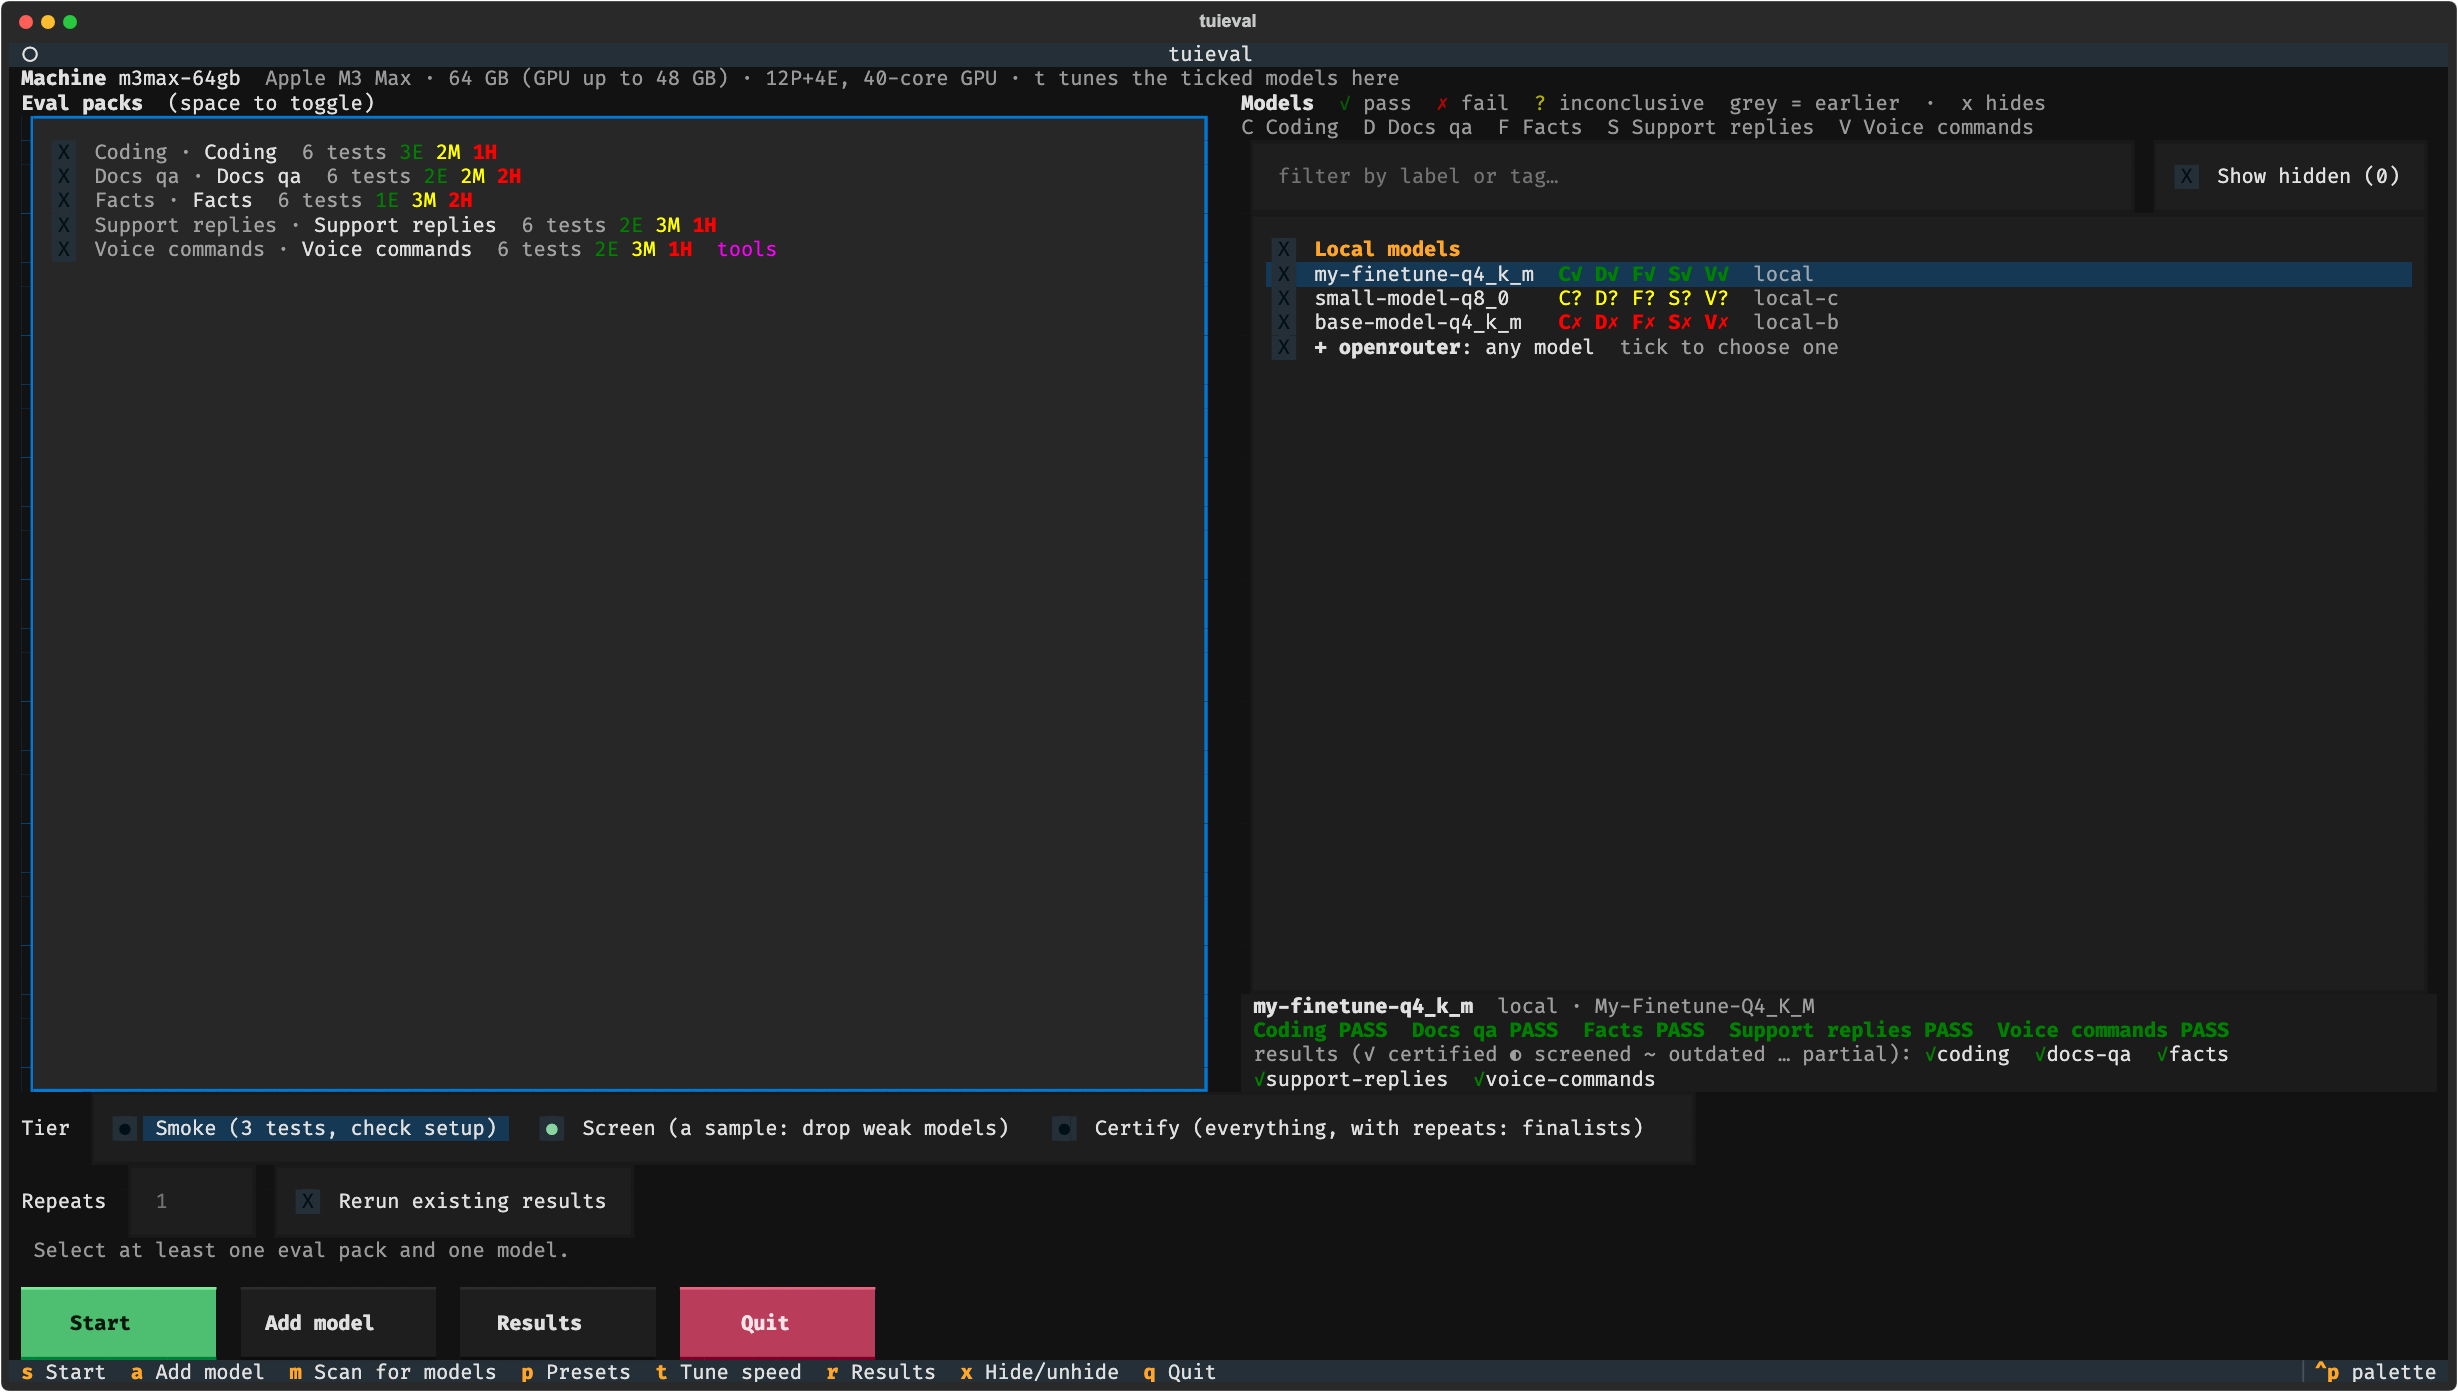
- tuieval-0.2.0.dev2/docs/images/tui-setup.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/models.md +7 -7
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/_version.py +2 -2
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/compare.py +1 -1
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/export.py +10 -7
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/machines.py +2 -3
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/run_evals.py +1 -1
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/models.toml +1 -1
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/tests/test_tuieval.py +5 -0
- tuieval-0.2.0.dev1/docs/images/tui-setup.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/.gitignore +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/LICENSE +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/RELEASING.md +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/README.md +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/favicon.ico +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/readme-header.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/social-preview.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-1024.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-128.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-16.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-16.svg +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-256.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-32.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-48.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-512.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-64.png +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon-animated.svg +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/images/brand/tuieval-icon.svg +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/docs/writing-packs.md +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/pyproject.toml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/__init__.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/__main__.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/cli.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/client.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/engine.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/graders/__init__.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/graders/answer.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/graders/code.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/graders/rag.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/graders/reply.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/graders/tool_call.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/packs.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/profiles.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/remove.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/scaffold.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/selftest.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/answer/pack.toml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/answer/system.txt +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/answer/tests.yaml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/code/pack.toml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/code/system.txt +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/code/tests.yaml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/rag/pack.toml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/rag/system.txt +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/rag/tests.yaml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/reply/pack.toml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/reply/system.txt +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/reply/tests.yaml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/tool_call/pack.toml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/tool_call/system.txt +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/tool_call/tests.yaml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/templates/packs/tool_call/tools.yaml +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/tui.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/tune.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/verdict.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/watch_proxy.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/workspace.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/src/tuieval/yamlout.py +0 -0
- {tuieval-0.2.0.dev1 → tuieval-0.2.0.dev2}/tests/mock_server.py +0 -0
|
@@ -2,12 +2,14 @@
|
|
|
2
2
|
|
|
3
3
|
## Unreleased
|
|
4
4
|
|
|
5
|
+
- `tuieval export pi` has no default presets path any more: set `[export.pi] presets` to your llama.cpp router's `--models-preset` file.
|
|
6
|
+
- A new README screenshot from a demo workspace.
|
|
5
7
|
- Versions come from git tags: a tag `vX.Y.Z` is that release, and every commit on `main` after it is published automatically as a dev build `X.(Y+1).0.devN` (N = commits since the release). `pip install tuieval` keeps installing releases only; `pip install --pre tuieval` gets the latest build.
|
|
6
8
|
|
|
7
9
|
## 0.1.7 (replaces 0.1.6, withdrawn)
|
|
8
10
|
|
|
9
11
|
- `tuieval tune` starts warm for fine-tunes: when a model with the same architecture and tensor shapes is already tuned on this machine, its flags are the starting point and only speculative decoding and micro-batch are re-tried (~4-6 server starts instead of 8-15). It tunes in full if the inherited flags fail, change answers or are slower than the defaults. `--cold` (or `[tune] warm_start = false`) always tunes in full; `[tune] warm_retest` names the re-tried knobs.
|
|
10
|
-
- `tuieval export pi <model>` (and `tuieval tune --export-pi`) writes a model's serving settings to the pi coding agent: a llama
|
|
12
|
+
- `tuieval export pi <model>` (and `tuieval tune --export-pi`) writes a model's serving settings to the pi coding agent: a llama.cpp router presets section and pi's models.json. It shows the diff, asks, and backs every file up. See docs/models.md.
|
|
11
13
|
- `tuieval list` lists the models, with hidden ones separately (`--packs` lists the packs).
|
|
12
14
|
- `tuieval remove <model>` / `--hidden` removes models: their models.toml entry, results, tuning profiles and hidden mark, archived in removed/.
|
|
13
15
|
- `tuieval --help` gives every command its own line.
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: tuieval
|
|
3
|
-
Version: 0.2.0.
|
|
3
|
+
Version: 0.2.0.dev2
|
|
4
4
|
Summary: Evaluate local and frontier LLMs on your own questions: accuracy, speed, tokens and PASS/FAIL verdicts, in the terminal.
|
|
5
5
|
Project-URL: Homepage, https://github.com/ashe-wb/tuieval
|
|
6
6
|
Project-URL: Issues, https://github.com/ashe-wb/tuieval/issues
|
|
@@ -47,7 +47,7 @@ tuieval # open the TUI
|
|
|
47
47
|
|
|
48
48
|
Once you've added your own packs and models, the setup screen looks like this (packs on the left, models with a verdict code per use case on the right, the highlighted model's details below):
|
|
49
49
|
|
|
50
|
-
|
|
51
51
|
|
|
52
52
|
## What you get
|
|
53
53
|
|
|
@@ -21,7 +21,7 @@ tuieval # open the TUI
|
|
|
21
21
|
|
|
22
22
|
Once you've added your own packs and models, the setup screen looks like this (packs on the left, models with a verdict code per use case on the right, the highlighted model's details below):
|
|
23
23
|
|
|
24
|
-

|
|
25
25
|
|
|
26
26
|
## What you get
|
|
27
27
|
|
|
Binary file
|
|
@@ -68,7 +68,7 @@ The best server flags differ per model and per machine, so tuieval splits them b
|
|
|
68
68
|
|
|
69
69
|
## Machines
|
|
70
70
|
|
|
71
|
-
- **Machine id** is detected automatically (`
|
|
71
|
+
- **Machine id** is detected automatically (e.g. `m3max-64gb`, `m2-16gb`; set `EVALS_MACHINE` to rename it). Every result records the machine, the server version and the exact speed flags used. `tuieval machines` lists this machine and every other machine that has run the evals (they record themselves in `tuning/`).
|
|
72
72
|
- **Fit check (Apple Silicon, llama):** before starting a GGUF, tuieval reads its header (layers, KV heads, hybrid attention layers) and picks the largest context that fits this machine's GPU memory, capped at `max_ctx`. A model that can't fit at 8k context is skipped with *doesn't fit on <machine>* instead of swapping. Packs that need more context than fits are skipped. It never quantizes the KV cache on its own, since that changes answers.
|
|
73
73
|
- **Per-machine settings** go under `[machines.<id>]`: `memory_headroom_gb` (GPU memory kept free for macOS, default 4) and `gpu_residency_gb` (see the stall guard).
|
|
74
74
|
|
|
@@ -90,18 +90,18 @@ The knobs are `[servers.<name>.tune]` in `models.toml`: each knob is a list of o
|
|
|
90
90
|
|
|
91
91
|
`tuieval export pi <model>` makes pi serve a model the way the evals did: the same file, the output-affecting flags, the context from the fit check, the model's sampling, and the speed flags tuned on this machine. `tuieval tune <model> --export-pi` does it right after tuning.
|
|
92
92
|
|
|
93
|
-
It writes a `[<id>]` section in llama
|
|
93
|
+
It writes a `[<id>]` section in the model presets file of a llama.cpp router (`llama-server --models-preset <file>`; keys that equal its `[*]` section are left out) and an entry under pi's `llama` provider `modelOverrides` (name, context window, vision, reasoning). It exports models on llama servers.
|
|
94
94
|
|
|
95
|
-
It shows the diff and the notes first (untuned or outdated tuning, other preset sections that name missing files, a reasoning effort to pick in pi), asks, backs every file up as `<file>.bak-tuieval-<time>`, and refuses to write a file that changed in the meantime. `--dry-run` only shows; `--yes` doesn't ask. Restart the router afterwards
|
|
95
|
+
It shows the diff and the notes first (untuned or outdated tuning, other preset sections that name missing files, a reasoning effort to pick in pi), asks, backs every file up as `<file>.bak-tuieval-<time>`, and refuses to write a file that changed in the meantime. `--dry-run` only shows; `--yes` doesn't ask. Restart the router afterwards so it reads the new presets.
|
|
96
96
|
|
|
97
97
|
The id pi sees defaults to the GGUF's name; set `pi_id` and `pi_name` on the model (or pass `--id`/`--name`). Paths and provider names come from `[export.pi]` in `models.toml`:
|
|
98
98
|
|
|
99
99
|
```toml
|
|
100
100
|
[export.pi]
|
|
101
|
-
presets = "
|
|
102
|
-
pi_models = "~/.pi/agent/models.json"
|
|
101
|
+
presets = "/path/to/presets.ini" # required: the router's --models-preset file
|
|
102
|
+
pi_models = "~/.pi/agent/models.json" # pi's default
|
|
103
103
|
llama_provider = "llama" # pi's provider name for the router
|
|
104
|
-
servers = ["llama"] # models.toml servers
|
|
104
|
+
servers = ["llama"] # models.toml servers the router can serve
|
|
105
105
|
```
|
|
106
106
|
|
|
107
107
|
## Speed verdicts
|
|
@@ -110,7 +110,7 @@ Speed is judged separately, per machine: the same model can be production-grade
|
|
|
110
110
|
|
|
111
111
|
## The stall guard (Apple Silicon)
|
|
112
112
|
|
|
113
|
-
|
|
113
|
+
On Apple Silicon Macs, once the system's GPU allocations pass about half of RAM, the GPU driver evicts and re-maps memory on every GPU job, the server spends 70–95% of its CPU in the kernel while the GPU idles, and servers that submit many small GPU jobs slow to a crawl. For servers with `stall_guard = true`, tuieval samples the server's own vs kernel CPU time and the system's GPU allocation every 5 s during runs and tuning. If more than 70% of its CPU goes to the kernel for a minute, the run stops with an explanation instead of crawling for hours. Finished answers are kept and resume next time. If your machine behaves differently, set `gpu_residency_gb` under `[machines.<id>]`.
|
|
114
114
|
|
|
115
115
|
## Server options
|
|
116
116
|
|
|
@@ -18,7 +18,7 @@ version_tuple: tuple[int | str, ...]
|
|
|
18
18
|
commit_id: str | None
|
|
19
19
|
__commit_id__: str | None
|
|
20
20
|
|
|
21
|
-
__version__ = version = '0.2.0.
|
|
22
|
-
__version_tuple__ = version_tuple = (0, 2, 0, '
|
|
21
|
+
__version__ = version = '0.2.0.dev2'
|
|
22
|
+
__version_tuple__ = version_tuple = (0, 2, 0, 'dev2')
|
|
23
23
|
|
|
24
24
|
__commit_id__ = commit_id = None
|
|
@@ -3,7 +3,7 @@
|
|
|
3
3
|
Usage:
|
|
4
4
|
tuieval compare # everything in results/<model>/<pack>.json
|
|
5
5
|
tuieval compare --speed # speed & tokens table (TTFT, tok/s, tokens, memory)
|
|
6
|
-
tuieval compare --machine
|
|
6
|
+
tuieval compare --machine m3max-64gb # speed on another machine (measured there, or projected)
|
|
7
7
|
tuieval compare --pairwise --failures # is each difference real? which tests failed?
|
|
8
8
|
tuieval compare results/some-model/*.json # specific files
|
|
9
9
|
"""
|
|
@@ -1,17 +1,18 @@
|
|
|
1
1
|
"""Export a model's serving settings to the pi coding agent, so pi serves it exactly as the evals did:
|
|
2
2
|
the same model file, output-affecting flags and context, plus the speed flags tuned on this machine.
|
|
3
3
|
|
|
4
|
-
a section in llama
|
|
5
|
-
left out) and an entry under pi's `llama` provider modelOverrides.
|
|
4
|
+
a section in a llama.cpp router's model presets file (llama-server --models-preset; keys that
|
|
5
|
+
equal its [*] section are left out) and an entry under pi's `llama` provider modelOverrides.
|
|
6
|
+
Models on llama servers only.
|
|
6
7
|
|
|
7
8
|
Every file is backed up next to itself (<file>.bak-tuieval-<time>) before it changes, and the diff
|
|
8
9
|
is shown first. Paths come from models.toml [export.pi]:
|
|
9
10
|
|
|
10
11
|
[export.pi]
|
|
11
|
-
presets = "
|
|
12
|
+
presets = "/path/to/presets.ini" # required: the router's --models-preset file
|
|
12
13
|
pi_models = "~/.pi/agent/models.json"
|
|
13
14
|
llama_provider = "llama" # pi's provider name for the router
|
|
14
|
-
servers = ["llama"] # models.toml servers
|
|
15
|
+
servers = ["llama"] # models.toml servers the router can serve
|
|
15
16
|
"""
|
|
16
17
|
import configparser
|
|
17
18
|
import difflib
|
|
@@ -23,7 +24,7 @@ import time
|
|
|
23
24
|
|
|
24
25
|
from . import engine as engine_mod
|
|
25
26
|
|
|
26
|
-
DEFAULTS = {"presets":
|
|
27
|
+
DEFAULTS = {"presets": None, "pi_models": "~/.pi/agent/models.json",
|
|
27
28
|
"llama_provider": "llama", "servers": ["llama"]}
|
|
28
29
|
# llama.cpp short flags -> the long names presets use as keys
|
|
29
30
|
SHORT = {"-m": "model", "-c": "ctx-size", "-t": "threads", "-tb": "threads-batch", "-ub": "ubatch-size",
|
|
@@ -127,7 +128,7 @@ def plan(eng, label, model_id=None, name=None):
|
|
|
127
128
|
m = eng.model(label)
|
|
128
129
|
s = settings(eng)
|
|
129
130
|
if m["server"] not in s["servers"]:
|
|
130
|
-
raise ExportError(f"{label} runs on the {m['server']} server; pi export writes llama
|
|
131
|
+
raise ExportError(f"{label} runs on the {m['server']} server; pi export writes llama.cpp router presets, "
|
|
131
132
|
"for llama servers ([export.pi] servers lists them)")
|
|
132
133
|
model_id = model_id or m.get("pi_id") or default_id(m)
|
|
133
134
|
name = name or m.get("pi_name") or model_id
|
|
@@ -157,6 +158,8 @@ def plan(eng, label, model_id=None, name=None):
|
|
|
157
158
|
for k, key in SAMPLING_KEYS.items():
|
|
158
159
|
if sampling.get(k) is not None:
|
|
159
160
|
flags[key] = str(sampling[k])
|
|
161
|
+
if not s.get("presets"):
|
|
162
|
+
raise ExportError("set [export.pi] presets in models.toml to your llama.cpp router's --models-preset file")
|
|
160
163
|
path = engine_mod.expand(s["presets"])
|
|
161
164
|
old = _read(path)
|
|
162
165
|
if not old:
|
|
@@ -183,7 +186,7 @@ def plan(eng, label, model_id=None, name=None):
|
|
|
183
186
|
"maxTokens": entry.get("maxTokens", sampling.get("max_tokens")),
|
|
184
187
|
"reasoning": bool(sampling.get("enable_thinking", True)),
|
|
185
188
|
"input": ["text", "image"] if vision else ["text"]})
|
|
186
|
-
notes.append("restart llama
|
|
189
|
+
notes.append("restart the llama.cpp router so it reads the new presets")
|
|
187
190
|
if sampling.get("reasoning_effort"):
|
|
188
191
|
notes.append(f"the evals ran reasoning_effort {sampling['reasoning_effort']}: pick that thinking level in pi")
|
|
189
192
|
pi_new = json.dumps(pi, indent=2, ensure_ascii=False) + "\n"
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
"""Which machine this is, what a model needs, and whether it fits.
|
|
2
2
|
|
|
3
|
-
detect() -> Machine (chip, cores, RAM, GPU memory limit, id like "
|
|
3
|
+
detect() -> Machine (chip, cores, RAM, GPU memory limit, id like "m3max-64gb")
|
|
4
4
|
read_gguf(path) -> GGUF header facts (architecture, layers, KV heads, context length, …)
|
|
5
5
|
fit(model_path, …) -> Fit (largest context that fits this machine, estimated memory)
|
|
6
6
|
|
|
@@ -219,8 +219,7 @@ def swapped_out_bytes():
|
|
|
219
219
|
|
|
220
220
|
|
|
221
221
|
# ---------------------------------------------------------------- GPU residency
|
|
222
|
-
#
|
|
223
|
-
# of RAM, the GPU driver evicts and re-maps memory on every command submission (70-95% of the
|
|
222
|
+
# On Apple Silicon Macs, once the system's GPU allocations exceed about half of RAM, the GPU driver evicts and re-maps memory on every command submission (70-95% of the
|
|
224
223
|
# server's CPU in the kernel, GPU idle), whatever iogpu.wired_limit_mb says. Servers that submit
|
|
225
224
|
# many small GPU jobs collapse; see the stall guard in docs/models.md.
|
|
226
225
|
RESIDENCY_FRACTION = 0.5
|
|
@@ -576,7 +576,7 @@ def cmd_export(argv):
|
|
|
576
576
|
description="Write a model's serving settings (model file, output-affecting flags, "
|
|
577
577
|
"context and the speed flags tuned on this machine) to another tool. "
|
|
578
578
|
"Shows the diff and asks first; every file is backed up.")
|
|
579
|
-
p.add_argument("target", choices=["pi"], help="pi: the pi coding agent (llama
|
|
579
|
+
p.add_argument("target", choices=["pi"], help="pi: the pi coding agent (llama.cpp router presets and pi's "
|
|
580
580
|
"models.json)")
|
|
581
581
|
p.add_argument("labels", nargs="+", help="models to export")
|
|
582
582
|
p.add_argument("--id", help="the model id pi sees (default: models.toml pi_id, else the GGUF's name)")
|
|
@@ -107,7 +107,7 @@ headers = { "X-Title" = "tuieval" }
|
|
|
107
107
|
# cmd = ["~/llama.cpp/build/bin/llama-bench"]
|
|
108
108
|
|
|
109
109
|
# Optional per-machine settings, by machine id (tuieval machines shows the ids).
|
|
110
|
-
# [machines.
|
|
110
|
+
# [machines.m3max-64gb]
|
|
111
111
|
# memory_headroom_gb = 3 # GPU memory kept free for macOS and other apps (default 4)
|
|
112
112
|
# gpu_residency_gb = 12 # GPU memory the driver keeps resident before churning (default: half of RAM)
|
|
113
113
|
|
|
@@ -398,6 +398,11 @@ class ExportPi(unittest.TestCase):
|
|
|
398
398
|
pi = json.loads(next(c for c in changes if c.path.endswith("models.json")).new)
|
|
399
399
|
self.assertEqual(pi["providers"]["llama"]["modelOverrides"]["Old"]["contextWindow"], 98304)
|
|
400
400
|
|
|
401
|
+
def test_presets_path_is_required(self):
|
|
402
|
+
del self.eng.cfg["export"]["pi"]["presets"]
|
|
403
|
+
with self.assertRaises(self.export.ExportError):
|
|
404
|
+
self.export.plan(self.eng, "l")
|
|
405
|
+
|
|
401
406
|
def test_only_llama_servers(self):
|
|
402
407
|
with self.assertRaises(self.export.ExportError):
|
|
403
408
|
self.export.plan(self.eng, "s")
|
|
Binary file
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|