tuieval 0.2.0.dev108__tar.gz → 0.2.0.dev116__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/CHANGELOG.md +4 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/PKG-INFO +2 -2
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/README.md +1 -1
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/writing-packs.md +5 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/_version.py +2 -2
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/client.py +5 -0
- tuieval-0.2.0.dev116/src/tuieval/dates.py +164 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/engine.py +4 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/packs.py +1 -1
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/pta.py +9 -4
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/tui.py +127 -24
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/tests/mock_server.py +14 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/tests/test_tuieval.py +170 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/.gitignore +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/LICENSE +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/RELEASING.md +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/README.md +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/favicon.ico +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/readme-header.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/social-preview.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-1024.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-128.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-16.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-16.svg +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-256.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-32.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-48.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-512.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-64.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon-animated.svg +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/brand/tuieval-icon.svg +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/tui-answer-reasoning.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/tui-run-reasoning.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/images/tui-setup.png +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/docs/models.md +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/pyproject.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/__init__.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/__main__.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/builtin.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/cli.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/compare.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/doctor.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/export.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/graders/__init__.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/graders/answer.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/graders/code.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/graders/rag.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/graders/reply.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/graders/tool_call.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/insights.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/logs.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/machines.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/onboard.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/profiles.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/remove.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/run_evals.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/scaffold.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/selftest.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/models.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/answer/pack.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/answer/system.txt +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/answer/tests.yaml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/code/pack.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/code/system.txt +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/code/tests.yaml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/rag/pack.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/rag/system.txt +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/rag/tests.yaml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/reply/pack.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/reply/system.txt +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/reply/tests.yaml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/pack.toml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/system.txt +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/tests.yaml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/tools.yaml +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/tune.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/verdict.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/watch_proxy.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/workspace.py +0 -0
- {tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/yamlout.py +0 -0
|
@@ -2,6 +2,10 @@
|
|
|
2
2
|
|
|
3
3
|
## Unreleased
|
|
4
4
|
|
|
5
|
+
- Fix: a server that crashes mid-request (the stream ends with no finish reason) was graded as an empty or cut-short answer; it's a server error now, never counted against the model.
|
|
6
|
+
- Dates: answers record `answered_at` (older ones read it from their log name); tests get an added date (an `added` field, or the day tuieval first saw them, in `test-dates.json`). Shown in the answer view, Pick tests, Per question, Failures and Production readiness.
|
|
7
|
+
- Copy reasoning: `y` in the answer view copies its full reasoning, `a` the answer; `y` on the run screen copies the reasoning streamed so far. Uses pbcopy, wl-copy, xclip, xsel or clip, else the terminal (OSC 52).
|
|
8
|
+
- PTA index: click a model's name to remove it from view (every Results tab follows); click it under the bars to bring it back, or show all.
|
|
5
9
|
- The Models heading shows how many are selected, naming any the filter hides; Start asks first when some are hidden.
|
|
6
10
|
- Results → Failures: a Models button filters the list (the same pick as the other tabs), with the number of failures shown.
|
|
7
11
|
- Fix: an answer followed by a stray `</think>` (or a stray code fence after it) was graded as empty; the answer before the tag is graded now. The code grader also reads a doubled ```` ```python ```` fence as one.
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: tuieval
|
|
3
|
-
Version: 0.2.0.
|
|
3
|
+
Version: 0.2.0.dev116
|
|
4
4
|
Summary: Evaluate local and frontier LLMs on your own questions: accuracy, speed, tokens and PASS/FAIL verdicts, in the terminal.
|
|
5
5
|
Project-URL: Homepage, https://github.com/ashe-wb/tuieval
|
|
6
6
|
Project-URL: Issues, https://github.com/ashe-wb/tuieval/issues
|
|
@@ -66,7 +66,7 @@ While a run goes, you watch each question's reasoning and answer stream in:
|
|
|
66
66
|
|
|
67
67
|
|
|
68
68
|
|
|
69
|
-
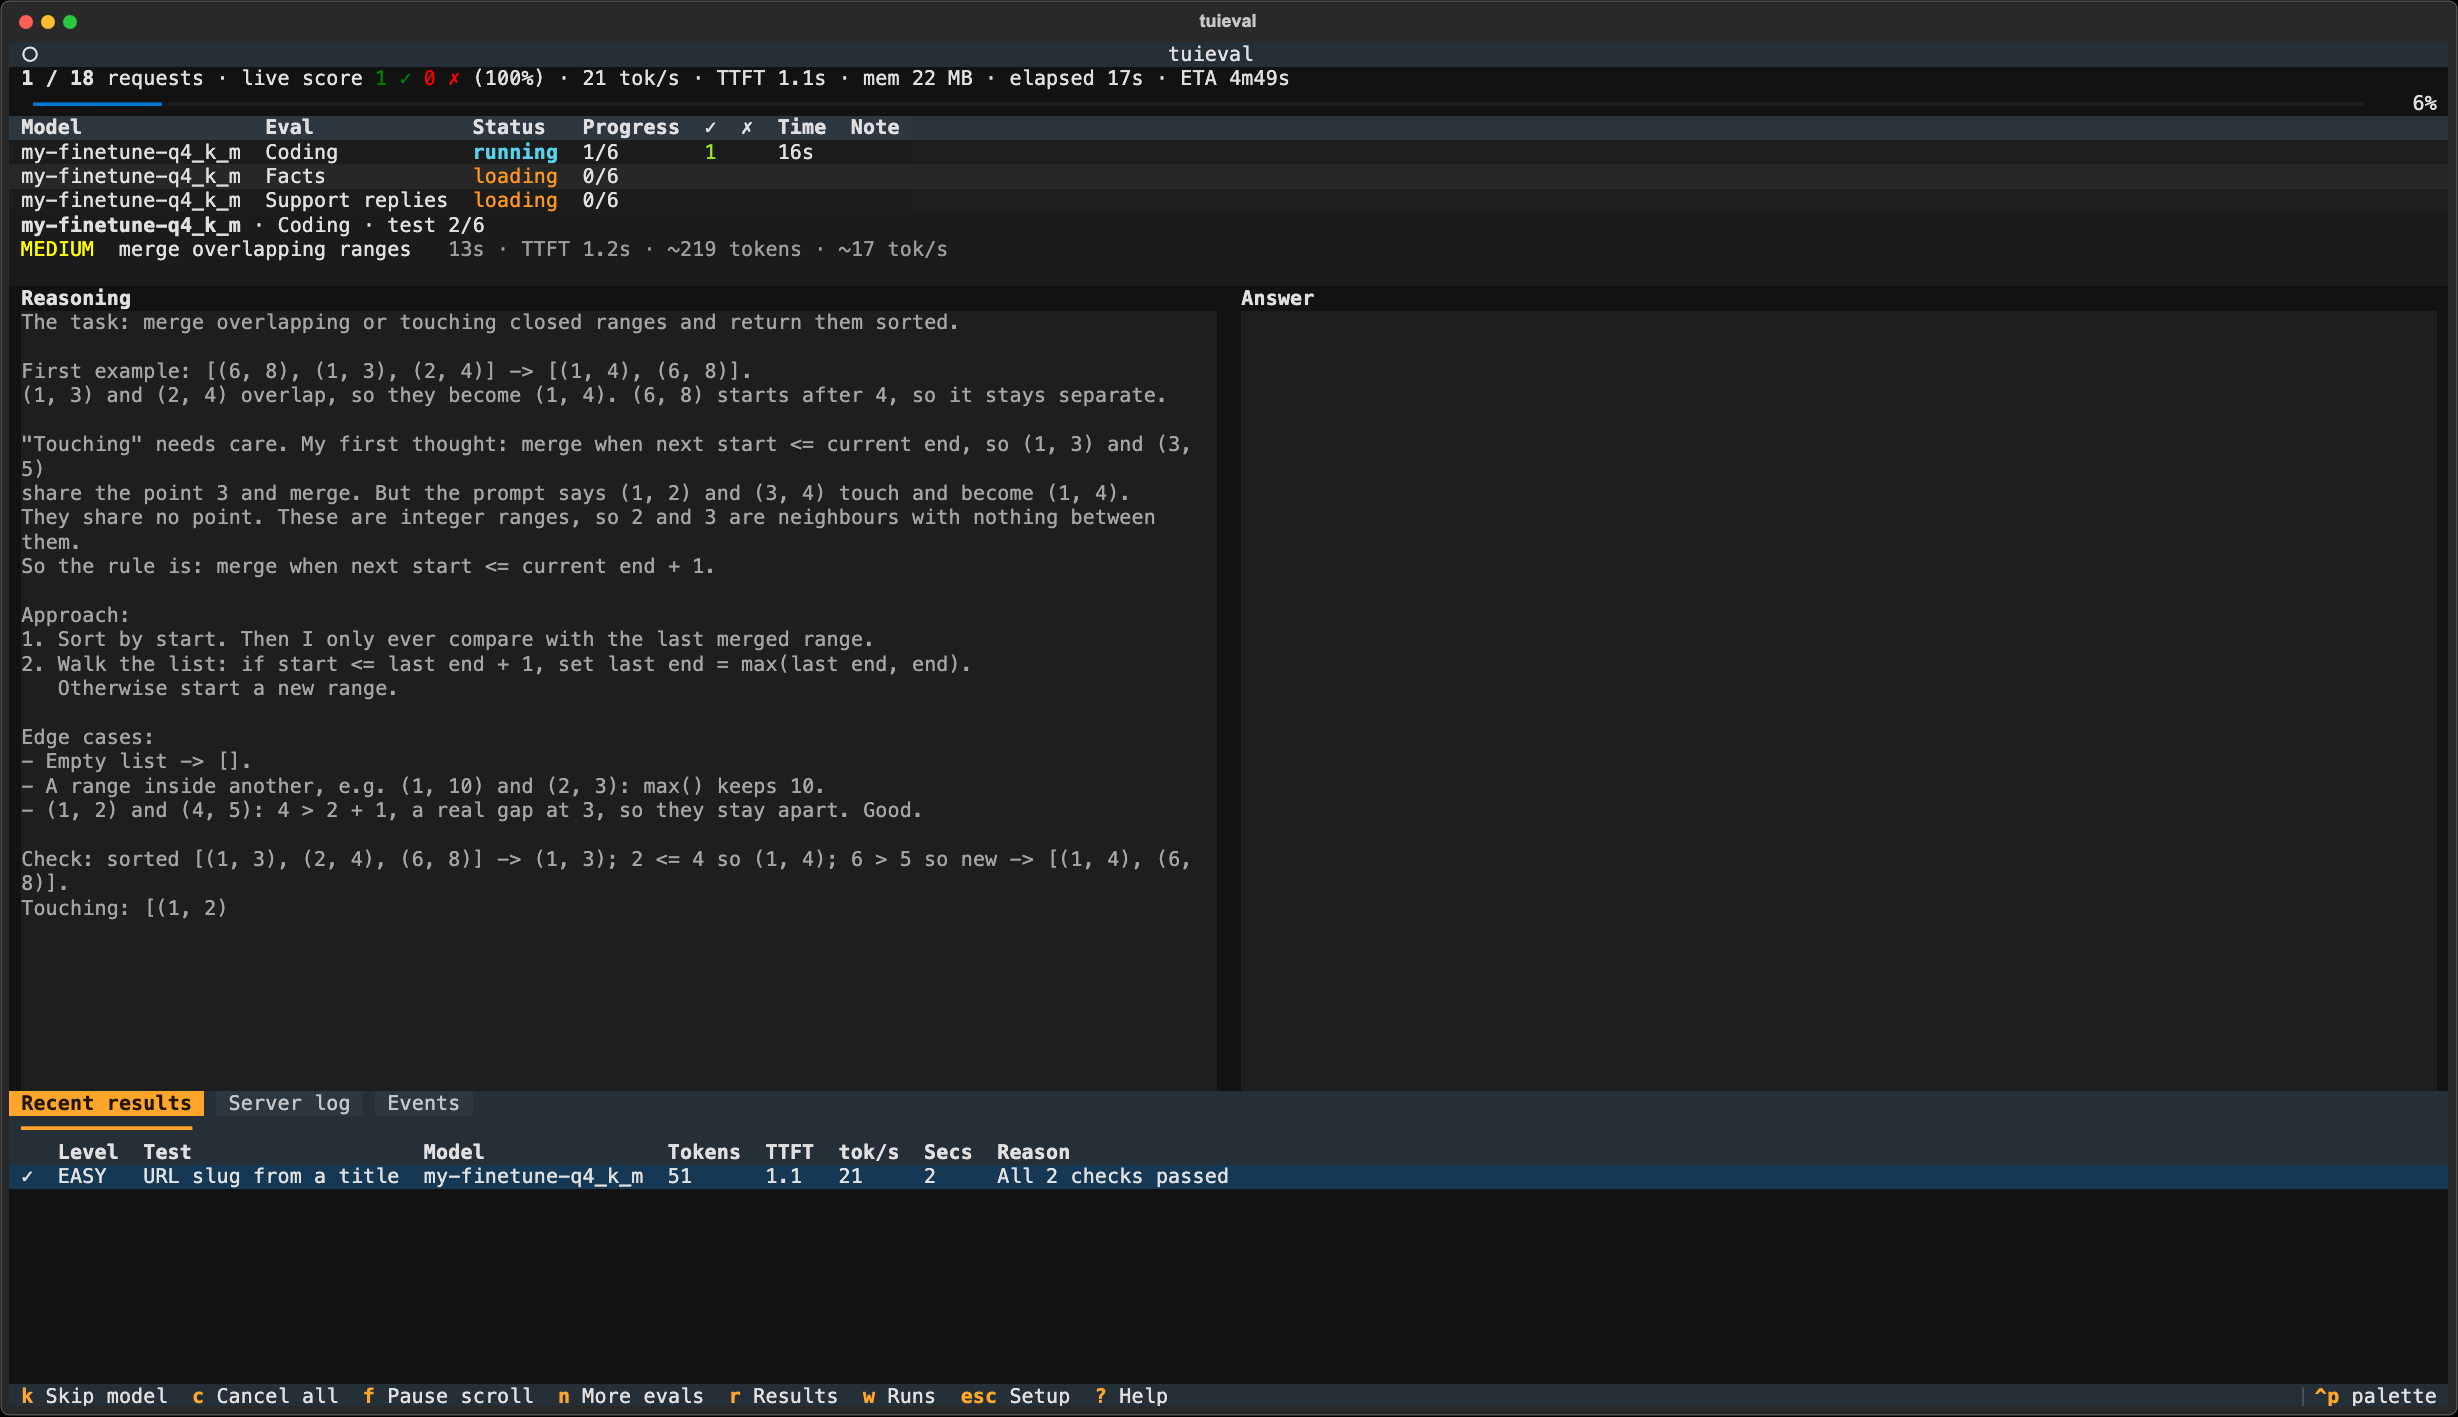
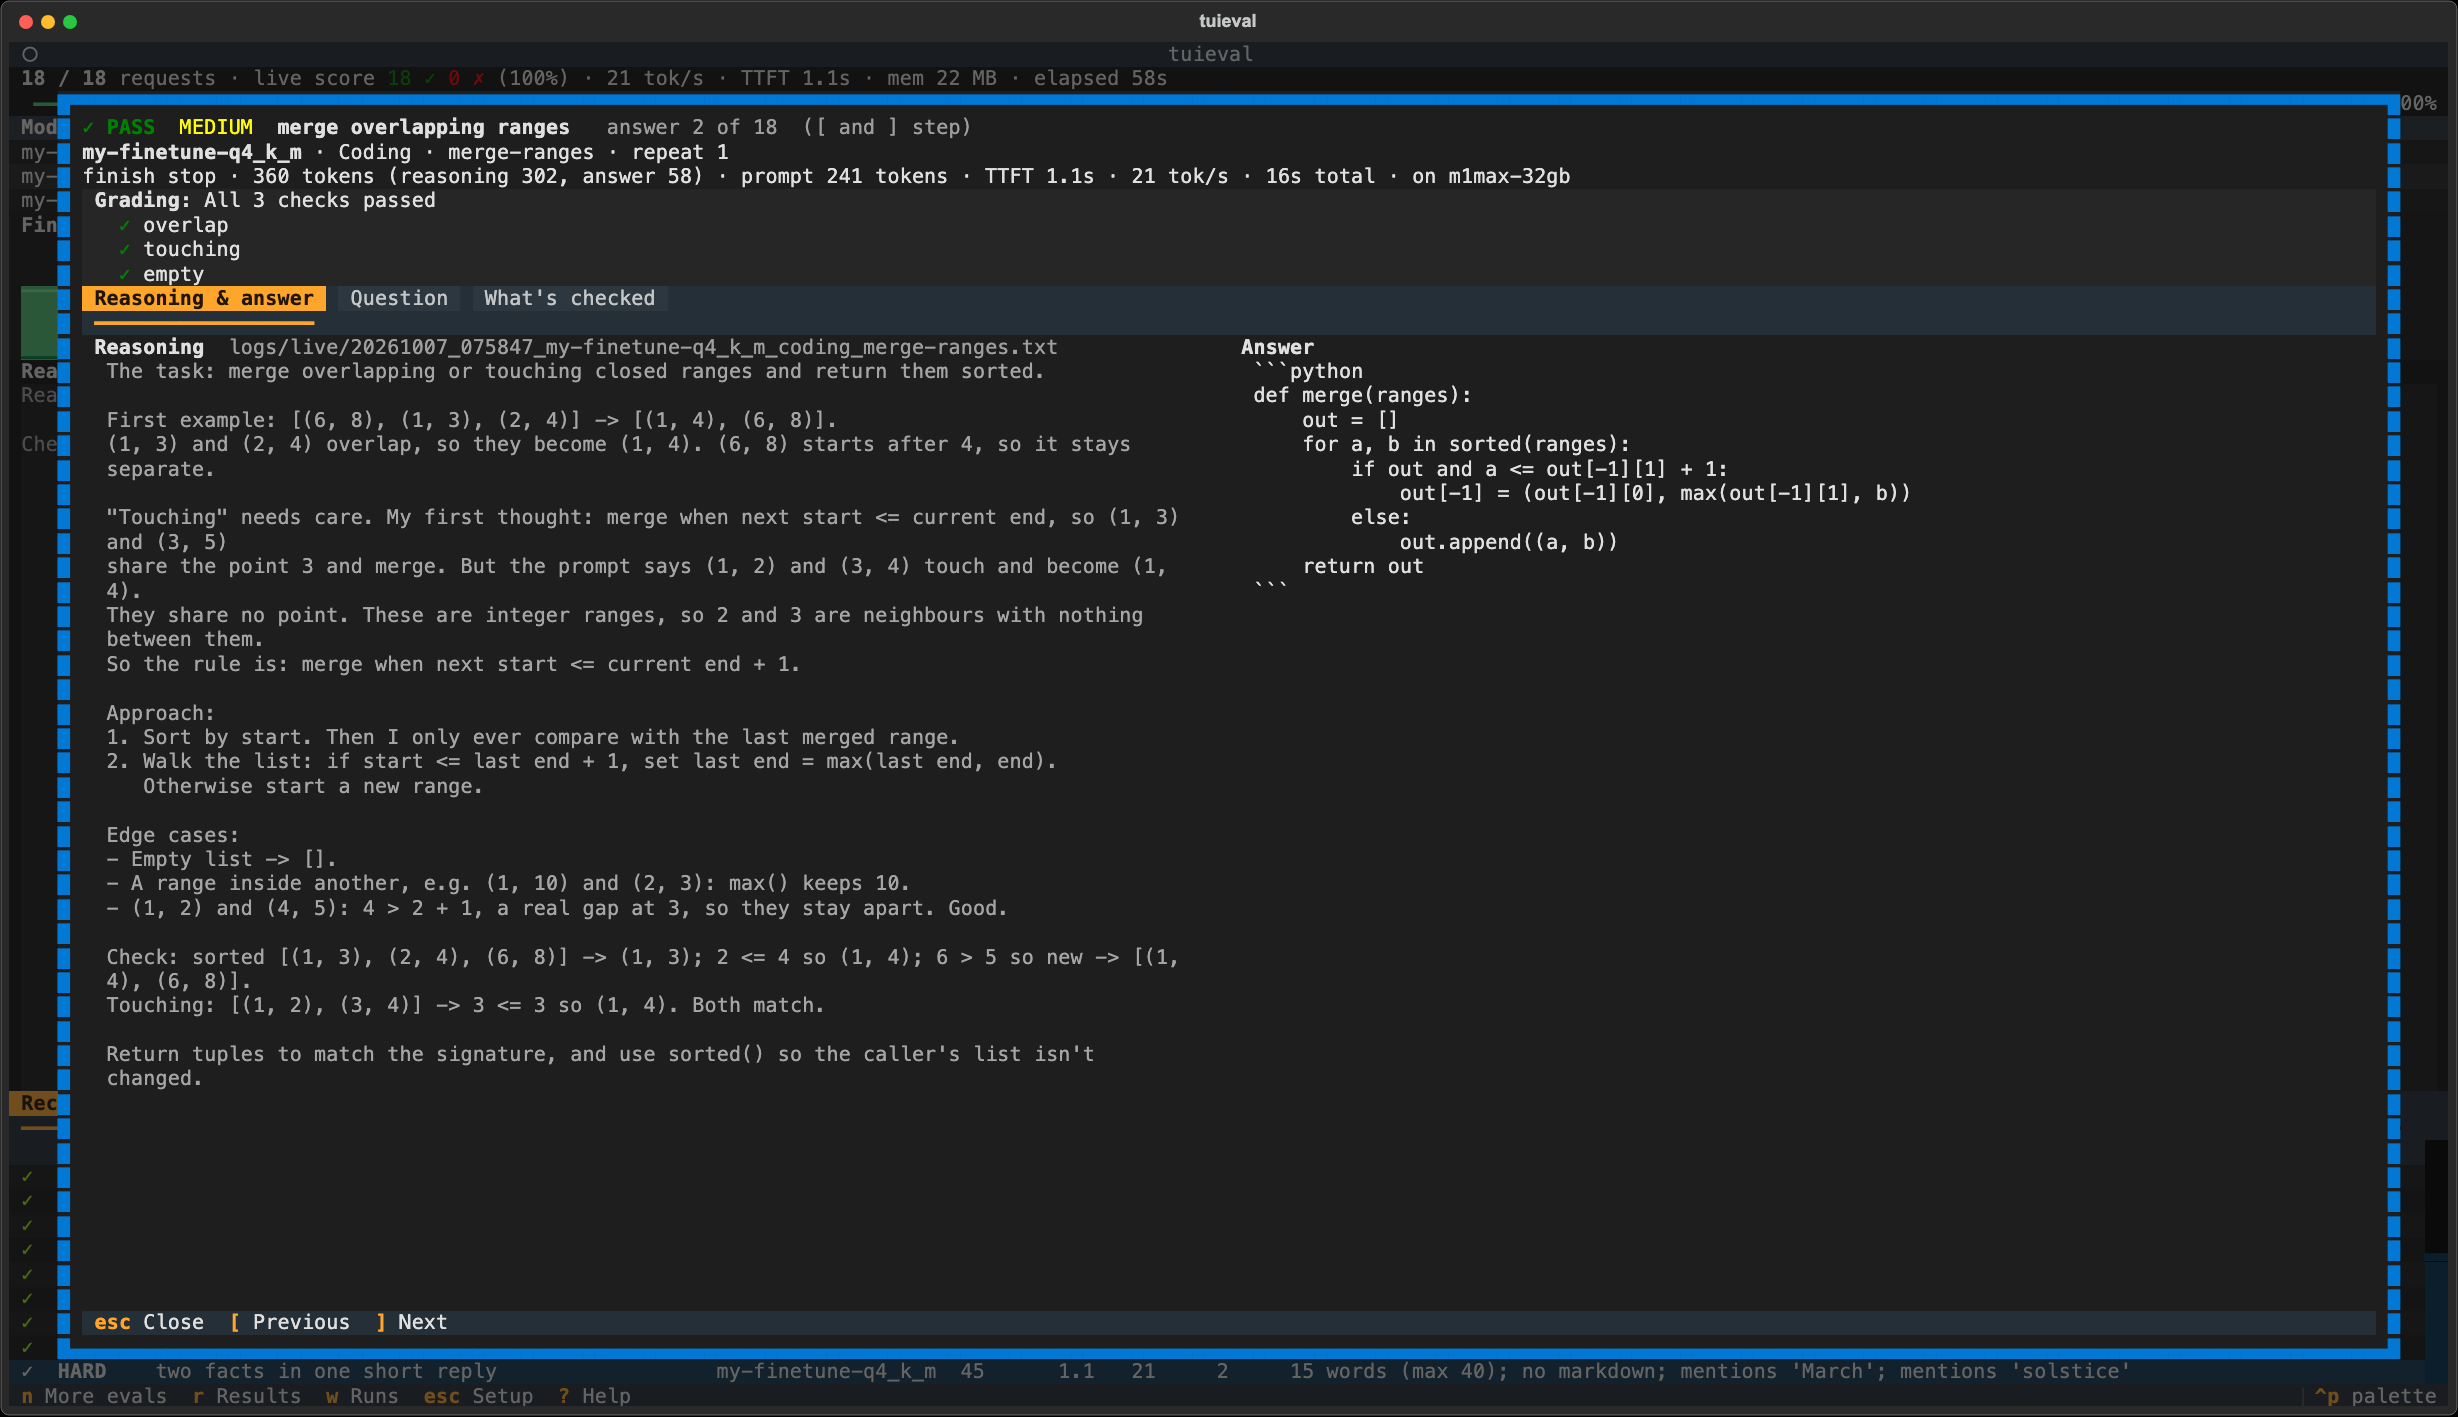
Afterwards, every answer keeps its reasoning. Enter on a result opens it with the grade and each check, the full reasoning and the answer; `[` and `]` step through the others:
|
|
69
|
+
Afterwards, every answer keeps its reasoning. Enter on a result opens it with the grade and each check, the full reasoning and the answer; `[` and `]` step through the others, `y` copies the reasoning and `a` the answer (on the run screen, `y` copies the reasoning streamed so far):
|
|
70
70
|
|
|
71
71
|
|
|
72
72
|
|
|
@@ -40,7 +40,7 @@ While a run goes, you watch each question's reasoning and answer stream in:
|
|
|
40
40
|
|
|
41
41
|

|
|
42
42
|
|
|
43
|
-
Afterwards, every answer keeps its reasoning. Enter on a result opens it with the grade and each check, the full reasoning and the answer; `[` and `]` step through the others:
|
|
43
|
+
Afterwards, every answer keeps its reasoning. Enter on a result opens it with the grade and each check, the full reasoning and the answer; `[` and `]` step through the others, `y` copies the reasoning and `a` the answer (on the run screen, `y` copies the reasoning streamed so far):
|
|
44
44
|
|
|
45
45
|

|
|
46
46
|
|
|
@@ -63,6 +63,7 @@ min_consistency = 0.95 # share of variant groups where every variant p
|
|
|
63
63
|
description: refund window # shown while running and in results
|
|
64
64
|
category: policy # optional grouping (Screen runs spread across categories)
|
|
65
65
|
difficulty: medium # easy | medium | hard: your label, shown in the TUI, never sent to the model
|
|
66
|
+
added: 2026-10-14 # optional: when the test was written (see Dates below)
|
|
66
67
|
input: | # the user message
|
|
67
68
|
A customer bought shoes 20 days ago …
|
|
68
69
|
image: images/receipt.png # optional: sent as an image (needs vision)
|
|
@@ -185,6 +186,10 @@ Every test has a `difficulty` of easy, medium or hard. It's for you, not the mod
|
|
|
185
186
|
|
|
186
187
|
A useful convention: **easy** = one rule or a direct read; **medium** = arithmetic, one trap, or two conditions; **hard** = rules in conflict, multi-step reasoning, or misleading data. Once several models have run, `tuieval items` flags labels the results contradict ("easier than labelled": a hard test every model passes; "harder than labelled": an easy test most models fail). `tuieval selftest` warns about tests without a label.
|
|
187
188
|
|
|
189
|
+
## Dates
|
|
190
|
+
|
|
191
|
+
Every answer records when it was given (`answered_at`); answers from before that field existed get the time from their log file's name. Every test has an added date: its own `added` field if it has one, otherwise the day tuieval first saw it, kept in `test-dates.json` at the workspace root. Tests that were already there when that file was started get the day of their first answer, or the day the file was started, shown as `≤ 2026-10-01` (on or before). Neither date changes the pack's fingerprint. The TUI shows them in the answer view, Pick tests, Results → Per question (Added), Failures and Production readiness (Answered).
|
|
192
|
+
|
|
188
193
|
## Writing tests that separate production-ready models
|
|
189
194
|
|
|
190
195
|
- **Spec every behaviour you check.** A correct answer written only from the prompt must pass.
|
|
@@ -18,7 +18,7 @@ version_tuple: tuple[int | str, ...]
|
|
|
18
18
|
commit_id: str | None
|
|
19
19
|
__commit_id__: str | None
|
|
20
20
|
|
|
21
|
-
__version__ = version = '0.2.0.
|
|
22
|
-
__version_tuple__ = version_tuple = (0, 2, 0, '
|
|
21
|
+
__version__ = version = '0.2.0.dev116'
|
|
22
|
+
__version_tuple__ = version_tuple = (0, 2, 0, 'dev116')
|
|
23
23
|
|
|
24
24
|
__commit_id__ = commit_id = None
|
|
@@ -118,6 +118,7 @@ def stream_chat(base_url, body, on_delta=None, timeout=1800, stream=None, header
|
|
|
118
118
|
out = {"answer": "", "reasoning": "", "tool_calls": [], "finish": None, "usage": {}, "timings": {},
|
|
119
119
|
"ttft_s": None, "total_s": None, "error": None}
|
|
120
120
|
reasoning, answer, tools = [], [], {}
|
|
121
|
+
done = False # [DONE] seen
|
|
121
122
|
start = last = time.time()
|
|
122
123
|
try:
|
|
123
124
|
conn.request("POST", prefix + "/v1/chat/completions", body=json.dumps(body),
|
|
@@ -142,6 +143,7 @@ def stream_chat(base_url, body, on_delta=None, timeout=1800, stream=None, header
|
|
|
142
143
|
continue
|
|
143
144
|
payload = line[5:].strip()
|
|
144
145
|
if payload == "[DONE]":
|
|
146
|
+
done = True
|
|
145
147
|
break
|
|
146
148
|
chunk = json.loads(payload)
|
|
147
149
|
if chunk.get("error"): # OpenRouter reports mid-stream failures this way
|
|
@@ -173,6 +175,9 @@ def stream_chat(base_url, body, on_delta=None, timeout=1800, stream=None, header
|
|
|
173
175
|
if text:
|
|
174
176
|
answer.append(text)
|
|
175
177
|
on_delta and on_delta("answer", text)
|
|
178
|
+
if not out["error"] and not done and out["finish"] is None:
|
|
179
|
+
# the stream just ended: a server that crashed or dropped the connection, not the model's answer
|
|
180
|
+
out["error"] = "connection error: the stream ended before the server finished (no finish reason)"
|
|
176
181
|
except (OSError, http.client.HTTPException, ValueError) as e:
|
|
177
182
|
if stream.cancelled:
|
|
178
183
|
raise Cancelled() from None
|
|
@@ -0,0 +1,164 @@
|
|
|
1
|
+
"""When each answer was given, and when each test was added to its pack.
|
|
2
|
+
|
|
3
|
+
Answers record `answered_at` (local time with its UTC offset). Older answers have none, but their
|
|
4
|
+
log file name starts with the time the answer finished (logs/live/20261014_143741_…), so they get it
|
|
5
|
+
from that.
|
|
6
|
+
|
|
7
|
+
A test's date is its `added` field when it has one (tests.yaml: `added: 2026-10-14`). Otherwise
|
|
8
|
+
tuieval notes the day it first sees the test, in test-dates.json at the workspace root. Tests that were
|
|
9
|
+
already there when that file was started get the day of their first answer, or the day the file was
|
|
10
|
+
started, as "on or before" dates: the day they were really written isn't known.
|
|
11
|
+
"""
|
|
12
|
+
import datetime
|
|
13
|
+
import glob
|
|
14
|
+
import json
|
|
15
|
+
import os
|
|
16
|
+
import re
|
|
17
|
+
|
|
18
|
+
FILE = "test-dates.json"
|
|
19
|
+
_LOG_STAMP = re.compile(r"(\d{8}_\d{6})_")
|
|
20
|
+
_HISTORY = re.compile(r"-\d{8}-\d{6}(\.partial\.jsonl|\.json)$")
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def now():
|
|
24
|
+
return datetime.datetime.now().astimezone().isoformat(timespec="seconds")
|
|
25
|
+
|
|
26
|
+
|
|
27
|
+
def answered_at(rec):
|
|
28
|
+
"""When an answer finished (an aware datetime), or None if its result doesn't say."""
|
|
29
|
+
if rec.get("answered_at"):
|
|
30
|
+
try:
|
|
31
|
+
return datetime.datetime.fromisoformat(rec["answered_at"])
|
|
32
|
+
except ValueError:
|
|
33
|
+
return None
|
|
34
|
+
m = _LOG_STAMP.match(rec.get("log") or "")
|
|
35
|
+
if m:
|
|
36
|
+
try:
|
|
37
|
+
return datetime.datetime.strptime(m.group(1), "%Y%m%d_%H%M%S").astimezone()
|
|
38
|
+
except ValueError:
|
|
39
|
+
return None
|
|
40
|
+
return None
|
|
41
|
+
|
|
42
|
+
|
|
43
|
+
def day(dt):
|
|
44
|
+
return dt.strftime("%Y-%m-%d") if dt else ""
|
|
45
|
+
|
|
46
|
+
|
|
47
|
+
def minute(dt):
|
|
48
|
+
return dt.strftime("%Y-%m-%d %H:%M") if dt else ""
|
|
49
|
+
|
|
50
|
+
|
|
51
|
+
def span(dts):
|
|
52
|
+
"""'2026-10-14', or '2026-10-01 – 10-07' for answers given over several days."""
|
|
53
|
+
dts = [d for d in dts if d]
|
|
54
|
+
if not dts:
|
|
55
|
+
return ""
|
|
56
|
+
first, last = day(min(dts)), day(max(dts))
|
|
57
|
+
if first == last:
|
|
58
|
+
return first
|
|
59
|
+
return f"{first} – {last[5:] if first[:4] == last[:4] else last}"
|
|
60
|
+
|
|
61
|
+
|
|
62
|
+
def _explicit(test):
|
|
63
|
+
v = test.get("added")
|
|
64
|
+
if isinstance(v, datetime.datetime):
|
|
65
|
+
return v.date().isoformat()
|
|
66
|
+
if isinstance(v, datetime.date):
|
|
67
|
+
return v.isoformat()
|
|
68
|
+
if isinstance(v, str):
|
|
69
|
+
try:
|
|
70
|
+
return datetime.date.fromisoformat(v.strip()).isoformat()
|
|
71
|
+
except ValueError:
|
|
72
|
+
return None
|
|
73
|
+
return None
|
|
74
|
+
|
|
75
|
+
|
|
76
|
+
def first_answers(results_dir):
|
|
77
|
+
"""{(pack, test id): the earliest day it was answered} over every result, history and archive."""
|
|
78
|
+
first = {}
|
|
79
|
+
|
|
80
|
+
def note(pack, rec):
|
|
81
|
+
dt = answered_at(rec)
|
|
82
|
+
if pack and dt and rec.get("test"):
|
|
83
|
+
key, d = (pack, rec["test"]), day(dt)
|
|
84
|
+
if key not in first or d < first[key]:
|
|
85
|
+
first[key] = d
|
|
86
|
+
for path in glob.glob(os.path.join(glob.escape(results_dir), "**", "*.json*"), recursive=True):
|
|
87
|
+
base = os.path.basename(path)
|
|
88
|
+
try:
|
|
89
|
+
if base.endswith(".partial.jsonl"):
|
|
90
|
+
pack = _HISTORY.sub("", base) if _HISTORY.search(base) else base[:-len(".json.partial.jsonl")]
|
|
91
|
+
with open(path) as f:
|
|
92
|
+
for line in f:
|
|
93
|
+
rec = json.loads(line)
|
|
94
|
+
if "test" in rec:
|
|
95
|
+
note(pack, rec)
|
|
96
|
+
elif base.endswith(".json"):
|
|
97
|
+
with open(path) as f:
|
|
98
|
+
data = json.load(f)
|
|
99
|
+
if isinstance(data, dict) and data.get("format") == "evals/1":
|
|
100
|
+
for rec in data.get("results", []):
|
|
101
|
+
note(data["pack"]["name"], rec)
|
|
102
|
+
except (OSError, ValueError, KeyError, TypeError):
|
|
103
|
+
continue
|
|
104
|
+
return first
|
|
105
|
+
|
|
106
|
+
|
|
107
|
+
class AddedDates:
|
|
108
|
+
"""Each test's added date: {(pack, test id): (YYYY-MM-DD, exact)}. Not exact = on or before."""
|
|
109
|
+
|
|
110
|
+
def __init__(self, root, packs, results_dir):
|
|
111
|
+
self.path = os.path.join(root, FILE)
|
|
112
|
+
try:
|
|
113
|
+
with open(self.path) as f:
|
|
114
|
+
saved = json.load(f).get("tests", {})
|
|
115
|
+
started = True
|
|
116
|
+
except (OSError, ValueError, AttributeError):
|
|
117
|
+
saved, started = {}, False
|
|
118
|
+
self.dates = {}
|
|
119
|
+
missing = []
|
|
120
|
+
for name, pack in packs.items():
|
|
121
|
+
for t in pack.tests:
|
|
122
|
+
key = (name, t["id"])
|
|
123
|
+
given = _explicit(t)
|
|
124
|
+
if given:
|
|
125
|
+
self.dates[key] = (given, True)
|
|
126
|
+
elif f"{name}/{t['id']}" in saved:
|
|
127
|
+
s = saved[f"{name}/{t['id']}"]
|
|
128
|
+
self.dates[key] = (s["added"], s.get("how") == "seen")
|
|
129
|
+
else:
|
|
130
|
+
missing.append(key)
|
|
131
|
+
if not missing:
|
|
132
|
+
return
|
|
133
|
+
today = datetime.date.today().isoformat()
|
|
134
|
+
first = first_answers(results_dir)
|
|
135
|
+
for key in missing:
|
|
136
|
+
if key in first: # answered before tuieval noted it: on or before its first answer
|
|
137
|
+
saved[f"{key[0]}/{key[1]}"] = {"added": first[key], "how": "first answer"}
|
|
138
|
+
elif started: # new since the file was started
|
|
139
|
+
saved[f"{key[0]}/{key[1]}"] = {"added": today, "how": "seen"}
|
|
140
|
+
else: # already there when the file was started
|
|
141
|
+
saved[f"{key[0]}/{key[1]}"] = {"added": today, "how": "already there"}
|
|
142
|
+
s = saved[f"{key[0]}/{key[1]}"]
|
|
143
|
+
self.dates[key] = (s["added"], s["how"] == "seen")
|
|
144
|
+
try:
|
|
145
|
+
tmp = self.path + ".tmp"
|
|
146
|
+
with open(tmp, "w") as f:
|
|
147
|
+
json.dump({"about": "The day tuieval first saw each test (how: seen), or for tests it found "
|
|
148
|
+
"already there, a day on or before it. A test's own `added` field wins.",
|
|
149
|
+
"tests": dict(sorted(saved.items()))}, f, indent=1)
|
|
150
|
+
f.write("\n")
|
|
151
|
+
os.replace(tmp, self.path)
|
|
152
|
+
except OSError:
|
|
153
|
+
pass # a read-only workspace: the dates still show, they just aren't kept
|
|
154
|
+
|
|
155
|
+
def get(self, pack, test_id):
|
|
156
|
+
"""(YYYY-MM-DD, exact) or None."""
|
|
157
|
+
return self.dates.get((pack, test_id))
|
|
158
|
+
|
|
159
|
+
def text(self, pack, test_id):
|
|
160
|
+
"""'2026-10-14', '≤ 2026-10-01' (on or before), or ''."""
|
|
161
|
+
got = self.get(pack, test_id)
|
|
162
|
+
if not got:
|
|
163
|
+
return ""
|
|
164
|
+
return got[0] if got[1] else f"≤ {got[0]}"
|
|
@@ -51,6 +51,7 @@ import urllib.parse
|
|
|
51
51
|
import urllib.request
|
|
52
52
|
|
|
53
53
|
from . import client
|
|
54
|
+
from . import dates
|
|
54
55
|
from . import graders
|
|
55
56
|
from . import machines
|
|
56
57
|
from . import packs as packs_mod
|
|
@@ -714,6 +715,7 @@ class Engine:
|
|
|
714
715
|
self.cfg = load_config(self.models_path)
|
|
715
716
|
self.pack_errors = []
|
|
716
717
|
self.packs = packs_mod.load_packs(self.packs_dir, self.pack_errors)
|
|
718
|
+
self.test_dates = dates.AddedDates(root, self.packs, self.results_dir)
|
|
717
719
|
self._cancel = threading.Event()
|
|
718
720
|
self._main_lane = Lane()
|
|
719
721
|
self._here = threading.local() # .lane: the lane this thread runs
|
|
@@ -766,6 +768,7 @@ class Engine:
|
|
|
766
768
|
self._add_remote_models()
|
|
767
769
|
self.pack_errors = []
|
|
768
770
|
self.packs = packs_mod.load_packs(self.packs_dir, self.pack_errors)
|
|
771
|
+
self.test_dates = dates.AddedDates(self.root, self.packs, self.results_dir)
|
|
769
772
|
|
|
770
773
|
def emit(self, kind, **data):
|
|
771
774
|
try:
|
|
@@ -2348,6 +2351,7 @@ class Engine:
|
|
|
2348
2351
|
"severity": g.get("severity"), "answer": res["answer"], "tool_calls": res["tool_calls"],
|
|
2349
2352
|
"finish": res["finish"], "reasoning_chars": len(res["reasoning"]),
|
|
2350
2353
|
"log": log_name, # logs/live/<log>: the reasoning, which the result doesn't keep
|
|
2354
|
+
"answered_at": dates.now(),
|
|
2351
2355
|
**({"checks": g["checks"]} if "checks" in g else {}),
|
|
2352
2356
|
"machine": self.machine().id,
|
|
2353
2357
|
**({"quantization": ep.get("quantization")} if ep else {}),
|
|
@@ -132,7 +132,7 @@ def _read_tests(path):
|
|
|
132
132
|
# Fields that never reach the model or the grader's decision: editing them doesn't make
|
|
133
133
|
# results outdated.
|
|
134
134
|
NOT_FINGERPRINTED = {"reference", "wrong", "description", "category", "critical", "critical_trial", "group",
|
|
135
|
-
"captured_from", "captured_answer", "difficulty"}
|
|
135
|
+
"captured_from", "captured_answer", "difficulty", "added"}
|
|
136
136
|
DIFFICULTIES = ("easy", "medium", "hard")
|
|
137
137
|
|
|
138
138
|
|
|
@@ -117,12 +117,13 @@ def _blocks(width, v, most):
|
|
|
117
117
|
return max(1, min(width, round(width * v / most)))
|
|
118
118
|
|
|
119
119
|
|
|
120
|
-
def bars(result, width=20, markup=True):
|
|
120
|
+
def bars(result, width=20, markup=True, click=None):
|
|
121
121
|
"""Lines with a row per model and a bar each for P, T and A: the at-a-glance view. The P and T bars
|
|
122
122
|
are proportional to tokens and time (the longest is the model that used most; shorter is better),
|
|
123
123
|
with how many times the leanest / fastest model's beside them; the A bar is the share of answers
|
|
124
124
|
right (longer is better, full only when every answer passed), then the share cut off at max_tokens in
|
|
125
|
-
orange (▓ in plain text) and "(n% truncated)" beside it. markup=False gives plain text
|
|
125
|
+
orange (▓ in plain text) and "(n% truncated)" beside it. markup=False gives plain text; click (an
|
|
126
|
+
action, e.g. "screen.remove") makes each model's name a link calling it with the row's index."""
|
|
126
127
|
if not result["models"]:
|
|
127
128
|
return []
|
|
128
129
|
name_w = max(len(x["model"]) for x in result["models"])
|
|
@@ -133,7 +134,7 @@ def bars(result, width=20, markup=True):
|
|
|
133
134
|
sub = pad + "".join(f"{better:<{cell_w}}" for _, _, better, *_ in LETTERS)
|
|
134
135
|
lines = [f"[b]{head.rstrip()}[/b]" if markup else head.rstrip(), f"[dim]{sub.rstrip()}[/dim]" if markup else sub.rstrip()]
|
|
135
136
|
most = {m: max((x.get(m) or 0 for x in result["models"]), default=0) for _, _, _, m, _, _ in LETTERS}
|
|
136
|
-
for x in result["models"]:
|
|
137
|
+
for row, x in enumerate(result["models"]):
|
|
137
138
|
cells = []
|
|
138
139
|
for k, _, _, measure, shown, color in LETTERS:
|
|
139
140
|
if k == "A":
|
|
@@ -155,7 +156,11 @@ def bars(result, width=20, markup=True):
|
|
|
155
156
|
if markup else bar + cut_bar + rest)
|
|
156
157
|
cells.append(f"{bar} {num:>6}" + " " * max(0, cell_w - width - 1 - max(6, len(num))))
|
|
157
158
|
name = f"{x['model']:<{name_w}}"
|
|
158
|
-
|
|
159
|
+
if markup:
|
|
160
|
+
pad_w = name_w - len(x["model"])
|
|
161
|
+
name = (f"[@click={click}({row})]{rich_escape(x['model'])}[/]" + " " * pad_w if click
|
|
162
|
+
else rich_escape(name))
|
|
163
|
+
lines.append((f"{name} " + "".join(cells)).rstrip())
|
|
159
164
|
return lines
|
|
160
165
|
|
|
161
166
|
|
|
@@ -24,6 +24,8 @@ import glob
|
|
|
24
24
|
import json
|
|
25
25
|
import os
|
|
26
26
|
import re
|
|
27
|
+
import shutil
|
|
28
|
+
import subprocess
|
|
27
29
|
import threading
|
|
28
30
|
import time
|
|
29
31
|
|
|
@@ -43,6 +45,7 @@ from rich.cells import cell_len
|
|
|
43
45
|
from rich.text import Text
|
|
44
46
|
|
|
45
47
|
from . import compare
|
|
48
|
+
from . import dates
|
|
46
49
|
from . import engine
|
|
47
50
|
from . import verdict
|
|
48
51
|
|
|
@@ -289,6 +292,37 @@ class StreamView(TextArea):
|
|
|
289
292
|
self.call_after_refresh(lambda: self.scroll_to(y=max(0, self.max_scroll_y - from_end), animate=False))
|
|
290
293
|
|
|
291
294
|
|
|
295
|
+
CLIPBOARD_TOOLS = (["pbcopy"], ["wl-copy"], ["xclip", "-selection", "clipboard"], ["xsel", "--clipboard", "--input"],
|
|
296
|
+
["clip"])
|
|
297
|
+
|
|
298
|
+
|
|
299
|
+
def copy_text(app, text):
|
|
300
|
+
"""Put text on the system clipboard with the first tool here that takes it (pbcopy, wl-copy, xclip, xsel,
|
|
301
|
+
clip). Without one, the terminal is asked to (OSC 52), which not every terminal allows. True if a tool did."""
|
|
302
|
+
for cmd in CLIPBOARD_TOOLS:
|
|
303
|
+
if not shutil.which(cmd[0]):
|
|
304
|
+
continue
|
|
305
|
+
try:
|
|
306
|
+
subprocess.run(cmd, input=text.encode("utf-16" if cmd[0] == "clip" else "utf-8"),
|
|
307
|
+
capture_output=True, check=True, timeout=10)
|
|
308
|
+
return True
|
|
309
|
+
except (OSError, subprocess.SubprocessError):
|
|
310
|
+
continue # e.g. xclip without a display: try the next
|
|
311
|
+
app.copy_to_clipboard(text)
|
|
312
|
+
return False
|
|
313
|
+
|
|
314
|
+
|
|
315
|
+
def notify_copied(app, what, text, note=""):
|
|
316
|
+
if not text:
|
|
317
|
+
app.notify(f"No {what} to copy.", severity="warning")
|
|
318
|
+
elif copy_text(app, text):
|
|
319
|
+
app.notify(f"Copied {what}{note}: {len(text):,} chars.")
|
|
320
|
+
else:
|
|
321
|
+
app.notify(f"Sent {what}{note} ({len(text):,} chars) to the terminal's clipboard. If nothing pastes, "
|
|
322
|
+
"the terminal doesn't allow it: install a clipboard tool (wl-copy, xclip or xsel).",
|
|
323
|
+
severity="warning", timeout=10)
|
|
324
|
+
|
|
325
|
+
|
|
292
326
|
# ------------------------------------------------------------------ answer detail
|
|
293
327
|
def answer_entry(row):
|
|
294
328
|
"""An answer for AnswerScreen from a compare row (None when the row has no stored answer)."""
|
|
@@ -451,7 +485,7 @@ with the model's reasoning and answer as they stream, then recent results with t
|
|
|
451
485
|
PTA index parsimony (tokens), time and accuracy per model, a bar each: tokens and time
|
|
452
486
|
as long as they took (shorter is better; 2.4× = 2.4 times the best), accuracy
|
|
453
487
|
longer is better. Per-answer numbers, tok/s, TTFT and memory in the table.
|
|
454
|
-
Results open here.
|
|
488
|
+
Results open here. Click a model's name to remove it from view (every tab).
|
|
455
489
|
Production readiness one verdict per model and use case; the table says why and what to run next
|
|
456
490
|
Per question every question, model by model (filters: pack, level, Models disagree)
|
|
457
491
|
Failures every wrong answer with the grader's reason (filter: Models); enter opens it
|
|
@@ -511,11 +545,14 @@ class AnswerScreen(ModalScreen):
|
|
|
511
545
|
Binding("q", "close", "Close", show=False, priority=True),
|
|
512
546
|
Binding("left_square_bracket", "step(-1)", "Previous", priority=True),
|
|
513
547
|
Binding("right_square_bracket", "step(1)", "Next", priority=True),
|
|
548
|
+
Binding("y", "copy('reasoning')", "Copy reasoning", priority=True),
|
|
549
|
+
Binding("a", "copy('answer')", "Copy answer", priority=True),
|
|
514
550
|
]
|
|
515
551
|
|
|
516
552
|
def __init__(self, entries, index=0, what="answer"):
|
|
517
553
|
super().__init__()
|
|
518
554
|
self.entries, self.index, self.what = entries, index, what
|
|
555
|
+
self.texts = {} # what's shown: "reasoning", "answer" -> text, for the copy keys
|
|
519
556
|
|
|
520
557
|
def check_action(self, action, parameters):
|
|
521
558
|
return len(self.entries) > 1 if action == "step" else True
|
|
@@ -550,6 +587,9 @@ class AnswerScreen(ModalScreen):
|
|
|
550
587
|
self.index = (self.index + delta) % len(self.entries)
|
|
551
588
|
self.show()
|
|
552
589
|
|
|
590
|
+
def action_copy(self, what):
|
|
591
|
+
notify_copied(self.app, what, self.texts.get(what, ""))
|
|
592
|
+
|
|
553
593
|
def show(self):
|
|
554
594
|
e = self.app.engine
|
|
555
595
|
entry = self.entries[self.index]
|
|
@@ -579,11 +619,14 @@ class AnswerScreen(ModalScreen):
|
|
|
579
619
|
f"on {rec['machine']}" if rec.get("machine") else "",
|
|
580
620
|
f"[yellow]ran alongside {', '.join(rec['ran_alongside'])}[/yellow]" if rec.get("ran_alongside") else "",
|
|
581
621
|
f"seed {rec['seed']}" if "seed" in rec else ""]
|
|
622
|
+
when = dates.minute(dates.answered_at(rec))
|
|
623
|
+
added = e.test_dates.text(entry["pack"], rec["test"])
|
|
582
624
|
self.query_one("#answer-head", Static).update(
|
|
583
625
|
f"{mark} {diff_badge(rec.get('difficulty', 'unrated'))} [b]{rich_escape(rec.get('description', rec['test']))}[/b]"
|
|
584
626
|
f"{partial}{pos}\n"
|
|
585
627
|
f"[b]{entry['model']}[/b]{quant} · {pack.label if pack else entry['pack']} · {rec['test']} · "
|
|
586
|
-
f"repeat {rec.get('repeat', 0) + 1}
|
|
628
|
+
f"repeat {rec.get('repeat', 0) + 1}" + (f" · answered {when}" if when else "")
|
|
629
|
+
+ (f" · test added {added}" if added else "") + "\n"
|
|
587
630
|
+ " · ".join(f for f in facts if f))
|
|
588
631
|
grading = [f"[b]Grading:[/b] {rich_escape(rec.get('reason', ''))}"]
|
|
589
632
|
grading += [" " + line for line in check_lines(rec, test)]
|
|
@@ -608,6 +651,7 @@ class AnswerScreen(ModalScreen):
|
|
|
608
651
|
answer += "\n\n=== TOOL CALLS ===\n" + json.dumps(rec["tool_calls"], indent=2)
|
|
609
652
|
for wid, text in (("#answer-reasoning", reasoning), ("#answer-answer", answer or "(empty)")):
|
|
610
653
|
self.query_one(wid, TextArea).load_text(text)
|
|
654
|
+
self.texts = {"reasoning": reasoning, "answer": answer}
|
|
611
655
|
|
|
612
656
|
question, checked = "(test not found)", "(test not found)"
|
|
613
657
|
if test:
|
|
@@ -1946,7 +1990,9 @@ class PickTestsScreen(ModalScreen):
|
|
|
1946
1990
|
mark = "[b green]\\[✓][/]" if on else "[dim]\\[ ][/dim]"
|
|
1947
1991
|
tid = f"[b]{rich_escape(t['id'])}[/b]" if on else rich_escape(t["id"])
|
|
1948
1992
|
note = test_note(t)
|
|
1949
|
-
|
|
1993
|
+
added = self.app.engine.test_dates.text(self.pack.name, t["id"])
|
|
1994
|
+
return f"{mark} {diff_badge(t.get('difficulty', 'unrated'))} {tid}" + (f" [dim]{rich_escape(note)}[/dim]" if note else "") \
|
|
1995
|
+
+ (f" [dim]added {added}[/dim]" if added else "")
|
|
1950
1996
|
|
|
1951
1997
|
def fill(self, text):
|
|
1952
1998
|
ol = self.query_one("#pick-tests", OptionList)
|
|
@@ -2163,6 +2209,7 @@ class RunScreen(Screen):
|
|
|
2163
2209
|
Binding("c", "cancel_all", "Cancel all", priority=True),
|
|
2164
2210
|
Binding("f", "toggle_follow", "Pause scroll", priority=True),
|
|
2165
2211
|
Binding("v", "watch_next", "Next model", priority=True),
|
|
2212
|
+
Binding("y", "copy_reasoning", "Copy reasoning", priority=True),
|
|
2166
2213
|
Binding("n", "new_run", "More evals", priority=True),
|
|
2167
2214
|
Binding("r", "results", "Results", priority=True),
|
|
2168
2215
|
Binding("w", "runs", "Runs", priority=True),
|
|
@@ -2182,6 +2229,8 @@ class RunScreen(Screen):
|
|
|
2182
2229
|
self.follow = True
|
|
2183
2230
|
self.buf = {"reasoning": [], "answer": []}
|
|
2184
2231
|
self.buf_lock = threading.Lock()
|
|
2232
|
+
self.streamed = {"reasoning": [], "answer": []} # the watched answer so far, untrimmed (for y)
|
|
2233
|
+
self.streamed_whole = False # from its start (not joined midway with v)
|
|
2185
2234
|
self.req_live = {} # model label -> its request now: phase, ~tokens, started, last token
|
|
2186
2235
|
self.started = time.time()
|
|
2187
2236
|
self.req_started = None
|
|
@@ -2344,6 +2393,7 @@ class RunScreen(Screen):
|
|
|
2344
2393
|
v.clear()
|
|
2345
2394
|
for stream, text in parts.items():
|
|
2346
2395
|
if text:
|
|
2396
|
+
self.streamed[stream].append(text)
|
|
2347
2397
|
self.query_one(f"#{stream}", StreamView).append(text, self.follow)
|
|
2348
2398
|
self.req_tokens += max(1, len(text) // 4)
|
|
2349
2399
|
if self.req_first is None and self.req_started:
|
|
@@ -2364,6 +2414,7 @@ class RunScreen(Screen):
|
|
|
2364
2414
|
self.flush_streams()
|
|
2365
2415
|
self.query_one("#reasoning", StreamView).clear()
|
|
2366
2416
|
self.query_one("#answer", StreamView).clear()
|
|
2417
|
+
self.streamed, self.streamed_whole = {"reasoning": [], "answer": []}, True
|
|
2367
2418
|
self.req_started, self.req_tokens, self.req_first = time.time(), 0, None
|
|
2368
2419
|
job = d["job"]
|
|
2369
2420
|
rep_note = f" · repeat {d['repeat'] + 1}/{job.repeat}" if job.repeat > 1 else ""
|
|
@@ -2731,6 +2782,7 @@ class RunScreen(Screen):
|
|
|
2731
2782
|
v.clear()
|
|
2732
2783
|
self.query_one("#reasoning", StreamView).clear()
|
|
2733
2784
|
self.query_one("#answer", StreamView).clear()
|
|
2785
|
+
self.streamed, self.streamed_whole = {"reasoning": [], "answer": []}, False
|
|
2734
2786
|
self.req_started = None
|
|
2735
2787
|
self.current = f"Streaming [b]{self.watch}[/b] from its next answer…"
|
|
2736
2788
|
self.refresh_current()
|
|
@@ -2748,6 +2800,12 @@ class RunScreen(Screen):
|
|
|
2748
2800
|
self.follow = not self.follow
|
|
2749
2801
|
self.update_overall()
|
|
2750
2802
|
|
|
2803
|
+
def action_copy_reasoning(self):
|
|
2804
|
+
"""The streaming answer's reasoning so far, all of it (the pane drops the oldest text when it's long)."""
|
|
2805
|
+
self.flush_streams()
|
|
2806
|
+
notify_copied(self.app, "reasoning", "".join(self.streamed["reasoning"]),
|
|
2807
|
+
"" if self.streamed_whole else " (from midway: streaming joined after it began)")
|
|
2808
|
+
|
|
2751
2809
|
@on(DataTable.RowSelected, "#recent")
|
|
2752
2810
|
def recent_selected(self, event):
|
|
2753
2811
|
keys = [k for k in event.data_table.rows if k in self.recent_entries]
|
|
@@ -2946,14 +3004,15 @@ class ResultsScreen(Screen):
|
|
|
2946
3004
|
"""Every wrong answer, of the models picked (Models: shared with the other tabs)."""
|
|
2947
3005
|
f = self.query_one("#failures", DataTable)
|
|
2948
3006
|
f.clear(columns=True)
|
|
2949
|
-
f.add_columns("Model", "Level", "Test", "Reason")
|
|
3007
|
+
f.add_columns("Model", "Level", "Test", "Answered", "Reason")
|
|
2950
3008
|
every = {r["model"] for r in self.rows}
|
|
2951
3009
|
chosen = {m for m in self.app.pq_models if m in every}
|
|
2952
3010
|
rows = [r for r in self.rows if not chosen or r["model"] in chosen]
|
|
2953
3011
|
# compare.failures lists the failed rows in order, so they line up with fail_rows
|
|
2954
3012
|
self.fail_rows = [r for r in rows if not r["ok"]]
|
|
2955
3013
|
for i, (model, test, reason, level) in enumerate(compare.failures(rows)):
|
|
2956
|
-
|
|
3014
|
+
when = dates.day(dates.answered_at(self.fail_rows[i].get("raw") or {}))
|
|
3015
|
+
f.add_row(model, diff_badge(level), rich_escape(test), when, rich_escape(reason[:130]), key=str(i))
|
|
2957
3016
|
self.query_one("#fail-models", Button).label = f"Models: {len(chosen)} picked" if chosen else "Models: all"
|
|
2958
3017
|
n = len(self.fail_rows)
|
|
2959
3018
|
self.query_one("#fail-count", Static).update(
|
|
@@ -3032,22 +3091,51 @@ class ResultsScreen(Screen):
|
|
|
3032
3091
|
models = sorted(counts, key=lambda m: (-counts[m], m))
|
|
3033
3092
|
|
|
3034
3093
|
def picked(chosen):
|
|
3035
|
-
if chosen is None:
|
|
3036
|
-
|
|
3037
|
-
first = chosen and not self.app.pq_models
|
|
3038
|
-
self.app.pq_models = chosen # kept for this session, so reopening Results keeps it
|
|
3039
|
-
if first: # a fair comparison needs the same questions: turn it on (you can untick it)
|
|
3040
|
-
with self.query_one("#pq-shared", Checkbox).prevent(Checkbox.Changed):
|
|
3041
|
-
self.query_one("#pq-shared", Checkbox).value = True
|
|
3042
|
-
# after the picker has closed: a table rebuilt under a modal keeps its header-only widths
|
|
3043
|
-
self.call_after_refresh(self.fill_per_question)
|
|
3044
|
-
self.call_after_refresh(self.fill_pta)
|
|
3045
|
-
self.call_after_refresh(self.fill_failures)
|
|
3046
|
-
self.insights_stale = True
|
|
3047
|
-
if self.query_one(TabbedContent).active == "tab-insights":
|
|
3048
|
-
self.call_after_refresh(self.fill_insights)
|
|
3094
|
+
if chosen is not None:
|
|
3095
|
+
self.set_models(chosen)
|
|
3049
3096
|
self.app.push_screen(ModelPickScreen(models, counts, self.app.pq_models), picked)
|
|
3050
3097
|
|
|
3098
|
+
def set_models(self, chosen):
|
|
3099
|
+
"""The models every Results tab compares (none: all of them)."""
|
|
3100
|
+
first = chosen and not self.app.pq_models
|
|
3101
|
+
self.app.pq_models = chosen # kept for this session, so reopening Results keeps it
|
|
3102
|
+
if first: # a fair comparison needs the same questions: turn it on (you can untick it)
|
|
3103
|
+
with self.query_one("#pq-shared", Checkbox).prevent(Checkbox.Changed):
|
|
3104
|
+
self.query_one("#pq-shared", Checkbox).value = True
|
|
3105
|
+
# after a picker has closed: a table rebuilt under a modal keeps its header-only widths
|
|
3106
|
+
self.call_after_refresh(self.fill_per_question)
|
|
3107
|
+
self.call_after_refresh(self.fill_pta)
|
|
3108
|
+
self.call_after_refresh(self.fill_failures)
|
|
3109
|
+
self.insights_stale = True
|
|
3110
|
+
if self.query_one(TabbedContent).active == "tab-insights":
|
|
3111
|
+
self.call_after_refresh(self.fill_insights)
|
|
3112
|
+
|
|
3113
|
+
def action_pta_remove(self, row):
|
|
3114
|
+
"""A click on a model's name in the PTA bars: leave it out of every tab (click it again below to bring it back)."""
|
|
3115
|
+
shown = [x["model"] for x in getattr(self, "pta_result", {}).get("models", [])]
|
|
3116
|
+
if not 0 <= row < len(shown):
|
|
3117
|
+
return
|
|
3118
|
+
if len(shown) == 1:
|
|
3119
|
+
self.notify("That's the last model shown.", severity="warning")
|
|
3120
|
+
return
|
|
3121
|
+
model = shown[row]
|
|
3122
|
+
self.app.pta_removed = [m for m in getattr(self.app, "pta_removed", []) if m != model] + [model]
|
|
3123
|
+
self.set_models((self.app.pq_models or set(shown)) - {model})
|
|
3124
|
+
|
|
3125
|
+
def action_pta_restore(self, row):
|
|
3126
|
+
removed = self.pta_removed_now()
|
|
3127
|
+
if 0 <= row < len(removed):
|
|
3128
|
+
self.app.pta_removed.remove(removed[row])
|
|
3129
|
+
self.set_models(self.app.pq_models | {removed[row]})
|
|
3130
|
+
|
|
3131
|
+
def action_pta_restore_all(self):
|
|
3132
|
+
self.app.pta_removed = []
|
|
3133
|
+
self.set_models(set())
|
|
3134
|
+
|
|
3135
|
+
def pta_removed_now(self):
|
|
3136
|
+
"""Models removed by a click that are still left out (the Models button may have put them back)."""
|
|
3137
|
+
return [m for m in getattr(self.app, "pta_removed", []) if self.app.pq_models and m not in self.app.pq_models]
|
|
3138
|
+
|
|
3051
3139
|
# -- insights: charts with what to do next (insights.py); built when the tab is first shown
|
|
3052
3140
|
@on(TabbedContent.TabActivated)
|
|
3053
3141
|
def tab_activated(self, event):
|
|
@@ -3127,7 +3215,16 @@ class ResultsScreen(Screen):
|
|
|
3127
3215
|
# none picked: every model with enough answers (pta.index leaves out the rest, and says so)
|
|
3128
3216
|
result = pta.index(rows, sorted(chosen) or None, pta.memory_gb(self.infos))
|
|
3129
3217
|
self.query_one("#pta-note", Static).update(pta.scope_note(result, sorted(present)))
|
|
3130
|
-
self.
|
|
3218
|
+
self.pta_result = result
|
|
3219
|
+
removed = [m for m in self.pta_removed_now() if m in present]
|
|
3220
|
+
self.query_one("#pta-bars", Static).update(
|
|
3221
|
+
"\n".join(pta.bars(result, click="screen.pta_remove")
|
|
3222
|
+
+ ([f"\n[dim]Click a name to remove it. Removed:[/dim] "
|
|
3223
|
+
+ " ".join(f"[@click=screen.pta_restore({self.pta_removed_now().index(m)})]{rich_escape(m)}[/]"
|
|
3224
|
+
for m in removed)
|
|
3225
|
+
+ " [dim]·[/dim] [@click=screen.pta_restore_all]show all[/]"] if removed
|
|
3226
|
+
else ["\n[dim]Click a name to remove it from view.[/dim]"]))
|
|
3227
|
+
if result["questions"] else "")
|
|
3131
3228
|
self.query_one("#pta-left-out", Static).update(
|
|
3132
3229
|
"\n".join(f"[dim]{rich_escape(line)}[/dim]" for line in pta.left_out_lines(result)))
|
|
3133
3230
|
header, table = pta.table(result)
|
|
@@ -3193,7 +3290,7 @@ class ResultsScreen(Screen):
|
|
|
3193
3290
|
here = self.app.engine.machine().id
|
|
3194
3291
|
table = self.query_one("#per-question", DataTable)
|
|
3195
3292
|
table.clear(columns=True)
|
|
3196
|
-
table.add_columns("Test", "Pack", "Level", "×tokens", *models)
|
|
3293
|
+
table.add_columns("Test", "Pack", "Level", "Added", "×tokens", *models)
|
|
3197
3294
|
self.pq_tests, self.pq_models = {}, models
|
|
3198
3295
|
for t in tests:
|
|
3199
3296
|
cells = []
|
|
@@ -3205,7 +3302,9 @@ class ResultsScreen(Screen):
|
|
|
3205
3302
|
spread = t["spread"]["tokens"]
|
|
3206
3303
|
sp = f"[yellow]{spread:.1f}×[/yellow]" if spread >= 3 else (f"{spread:.1f}×" if len(t["cells"]) > 1 else "")
|
|
3207
3304
|
desc = t["cells"][next(iter(t["cells"]))]["rows"][0].get("raw", {}).get("description") or t["name"]
|
|
3208
|
-
|
|
3305
|
+
added = self.app.engine.test_dates.get(t["suite"], t["test"].split(": ", 1)[-1])
|
|
3306
|
+
added = sort_cell(added[0] if added[1] else f"≤ {added[0]}", added[0]) if added else ""
|
|
3307
|
+
table.add_row(rich_escape(desc[:48]), t["suite"], diff_badge(t["difficulty"]), added, sp, *cells, key=t["test"])
|
|
3209
3308
|
self.pq_tests[t["test"]] = t
|
|
3210
3309
|
self.sort_table(table)
|
|
3211
3310
|
self.sort_table(self.query_one("#pq-summary", DataTable))
|
|
@@ -3344,9 +3443,12 @@ class ResultsScreen(Screen):
|
|
|
3344
3443
|
"[dim]No verdicts yet: run something from Setup.[/dim]")
|
|
3345
3444
|
groups = sorted({g for t in table.values() for g in t})
|
|
3346
3445
|
matrix.add_columns("Model", *groups)
|
|
3347
|
-
detail.add_columns("Model", "Use case", "Pack", "Verdict", "Answers right", "Why")
|
|
3446
|
+
detail.add_columns("Model", "Use case", "Pack", "Verdict", "Answers right", "Answered", "Why")
|
|
3348
3447
|
right = collections.Counter((r["model"], r["suite"]) for r in self.rows if r["ok"])
|
|
3349
3448
|
answered = collections.Counter((r["model"], r["suite"]) for r in self.rows)
|
|
3449
|
+
when = collections.defaultdict(list)
|
|
3450
|
+
for r in self.rows:
|
|
3451
|
+
when[(r["model"], r["suite"])].append(dates.answered_at(r.get("raw") or {}))
|
|
3350
3452
|
lat = verdict.latency_table(self.app.engine, None, table)
|
|
3351
3453
|
machine_ids = [mc.id for mc in self.app.engine.machines()]
|
|
3352
3454
|
lt = self.query_one("#latency", DataTable)
|
|
@@ -3365,7 +3467,8 @@ class ResultsScreen(Screen):
|
|
|
3365
3467
|
if pv.status != "NO DATA":
|
|
3366
3468
|
n = answered[(label, name)]
|
|
3367
3469
|
detail.add_row(label, g, name, f"[{style[pv.status]}]{pv.status}[/]",
|
|
3368
|
-
f"{right[(label, name)]}/{n}" if n else "-",
|
|
3470
|
+
f"{right[(label, name)]}/{n}" if n else "-", dates.span(when[(label, name)]),
|
|
3471
|
+
"; ".join(pv.reasons)[:160])
|
|
3369
3472
|
|
|
3370
3473
|
|
|
3371
3474
|
# ------------------------------------------------------------------ app
|
|
@@ -11,6 +11,8 @@ unavailable HTTP 404 "No endpoints found" for every chat request
|
|
|
11
11
|
Streams like llama.cpp: reasoning_content then content deltas, usage and timings at the end.
|
|
12
12
|
--stall S: after the first token, S seconds of nothing but keep-alive comments (": OPENROUTER
|
|
13
13
|
PROCESSING"), or of silence with --silent; --stall-before S: the same before the first token.
|
|
14
|
+
--die-after N: the process exits after N stream chunks (0: right after the headers), with no finish
|
|
15
|
+
reason or [DONE], like a server that crashes mid-request.
|
|
14
16
|
An answer longer than the request's max_tokens (one token per word) is cut off with finish
|
|
15
17
|
"length". --max-output N also serves an OpenRouter-style endpoints list with that output limit.
|
|
16
18
|
"""
|
|
@@ -53,6 +55,7 @@ def reply_for(test, mode):
|
|
|
53
55
|
class Handler(BaseHTTPRequestHandler):
|
|
54
56
|
answers, mode, model, delay, max_output = {}, "oracle", "mock", 0.0, None
|
|
55
57
|
stall, stall_before, silent = 0.0, 0.0, False
|
|
58
|
+
die_after = None
|
|
56
59
|
|
|
57
60
|
def log_message(self, *a):
|
|
58
61
|
pass
|
|
@@ -96,10 +99,18 @@ class Handler(BaseHTTPRequestHandler):
|
|
|
96
99
|
self.send_response(200)
|
|
97
100
|
self.send_header("Content-Type", "text/event-stream")
|
|
98
101
|
self.end_headers()
|
|
102
|
+
sent = [0]
|
|
103
|
+
|
|
104
|
+
def die_if_due():
|
|
105
|
+
if self.die_after is not None and sent[0] >= self.die_after:
|
|
106
|
+
self.wfile.flush()
|
|
107
|
+
os._exit(3)
|
|
99
108
|
|
|
100
109
|
def send(obj):
|
|
110
|
+
die_if_due()
|
|
101
111
|
self.wfile.write(f"data: {json.dumps(obj)}\n\n".encode())
|
|
102
112
|
self.wfile.flush()
|
|
113
|
+
sent[0] += 1
|
|
103
114
|
|
|
104
115
|
def wait(secs):
|
|
105
116
|
end = time.time() + secs
|
|
@@ -123,6 +134,7 @@ class Handler(BaseHTTPRequestHandler):
|
|
|
123
134
|
"usage": {"prompt_tokens": len(str(content).split()), "completion_tokens": words},
|
|
124
135
|
"timings": {"predicted_n": words, "predicted_per_second": 50.0, "prompt_n": 10,
|
|
125
136
|
"prompt_per_second": 500.0, "cache_n": 0}})
|
|
137
|
+
die_if_due()
|
|
126
138
|
self.wfile.write(b"data: [DONE]\n\n")
|
|
127
139
|
|
|
128
140
|
|
|
@@ -144,10 +156,12 @@ def main(argv=None):
|
|
|
144
156
|
p.add_argument("--stall", type=float, default=0.0)
|
|
145
157
|
p.add_argument("--stall-before", type=float, default=0.0)
|
|
146
158
|
p.add_argument("--silent", action="store_true")
|
|
159
|
+
p.add_argument("--die-after", type=int)
|
|
147
160
|
a, _ = p.parse_known_args(argv) # other flags (e.g. speed knobs under test) are accepted and ignored
|
|
148
161
|
Handler.answers, Handler.mode, Handler.model, Handler.delay = load_answers(a.packs), a.mode, a.model, a.delay
|
|
149
162
|
Handler.max_output = a.max_output
|
|
150
163
|
Handler.stall, Handler.stall_before, Handler.silent = a.stall, a.stall_before, a.silent
|
|
164
|
+
Handler.die_after = a.die_after
|
|
151
165
|
srv = Server(("127.0.0.1", a.port), Handler)
|
|
152
166
|
print(f"mock server on 127.0.0.1:{a.port} ({a.mode}, {len(Handler.answers)} known questions)", flush=True)
|
|
153
167
|
try:
|
|
@@ -2,6 +2,7 @@
|
|
|
2
2
|
|
|
3
3
|
Uses a temporary workspace and tests/mock_server.py on a free local port; no model or GPU needed.
|
|
4
4
|
"""
|
|
5
|
+
import glob
|
|
5
6
|
import json
|
|
6
7
|
import math
|
|
7
8
|
import os
|
|
@@ -452,6 +453,42 @@ class PickTests(unittest.TestCase):
|
|
|
452
453
|
self.assertIn("'zz'", str(cm.exception))
|
|
453
454
|
self.assertIn("a, b, c, d", str(cm.exception))
|
|
454
455
|
|
|
456
|
+
def test_answers_and_tests_are_dated(self):
|
|
457
|
+
from tuieval import dates, engine, packs
|
|
458
|
+
before = packs.load_pack(os.path.join(self.ws, "packs", "apps")).fingerprint
|
|
459
|
+
tests = os.path.join(self.ws, "packs", "apps", "tests.yaml")
|
|
460
|
+
write(tests, read(tests).replace("{id: a,", "{id: a, added: 2025-03-04,"))
|
|
461
|
+
self.assertEqual(packs.load_pack(os.path.join(self.ws, "packs", "apps")).fingerprint, before) # not outdated
|
|
462
|
+
self.server("oracle")
|
|
463
|
+
tuieval(self.ws, "run", "--packs", "apps", "--tests", "b")
|
|
464
|
+
rec = json.loads(read(os.path.join(self.ws, "results", "m", "apps.json")))["results"][0]
|
|
465
|
+
answered = dates.answered_at(rec)
|
|
466
|
+
self.assertLess(abs(time.time() - answered.timestamp()), 300)
|
|
467
|
+
self.assertEqual(rec["answered_at"][:10], time.strftime("%Y-%m-%d"))
|
|
468
|
+
old = {k: v for k, v in rec.items() if k != "answered_at"} # older results: from the log name
|
|
469
|
+
self.assertEqual(dates.answered_at(old).replace(microsecond=0), answered.replace(microsecond=0))
|
|
470
|
+
self.assertIsNone(dates.answered_at({"log": "unnamed.txt"}))
|
|
471
|
+
|
|
472
|
+
def fake_answer(test, day): # an answer from before the dates file existed
|
|
473
|
+
write(os.path.join(self.ws, "results", "m", "other.json.partial.jsonl"), json.dumps(
|
|
474
|
+
{"pack_fingerprint": "x"}) + "\n" + json.dumps({"test": test, "log": f"{day}_101010_m_other_{test}.txt"}) + "\n")
|
|
475
|
+
fake_answer("c", "20250102")
|
|
476
|
+
os.remove(os.path.join(self.ws, dates.FILE))
|
|
477
|
+
e = engine.Engine(root=self.ws)
|
|
478
|
+
today = time.strftime("%Y-%m-%d")
|
|
479
|
+
self.assertEqual(e.test_dates.get("apps", "a"), ("2025-03-04", True)) # its own `added` wins
|
|
480
|
+
self.assertEqual(e.test_dates.get("other", "c"), ("2025-01-02", False)) # on or before its first answer
|
|
481
|
+
self.assertEqual(e.test_dates.text("apps", "d"), f"≤ {today}") # already there, never answered
|
|
482
|
+
write(os.path.join(self.ws, "packs", "apps", "tests.yaml"), read(tests) + "- {id: e, input: apps question e, "
|
|
483
|
+
"expected: 1, reference: 'ANSWER: 1', difficulty: easy}\n")
|
|
484
|
+
e.reload()
|
|
485
|
+
self.assertEqual(e.test_dates.get("apps", "e"), (today, True)) # new since: the day it was seen
|
|
486
|
+
self.assertEqual(engine.Engine(root=self.ws).test_dates.get("other", "c"), ("2025-01-02", False)) # kept
|
|
487
|
+
self.assertEqual(dates.span([answered]), answered.strftime("%Y-%m-%d"))
|
|
488
|
+
self.assertEqual(dates.span([dates.answered_at(old), dates.answered_at({"log": "20250102_101010_x"})]),
|
|
489
|
+
f"2025-01-02 – {answered.strftime('%m-%d')}" if answered.year == 2025 else
|
|
490
|
+
f"2025-01-02 – {answered.strftime('%Y-%m-%d')}")
|
|
491
|
+
|
|
455
492
|
def test_partial_runs_add_up_and_force_redoes_only_the_picked(self):
|
|
456
493
|
self.server("oracle")
|
|
457
494
|
tuieval(self.ws, "run", "--packs", "apps", "--tests", "b")
|
|
@@ -1130,6 +1167,70 @@ class AddToRun(unittest.TestCase):
|
|
|
1130
1167
|
self.assertEqual(fewer, 4) # its 4 questions are no longer counted
|
|
1131
1168
|
self.assertEqual(out["running"], [False, True])
|
|
1132
1169
|
|
|
1170
|
+
def test_tui_copies_reasoning_and_answer(self):
|
|
1171
|
+
path = os.path.join(self.ws, "models.toml")
|
|
1172
|
+
write(path, read(path).replace('"--delay", "0.2"', '"--delay", "1.5"')) # reasoning first, then a wait
|
|
1173
|
+
fake = os.path.join(self.tmp.name, "bin")
|
|
1174
|
+
os.makedirs(fake)
|
|
1175
|
+
write(os.path.join(fake, "pbcopy"), '#!/bin/sh\ncat > "$CLIP_OUT"\n')
|
|
1176
|
+
os.chmod(os.path.join(fake, "pbcopy"), 0o755)
|
|
1177
|
+
clip = os.path.join(self.tmp.name, "clip.txt")
|
|
1178
|
+
code = textwrap.dedent("""
|
|
1179
|
+
import asyncio, json, os, time
|
|
1180
|
+
from tuieval.tui import AnswerScreen, EvalsApp, RunScreen
|
|
1181
|
+
from textual.widgets import SelectionList
|
|
1182
|
+
def pasted():
|
|
1183
|
+
with open(os.environ["CLIP_OUT"]) as f:
|
|
1184
|
+
text = f.read()
|
|
1185
|
+
os.remove(os.environ["CLIP_OUT"])
|
|
1186
|
+
return text
|
|
1187
|
+
async def go():
|
|
1188
|
+
app = EvalsApp({})
|
|
1189
|
+
async with app.run_test(size=(160, 50)) as pilot:
|
|
1190
|
+
await pilot.pause()
|
|
1191
|
+
s = app.screen
|
|
1192
|
+
s.query_one("#suites", SelectionList).select("apps")
|
|
1193
|
+
s.selected_models = {"a"}
|
|
1194
|
+
s.refresh_models()
|
|
1195
|
+
s.query_one("#tier-certify").value = True
|
|
1196
|
+
await pilot.pause()
|
|
1197
|
+
s.action_start()
|
|
1198
|
+
deadline = time.time() + 180 # CI machines can take long to start servers
|
|
1199
|
+
while time.time() < deadline:
|
|
1200
|
+
await pilot.pause(0.1)
|
|
1201
|
+
if isinstance(app.screen, RunScreen) and app.screen.req_started:
|
|
1202
|
+
break
|
|
1203
|
+
run, out = app.screen, {}
|
|
1204
|
+
await pilot.pause(0.5) # the reasoning has streamed; the answer waits 1.5 s
|
|
1205
|
+
await pilot.press("y")
|
|
1206
|
+
await pilot.pause()
|
|
1207
|
+
out["live"] = pasted()
|
|
1208
|
+
deadline = time.time() + 120
|
|
1209
|
+
while run.running and time.time() < deadline:
|
|
1210
|
+
await pilot.pause(0.2)
|
|
1211
|
+
app.push_screen(AnswerScreen(list(run.recent_entries.values())))
|
|
1212
|
+
await pilot.pause()
|
|
1213
|
+
for key in "ya":
|
|
1214
|
+
await pilot.press(key)
|
|
1215
|
+
await pilot.pause()
|
|
1216
|
+
out[key] = pasted()
|
|
1217
|
+
print(json.dumps(out))
|
|
1218
|
+
asyncio.run(go())
|
|
1219
|
+
""")
|
|
1220
|
+
p = subprocess.run([sys.executable, "-c", code], capture_output=True, text=True, timeout=600,
|
|
1221
|
+
env=dict(os.environ, TUIEVAL_HOME=self.ws, TUIEVAL_DETECT_PORTS="", CLIP_OUT=clip,
|
|
1222
|
+
PATH=fake + os.pathsep + os.environ["PATH"]))
|
|
1223
|
+
out = json.loads(p.stdout.strip().splitlines()[-1]) if p.stdout.strip() else p.stderr
|
|
1224
|
+
self.assertEqual(out, {"live": "Thinking it over. ", "y": "Thinking it over. ", "a": "ANSWER: 1"}, out)
|
|
1225
|
+
|
|
1226
|
+
def test_copy_falls_back_to_the_terminal(self):
|
|
1227
|
+
from unittest import mock
|
|
1228
|
+
from tuieval.tui import copy_text
|
|
1229
|
+
app = mock.Mock()
|
|
1230
|
+
with mock.patch.dict(os.environ, {"PATH": self.tmp.name}): # no clipboard tool here
|
|
1231
|
+
self.assertFalse(copy_text(app, "some reasoning"))
|
|
1232
|
+
app.copy_to_clipboard.assert_called_once_with("some reasoning")
|
|
1233
|
+
|
|
1133
1234
|
def test_tui_counts_ticked_models_and_names_filtered_ones_before_start(self):
|
|
1134
1235
|
code = textwrap.dedent("""
|
|
1135
1236
|
import asyncio, json
|
|
@@ -1609,6 +1710,23 @@ class PTAIndex(unittest.TestCase):
|
|
|
1609
1710
|
app.screen.fill_pta() # rebuilt: still sorted
|
|
1610
1711
|
await pilot.pause(0.2)
|
|
1611
1712
|
sorts["kept"] = [str(pta_t.get_row_at(r)[0]) for r in range(pta_t.row_count)]
|
|
1713
|
+
bars_w = app.screen.query_one("#pta-bars", Static)
|
|
1714
|
+
shown = [x["model"] for x in app.screen.pta_result["models"]]
|
|
1715
|
+
await pilot.click(bars_w, offset=(1, 1 + 2 + shown.index("hosted"))) # a click on its name
|
|
1716
|
+
await pilot.pause(0.3)
|
|
1717
|
+
clicks = {"removed": [sorted(app.pq_models), [x["model"] for x in app.screen.pta_result["models"]],
|
|
1718
|
+
"Removed: hosted" in str(bars_w.render())]}
|
|
1719
|
+
await pilot.click(bars_w, offset=(1, 1 + 2)) # the last one stays
|
|
1720
|
+
await pilot.pause(0.3)
|
|
1721
|
+
clicks["last"] = sorted(app.pq_models)
|
|
1722
|
+
app.screen.action_pta_restore(0)
|
|
1723
|
+
await pilot.pause(0.3)
|
|
1724
|
+
clicks["restored"] = [sorted(app.pq_models), len(app.screen.pta_result["models"])]
|
|
1725
|
+
app.screen.action_pta_remove(shown.index("hosted"))
|
|
1726
|
+
app.screen.action_pta_restore_all()
|
|
1727
|
+
await pilot.pause(0.3)
|
|
1728
|
+
clicks["all"] = [sorted(app.pq_models), "Removed" in str(bars_w.render())]
|
|
1729
|
+
sorts["clicks"] = clicks
|
|
1612
1730
|
app.screen.query_one(TabbedContent).active = "tab-failures"
|
|
1613
1731
|
await pilot.pause(0.3)
|
|
1614
1732
|
f = app.screen.query_one("#failures", DataTable)
|
|
@@ -1647,6 +1765,11 @@ class PTAIndex(unittest.TestCase):
|
|
|
1647
1765
|
s = got["sorts"] # a click on a column name sorts by it, a second click reverses
|
|
1648
1766
|
self.assertEqual((s["up"], s["down"], s["kept"]), (["hosted", "good"], ["good", "hosted"], ["good", "hosted"]))
|
|
1649
1767
|
self.assertIn("answers right ▼", s["labels"])
|
|
1768
|
+
c = s["clicks"] # a click on a name in the bars leaves it out of every tab; the last one stays
|
|
1769
|
+
self.assertEqual(c["removed"], [["good"], ["good"], True])
|
|
1770
|
+
self.assertEqual(c["last"], ["good"])
|
|
1771
|
+
self.assertEqual(c["restored"], [["good", "hosted"], 2])
|
|
1772
|
+
self.assertEqual(c["all"], [[], False])
|
|
1650
1773
|
self.assertEqual((s["tests"][0], s["opened"]), ("apps: d", "d"))
|
|
1651
1774
|
fails = got["fails"]
|
|
1652
1775
|
self.assertEqual(fails["all"], [4, "4 failures"])
|
|
@@ -2724,6 +2847,25 @@ class StallGuard(unittest.TestCase):
|
|
|
2724
2847
|
self.assertFalse(client.is_server_error(res["error"])) # slow, like any timeout: counts
|
|
2725
2848
|
self.assertLess(took, 4)
|
|
2726
2849
|
|
|
2850
|
+
def test_crash_before_any_token_is_a_server_error(self):
|
|
2851
|
+
from tuieval import client
|
|
2852
|
+
res, _ = self.ask("--die-after", "0", timeout=30)
|
|
2853
|
+
self.assertTrue(client.is_server_error(res["error"]), res["error"])
|
|
2854
|
+
self.assertIn("stream ended", res["error"])
|
|
2855
|
+
self.assertEqual(res["answer"], "")
|
|
2856
|
+
|
|
2857
|
+
def test_crash_mid_answer_is_a_server_error(self):
|
|
2858
|
+
from tuieval import client
|
|
2859
|
+
res, _ = self.ask("--die-after", "2", timeout=30)
|
|
2860
|
+
self.assertTrue(client.is_server_error(res["error"]), res["error"])
|
|
2861
|
+
self.assertIsNone(res["finish"])
|
|
2862
|
+
|
|
2863
|
+
def test_finish_without_done_is_an_answer(self):
|
|
2864
|
+
res, _ = self.ask("--die-after", "99", timeout=30) # every chunk, then gone before [DONE]
|
|
2865
|
+
self.assertIsNone(res["error"])
|
|
2866
|
+
self.assertEqual(res["finish"], "stop")
|
|
2867
|
+
self.assertIn("42", res["answer"])
|
|
2868
|
+
|
|
2727
2869
|
def test_run_screen_shows_each_running_models_progress(self):
|
|
2728
2870
|
from types import SimpleNamespace
|
|
2729
2871
|
from tuieval import tui
|
|
@@ -2868,5 +3010,33 @@ class Insights(unittest.TestCase):
|
|
|
2868
3010
|
self.assertEqual(p.stdout.split(), ["True", "True", "True", "True", "bad"], p.stderr[-2000:])
|
|
2869
3011
|
|
|
2870
3012
|
|
|
3013
|
+
class ServerCrash(unittest.TestCase):
|
|
3014
|
+
"""A server that crashes mid-request (the stream just ends) never judges the model: the run says the
|
|
3015
|
+
server stopped and records no answer."""
|
|
3016
|
+
|
|
3017
|
+
def test_crash_records_no_answer(self):
|
|
3018
|
+
with tempfile.TemporaryDirectory() as tmp:
|
|
3019
|
+
ws = os.path.join(tmp, "ws")
|
|
3020
|
+
tuieval(tmp, "init", ws)
|
|
3021
|
+
d = os.path.join(ws, "packs", "apps")
|
|
3022
|
+
os.makedirs(d)
|
|
3023
|
+
write(os.path.join(d, "pack.toml"), 'label = "apps"\n[certify]\nrepeat = 1\n[gate]\nmin_accuracy = 0.1\n')
|
|
3024
|
+
write(os.path.join(d, "tests.yaml"), "- {id: a, input: question a, expected: 1, reference: 'ANSWER: 1'}\n")
|
|
3025
|
+
mock = [sys.executable, os.path.join(HERE, "mock_server.py"), "--port", "{port}", "--packs",
|
|
3026
|
+
os.path.join(ws, "packs"), "--model", "{served_name}", "--die-after", "0"]
|
|
3027
|
+
with open(os.path.join(ws, "models.toml"), "a") as f:
|
|
3028
|
+
f.write(f"\n[servers.mk]\ncmd = {json.dumps(mock)}\nport = {free_port()}\n"
|
|
3029
|
+
'\n[[models]]\nlabel = "crashy"\nserver = "mk"\nmodel = "crashy"\n')
|
|
3030
|
+
p = tuieval(ws, "run", "--only", "crashy", "--tier", "certify", check=False)
|
|
3031
|
+
self.assertIn("server stopped", p.stdout + p.stderr)
|
|
3032
|
+
self.assertNotIn("Empty answer", p.stdout + p.stderr)
|
|
3033
|
+
rows = []
|
|
3034
|
+
for path in glob.glob(os.path.join(ws, "results", "crashy", "*.json*")):
|
|
3035
|
+
text = read(path)
|
|
3036
|
+
rows += [r for r in (json.loads(text).get("results", []) if path.endswith(".json") else
|
|
3037
|
+
[json.loads(l) for l in text.splitlines() if l.strip()]) if "test" in r]
|
|
3038
|
+
self.assertEqual(rows, [])
|
|
3039
|
+
|
|
3040
|
+
|
|
2871
3041
|
if __name__ == "__main__":
|
|
2872
3042
|
unittest.main()
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/pack.toml
RENAMED
|
File without changes
|
{tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/system.txt
RENAMED
|
File without changes
|
{tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/tests.yaml
RENAMED
|
File without changes
|
{tuieval-0.2.0.dev108 → tuieval-0.2.0.dev116}/src/tuieval/templates/packs/tool_call/tools.yaml
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|