tuieval 0.1.6__tar.gz → 0.2.0.dev1__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/.gitignore +1 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/CHANGELOG.md +6 -2
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/PKG-INFO +3 -1
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/README.md +2 -0
- tuieval-0.2.0.dev1/RELEASING.md +31 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/models.md +4 -7
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/pyproject.toml +11 -2
- tuieval-0.2.0.dev1/src/tuieval/__init__.py +5 -0
- tuieval-0.2.0.dev1/src/tuieval/_version.py +24 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/export.py +52 -97
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/run_evals.py +3 -3
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/tests/test_tuieval.py +20 -27
- tuieval-0.1.6/RELEASING.md +0 -7
- tuieval-0.1.6/src/tuieval/__init__.py +0 -2
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/LICENSE +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/README.md +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/favicon.ico +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/readme-header.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/social-preview.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-1024.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-128.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-16.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-16.svg +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-256.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-32.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-48.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-512.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-64.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon-animated.svg +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/brand/tuieval-icon.svg +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/images/tui-setup.png +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/docs/writing-packs.md +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/__main__.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/cli.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/client.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/compare.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/engine.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/graders/__init__.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/graders/answer.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/graders/code.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/graders/rag.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/graders/reply.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/graders/tool_call.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/machines.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/packs.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/profiles.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/remove.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/scaffold.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/selftest.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/models.toml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/answer/pack.toml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/answer/system.txt +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/answer/tests.yaml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/code/pack.toml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/code/system.txt +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/code/tests.yaml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/rag/pack.toml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/rag/system.txt +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/rag/tests.yaml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/reply/pack.toml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/reply/system.txt +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/reply/tests.yaml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/tool_call/pack.toml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/tool_call/system.txt +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/tool_call/tests.yaml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/templates/packs/tool_call/tools.yaml +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/tui.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/tune.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/verdict.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/watch_proxy.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/workspace.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/src/tuieval/yamlout.py +0 -0
- {tuieval-0.1.6 → tuieval-0.2.0.dev1}/tests/mock_server.py +0 -0
|
@@ -1,9 +1,13 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
-
##
|
|
3
|
+
## Unreleased
|
|
4
|
+
|
|
5
|
+
- Versions come from git tags: a tag `vX.Y.Z` is that release, and every commit on `main` after it is published automatically as a dev build `X.(Y+1).0.devN` (N = commits since the release). `pip install tuieval` keeps installing releases only; `pip install --pre tuieval` gets the latest build.
|
|
6
|
+
|
|
7
|
+
## 0.1.7 (replaces 0.1.6, withdrawn)
|
|
4
8
|
|
|
5
9
|
- `tuieval tune` starts warm for fine-tunes: when a model with the same architecture and tensor shapes is already tuned on this machine, its flags are the starting point and only speculative decoding and micro-batch are re-tried (~4-6 server starts instead of 8-15). It tunes in full if the inherited flags fail, change answers or are slower than the defaults. `--cold` (or `[tune] warm_start = false`) always tunes in full; `[tune] warm_retest` names the re-tried knobs.
|
|
6
|
-
- `tuieval export pi <model>` (and `tuieval tune --export-pi`) writes a model's serving settings to the pi coding agent: a llama-router preset section
|
|
10
|
+
- `tuieval export pi <model>` (and `tuieval tune --export-pi`) writes a model's serving settings to the pi coding agent: a llama-router preset section and pi's models.json. It shows the diff, asks, and backs every file up. See docs/models.md.
|
|
7
11
|
- `tuieval list` lists the models, with hidden ones separately (`--packs` lists the packs).
|
|
8
12
|
- `tuieval remove <model>` / `--hidden` removes models: their models.toml entry, results, tuning profiles and hidden mark, archived in removed/.
|
|
9
13
|
- `tuieval --help` gives every command its own line.
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: tuieval
|
|
3
|
-
Version: 0.
|
|
3
|
+
Version: 0.2.0.dev1
|
|
4
4
|
Summary: Evaluate local and frontier LLMs on your own questions: accuracy, speed, tokens and PASS/FAIL verdicts, in the terminal.
|
|
5
5
|
Project-URL: Homepage, https://github.com/ashe-wb/tuieval
|
|
6
6
|
Project-URL: Issues, https://github.com/ashe-wb/tuieval/issues
|
|
@@ -43,6 +43,8 @@ tuieval add ~/models/Some-Model-Q4_K_M.gguf
|
|
|
43
43
|
tuieval # open the TUI
|
|
44
44
|
```
|
|
45
45
|
|
|
46
|
+
`pip install tuieval` gets the latest release. Every change on `main` is also published as a dev build (`X.Y.0.devN`); get it with `pipx install --pip-args=--pre tuieval` or `pip install --pre tuieval`.
|
|
47
|
+
|
|
46
48
|
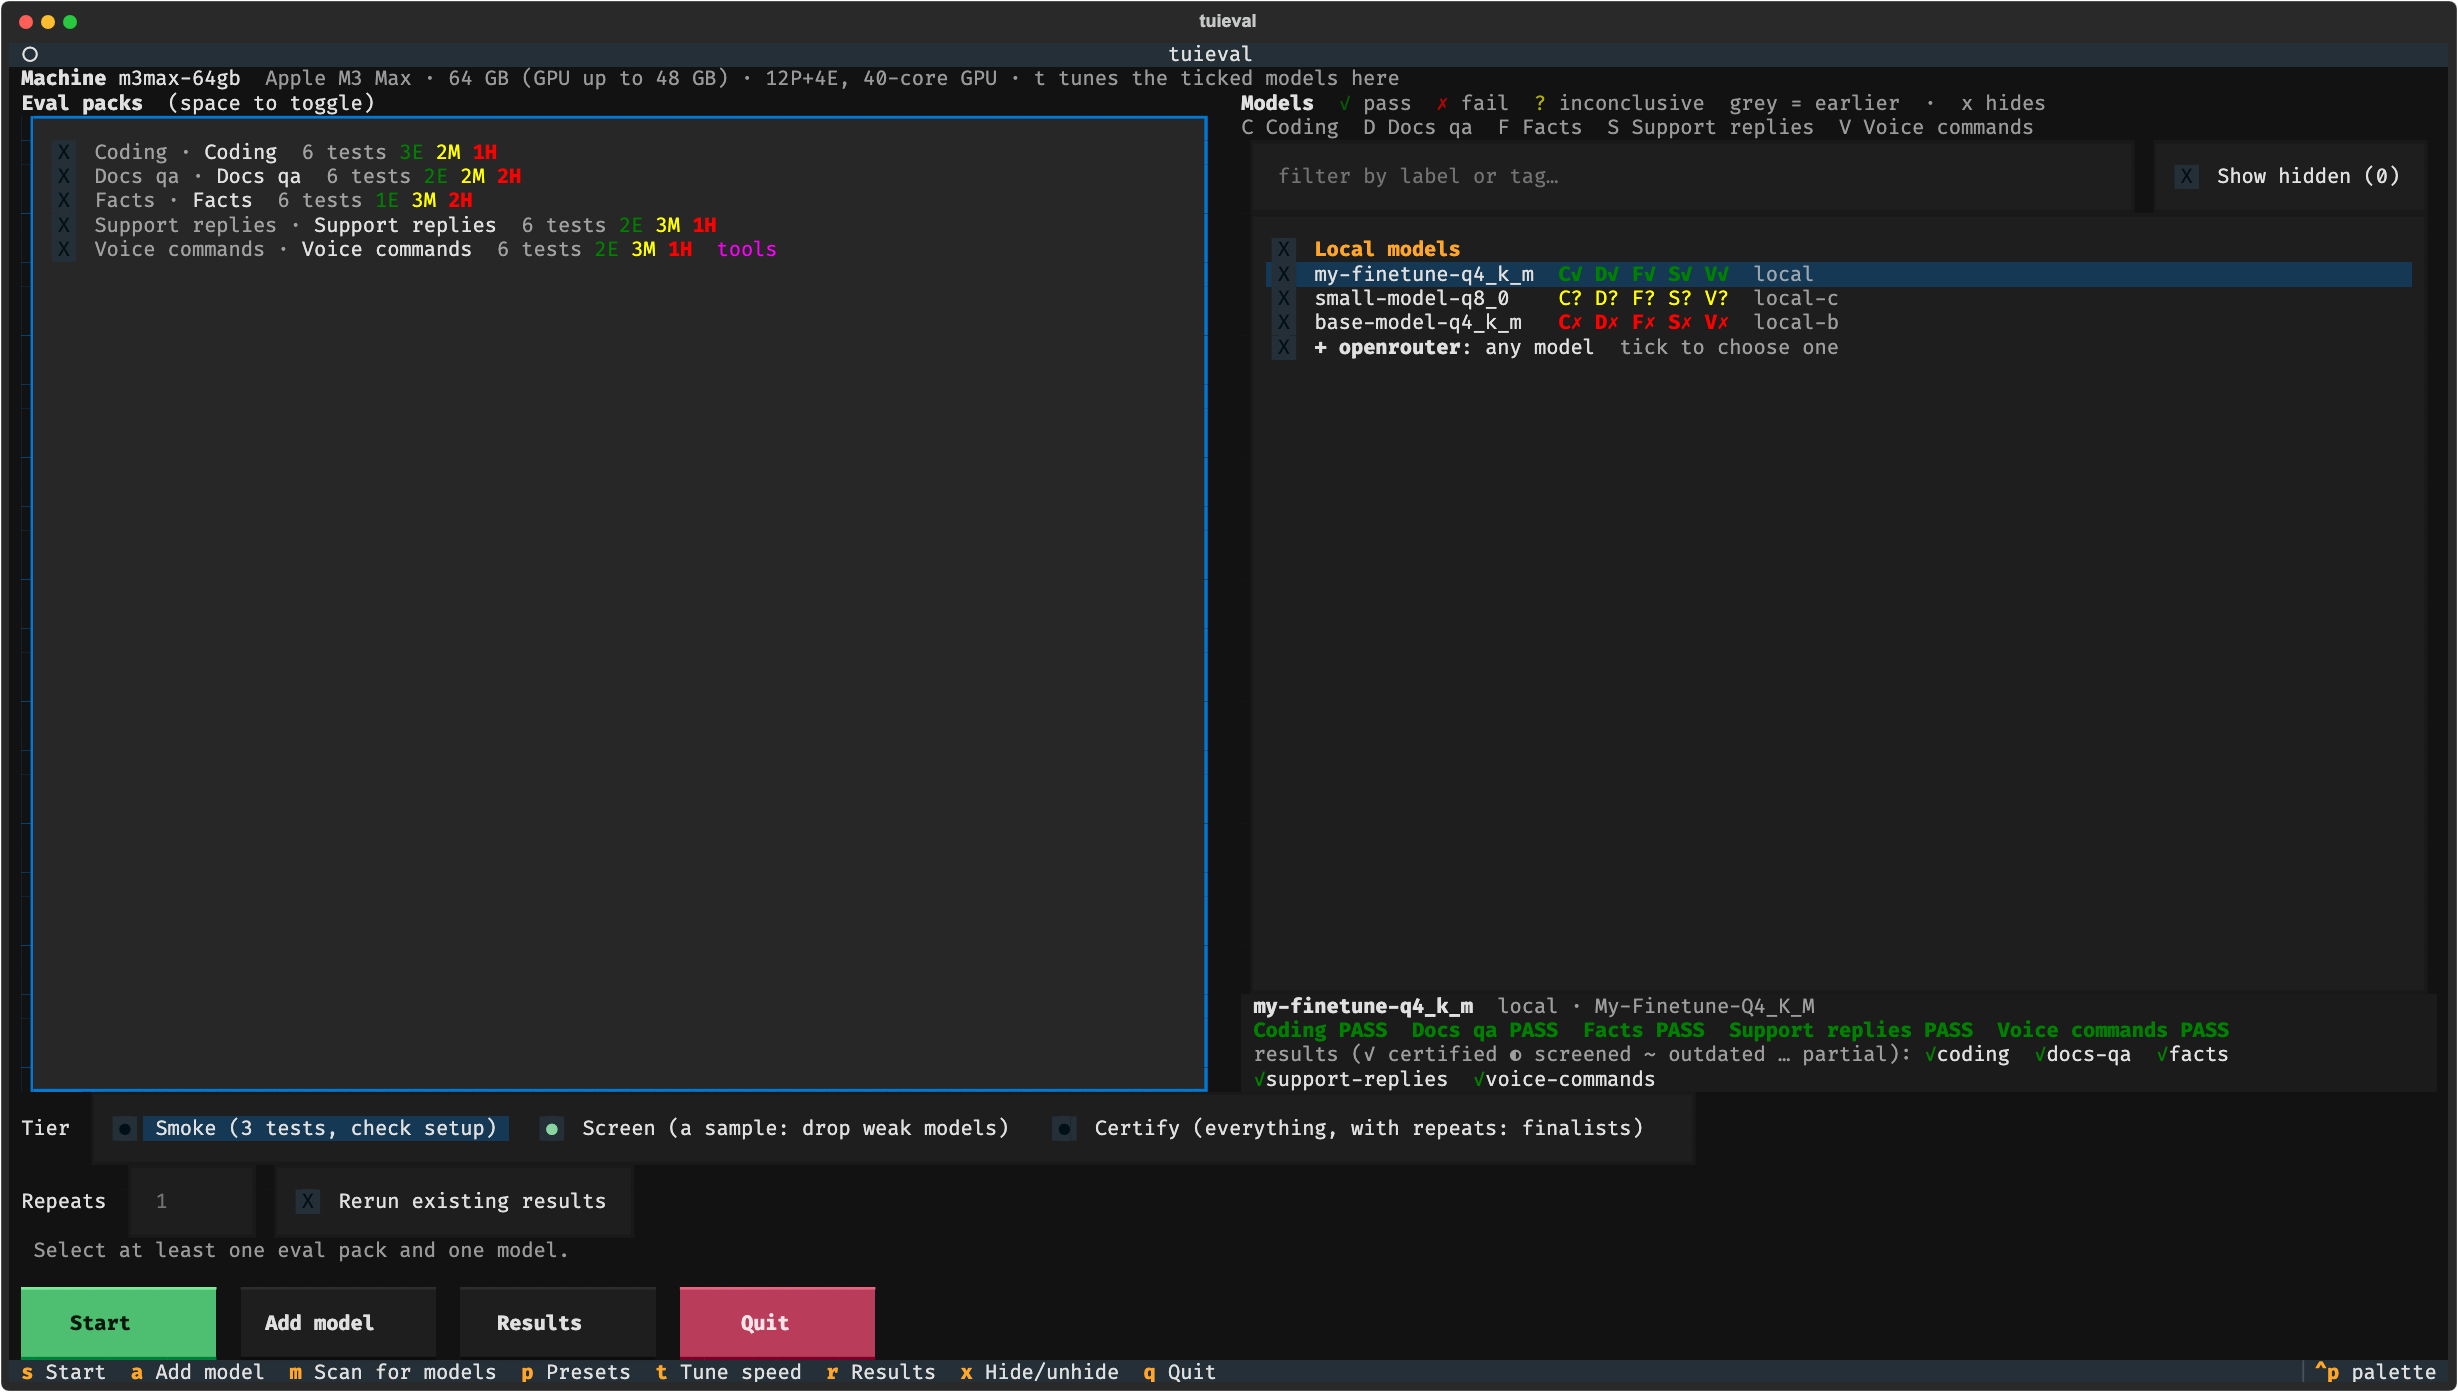
Once you've added your own packs and models, the setup screen looks like this (packs on the left, models with a verdict code per use case on the right, the highlighted model's details below):
|
|
47
49
|
|
|
48
50
|
|
|
@@ -17,6 +17,8 @@ tuieval add ~/models/Some-Model-Q4_K_M.gguf
|
|
|
17
17
|
tuieval # open the TUI
|
|
18
18
|
```
|
|
19
19
|
|
|
20
|
+
`pip install tuieval` gets the latest release. Every change on `main` is also published as a dev build (`X.Y.0.devN`); get it with `pipx install --pip-args=--pre tuieval` or `pip install --pre tuieval`.
|
|
21
|
+
|
|
20
22
|
Once you've added your own packs and models, the setup screen looks like this (packs on the left, models with a verdict code per use case on the right, the highlighted model's details below):
|
|
21
23
|
|
|
22
24
|

|
|
@@ -0,0 +1,31 @@
|
|
|
1
|
+
# Releasing
|
|
2
|
+
|
|
3
|
+
Versions come from git (hatch-vcs). Nobody edits a version number by hand.
|
|
4
|
+
|
|
5
|
+
| What | Version | Who gets it |
|
|
6
|
+
|---|---|---|
|
|
7
|
+
| A tag `vX.Y.Z` | `X.Y.Z` | `pip install tuieval` |
|
|
8
|
+
| Every other commit on `main` | `X.(Y+1).0.devN`, N = commits since the last tag | `pip install --pre tuieval` |
|
|
9
|
+
|
|
10
|
+
CI (`.github/workflows/test.yml`) runs the tests on every push. When they pass, the `publish` job builds the package, checks it with `twine check`, and uploads it to PyPI with trusted publishing (no token is stored anywhere): every push to `main` as a dev build, every `v*` tag as a release.
|
|
11
|
+
|
|
12
|
+
## Day to day
|
|
13
|
+
|
|
14
|
+
1. Commit and push to `main`. Add a line under `## Unreleased` in `CHANGELOG.md` for anything users would notice.
|
|
15
|
+
2. CI publishes the dev build. Check it: `pipx install --force --pip-args=--pre tuieval && tuieval --version`.
|
|
16
|
+
|
|
17
|
+
## A release
|
|
18
|
+
|
|
19
|
+
Cut one when there's something worth announcing, not for every change. Semantic versioning: PATCH for fixes, MINOR for features (and anything that changes behaviour while the major version is 0), MAJOR for breaking changes after 1.0.
|
|
20
|
+
|
|
21
|
+
1. In `CHANGELOG.md`, rename `## Unreleased` to `## X.Y.Z` and add a new empty `## Unreleased` above it. Commit and push.
|
|
22
|
+
2. Tag that commit and push the tag: `git tag -a vX.Y.Z -m "X.Y.Z" && git push origin vX.Y.Z`.
|
|
23
|
+
3. CI publishes `X.Y.Z`. Check a fresh install: `pipx install --force tuieval==X.Y.Z && tuieval --version`.
|
|
24
|
+
|
|
25
|
+
## One-time setup (done once per PyPI project)
|
|
26
|
+
|
|
27
|
+
On PyPI, under the project's Publishing settings, add a trusted publisher: owner `ashe-wb`, repository `tuieval`, workflow `test.yml`, environment `pypi`.
|
|
28
|
+
|
|
29
|
+
## Building by hand
|
|
30
|
+
|
|
31
|
+
`python -m pip install build twine && python -m build && twine check dist/*`. A build needs the git history and tags (a full clone), or it can't tell its version.
|
|
@@ -90,10 +90,9 @@ The knobs are `[servers.<name>.tune]` in `models.toml`: each knob is a list of o
|
|
|
90
90
|
|
|
91
91
|
`tuieval export pi <model>` makes pi serve a model the way the evals did: the same file, the output-affecting flags, the context from the fit check, the model's sampling, and the speed flags tuned on this machine. `tuieval tune <model> --export-pi` does it right after tuning.
|
|
92
92
|
|
|
93
|
-
|
|
94
|
-
- **amalgam models:** a `[models."<id>"]` entry in the amalgam router's `models.toml` and an entry in pi's `amalgam` provider models (copied from the first one there, then name, context and vision set). The router passes the same args to every model, so a model's own `server_args` can't be exported; the export says so.
|
|
93
|
+
It writes a `[<id>]` section in llama-router's presets file (keys that equal its `[*]` section are left out) and an entry under pi's `llama` provider `modelOverrides` (name, context window, vision, reasoning). It exports models on llama servers.
|
|
95
94
|
|
|
96
|
-
It shows the diff and the notes first (untuned or outdated tuning, other preset sections that name missing files, a reasoning effort to pick in pi), asks, backs every file up as `<file>.bak-tuieval-<time>`, and refuses to write a file that changed in the meantime. `--dry-run` only shows; `--yes` doesn't ask. Restart the router afterwards (`llama-router restart`
|
|
95
|
+
It shows the diff and the notes first (untuned or outdated tuning, other preset sections that name missing files, a reasoning effort to pick in pi), asks, backs every file up as `<file>.bak-tuieval-<time>`, and refuses to write a file that changed in the meantime. `--dry-run` only shows; `--yes` doesn't ask. Restart the router afterwards (`llama-router restart`).
|
|
97
96
|
|
|
98
97
|
The id pi sees defaults to the GGUF's name; set `pi_id` and `pi_name` on the model (or pass `--id`/`--name`). Paths and provider names come from `[export.pi]` in `models.toml`:
|
|
99
98
|
|
|
@@ -101,10 +100,8 @@ The id pi sees defaults to the GGUF's name; set `pi_id` and `pi_name` on the mod
|
|
|
101
100
|
[export.pi]
|
|
102
101
|
presets = "~/models/presets.ini"
|
|
103
102
|
pi_models = "~/.pi/agent/models.json"
|
|
104
|
-
|
|
105
|
-
|
|
106
|
-
amalgam_provider = "amalgam"
|
|
107
|
-
servers = { llama = "llama", amalgam = "amalgam" } # models.toml server -> which export it gets
|
|
103
|
+
llama_provider = "llama" # pi's provider name for the router
|
|
104
|
+
servers = ["llama"] # models.toml servers that llama-router can serve
|
|
108
105
|
```
|
|
109
106
|
|
|
110
107
|
## Speed verdicts
|
|
@@ -1,5 +1,5 @@
|
|
|
1
1
|
[build-system]
|
|
2
|
-
requires = ["hatchling>=1.24"]
|
|
2
|
+
requires = ["hatchling>=1.24", "hatch-vcs>=0.4"]
|
|
3
3
|
build-backend = "hatchling.build"
|
|
4
4
|
|
|
5
5
|
[project]
|
|
@@ -37,8 +37,17 @@ tuieval = "tuieval.cli:main"
|
|
|
37
37
|
Homepage = "https://github.com/ashe-wb/tuieval"
|
|
38
38
|
Issues = "https://github.com/ashe-wb/tuieval/issues"
|
|
39
39
|
|
|
40
|
+
# The version comes from git: a tag vX.Y.Z is that release; every commit after it on main is
|
|
41
|
+
# X.(Y+1).0.devN, N = commits since the tag (see RELEASING.md).
|
|
40
42
|
[tool.hatch.version]
|
|
41
|
-
|
|
43
|
+
source = "vcs"
|
|
44
|
+
|
|
45
|
+
[tool.hatch.version.raw-options]
|
|
46
|
+
version_scheme = "release-branch-semver"
|
|
47
|
+
local_scheme = "no-local-version"
|
|
48
|
+
|
|
49
|
+
[tool.hatch.build.hooks.vcs]
|
|
50
|
+
version-file = "src/tuieval/_version.py"
|
|
42
51
|
|
|
43
52
|
[tool.hatch.build.targets.wheel]
|
|
44
53
|
packages = ["src/tuieval"]
|
|
@@ -0,0 +1,5 @@
|
|
|
1
|
+
"""tuieval: evaluate local and frontier models on your own eval packs, in the terminal."""
|
|
2
|
+
try:
|
|
3
|
+
from ._version import __version__ # written by the build from the git tag (RELEASING.md)
|
|
4
|
+
except ImportError: # a source tree that was never built or installed
|
|
5
|
+
__version__ = "0+unknown"
|
|
@@ -0,0 +1,24 @@
|
|
|
1
|
+
# file generated by vcs-versioning
|
|
2
|
+
# don't change, don't track in version control
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
__all__ = [
|
|
6
|
+
"__version__",
|
|
7
|
+
"__version_tuple__",
|
|
8
|
+
"version",
|
|
9
|
+
"version_tuple",
|
|
10
|
+
"__commit_id__",
|
|
11
|
+
"commit_id",
|
|
12
|
+
]
|
|
13
|
+
|
|
14
|
+
version: str
|
|
15
|
+
__version__: str
|
|
16
|
+
__version_tuple__: tuple[int | str, ...]
|
|
17
|
+
version_tuple: tuple[int | str, ...]
|
|
18
|
+
commit_id: str | None
|
|
19
|
+
__commit_id__: str | None
|
|
20
|
+
|
|
21
|
+
__version__ = version = '0.2.0.dev1'
|
|
22
|
+
__version_tuple__ = version_tuple = (0, 2, 0, 'dev1')
|
|
23
|
+
|
|
24
|
+
__commit_id__ = commit_id = None
|
|
@@ -1,10 +1,8 @@
|
|
|
1
1
|
"""Export a model's serving settings to the pi coding agent, so pi serves it exactly as the evals did:
|
|
2
2
|
the same model file, output-affecting flags and context, plus the speed flags tuned on this machine.
|
|
3
3
|
|
|
4
|
-
|
|
5
|
-
|
|
6
|
-
amalgam models a [models."<id>"] entry in the amalgam router's models.toml and an entry in pi's
|
|
7
|
-
`amalgam` provider models
|
|
4
|
+
a section in llama-router's presets (~/models/presets.ini; keys that equal the [*] section are
|
|
5
|
+
left out) and an entry under pi's `llama` provider modelOverrides. Models on llama servers only.
|
|
8
6
|
|
|
9
7
|
Every file is backed up next to itself (<file>.bak-tuieval-<time>) before it changes, and the diff
|
|
10
8
|
is shown first. Paths come from models.toml [export.pi]:
|
|
@@ -12,10 +10,8 @@ is shown first. Paths come from models.toml [export.pi]:
|
|
|
12
10
|
[export.pi]
|
|
13
11
|
presets = "~/models/presets.ini" # llama-router --models-preset
|
|
14
12
|
pi_models = "~/.pi/agent/models.json"
|
|
15
|
-
|
|
16
|
-
|
|
17
|
-
amalgam_provider = "amalgam"
|
|
18
|
-
servers = { llama = "llama", amalgam = "amalgam" } # models.toml server -> export kind
|
|
13
|
+
llama_provider = "llama" # pi's provider name for the router
|
|
14
|
+
servers = ["llama"] # models.toml servers that llama-router can serve
|
|
19
15
|
"""
|
|
20
16
|
import configparser
|
|
21
17
|
import difflib
|
|
@@ -28,8 +24,7 @@ import time
|
|
|
28
24
|
from . import engine as engine_mod
|
|
29
25
|
|
|
30
26
|
DEFAULTS = {"presets": "~/models/presets.ini", "pi_models": "~/.pi/agent/models.json",
|
|
31
|
-
"
|
|
32
|
-
"amalgam_provider": "amalgam", "servers": {"llama": "llama", "amalgam": "amalgam"}}
|
|
27
|
+
"llama_provider": "llama", "servers": ["llama"]}
|
|
33
28
|
# llama.cpp short flags -> the long names presets use as keys
|
|
34
29
|
SHORT = {"-m": "model", "-c": "ctx-size", "-t": "threads", "-tb": "threads-batch", "-ub": "ubatch-size",
|
|
35
30
|
"-b": "batch-size", "-fa": "flash-attn", "-ngl": "n-gpu-layers", "-np": "parallel",
|
|
@@ -42,9 +37,7 @@ class ExportError(Exception):
|
|
|
42
37
|
|
|
43
38
|
|
|
44
39
|
def settings(eng):
|
|
45
|
-
|
|
46
|
-
s["servers"] = {**DEFAULTS["servers"], **s.get("servers", {})}
|
|
47
|
-
return s
|
|
40
|
+
return {**DEFAULTS, **eng.cfg.get("export", {}).get("pi", {})}
|
|
48
41
|
|
|
49
42
|
|
|
50
43
|
def default_id(m):
|
|
@@ -133,12 +126,11 @@ def plan(eng, label, model_id=None, name=None):
|
|
|
133
126
|
"""(changes, notes) that export one model to pi. Nothing is written."""
|
|
134
127
|
m = eng.model(label)
|
|
135
128
|
s = settings(eng)
|
|
136
|
-
|
|
137
|
-
|
|
138
|
-
|
|
139
|
-
"servers ([export.pi] servers maps others)")
|
|
129
|
+
if m["server"] not in s["servers"]:
|
|
130
|
+
raise ExportError(f"{label} runs on the {m['server']} server; pi export writes llama-router presets, "
|
|
131
|
+
"for llama servers ([export.pi] servers lists them)")
|
|
140
132
|
model_id = model_id or m.get("pi_id") or default_id(m)
|
|
141
|
-
name = name or m.get("pi_name") or
|
|
133
|
+
name = name or m.get("pi_name") or model_id
|
|
142
134
|
sv = eng.serving(m)
|
|
143
135
|
notes = []
|
|
144
136
|
sampling = engine_mod.effective_sampling(eng.cfg, m)
|
|
@@ -150,85 +142,48 @@ def plan(eng, label, model_id=None, name=None):
|
|
|
150
142
|
pi = json.loads(pi_old)
|
|
151
143
|
providers = pi.setdefault("providers", {})
|
|
152
144
|
changes = []
|
|
153
|
-
if
|
|
154
|
-
|
|
155
|
-
|
|
156
|
-
|
|
157
|
-
|
|
158
|
-
|
|
159
|
-
|
|
160
|
-
|
|
161
|
-
|
|
162
|
-
|
|
163
|
-
|
|
164
|
-
|
|
165
|
-
|
|
166
|
-
|
|
167
|
-
|
|
168
|
-
|
|
169
|
-
|
|
170
|
-
|
|
171
|
-
|
|
172
|
-
|
|
173
|
-
|
|
174
|
-
|
|
175
|
-
|
|
176
|
-
|
|
177
|
-
|
|
178
|
-
|
|
179
|
-
|
|
180
|
-
|
|
181
|
-
|
|
182
|
-
|
|
183
|
-
|
|
184
|
-
|
|
185
|
-
|
|
186
|
-
|
|
187
|
-
|
|
188
|
-
|
|
189
|
-
|
|
190
|
-
|
|
191
|
-
|
|
192
|
-
|
|
193
|
-
|
|
194
|
-
|
|
195
|
-
notes.append("restart llama-router to load the new presets (llama-router restart)")
|
|
196
|
-
else:
|
|
197
|
-
path = engine_mod.expand(s["amalgam_models"])
|
|
198
|
-
old = _read(path)
|
|
199
|
-
if not old:
|
|
200
|
-
raise ExportError(f"amalgam router config {path} not found ([export.pi] amalgam_models)")
|
|
201
|
-
import tomllib
|
|
202
|
-
router = tomllib.loads(old)
|
|
203
|
-
want = m["model"]
|
|
204
|
-
have = router.get("models", {}).get(model_id, {}).get("path")
|
|
205
|
-
if have is None:
|
|
206
|
-
new = old.rstrip("\n") + f'\n\n[models."{model_id}"]\npath = "{want}"\n'
|
|
207
|
-
elif engine_mod.expand(have) != engine_mod.expand(want):
|
|
208
|
-
new = re.sub(r'(\[models\."' + re.escape(model_id) + r'"\][^\[]*?path\s*=\s*)"[^"]*"',
|
|
209
|
-
lambda h: h.group(1) + f'"{want}"', old, count=1)
|
|
210
|
-
else:
|
|
211
|
-
new = old
|
|
212
|
-
if new != old:
|
|
213
|
-
changes.append(Change(path, old, new))
|
|
214
|
-
args = [str(a) for a in router.get("args", [])]
|
|
215
|
-
if m.get("server_args"):
|
|
216
|
-
notes.append(f"{label} has server_args {m['server_args']}, but the amalgam router passes the same "
|
|
217
|
-
f"args to every model ({' '.join(args)}): pi won't get them")
|
|
218
|
-
ctx = m.get("max_context") or sv.ctx
|
|
219
|
-
if "--max-context" in args[:-1] and ctx and str(ctx) != args[args.index("--max-context") + 1]:
|
|
220
|
-
notes.append(f"the router serves --max-context {args[args.index('--max-context') + 1]}; the evals ran {ctx}")
|
|
221
|
-
prov = providers.setdefault(s["amalgam_provider"], {})
|
|
222
|
-
models = prov.setdefault("models", [])
|
|
223
|
-
entry = next((x for x in models if x.get("id") == model_id), None)
|
|
224
|
-
if entry is None:
|
|
225
|
-
template = {k: v for k, v in (models[0] if models else {}).items() if k not in ("id", "name")}
|
|
226
|
-
entry = {"id": model_id, "name": name, **template}
|
|
227
|
-
models.append(entry)
|
|
228
|
-
entry.update({"name": name, "reasoning": bool(sampling.get("enable_thinking", True)),
|
|
229
|
-
"input": ["text", "image"] if vision else ["text"], "contextWindow": ctx})
|
|
230
|
-
entry.setdefault("maxTokens", sampling.get("max_tokens"))
|
|
231
|
-
notes.append("restart the amalgam router to serve it (amalgam restart)")
|
|
145
|
+
if sv.perf_source == "untuned":
|
|
146
|
+
notes.append(f"{label} isn't tuned on this machine: exporting the untuned defaults (tuieval tune {label})")
|
|
147
|
+
elif sv.perf_source.startswith("outdated"):
|
|
148
|
+
notes.append(f"{label}'s tuning is {sv.perf_source}; consider tuieval tune {label}")
|
|
149
|
+
cmd, _, _ = eng.server_command(m)
|
|
150
|
+
if cmd[0] == "env":
|
|
151
|
+
raise ExportError("the server command sets environment variables, which presets can't hold")
|
|
152
|
+
first = next(i for i, a in enumerate(cmd) if a.startswith("-"))
|
|
153
|
+
flags = {}
|
|
154
|
+
for k, v in flags_to_keys(cmd[first:]):
|
|
155
|
+
if k not in ROUTER_OWNED:
|
|
156
|
+
flags[k] = v # a repeated flag: the last wins, as on the command line
|
|
157
|
+
for k, key in SAMPLING_KEYS.items():
|
|
158
|
+
if sampling.get(k) is not None:
|
|
159
|
+
flags[key] = str(sampling[k])
|
|
160
|
+
path = engine_mod.expand(s["presets"])
|
|
161
|
+
old = _read(path)
|
|
162
|
+
if not old:
|
|
163
|
+
raise ExportError(f"presets file {path} not found ([export.pi] presets)")
|
|
164
|
+
sections = _ini_sections(old)
|
|
165
|
+
common = sections.get("*", {})
|
|
166
|
+
order = ["model", "mmproj"] + [k for k in flags if k not in ("model", "mmproj")]
|
|
167
|
+
lines = [f"{k:<16} = {flags[k]}" for k in order if k in flags and common.get(k) != flags[k]]
|
|
168
|
+
tuned = {k for opts in eng.cfg["servers"][m["server"]].get("tune", {}).values() for o in opts
|
|
169
|
+
for k, _ in flags_to_keys(o)}
|
|
170
|
+
for k in common:
|
|
171
|
+
if k in tuned and k not in flags:
|
|
172
|
+
notes.append(f"presets [*] sets {k} = {common[k]}, which {label}'s tuned flags leave off; "
|
|
173
|
+
"the router will still apply it")
|
|
174
|
+
broken = [sec for sec, kv in sections.items() if sec != model_id
|
|
175
|
+
and any(kv.get(k) and not os.path.exists(os.path.expanduser(kv[k])) for k in ("model", "mmproj"))]
|
|
176
|
+
if broken:
|
|
177
|
+
notes.append(f"{path}: {len(broken)} other section(s) name files that don't exist, so pi can't load "
|
|
178
|
+
f"them: {', '.join(broken)}")
|
|
179
|
+
changes.append(Change(path, old, set_ini_section(old, model_id, lines)))
|
|
180
|
+
prov = providers.setdefault(s["llama_provider"], {})
|
|
181
|
+
entry = prov.setdefault("modelOverrides", {}).setdefault(model_id, {})
|
|
182
|
+
entry.update({"name": name, "contextWindow": sv.ctx,
|
|
183
|
+
"maxTokens": entry.get("maxTokens", sampling.get("max_tokens")),
|
|
184
|
+
"reasoning": bool(sampling.get("enable_thinking", True)),
|
|
185
|
+
"input": ["text", "image"] if vision else ["text"]})
|
|
186
|
+
notes.append("restart llama-router to load the new presets (llama-router restart)")
|
|
232
187
|
if sampling.get("reasoning_effort"):
|
|
233
188
|
notes.append(f"the evals ran reasoning_effort {sampling['reasoning_effort']}: pick that thinking level in pi")
|
|
234
189
|
pi_new = json.dumps(pi, indent=2, ensure_ascii=False) + "\n"
|
|
@@ -576,11 +576,11 @@ def cmd_export(argv):
|
|
|
576
576
|
description="Write a model's serving settings (model file, output-affecting flags, "
|
|
577
577
|
"context and the speed flags tuned on this machine) to another tool. "
|
|
578
578
|
"Shows the diff and asks first; every file is backed up.")
|
|
579
|
-
p.add_argument("target", choices=["pi"], help="pi: the pi coding agent (llama-router presets
|
|
580
|
-
"
|
|
579
|
+
p.add_argument("target", choices=["pi"], help="pi: the pi coding agent (llama-router presets and pi's "
|
|
580
|
+
"models.json)")
|
|
581
581
|
p.add_argument("labels", nargs="+", help="models to export")
|
|
582
582
|
p.add_argument("--id", help="the model id pi sees (default: models.toml pi_id, else the GGUF's name)")
|
|
583
|
-
p.add_argument("--name", help="the name pi shows (default: models.toml pi_name, else
|
|
583
|
+
p.add_argument("--name", help="the name pi shows (default: models.toml pi_name, else the id)")
|
|
584
584
|
p.add_argument("--dry-run", action="store_true", help="show the changes only")
|
|
585
585
|
p.add_argument("--yes", action="store_true", help="write without asking")
|
|
586
586
|
p.add_argument("--models", default=None, help="default: the workspace's models.toml")
|
|
@@ -329,7 +329,7 @@ class WarmTune(unittest.TestCase):
|
|
|
329
329
|
|
|
330
330
|
|
|
331
331
|
class ExportPi(unittest.TestCase):
|
|
332
|
-
"""export.plan/apply against temporary presets
|
|
332
|
+
"""export.plan/apply against a temporary presets file and pi models.json."""
|
|
333
333
|
PRESETS = textwrap.dedent("""\
|
|
334
334
|
version = 1
|
|
335
335
|
|
|
@@ -356,19 +356,14 @@ class ExportPi(unittest.TestCase):
|
|
|
356
356
|
fake_gguf(f"{d}/Old.gguf")
|
|
357
357
|
write(f"{d}/presets.ini", self.PRESETS)
|
|
358
358
|
write(f"{d}/models.json", json.dumps({"providers": {
|
|
359
|
-
"
|
|
360
|
-
{"id": "A", "name": "a", "maxTokens": 32768, "thinkingLevelMap": {"off": "none"}}]},
|
|
361
|
-
"llama": {"modelOverrides": {}}}}, indent=2) + "\n")
|
|
362
|
-
write(f"{d}/router.toml", 'args = ["--max-context", "131072"]\n\n[models."A"]\npath = "~/a.gguf"\n')
|
|
359
|
+
"llama": {"apiKey": "SECRET", "modelOverrides": {}}}}, indent=2) + "\n")
|
|
363
360
|
cfg = {"sampling": {"temperature": 1.0, "max_tokens": 16384, "enable_thinking": True},
|
|
364
361
|
"servers": {"llama": {"cmd": ["llama"], "tune": {"cache_reuse": [["--cache-reuse", "256"], []]}},
|
|
365
|
-
"
|
|
362
|
+
"mlx": {"cmd": ["mlx"]}},
|
|
366
363
|
"models": [{"label": "l", "server": "llama", "model": f"{d}/Old.gguf",
|
|
367
364
|
"sampling": {"presence_penalty": 1.5}},
|
|
368
|
-
{"label": "s", "server": "
|
|
369
|
-
|
|
370
|
-
"export": {"pi": {"presets": f"{d}/presets.ini", "pi_models": f"{d}/models.json",
|
|
371
|
-
"amalgam_models": f"{d}/router.toml"}}}
|
|
365
|
+
{"label": "s", "server": "mlx", "model": "~/b"}],
|
|
366
|
+
"export": {"pi": {"presets": f"{d}/presets.ini", "pi_models": f"{d}/models.json"}}}
|
|
372
367
|
eng = types.SimpleNamespace(cfg=cfg)
|
|
373
368
|
eng.model = lambda label: next(m for m in cfg["models"] if m["label"] == label)
|
|
374
369
|
eng.serving = lambda m: types.SimpleNamespace(perf_source="tuned", ctx=98304)
|
|
@@ -403,30 +398,28 @@ class ExportPi(unittest.TestCase):
|
|
|
403
398
|
pi = json.loads(next(c for c in changes if c.path.endswith("models.json")).new)
|
|
404
399
|
self.assertEqual(pi["providers"]["llama"]["modelOverrides"]["Old"]["contextWindow"], 98304)
|
|
405
400
|
|
|
406
|
-
def
|
|
407
|
-
|
|
408
|
-
|
|
409
|
-
|
|
410
|
-
|
|
411
|
-
|
|
412
|
-
|
|
413
|
-
|
|
414
|
-
self.
|
|
415
|
-
self.assertNotIn("SECRET", pi_change.diff())
|
|
401
|
+
def test_only_llama_servers(self):
|
|
402
|
+
with self.assertRaises(self.export.ExportError):
|
|
403
|
+
self.export.plan(self.eng, "s")
|
|
404
|
+
|
|
405
|
+
def test_diff_hides_credentials(self):
|
|
406
|
+
changes, _ = self.export.plan(self.eng, "l", model_id="New")
|
|
407
|
+
diff = next(c for c in changes if c.path.endswith("models.json")).diff()
|
|
408
|
+
self.assertIn('"New"', diff)
|
|
409
|
+
self.assertNotIn("SECRET", diff)
|
|
416
410
|
|
|
417
411
|
def test_apply_backs_up_and_refuses_a_file_changed_since(self):
|
|
418
|
-
changes, _ = self.export.plan(self.eng, "
|
|
412
|
+
changes, _ = self.export.plan(self.eng, "l", model_id="New")
|
|
419
413
|
backups = self.export.apply(changes)
|
|
420
414
|
self.assertEqual(len(backups), 2)
|
|
421
|
-
self.assertIn(
|
|
422
|
-
self.assertNotIn(
|
|
423
|
-
self.assertEqual(self.export.plan(self.eng, "
|
|
424
|
-
changes, _ = self.export.plan(self.eng, "
|
|
425
|
-
write(f"{self.d}/
|
|
415
|
+
self.assertIn("[New]", read(f"{self.d}/presets.ini"))
|
|
416
|
+
self.assertNotIn("[New]", read(next(b for b in backups if "presets.ini" in b)))
|
|
417
|
+
self.assertEqual(self.export.plan(self.eng, "l", model_id="New")[0], []) # already exported
|
|
418
|
+
changes, _ = self.export.plan(self.eng, "l", model_id="Other")
|
|
419
|
+
write(f"{self.d}/presets.ini", "edited\n")
|
|
426
420
|
with self.assertRaises(self.export.ExportError):
|
|
427
421
|
self.export.apply(changes)
|
|
428
422
|
|
|
429
|
-
|
|
430
423
|
class Remove(unittest.TestCase):
|
|
431
424
|
TOML = textwrap.dedent("""\
|
|
432
425
|
[servers.llama]
|
tuieval-0.1.6/RELEASING.md
DELETED
|
@@ -1,7 +0,0 @@
|
|
|
1
|
-
# Releasing
|
|
2
|
-
|
|
3
|
-
1. Bump `__version__` in `src/tuieval/__init__.py` and add a `CHANGELOG.md` entry.
|
|
4
|
-
2. Commit, push, and wait for CI to pass.
|
|
5
|
-
3. Build from a clean checkout and check: `python -m pip install build twine && python -m build && twine check dist/*`
|
|
6
|
-
4. Publish to PyPI: `twine upload dist/*` (username `__token__`, password: a PyPI API token).
|
|
7
|
-
5. Check a fresh install: `pipx install --force tuieval==<version> && tuieval --version`
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|