trulens-eval 0.33.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- trulens_eval-0.33.0/MANIFEST.in +6 -0
- trulens_eval-0.33.0/PKG-INFO +98 -0
- trulens_eval-0.33.0/README.md +55 -0
- trulens_eval-0.33.0/setup.cfg +20 -0
- trulens_eval-0.33.0/setup.py +72 -0
- trulens_eval-0.33.0/trulens_eval/Example_TruBot.py +172 -0
- trulens_eval-0.33.0/trulens_eval/LICENSE +21 -0
- trulens_eval-0.33.0/trulens_eval/Leaderboard.py +150 -0
- trulens_eval-0.33.0/trulens_eval/__init__.py +111 -0
- trulens_eval-0.33.0/trulens_eval/app.py +1533 -0
- trulens_eval-0.33.0/trulens_eval/appui.py +457 -0
- trulens_eval-0.33.0/trulens_eval/database/__init__.py +0 -0
- trulens_eval-0.33.0/trulens_eval/database/base.py +292 -0
- trulens_eval-0.33.0/trulens_eval/database/exceptions.py +65 -0
- trulens_eval-0.33.0/trulens_eval/database/legacy/migration.py +406 -0
- trulens_eval-0.33.0/trulens_eval/database/migrations/__init__.py +120 -0
- trulens_eval-0.33.0/trulens_eval/database/migrations/alembic.ini +104 -0
- trulens_eval-0.33.0/trulens_eval/database/migrations/data.py +192 -0
- trulens_eval-0.33.0/trulens_eval/database/migrations/env.py +99 -0
- trulens_eval-0.33.0/trulens_eval/database/migrations/versions/1_first_revision.py +78 -0
- trulens_eval-0.33.0/trulens_eval/database/orm.py +389 -0
- trulens_eval-0.33.0/trulens_eval/database/sqlalchemy.py +883 -0
- trulens_eval-0.33.0/trulens_eval/database/utils.py +234 -0
- trulens_eval-0.33.0/trulens_eval/feedback/__init__.py +43 -0
- trulens_eval-0.33.0/trulens_eval/feedback/embeddings.py +204 -0
- trulens_eval-0.33.0/trulens_eval/feedback/feedback.py +1227 -0
- trulens_eval-0.33.0/trulens_eval/feedback/groundtruth.py +328 -0
- trulens_eval-0.33.0/trulens_eval/feedback/prompts.py +168 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/__init__.py +34 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/base.py +1242 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/bedrock.py +290 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/cortex.py +113 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/__init__.py +31 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/base.py +923 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/bedrock.py +244 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/cortex.py +99 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/hugs.py +80 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/langchain.py +64 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/litellm.py +124 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/endpoint/openai.py +369 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/hugs.py +760 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/langchain.py +77 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/litellm.py +126 -0
- trulens_eval-0.33.0/trulens_eval/feedback/provider/openai.py +445 -0
- trulens_eval-0.33.0/trulens_eval/feedback/v2/feedback.py +617 -0
- trulens_eval-0.33.0/trulens_eval/feedback/v2/provider/base.py +96 -0
- trulens_eval-0.33.0/trulens_eval/generate_test_set.py +216 -0
- trulens_eval-0.33.0/trulens_eval/guardrails/__init__.py +0 -0
- trulens_eval-0.33.0/trulens_eval/guardrails/base.py +67 -0
- trulens_eval-0.33.0/trulens_eval/guardrails/langchain.py +122 -0
- trulens_eval-0.33.0/trulens_eval/guardrails/llama.py +103 -0
- trulens_eval-0.33.0/trulens_eval/instruments.py +1003 -0
- trulens_eval-0.33.0/trulens_eval/keys.py +416 -0
- trulens_eval-0.33.0/trulens_eval/pages/Apps.py +429 -0
- trulens_eval-0.33.0/trulens_eval/pages/Evaluations.py +443 -0
- trulens_eval-0.33.0/trulens_eval/react_components/record_viewer/__init__.py +80 -0
- trulens_eval-0.33.0/trulens_eval/react_components/record_viewer/dist/assets/SourceCodePro-Bold-839f42df.ttf +0 -0
- trulens_eval-0.33.0/trulens_eval/react_components/record_viewer/dist/assets/SourceCodePro-Regular-6e5dd049.ttf +0 -0
- trulens_eval-0.33.0/trulens_eval/react_components/record_viewer/dist/assets/SourceCodePro-SemiBold-ccfba566.ttf +0 -0
- trulens_eval-0.33.0/trulens_eval/react_components/record_viewer/dist/assets/index-00b8e16d.css +1 -0
- trulens_eval-0.33.0/trulens_eval/react_components/record_viewer/dist/assets/index-923e1c7a.js +236 -0
- trulens_eval-0.33.0/trulens_eval/react_components/record_viewer/dist/index.html +14 -0
- trulens_eval-0.33.0/trulens_eval/requirements.optional.txt +74 -0
- trulens_eval-0.33.0/trulens_eval/requirements.txt +43 -0
- trulens_eval-0.33.0/trulens_eval/schema/__init__.py +22 -0
- trulens_eval-0.33.0/trulens_eval/schema/app.py +278 -0
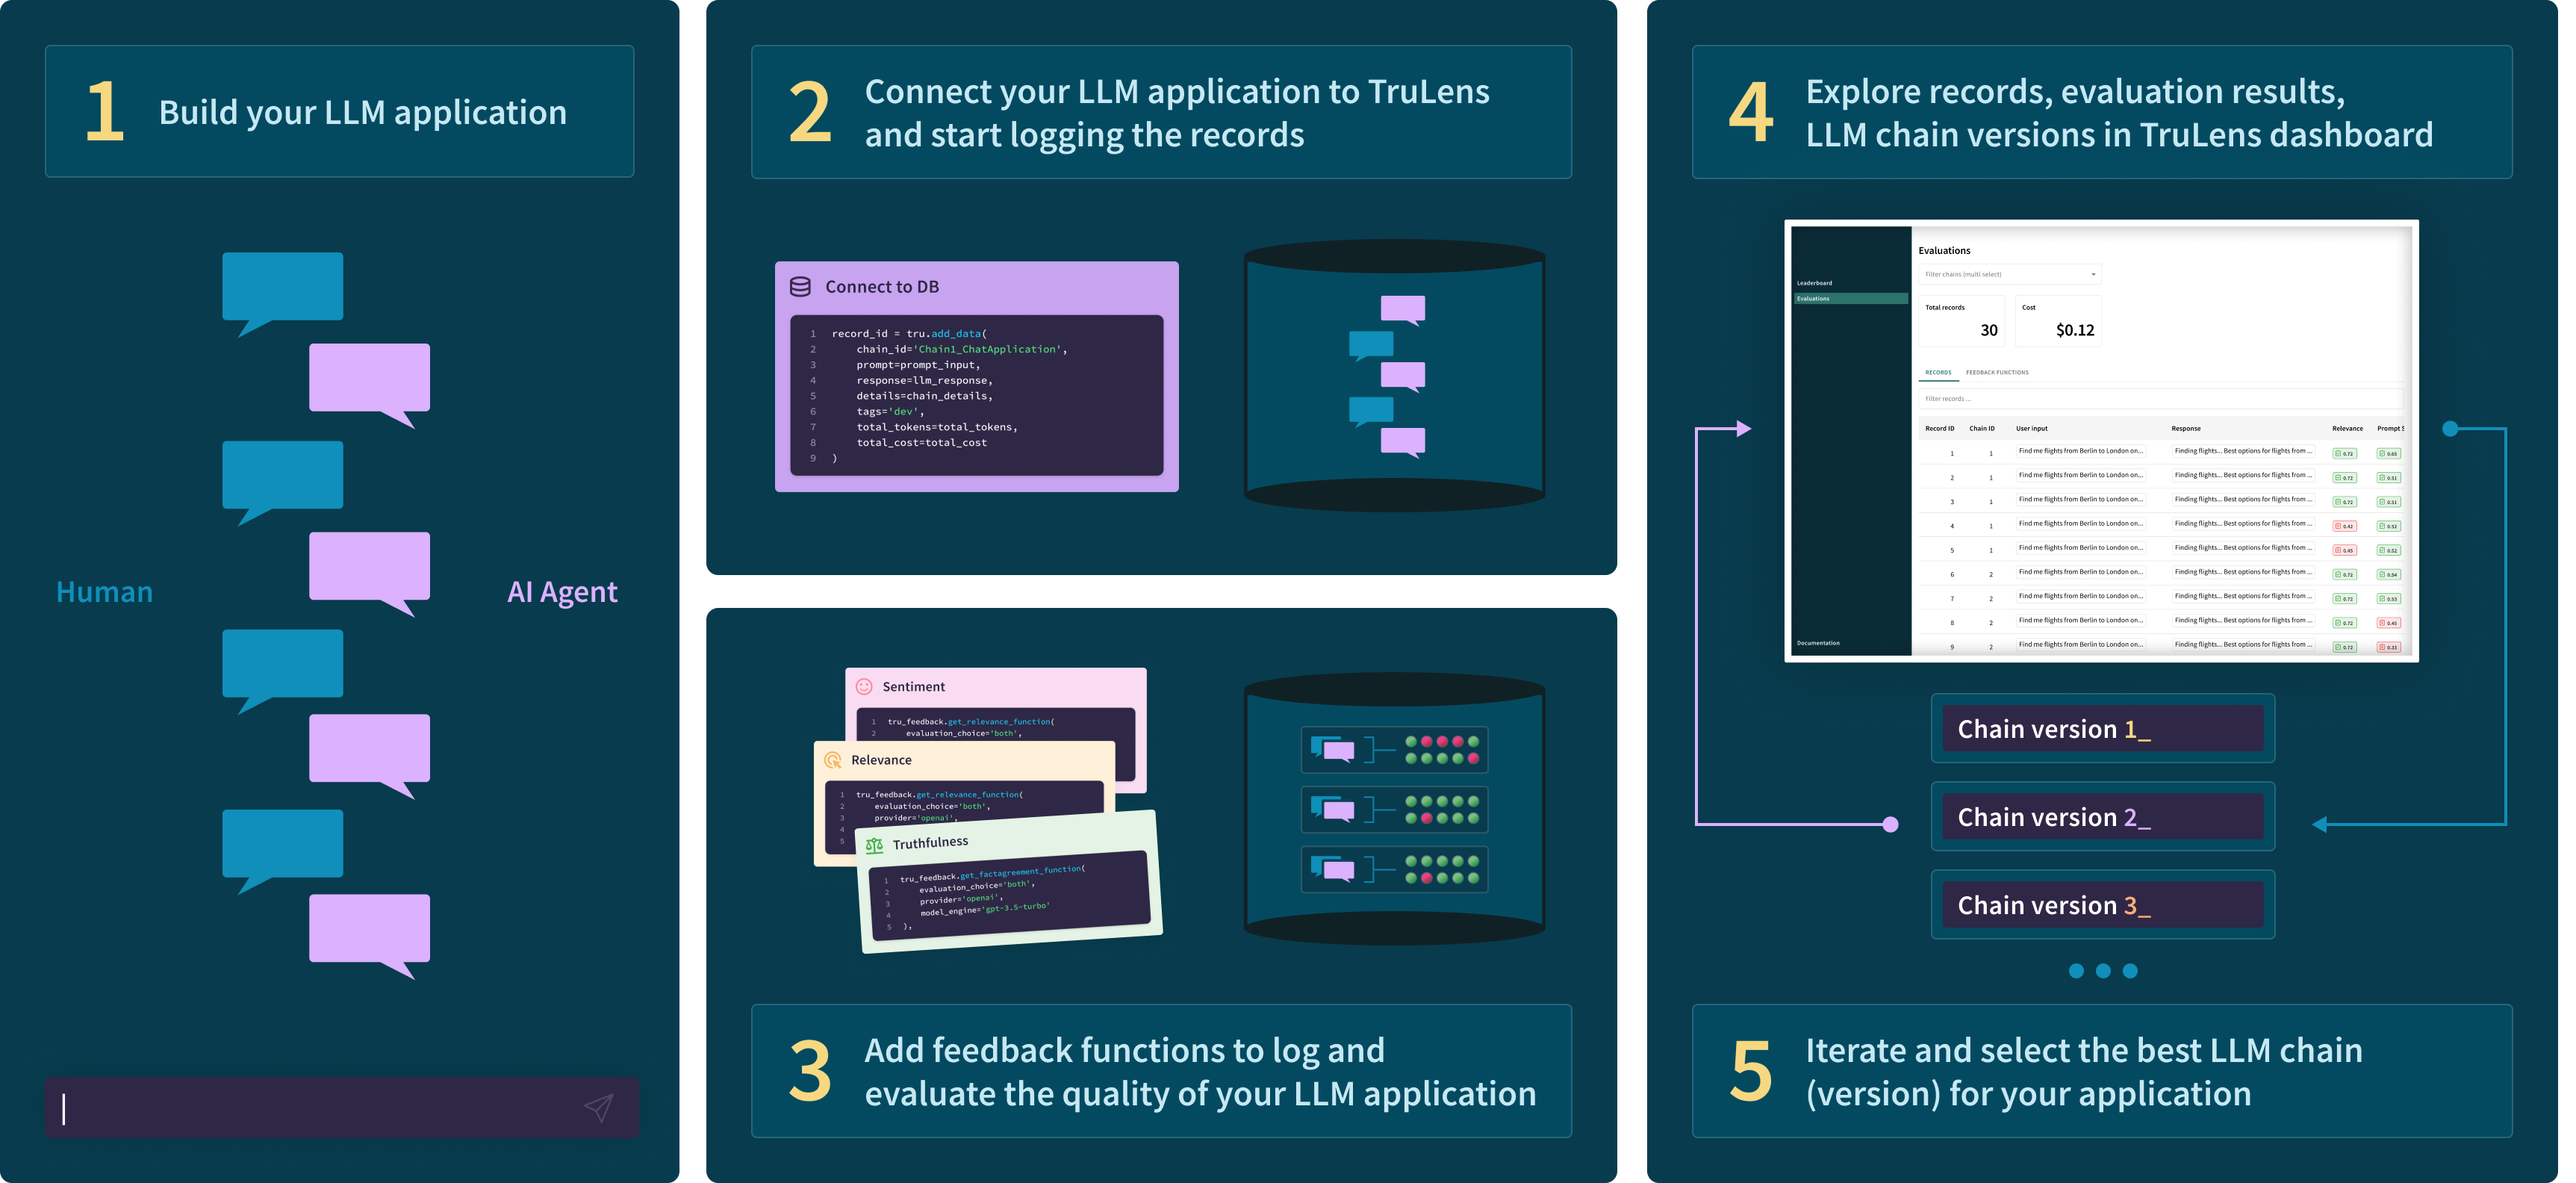
- trulens_eval-0.33.0/trulens_eval/schema/base.py +103 -0
- trulens_eval-0.33.0/trulens_eval/schema/feedback.py +537 -0
- trulens_eval-0.33.0/trulens_eval/schema/record.py +251 -0
- trulens_eval-0.33.0/trulens_eval/schema/types.py +60 -0
- trulens_eval-0.33.0/trulens_eval/streamlit.py +237 -0
- trulens_eval-0.33.0/trulens_eval/tests/benchmark_frameworks/eval_as_recommendation.py +127 -0
- trulens_eval-0.33.0/trulens_eval/tests/test_cases.py +337 -0
- trulens_eval-0.33.0/trulens_eval/tru.py +1267 -0
- trulens_eval-0.33.0/trulens_eval/tru_basic_app.py +170 -0
- trulens_eval-0.33.0/trulens_eval/tru_chain.py +412 -0
- trulens_eval-0.33.0/trulens_eval/tru_custom_app.py +544 -0
- trulens_eval-0.33.0/trulens_eval/tru_llama.py +539 -0
- trulens_eval-0.33.0/trulens_eval/tru_rails.py +454 -0
- trulens_eval-0.33.0/trulens_eval/tru_virtual.py +568 -0
- trulens_eval-0.33.0/trulens_eval/utils/__init__.py +0 -0
- trulens_eval-0.33.0/trulens_eval/utils/asynchro.py +171 -0
- trulens_eval-0.33.0/trulens_eval/utils/command_line.py +6 -0
- trulens_eval-0.33.0/trulens_eval/utils/containers.py +187 -0
- trulens_eval-0.33.0/trulens_eval/utils/display.py +76 -0
- trulens_eval-0.33.0/trulens_eval/utils/generated.py +90 -0
- trulens_eval-0.33.0/trulens_eval/utils/imports.py +684 -0
- trulens_eval-0.33.0/trulens_eval/utils/json.py +392 -0
- trulens_eval-0.33.0/trulens_eval/utils/langchain.py +74 -0
- trulens_eval-0.33.0/trulens_eval/utils/llama.py +110 -0
- trulens_eval-0.33.0/trulens_eval/utils/notebook_utils.py +56 -0
- trulens_eval-0.33.0/trulens_eval/utils/pace.py +134 -0
- trulens_eval-0.33.0/trulens_eval/utils/pyschema.py +724 -0
- trulens_eval-0.33.0/trulens_eval/utils/python.py +838 -0
- trulens_eval-0.33.0/trulens_eval/utils/serial.py +1223 -0
- trulens_eval-0.33.0/trulens_eval/utils/streamlit.py +30 -0
- trulens_eval-0.33.0/trulens_eval/utils/text.py +35 -0
- trulens_eval-0.33.0/trulens_eval/utils/threading.py +211 -0
- trulens_eval-0.33.0/trulens_eval/utils/trulens.py +33 -0
- trulens_eval-0.33.0/trulens_eval/ux/apps.py +29 -0
- trulens_eval-0.33.0/trulens_eval/ux/components.py +279 -0
- trulens_eval-0.33.0/trulens_eval/ux/page_config.py +74 -0
- trulens_eval-0.33.0/trulens_eval/ux/styles.py +143 -0
- trulens_eval-0.33.0/trulens_eval/ux/trulens_logo.svg +44 -0
- trulens_eval-0.33.0/trulens_eval.egg-info/PKG-INFO +98 -0
- trulens_eval-0.33.0/trulens_eval.egg-info/SOURCES.txt +109 -0
- trulens_eval-0.33.0/trulens_eval.egg-info/dependency_links.txt +1 -0
- trulens_eval-0.33.0/trulens_eval.egg-info/entry_points.txt +2 -0
- trulens_eval-0.33.0/trulens_eval.egg-info/requires.txt +28 -0
- trulens_eval-0.33.0/trulens_eval.egg-info/top_level.txt +1 -0
|
@@ -0,0 +1,6 @@
|
|
|
1
|
+
include trulens_eval/LICENSE
|
|
2
|
+
include trulens_eval/requirements.txt
|
|
3
|
+
include trulens_eval/requirements.optional.txt
|
|
4
|
+
include trulens_eval/ux/trulens_logo.svg
|
|
5
|
+
include trulens_eval/database/migrations/alembic.ini
|
|
6
|
+
recursive-include trulens_eval/react_components/record_viewer/dist *
|
|
@@ -0,0 +1,98 @@
|
|
|
1
|
+
Metadata-Version: 2.1
|
|
2
|
+
Name: trulens_eval
|
|
3
|
+
Version: 0.33.0
|
|
4
|
+
Summary: Library to systematically track and evaluate LLM based applications.
|
|
5
|
+
Home-page: https://www.trulens.org
|
|
6
|
+
Author: Truera Inc
|
|
7
|
+
Author-email: all@truera.com
|
|
8
|
+
License: MIT
|
|
9
|
+
Classifier: Programming Language :: Python :: 3
|
|
10
|
+
Classifier: Operating System :: OS Independent
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
13
|
+
Requires-Python: >= 3.8, < 3.13
|
|
14
|
+
Description-Content-Type: text/markdown
|
|
15
|
+
Requires-Dist: numpy>=1.23.5
|
|
16
|
+
Requires-Dist: frozendict>=2.3.8
|
|
17
|
+
Requires-Dist: munch>=3.0.0
|
|
18
|
+
Requires-Dist: dill>=0.3.7
|
|
19
|
+
Requires-Dist: tqdm>=4.66.1
|
|
20
|
+
Requires-Dist: nltk>=3.8.1
|
|
21
|
+
Requires-Dist: requests>=2.31.0
|
|
22
|
+
Requires-Dist: nest-asyncio>=1.5.8
|
|
23
|
+
Requires-Dist: typing_extensions>=4.9.0
|
|
24
|
+
Requires-Dist: psutil>=5.9.8
|
|
25
|
+
Requires-Dist: pip>=24.0
|
|
26
|
+
Requires-Dist: packaging>=23.2
|
|
27
|
+
Requires-Dist: python-dotenv>=1.0.0
|
|
28
|
+
Requires-Dist: pydantic<3,>=2
|
|
29
|
+
Requires-Dist: merkle-json>=1.0.0
|
|
30
|
+
Requires-Dist: langchain>=0.1.14
|
|
31
|
+
Requires-Dist: langchain-core>=0.1.6
|
|
32
|
+
Requires-Dist: langchain-community>=0.0.38
|
|
33
|
+
Requires-Dist: typing-inspect>=0.8.0
|
|
34
|
+
Requires-Dist: millify>=0.1.1
|
|
35
|
+
Requires-Dist: humanize>=4.6.0
|
|
36
|
+
Requires-Dist: streamlit>=1.33.0
|
|
37
|
+
Requires-Dist: streamlit-aggrid==0.3.4
|
|
38
|
+
Requires-Dist: streamlit-extras>=0.4.0
|
|
39
|
+
Requires-Dist: streamlit-pills>=0.3.0
|
|
40
|
+
Requires-Dist: rich>=13.6.0
|
|
41
|
+
Requires-Dist: sqlalchemy>=2.0.19
|
|
42
|
+
Requires-Dist: alembic>=1.11.2
|
|
43
|
+
|
|
44
|
+
<!---
|
|
45
|
+
start of docs/trulens_eval/intro.md
|
|
46
|
+
NOTE: This content is from docs/trulens_eval/intro.md and is merged into
|
|
47
|
+
trulens_eval/README.md . If you are editing README.md, your changes will be overwritten.
|
|
48
|
+
-->
|
|
49
|
+
# Welcome to TruLens-Eval!
|
|
50
|
+
|
|
51
|
+
|
|
52
|
+
|
|
53
|
+
**Don't just vibe-check your llm app!** Systematically evaluate and track your
|
|
54
|
+
LLM experiments with TruLens. As you develop your app including prompts, models,
|
|
55
|
+
retreivers, knowledge sources and more, *TruLens-Eval* is the tool you need to
|
|
56
|
+
understand its performance.
|
|
57
|
+
|
|
58
|
+
Fine-grained, stack-agnostic instrumentation and comprehensive evaluations help
|
|
59
|
+
you to identify failure modes & systematically iterate to improve your
|
|
60
|
+
application.
|
|
61
|
+
|
|
62
|
+
Read more about the core concepts behind TruLens including [Feedback Functions](https://www.trulens.org/trulens_eval/getting_started/core_concepts/feedback_functions/),
|
|
63
|
+
[The RAG Triad](https://www.trulens.org/trulens_eval/getting_started/core_concepts/rag_triad/),
|
|
64
|
+
and [Honest, Harmless and Helpful Evals](https://www.trulens.org/trulens_eval/getting_started/core_concepts/honest_harmless_helpful_evals/).
|
|
65
|
+
|
|
66
|
+
## TruLens in the development workflow
|
|
67
|
+
|
|
68
|
+
Build your first prototype then connect instrumentation and logging with
|
|
69
|
+
TruLens. Decide what feedbacks you need, and specify them with TruLens to run
|
|
70
|
+
alongside your app. Then iterate and compare versions of your app in an
|
|
71
|
+
easy-to-use user interface 👇
|
|
72
|
+
|
|
73
|
+
|
|
75
|
+
|
|
76
|
+
## Installation and Setup
|
|
77
|
+
|
|
78
|
+
Install the trulens-eval pip package from PyPI.
|
|
79
|
+
|
|
80
|
+
```bash
|
|
81
|
+
pip install trulens-eval
|
|
82
|
+
```
|
|
83
|
+
|
|
84
|
+
## Quick Usage
|
|
85
|
+
|
|
86
|
+
Walk through how to instrument and evaluate a RAG built from scratch with
|
|
87
|
+
TruLens.
|
|
88
|
+
|
|
89
|
+
[](https://colab.research.google.com/github/truera/trulens/blob/main/trulens_eval/examples/quickstart/quickstart.ipynb)
|
|
91
|
+
|
|
92
|
+
### 💡 Contributing
|
|
93
|
+
|
|
94
|
+
Interested in contributing? See our [contributing
|
|
95
|
+
guide](https://www.trulens.org/trulens_eval/contributing/) for more details.
|
|
96
|
+
<!---
|
|
97
|
+
end of docs/trulens_eval/intro.md
|
|
98
|
+
-->
|
|
@@ -0,0 +1,55 @@
|
|
|
1
|
+
<!---
|
|
2
|
+
start of docs/trulens_eval/intro.md
|
|
3
|
+
NOTE: This content is from docs/trulens_eval/intro.md and is merged into
|
|
4
|
+
trulens_eval/README.md . If you are editing README.md, your changes will be overwritten.
|
|
5
|
+
-->
|
|
6
|
+
# Welcome to TruLens-Eval!
|
|
7
|
+
|
|
8
|
+

|
|
9
|
+
|
|
10
|
+
**Don't just vibe-check your llm app!** Systematically evaluate and track your
|
|
11
|
+
LLM experiments with TruLens. As you develop your app including prompts, models,
|
|
12
|
+
retreivers, knowledge sources and more, *TruLens-Eval* is the tool you need to
|
|
13
|
+
understand its performance.
|
|
14
|
+
|
|
15
|
+
Fine-grained, stack-agnostic instrumentation and comprehensive evaluations help
|
|
16
|
+
you to identify failure modes & systematically iterate to improve your
|
|
17
|
+
application.
|
|
18
|
+
|
|
19
|
+
Read more about the core concepts behind TruLens including [Feedback Functions](https://www.trulens.org/trulens_eval/getting_started/core_concepts/feedback_functions/),
|
|
20
|
+
[The RAG Triad](https://www.trulens.org/trulens_eval/getting_started/core_concepts/rag_triad/),
|
|
21
|
+
and [Honest, Harmless and Helpful Evals](https://www.trulens.org/trulens_eval/getting_started/core_concepts/honest_harmless_helpful_evals/).
|
|
22
|
+
|
|
23
|
+
## TruLens in the development workflow
|
|
24
|
+
|
|
25
|
+
Build your first prototype then connect instrumentation and logging with
|
|
26
|
+
TruLens. Decide what feedbacks you need, and specify them with TruLens to run
|
|
27
|
+
alongside your app. Then iterate and compare versions of your app in an
|
|
28
|
+
easy-to-use user interface 👇
|
|
29
|
+
|
|
30
|
+

|
|
32
|
+
|
|
33
|
+
## Installation and Setup
|
|
34
|
+
|
|
35
|
+
Install the trulens-eval pip package from PyPI.
|
|
36
|
+
|
|
37
|
+
```bash
|
|
38
|
+
pip install trulens-eval
|
|
39
|
+
```
|
|
40
|
+
|
|
41
|
+
## Quick Usage
|
|
42
|
+
|
|
43
|
+
Walk through how to instrument and evaluate a RAG built from scratch with
|
|
44
|
+
TruLens.
|
|
45
|
+
|
|
46
|
+
[](https://colab.research.google.com/github/truera/trulens/blob/main/trulens_eval/examples/quickstart/quickstart.ipynb)
|
|
48
|
+
|
|
49
|
+
### 💡 Contributing
|
|
50
|
+
|
|
51
|
+
Interested in contributing? See our [contributing
|
|
52
|
+
guide](https://www.trulens.org/trulens_eval/contributing/) for more details.
|
|
53
|
+
<!---
|
|
54
|
+
end of docs/trulens_eval/intro.md
|
|
55
|
+
-->
|
|
@@ -0,0 +1,20 @@
|
|
|
1
|
+
[metadata]
|
|
2
|
+
name = trulens_eval
|
|
3
|
+
version = attr: trulens_eval.__version__
|
|
4
|
+
url = https://www.trulens.org
|
|
5
|
+
license = MIT
|
|
6
|
+
author = Truera Inc
|
|
7
|
+
author_email = all@truera.com
|
|
8
|
+
description = Library to systematically track and evaluate LLM based applications.
|
|
9
|
+
long_description = file: README.md
|
|
10
|
+
long_description_content_type = text/markdown
|
|
11
|
+
classifiers =
|
|
12
|
+
Programming Language :: Python :: 3
|
|
13
|
+
Operating System :: OS Independent
|
|
14
|
+
Development Status :: 3 - Alpha
|
|
15
|
+
License :: OSI Approved :: MIT License
|
|
16
|
+
|
|
17
|
+
[egg_info]
|
|
18
|
+
tag_build =
|
|
19
|
+
tag_date = 0
|
|
20
|
+
|
|
@@ -0,0 +1,72 @@
|
|
|
1
|
+
"""
|
|
2
|
+
# _TruLens-Eval_ build script
|
|
3
|
+
|
|
4
|
+
To build:
|
|
5
|
+
|
|
6
|
+
```bash
|
|
7
|
+
python setup.py bdist_wheel
|
|
8
|
+
```
|
|
9
|
+
|
|
10
|
+
TODO: It is more standard to configure a lot of things we configure
|
|
11
|
+
here in a setup.cfg file instead. It is unclear whether we can do everything
|
|
12
|
+
with a config file though so we may need to keep this script or parts of it.
|
|
13
|
+
"""
|
|
14
|
+
|
|
15
|
+
import os
|
|
16
|
+
|
|
17
|
+
from pip._internal.req import parse_requirements
|
|
18
|
+
from setuptools import find_namespace_packages
|
|
19
|
+
from setuptools import setup
|
|
20
|
+
from setuptools.command.build import build
|
|
21
|
+
from setuptools.logging import logging
|
|
22
|
+
|
|
23
|
+
required_packages = list(
|
|
24
|
+
map(
|
|
25
|
+
lambda pip_req: str(pip_req.requirement),
|
|
26
|
+
parse_requirements("trulens_eval/requirements.txt", session=None)
|
|
27
|
+
)
|
|
28
|
+
)
|
|
29
|
+
optional_packages = list(
|
|
30
|
+
map(
|
|
31
|
+
lambda pip_req: str(pip_req.requirement),
|
|
32
|
+
parse_requirements(
|
|
33
|
+
"trulens_eval/requirements.optional.txt", session=None
|
|
34
|
+
)
|
|
35
|
+
)
|
|
36
|
+
)
|
|
37
|
+
|
|
38
|
+
|
|
39
|
+
class BuildJavascript(build):
|
|
40
|
+
|
|
41
|
+
def run(self):
|
|
42
|
+
"""Custom build command to run npm commands before building the package.
|
|
43
|
+
|
|
44
|
+
This builds the record timeline component for the dashboard.
|
|
45
|
+
"""
|
|
46
|
+
|
|
47
|
+
logging.info("running npm i")
|
|
48
|
+
os.system("npm i --prefix trulens_eval/react_components/record_viewer")
|
|
49
|
+
logging.info("running npm run build")
|
|
50
|
+
os.system(
|
|
51
|
+
"npm run --prefix trulens_eval/react_components/record_viewer build"
|
|
52
|
+
)
|
|
53
|
+
build.run(self)
|
|
54
|
+
|
|
55
|
+
|
|
56
|
+
setup(
|
|
57
|
+
name="trulens_eval",
|
|
58
|
+
cmdclass={
|
|
59
|
+
'build': BuildJavascript,
|
|
60
|
+
},
|
|
61
|
+
include_package_data=True, # includes things specified in MANIFEST.in
|
|
62
|
+
packages=find_namespace_packages(
|
|
63
|
+
include=["trulens_eval", "trulens_eval.*"]
|
|
64
|
+
),
|
|
65
|
+
python_requires='>= 3.8, < 3.13',
|
|
66
|
+
entry_points={
|
|
67
|
+
'console_scripts': [
|
|
68
|
+
'trulens-eval=trulens_eval.utils.command_line:main'
|
|
69
|
+
],
|
|
70
|
+
},
|
|
71
|
+
install_requires=required_packages
|
|
72
|
+
)
|
|
@@ -0,0 +1,172 @@
|
|
|
1
|
+
import os
|
|
2
|
+
|
|
3
|
+
os.environ['PROTOCOL_BUFFERS_PYTHON_IMPLEMENTATION'] = 'python'
|
|
4
|
+
|
|
5
|
+
from langchain.chains import ConversationalRetrievalChain
|
|
6
|
+
from langchain.memory import ConversationSummaryBufferMemory
|
|
7
|
+
import numpy as np
|
|
8
|
+
import streamlit as st
|
|
9
|
+
|
|
10
|
+
from trulens_eval import feedback
|
|
11
|
+
from trulens_eval import Select
|
|
12
|
+
from trulens_eval import tru
|
|
13
|
+
from trulens_eval import tru_chain
|
|
14
|
+
from trulens_eval.feedback import Feedback
|
|
15
|
+
from trulens_eval.keys import check_keys
|
|
16
|
+
from trulens_eval.utils.imports import OptionalImports
|
|
17
|
+
from trulens_eval.utils.imports import REQUIREMENT_PINECONE
|
|
18
|
+
|
|
19
|
+
with OptionalImports(messages=REQUIREMENT_PINECONE) as opt:
|
|
20
|
+
from langchain.embeddings.openai import OpenAIEmbeddings
|
|
21
|
+
import langchain_community
|
|
22
|
+
from langchain_community.callbacks import get_openai_callback
|
|
23
|
+
from langchain_community.llms import OpenAI
|
|
24
|
+
import pinecone
|
|
25
|
+
|
|
26
|
+
opt.assert_installed(mods=[pinecone, langchain_community, OpenAIEmbeddings])
|
|
27
|
+
|
|
28
|
+
check_keys("OPENAI_API_KEY", "PINECONE_API_KEY", "PINECONE_ENV")
|
|
29
|
+
|
|
30
|
+
# Set up GPT-3 model
|
|
31
|
+
model_name = "gpt-3.5-turbo"
|
|
32
|
+
|
|
33
|
+
app_id = "TruBot"
|
|
34
|
+
# app_id = "TruBot_langprompt"
|
|
35
|
+
# app_id = "TruBot_relevance"
|
|
36
|
+
|
|
37
|
+
# Pinecone configuration.
|
|
38
|
+
pinecone_client = pinecone.Pinecone(
|
|
39
|
+
api_key=os.environ.get("PINECONE_API_KEY"), # find at app.pinecone.io
|
|
40
|
+
environment=os.environ.get("PINECONE_ENV") # next to api key in console
|
|
41
|
+
)
|
|
42
|
+
|
|
43
|
+
identity = lambda h: h
|
|
44
|
+
|
|
45
|
+
hugs = feedback.Huggingface()
|
|
46
|
+
openai = feedback.OpenAI()
|
|
47
|
+
|
|
48
|
+
# Language match between question/answer.
|
|
49
|
+
f_lang_match = Feedback(hugs.language_match).on_input_output()
|
|
50
|
+
# By default this will evaluate feedback on main app input and main app output.
|
|
51
|
+
|
|
52
|
+
# Question/answer relevance between overall question and answer.
|
|
53
|
+
f_qa_relevance = Feedback(openai.relevance).on_input_output()
|
|
54
|
+
# By default this will evaluate feedback on main app input and main app output.
|
|
55
|
+
|
|
56
|
+
# Question/statement relevance between question and each context chunk.
|
|
57
|
+
f_qs_relevance = feedback.Feedback(openai.qs_relevance).on_input().on(
|
|
58
|
+
Select.Record.app.combine_docs_chain._call.args.inputs.input_documents[:].
|
|
59
|
+
page_content
|
|
60
|
+
).aggregate(np.min)
|
|
61
|
+
|
|
62
|
+
# First feedback argument is set to main app input, and the second is taken from
|
|
63
|
+
# the context sources as passed to an internal `combine_docs_chain._call`.
|
|
64
|
+
|
|
65
|
+
|
|
66
|
+
# @st.cache_data
|
|
67
|
+
def generate_response(prompt):
|
|
68
|
+
# Embedding needed for Pinecone vector db.
|
|
69
|
+
embedding = OpenAIEmbeddings(model='text-embedding-ada-002') # 1536 dims
|
|
70
|
+
|
|
71
|
+
# TODO: Check updated usage here.
|
|
72
|
+
docsearch = pinecone_client.from_existing_index(
|
|
73
|
+
index_name="llmdemo", embedding=embedding
|
|
74
|
+
)
|
|
75
|
+
retriever = docsearch.as_retriever()
|
|
76
|
+
|
|
77
|
+
# LLM for completing prompts, and other tasks.
|
|
78
|
+
llm = OpenAI(temperature=0, max_tokens=128)
|
|
79
|
+
|
|
80
|
+
# Conversation memory.
|
|
81
|
+
memory = ConversationSummaryBufferMemory(
|
|
82
|
+
max_token_limit=650,
|
|
83
|
+
llm=llm,
|
|
84
|
+
memory_key="chat_history",
|
|
85
|
+
output_key='answer'
|
|
86
|
+
)
|
|
87
|
+
|
|
88
|
+
# Conversational chain puts it all together.
|
|
89
|
+
chain = ConversationalRetrievalChain.from_llm(
|
|
90
|
+
llm=llm,
|
|
91
|
+
retriever=retriever,
|
|
92
|
+
return_source_documents=True,
|
|
93
|
+
memory=memory,
|
|
94
|
+
get_chat_history=identity,
|
|
95
|
+
max_tokens_limit=4096
|
|
96
|
+
)
|
|
97
|
+
|
|
98
|
+
# Language mismatch fix:
|
|
99
|
+
if "langprompt" in app_id:
|
|
100
|
+
chain.combine_docs_chain.llm_chain.prompt.template = \
|
|
101
|
+
"Use the following pieces of CONTEXT to answer the question at the end " \
|
|
102
|
+
"in the same language as the question. If you don't know the answer, " \
|
|
103
|
+
"just say that you don't know, don't try to make up an answer.\n" \
|
|
104
|
+
"\n" \
|
|
105
|
+
"CONTEXT: {context}\n" \
|
|
106
|
+
"\n" \
|
|
107
|
+
"Question: {question}\n" \
|
|
108
|
+
"Helpful Answer: "
|
|
109
|
+
|
|
110
|
+
elif "relevance" in app_id:
|
|
111
|
+
# Contexts fix
|
|
112
|
+
chain.combine_docs_chain.llm_chain.prompt.template = \
|
|
113
|
+
"Use only the relevant contexts to answer the question at the end " \
|
|
114
|
+
". Some pieces of context may not be relevant. If you don't know the answer, " \
|
|
115
|
+
"just say that you don't know, don't try to make up an answer.\n" \
|
|
116
|
+
"\n" \
|
|
117
|
+
"Contexts: \n" \
|
|
118
|
+
"{context}\n" \
|
|
119
|
+
"\n" \
|
|
120
|
+
"Question: {question}\n" \
|
|
121
|
+
"Helpful Answer: "
|
|
122
|
+
|
|
123
|
+
# space is important
|
|
124
|
+
|
|
125
|
+
chain.combine_docs_chain.document_prompt.template = "\tContext: {page_content}"
|
|
126
|
+
|
|
127
|
+
# Trulens instrumentation.
|
|
128
|
+
tc_recorder = tru_chain.TruChain(chain, app_id=app_id)
|
|
129
|
+
with tc_recorder as recording:
|
|
130
|
+
resp = chain(dict(question=prompt))
|
|
131
|
+
tru_record = recording.records[0]
|
|
132
|
+
return tc_recorder, (resp, tru_record)
|
|
133
|
+
|
|
134
|
+
|
|
135
|
+
# Set up Streamlit app
|
|
136
|
+
st.title("TruBot")
|
|
137
|
+
user_input = st.text_input("Ask a question about TruEra")
|
|
138
|
+
|
|
139
|
+
if user_input:
|
|
140
|
+
# Generate GPT-3 response
|
|
141
|
+
prompt_input = user_input
|
|
142
|
+
# add context manager to capture tokens and cost of the chain
|
|
143
|
+
|
|
144
|
+
with get_openai_callback() as cb:
|
|
145
|
+
chain, (response, record) = generate_response(prompt_input)
|
|
146
|
+
total_tokens = cb.total_tokens
|
|
147
|
+
total_cost = cb.total_cost
|
|
148
|
+
|
|
149
|
+
answer = response['answer']
|
|
150
|
+
|
|
151
|
+
# Display response
|
|
152
|
+
st.write(answer)
|
|
153
|
+
|
|
154
|
+
record_id = tru.add_data(
|
|
155
|
+
app_id=app_id,
|
|
156
|
+
prompt=prompt_input,
|
|
157
|
+
response=answer,
|
|
158
|
+
record=record,
|
|
159
|
+
tags='dev',
|
|
160
|
+
total_tokens=total_tokens,
|
|
161
|
+
total_cost=total_cost
|
|
162
|
+
)
|
|
163
|
+
|
|
164
|
+
# Run feedback function and get value
|
|
165
|
+
feedbacks = tru.run_feedback_functions(
|
|
166
|
+
app=app,
|
|
167
|
+
record=record,
|
|
168
|
+
feedback_functions=[f_lang_match, f_qa_relevance, f_qs_relevance]
|
|
169
|
+
)
|
|
170
|
+
|
|
171
|
+
# Add value to database
|
|
172
|
+
tru.add_feedback(record_id, feedbacks)
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2023 Truera, Inc.
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,150 @@
|
|
|
1
|
+
import asyncio
|
|
2
|
+
import json
|
|
3
|
+
import math
|
|
4
|
+
|
|
5
|
+
# https://github.com/jerryjliu/llama_index/issues/7244:
|
|
6
|
+
asyncio.set_event_loop(asyncio.new_event_loop())
|
|
7
|
+
|
|
8
|
+
from millify import millify
|
|
9
|
+
import streamlit as st
|
|
10
|
+
from streamlit_extras.switch_page_button import switch_page
|
|
11
|
+
|
|
12
|
+
from trulens_eval import Tru
|
|
13
|
+
from trulens_eval.database import base as mod_db
|
|
14
|
+
from trulens_eval.database.legacy.migration import MIGRATION_UNKNOWN_STR
|
|
15
|
+
from trulens_eval.utils.streamlit import init_from_args
|
|
16
|
+
from trulens_eval.ux import styles
|
|
17
|
+
from trulens_eval.ux.components import draw_metadata
|
|
18
|
+
from trulens_eval.ux.page_config import set_page_config
|
|
19
|
+
from trulens_eval.ux.styles import CATEGORY
|
|
20
|
+
|
|
21
|
+
if __name__ == "__main__":
|
|
22
|
+
# If not imported, gets args from command line and creates Tru singleton
|
|
23
|
+
init_from_args()
|
|
24
|
+
|
|
25
|
+
|
|
26
|
+
def leaderboard():
|
|
27
|
+
"""Render the leaderboard page."""
|
|
28
|
+
|
|
29
|
+
set_page_config(page_title="Leaderboard")
|
|
30
|
+
|
|
31
|
+
tru = Tru(
|
|
32
|
+
) # get singletone whether this file was imported or executed from command line.
|
|
33
|
+
|
|
34
|
+
lms = tru.db
|
|
35
|
+
|
|
36
|
+
# Set the title and subtitle of the app
|
|
37
|
+
st.title("App Leaderboard")
|
|
38
|
+
st.write(
|
|
39
|
+
"Average feedback values displayed in the range from 0 (worst) to 1 (best)."
|
|
40
|
+
)
|
|
41
|
+
df, feedback_col_names = lms.get_records_and_feedback([])
|
|
42
|
+
feedback_defs = lms.get_feedback_defs()
|
|
43
|
+
feedback_directions = {
|
|
44
|
+
(
|
|
45
|
+
row.feedback_json.get("supplied_name", "") or
|
|
46
|
+
row.feedback_json["implementation"]["name"]
|
|
47
|
+
): row.feedback_json.get("higher_is_better", True)
|
|
48
|
+
for _, row in feedback_defs.iterrows()
|
|
49
|
+
}
|
|
50
|
+
|
|
51
|
+
if df.empty:
|
|
52
|
+
st.write("No records yet...")
|
|
53
|
+
return
|
|
54
|
+
|
|
55
|
+
df = df.sort_values(by="app_id")
|
|
56
|
+
|
|
57
|
+
if df.empty:
|
|
58
|
+
st.write("No records yet...")
|
|
59
|
+
|
|
60
|
+
apps = list(df.app_id.unique())
|
|
61
|
+
st.markdown("""---""")
|
|
62
|
+
|
|
63
|
+
for app in apps:
|
|
64
|
+
app_df = df.loc[df.app_id == app]
|
|
65
|
+
if app_df.empty:
|
|
66
|
+
continue
|
|
67
|
+
app_str = app_df["app_json"].iloc[0]
|
|
68
|
+
app_json = json.loads(app_str)
|
|
69
|
+
metadata = app_json.get("metadata")
|
|
70
|
+
# st.text('Metadata' + str(metadata))
|
|
71
|
+
st.header(app, help=draw_metadata(metadata))
|
|
72
|
+
app_feedback_col_names = [
|
|
73
|
+
col_name for col_name in feedback_col_names
|
|
74
|
+
if not app_df[col_name].isna().all()
|
|
75
|
+
]
|
|
76
|
+
col1, col2, col3, col4, *feedback_cols, col99 = st.columns(
|
|
77
|
+
5 + len(app_feedback_col_names)
|
|
78
|
+
)
|
|
79
|
+
latency_mean = (
|
|
80
|
+
app_df["latency"].
|
|
81
|
+
apply(lambda td: td if td != MIGRATION_UNKNOWN_STR else None).mean()
|
|
82
|
+
)
|
|
83
|
+
|
|
84
|
+
# app_df_feedback = df.loc[df.app_id == app]
|
|
85
|
+
|
|
86
|
+
col1.metric("Records", len(app_df))
|
|
87
|
+
col2.metric(
|
|
88
|
+
"Average Latency (Seconds)",
|
|
89
|
+
(
|
|
90
|
+
f"{millify(round(latency_mean, 5), precision=2)}"
|
|
91
|
+
if not math.isnan(latency_mean) else "nan"
|
|
92
|
+
),
|
|
93
|
+
)
|
|
94
|
+
col3.metric(
|
|
95
|
+
"Total Cost (USD)",
|
|
96
|
+
f"${millify(round(sum(cost for cost in app_df.total_cost if cost is not None), 5), precision = 2)}",
|
|
97
|
+
)
|
|
98
|
+
col4.metric(
|
|
99
|
+
"Total Tokens",
|
|
100
|
+
millify(
|
|
101
|
+
sum(
|
|
102
|
+
tokens for tokens in app_df.total_tokens
|
|
103
|
+
if tokens is not None
|
|
104
|
+
),
|
|
105
|
+
precision=2
|
|
106
|
+
),
|
|
107
|
+
)
|
|
108
|
+
|
|
109
|
+
for i, col_name in enumerate(app_feedback_col_names):
|
|
110
|
+
mean = app_df[col_name].mean()
|
|
111
|
+
|
|
112
|
+
st.write(
|
|
113
|
+
styles.stmetricdelta_hidearrow,
|
|
114
|
+
unsafe_allow_html=True,
|
|
115
|
+
)
|
|
116
|
+
|
|
117
|
+
higher_is_better = feedback_directions.get(col_name, True)
|
|
118
|
+
|
|
119
|
+
if "distance" in col_name:
|
|
120
|
+
feedback_cols[i].metric(
|
|
121
|
+
label=col_name,
|
|
122
|
+
value=f"{round(mean, 2)}",
|
|
123
|
+
delta_color="normal"
|
|
124
|
+
)
|
|
125
|
+
else:
|
|
126
|
+
cat = CATEGORY.of_score(mean, higher_is_better=higher_is_better)
|
|
127
|
+
feedback_cols[i].metric(
|
|
128
|
+
label=col_name,
|
|
129
|
+
value=f"{round(mean, 2)}",
|
|
130
|
+
delta=f"{cat.icon} {cat.adjective}",
|
|
131
|
+
delta_color=(
|
|
132
|
+
"normal" if cat.compare(
|
|
133
|
+
mean, CATEGORY.PASS[cat.direction].threshold
|
|
134
|
+
) else "inverse"
|
|
135
|
+
),
|
|
136
|
+
)
|
|
137
|
+
|
|
138
|
+
with col99:
|
|
139
|
+
if st.button("Select App", key=f"app-selector-{app}"):
|
|
140
|
+
st.session_state.app = app
|
|
141
|
+
switch_page("Evaluations")
|
|
142
|
+
|
|
143
|
+
# with st.expander("Model metadata"):
|
|
144
|
+
# st.markdown(draw_metadata(metadata))
|
|
145
|
+
|
|
146
|
+
st.markdown("""---""")
|
|
147
|
+
|
|
148
|
+
|
|
149
|
+
if __name__ == "__main__":
|
|
150
|
+
leaderboard()
|