trasmuon-pytorch 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- trasmuon_pytorch-0.1.0/.gitignore +11 -0
- trasmuon_pytorch-0.1.0/LICENSE +21 -0
- trasmuon_pytorch-0.1.0/NOTICE.md +56 -0
- trasmuon_pytorch-0.1.0/PKG-INFO +105 -0
- trasmuon_pytorch-0.1.0/README.md +83 -0
- trasmuon_pytorch-0.1.0/assets/trasmuon-algorithm.png +0 -0
- trasmuon_pytorch-0.1.0/pyproject.toml +33 -0
- trasmuon_pytorch-0.1.0/trasmuon/__init__.py +5 -0
- trasmuon_pytorch-0.1.0/trasmuon/newton_schulz_triton.py +374 -0
- trasmuon_pytorch-0.1.0/trasmuon/optimizer.py +783 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
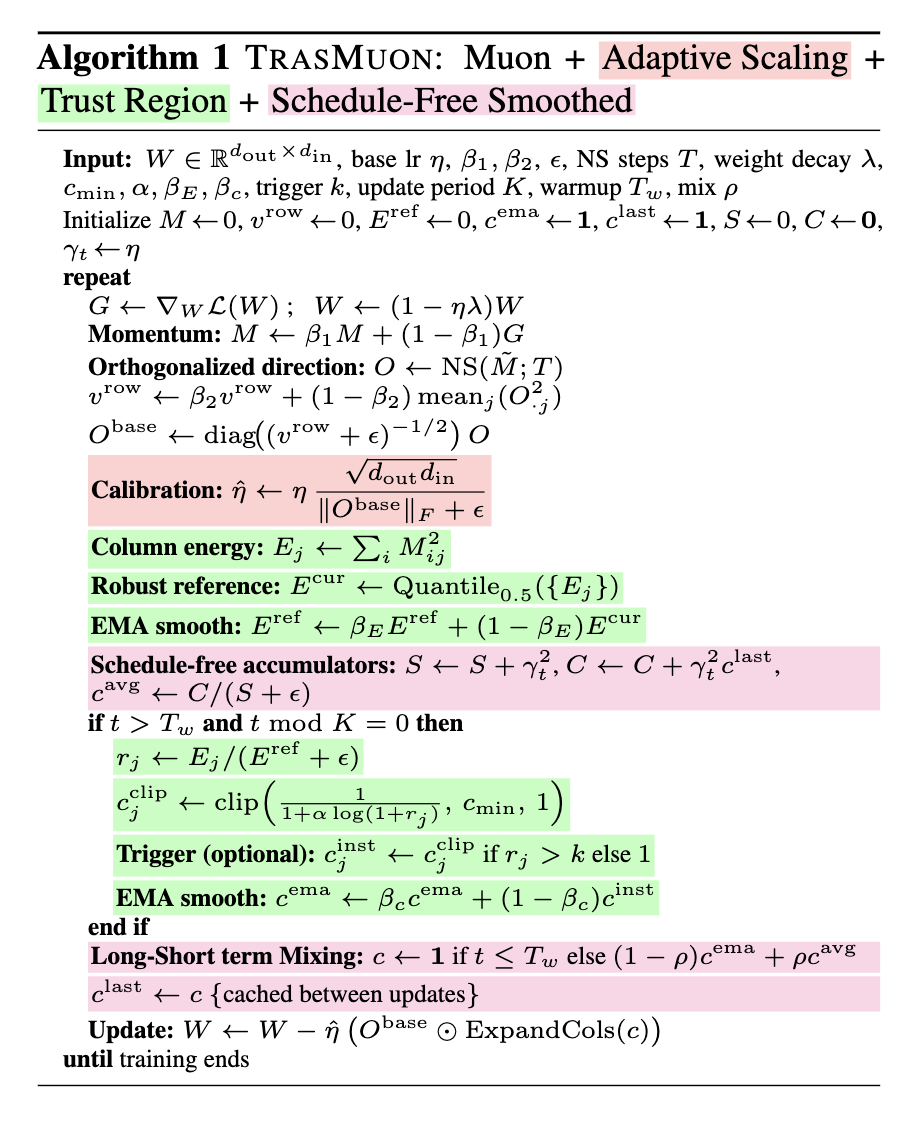
|
3
|
+
Copyright (c) TrasMuon Authors
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE
|
|
@@ -0,0 +1,56 @@
|
|
|
1
|
+
# Notice
|
|
2
|
+
|
|
3
|
+
This repository is a trimmed research code release for the TrasMuon project and paper at <https://arxiv.org/abs/2602.13498>.
|
|
4
|
+
|
|
5
|
+
The repository remains MIT licensed under `LICENSE`. It also retains material adapted from the following upstream sources.
|
|
6
|
+
|
|
7
|
+
## Modded-NanoGPT
|
|
8
|
+
|
|
9
|
+
Source: <https://github.com/KellerJordan/modded-nanogpt>
|
|
10
|
+
|
|
11
|
+
MIT License
|
|
12
|
+
|
|
13
|
+
Copyright (c) 2024 Keller Jordan
|
|
14
|
+
|
|
15
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
16
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
17
|
+
in the Software without restriction, including without limitation the rights
|
|
18
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
19
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
20
|
+
furnished to do so, subject to the following conditions:
|
|
21
|
+
|
|
22
|
+
The above copyright notice and this permission notice shall be included in all
|
|
23
|
+
copies or substantial portions of the Software.
|
|
24
|
+
|
|
25
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
26
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
27
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
28
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
29
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
30
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
31
|
+
SOFTWARE.
|
|
32
|
+
|
|
33
|
+
## Moonlight
|
|
34
|
+
|
|
35
|
+
Source: <https://github.com/MoonshotAI/Moonlight>
|
|
36
|
+
|
|
37
|
+
The MIT License (MIT)
|
|
38
|
+
Copyright (c) 2025 Moonshot AI
|
|
39
|
+
|
|
40
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
41
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
42
|
+
in the Software without restriction, including without limitation the rights
|
|
43
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
44
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
45
|
+
furnished to do so, subject to the following conditions:
|
|
46
|
+
|
|
47
|
+
The above copyright notice and this permission notice shall be included in all
|
|
48
|
+
copies or substantial portions of the Software.
|
|
49
|
+
|
|
50
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
51
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
52
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
53
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
54
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
55
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
56
|
+
SOFTWARE.
|
|
@@ -0,0 +1,105 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: trasmuon-pytorch
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Trust-region adaptive scaling for orthogonalized momentum optimizers in PyTorch
|
|
5
|
+
Project-URL: Homepage, https://github.com/zangjiucheng/TrasMuon
|
|
6
|
+
Project-URL: Source, https://github.com/zangjiucheng/TrasMuon
|
|
7
|
+
Project-URL: Issues, https://github.com/zangjiucheng/TrasMuon/issues
|
|
8
|
+
Project-URL: Paper, https://arxiv.org/abs/2602.13498
|
|
9
|
+
Author: TrasMuon Authors
|
|
10
|
+
License-Expression: MIT
|
|
11
|
+
License-File: LICENSE
|
|
12
|
+
License-File: NOTICE.md
|
|
13
|
+
Keywords: deep-learning,muon,optimizer,pytorch
|
|
14
|
+
Classifier: Development Status :: 3 - Alpha
|
|
15
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
16
|
+
Classifier: Programming Language :: Python :: 3
|
|
17
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
18
|
+
Requires-Python: >=3.10
|
|
19
|
+
Requires-Dist: torch>=2.5.1
|
|
20
|
+
Requires-Dist: triton
|
|
21
|
+
Description-Content-Type: text/markdown
|
|
22
|
+
|
|
23
|
+
# TrasMuon
|
|
24
|
+
|
|
25
|
+
[](https://arxiv.org/abs/2602.13498)
|
|
26
|
+
|
|
27
|
+
Optimizer implementation for **TrasMuon: Trust-Region Adaptive Scaling for Orthogonalized Momentum Optimizers**. TrasMuon combines Muon with adaptive scaling, trust-region column gating, and schedule-free smoothing.
|
|
28
|
+
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
## Installation
|
|
32
|
+
|
|
33
|
+
Requires Python ≥ 3.10, PyTorch ≥ 2.5.1, and Triton. Use Linux with CUDA-enabled PyTorch for GPU execution.
|
|
34
|
+
|
|
35
|
+
Install from GitHub:
|
|
36
|
+
|
|
37
|
+
```bash
|
|
38
|
+
pip install git+https://github.com/zangjiucheng/TrasMuon.git
|
|
39
|
+
```
|
|
40
|
+
|
|
41
|
+
After the first PyPI release, install with:
|
|
42
|
+
|
|
43
|
+
```bash
|
|
44
|
+
pip install trasmuon-pytorch
|
|
45
|
+
```
|
|
46
|
+
|
|
47
|
+
## Usage
|
|
48
|
+
|
|
49
|
+
```python
|
|
50
|
+
from trasmuon import TrasMuon
|
|
51
|
+
|
|
52
|
+
optimizer = TrasMuon(model.parameters(), lr=1e-3, weight_decay=0.01)
|
|
53
|
+
|
|
54
|
+
optimizer.zero_grad(set_to_none=True)
|
|
55
|
+
loss = loss_fn(model(inputs), targets)
|
|
56
|
+
loss.backward()
|
|
57
|
+
optimizer.step()
|
|
58
|
+
```
|
|
59
|
+
|
|
60
|
+
Two-dimensional parameters use TrasMuon; other parameter shapes use the optimizer's AdamW fallback. See [`TrasMuon.__init__`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/optimizer.py) for available options.
|
|
61
|
+
|
|
62
|
+
## Files
|
|
63
|
+
|
|
64
|
+
- [`trasmuon/optimizer.py`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/optimizer.py): optimizer implementation.
|
|
65
|
+
- [`trasmuon/newton_schulz_triton.py`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/newton_schulz_triton.py): required Newton–Schulz kernel dependency.
|
|
66
|
+
- [`trasmuon/__init__.py`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/__init__.py): exports `TrasMuon`.
|
|
67
|
+
|
|
68
|
+
## Publishing
|
|
69
|
+
|
|
70
|
+
Build and validate a release locally:
|
|
71
|
+
|
|
72
|
+
```bash
|
|
73
|
+
python -m pip install build twine
|
|
74
|
+
python -m build
|
|
75
|
+
python -m twine check --strict dist/*
|
|
76
|
+
```
|
|
77
|
+
|
|
78
|
+
For the first release, add a [pending Trusted Publisher](https://pypi.org/manage/account/publishing/) on PyPI with:
|
|
79
|
+
|
|
80
|
+
- Project: `trasmuon-pytorch`
|
|
81
|
+
- Owner / repository: `zangjiucheng` / `TrasMuon`
|
|
82
|
+
- Workflow: `publish.yml`
|
|
83
|
+
- Environment: `pypi`
|
|
84
|
+
|
|
85
|
+
Create the matching `pypi` environment in the GitHub repository settings. Update the version in `pyproject.toml`, then publish a GitHub Release with the matching tag (initially `v0.1.0`). The release workflow builds and validates both distributions, then publishes them through Trusted Publishing. No PyPI API token is needed. See the [PyPI setup guide](https://docs.pypi.org/trusted-publishers/creating-a-project-through-oidc/).
|
|
86
|
+
|
|
87
|
+
## Citation
|
|
88
|
+
|
|
89
|
+
If you use this code, cite the TrasMuon paper:
|
|
90
|
+
|
|
91
|
+
```bibtex
|
|
92
|
+
@misc{cheng2026trasmuon,
|
|
93
|
+
title = {TrasMuon: Trust-Region Adaptive Scaling for Orthogonalized Momentum Optimizers},
|
|
94
|
+
author = {Peng Cheng and Jiucheng Zang and Qingnan Li and Liheng Ma and Yufei Cui and Yingxue Zhang and Boxing Chen and Ming Jian and Wen Tong},
|
|
95
|
+
year = {2026},
|
|
96
|
+
eprint = {2602.13498},
|
|
97
|
+
archivePrefix = {arXiv},
|
|
98
|
+
primaryClass = {cs.LG},
|
|
99
|
+
url = {https://arxiv.org/abs/2602.13498}
|
|
100
|
+
}
|
|
101
|
+
```
|
|
102
|
+
|
|
103
|
+
## License
|
|
104
|
+
|
|
105
|
+
This repository is released under the MIT license. See [LICENSE](https://github.com/zangjiucheng/TrasMuon/blob/main/LICENSE) and [NOTICE.md](https://github.com/zangjiucheng/TrasMuon/blob/main/NOTICE.md).
|
|
@@ -0,0 +1,83 @@
|
|
|
1
|
+
# TrasMuon
|
|
2
|
+
|
|
3
|
+
[](https://arxiv.org/abs/2602.13498)
|
|
4
|
+
|
|
5
|
+
Optimizer implementation for **TrasMuon: Trust-Region Adaptive Scaling for Orthogonalized Momentum Optimizers**. TrasMuon combines Muon with adaptive scaling, trust-region column gating, and schedule-free smoothing.
|
|
6
|
+
|
|
7
|
+

|
|
8
|
+
|
|
9
|
+
## Installation
|
|
10
|
+
|
|
11
|
+
Requires Python ≥ 3.10, PyTorch ≥ 2.5.1, and Triton. Use Linux with CUDA-enabled PyTorch for GPU execution.
|
|
12
|
+
|
|
13
|
+
Install from GitHub:
|
|
14
|
+
|
|
15
|
+
```bash
|
|
16
|
+
pip install git+https://github.com/zangjiucheng/TrasMuon.git
|
|
17
|
+
```
|
|
18
|
+
|
|
19
|
+
After the first PyPI release, install with:
|
|
20
|
+
|
|
21
|
+
```bash
|
|
22
|
+
pip install trasmuon-pytorch
|
|
23
|
+
```
|
|
24
|
+
|
|
25
|
+
## Usage
|
|
26
|
+
|
|
27
|
+
```python
|
|
28
|
+
from trasmuon import TrasMuon
|
|
29
|
+
|
|
30
|
+
optimizer = TrasMuon(model.parameters(), lr=1e-3, weight_decay=0.01)
|
|
31
|
+
|
|
32
|
+
optimizer.zero_grad(set_to_none=True)
|
|
33
|
+
loss = loss_fn(model(inputs), targets)
|
|
34
|
+
loss.backward()
|
|
35
|
+
optimizer.step()
|
|
36
|
+
```
|
|
37
|
+
|
|
38
|
+
Two-dimensional parameters use TrasMuon; other parameter shapes use the optimizer's AdamW fallback. See [`TrasMuon.__init__`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/optimizer.py) for available options.
|
|
39
|
+
|
|
40
|
+
## Files
|
|
41
|
+
|
|
42
|
+
- [`trasmuon/optimizer.py`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/optimizer.py): optimizer implementation.
|
|
43
|
+
- [`trasmuon/newton_schulz_triton.py`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/newton_schulz_triton.py): required Newton–Schulz kernel dependency.
|
|
44
|
+
- [`trasmuon/__init__.py`](https://github.com/zangjiucheng/TrasMuon/blob/main/trasmuon/__init__.py): exports `TrasMuon`.
|
|
45
|
+
|
|
46
|
+
## Publishing
|
|
47
|
+
|
|
48
|
+
Build and validate a release locally:
|
|
49
|
+
|
|
50
|
+
```bash
|
|
51
|
+
python -m pip install build twine
|
|
52
|
+
python -m build
|
|
53
|
+
python -m twine check --strict dist/*
|
|
54
|
+
```
|
|
55
|
+
|
|
56
|
+
For the first release, add a [pending Trusted Publisher](https://pypi.org/manage/account/publishing/) on PyPI with:
|
|
57
|
+
|
|
58
|
+
- Project: `trasmuon-pytorch`
|
|
59
|
+
- Owner / repository: `zangjiucheng` / `TrasMuon`
|
|
60
|
+
- Workflow: `publish.yml`
|
|
61
|
+
- Environment: `pypi`
|
|
62
|
+
|
|
63
|
+
Create the matching `pypi` environment in the GitHub repository settings. Update the version in `pyproject.toml`, then publish a GitHub Release with the matching tag (initially `v0.1.0`). The release workflow builds and validates both distributions, then publishes them through Trusted Publishing. No PyPI API token is needed. See the [PyPI setup guide](https://docs.pypi.org/trusted-publishers/creating-a-project-through-oidc/).
|
|
64
|
+
|
|
65
|
+
## Citation
|
|
66
|
+
|
|
67
|
+
If you use this code, cite the TrasMuon paper:
|
|
68
|
+
|
|
69
|
+
```bibtex
|
|
70
|
+
@misc{cheng2026trasmuon,
|
|
71
|
+
title = {TrasMuon: Trust-Region Adaptive Scaling for Orthogonalized Momentum Optimizers},
|
|
72
|
+
author = {Peng Cheng and Jiucheng Zang and Qingnan Li and Liheng Ma and Yufei Cui and Yingxue Zhang and Boxing Chen and Ming Jian and Wen Tong},
|
|
73
|
+
year = {2026},
|
|
74
|
+
eprint = {2602.13498},
|
|
75
|
+
archivePrefix = {arXiv},
|
|
76
|
+
primaryClass = {cs.LG},
|
|
77
|
+
url = {https://arxiv.org/abs/2602.13498}
|
|
78
|
+
}
|
|
79
|
+
```
|
|
80
|
+
|
|
81
|
+
## License
|
|
82
|
+
|
|
83
|
+
This repository is released under the MIT license. See [LICENSE](https://github.com/zangjiucheng/TrasMuon/blob/main/LICENSE) and [NOTICE.md](https://github.com/zangjiucheng/TrasMuon/blob/main/NOTICE.md).
|
|
Binary file
|
|
@@ -0,0 +1,33 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["hatchling>=1.26"]
|
|
3
|
+
build-backend = "hatchling.build"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "trasmuon-pytorch"
|
|
7
|
+
version = "0.1.0"
|
|
8
|
+
description = "Trust-region adaptive scaling for orthogonalized momentum optimizers in PyTorch"
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
requires-python = ">=3.10"
|
|
11
|
+
license = "MIT"
|
|
12
|
+
license-files = ["LICENSE", "NOTICE.md"]
|
|
13
|
+
authors = [{ name = "TrasMuon Authors" }]
|
|
14
|
+
keywords = ["pytorch", "optimizer", "muon", "deep-learning"]
|
|
15
|
+
classifiers = [
|
|
16
|
+
"Development Status :: 3 - Alpha",
|
|
17
|
+
"Programming Language :: Python :: 3",
|
|
18
|
+
"Operating System :: POSIX :: Linux",
|
|
19
|
+
"Topic :: Scientific/Engineering :: Artificial Intelligence",
|
|
20
|
+
]
|
|
21
|
+
dependencies = ["torch>=2.5.1", "triton"]
|
|
22
|
+
|
|
23
|
+
[project.urls]
|
|
24
|
+
Homepage = "https://github.com/zangjiucheng/TrasMuon"
|
|
25
|
+
Source = "https://github.com/zangjiucheng/TrasMuon"
|
|
26
|
+
Issues = "https://github.com/zangjiucheng/TrasMuon/issues"
|
|
27
|
+
Paper = "https://arxiv.org/abs/2602.13498"
|
|
28
|
+
|
|
29
|
+
[tool.hatch.build.targets.wheel]
|
|
30
|
+
packages = ["trasmuon"]
|
|
31
|
+
|
|
32
|
+
[tool.hatch.build.targets.sdist]
|
|
33
|
+
include = ["/trasmuon", "/assets", "/README.md", "/LICENSE", "/NOTICE.md", "/pyproject.toml"]
|
|
@@ -0,0 +1,374 @@
|
|
|
1
|
+
import torch
|
|
2
|
+
import triton
|
|
3
|
+
import triton.language as tl
|
|
4
|
+
from torch import Tensor
|
|
5
|
+
|
|
6
|
+
|
|
7
|
+
def _get_autotune_configs():
|
|
8
|
+
return [
|
|
9
|
+
triton.Config(
|
|
10
|
+
{
|
|
11
|
+
"BLOCK_SIZE_M": bm,
|
|
12
|
+
"BLOCK_SIZE_N": bn,
|
|
13
|
+
"BLOCK_SIZE_K": bk,
|
|
14
|
+
"GROUP_SIZE_M": 8,
|
|
15
|
+
"LOWER_UPPER": 1,
|
|
16
|
+
},
|
|
17
|
+
num_stages=stages,
|
|
18
|
+
num_warps=warps,
|
|
19
|
+
)
|
|
20
|
+
for bm in [64, 128]
|
|
21
|
+
for bn in [64, 128, 256]
|
|
22
|
+
for bk in [64, 128]
|
|
23
|
+
for stages, warps in [(3, 4), (3, 8), (4, 4)]
|
|
24
|
+
if bm // bn <= 2 and bn // bm <= 2
|
|
25
|
+
]
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
@triton.jit
|
|
29
|
+
def _pid_to_block(
|
|
30
|
+
pid,
|
|
31
|
+
M,
|
|
32
|
+
BLOCK_SIZE_M: tl.constexpr,
|
|
33
|
+
BLOCK_SIZE_N: tl.constexpr,
|
|
34
|
+
GROUP_SIZE_M: tl.constexpr,
|
|
35
|
+
):
|
|
36
|
+
"""
|
|
37
|
+
Helper function to map Triton program ID to (batch, row, col) of the output matrix.
|
|
38
|
+
"""
|
|
39
|
+
# Split output matrix into blocks of size (BLOCK_SIZE_M, BLOCK_SIZE_N)
|
|
40
|
+
num_pid_m = tl.cdiv(M, BLOCK_SIZE_M)
|
|
41
|
+
num_pid_n = tl.cdiv(M, BLOCK_SIZE_N)
|
|
42
|
+
|
|
43
|
+
# Map PID to a single matrix in batch
|
|
44
|
+
batch_idx = pid // (num_pid_m * num_pid_n)
|
|
45
|
+
pid = pid % (num_pid_m * num_pid_n)
|
|
46
|
+
|
|
47
|
+
# Map PID to 2D grid of blocks
|
|
48
|
+
pid_m = pid // num_pid_n
|
|
49
|
+
pid_n = pid % num_pid_n
|
|
50
|
+
pid_m, pid_n = tl.swizzle2d(pid_m, pid_n, num_pid_m, num_pid_n, GROUP_SIZE_M)
|
|
51
|
+
|
|
52
|
+
m_idx = pid_m * BLOCK_SIZE_M
|
|
53
|
+
n_idx = pid_n * BLOCK_SIZE_N
|
|
54
|
+
|
|
55
|
+
return batch_idx, m_idx, n_idx
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
@triton.autotune(
|
|
59
|
+
configs=_get_autotune_configs(),
|
|
60
|
+
key=["M", "K", "a_stride_r", "a_stride_c", "c_stride_r", "c_stride_c"],
|
|
61
|
+
)
|
|
62
|
+
@triton.jit
|
|
63
|
+
def ns_line_1_kernel(
|
|
64
|
+
A_ptr,
|
|
65
|
+
C_ptr,
|
|
66
|
+
M,
|
|
67
|
+
K,
|
|
68
|
+
a_stride_b,
|
|
69
|
+
a_stride_r,
|
|
70
|
+
a_stride_c,
|
|
71
|
+
c_stride_b,
|
|
72
|
+
c_stride_r,
|
|
73
|
+
c_stride_c,
|
|
74
|
+
BLOCK_SIZE_M: tl.constexpr,
|
|
75
|
+
BLOCK_SIZE_N: tl.constexpr,
|
|
76
|
+
BLOCK_SIZE_K: tl.constexpr,
|
|
77
|
+
GROUP_SIZE_M: tl.constexpr,
|
|
78
|
+
LOWER_UPPER: tl.constexpr,
|
|
79
|
+
):
|
|
80
|
+
"""
|
|
81
|
+
Input A has shape (M, K)
|
|
82
|
+
Output C has shape (M, M)
|
|
83
|
+
Compute C = A @ A.T
|
|
84
|
+
"""
|
|
85
|
+
|
|
86
|
+
pid = tl.program_id(axis=0)
|
|
87
|
+
batch_idx, m_idx, n_idx = _pid_to_block(
|
|
88
|
+
pid, M, BLOCK_SIZE_M, BLOCK_SIZE_N, GROUP_SIZE_M
|
|
89
|
+
)
|
|
90
|
+
|
|
91
|
+
# Skip blocks that don't need to be computed
|
|
92
|
+
skip_block_below_diag = (LOWER_UPPER == 0) and (n_idx + BLOCK_SIZE_N <= m_idx)
|
|
93
|
+
skip_block_above_diag = (LOWER_UPPER != 0) and (m_idx + BLOCK_SIZE_M <= n_idx)
|
|
94
|
+
if skip_block_below_diag or skip_block_above_diag:
|
|
95
|
+
return
|
|
96
|
+
|
|
97
|
+
# Index into one matrix of batch
|
|
98
|
+
A_ptr += batch_idx * a_stride_b
|
|
99
|
+
C_ptr += batch_idx * c_stride_b
|
|
100
|
+
|
|
101
|
+
# Create pointer arrays for A and A.T
|
|
102
|
+
offs_m = (m_idx + tl.arange(0, BLOCK_SIZE_M)) % M
|
|
103
|
+
offs_n = (n_idx + tl.arange(0, BLOCK_SIZE_N)) % M
|
|
104
|
+
offs_k = tl.arange(0, BLOCK_SIZE_K)
|
|
105
|
+
a_ptrs = A_ptr + (offs_m[:, None] * a_stride_r + offs_k[None, :] * a_stride_c)
|
|
106
|
+
at_ptrs = A_ptr + (offs_k[:, None] * a_stride_c + offs_n[None, :] * a_stride_r)
|
|
107
|
+
|
|
108
|
+
accumulator = tl.zeros((BLOCK_SIZE_M, BLOCK_SIZE_N), dtype=tl.float32)
|
|
109
|
+
|
|
110
|
+
# Accumulate over blocks of K
|
|
111
|
+
for k in tl.range(0, tl.cdiv(K, BLOCK_SIZE_K)):
|
|
112
|
+
a = tl.load(a_ptrs, mask=offs_k[None, :] < K - k * BLOCK_SIZE_K, other=0.0)
|
|
113
|
+
at = tl.load(at_ptrs, mask=offs_k[:, None] < K - k * BLOCK_SIZE_K, other=0.0)
|
|
114
|
+
accumulator = tl.dot(a, at, accumulator)
|
|
115
|
+
a_ptrs += BLOCK_SIZE_K * a_stride_c
|
|
116
|
+
at_ptrs += BLOCK_SIZE_K * a_stride_c
|
|
117
|
+
|
|
118
|
+
out_dtype = C_ptr.dtype.element_ty
|
|
119
|
+
output = accumulator.to(out_dtype)
|
|
120
|
+
|
|
121
|
+
# Store block of C
|
|
122
|
+
offs_cm = m_idx + tl.arange(0, BLOCK_SIZE_M)
|
|
123
|
+
offs_cn = n_idx + tl.arange(0, BLOCK_SIZE_N)
|
|
124
|
+
c_ptrs = C_ptr + (offs_cm[:, None] * c_stride_r + offs_cn[None, :] * c_stride_c)
|
|
125
|
+
c_mask = (offs_cm[:, None] < M) & (offs_cn[None, :] < M)
|
|
126
|
+
tl.store(c_ptrs, output, mask=c_mask)
|
|
127
|
+
|
|
128
|
+
# Store block of C mirrored across the diagonal
|
|
129
|
+
c_ptrs_t = C_ptr + (offs_cn[:, None] * c_stride_r + offs_cm[None, :] * c_stride_c)
|
|
130
|
+
c_mask_t = (offs_cn[:, None] < M) & (offs_cm[None, :] < M)
|
|
131
|
+
tl.store(c_ptrs_t, output.T, mask=c_mask_t)
|
|
132
|
+
|
|
133
|
+
|
|
134
|
+
def ns_line_1(A: Tensor, *, out: Tensor = None):
|
|
135
|
+
"""
|
|
136
|
+
Launch Triton kernel to compute C = A @ A.T
|
|
137
|
+
"""
|
|
138
|
+
if A.ndim > 3 or A.ndim < 2:
|
|
139
|
+
raise ValueError(f"Input tensor must be 2D or 3D, but got {A.ndim}D tensor.")
|
|
140
|
+
|
|
141
|
+
M, K = A.shape[-2:]
|
|
142
|
+
|
|
143
|
+
if out is None:
|
|
144
|
+
out = torch.empty((*A.shape[:-1], M), device=A.device, dtype=A.dtype)
|
|
145
|
+
assert out.size(-2) == M, "Output matrix has incorrect shape"
|
|
146
|
+
assert out.size(-1) == M, "Output matrix has incorrect shape"
|
|
147
|
+
|
|
148
|
+
batch_size = A.size(0) if A.ndim == 3 else 1
|
|
149
|
+
input_batch_stride = A.stride(0) if A.ndim == 3 else 0
|
|
150
|
+
output_batch_stride = out.stride(0) if out.ndim == 3 else 0
|
|
151
|
+
|
|
152
|
+
grid = lambda meta: (
|
|
153
|
+
batch_size
|
|
154
|
+
* triton.cdiv(M, meta["BLOCK_SIZE_M"])
|
|
155
|
+
* triton.cdiv(M, meta["BLOCK_SIZE_N"]),
|
|
156
|
+
)
|
|
157
|
+
ns_line_1_kernel[grid](
|
|
158
|
+
A_ptr=A,
|
|
159
|
+
C_ptr=out,
|
|
160
|
+
M=M,
|
|
161
|
+
K=K,
|
|
162
|
+
a_stride_b=input_batch_stride,
|
|
163
|
+
a_stride_r=A.stride(-2),
|
|
164
|
+
a_stride_c=A.stride(-1),
|
|
165
|
+
c_stride_b=output_batch_stride,
|
|
166
|
+
c_stride_r=out.stride(-2),
|
|
167
|
+
c_stride_c=out.stride(-1),
|
|
168
|
+
)
|
|
169
|
+
|
|
170
|
+
return out
|
|
171
|
+
|
|
172
|
+
|
|
173
|
+
@triton.autotune(
|
|
174
|
+
configs=_get_autotune_configs(),
|
|
175
|
+
key=["M", "a_stride_r", "a_stride_c", "c_stride_r", "c_stride_c"],
|
|
176
|
+
)
|
|
177
|
+
@triton.jit
|
|
178
|
+
def ns_line_2_kernel(
|
|
179
|
+
A_ptr,
|
|
180
|
+
C_ptr,
|
|
181
|
+
M,
|
|
182
|
+
a_stride_b,
|
|
183
|
+
a_stride_r,
|
|
184
|
+
a_stride_c,
|
|
185
|
+
c_stride_b,
|
|
186
|
+
c_stride_r,
|
|
187
|
+
c_stride_c,
|
|
188
|
+
alpha,
|
|
189
|
+
beta,
|
|
190
|
+
BLOCK_SIZE_M: tl.constexpr,
|
|
191
|
+
BLOCK_SIZE_N: tl.constexpr,
|
|
192
|
+
BLOCK_SIZE_K: tl.constexpr,
|
|
193
|
+
GROUP_SIZE_M: tl.constexpr,
|
|
194
|
+
LOWER_UPPER: tl.constexpr,
|
|
195
|
+
):
|
|
196
|
+
"""
|
|
197
|
+
Input A is square matrix with shape (M, M)
|
|
198
|
+
Output C has shape (M, M)
|
|
199
|
+
Compute C = alpha * A @ A.T + beta * A
|
|
200
|
+
"""
|
|
201
|
+
|
|
202
|
+
pid = tl.program_id(axis=0)
|
|
203
|
+
batch_idx, m_idx, n_idx = _pid_to_block(
|
|
204
|
+
pid, M, BLOCK_SIZE_M, BLOCK_SIZE_N, GROUP_SIZE_M
|
|
205
|
+
)
|
|
206
|
+
|
|
207
|
+
# Skip blocks that don't need to be computed
|
|
208
|
+
skip_block_below_diag = (LOWER_UPPER == 0) and (n_idx + BLOCK_SIZE_N <= m_idx)
|
|
209
|
+
skip_block_above_diag = (LOWER_UPPER != 0) and (m_idx + BLOCK_SIZE_M <= n_idx)
|
|
210
|
+
if skip_block_below_diag or skip_block_above_diag:
|
|
211
|
+
return
|
|
212
|
+
|
|
213
|
+
# Index into one matrix of batch
|
|
214
|
+
A_ptr += batch_idx * a_stride_b
|
|
215
|
+
C_ptr += batch_idx * c_stride_b
|
|
216
|
+
|
|
217
|
+
# Create pointer arrays for A and A.T
|
|
218
|
+
offs_m = (m_idx + tl.arange(0, BLOCK_SIZE_M)) % M
|
|
219
|
+
offs_n = (n_idx + tl.arange(0, BLOCK_SIZE_N)) % M
|
|
220
|
+
offs_k = tl.arange(0, BLOCK_SIZE_K)
|
|
221
|
+
a_ptrs = A_ptr + (offs_m[:, None] * a_stride_r + offs_k[None, :] * a_stride_c)
|
|
222
|
+
at_ptrs = A_ptr + (offs_k[:, None] * a_stride_c + offs_n[None, :] * a_stride_r)
|
|
223
|
+
|
|
224
|
+
accumulator = tl.zeros((BLOCK_SIZE_M, BLOCK_SIZE_N), dtype=tl.float32)
|
|
225
|
+
|
|
226
|
+
# Accumulate over blocks of K
|
|
227
|
+
for k in tl.range(0, tl.cdiv(M, BLOCK_SIZE_K)):
|
|
228
|
+
a = tl.load(a_ptrs, mask=offs_k[None, :] < M - k * BLOCK_SIZE_K, other=0.0)
|
|
229
|
+
at = tl.load(at_ptrs, mask=offs_k[:, None] < M - k * BLOCK_SIZE_K, other=0.0)
|
|
230
|
+
accumulator = tl.dot(a, at, accumulator)
|
|
231
|
+
a_ptrs += BLOCK_SIZE_K * a_stride_c
|
|
232
|
+
at_ptrs += BLOCK_SIZE_K * a_stride_c
|
|
233
|
+
|
|
234
|
+
# Load block of A to add (corresponds to the current block of C)
|
|
235
|
+
offs_am = m_idx + tl.arange(0, BLOCK_SIZE_M)
|
|
236
|
+
offs_an = n_idx + tl.arange(0, BLOCK_SIZE_N)
|
|
237
|
+
a_add_ptrs = A_ptr + (offs_am[:, None] * a_stride_r + offs_an[None, :] * a_stride_c)
|
|
238
|
+
a_add_mask = (offs_am[:, None] < M) & (offs_an[None, :] < M)
|
|
239
|
+
a_add = tl.load(a_add_ptrs, mask=a_add_mask, other=0.0).to(tl.float32)
|
|
240
|
+
|
|
241
|
+
# Apply alpha and beta
|
|
242
|
+
accumulator *= alpha
|
|
243
|
+
accumulator += a_add * beta
|
|
244
|
+
|
|
245
|
+
out_dtype = C_ptr.dtype.element_ty
|
|
246
|
+
output = accumulator.to(out_dtype)
|
|
247
|
+
|
|
248
|
+
# Store block of C
|
|
249
|
+
offs_cm = m_idx + tl.arange(0, BLOCK_SIZE_M)
|
|
250
|
+
offs_cn = n_idx + tl.arange(0, BLOCK_SIZE_N)
|
|
251
|
+
c_ptrs = C_ptr + (offs_cm[:, None] * c_stride_r + offs_cn[None, :] * c_stride_c)
|
|
252
|
+
c_mask = (offs_cm[:, None] < M) & (offs_cn[None, :] < M)
|
|
253
|
+
tl.store(c_ptrs, output, mask=c_mask)
|
|
254
|
+
|
|
255
|
+
# Store block of C mirrored across the diagonal
|
|
256
|
+
c_ptrs_t = C_ptr + (offs_cn[:, None] * c_stride_r + offs_cm[None, :] * c_stride_c)
|
|
257
|
+
c_mask_t = (offs_cn[:, None] < M) & (offs_cm[None, :] < M)
|
|
258
|
+
tl.store(c_ptrs_t, output.T, mask=c_mask_t)
|
|
259
|
+
|
|
260
|
+
|
|
261
|
+
def ns_line_2(A: Tensor, alpha: float, beta: float, *, out: Tensor = None):
|
|
262
|
+
"""
|
|
263
|
+
Launch Triton kernel to compute C = alpha * A @ A.T + beta * A
|
|
264
|
+
"""
|
|
265
|
+
if A.ndim > 3 or A.ndim < 2:
|
|
266
|
+
raise ValueError(f"Input tensor must be 2D or 3D, but got {A.ndim}D tensor.")
|
|
267
|
+
|
|
268
|
+
M, K = A.shape[-2:]
|
|
269
|
+
if M != K:
|
|
270
|
+
raise ValueError(
|
|
271
|
+
f"Input must be symmetric square matrix, but got shape {A.shape}"
|
|
272
|
+
)
|
|
273
|
+
|
|
274
|
+
if out is None:
|
|
275
|
+
out = torch.empty((*A.shape[:-1], M), device=A.device, dtype=A.dtype)
|
|
276
|
+
assert out.size(-2) == M, "Output matrix has incorrect shape"
|
|
277
|
+
assert out.size(-1) == M, "Output matrix has incorrect shape"
|
|
278
|
+
|
|
279
|
+
batch_size = A.size(0) if A.ndim == 3 else 1
|
|
280
|
+
input_batch_stride = A.stride(0) if A.ndim == 3 else 0
|
|
281
|
+
output_batch_stride = out.stride(0) if out.ndim == 3 else 0
|
|
282
|
+
|
|
283
|
+
grid = lambda meta: (
|
|
284
|
+
batch_size
|
|
285
|
+
* triton.cdiv(M, meta["BLOCK_SIZE_M"])
|
|
286
|
+
* triton.cdiv(M, meta["BLOCK_SIZE_N"]),
|
|
287
|
+
)
|
|
288
|
+
ns_line_2_kernel[grid](
|
|
289
|
+
A_ptr=A,
|
|
290
|
+
C_ptr=out,
|
|
291
|
+
M=M,
|
|
292
|
+
a_stride_b=input_batch_stride,
|
|
293
|
+
a_stride_r=A.stride(-2),
|
|
294
|
+
a_stride_c=A.stride(-1),
|
|
295
|
+
c_stride_b=output_batch_stride,
|
|
296
|
+
c_stride_r=out.stride(-2),
|
|
297
|
+
c_stride_c=out.stride(-1),
|
|
298
|
+
alpha=alpha,
|
|
299
|
+
beta=beta,
|
|
300
|
+
)
|
|
301
|
+
|
|
302
|
+
return out
|
|
303
|
+
|
|
304
|
+
|
|
305
|
+
@torch.compile(dynamic=False, fullgraph=True)
|
|
306
|
+
def zeropower_via_newtonschulz5(G: Tensor, epsilon: float = 1e-7):
|
|
307
|
+
"""
|
|
308
|
+
Reference implementation of Newton-Schulz without Triton.
|
|
309
|
+
"""
|
|
310
|
+
# Newton-Schulz constants
|
|
311
|
+
ns_consts = [
|
|
312
|
+
(4.0848, -6.8946, 2.9270),
|
|
313
|
+
(3.9505, -6.3029, 2.6377),
|
|
314
|
+
(3.7418, -5.5913, 2.3037),
|
|
315
|
+
(2.8769, -3.1427, 1.2046),
|
|
316
|
+
(2.8366, -3.0525, 1.2012),
|
|
317
|
+
]
|
|
318
|
+
|
|
319
|
+
X = G.to(dtype=torch.bfloat16)
|
|
320
|
+
if G.size(-2) > G.size(-1):
|
|
321
|
+
X = X.mT
|
|
322
|
+
|
|
323
|
+
# Ensure spectral norm is at most 1
|
|
324
|
+
X = X / (X.norm(dim=(-2, -1), keepdim=True) + epsilon)
|
|
325
|
+
|
|
326
|
+
for a, b, c in ns_consts:
|
|
327
|
+
A = X @ X.mT
|
|
328
|
+
B = b * A + c * (A @ A)
|
|
329
|
+
X = a * X + B @ X
|
|
330
|
+
|
|
331
|
+
if G.size(-2) > G.size(-1):
|
|
332
|
+
X = X.mT
|
|
333
|
+
return X
|
|
334
|
+
|
|
335
|
+
|
|
336
|
+
@torch.compile(dynamic=False, fullgraph=True)
|
|
337
|
+
def newton_schulz_triton(G: Tensor, epsilon: float = 1e-7):
|
|
338
|
+
"""
|
|
339
|
+
Triton implementation of Newton-Schulz iteration
|
|
340
|
+
"""
|
|
341
|
+
# Newton-Schulz constants
|
|
342
|
+
ns_consts = [
|
|
343
|
+
(4.0848, -6.8946, 2.9270),
|
|
344
|
+
(3.9505, -6.3029, 2.6377),
|
|
345
|
+
(3.7418, -5.5913, 2.3037),
|
|
346
|
+
(2.8769, -3.1427, 1.2046),
|
|
347
|
+
(2.8366, -3.0525, 1.2012),
|
|
348
|
+
]
|
|
349
|
+
|
|
350
|
+
X = G.to(dtype=torch.bfloat16)
|
|
351
|
+
if G.size(-2) > G.size(-1):
|
|
352
|
+
X = X.mT
|
|
353
|
+
|
|
354
|
+
# Ensure spectral norm is at most 1
|
|
355
|
+
X = X / (X.norm(dim=(-2, -1), keepdim=True) + epsilon)
|
|
356
|
+
|
|
357
|
+
# Allocate buffers
|
|
358
|
+
X = X.contiguous()
|
|
359
|
+
A = torch.empty((*X.shape[:-1], X.size(-2)), device=X.device, dtype=X.dtype)
|
|
360
|
+
B = torch.empty_like(A)
|
|
361
|
+
C = torch.empty_like(X)
|
|
362
|
+
|
|
363
|
+
ns_line_3 = torch.baddbmm if X.ndim > 2 else torch.addmm
|
|
364
|
+
|
|
365
|
+
# Perform the NS iterations
|
|
366
|
+
for a, b, c in ns_consts:
|
|
367
|
+
ns_line_1(X, out=A) # A = X @ X.mT
|
|
368
|
+
ns_line_2(A, alpha=c, beta=b, out=B) # B = b * A + c * A @ A
|
|
369
|
+
ns_line_3(X, B, X, beta=a, out=C) # C = a * X + B @ X
|
|
370
|
+
X, C = C, X # Swap references to avoid unnecessary copies
|
|
371
|
+
|
|
372
|
+
if G.size(-2) > G.size(-1):
|
|
373
|
+
X = X.mT
|
|
374
|
+
return X
|