tidybatch 1.1.1__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- tidybatch-1.1.1/LICENSE +21 -0
- tidybatch-1.1.1/PKG-INFO +124 -0
- tidybatch-1.1.1/README.md +103 -0
- tidybatch-1.1.1/pyproject.toml +35 -0
- tidybatch-1.1.1/setup.cfg +4 -0
- tidybatch-1.1.1/tests/test_tidybatch.py +175 -0
- tidybatch-1.1.1/tidybatch.egg-info/PKG-INFO +124 -0
- tidybatch-1.1.1/tidybatch.egg-info/SOURCES.txt +10 -0
- tidybatch-1.1.1/tidybatch.egg-info/dependency_links.txt +1 -0
- tidybatch-1.1.1/tidybatch.egg-info/entry_points.txt +2 -0
- tidybatch-1.1.1/tidybatch.egg-info/top_level.txt +1 -0
- tidybatch-1.1.1/tidybatch.py +604 -0
tidybatch-1.1.1/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 TidyBatch
|
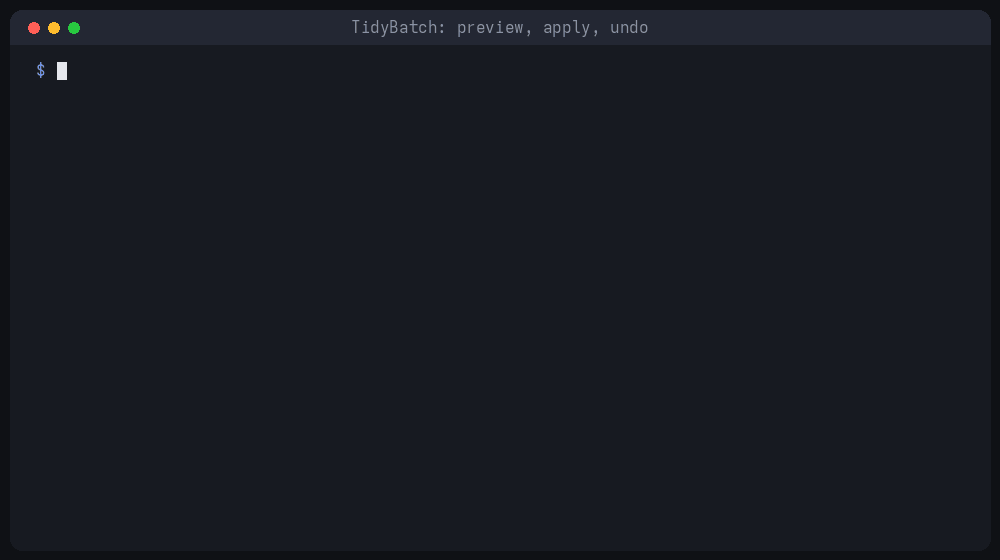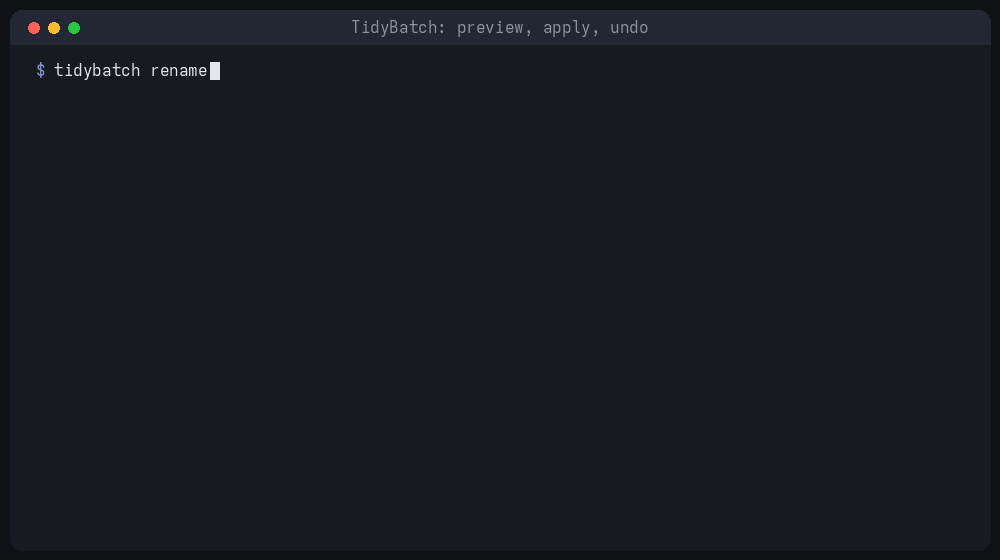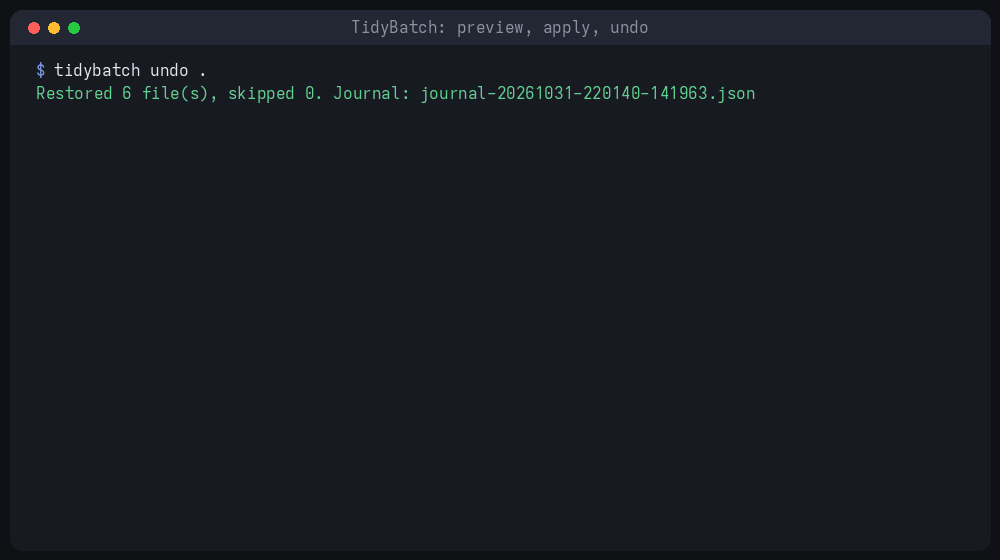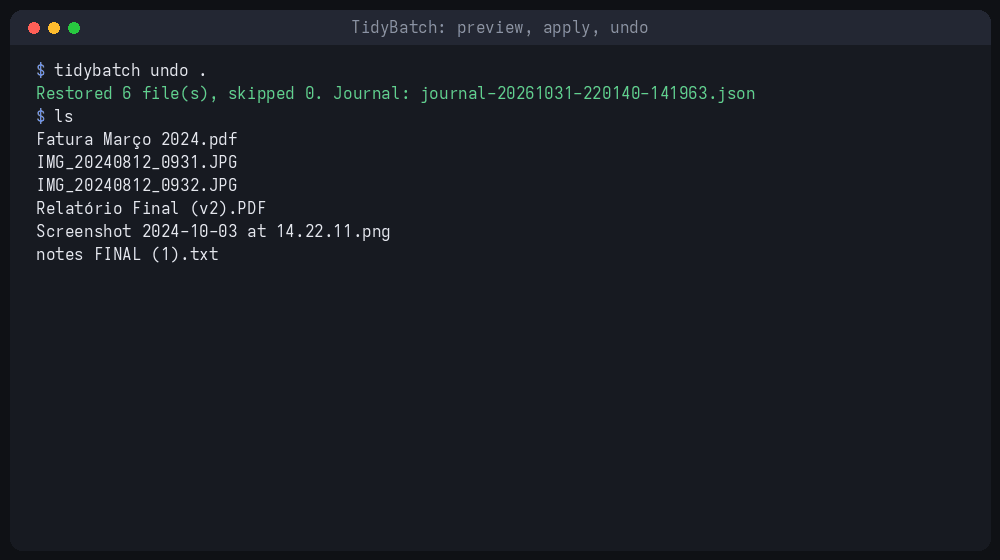
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
tidybatch-1.1.1/PKG-INFO
ADDED
|
@@ -0,0 +1,124 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: tidybatch
|
|
3
|
+
Version: 1.1.1
|
|
4
|
+
Summary: Bulk rename files safely: dry-run preview, collision-proof two-phase renames, one-command undo.
|
|
5
|
+
Author: TidyBatch
|
|
6
|
+
License: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/tidybatch/tidybatch
|
|
8
|
+
Project-URL: Issues, https://github.com/tidybatch/tidybatch/issues
|
|
9
|
+
Project-URL: TidyBatch Pro, https://whop.com/tidybatch/bulk-file-renamer/
|
|
10
|
+
Keywords: rename,bulk-rename,batch-rename,files,cli,undo,dry-run
|
|
11
|
+
Classifier: Environment :: Console
|
|
12
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
13
|
+
Classifier: Operating System :: OS Independent
|
|
14
|
+
Classifier: Programming Language :: Python :: 3
|
|
15
|
+
Classifier: Topic :: System :: Filesystems
|
|
16
|
+
Classifier: Topic :: Utilities
|
|
17
|
+
Requires-Python: >=3.9
|
|
18
|
+
Description-Content-Type: text/markdown
|
|
19
|
+
License-File: LICENSE
|
|
20
|
+
Dynamic: license-file
|
|
21
|
+
|
|
22
|
+
# TidyBatch
|
|
23
|
+
|
|
24
|
+
**Bulk rename files without the fear.** Preview every change, apply it, and undo it with one command.
|
|
25
|
+
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
[](https://github.com/tidybatch/tidybatch/actions/workflows/ci.yml)
|
|
29
|
+
[](https://pypi.org/project/tidybatch/)
|
|
30
|
+

|
|
31
|
+

|
|
32
|
+

|
|
33
|
+
|
|
34
|
+
Most bulk-rename scripts have a silent bug: renumber `1.txt 2.txt 3.txt` → `2.txt 3.txt 4.txt` and the first `mv` overwrites the original `2.txt`. TidyBatch is built around not doing that:
|
|
35
|
+
|
|
36
|
+
- **Dry run by default.** Nothing changes until you add `--apply`.
|
|
37
|
+
- **One-command undo.** Every applied run is journaled; `tidybatch undo <folder>` puts every file back.
|
|
38
|
+
- **Never overwrites.** Two-phase renames make chains and swaps safe; clashes get `_1`, `_2`, …
|
|
39
|
+
- **Case-insensitive collision checks**, because Windows and macOS treat `Photo.JPG` and `photo.jpg` as the same file.
|
|
40
|
+
- **One file, standard library only.** No dependencies: you can read all of it before you trust it with your photos.
|
|
41
|
+
|
|
42
|
+
New to bulk renaming? Read the tested guides at **[tidybatch.github.io/guides](https://tidybatch.github.io/guides/)**: how to rename safely on any OS, how to undo a bulk rename, and how to add dates to file names.
|
|
43
|
+
|
|
44
|
+
## Install
|
|
45
|
+
|
|
46
|
+
```bash
|
|
47
|
+
pipx install tidybatch
|
|
48
|
+
# or: uv tool install tidybatch
|
|
49
|
+
# or: pip install tidybatch
|
|
50
|
+
# or just download tidybatch.py and run: python3 tidybatch.py --help
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
Try it on a folder without installing anything permanent (it's a preview, so nothing changes):
|
|
54
|
+
|
|
55
|
+
```bash
|
|
56
|
+
uvx tidybatch rename ~/Downloads --slug --lower
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
## Recipes
|
|
60
|
+
|
|
61
|
+
```bash
|
|
62
|
+
# Clean names: no accents, spaces or symbols, all lowercase
|
|
63
|
+
tidybatch rename ~/Downloads --slug --lower
|
|
64
|
+
|
|
65
|
+
# Number photos in date order: holiday_001.jpg, holiday_002.jpg, …
|
|
66
|
+
tidybatch rename ./photos -g "*.jpg" --sort date -t "holiday_{n:03}{ext}"
|
|
67
|
+
|
|
68
|
+
# Put the file date in front: 2024-08-12_invoice.pdf
|
|
69
|
+
tidybatch rename ./invoices -t "{date:%Y-%m-%d}_{stem}{ext}"
|
|
70
|
+
|
|
71
|
+
# Name photos by when they were TAKEN (EXIF): 2023-07-14_182205.jpg
|
|
72
|
+
tidybatch rename ./camera -t "{taken:%Y-%m-%d_%H%M%S}{ext}"
|
|
73
|
+
|
|
74
|
+
# Regex with groups: IMG_2024_0001.jpg -> 2024-photo-0001.jpg
|
|
75
|
+
tidybatch rename . --find "IMG_(\d{4})_(\d+)" --replace "\1-photo-\2"
|
|
76
|
+
|
|
77
|
+
# Happy with the preview? Run it for real, then change your mind
|
|
78
|
+
tidybatch rename ~/Downloads --slug --lower --apply
|
|
79
|
+
tidybatch undo ~/Downloads
|
|
80
|
+
```
|
|
81
|
+
|
|
82
|
+
**Template fields:** `{stem}` `{ext}` `{n}` (counter, e.g. `{n:03}`) `{date}` (modification date, e.g. `{date:%Y%m%d}`) `{taken}` (photo **date taken** from EXIF, falling back to `{date}`) `{today}` `{parent}` `{size_kb}`
|
|
83
|
+
|
|
84
|
+
**Options:** `-r` sub-folders · `-g "*.jpg"` filter · `--hidden` include hidden files · `--sort name|date|taken|size` · `--start N` · `--apply`
|
|
85
|
+
|
|
86
|
+
**Photo dates:** `{taken}` reads EXIF with the standard library only, with no Pillow or exiftool needed. Every CI run checks it against ExifTool on ExifTool's own sample images (JPEG, HEIC, TIFF, DNG, CR2, CR3, NEF, RW2, RAF: same date for every file, [dev/verify_exif.py](https://github.com/tidybatch/tidybatch/blob/main/dev/verify_exif.py)) and feeds it 20,000 corrupted files, which must never crash or hang it ([dev/fuzz_exif.py](https://github.com/tidybatch/tidybatch/blob/main/dev/fuzz_exif.py)). Dates stored only in XMP/IPTC aren't read; those files fall back to the modification date.
|
|
87
|
+
|
|
88
|
+
## How it stays safe
|
|
89
|
+
|
|
90
|
+
1. **Plan:** compute every new name without touching the disk, then resolve collisions. A destination is free only if nobody else claimed it *and* whatever is there now is itself moving away.
|
|
91
|
+
2. **Phase 1:** every file moves to a temporary name in the same folder.
|
|
92
|
+
3. **Phase 2:** every temporary file moves to its final name, refusing to overwrite anything that appeared in the meantime.
|
|
93
|
+
4. **Journal:** `<folder>/.tidybatch/journal-*.json` records each completed move, even if the run is interrupted, so `undo` can replay it backwards.
|
|
94
|
+
|
|
95
|
+
## How it's made
|
|
96
|
+
|
|
97
|
+
Most of the code was written with an AI coding agent. The behaviour that protects your files (two-phase moves, collision checks, undo) is pinned down by the test suite, which runs on Linux, macOS and Windows on every push.
|
|
98
|
+
|
|
99
|
+
## TidyBatch Pro
|
|
100
|
+
|
|
101
|
+
This repository is **TidyBatch Core** (rename + undo), free and MIT-licensed. **[TidyBatch Pro](https://whop.com/tidybatch/bulk-file-renamer/?utm_source=github&utm_campaign=tidybatch)** adds:
|
|
102
|
+
|
|
103
|
+
- `organize`: sort a folder into Images / Documents / Videos…, by year/month (modified **or photo date taken**), or by extension
|
|
104
|
+
- `dedupe`: find exact duplicates by content (SHA-256), keep the oldest, move the rest aside (never deleted)
|
|
105
|
+
- ready-to-run apps for **Windows and Linux** (no Python needed), plus free 1.x updates
|
|
106
|
+
|
|
107
|
+
Buying Pro also funds the free version. Thank you!
|
|
108
|
+
|
|
109
|
+
## Contributing
|
|
110
|
+
|
|
111
|
+
Bug reports with a reproducible folder layout are gold. Run the tests with:
|
|
112
|
+
|
|
113
|
+
```bash
|
|
114
|
+
python -m unittest discover -s tests
|
|
115
|
+
|
|
116
|
+
# photo-date checks (needs perl and an ExifTool checkout)
|
|
117
|
+
git clone --depth 1 https://github.com/exiftool/exiftool /tmp/exiftool
|
|
118
|
+
python dev/verify_exif.py /tmp/exiftool
|
|
119
|
+
python dev/fuzz_exif.py /tmp/exiftool
|
|
120
|
+
```
|
|
121
|
+
|
|
122
|
+
## License
|
|
123
|
+
|
|
124
|
+
[MIT](https://github.com/tidybatch/tidybatch/blob/main/LICENSE)
|
|
@@ -0,0 +1,103 @@
|
|
|
1
|
+
# TidyBatch
|
|
2
|
+
|
|
3
|
+
**Bulk rename files without the fear.** Preview every change, apply it, and undo it with one command.
|
|
4
|
+
|
|
5
|
+

|
|
6
|
+
|
|
7
|
+
[](https://github.com/tidybatch/tidybatch/actions/workflows/ci.yml)
|
|
8
|
+
[](https://pypi.org/project/tidybatch/)
|
|
9
|
+

|
|
10
|
+

|
|
11
|
+

|
|
12
|
+
|
|
13
|
+
Most bulk-rename scripts have a silent bug: renumber `1.txt 2.txt 3.txt` → `2.txt 3.txt 4.txt` and the first `mv` overwrites the original `2.txt`. TidyBatch is built around not doing that:
|
|
14
|
+
|
|
15
|
+
- **Dry run by default.** Nothing changes until you add `--apply`.
|
|
16
|
+
- **One-command undo.** Every applied run is journaled; `tidybatch undo <folder>` puts every file back.
|
|
17
|
+
- **Never overwrites.** Two-phase renames make chains and swaps safe; clashes get `_1`, `_2`, …
|
|
18
|
+
- **Case-insensitive collision checks**, because Windows and macOS treat `Photo.JPG` and `photo.jpg` as the same file.
|
|
19
|
+
- **One file, standard library only.** No dependencies: you can read all of it before you trust it with your photos.
|
|
20
|
+
|
|
21
|
+
New to bulk renaming? Read the tested guides at **[tidybatch.github.io/guides](https://tidybatch.github.io/guides/)**: how to rename safely on any OS, how to undo a bulk rename, and how to add dates to file names.
|
|
22
|
+
|
|
23
|
+
## Install
|
|
24
|
+
|
|
25
|
+
```bash
|
|
26
|
+
pipx install tidybatch
|
|
27
|
+
# or: uv tool install tidybatch
|
|
28
|
+
# or: pip install tidybatch
|
|
29
|
+
# or just download tidybatch.py and run: python3 tidybatch.py --help
|
|
30
|
+
```
|
|
31
|
+
|
|
32
|
+
Try it on a folder without installing anything permanent (it's a preview, so nothing changes):
|
|
33
|
+
|
|
34
|
+
```bash
|
|
35
|
+
uvx tidybatch rename ~/Downloads --slug --lower
|
|
36
|
+
```
|
|
37
|
+
|
|
38
|
+
## Recipes
|
|
39
|
+
|
|
40
|
+
```bash
|
|
41
|
+
# Clean names: no accents, spaces or symbols, all lowercase
|
|
42
|
+
tidybatch rename ~/Downloads --slug --lower
|
|
43
|
+
|
|
44
|
+
# Number photos in date order: holiday_001.jpg, holiday_002.jpg, …
|
|
45
|
+
tidybatch rename ./photos -g "*.jpg" --sort date -t "holiday_{n:03}{ext}"
|
|
46
|
+
|
|
47
|
+
# Put the file date in front: 2024-08-12_invoice.pdf
|
|
48
|
+
tidybatch rename ./invoices -t "{date:%Y-%m-%d}_{stem}{ext}"
|
|
49
|
+
|
|
50
|
+
# Name photos by when they were TAKEN (EXIF): 2023-07-14_182205.jpg
|
|
51
|
+
tidybatch rename ./camera -t "{taken:%Y-%m-%d_%H%M%S}{ext}"
|
|
52
|
+
|
|
53
|
+
# Regex with groups: IMG_2024_0001.jpg -> 2024-photo-0001.jpg
|
|
54
|
+
tidybatch rename . --find "IMG_(\d{4})_(\d+)" --replace "\1-photo-\2"
|
|
55
|
+
|
|
56
|
+
# Happy with the preview? Run it for real, then change your mind
|
|
57
|
+
tidybatch rename ~/Downloads --slug --lower --apply
|
|
58
|
+
tidybatch undo ~/Downloads
|
|
59
|
+
```
|
|
60
|
+
|
|
61
|
+
**Template fields:** `{stem}` `{ext}` `{n}` (counter, e.g. `{n:03}`) `{date}` (modification date, e.g. `{date:%Y%m%d}`) `{taken}` (photo **date taken** from EXIF, falling back to `{date}`) `{today}` `{parent}` `{size_kb}`
|
|
62
|
+
|
|
63
|
+
**Options:** `-r` sub-folders · `-g "*.jpg"` filter · `--hidden` include hidden files · `--sort name|date|taken|size` · `--start N` · `--apply`
|
|
64
|
+
|
|
65
|
+
**Photo dates:** `{taken}` reads EXIF with the standard library only, with no Pillow or exiftool needed. Every CI run checks it against ExifTool on ExifTool's own sample images (JPEG, HEIC, TIFF, DNG, CR2, CR3, NEF, RW2, RAF: same date for every file, [dev/verify_exif.py](https://github.com/tidybatch/tidybatch/blob/main/dev/verify_exif.py)) and feeds it 20,000 corrupted files, which must never crash or hang it ([dev/fuzz_exif.py](https://github.com/tidybatch/tidybatch/blob/main/dev/fuzz_exif.py)). Dates stored only in XMP/IPTC aren't read; those files fall back to the modification date.
|
|
66
|
+
|
|
67
|
+
## How it stays safe
|
|
68
|
+
|
|
69
|
+
1. **Plan:** compute every new name without touching the disk, then resolve collisions. A destination is free only if nobody else claimed it *and* whatever is there now is itself moving away.
|
|
70
|
+
2. **Phase 1:** every file moves to a temporary name in the same folder.
|
|
71
|
+
3. **Phase 2:** every temporary file moves to its final name, refusing to overwrite anything that appeared in the meantime.
|
|
72
|
+
4. **Journal:** `<folder>/.tidybatch/journal-*.json` records each completed move, even if the run is interrupted, so `undo` can replay it backwards.
|
|
73
|
+
|
|
74
|
+
## How it's made
|
|
75
|
+
|
|
76
|
+
Most of the code was written with an AI coding agent. The behaviour that protects your files (two-phase moves, collision checks, undo) is pinned down by the test suite, which runs on Linux, macOS and Windows on every push.
|
|
77
|
+
|
|
78
|
+
## TidyBatch Pro
|
|
79
|
+
|
|
80
|
+
This repository is **TidyBatch Core** (rename + undo), free and MIT-licensed. **[TidyBatch Pro](https://whop.com/tidybatch/bulk-file-renamer/?utm_source=github&utm_campaign=tidybatch)** adds:
|
|
81
|
+
|
|
82
|
+
- `organize`: sort a folder into Images / Documents / Videos…, by year/month (modified **or photo date taken**), or by extension
|
|
83
|
+
- `dedupe`: find exact duplicates by content (SHA-256), keep the oldest, move the rest aside (never deleted)
|
|
84
|
+
- ready-to-run apps for **Windows and Linux** (no Python needed), plus free 1.x updates
|
|
85
|
+
|
|
86
|
+
Buying Pro also funds the free version. Thank you!
|
|
87
|
+
|
|
88
|
+
## Contributing
|
|
89
|
+
|
|
90
|
+
Bug reports with a reproducible folder layout are gold. Run the tests with:
|
|
91
|
+
|
|
92
|
+
```bash
|
|
93
|
+
python -m unittest discover -s tests
|
|
94
|
+
|
|
95
|
+
# photo-date checks (needs perl and an ExifTool checkout)
|
|
96
|
+
git clone --depth 1 https://github.com/exiftool/exiftool /tmp/exiftool
|
|
97
|
+
python dev/verify_exif.py /tmp/exiftool
|
|
98
|
+
python dev/fuzz_exif.py /tmp/exiftool
|
|
99
|
+
```
|
|
100
|
+
|
|
101
|
+
## License
|
|
102
|
+
|
|
103
|
+
[MIT](https://github.com/tidybatch/tidybatch/blob/main/LICENSE)
|
|
@@ -0,0 +1,35 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["setuptools>=64"]
|
|
3
|
+
build-backend = "setuptools.build_meta"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "tidybatch"
|
|
7
|
+
dynamic = ["version"]
|
|
8
|
+
description = "Bulk rename files safely: dry-run preview, collision-proof two-phase renames, one-command undo."
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
license = { text = "MIT" }
|
|
11
|
+
requires-python = ">=3.9"
|
|
12
|
+
authors = [{ name = "TidyBatch" }]
|
|
13
|
+
keywords = ["rename", "bulk-rename", "batch-rename", "files", "cli", "undo", "dry-run"]
|
|
14
|
+
classifiers = [
|
|
15
|
+
"Environment :: Console",
|
|
16
|
+
"License :: OSI Approved :: MIT License",
|
|
17
|
+
"Operating System :: OS Independent",
|
|
18
|
+
"Programming Language :: Python :: 3",
|
|
19
|
+
"Topic :: System :: Filesystems",
|
|
20
|
+
"Topic :: Utilities",
|
|
21
|
+
]
|
|
22
|
+
|
|
23
|
+
[project.urls]
|
|
24
|
+
Homepage = "https://github.com/tidybatch/tidybatch"
|
|
25
|
+
Issues = "https://github.com/tidybatch/tidybatch/issues"
|
|
26
|
+
"TidyBatch Pro" = "https://whop.com/tidybatch/bulk-file-renamer/"
|
|
27
|
+
|
|
28
|
+
[project.scripts]
|
|
29
|
+
tidybatch = "tidybatch:main"
|
|
30
|
+
|
|
31
|
+
[tool.setuptools]
|
|
32
|
+
py-modules = ["tidybatch"]
|
|
33
|
+
|
|
34
|
+
[tool.setuptools.dynamic]
|
|
35
|
+
version = { attr = "tidybatch.__version__" }
|
|
@@ -0,0 +1,175 @@
|
|
|
1
|
+
"""Run with: python -m unittest discover -s tests (from the product folder)."""
|
|
2
|
+
from __future__ import annotations
|
|
3
|
+
|
|
4
|
+
import io
|
|
5
|
+
import os
|
|
6
|
+
import sys
|
|
7
|
+
import tempfile
|
|
8
|
+
import time
|
|
9
|
+
import unittest
|
|
10
|
+
from contextlib import redirect_stderr, redirect_stdout
|
|
11
|
+
from pathlib import Path
|
|
12
|
+
|
|
13
|
+
sys.path.insert(0, str(Path(__file__).resolve().parents[1]))
|
|
14
|
+
import tidybatch # noqa: E402
|
|
15
|
+
|
|
16
|
+
|
|
17
|
+
def run(*argv: str) -> int:
|
|
18
|
+
with redirect_stdout(io.StringIO()), redirect_stderr(io.StringIO()):
|
|
19
|
+
return tidybatch.main(list(argv))
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
def jpeg_with_exif_date(when: str) -> bytes:
|
|
23
|
+
"""Smallest JPEG-ish file whose APP1 segment carries EXIF DateTimeOriginal."""
|
|
24
|
+
import struct
|
|
25
|
+
tiff = b"II*\x00" + struct.pack("<I", 8)
|
|
26
|
+
tiff += struct.pack("<H", 1) + struct.pack("<HHII", 0x8769, 4, 1, 26) + struct.pack("<I", 0)
|
|
27
|
+
tiff += struct.pack("<H", 1) + struct.pack("<HHII", 0x9003, 2, 20, 44) + struct.pack("<I", 0)
|
|
28
|
+
tiff += when.encode("ascii") + b"\x00"
|
|
29
|
+
payload = b"Exif\x00\x00" + tiff
|
|
30
|
+
return b"\xff\xd8" + b"\xff\xe1" + struct.pack(">H", len(payload) + 2) + payload + b"\xff\xd9"
|
|
31
|
+
|
|
32
|
+
|
|
33
|
+
class TidyBatchTest(unittest.TestCase):
|
|
34
|
+
def setUp(self):
|
|
35
|
+
self._tmp = tempfile.TemporaryDirectory()
|
|
36
|
+
self.root = Path(self._tmp.name)
|
|
37
|
+
|
|
38
|
+
def tearDown(self):
|
|
39
|
+
self._tmp.cleanup()
|
|
40
|
+
|
|
41
|
+
def make(self, rel: str, content: str = "x", age: float = 0) -> Path:
|
|
42
|
+
p = self.root / rel
|
|
43
|
+
p.parent.mkdir(parents=True, exist_ok=True)
|
|
44
|
+
p.write_text(content)
|
|
45
|
+
if age:
|
|
46
|
+
t = time.time() - age
|
|
47
|
+
os.utime(p, (t, t))
|
|
48
|
+
return p
|
|
49
|
+
|
|
50
|
+
def names(self, folder: Path | None = None) -> set[str]:
|
|
51
|
+
folder = folder or self.root
|
|
52
|
+
return {str(p.relative_to(folder)) for p in folder.rglob("*")
|
|
53
|
+
if p.is_file() and tidybatch.JOURNAL_DIR not in p.parts}
|
|
54
|
+
|
|
55
|
+
def make_photo(self, rel: str, taken: str, age: float = 0) -> Path:
|
|
56
|
+
p = self.root / rel
|
|
57
|
+
p.write_bytes(jpeg_with_exif_date(taken))
|
|
58
|
+
if age:
|
|
59
|
+
t = time.time() - age
|
|
60
|
+
os.utime(p, (t, t))
|
|
61
|
+
return p
|
|
62
|
+
|
|
63
|
+
def test_taken_date_reads_exif(self):
|
|
64
|
+
p = self.make_photo("a.jpg", "2021:05:06 07:08:09")
|
|
65
|
+
self.assertEqual(str(tidybatch.taken_date(p)), "2021-05-06 07:08:09")
|
|
66
|
+
|
|
67
|
+
def test_taken_template_uses_exif_not_mtime(self):
|
|
68
|
+
self.make_photo("IMG_1.jpg", "2019:12:31 23:59:59")
|
|
69
|
+
run("rename", str(self.root), "-t", "{taken:%Y-%m-%d_%H%M%S}{ext}", "--apply")
|
|
70
|
+
self.assertEqual(self.names(), {"2019-12-31_235959.jpg"})
|
|
71
|
+
|
|
72
|
+
def test_taken_falls_back_to_mtime(self):
|
|
73
|
+
self.make("notes.txt")
|
|
74
|
+
p = self.root / "notes.txt"
|
|
75
|
+
t = time.mktime((2020, 2, 3, 12, 0, 0, 0, 0, -1)); os.utime(p, (t, t))
|
|
76
|
+
run("rename", str(self.root), "-t", "{taken:%Y-%m-%d}_{stem}{ext}", "--apply")
|
|
77
|
+
self.assertEqual(self.names(), {"2020-02-03_notes.txt"})
|
|
78
|
+
|
|
79
|
+
def test_garbage_file_has_no_taken_date(self):
|
|
80
|
+
p = self.root / "broken.jpg"
|
|
81
|
+
p.write_bytes(b"\xff\xd8\xff\xe1\x00")
|
|
82
|
+
self.assertIsNone(tidybatch.taken_date(p))
|
|
83
|
+
|
|
84
|
+
def test_sort_taken_orders_by_photo_date(self):
|
|
85
|
+
self.make_photo("b.jpg", "2020:01:01 10:00:00")
|
|
86
|
+
self.make_photo("a.jpg", "2021:01:01 10:00:00")
|
|
87
|
+
run("rename", str(self.root), "--sort", "taken", "-t", "{n}{ext}", "--apply")
|
|
88
|
+
self.assertEqual(tidybatch.taken_date(self.root / "1.jpg").year, 2020)
|
|
89
|
+
|
|
90
|
+
def test_dry_run_changes_nothing(self):
|
|
91
|
+
self.make("My File.TXT")
|
|
92
|
+
self.assertEqual(run("rename", str(self.root), "--slug", "--lower"), 0)
|
|
93
|
+
self.assertEqual(self.names(), {"My File.TXT"})
|
|
94
|
+
|
|
95
|
+
def test_slug_and_undo_round_trip(self):
|
|
96
|
+
self.make("Relatório Final (v2).PDF")
|
|
97
|
+
self.make("Foto Férias 01.JPG")
|
|
98
|
+
before = self.names()
|
|
99
|
+
run("rename", str(self.root), "--slug", "--lower", "--apply")
|
|
100
|
+
self.assertEqual(self.names(), {"relatorio_final_v2.pdf", "foto_ferias_01.jpg"})
|
|
101
|
+
run("undo", str(self.root))
|
|
102
|
+
self.assertEqual(self.names(), before)
|
|
103
|
+
|
|
104
|
+
def test_numbering_chain_does_not_clobber(self):
|
|
105
|
+
# 1->2, 2->3, 3->4: a naive renamer overwrites file 2 with file 1.
|
|
106
|
+
for i in (1, 2, 3):
|
|
107
|
+
self.make(f"{i}.txt", content=f"content-{i}")
|
|
108
|
+
run("rename", str(self.root), "-t", "{n}{ext}", "--start", "2", "--apply")
|
|
109
|
+
self.assertEqual(self.names(), {"2.txt", "3.txt", "4.txt"})
|
|
110
|
+
self.assertEqual((self.root / "4.txt").read_text(), "content-3")
|
|
111
|
+
self.assertEqual((self.root / "2.txt").read_text(), "content-1")
|
|
112
|
+
|
|
113
|
+
def test_collisions_get_suffix(self):
|
|
114
|
+
self.make("a b.txt", "1")
|
|
115
|
+
self.make("a_b.txt", "2") # already the slug of the first one
|
|
116
|
+
run("rename", str(self.root), "--slug", "--apply")
|
|
117
|
+
self.assertEqual(self.names(), {"a_b.txt", "a_b_1.txt"})
|
|
118
|
+
self.assertEqual((self.root / "a_b.txt").read_text(), "2")
|
|
119
|
+
|
|
120
|
+
def test_find_replace_with_groups(self):
|
|
121
|
+
self.make("IMG_2024_0001.jpg")
|
|
122
|
+
run("rename", str(self.root), "--find", r"IMG_(\d{4})_(\d+)", "--replace", r"\1-photo-\2", "--apply")
|
|
123
|
+
self.assertEqual(self.names(), {"2024-photo-0001.jpg"})
|
|
124
|
+
|
|
125
|
+
def test_natural_sort_numbering(self):
|
|
126
|
+
for name in ("img10.png", "img2.png", "img1.png"):
|
|
127
|
+
self.make(name, content=name)
|
|
128
|
+
run("rename", str(self.root), "-t", "{n:02}{ext}", "--apply")
|
|
129
|
+
self.assertEqual((self.root / "02.png").read_text(), "img2.png")
|
|
130
|
+
self.assertEqual((self.root / "03.png").read_text(), "img10.png")
|
|
131
|
+
|
|
132
|
+
def test_summary_wording_matches_mode(self):
|
|
133
|
+
self.make("A B.txt")
|
|
134
|
+
out = io.StringIO()
|
|
135
|
+
with redirect_stdout(out):
|
|
136
|
+
tidybatch.main(["rename", str(self.root), "--slug"])
|
|
137
|
+
self.assertIn("1 file(s) would change.", out.getvalue())
|
|
138
|
+
out = io.StringIO()
|
|
139
|
+
with redirect_stdout(out):
|
|
140
|
+
tidybatch.main(["rename", str(self.root), "--slug", "--apply"])
|
|
141
|
+
self.assertIn("1 file(s) will change.", out.getvalue())
|
|
142
|
+
|
|
143
|
+
def test_unicode_normalization_counts_as_collision(self):
|
|
144
|
+
# 'é' precomposed (NFC) vs 'e' + combining accent (NFD): one file on macOS.
|
|
145
|
+
a, b = self.make("a.txt"), self.make("b.txt")
|
|
146
|
+
moves = tidybatch.resolve_collisions([
|
|
147
|
+
tidybatch.Move(a, self.root / "caf\u00e9.txt"),
|
|
148
|
+
tidybatch.Move(b, self.root / "cafe\u0301.txt"),
|
|
149
|
+
])
|
|
150
|
+
self.assertEqual(moves[1].dst.name, "cafe\u0301_1.txt")
|
|
151
|
+
|
|
152
|
+
def test_pro_commands_point_to_pro_without_touching_files(self):
|
|
153
|
+
self.make("a b.txt")
|
|
154
|
+
for argv in (["organize", str(self.root), "--apply"], ["dedupe", str(self.root)]):
|
|
155
|
+
out, err = io.StringIO(), io.StringIO()
|
|
156
|
+
with redirect_stdout(out), redirect_stderr(err):
|
|
157
|
+
code = tidybatch.main(argv)
|
|
158
|
+
# A script must not mistake "not in Core" for success.
|
|
159
|
+
self.assertEqual(code, 2)
|
|
160
|
+
self.assertIn("TidyBatch Pro", err.getvalue())
|
|
161
|
+
self.assertEqual(out.getvalue(), "")
|
|
162
|
+
self.assertEqual(self.names(), {"a b.txt"})
|
|
163
|
+
|
|
164
|
+
def test_bad_template_is_a_clean_error(self):
|
|
165
|
+
self.make("a.txt")
|
|
166
|
+
self.assertEqual(run("rename", str(self.root), "-t", "{nope}"), 2)
|
|
167
|
+
|
|
168
|
+
def test_template_cannot_create_paths(self):
|
|
169
|
+
self.make("a.txt")
|
|
170
|
+
self.assertEqual(run("rename", str(self.root), "-t", "../{stem}{ext}", "--apply"), 2)
|
|
171
|
+
self.assertEqual(self.names(), {"a.txt"})
|
|
172
|
+
|
|
173
|
+
|
|
174
|
+
if __name__ == "__main__":
|
|
175
|
+
unittest.main()
|
|
@@ -0,0 +1,124 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: tidybatch
|
|
3
|
+
Version: 1.1.1
|
|
4
|
+
Summary: Bulk rename files safely: dry-run preview, collision-proof two-phase renames, one-command undo.
|
|
5
|
+
Author: TidyBatch
|
|
6
|
+
License: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/tidybatch/tidybatch
|
|
8
|
+
Project-URL: Issues, https://github.com/tidybatch/tidybatch/issues
|
|
9
|
+
Project-URL: TidyBatch Pro, https://whop.com/tidybatch/bulk-file-renamer/
|
|
10
|
+
Keywords: rename,bulk-rename,batch-rename,files,cli,undo,dry-run
|
|
11
|
+
Classifier: Environment :: Console
|
|
12
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
13
|
+
Classifier: Operating System :: OS Independent
|
|
14
|
+
Classifier: Programming Language :: Python :: 3
|
|
15
|
+
Classifier: Topic :: System :: Filesystems
|
|
16
|
+
Classifier: Topic :: Utilities
|
|
17
|
+
Requires-Python: >=3.9
|
|
18
|
+
Description-Content-Type: text/markdown
|
|
19
|
+
License-File: LICENSE
|
|
20
|
+
Dynamic: license-file
|
|
21
|
+
|
|
22
|
+
# TidyBatch
|
|
23
|
+
|
|
24
|
+
**Bulk rename files without the fear.** Preview every change, apply it, and undo it with one command.
|
|
25
|
+
|
|
26
|
+

|
|
27
|
+
|
|
28
|
+
[](https://github.com/tidybatch/tidybatch/actions/workflows/ci.yml)
|
|
29
|
+
[](https://pypi.org/project/tidybatch/)
|
|
30
|
+

|
|
31
|
+

|
|
32
|
+

|
|
33
|
+
|
|
34
|
+
Most bulk-rename scripts have a silent bug: renumber `1.txt 2.txt 3.txt` → `2.txt 3.txt 4.txt` and the first `mv` overwrites the original `2.txt`. TidyBatch is built around not doing that:
|
|
35
|
+
|
|
36
|
+
- **Dry run by default.** Nothing changes until you add `--apply`.
|
|
37
|
+
- **One-command undo.** Every applied run is journaled; `tidybatch undo <folder>` puts every file back.
|
|
38
|
+
- **Never overwrites.** Two-phase renames make chains and swaps safe; clashes get `_1`, `_2`, …
|
|
39
|
+
- **Case-insensitive collision checks**, because Windows and macOS treat `Photo.JPG` and `photo.jpg` as the same file.
|
|
40
|
+
- **One file, standard library only.** No dependencies: you can read all of it before you trust it with your photos.
|
|
41
|
+
|
|
42
|
+
New to bulk renaming? Read the tested guides at **[tidybatch.github.io/guides](https://tidybatch.github.io/guides/)**: how to rename safely on any OS, how to undo a bulk rename, and how to add dates to file names.
|
|
43
|
+
|
|
44
|
+
## Install
|
|
45
|
+
|
|
46
|
+
```bash
|
|
47
|
+
pipx install tidybatch
|
|
48
|
+
# or: uv tool install tidybatch
|
|
49
|
+
# or: pip install tidybatch
|
|
50
|
+
# or just download tidybatch.py and run: python3 tidybatch.py --help
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
Try it on a folder without installing anything permanent (it's a preview, so nothing changes):
|
|
54
|
+
|
|
55
|
+
```bash
|
|
56
|
+
uvx tidybatch rename ~/Downloads --slug --lower
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
## Recipes
|
|
60
|
+
|
|
61
|
+
```bash
|
|
62
|
+
# Clean names: no accents, spaces or symbols, all lowercase
|
|
63
|
+
tidybatch rename ~/Downloads --slug --lower
|
|
64
|
+
|
|
65
|
+
# Number photos in date order: holiday_001.jpg, holiday_002.jpg, …
|
|
66
|
+
tidybatch rename ./photos -g "*.jpg" --sort date -t "holiday_{n:03}{ext}"
|
|
67
|
+
|
|
68
|
+
# Put the file date in front: 2024-08-12_invoice.pdf
|
|
69
|
+
tidybatch rename ./invoices -t "{date:%Y-%m-%d}_{stem}{ext}"
|
|
70
|
+
|
|
71
|
+
# Name photos by when they were TAKEN (EXIF): 2023-07-14_182205.jpg
|
|
72
|
+
tidybatch rename ./camera -t "{taken:%Y-%m-%d_%H%M%S}{ext}"
|
|
73
|
+
|
|
74
|
+
# Regex with groups: IMG_2024_0001.jpg -> 2024-photo-0001.jpg
|
|
75
|
+
tidybatch rename . --find "IMG_(\d{4})_(\d+)" --replace "\1-photo-\2"
|
|
76
|
+
|
|
77
|
+
# Happy with the preview? Run it for real, then change your mind
|
|
78
|
+
tidybatch rename ~/Downloads --slug --lower --apply
|
|
79
|
+
tidybatch undo ~/Downloads
|
|
80
|
+
```
|
|
81
|
+
|
|
82
|
+
**Template fields:** `{stem}` `{ext}` `{n}` (counter, e.g. `{n:03}`) `{date}` (modification date, e.g. `{date:%Y%m%d}`) `{taken}` (photo **date taken** from EXIF, falling back to `{date}`) `{today}` `{parent}` `{size_kb}`
|
|
83
|
+
|
|
84
|
+
**Options:** `-r` sub-folders · `-g "*.jpg"` filter · `--hidden` include hidden files · `--sort name|date|taken|size` · `--start N` · `--apply`
|
|
85
|
+
|
|
86
|
+
**Photo dates:** `{taken}` reads EXIF with the standard library only, with no Pillow or exiftool needed. Every CI run checks it against ExifTool on ExifTool's own sample images (JPEG, HEIC, TIFF, DNG, CR2, CR3, NEF, RW2, RAF: same date for every file, [dev/verify_exif.py](https://github.com/tidybatch/tidybatch/blob/main/dev/verify_exif.py)) and feeds it 20,000 corrupted files, which must never crash or hang it ([dev/fuzz_exif.py](https://github.com/tidybatch/tidybatch/blob/main/dev/fuzz_exif.py)). Dates stored only in XMP/IPTC aren't read; those files fall back to the modification date.
|
|
87
|
+
|
|
88
|
+
## How it stays safe
|
|
89
|
+
|
|
90
|
+
1. **Plan:** compute every new name without touching the disk, then resolve collisions. A destination is free only if nobody else claimed it *and* whatever is there now is itself moving away.
|
|
91
|
+
2. **Phase 1:** every file moves to a temporary name in the same folder.
|
|
92
|
+
3. **Phase 2:** every temporary file moves to its final name, refusing to overwrite anything that appeared in the meantime.
|
|
93
|
+
4. **Journal:** `<folder>/.tidybatch/journal-*.json` records each completed move, even if the run is interrupted, so `undo` can replay it backwards.
|
|
94
|
+
|
|
95
|
+
## How it's made
|
|
96
|
+
|
|
97
|
+
Most of the code was written with an AI coding agent. The behaviour that protects your files (two-phase moves, collision checks, undo) is pinned down by the test suite, which runs on Linux, macOS and Windows on every push.
|
|
98
|
+
|
|
99
|
+
## TidyBatch Pro
|
|
100
|
+
|
|
101
|
+
This repository is **TidyBatch Core** (rename + undo), free and MIT-licensed. **[TidyBatch Pro](https://whop.com/tidybatch/bulk-file-renamer/?utm_source=github&utm_campaign=tidybatch)** adds:
|
|
102
|
+
|
|
103
|
+
- `organize`: sort a folder into Images / Documents / Videos…, by year/month (modified **or photo date taken**), or by extension
|
|
104
|
+
- `dedupe`: find exact duplicates by content (SHA-256), keep the oldest, move the rest aside (never deleted)
|
|
105
|
+
- ready-to-run apps for **Windows and Linux** (no Python needed), plus free 1.x updates
|
|
106
|
+
|
|
107
|
+
Buying Pro also funds the free version. Thank you!
|
|
108
|
+
|
|
109
|
+
## Contributing
|
|
110
|
+
|
|
111
|
+
Bug reports with a reproducible folder layout are gold. Run the tests with:
|
|
112
|
+
|
|
113
|
+
```bash
|
|
114
|
+
python -m unittest discover -s tests
|
|
115
|
+
|
|
116
|
+
# photo-date checks (needs perl and an ExifTool checkout)
|
|
117
|
+
git clone --depth 1 https://github.com/exiftool/exiftool /tmp/exiftool
|
|
118
|
+
python dev/verify_exif.py /tmp/exiftool
|
|
119
|
+
python dev/fuzz_exif.py /tmp/exiftool
|
|
120
|
+
```
|
|
121
|
+
|
|
122
|
+
## License
|
|
123
|
+
|
|
124
|
+
[MIT](https://github.com/tidybatch/tidybatch/blob/main/LICENSE)
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
tidybatch
|
|
@@ -0,0 +1,604 @@
|
|
|
1
|
+
#!/usr/bin/env python3
|
|
2
|
+
"""
|
|
3
|
+
TidyBatch Core - bulk rename files safely, with preview and one-command undo.
|
|
4
|
+
|
|
5
|
+
Safety model:
|
|
6
|
+
* Every command is a DRY RUN unless you pass --apply.
|
|
7
|
+
* Every applied run writes a journal to <folder>/.tidybatch/,
|
|
8
|
+
so `tidybatch undo <folder>` puts every file back where it was.
|
|
9
|
+
* Nothing is ever deleted or overwritten.
|
|
10
|
+
* Name collisions are resolved with a numeric suffix, never by overwriting.
|
|
11
|
+
|
|
12
|
+
Standard library only (Python 3.9+). MIT licensed.
|
|
13
|
+
|
|
14
|
+
`organize` and `dedupe` are part of TidyBatch Pro: https://whop.com/tidybatch/bulk-file-renamer/
|
|
15
|
+
"""
|
|
16
|
+
from __future__ import annotations
|
|
17
|
+
|
|
18
|
+
import argparse
|
|
19
|
+
import json
|
|
20
|
+
import os
|
|
21
|
+
import re
|
|
22
|
+
import shutil
|
|
23
|
+
import struct
|
|
24
|
+
import sys
|
|
25
|
+
import unicodedata
|
|
26
|
+
from dataclasses import dataclass
|
|
27
|
+
from datetime import datetime
|
|
28
|
+
from pathlib import Path
|
|
29
|
+
from typing import Iterable, Iterator
|
|
30
|
+
|
|
31
|
+
__version__ = "1.1.1"
|
|
32
|
+
|
|
33
|
+
JOURNAL_DIR = ".tidybatch"
|
|
34
|
+
TMP_PREFIX = ".tidybatch-tmp-"
|
|
35
|
+
SKIP_DIRS = {JOURNAL_DIR, "_duplicates", ".git", "__pycache__"}
|
|
36
|
+
|
|
37
|
+
class TidyError(Exception):
|
|
38
|
+
"""A user-facing error: printed without a traceback."""
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
@dataclass(frozen=True)
|
|
42
|
+
class Move:
|
|
43
|
+
src: Path
|
|
44
|
+
dst: Path
|
|
45
|
+
|
|
46
|
+
|
|
47
|
+
# --------------------------------------------------------------------------- #
|
|
48
|
+
# File discovery
|
|
49
|
+
# --------------------------------------------------------------------------- #
|
|
50
|
+
|
|
51
|
+
def iter_files(root: Path, recursive: bool, glob: str | None, include_hidden: bool) -> Iterator[Path]:
|
|
52
|
+
"""Yield regular files under root, skipping TidyBatch's own folders."""
|
|
53
|
+
if recursive:
|
|
54
|
+
for dirpath, dirnames, filenames in os.walk(root):
|
|
55
|
+
dirnames[:] = [d for d in dirnames if d not in SKIP_DIRS and (include_hidden or not d.startswith("."))]
|
|
56
|
+
for name in filenames:
|
|
57
|
+
p = Path(dirpath) / name
|
|
58
|
+
if _wanted(p, glob, include_hidden):
|
|
59
|
+
yield p
|
|
60
|
+
else:
|
|
61
|
+
for p in root.iterdir():
|
|
62
|
+
if p.is_file() and _wanted(p, glob, include_hidden):
|
|
63
|
+
yield p
|
|
64
|
+
|
|
65
|
+
|
|
66
|
+
def _wanted(p: Path, glob: str | None, include_hidden: bool) -> bool:
|
|
67
|
+
if p.name.startswith(TMP_PREFIX) or p.is_symlink():
|
|
68
|
+
return False
|
|
69
|
+
if not include_hidden and p.name.startswith("."):
|
|
70
|
+
return False
|
|
71
|
+
return glob is None or p.match(glob)
|
|
72
|
+
|
|
73
|
+
|
|
74
|
+
def natural_key(p: Path) -> list:
|
|
75
|
+
"""Sort 'img2' before 'img10', the way humans expect."""
|
|
76
|
+
return [int(t) if t.isdigit() else t for t in re.split(r"(\d+)", p.name.casefold())]
|
|
77
|
+
|
|
78
|
+
|
|
79
|
+
def sort_files(files: Iterable[Path], by: str) -> list[Path]:
|
|
80
|
+
if by == "taken":
|
|
81
|
+
return sorted(files, key=lambda p: (taken_or_mtime(p), natural_key(p)))
|
|
82
|
+
if by == "date":
|
|
83
|
+
return sorted(files, key=lambda p: (p.stat().st_mtime, natural_key(p)))
|
|
84
|
+
if by == "size":
|
|
85
|
+
return sorted(files, key=lambda p: (p.stat().st_size, natural_key(p)))
|
|
86
|
+
return sorted(files, key=natural_key)
|
|
87
|
+
|
|
88
|
+
|
|
89
|
+
# --------------------------------------------------------------------------- #
|
|
90
|
+
# Photo dates (EXIF "date taken"), standard library only.
|
|
91
|
+
# JPEG, TIFF, TIFF-based RAW (DNG, CR2, NEF, ARW, ORF, RW2), Fuji RAF, Canon CR3
|
|
92
|
+
# and HEIC/HEIF/AVIF. Checked against ExifTool's sample images; see dev/.
|
|
93
|
+
# --------------------------------------------------------------------------- #
|
|
94
|
+
|
|
95
|
+
_TIFF_MAGIC = {42, 0x4F52, 0x5352, 0x55} # TIFF, Olympus ORF (x2), Panasonic RW2
|
|
96
|
+
_DATE_TAGS = (0x9003, 0x9004, 0x0132) # DateTimeOriginal, DateTimeDigitized, DateTime
|
|
97
|
+
|
|
98
|
+
|
|
99
|
+
def taken_date(path: Path) -> datetime | None:
|
|
100
|
+
"""EXIF DateTimeOriginal, else DateTimeDigitized, else IFD0 DateTime; None if absent."""
|
|
101
|
+
try:
|
|
102
|
+
with path.open("rb") as f:
|
|
103
|
+
head = f.read(16)
|
|
104
|
+
if head[:2] == b"\xff\xd8":
|
|
105
|
+
base = _jpeg_tiff_offset(f, 0)
|
|
106
|
+
elif head[:4] in (b"II*\x00", b"MM\x00*", b"IIRO", b"IIRS", b"IIU\x00"):
|
|
107
|
+
base = 0
|
|
108
|
+
elif head.startswith(b"FUJIFILMCCD-RAW"):
|
|
109
|
+
f.seek(84)
|
|
110
|
+
jpeg_at = struct.unpack(">I", f.read(4))[0]
|
|
111
|
+
base = _jpeg_tiff_offset(f, jpeg_at)
|
|
112
|
+
elif head[4:12] == b"ftypcrx ":
|
|
113
|
+
return _cr3_date(f)
|
|
114
|
+
elif head[4:8] == b"ftyp":
|
|
115
|
+
base = _isobmff_tiff_offset(f)
|
|
116
|
+
else:
|
|
117
|
+
return None
|
|
118
|
+
return _tiff_date(f, base) if base is not None else None
|
|
119
|
+
except Exception: # metadata is best-effort: a broken file must never stop a rename
|
|
120
|
+
return None
|
|
121
|
+
|
|
122
|
+
|
|
123
|
+
def _cr3_date(f) -> datetime | None:
|
|
124
|
+
"""Canon CR3: EXIF lives in 'CMT1' (IFD0) and 'CMT2' (Exif IFD) boxes, each a TIFF."""
|
|
125
|
+
f.seek(0)
|
|
126
|
+
head = f.read(1 << 18)
|
|
127
|
+
for box in (b"CMT2", b"CMT1"):
|
|
128
|
+
i = head.find(box)
|
|
129
|
+
if i >= 4:
|
|
130
|
+
d = _tiff_date(f, i + 4, exif_ifd_at_root=(box == b"CMT2"))
|
|
131
|
+
if d:
|
|
132
|
+
return d
|
|
133
|
+
return None
|
|
134
|
+
|
|
135
|
+
|
|
136
|
+
def _jpeg_tiff_offset(f, start: int) -> int | None:
|
|
137
|
+
"""Offset of the TIFF header inside a JPEG's 'Exif' APP1 segment."""
|
|
138
|
+
pos = start + 2
|
|
139
|
+
for _ in range(1000):
|
|
140
|
+
f.seek(pos)
|
|
141
|
+
marker = f.read(2)
|
|
142
|
+
if len(marker) < 2 or marker[0] != 0xFF:
|
|
143
|
+
return None
|
|
144
|
+
m = marker[1]
|
|
145
|
+
if m == 0xFF: # fill byte
|
|
146
|
+
pos += 1
|
|
147
|
+
continue
|
|
148
|
+
if m in (0xD9, 0xDA): # end of image / start of scan: no EXIF before pixels
|
|
149
|
+
return None
|
|
150
|
+
if 0xD0 <= m <= 0xD7 or m == 0x01:
|
|
151
|
+
pos += 2
|
|
152
|
+
continue
|
|
153
|
+
seglen = struct.unpack(">H", f.read(2))[0]
|
|
154
|
+
if m == 0xE1 and f.read(6) == b"Exif\x00\x00":
|
|
155
|
+
return pos + 10
|
|
156
|
+
pos += 2 + seglen
|
|
157
|
+
return None
|
|
158
|
+
|
|
159
|
+
|
|
160
|
+
def _boxes(f, start: int, end: int):
|
|
161
|
+
pos = start
|
|
162
|
+
while pos + 8 <= end:
|
|
163
|
+
f.seek(pos)
|
|
164
|
+
size, btype = struct.unpack(">I4s", f.read(8))
|
|
165
|
+
hdr = 8
|
|
166
|
+
if size == 1:
|
|
167
|
+
size = struct.unpack(">Q", f.read(8))[0]
|
|
168
|
+
hdr = 16
|
|
169
|
+
elif size == 0:
|
|
170
|
+
size = end - pos
|
|
171
|
+
if size < hdr:
|
|
172
|
+
return
|
|
173
|
+
yield btype, pos, size, hdr
|
|
174
|
+
pos += size
|
|
175
|
+
|
|
176
|
+
|
|
177
|
+
def _isobmff_tiff_offset(f) -> int | None:
|
|
178
|
+
"""HEIC/HEIF/AVIF: locate the 'Exif' item via meta/iinf + meta/iloc."""
|
|
179
|
+
f.seek(0, 2)
|
|
180
|
+
file_end = f.tell()
|
|
181
|
+
meta = next(((p + h + 4, p + s) for t, p, s, h in _boxes(f, 0, file_end) if t == b"meta"), None)
|
|
182
|
+
if not meta:
|
|
183
|
+
return None
|
|
184
|
+
exif_id, iloc = None, None
|
|
185
|
+
for btype, p, s, h in _boxes(f, *meta):
|
|
186
|
+
if btype == b"iinf":
|
|
187
|
+
exif_id = _iinf_exif_id(f, p + h, p + s)
|
|
188
|
+
elif btype == b"iloc":
|
|
189
|
+
iloc = (p + h, p + s)
|
|
190
|
+
if exif_id is None or iloc is None:
|
|
191
|
+
return None
|
|
192
|
+
loc = _iloc_offset(f, iloc[0], exif_id)
|
|
193
|
+
if loc is None:
|
|
194
|
+
return None
|
|
195
|
+
f.seek(loc)
|
|
196
|
+
tiff = loc + 4 + struct.unpack(">I", f.read(4))[0]
|
|
197
|
+
f.seek(tiff)
|
|
198
|
+
if f.read(2) not in (b"II", b"MM"): # some writers point at "Exif\0\0"
|
|
199
|
+
f.seek(loc)
|
|
200
|
+
blob = f.read(32)
|
|
201
|
+
i = blob.find(b"Exif\x00\x00")
|
|
202
|
+
tiff = loc + i + 6 if i >= 0 else None
|
|
203
|
+
return tiff
|
|
204
|
+
|
|
205
|
+
|
|
206
|
+
def _iinf_exif_id(f, start: int, end: int) -> int | None:
|
|
207
|
+
f.seek(start)
|
|
208
|
+
version = f.read(4)[0]
|
|
209
|
+
f.read(2 if version == 0 else 4) # entry_count
|
|
210
|
+
for btype, p, s, h in _boxes(f, f.tell(), end):
|
|
211
|
+
if btype != b"infe":
|
|
212
|
+
continue
|
|
213
|
+
f.seek(p + h)
|
|
214
|
+
v = f.read(4)[0]
|
|
215
|
+
if v < 2:
|
|
216
|
+
continue
|
|
217
|
+
item_id = struct.unpack(">H" if v == 2 else ">I", f.read(2 if v == 2 else 4))[0]
|
|
218
|
+
f.read(2) # protection index
|
|
219
|
+
if f.read(4) == b"Exif":
|
|
220
|
+
return item_id
|
|
221
|
+
return None
|
|
222
|
+
|
|
223
|
+
|
|
224
|
+
def _uint(f, size: int) -> int:
|
|
225
|
+
return int.from_bytes(f.read(size), "big") if size else 0
|
|
226
|
+
|
|
227
|
+
|
|
228
|
+
def _iloc_offset(f, start: int, wanted: int) -> int | None:
|
|
229
|
+
f.seek(start)
|
|
230
|
+
version = f.read(4)[0]
|
|
231
|
+
b1, b2 = f.read(2)
|
|
232
|
+
off_size, len_size, base_size = b1 >> 4, b1 & 15, b2 >> 4
|
|
233
|
+
idx_size = b2 & 15 if version in (1, 2) else 0
|
|
234
|
+
count = _uint(f, 2 if version < 2 else 4)
|
|
235
|
+
if count > 4096:
|
|
236
|
+
return None
|
|
237
|
+
for _ in range(count):
|
|
238
|
+
item_id = _uint(f, 2 if version < 2 else 4)
|
|
239
|
+
method = _uint(f, 2) & 15 if version in (1, 2) else 0
|
|
240
|
+
f.read(2) # data reference index
|
|
241
|
+
base = _uint(f, base_size)
|
|
242
|
+
extents = _uint(f, 2)
|
|
243
|
+
if extents > 4096:
|
|
244
|
+
return None
|
|
245
|
+
first = None
|
|
246
|
+
for _ in range(extents):
|
|
247
|
+
_uint(f, idx_size)
|
|
248
|
+
off = _uint(f, off_size)
|
|
249
|
+
_uint(f, len_size)
|
|
250
|
+
if first is None:
|
|
251
|
+
first = off
|
|
252
|
+
if item_id == wanted:
|
|
253
|
+
return base + (first or 0) if method == 0 else None
|
|
254
|
+
return None
|
|
255
|
+
|
|
256
|
+
|
|
257
|
+
def _tiff_date(f, base: int, exif_ifd_at_root: bool = False) -> datetime | None:
|
|
258
|
+
f.seek(base)
|
|
259
|
+
hdr = f.read(8)
|
|
260
|
+
if hdr[:2] == b"II":
|
|
261
|
+
e = "<"
|
|
262
|
+
elif hdr[:2] == b"MM":
|
|
263
|
+
e = ">"
|
|
264
|
+
else:
|
|
265
|
+
return None
|
|
266
|
+
magic, ifd0 = struct.unpack(e + "HI", hdr[2:8])
|
|
267
|
+
if magic not in _TIFF_MAGIC:
|
|
268
|
+
return None
|
|
269
|
+
found: dict[int, tuple] = {}
|
|
270
|
+
exif_ifd = None
|
|
271
|
+
for tag, typ, count, raw in _ifd(f, base, ifd0, e):
|
|
272
|
+
if exif_ifd_at_root and tag in (0x9003, 0x9004):
|
|
273
|
+
found[tag] = (typ, count, raw)
|
|
274
|
+
elif tag == 0x8769:
|
|
275
|
+
exif_ifd = struct.unpack(e + "I", raw)[0]
|
|
276
|
+
elif tag == 0x0132:
|
|
277
|
+
found[tag] = (typ, count, raw)
|
|
278
|
+
if exif_ifd:
|
|
279
|
+
for tag, typ, count, raw in _ifd(f, base, exif_ifd, e):
|
|
280
|
+
if tag in (0x9003, 0x9004):
|
|
281
|
+
found[tag] = (typ, count, raw)
|
|
282
|
+
for tag in _DATE_TAGS:
|
|
283
|
+
if tag in found:
|
|
284
|
+
d = _ascii_date(f, base, e, *found[tag])
|
|
285
|
+
if d:
|
|
286
|
+
return d
|
|
287
|
+
return None
|
|
288
|
+
|
|
289
|
+
|
|
290
|
+
def _ifd(f, base: int, offset: int, e: str):
|
|
291
|
+
f.seek(base + offset)
|
|
292
|
+
n = struct.unpack(e + "H", f.read(2))[0]
|
|
293
|
+
if n > 1000:
|
|
294
|
+
return
|
|
295
|
+
data = f.read(12 * n)
|
|
296
|
+
for i in range(n):
|
|
297
|
+
entry = data[12 * i:12 * i + 12]
|
|
298
|
+
if len(entry) < 12:
|
|
299
|
+
return
|
|
300
|
+
tag, typ, count = struct.unpack(e + "HHI", entry[:8])
|
|
301
|
+
yield tag, typ, count, entry[8:12]
|
|
302
|
+
|
|
303
|
+
|
|
304
|
+
def _ascii_date(f, base: int, e: str, typ: int, count: int, raw: bytes) -> datetime | None:
|
|
305
|
+
if typ != 2 or count < 19:
|
|
306
|
+
return None
|
|
307
|
+
f.seek(base + struct.unpack(e + "I", raw)[0])
|
|
308
|
+
text = f.read(min(count, 32)).split(b"\x00")[0].decode("ascii", "ignore").strip()
|
|
309
|
+
for fmt in ("%Y:%m:%d %H:%M:%S", "%Y-%m-%d %H:%M:%S", "%Y:%m:%d %H:%M"):
|
|
310
|
+
try:
|
|
311
|
+
return datetime.strptime(text[:19] if "S" in fmt else text[:16], fmt)
|
|
312
|
+
except ValueError:
|
|
313
|
+
continue
|
|
314
|
+
return None
|
|
315
|
+
|
|
316
|
+
|
|
317
|
+
def taken_or_mtime(path: Path) -> datetime:
|
|
318
|
+
"""Photo 'date taken' when the file has one, otherwise its modification time."""
|
|
319
|
+
return taken_date(path) or datetime.fromtimestamp(path.stat().st_mtime)
|
|
320
|
+
|
|
321
|
+
|
|
322
|
+
# --------------------------------------------------------------------------- #
|
|
323
|
+
# Naming helpers
|
|
324
|
+
# --------------------------------------------------------------------------- #
|
|
325
|
+
|
|
326
|
+
_INVALID_CHARS = re.compile(r'[<>:"/\\|?*\x00-\x1f]')
|
|
327
|
+
|
|
328
|
+
|
|
329
|
+
def slugify(text: str, lower: bool = True, sep: str = "_") -> str:
|
|
330
|
+
"""'Relatório Final (v2)' -> 'relatorio_final_v2'. Safe on every OS."""
|
|
331
|
+
text = unicodedata.normalize("NFKD", text).encode("ascii", "ignore").decode("ascii")
|
|
332
|
+
text = re.sub(r"[^\w.-]+", sep, text)
|
|
333
|
+
text = re.sub(rf"{re.escape(sep)}{{2,}}", sep, text).strip(sep + ".")
|
|
334
|
+
return text.lower() if lower else text
|
|
335
|
+
|
|
336
|
+
|
|
337
|
+
def render_name(template: str, path: Path, index: int, stem: str | None = None) -> str:
|
|
338
|
+
stat = path.stat()
|
|
339
|
+
fields = {
|
|
340
|
+
"stem": path.stem if stem is None else stem,
|
|
341
|
+
"ext": path.suffix,
|
|
342
|
+
"n": index,
|
|
343
|
+
"date": datetime.fromtimestamp(stat.st_mtime),
|
|
344
|
+
# Reading EXIF costs a file read, so only do it when the template asks.
|
|
345
|
+
"taken": taken_or_mtime(path) if "{taken" in template else None,
|
|
346
|
+
"today": datetime.now(),
|
|
347
|
+
"parent": path.parent.name,
|
|
348
|
+
"size_kb": stat.st_size // 1024,
|
|
349
|
+
}
|
|
350
|
+
try:
|
|
351
|
+
name = template.format(**fields)
|
|
352
|
+
except KeyError as e:
|
|
353
|
+
raise TidyError(f"Unknown template field {e}. Available: {', '.join('{' + k + '}' for k in fields)}")
|
|
354
|
+
except (ValueError, IndexError) as e:
|
|
355
|
+
raise TidyError(f"Invalid template '{template}': {e}")
|
|
356
|
+
if "/" in name or "\\" in name:
|
|
357
|
+
raise TidyError("Template must produce a file name, not a path (no '/' or '\\').")
|
|
358
|
+
return name
|
|
359
|
+
|
|
360
|
+
|
|
361
|
+
def _key(p: Path) -> str:
|
|
362
|
+
# Case- and normalization-insensitive on purpose: Windows and macOS file
|
|
363
|
+
# systems treat 'A.txt'/'a.txt' (and composed/decomposed 'é') as the same
|
|
364
|
+
# file, so we must too.
|
|
365
|
+
return unicodedata.normalize("NFC", str(p)).casefold()
|
|
366
|
+
|
|
367
|
+
|
|
368
|
+
def resolve_collisions(moves: list[Move]) -> list[Move]:
|
|
369
|
+
"""
|
|
370
|
+
Make every destination unique. A destination is free if nobody else
|
|
371
|
+
already claimed it in this plan and either nothing is there on disk, or
|
|
372
|
+
whatever is there is itself being moved away by this plan.
|
|
373
|
+
"""
|
|
374
|
+
active = [m for m in moves if m.src != m.dst]
|
|
375
|
+
leaving = {_key(m.src) for m in active}
|
|
376
|
+
# Files that keep their name still occupy it.
|
|
377
|
+
claimed = {_key(m.src) for m in moves if m.src == m.dst}
|
|
378
|
+
result = []
|
|
379
|
+
for m in active:
|
|
380
|
+
dst, i = m.dst, 1
|
|
381
|
+
# A case-only rename (Photo.JPG -> photo.jpg) passes: its own src is "leaving".
|
|
382
|
+
while _key(dst) in claimed or (dst.exists() and _key(dst) not in leaving):
|
|
383
|
+
dst = m.dst.with_name(f"{m.dst.stem}_{i}{m.dst.suffix}")
|
|
384
|
+
i += 1
|
|
385
|
+
claimed.add(_key(dst))
|
|
386
|
+
result.append(Move(m.src, dst))
|
|
387
|
+
return result
|
|
388
|
+
|
|
389
|
+
|
|
390
|
+
# --------------------------------------------------------------------------- #
|
|
391
|
+
# Planners: they only compute moves, never touch the disk
|
|
392
|
+
# --------------------------------------------------------------------------- #
|
|
393
|
+
|
|
394
|
+
def plan_rename(files: list[Path], template: str, find: str | None, replace: str,
|
|
395
|
+
slug: bool, lower: bool, start: int) -> list[Move]:
|
|
396
|
+
pattern = None
|
|
397
|
+
if find:
|
|
398
|
+
try:
|
|
399
|
+
pattern = re.compile(find)
|
|
400
|
+
except re.error as e:
|
|
401
|
+
raise TidyError(f"Invalid --find regex: {e}")
|
|
402
|
+
|
|
403
|
+
moves = []
|
|
404
|
+
for index, path in enumerate(files, start=start):
|
|
405
|
+
stem = pattern.sub(replace, path.stem) if pattern else path.stem
|
|
406
|
+
name = render_name(template, path, index, stem)
|
|
407
|
+
if slug or lower:
|
|
408
|
+
p = Path(name)
|
|
409
|
+
stem = slugify(p.stem, lower=lower) if slug else p.stem.lower()
|
|
410
|
+
name = (stem or "file") + (p.suffix.lower() if lower else p.suffix)
|
|
411
|
+
name = _INVALID_CHARS.sub("_", name).strip() or f"file{path.suffix}"
|
|
412
|
+
moves.append(Move(path, path.with_name(name)))
|
|
413
|
+
return resolve_collisions(moves)
|
|
414
|
+
|
|
415
|
+
|
|
416
|
+
# --------------------------------------------------------------------------- #
|
|
417
|
+
# Execution + journal
|
|
418
|
+
# --------------------------------------------------------------------------- #
|
|
419
|
+
|
|
420
|
+
def apply_moves(moves: list[Move], root: Path) -> Path:
|
|
421
|
+
"""
|
|
422
|
+
Two-phase move: every source first goes to a temporary name, then to its
|
|
423
|
+
final name. This makes chains and swaps safe (a->b while b->c, or a<->b).
|
|
424
|
+
The journal is written even if something fails halfway.
|
|
425
|
+
"""
|
|
426
|
+
journal_dir = root / JOURNAL_DIR
|
|
427
|
+
journal_dir.mkdir(exist_ok=True)
|
|
428
|
+
journal = journal_dir / f"journal-{datetime.now():%Y%m%d-%H%M%S-%f}.json"
|
|
429
|
+
|
|
430
|
+
staged: list[tuple[Move, Path]] = []
|
|
431
|
+
done: list[Move] = []
|
|
432
|
+
try:
|
|
433
|
+
for i, m in enumerate(moves):
|
|
434
|
+
tmp = m.src.with_name(f"{TMP_PREFIX}{os.getpid()}-{i}{m.src.suffix}")
|
|
435
|
+
os.rename(m.src, tmp)
|
|
436
|
+
staged.append((m, tmp))
|
|
437
|
+
for m, tmp in staged:
|
|
438
|
+
if m.dst.exists():
|
|
439
|
+
raise TidyError(f"Refusing to overwrite '{m.dst}' (it appeared during the run).")
|
|
440
|
+
m.dst.parent.mkdir(parents=True, exist_ok=True)
|
|
441
|
+
shutil.move(str(tmp), str(m.dst))
|
|
442
|
+
done.append(m)
|
|
443
|
+
except BaseException:
|
|
444
|
+
finished = {id(m) for m in done}
|
|
445
|
+
for m, tmp in staged:
|
|
446
|
+
if id(m) not in finished and tmp.exists():
|
|
447
|
+
os.rename(tmp, m.src)
|
|
448
|
+
raise
|
|
449
|
+
finally:
|
|
450
|
+
if done:
|
|
451
|
+
payload = {
|
|
452
|
+
"version": __version__,
|
|
453
|
+
"root": str(root.resolve()),
|
|
454
|
+
"created": datetime.now().isoformat(timespec="seconds"),
|
|
455
|
+
"moves": [{"src": str(m.src.resolve()), "dst": str(m.dst.resolve())} for m in done],
|
|
456
|
+
}
|
|
457
|
+
journal.write_text(json.dumps(payload, indent=2), encoding="utf-8")
|
|
458
|
+
return journal
|
|
459
|
+
|
|
460
|
+
|
|
461
|
+
def undo(root: Path, journal_path: Path | None) -> int:
|
|
462
|
+
journal_dir = root / JOURNAL_DIR
|
|
463
|
+
if journal_path is None:
|
|
464
|
+
journals = sorted(journal_dir.glob("journal-*.json")) if journal_dir.is_dir() else []
|
|
465
|
+
if not journals:
|
|
466
|
+
raise TidyError(f"No journal found in '{journal_dir}'. Nothing to undo.")
|
|
467
|
+
journal_path = journals[-1]
|
|
468
|
+
|
|
469
|
+
data = json.loads(journal_path.read_text(encoding="utf-8"))
|
|
470
|
+
journal_root = Path(data["root"])
|
|
471
|
+
restored = skipped = 0
|
|
472
|
+
for entry in reversed(data["moves"]):
|
|
473
|
+
src, dst = Path(entry["src"]), Path(entry["dst"])
|
|
474
|
+
if not dst.exists():
|
|
475
|
+
print(f" skip (missing now): {dst}")
|
|
476
|
+
skipped += 1
|
|
477
|
+
continue
|
|
478
|
+
if src.exists() and _key(src) != _key(dst):
|
|
479
|
+
print(f" skip (original name taken): {src}")
|
|
480
|
+
skipped += 1
|
|
481
|
+
continue
|
|
482
|
+
src.parent.mkdir(parents=True, exist_ok=True)
|
|
483
|
+
shutil.move(str(dst), str(src))
|
|
484
|
+
_remove_empty_parents(dst.parent, stop_at=journal_root)
|
|
485
|
+
restored += 1
|
|
486
|
+
|
|
487
|
+
journal_path.rename(journal_path.with_suffix(".undone"))
|
|
488
|
+
print(f"Restored {restored} file(s), skipped {skipped}. Journal: {journal_path.name}")
|
|
489
|
+
return 0 if skipped == 0 else 1
|
|
490
|
+
|
|
491
|
+
|
|
492
|
+
def _remove_empty_parents(folder: Path, stop_at: Path) -> None:
|
|
493
|
+
folder, stop_at = folder.resolve(), stop_at.resolve()
|
|
494
|
+
while folder != stop_at and stop_at in folder.parents:
|
|
495
|
+
try:
|
|
496
|
+
folder.rmdir() # only succeeds when empty
|
|
497
|
+
except OSError:
|
|
498
|
+
return
|
|
499
|
+
folder = folder.parent
|
|
500
|
+
|
|
501
|
+
|
|
502
|
+
# --------------------------------------------------------------------------- #
|
|
503
|
+
# CLI
|
|
504
|
+
# --------------------------------------------------------------------------- #
|
|
505
|
+
|
|
506
|
+
def show_plan(moves: list[Move], root: Path, applying: bool = False) -> None:
|
|
507
|
+
def rel(p: Path) -> str:
|
|
508
|
+
try:
|
|
509
|
+
return str(p.relative_to(root))
|
|
510
|
+
except ValueError:
|
|
511
|
+
return str(p)
|
|
512
|
+
|
|
513
|
+
if not moves:
|
|
514
|
+
print("Nothing to do: every file already matches.")
|
|
515
|
+
return
|
|
516
|
+
width = min(max(len(rel(m.src)) for m in moves), 60)
|
|
517
|
+
for m in moves:
|
|
518
|
+
print(f" {rel(m.src):<{width}} -> {rel(m.dst)}")
|
|
519
|
+
print(f"\n{len(moves)} file(s) {'will change' if applying else 'would change'}.")
|
|
520
|
+
|
|
521
|
+
|
|
522
|
+
def build_parser() -> argparse.ArgumentParser:
|
|
523
|
+
common = argparse.ArgumentParser(add_help=False)
|
|
524
|
+
common.add_argument("folder", type=Path, help="folder to work on")
|
|
525
|
+
common.add_argument("-r", "--recursive", action="store_true", help="include sub-folders")
|
|
526
|
+
common.add_argument("-g", "--glob", help="only files matching this pattern, e.g. '*.jpg'")
|
|
527
|
+
common.add_argument("--hidden", action="store_true", help="include hidden files")
|
|
528
|
+
common.add_argument("--apply", action="store_true", help="actually do it (default is a dry run)")
|
|
529
|
+
|
|
530
|
+
parser = argparse.ArgumentParser(
|
|
531
|
+
prog="tidybatch",
|
|
532
|
+
description="Bulk rename files safely. Dry run by default; every change can be undone.",
|
|
533
|
+
epilog="Need to sort folders or remove duplicates? TidyBatch Pro adds `organize` and `dedupe`: https://whop.com/tidybatch/bulk-file-renamer/",
|
|
534
|
+
)
|
|
535
|
+
parser.add_argument("--version", action="version", version=f"%(prog)s {__version__}")
|
|
536
|
+
sub = parser.add_subparsers(dest="command", required=True)
|
|
537
|
+
|
|
538
|
+
r = sub.add_parser("rename", parents=[common], help="rename files from a template",
|
|
539
|
+
description="Template fields: {stem} {ext} {n} {date} {taken} {today} {parent} {size_kb}. "
|
|
540
|
+
"{date} is the modification time; {taken} is the photo's EXIF date taken "
|
|
541
|
+
"(falls back to {date}). Formats work: {n:03}, {taken:%Y-%m-%d}.")
|
|
542
|
+
r.add_argument("-t", "--template", default="{stem}{ext}", help="new name template (default: {stem}{ext})")
|
|
543
|
+
r.add_argument("--find", help="regex to search in the original name (without extension)")
|
|
544
|
+
r.add_argument("--replace", default="", help="replacement for --find (supports \\1 groups)")
|
|
545
|
+
r.add_argument("--slug", action="store_true", help="remove accents, spaces and symbols")
|
|
546
|
+
r.add_argument("--lower", action="store_true", help="lowercase the whole name")
|
|
547
|
+
r.add_argument("--sort", choices=["name", "date", "taken", "size"], default="name", help="order used for {n}")
|
|
548
|
+
r.add_argument("--start", type=int, default=1, help="first value of {n} (default: 1)")
|
|
549
|
+
|
|
550
|
+
u = sub.add_parser("undo", help="revert the last applied run in a folder")
|
|
551
|
+
u.add_argument("folder", type=Path)
|
|
552
|
+
u.add_argument("--journal", type=Path, help="a specific journal file to revert")
|
|
553
|
+
|
|
554
|
+
for name, what in (("organize", "sort files into folders"), ("dedupe", "move exact duplicates aside")):
|
|
555
|
+
pro = sub.add_parser(name, help=f"[Pro] {what}")
|
|
556
|
+
pro.add_argument("rest", nargs=argparse.REMAINDER, help=argparse.SUPPRESS)
|
|
557
|
+
return parser
|
|
558
|
+
|
|
559
|
+
|
|
560
|
+
def main(argv: list[str] | None = None) -> int:
|
|
561
|
+
# Windows consoles/redirects may use a legacy code page: never crash on a file name.
|
|
562
|
+
for stream in (sys.stdout, sys.stderr):
|
|
563
|
+
if hasattr(stream, "reconfigure"):
|
|
564
|
+
stream.reconfigure(errors="replace")
|
|
565
|
+
args = build_parser().parse_args(argv)
|
|
566
|
+
if args.command in ("organize", "dedupe"):
|
|
567
|
+
# Non-zero so a script calling it never mistakes "not available" for success.
|
|
568
|
+
print(f"`{args.command}` is part of TidyBatch Pro (one-time purchase, includes ready-to-run apps):\n"
|
|
569
|
+
f" https://whop.com/tidybatch/bulk-file-renamer/\n"
|
|
570
|
+
"TidyBatch Core (this version) does `rename` and `undo`.", file=sys.stderr)
|
|
571
|
+
return 2
|
|
572
|
+
root: Path = args.folder.expanduser()
|
|
573
|
+
if not root.is_dir():
|
|
574
|
+
print(f"error: '{root}' is not a folder", file=sys.stderr)
|
|
575
|
+
return 2
|
|
576
|
+
|
|
577
|
+
try:
|
|
578
|
+
if args.command == "undo":
|
|
579
|
+
return undo(root, args.journal)
|
|
580
|
+
|
|
581
|
+
files = sort_files(iter_files(root, args.recursive, args.glob, args.hidden),
|
|
582
|
+
getattr(args, "sort", "name"))
|
|
583
|
+
moves = plan_rename(files, args.template, args.find,
|
|
584
|
+
args.replace, args.slug, args.lower, args.start)
|
|
585
|
+
|
|
586
|
+
show_plan(moves, root, applying=args.apply)
|
|
587
|
+
if not moves:
|
|
588
|
+
return 0
|
|
589
|
+
if not args.apply:
|
|
590
|
+
print("Dry run: nothing was changed. Add --apply to do it.")
|
|
591
|
+
return 0
|
|
592
|
+
journal = apply_moves(moves, root)
|
|
593
|
+
print(f"Done. To revert: tidybatch undo \"{root}\" (journal: {journal.name})")
|
|
594
|
+
return 0
|
|
595
|
+
except TidyError as e:
|
|
596
|
+
print(f"error: {e}", file=sys.stderr)
|
|
597
|
+
return 2
|
|
598
|
+
except KeyboardInterrupt:
|
|
599
|
+
print("\nInterrupted. Files already moved are listed in the journal; run `undo` to revert.", file=sys.stderr)
|
|
600
|
+
return 130
|
|
601
|
+
|
|
602
|
+
|
|
603
|
+
if __name__ == "__main__":
|
|
604
|
+
sys.exit(main())
|