templify-cli 0.1.0__tar.gz → 0.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {templify_cli-0.1.0 → templify_cli-0.2.0}/PKG-INFO +983 -945
- {templify_cli-0.1.0 → templify_cli-0.2.0}/README.md +980 -943
- {templify_cli-0.1.0 → templify_cli-0.2.0}/pyproject.toml +3 -2
- {templify_cli-0.1.0 → templify_cli-0.2.0}/pyproject.toml.orig +75 -80
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/cli/dependencies/data.py +202 -196
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/cli/main.py +230 -165
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/filter_rules.py +382 -366
- {templify_cli-0.1.0 → templify_cli-0.2.0}/LICENSE +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/__init__.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/cli/__init__.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/cli/dependencies/__init__.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/cli/dependencies/console.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/cli/dependencies/template.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/cli/help.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/models.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/py.typed +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/readers.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/transformers.py +0 -0
- {templify_cli-0.1.0 → templify_cli-0.2.0}/src/templify/writers.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: templify-cli
|
|
3
|
-
Version: 0.
|
|
3
|
+
Version: 0.2.0
|
|
4
4
|
Summary: Fill Word, text, Markdown, HTML and JSON templates with Excel or JSON data, from the command line.
|
|
5
5
|
Keywords: template,templating,jinja2,docx,word,excel,mail-merge,document-generation,cli
|
|
6
6
|
Author: aaltatan
|
|
@@ -23,8 +23,9 @@ Classifier: Typing :: Typed
|
|
|
23
23
|
Requires-Dist: docxtpl>=0.20.2
|
|
24
24
|
Requires-Dist: jinja2>=3.1
|
|
25
25
|
Requires-Dist: openpyxl>=3.1.5
|
|
26
|
-
Requires-Dist: pyspecification>=
|
|
26
|
+
Requires-Dist: pyspecification>=4.0.0
|
|
27
27
|
Requires-Dist: rich>=13.0
|
|
28
|
+
Requires-Dist: schemify-cli
|
|
28
29
|
Requires-Dist: typer>=0.27.2
|
|
29
30
|
Requires-Dist: typer-di>=0.1.5
|
|
30
31
|
Requires-Dist: typer-swissknife>=0.1.0
|
|
@@ -35,946 +36,983 @@ Project-URL: Repository, https://github.com/aaltatan/templify
|
|
|
35
36
|
Project-URL: Issues, https://github.com/aaltatan/templify/issues
|
|
36
37
|
Description-Content-Type: text/markdown
|
|
37
38
|
|
|
38
|
-
# templify
|
|
39
|
-
|
|
40
|
-
A command line tool that fills document templates with data.
|
|
41
|
-
|
|
42
|
-
Point it at a **template** (Word, text, Markdown, HTML or JSON) and a **data file** (Excel or JSON). templify renders one file per row, or one file with every row in it. Before rendering, you can **order**, **filter** and **group** the data.
|
|
43
|
-
|
|
44
|
-
```bash
|
|
45
|
-
templify m -t offer.docx -d employees.xlsx -o offers -k name
|
|
46
|
-
```
|
|
47
|
-
|
|
48
|
-
```text
|
|
49
|
-
offers/
|
|
50
|
-
├── Abdullah.docx
|
|
51
|
-
├── Rawaa.docx
|
|
52
|
-
├── Rama.docx
|
|
53
|
-
└── Omar.docx
|
|
54
|
-
```
|
|
55
|
-
|
|
56
|
-
---
|
|
57
|
-
|
|
58
|
-
## Table of contents
|
|
59
|
-
|
|
60
|
-
- [Features](#features)
|
|
61
|
-
- [Installation](#installation)
|
|
62
|
-
- [Quick start](#quick-start)
|
|
63
|
-
- [How it works](#how-it-works)
|
|
64
|
-
- [Commands](#commands)
|
|
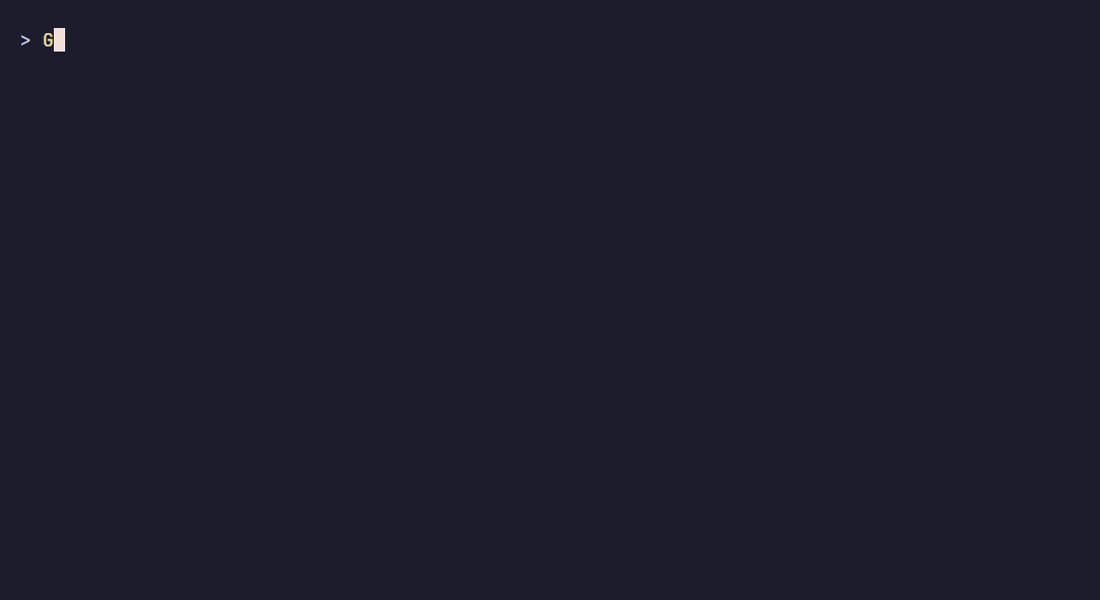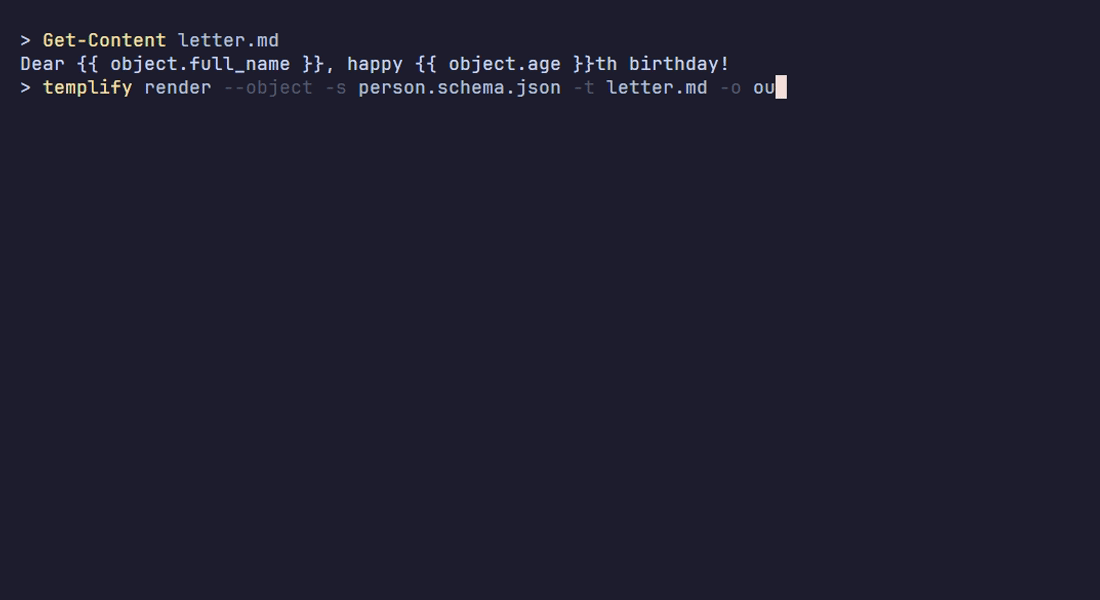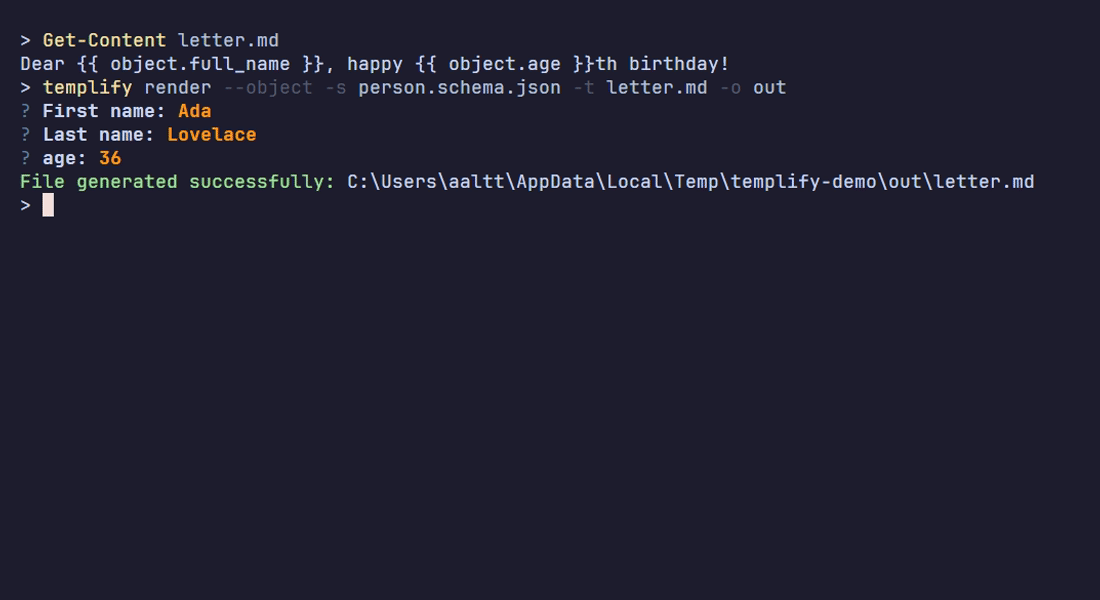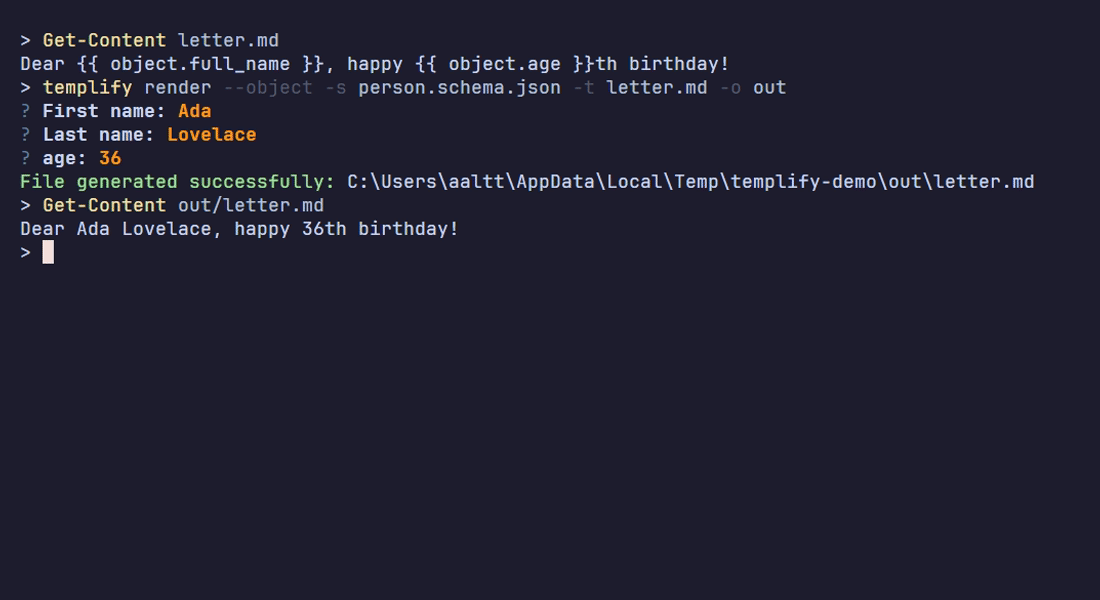
65
|
-
- [`multiple-templates` (`m`)](#multiple-templates-m)
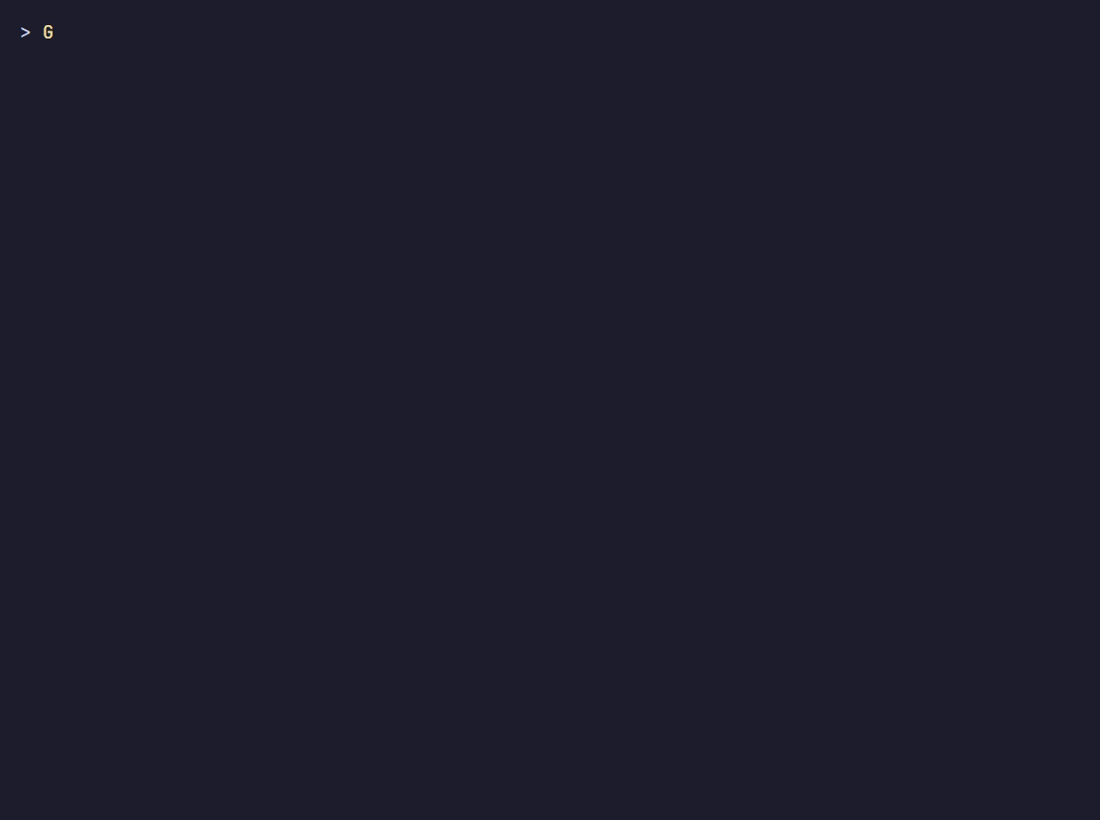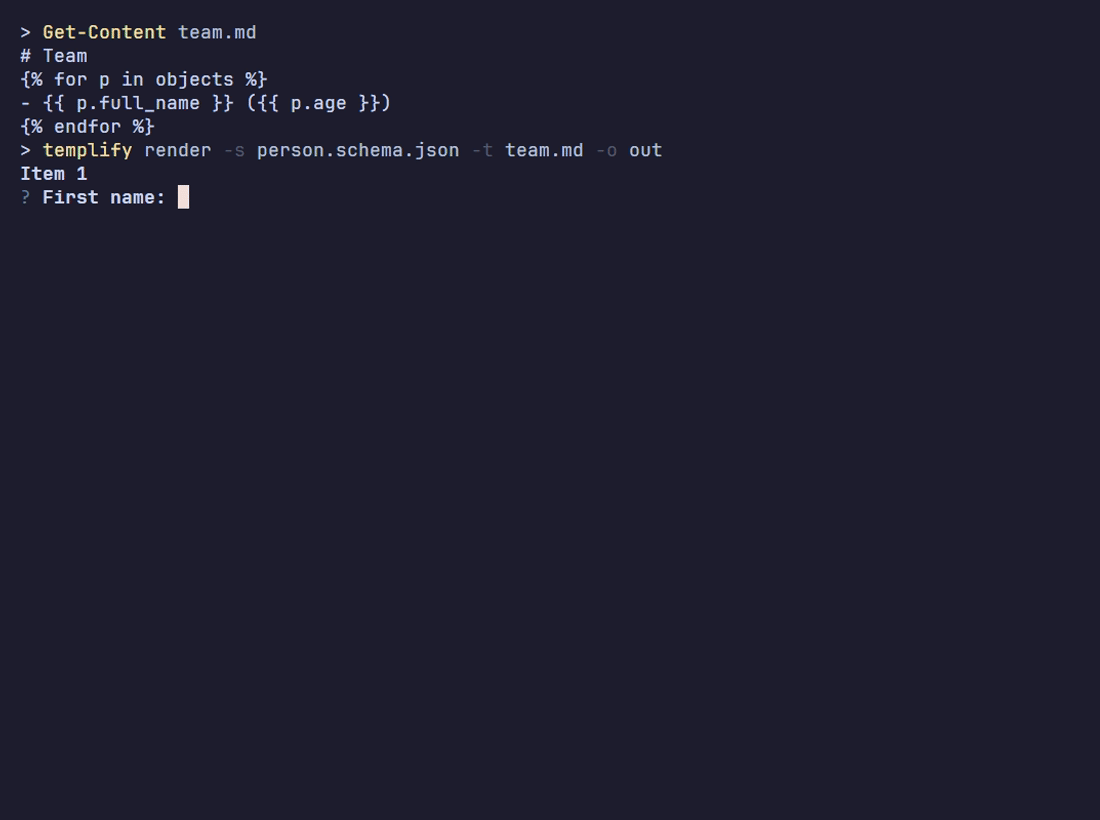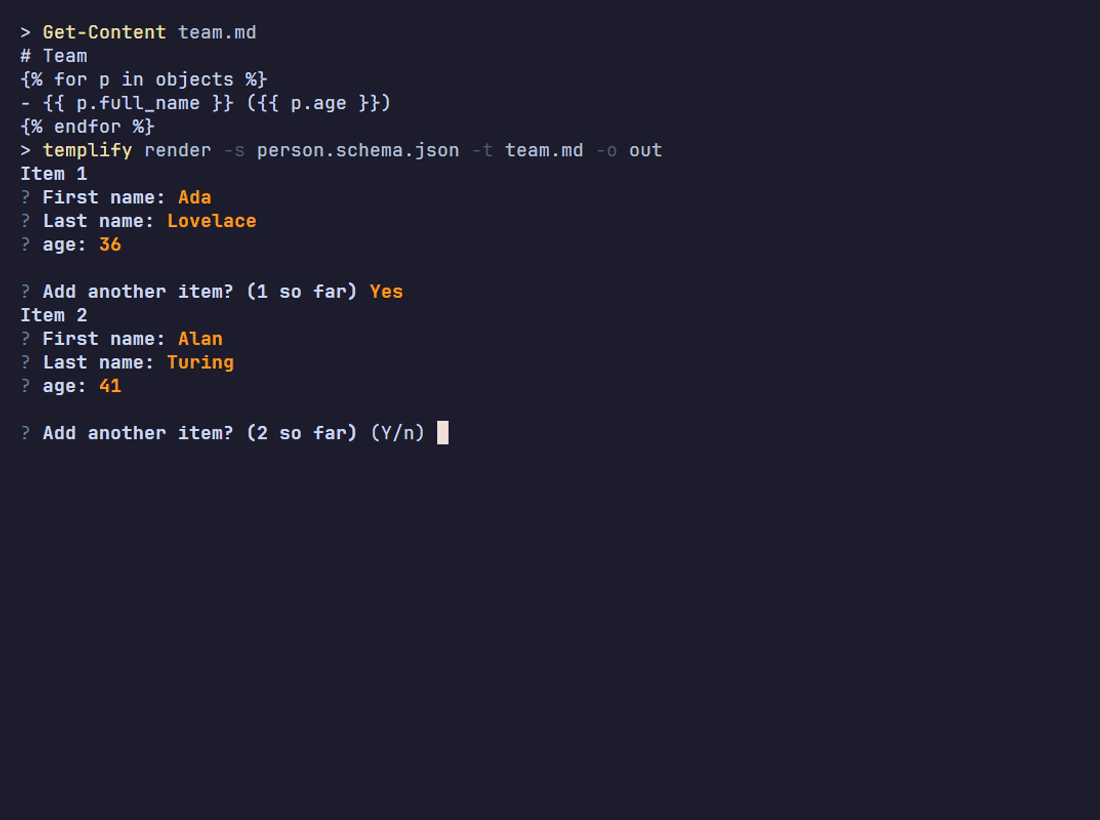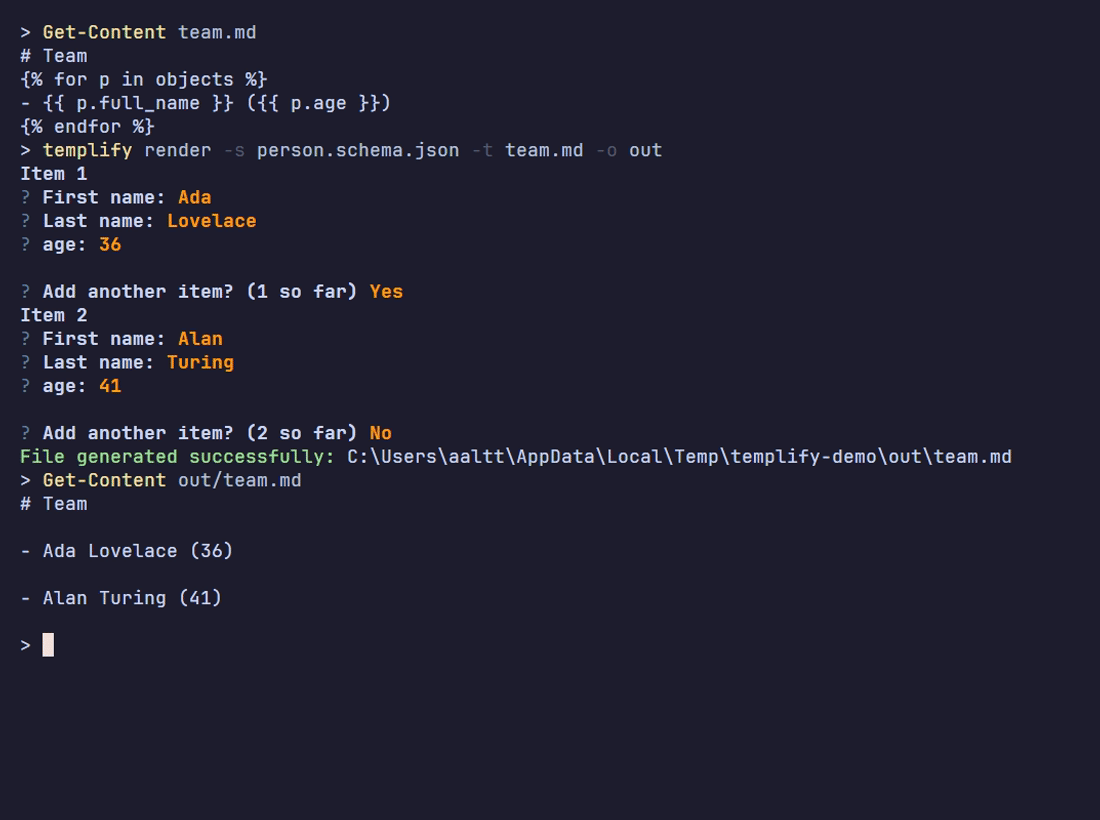
|
|
66
|
-
- [`single-template` (`s`)](#single-template-s)
|
|
67
|
-
- [`
|
|
68
|
-
- [
|
|
69
|
-
- [
|
|
70
|
-
|
|
71
|
-
- [
|
|
72
|
-
- [
|
|
73
|
-
- [
|
|
74
|
-
- [
|
|
75
|
-
- [
|
|
76
|
-
- [
|
|
77
|
-
- [
|
|
78
|
-
- [
|
|
79
|
-
|
|
80
|
-
- [Filter
|
|
81
|
-
- [
|
|
82
|
-
- [
|
|
83
|
-
- [
|
|
84
|
-
- [
|
|
85
|
-
- [
|
|
86
|
-
|
|
87
|
-
|
|
88
|
-
|
|
89
|
-
|
|
90
|
-
|
|
91
|
-
|
|
92
|
-
- **Many
|
|
93
|
-
- **
|
|
94
|
-
- **
|
|
95
|
-
- **
|
|
96
|
-
- **
|
|
97
|
-
- **
|
|
98
|
-
- **
|
|
99
|
-
- **
|
|
100
|
-
- **
|
|
101
|
-
|
|
102
|
-
|
|
103
|
-
|
|
104
|
-
|
|
105
|
-
|
|
106
|
-
|
|
107
|
-
|
|
108
|
-
|
|
109
|
-
|
|
110
|
-
|
|
111
|
-
|
|
112
|
-
|
|
113
|
-
|
|
114
|
-
|
|
115
|
-
|
|
116
|
-
|
|
117
|
-
|
|
118
|
-
|
|
119
|
-
|
|
120
|
-
|
|
121
|
-
|
|
122
|
-
|
|
123
|
-
|
|
124
|
-
|
|
125
|
-
|
|
126
|
-
|
|
127
|
-
|
|
128
|
-
|
|
129
|
-
|
|
130
|
-
|
|
131
|
-
|
|
132
|
-
|
|
133
|
-
|
|
|
134
|
-
|
|
|
135
|
-
|
|
|
136
|
-
|
|
|
137
|
-
|
|
|
138
|
-
|
|
139
|
-
|
|
140
|
-
|
|
141
|
-
|
|
142
|
-
|
|
143
|
-
|
|
144
|
-
|
|
145
|
-
|
|
146
|
-
|
|
147
|
-
|
|
148
|
-
|
|
149
|
-
|
|
150
|
-
|
|
151
|
-
|
|
152
|
-
|
|
153
|
-
|
|
154
|
-
|
|
155
|
-
|
|
156
|
-
|
|
157
|
-
|
|
158
|
-
|
|
159
|
-
|
|
160
|
-
|
|
161
|
-
|
|
162
|
-
|
|
163
|
-
|
|
164
|
-
|
|
165
|
-
|
|
166
|
-
|
|
167
|
-
|
|
168
|
-
|
|
169
|
-
|
|
170
|
-
|
|
171
|
-
|
|
172
|
-
|
|
173
|
-
|
|
174
|
-
|
|
175
|
-
|
|
176
|
-
|
|
177
|
-
- `
|
|
178
|
-
|
|
179
|
-
|
|
180
|
-
|
|
181
|
-
|
|
182
|
-
|
|
183
|
-
|
|
184
|
-
|
|
185
|
-
|
|
186
|
-
|
|
|
187
|
-
|
|
|
188
|
-
| `
|
|
189
|
-
| `
|
|
190
|
-
|
|
191
|
-
|
|
192
|
-
|
|
193
|
-
|
|
194
|
-
|
|
195
|
-
|
|
196
|
-
|
|
197
|
-
|
|
198
|
-
|
|
199
|
-
|
|
200
|
-
|
|
201
|
-
|
|
202
|
-
|
|
|
203
|
-
|
|
|
204
|
-
| `--
|
|
205
|
-
| `--
|
|
206
|
-
| `--
|
|
207
|
-
| `--
|
|
208
|
-
| `--
|
|
209
|
-
| `--
|
|
210
|
-
|
|
211
|
-
|
|
212
|
-
|
|
213
|
-
|
|
214
|
-
|
|
215
|
-
|
|
216
|
-
|
|
217
|
-
|
|
218
|
-
|
|
219
|
-
|
|
220
|
-
|
|
221
|
-
|
|
222
|
-
|
|
223
|
-
|
|
224
|
-
|
|
225
|
-
|
|
226
|
-
|
|
227
|
-
|
|
228
|
-
|
|
229
|
-
|
|
230
|
-
|
|
231
|
-
|
|
232
|
-
|
|
233
|
-
|
|
234
|
-
|
|
235
|
-
|
|
236
|
-
|
|
|
237
|
-
|
|
|
238
|
-
| `--
|
|
239
|
-
| `--data
|
|
240
|
-
| `--
|
|
241
|
-
| `--
|
|
242
|
-
| `--
|
|
243
|
-
| `--
|
|
244
|
-
|
|
245
|
-
|
|
246
|
-
|
|
247
|
-
|
|
248
|
-
|
|
249
|
-
|
|
250
|
-
|
|
251
|
-
|
|
252
|
-
|
|
253
|
-
|
|
|
254
|
-
|
|
255
|
-
|
|
256
|
-
|
|
257
|
-
|
|
258
|
-
|
|
259
|
-
|
|
260
|
-
|
|
261
|
-
|
|
262
|
-
|
|
263
|
-
|
|
264
|
-
|
|
265
|
-
|
|
266
|
-
|
|
267
|
-
|
|
268
|
-
|
|
269
|
-
|
|
270
|
-
|
|
|
271
|
-
|
|
272
|
-
|
|
|
273
|
-
|
|
274
|
-
|
|
275
|
-
|
|
276
|
-
|
|
277
|
-
|
|
278
|
-
|
|
279
|
-
|
|
280
|
-
|
|
281
|
-
|
|
282
|
-
|
|
283
|
-
|
|
284
|
-
|
|
285
|
-
|
|
286
|
-
|
|
287
|
-
|
|
288
|
-
|
|
289
|
-
|
|
290
|
-
|
|
291
|
-
|
|
292
|
-
|
|
293
|
-
|
|
294
|
-
|
|
295
|
-
|
|
296
|
-
|
|
297
|
-
|
|
298
|
-
|
|
299
|
-
|
|
300
|
-
|
|
301
|
-
|
|
302
|
-
|
|
303
|
-
|
|
304
|
-
|
|
305
|
-
|
|
306
|
-
|
|
307
|
-
|
|
308
|
-
|
|
309
|
-
|
|
310
|
-
|
|
311
|
-
|
|
312
|
-
|
|
313
|
-
|
|
314
|
-
|
|
315
|
-
|
|
316
|
-
|
|
317
|
-
|
|
318
|
-
|
|
319
|
-
|
|
320
|
-
|
|
321
|
-
|
|
322
|
-
|
|
323
|
-
|
|
324
|
-
|
|
325
|
-
|
|
326
|
-
|
|
327
|
-
|
|
328
|
-
|
|
329
|
-
|
|
330
|
-
`
|
|
331
|
-
|
|
332
|
-
|
|
333
|
-
|
|
334
|
-
|
|
335
|
-
|
|
336
|
-
|
|
337
|
-
|
|
338
|
-
|
|
339
|
-
|
|
340
|
-
|
|
341
|
-
|
|
342
|
-
|
|
343
|
-
|
|
344
|
-
|
|
345
|
-
|
|
346
|
-
|
|
347
|
-
|
|
348
|
-
|
|
349
|
-
The
|
|
350
|
-
|
|
351
|
-
|
|
352
|
-
|
|
353
|
-
|
|
354
|
-
|
|
355
|
-
|
|
356
|
-
|
|
357
|
-
|
|
358
|
-
|
|
359
|
-
|
|
360
|
-
|
|
361
|
-
|
|
362
|
-
|
|
363
|
-
|
|
364
|
-
|
|
365
|
-
|
|
366
|
-
|
|
367
|
-
|
|
368
|
-
|
|
369
|
-
|
|
370
|
-
|
|
371
|
-
|
|
372
|
-
|
|
373
|
-
|
|
374
|
-
|
|
375
|
-
|
|
376
|
-
|
|
377
|
-
|
|
378
|
-
|
|
379
|
-
|
|
380
|
-
|
|
381
|
-
|
|
382
|
-
|
|
383
|
-
|
|
384
|
-
|
|
|
385
|
-
|
|
|
386
|
-
|
|
387
|
-
|
|
388
|
-
|
|
389
|
-
|
|
390
|
-
|
|
391
|
-
|
|
392
|
-
|
|
393
|
-
|
|
394
|
-
|
|
395
|
-
|
|
396
|
-
`
|
|
397
|
-
|
|
398
|
-
|
|
399
|
-
|
|
400
|
-
|
|
401
|
-
|
|
402
|
-
|
|
403
|
-
|
|
404
|
-
|
|
405
|
-
|
|
|
406
|
-
|
|
|
407
|
-
|
|
408
|
-
|
|
409
|
-
|
|
410
|
-
|
|
411
|
-
|
|
412
|
-
|
|
413
|
-
|
|
414
|
-
|
|
415
|
-
|
|
416
|
-
{{
|
|
417
|
-
{
|
|
418
|
-
|
|
419
|
-
|
|
420
|
-
|
|
421
|
-
|
|
422
|
-
|
|
423
|
-
|
|
424
|
-
|
|
425
|
-
|
|
426
|
-
|
|
427
|
-
|
|
428
|
-
|
|
429
|
-
|
|
430
|
-
|
|
431
|
-
|
|
432
|
-
|
|
433
|
-
|
|
434
|
-
|
|
435
|
-
|
|
436
|
-
|
|
437
|
-
{
|
|
438
|
-
|
|
439
|
-
|
|
440
|
-
|
|
441
|
-
|
|
442
|
-
|
|
443
|
-
|
|
444
|
-
|
|
445
|
-
|
|
446
|
-
|
|
447
|
-
|
|
448
|
-
|
|
449
|
-
|
|
450
|
-
|
|
451
|
-
|
|
452
|
-
|
|
453
|
-
|
|
454
|
-
|
|
455
|
-
|
|
456
|
-
|
|
457
|
-
|
|
458
|
-
|
|
459
|
-
|
|
460
|
-
|
|
461
|
-
|
|
462
|
-
|
|
463
|
-
|
|
464
|
-
|
|
465
|
-
|
|
466
|
-
```
|
|
467
|
-
|
|
468
|
-
|
|
469
|
-
|
|
470
|
-
|
|
471
|
-
|
|
472
|
-
|
|
473
|
-
|
|
474
|
-
|
|
475
|
-
|
|
476
|
-
|
|
477
|
-
|
|
478
|
-
|
|
479
|
-
|
|
480
|
-
|
|
481
|
-
|
|
482
|
-
|
|
483
|
-
|
|
484
|
-
|
|
485
|
-
|
|
486
|
-
|
|
487
|
-
|
|
488
|
-
|
|
489
|
-
|
|
490
|
-
|
|
491
|
-
|
|
492
|
-
|
|
493
|
-
|
|
494
|
-
|
|
495
|
-
|
|
496
|
-
|
|
497
|
-
|
|
498
|
-
|
|
499
|
-
|
|
500
|
-
|
|
501
|
-
|
|
502
|
-
|
|
503
|
-
|
|
504
|
-
|
|
505
|
-
|
|
506
|
-
|
|
507
|
-
|
|
508
|
-
|
|
509
|
-
|
|
510
|
-
|
|
511
|
-
|
|
512
|
-
|
|
513
|
-
|
|
514
|
-
|
|
515
|
-
|
|
516
|
-
|
|
517
|
-
|
|
518
|
-
|
|
519
|
-
|
|
520
|
-
|
|
521
|
-
|
|
522
|
-
|
|
523
|
-
|
|
524
|
-
|
|
525
|
-
|
|
526
|
-
|
|
527
|
-
|
|
528
|
-
templify
|
|
529
|
-
```
|
|
530
|
-
|
|
531
|
-
|
|
532
|
-
|
|
533
|
-
|
|
534
|
-
|
|
535
|
-
|
|
536
|
-
|
|
537
|
-
|
|
538
|
-
|
|
539
|
-
|
|
540
|
-
|
|
541
|
-
|
|
542
|
-
|
|
543
|
-
|
|
544
|
-
|
|
545
|
-
|
|
546
|
-
|
|
547
|
-
|
|
548
|
-
|
|
549
|
-
|
|
550
|
-
|
|
551
|
-
|
|
552
|
-
|
|
553
|
-
|
|
554
|
-
|
|
555
|
-
|
|
556
|
-
|
|
557
|
-
|
|
558
|
-
|
|
559
|
-
|
|
560
|
-
|
|
561
|
-
|
|
562
|
-
|
|
563
|
-
|
|
564
|
-
|
|
565
|
-
|
|
566
|
-
|
|
567
|
-
|
|
568
|
-
|
|
569
|
-
|
|
570
|
-
|
|
571
|
-
|
|
572
|
-
|
|
573
|
-
|
|
574
|
-
|
|
575
|
-
|
|
576
|
-
|
|
577
|
-
|
|
578
|
-
|
|
579
|
-
|
|
580
|
-
|
|
581
|
-
|
|
582
|
-
|
|
583
|
-
|
|
584
|
-
|
|
585
|
-
|
|
586
|
-
|
|
587
|
-
|
|
588
|
-
|
|
589
|
-
|
|
590
|
-
|
|
591
|
-
|
|
592
|
-
|
|
593
|
-
"
|
|
594
|
-
|
|
595
|
-
|
|
596
|
-
|
|
597
|
-
|
|
598
|
-
|
|
599
|
-
|
|
600
|
-
|
|
601
|
-
|
|
602
|
-
|
|
603
|
-
|
|
604
|
-
"
|
|
605
|
-
|
|
606
|
-
|
|
607
|
-
|
|
608
|
-
|
|
609
|
-
|
|
610
|
-
|
|
611
|
-
|
|
612
|
-
|
|
613
|
-
|
|
614
|
-
|
|
615
|
-
|
|
616
|
-
|
|
617
|
-
|
|
618
|
-
|
|
619
|
-
|
|
620
|
-
|
|
621
|
-
|
|
622
|
-
|
|
623
|
-
|
|
624
|
-
|
|
625
|
-
|
|
626
|
-
}
|
|
627
|
-
]
|
|
628
|
-
}'
|
|
629
|
-
# →
|
|
630
|
-
|
|
631
|
-
|
|
632
|
-
|
|
633
|
-
|
|
634
|
-
|
|
635
|
-
|
|
636
|
-
|
|
637
|
-
|
|
638
|
-
|
|
639
|
-
|
|
640
|
-
|
|
641
|
-
|
|
642
|
-
|
|
643
|
-
|
|
644
|
-
|
|
645
|
-
|
|
646
|
-
|
|
647
|
-
|
|
648
|
-
|
|
649
|
-
|
|
650
|
-
|
|
651
|
-
|
|
652
|
-
|
|
653
|
-
|
|
654
|
-
|
|
655
|
-
|
|
656
|
-
|
|
657
|
-
|
|
658
|
-
|
|
659
|
-
|
|
660
|
-
|
|
661
|
-
|
|
662
|
-
|
|
663
|
-
|
|
664
|
-
|
|
665
|
-
|
|
666
|
-
|
|
667
|
-
|
|
668
|
-
|
|
669
|
-
|
|
670
|
-
|
|
671
|
-
|
|
672
|
-
|
|
|
673
|
-
|
|
|
674
|
-
|
|
675
|
-
|
|
676
|
-
|
|
677
|
-
|
|
678
|
-
|
|
679
|
-
|
|
680
|
-
|
|
681
|
-
|
|
682
|
-
|
|
683
|
-
|
|
684
|
-
|
|
685
|
-
|
|
686
|
-
|
|
687
|
-
|
|
688
|
-
|
|
689
|
-
|
|
690
|
-
|
|
691
|
-
|
|
692
|
-
|
|
693
|
-
|
|
694
|
-
|
|
695
|
-
|
|
696
|
-
|
|
697
|
-
|
|
698
|
-
|
|
699
|
-
|
|
700
|
-
|
|
701
|
-
|
|
702
|
-
|
|
703
|
-
|
|
704
|
-
|
|
705
|
-
|
|
706
|
-
|
|
707
|
-
|
|
708
|
-
|
|
709
|
-
|
|
710
|
-
|
|
711
|
-
|
|
712
|
-
|
|
713
|
-
|
|
714
|
-
|
|
715
|
-
|
|
716
|
-
|
|
717
|
-
|
|
718
|
-
|
|
719
|
-
|
|
720
|
-
|
|
721
|
-
|
|
722
|
-
|
|
723
|
-
|
|
724
|
-
|
|
725
|
-
|
|
726
|
-
|
|
727
|
-
|
|
728
|
-
|
|
729
|
-
|
|
730
|
-
|
|
731
|
-
|
|
732
|
-
{name:
|
|
733
|
-
|
|
734
|
-
|
|
735
|
-
|
|
736
|
-
|
|
737
|
-
|
|
738
|
-
|
|
739
|
-
|
|
740
|
-
|
|
741
|
-
|
|
742
|
-
|
|
743
|
-
|
|
744
|
-
|
|
745
|
-
|
|
746
|
-
|
|
747
|
-
|
|
748
|
-
|
|
749
|
-
|
|
750
|
-
|
|
751
|
-
|
|
752
|
-
|
|
753
|
-
|
|
754
|
-
|
|
755
|
-
|
|
756
|
-
|
|
757
|
-
|
|
758
|
-
|
|
759
|
-
|
|
760
|
-
|
|
761
|
-
|
|
762
|
-
|
|
763
|
-
```
|
|
764
|
-
|
|
765
|
-
|
|
766
|
-
|
|
767
|
-
|
|
768
|
-
|
|
769
|
-
|
|
770
|
-
|
|
771
|
-
|
|
772
|
-
|
|
773
|
-
|
|
774
|
-
|
|
775
|
-
|
|
776
|
-
|
|
777
|
-
|
|
778
|
-
|
|
779
|
-
|
|
780
|
-
|
|
781
|
-
|
|
782
|
-
|
|
783
|
-
|
|
784
|
-
|
|
785
|
-
|
|
786
|
-
|
|
787
|
-
|
|
788
|
-
|
|
789
|
-
|
|
790
|
-
|
|
791
|
-
|
|
792
|
-
|
|
793
|
-
```
|
|
794
|
-
|
|
795
|
-
```
|
|
796
|
-
|
|
797
|
-
|
|
798
|
-
|
|
799
|
-
|
|
800
|
-
|
|
801
|
-
|
|
802
|
-
|
|
803
|
-
|
|
804
|
-
|
|
805
|
-
|
|
806
|
-
|
|
807
|
-
|
|
808
|
-
|
|
809
|
-
```
|
|
810
|
-
|
|
811
|
-
**
|
|
812
|
-
|
|
813
|
-
|
|
814
|
-
|
|
815
|
-
|
|
816
|
-
|
|
817
|
-
|
|
818
|
-
|
|
819
|
-
|
|
820
|
-
|
|
821
|
-
|
|
822
|
-
|
|
823
|
-
|
|
824
|
-
|
|
825
|
-
|
|
826
|
-
|
|
827
|
-
|
|
828
|
-
|
|
829
|
-
|
|
830
|
-
|
|
831
|
-
|
|
832
|
-
```
|
|
833
|
-
|
|
834
|
-
|
|
835
|
-
|
|
836
|
-
|
|
837
|
-
|
|
838
|
-
|
|
839
|
-
|
|
840
|
-
|
|
841
|
-
|
|
842
|
-
|
|
843
|
-
|
|
844
|
-
|
|
845
|
-
|
|
846
|
-
|
|
847
|
-
|
|
848
|
-
|
|
849
|
-
|
|
850
|
-
|
|
851
|
-
|
|
852
|
-
|
|
853
|
-
|
|
854
|
-
|
|
855
|
-
|
|
856
|
-
|
|
857
|
-
|
|
858
|
-
|
|
859
|
-
|
|
860
|
-
|
|
861
|
-
|
|
862
|
-
|
|
863
|
-
|
|
864
|
-
|
|
865
|
-
|
|
866
|
-
|
|
867
|
-
|
|
868
|
-
|
|
869
|
-
|
|
870
|
-
|
|
871
|
-
|
|
872
|
-
|
|
873
|
-
|
|
874
|
-
|
|
875
|
-
|
|
876
|
-
|
|
877
|
-
|
|
878
|
-
|
|
879
|
-
|
|
880
|
-
|
|
881
|
-
|
|
882
|
-
|
|
883
|
-
|
|
884
|
-
|
|
885
|
-
|
|
886
|
-
|
|
887
|
-
|
|
888
|
-
|
|
889
|
-
|
|
890
|
-
|
|
891
|
-
|
|
892
|
-
|
|
893
|
-
|
|
894
|
-
|
|
895
|
-
|
|
896
|
-
|
|
897
|
-
|
|
898
|
-
|
|
899
|
-
|
|
900
|
-
|
|
901
|
-
|
|
902
|
-
|
|
903
|
-
A
|
|
904
|
-
|
|
905
|
-
|
|
906
|
-
|
|
907
|
-
|
|
908
|
-
|
|
909
|
-
|
|
910
|
-
|
|
911
|
-
|
|
912
|
-
|
|
913
|
-
|
|
914
|
-
|
|
915
|
-
|
|
916
|
-
|
|
917
|
-
### A new
|
|
918
|
-
|
|
919
|
-
`src/templify/
|
|
920
|
-
|
|
921
|
-
```python
|
|
922
|
-
|
|
923
|
-
def
|
|
924
|
-
|
|
925
|
-
|
|
926
|
-
|
|
927
|
-
|
|
928
|
-
|
|
929
|
-
|
|
930
|
-
|
|
931
|
-
|
|
932
|
-
|
|
933
|
-
|
|
934
|
-
|
|
935
|
-
```
|
|
936
|
-
|
|
937
|
-
|
|
938
|
-
|
|
939
|
-
|
|
940
|
-
|
|
941
|
-
|
|
942
|
-
|
|
943
|
-
|
|
944
|
-
|
|
945
|
-
|
|
946
|
-
|
|
947
|
-
|
|
948
|
-
|
|
949
|
-
|
|
950
|
-
|
|
951
|
-
```
|
|
952
|
-
|
|
953
|
-
|
|
954
|
-
|
|
955
|
-
```
|
|
956
|
-
|
|
957
|
-
|
|
958
|
-
|
|
959
|
-
|
|
960
|
-
|
|
961
|
-
|
|
962
|
-
|
|
963
|
-
|
|
964
|
-
|
|
965
|
-
|
|
966
|
-
|
|
967
|
-
|
|
968
|
-
|
|
969
|
-
|
|
970
|
-
|
|
971
|
-
|
|
972
|
-
|
|
973
|
-
|
|
974
|
-
|
|
975
|
-
|
|
976
|
-
|
|
977
|
-
|
|
978
|
-
|
|
979
|
-
|
|
980
|
-
|
|
39
|
+
# templify
|
|
40
|
+
|
|
41
|
+
A command line tool that fills document templates with data.
|
|
42
|
+
|
|
43
|
+
Point it at a **template** (Word, text, Markdown, HTML or JSON) and a **data file** (Excel or JSON). templify renders one file per row, or one file with every row in it. Before rendering, you can **order**, **filter** and **group** the data.
|
|
44
|
+
|
|
45
|
+
```bash
|
|
46
|
+
templify m -t offer.docx -d employees.xlsx -o offers -k name
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
```text
|
|
50
|
+
offers/
|
|
51
|
+
├── Abdullah.docx
|
|
52
|
+
├── Rawaa.docx
|
|
53
|
+
├── Rama.docx
|
|
54
|
+
└── Omar.docx
|
|
55
|
+
```
|
|
56
|
+
|
|
57
|
+
---
|
|
58
|
+
|
|
59
|
+
## Table of contents
|
|
60
|
+
|
|
61
|
+
- [Features](#features)
|
|
62
|
+
- [Installation](#installation)
|
|
63
|
+
- [Quick start](#quick-start)
|
|
64
|
+
- [How it works](#how-it-works)
|
|
65
|
+
- [Commands](#commands)
|
|
66
|
+
- [`multiple-templates` (`m`)](#multiple-templates-m)
|
|
67
|
+
- [`single-template` (`s`)](#single-template-s)
|
|
68
|
+
- [`schema-template` (`js`) and `schema-list-template` (`jsl`)](#schema-template-js-and-schema-list-template-jsl)
|
|
69
|
+
- [`filters-json-schema` (`fjs`)](#filters-json-schema-fjs)
|
|
70
|
+
- [Data sources](#data-sources)
|
|
71
|
+
- [Templates](#templates)
|
|
72
|
+
- [Supported formats](#supported-formats)
|
|
73
|
+
- [Jinja2 in 60 seconds](#jinja2-in-60-seconds)
|
|
74
|
+
- [Built-in variables](#built-in-variables)
|
|
75
|
+
- [Word (`.docx`) templates](#word-docx-templates)
|
|
76
|
+
- [JSON templates](#json-templates)
|
|
77
|
+
- [HTML templates](#html-templates)
|
|
78
|
+
- [Output files](#output-files)
|
|
79
|
+
- [Ordering](#ordering)
|
|
80
|
+
- [Filtering](#filtering)
|
|
81
|
+
- [Filter schema](#filter-schema)
|
|
82
|
+
- [Filter rules reference](#filter-rules-reference)
|
|
83
|
+
- [Grouping](#grouping)
|
|
84
|
+
- [Cookbook](#cookbook)
|
|
85
|
+
- [Errors](#errors)
|
|
86
|
+
- [Extending templify](#extending-templify)
|
|
87
|
+
- [Development](#development)
|
|
88
|
+
|
|
89
|
+
---
|
|
90
|
+
|
|
91
|
+
## Features
|
|
92
|
+
|
|
93
|
+
- **Many template formats**: `.docx`, `.txt`, `.md`, `.html`, `.htm` and `.json`. The writer is picked automatically from the template's extension.
|
|
94
|
+
- **Many data sources**: Excel (`.xlsx`) and JSON (`.json`).
|
|
95
|
+
- **Two output modes**: one file per row (`multiple-templates`), or every row in one file (`single-template`).
|
|
96
|
+
- **Ordering** by any number of columns, ascending or descending.
|
|
97
|
+
- **Filtering** with a JSON filter language: 50+ rules for strings, numbers, decimals, dates, datetimes and UUIDs. Rules combine with `all` / `any`, nest, and can be inverted.
|
|
98
|
+
- **Grouping** by one or more columns, e.g. one file per department listing its employees.
|
|
99
|
+
- **Safe output**: existing files are never overwritten, invalid filename characters are replaced, and missing folders are created.
|
|
100
|
+
- **Validated JSON output**: a JSON template that renders invalid JSON is rejected before anything is saved.
|
|
101
|
+
- **Clear errors** for bad templates, bad data, unknown columns and bad filters, instead of Python tracebacks.
|
|
102
|
+
- **Extensible**: add a new data reader, template writer or filter rule with one decorator.
|
|
103
|
+
|
|
104
|
+
## Installation
|
|
105
|
+
|
|
106
|
+
Requires **Python 3.12+**.
|
|
107
|
+
|
|
108
|
+
Install it as a global command from PyPI with [uv](https://docs.astral.sh/uv/):
|
|
109
|
+
|
|
110
|
+
```bash
|
|
111
|
+
uv tool install templify-cli
|
|
112
|
+
```
|
|
113
|
+
|
|
114
|
+
or with [pipx](https://pipx.pypa.io/):
|
|
115
|
+
|
|
116
|
+
```bash
|
|
117
|
+
pipx install templify-cli
|
|
118
|
+
```
|
|
119
|
+
|
|
120
|
+
Or run it from a clone without installing:
|
|
121
|
+
|
|
122
|
+
```bash
|
|
123
|
+
uv sync
|
|
124
|
+
```
|
|
125
|
+
|
|
126
|
+
```bash
|
|
127
|
+
uv run templify --help
|
|
128
|
+
```
|
|
129
|
+
|
|
130
|
+
## Quick start
|
|
131
|
+
|
|
132
|
+
**1. Prepare your data**, e.g. `employees.xlsx`. The first row holds the column names:
|
|
133
|
+
|
|
134
|
+
| name | department | city | salary | hired | email |
|
|
135
|
+
| -------- | ---------- | -------- | -----: | ---------- | -------------------- |
|
|
136
|
+
| Abdullah | Sales | Homs | 1200 | 2021-04-01 | abdullah@example.com |
|
|
137
|
+
| Rawaa | IT | Damascus | 1800 | 2023-09-15 | rawaa@example.com |
|
|
138
|
+
| Rama | IT | Homs | 1500 | 2024-02-10 | rama@example.com |
|
|
139
|
+
| Omar | Sales | Aleppo | 1100 | 2024-11-03 | |
|
|
140
|
+
|
|
141
|
+
**2. Write a template** that uses the column names as variables, e.g. `welcome.txt`:
|
|
142
|
+
|
|
143
|
+
```jinja
|
|
144
|
+
Hello {{ name }},
|
|
145
|
+
You joined {{ department }} on {{ hired.strftime("%d/%m/%Y") }}.
|
|
146
|
+
```
|
|
147
|
+
|
|
148
|
+
**3. Run templify:**
|
|
149
|
+
|
|
150
|
+
```bash
|
|
151
|
+
templify m -t welcome.txt -d employees.xlsx -o welcome -k name
|
|
152
|
+
```
|
|
153
|
+
|
|
154
|
+
`welcome/Rama.txt`:
|
|
155
|
+
|
|
156
|
+
```text
|
|
157
|
+
Hello Rama,
|
|
158
|
+
You joined IT on 10/02/2024.
|
|
159
|
+
```
|
|
160
|
+
|
|
161
|
+
> The same data file is used in every example below.
|
|
162
|
+
|
|
163
|
+
## How it works
|
|
164
|
+
|
|
165
|
+
Every command runs the same pipeline:
|
|
166
|
+
|
|
167
|
+
```text
|
|
168
|
+
read data ──► order ──► filter ──► group ──► render template ──► save file(s)
|
|
169
|
+
(-d) (--order) (--filter) (--group-by) (-t) (-o)
|
|
170
|
+
```
|
|
171
|
+
|
|
172
|
+
1. **Read**: the data file becomes a list of rows, each row a set of `column: value` pairs.
|
|
173
|
+
2. **Order**: rows are sorted by `--order` columns (optional).
|
|
174
|
+
3. **Filter**: rows not matching `--filter` are dropped (optional).
|
|
175
|
+
4. **Group**: rows are grouped by `--group-by` columns (optional).
|
|
176
|
+
5. **Render**: the writer chosen from the template extension renders the rows.
|
|
177
|
+
6. **Save**:
|
|
178
|
+
- `multiple-templates` saves one file per row, or per group when grouping.
|
|
179
|
+
- `single-template` saves one file containing every row.
|
|
180
|
+
|
|
181
|
+
## Commands
|
|
182
|
+
|
|
183
|
+
```bash
|
|
184
|
+
templify --help
|
|
185
|
+
```
|
|
186
|
+
|
|
187
|
+
| Command | Aliases | What it does |
|
|
188
|
+
| --------------------- | --------------------- | -------------------------------------------- |
|
|
189
|
+
| `multiple-templates` | `multiple`, `m` | Render **one file per row** (or per group) |
|
|
190
|
+
| `single-template` | `single`, `s` | Render **one file** with all the rows |
|
|
191
|
+
| `schema-template` | `schema`, `js` | Ask for one object from a JSON Schema, render **one file** |
|
|
192
|
+
| `schema-list-template`| `schema-list`, `jsl` | Ask for a list from a JSON Schema, render **one file** |
|
|
193
|
+
| `filters-json-schema` | `filters-schema`, `fjs` | List the filter rules and their arguments |
|
|
194
|
+
|
|
195
|
+
### `multiple-templates` (`m`)
|
|
196
|
+
|
|
197
|
+
Renders the template once **per row**. Each row's columns are the template variables: `{{ name }}`, `{{ salary }}`, ...
|
|
198
|
+
|
|
199
|
+
```bash
|
|
200
|
+
templify m -t <template> -d <data> -o <output-dir> [OPTIONS]
|
|
201
|
+
```
|
|
202
|
+
|
|
203
|
+
| Option | Short | Description | Default |
|
|
204
|
+
| ------------------ | ----- | -------------------------------------------------------------------- | ---------------- |
|
|
205
|
+
| `--template` | `-t` | Template file. **Required.** | |
|
|
206
|
+
| `--data` | `-d` | Data file. **Required.** | |
|
|
207
|
+
| `--output` | `-o` | Output directory, created if missing. **Required.** | |
|
|
208
|
+
| `--filename-key` | `-k` | Column whose value names each file | `template-<n>` |
|
|
209
|
+
| `--index` | `-i` | Prefix each filename with its row number: `1 - Rama.docx` | off |
|
|
210
|
+
| `--order` | | Column to order by, `-column` for descending. Repeatable | |
|
|
211
|
+
| `--filter` | | JSON [filter schema](#filter-schema) | |
|
|
212
|
+
| `--group-by` | | Column to [group](#grouping) by. Repeatable | |
|
|
213
|
+
| `--group-items` | | Variable name holding each group's rows | `items` |
|
|
214
|
+
|
|
215
|
+
Example:
|
|
216
|
+
|
|
217
|
+
```bash
|
|
218
|
+
templify m -t offer.docx -d employees.xlsx -o offers -k name --index
|
|
219
|
+
```
|
|
220
|
+
|
|
221
|
+
```text
|
|
222
|
+
offers/
|
|
223
|
+
├── 1 - Abdullah.docx
|
|
224
|
+
├── 2 - Rawaa.docx
|
|
225
|
+
├── 3 - Rama.docx
|
|
226
|
+
└── 4 - Omar.docx
|
|
227
|
+
```
|
|
228
|
+
|
|
229
|
+
### `single-template` (`s`)
|
|
230
|
+
|
|
231
|
+
Renders the template **once**, with every row in a list variable (`data` by default). The template loops over it.
|
|
232
|
+
|
|
233
|
+
```bash
|
|
234
|
+
templify s -t <template> -d <data> -o <output-dir> [OPTIONS]
|
|
235
|
+
```
|
|
236
|
+
|
|
237
|
+
| Option | Short | Description | Default |
|
|
238
|
+
| ----------------- | ----- | ---------------------------------------------------------- | ---------------------- |
|
|
239
|
+
| `--template` | `-t` | Template file. **Required.** | |
|
|
240
|
+
| `--data` | `-d` | Data file. **Required.** | |
|
|
241
|
+
| `--output` | `-o` | Output directory, created if missing. **Required.** | |
|
|
242
|
+
| `--filename` | `-f` | Output filename **without** extension | the template's name |
|
|
243
|
+
| `--data-variable` | `-v` | Name of the list variable inside the template | `data` |
|
|
244
|
+
| `--order` | | Column to order by, `-column` for descending. Repeatable | |
|
|
245
|
+
| `--filter` | | JSON [filter schema](#filter-schema) | |
|
|
246
|
+
| `--group-by` | | Column to [group](#grouping) by. Repeatable | |
|
|
247
|
+
| `--group-items` | | Variable name holding each group's rows | `items` |
|
|
248
|
+
|
|
249
|
+
Example with `team.md`:
|
|
250
|
+
|
|
251
|
+
```jinja
|
|
252
|
+
# Team report
|
|
253
|
+
|
|
254
|
+
| # | Name | Department | Salary |
|
|
255
|
+
|---|------|------------|-------:|
|
|
256
|
+
{% for e in data -%}
|
|
257
|
+
| {{ loop.index }} | {{ e.name }} | {{ e.department }} | {{ "{:,}".format(e.salary) }} |
|
|
258
|
+
{% endfor %}
|
|
259
|
+
**Total salaries:** {{ data | sum(attribute="salary") }}
|
|
260
|
+
```
|
|
261
|
+
|
|
262
|
+
```bash
|
|
263
|
+
templify s -t team.md -d employees.xlsx -o reports --order -salary
|
|
264
|
+
```
|
|
265
|
+
|
|
266
|
+
`reports/team.md`:
|
|
267
|
+
|
|
268
|
+
```markdown
|
|
269
|
+
# Team report
|
|
270
|
+
|
|
271
|
+
| # | Name | Department | Salary |
|
|
272
|
+
|---|------|------------|-------:|
|
|
273
|
+
| 1 | Rawaa | IT | 1,800 |
|
|
274
|
+
| 2 | Rama | IT | 1,500 |
|
|
275
|
+
| 3 | Abdullah | Sales | 1,200 |
|
|
276
|
+
| 4 | Omar | Sales | 1,100 |
|
|
277
|
+
|
|
278
|
+
**Total salaries:** 5600
|
|
279
|
+
```
|
|
280
|
+
|
|
281
|
+
Rename the output and the loop variable:
|
|
282
|
+
|
|
283
|
+
```bash
|
|
284
|
+
templify s -t team.md -d employees.xlsx -o reports -f "2024 team" -v employees
|
|
285
|
+
```
|
|
286
|
+
|
|
287
|
+
The template then loops with `{% for e in employees %}`, and the file is saved as `reports/2024 team.md`.
|
|
288
|
+
|
|
289
|
+
### `schema-template` (`js`) and `schema-list-template` (`jsl`)
|
|
290
|
+
|
|
291
|
+
No data file: [schemify](https://github.com/aaltatan/schemify-cli) asks for the data matching a
|
|
292
|
+
JSON Schema file, then it is rendered into **one file**. `schema-template` asks for one object,
|
|
293
|
+
`schema-list-template` for a list of them.
|
|
294
|
+
|
|
295
|
+
| Option | Short | Description | Default |
|
|
296
|
+
| ----------------- | ----- | --------------------------------------------------- | ------------------- |
|
|
297
|
+
| `--json-schema` | `--js`| JSON Schema file. **Required.** | |
|
|
298
|
+
| `--template` | `-t` | Template file. **Required.** | |
|
|
299
|
+
| `--output` | `-o` | Output directory, created if missing. **Required.** | |
|
|
300
|
+
| `--filename` | `-f` | Output filename **without** extension | the template's name |
|
|
301
|
+
| `--data-variable` | `-v` | Name of the variable holding the data | `data` |
|
|
302
|
+
|
|
303
|
+
```bash
|
|
304
|
+
templify js --js person.schema.json -t letter.docx -o out # Hello {{ data.name }}
|
|
305
|
+
templify jsl --js person.schema.json -t team.md -o out # {% for p in data %}...{% endfor %}
|
|
306
|
+
```
|
|
307
|
+
|
|
308
|
+
`schema-template` fills one object:
|
|
309
|
+
|
|
310
|
+
|
|
311
|
+
|
|
312
|
+
`schema-list-template` keeps asking for items until you answer **No**:
|
|
313
|
+
|
|
314
|
+
|
|
315
|
+
|
|
316
|
+
### `filters-json-schema` (`fjs`)
|
|
317
|
+
|
|
318
|
+
Lists every filter rule you can use in `--filter`, with its arguments (in `args` order) and description:
|
|
319
|
+
|
|
320
|
+
```bash
|
|
321
|
+
templify fjs
|
|
322
|
+
```
|
|
323
|
+
|
|
324
|
+
```text
|
|
325
|
+
Rule Arguments Description
|
|
326
|
+
is_true key: string Keep records where `key` is `true`.
|
|
327
|
+
is_null key: string Keep records where `key` is empty (`null`).
|
|
328
|
+
int__eq key: string, value: integer Keep records where `key` equals `value`.
|
|
329
|
+
...
|
|
330
|
+
string__regex key: string, pattern: string Keep records where `key` matches the regular expression `pattern`.
|
|
331
|
+
string__is_in key: string, value: list[string] Keep records where `key` is one of the `value` list.
|
|
332
|
+
...
|
|
333
|
+
date__ge key: string, value: date Keep records where `key` is greater than or equal to `value`, comparing the day only.
|
|
334
|
+
...
|
|
335
|
+
```
|
|
336
|
+
|
|
337
|
+
The argument names are also the `kwargs` names: `{"key": "salary", "value": 1400}`.
|
|
338
|
+
|
|
339
|
+
## Data sources
|
|
340
|
+
|
|
341
|
+
The reader is chosen from the data file extension, ignoring case.
|
|
342
|
+
|
|
343
|
+
| Extension | Format |
|
|
344
|
+
| --------- | --------------------------------------------------------------------------- |
|
|
345
|
+
| `.xlsx` | Excel workbook: the **active sheet**, first row = column names |
|
|
346
|
+
| `.json` | A JSON **list of objects**: `[{"name": "Rama", ...}, ...]` |
|
|
347
|
+
|
|
348
|
+
**Excel notes**
|
|
349
|
+
|
|
350
|
+
- The first row holds the column names, and each following row is one record.
|
|
351
|
+
- Fully blank rows are skipped.
|
|
352
|
+
- Formula cells give their **last calculated value**, not the formula text. A file created by a script and never opened in Excel has no calculated values yet, so those cells come back empty.
|
|
353
|
+
- Values keep their type: numbers stay numbers, dates become Python `datetime`s (so `{{ hired.strftime("%Y") }}` works), and empty cells become `None`.
|
|
354
|
+
|
|
355
|
+
**JSON notes**
|
|
356
|
+
|
|
357
|
+
- Must be a list of objects. An object, a list of numbers and so on are rejected with a clear error.
|
|
358
|
+
- Read as UTF-8, so Arabic and other non-Latin text works.
|
|
359
|
+
- JSON has no date type, so dates are strings (`"2024-02-10"`). The [`date__*` filter rules](#dates) understand both forms.
|
|
360
|
+
|
|
361
|
+
`employees.json`:
|
|
362
|
+
|
|
363
|
+
```json
|
|
364
|
+
[
|
|
365
|
+
{
|
|
366
|
+
"name": "Abdullah",
|
|
367
|
+
"department": "Sales",
|
|
368
|
+
"city": "Homs",
|
|
369
|
+
"salary": 1200,
|
|
370
|
+
"hired": "2021-04-01",
|
|
371
|
+
"email": "abdullah@example.com"
|
|
372
|
+
}
|
|
373
|
+
]
|
|
374
|
+
```
|
|
375
|
+
|
|
376
|
+
## Templates
|
|
377
|
+
|
|
378
|
+
### Supported formats
|
|
379
|
+
|
|
380
|
+
The writer is chosen from the **template extension**, ignoring case. The output file gets the same extension.
|
|
381
|
+
|
|
382
|
+
| Extension | Writer | Engine |
|
|
383
|
+
| ----------------------------- | ------------ | ------------------------------------------------ |
|
|
384
|
+
| `.docx` | `DocxWriter` | [docxtpl](https://docxtpl.readthedocs.io/) (Jinja2 inside Word) |
|
|
385
|
+
| `.txt`, `.md`, `.html`, `.htm` | `TextWriter` | [Jinja2](https://jinja.palletsprojects.com/) |
|
|
386
|
+
| `.json` | `JsonWriter` | Jinja2 + validates that the output is JSON |
|
|
387
|
+
|
|
388
|
+
Any other extension is rejected, and the error lists the supported ones.
|
|
389
|
+
|
|
390
|
+
### Jinja2 in 60 seconds
|
|
391
|
+
|
|
392
|
+
All templates use [Jinja2](https://jinja.palletsprojects.com/en/stable/templates/) syntax:
|
|
393
|
+
|
|
394
|
+
| Syntax | Meaning |
|
|
395
|
+
| ------------------------------------------ | ---------------------------------------- |
|
|
396
|
+
| `{{ name }}` | Print a variable |
|
|
397
|
+
| `{{ e.name }}` or `{{ e["name"] }}` | Print a field of a row |
|
|
398
|
+
| `{% for e in data %} ... {% endfor %}` | Loop |
|
|
399
|
+
| `{{ loop.index }}` | 1-based loop counter |
|
|
400
|
+
| `{% if salary > 1400 %} ... {% endif %}` | Condition |
|
|
401
|
+
| `{{ name \| upper }}` | Filter: `upper`, `lower`, `title`, `length`, `sum`, `default`, `tojson`, ... |
|
|
402
|
+
| `{{ email or "no email" }}` | Fallback for empty values |
|
|
403
|
+
| `{{ hired.strftime("%d/%m/%Y") }}` | Format an Excel date |
|
|
404
|
+
| `{{ "{:,.2f}".format(salary) }}` | Format a number: `1,200.00` |
|
|
405
|
+
| `{# comment #}` | Comment, not rendered |
|
|
406
|
+
| `{%- ... -%}` | Trim the whitespace around a tag |
|
|
407
|
+
| `{% include "header.txt" %}` | Include another file from the template's folder (text formats) |
|
|
408
|
+
|
|
409
|
+
A variable that doesn't exist renders as an empty string instead of failing.
|
|
410
|
+
|
|
411
|
+
### Built-in variables
|
|
412
|
+
|
|
413
|
+
These are always available, in both modes:
|
|
414
|
+
|
|
415
|
+
| Variable | Value | In `.docx` it becomes |
|
|
416
|
+
| ---------------- | ------ | --------------------- |
|
|
417
|
+
| `{{ new_line }}` | `\n` | a line break |
|
|
418
|
+
| `{{ tab }}` | `\t` | a tab |
|
|
419
|
+
| `{{ page_break }}` | `\f` | a page break |
|
|
420
|
+
|
|
421
|
+
> If your data has a column with one of these names, the built-in value wins.
|
|
422
|
+
|
|
423
|
+
### Word (`.docx`) templates
|
|
424
|
+
|
|
425
|
+
Write Jinja2 tags directly in the Word document. Keep each tag in the **same formatting** (don't bold half of `{{ name }}`), otherwise Word splits it into pieces and Jinja can't read it.
|
|
426
|
+
|
|
427
|
+
`offer.docx`:
|
|
428
|
+
|
|
429
|
+
```text
|
|
430
|
+
Dear {{ name }},
|
|
431
|
+
Welcome to the {{ department }} team in {{ city }}. Your salary is {{ salary }}$.
|
|
432
|
+
```
|
|
433
|
+
|
|
434
|
+
docxtpl adds special tags for Word structure:
|
|
435
|
+
|
|
436
|
+
| Tag | Use |
|
|
437
|
+
| ----------------------------------- | ------------------------------------------------------- |
|
|
438
|
+
| `{%p for e in data %}` ... `{%p endfor %}` | Loop over **paragraphs**: each tag sits on its own paragraph |
|
|
439
|
+
| `{%tr for e in data %}` ... `{%tr endfor %}` | Loop over **table rows**: one row per record |
|
|
440
|
+
| `{%tc ... %}` | Loop over table cells |
|
|
441
|
+
| `{%r ... %}` | Tag applied to a run |
|
|
442
|
+
|
|
443
|
+
**One Word file, one page per employee** (`all-offers.docx`, three paragraphs):
|
|
444
|
+
|
|
445
|
+
```text
|
|
446
|
+
{%p for e in data %}
|
|
447
|
+
{{ e.name }} - {{ e.department }}{{ page_break }}
|
|
448
|
+
{%p endfor %}
|
|
449
|
+
```
|
|
450
|
+
|
|
451
|
+
```bash
|
|
452
|
+
templify s -t all-offers.docx -d employees.xlsx -o offers
|
|
453
|
+
```
|
|
454
|
+
|
|
455
|
+
**A Word table with one row per employee**: create a 2-row table. Put `{%tr for e in data %}` and `{%tr endfor %}` in rows of their own, around a row containing `{{ e.name }}`, `{{ e.salary }}`, ...
|
|
456
|
+
|
|
457
|
+
See the [docxtpl documentation](https://docxtpl.readthedocs.io/) for images, rich text and more.
|
|
458
|
+
|
|
459
|
+
### JSON templates
|
|
460
|
+
|
|
461
|
+
A `.json` template is rendered like text, then **validated**. If the result isn't valid JSON, nothing is saved and you get an error that points at the problem.
|
|
462
|
+
|
|
463
|
+
Always write values through the `tojson` filter. It adds quotes and escapes characters like `"` for you, and turns `None` into `null` and `True` into `true`.
|
|
464
|
+
|
|
465
|
+
`profile.json`:
|
|
466
|
+
|
|
467
|
+
```jinja
|
|
468
|
+
{
|
|
469
|
+
"name": {{ name | tojson }},
|
|
470
|
+
"department": {{ department | tojson }},
|
|
471
|
+
"email": {{ email | tojson }},
|
|
472
|
+
"senior": {{ (salary > 1400) | tojson }}
|
|
473
|
+
}
|
|
474
|
+
```
|
|
475
|
+
|
|
476
|
+
```bash
|
|
477
|
+
templify m -t profile.json -d employees.json -o profiles -k name
|
|
478
|
+
```
|
|
479
|
+
|
|
480
|
+
`profiles/Omar.json`:
|
|
481
|
+
|
|
482
|
+
```json
|
|
483
|
+
{
|
|
484
|
+
"name": "Omar",
|
|
485
|
+
"department": "Sales",
|
|
486
|
+
"email": null,
|
|
487
|
+
"senior": false
|
|
488
|
+
}
|
|
489
|
+
```
|
|
490
|
+
|
|
491
|
+
Dump the whole (ordered / filtered / grouped) dataset:
|
|
492
|
+
|
|
493
|
+
```jinja
|
|
494
|
+
{{ data | tojson(indent=2) }}
|
|
495
|
+
```
|
|
496
|
+
|
|
497
|
+
```bash
|
|
498
|
+
templify s -t all.json -d employees.xlsx -o export -f employees --order name
|
|
499
|
+
```
|
|
500
|
+
|
|
501
|
+
> `tojson` sorts object keys alphabetically.
|
|
502
|
+
|
|
503
|
+
**Why use `tojson`?** With `"name": "{{ name }}"`, a name like `Ra"ma` produces broken JSON:
|
|
504
|
+
|
|
505
|
+
```text
|
|
506
|
+
Invalid value: Template Error: Rendered output is not valid JSON: Expecting ',' delimiter: line 1 column 14 (char 13)
|
|
507
|
+
```
|
|
508
|
+
|
|
509
|
+
### HTML templates
|
|
510
|
+
|
|
511
|
+
`department.html`:
|
|
512
|
+
|
|
513
|
+
```jinja
|
|
514
|
+
<!DOCTYPE html>
|
|
515
|
+
<html>
|
|
516
|
+
<body>
|
|
517
|
+
<h1>{{ department }} department</h1>
|
|
518
|
+
<ul>
|
|
519
|
+
{%- for e in items %}
|
|
520
|
+
<li>{{ e.name }} ({{ e.city }})</li>
|
|
521
|
+
{%- endfor %}
|
|
522
|
+
</ul>
|
|
523
|
+
<p>{{ items | length }} employees</p>
|
|
524
|
+
</body>
|
|
525
|
+
</html>
|
|
526
|
+
```
|
|
527
|
+
|
|
528
|
+
```bash
|
|
529
|
+
templify m -t department.html -d employees.xlsx -o departments --group-by department -k department
|
|
530
|
+
```
|
|
531
|
+
|
|
532
|
+
> Values are **not** HTML-escaped, so `<b>` in your data stays bold. If the data isn't trusted, escape it with `{{ value | e }}`.
|
|
533
|
+
|
|
534
|
+
## Output files
|
|
535
|
+
|
|
536
|
+
| Situation | Result |
|
|
537
|
+
| ------------------------------------------- | --------------------------------------------------- |
|
|
538
|
+
| No `-k` | `template-1.txt`, `template-2.txt`, ... |
|
|
539
|
+
| `-k name` | `Rama.txt` |
|
|
540
|
+
| `-k name -i` | `3 - Rama.txt` |
|
|
541
|
+
| The `-k` column is empty or missing for a row | That row falls back to `template-<n>.txt` |
|
|
542
|
+
| The value has invalid characters: `a/b:c?` | They become `_`: `a_b_c_.txt` |
|
|
543
|
+
| The value is a number: `-k id` | `42.txt` |
|
|
544
|
+
| The file already exists | A short random suffix is added: `Rama-3f9a1c2e.txt`. **Nothing is ever overwritten** |
|
|
545
|
+
| The output folder doesn't exist | It is created, including parent folders |
|
|
546
|
+
| `single-template` without `-f` | Named after the template: `team.md` → `team.md` |
|
|
547
|
+
|
|
548
|
+
Output files are written as **UTF-8**, with the template's line endings kept as they are.
|
|
549
|
+
|
|
550
|
+
## Ordering
|
|
551
|
+
|
|
552
|
+
`--order <column>` sorts ascending, and `--order -<column>` sorts descending. Repeat it to sort by several columns. The first one has the highest priority.
|
|
553
|
+
|
|
554
|
+
```bash
|
|
555
|
+
# highest salary first
|
|
556
|
+
templify s -t names.txt -d employees.xlsx -o out --order -salary
|
|
557
|
+
|
|
558
|
+
# by department A→Z, then by salary high→low inside each department
|
|
559
|
+
templify s -t names.txt -d employees.xlsx -o out --order department --order -salary
|
|
560
|
+
```
|
|
561
|
+
|
|
562
|
+
```text
|
|
563
|
+
Rawaa Rama Abdullah Omar
|
|
564
|
+
```
|
|
565
|
+
|
|
566
|
+
Ordering by a column that doesn't exist fails with the list of available columns.
|
|
567
|
+
|
|
568
|
+
## Filtering
|
|
569
|
+
|
|
570
|
+
`--filter` takes a JSON string that describes which rows to **keep**.
|
|
571
|
+
|
|
572
|
+
> **Quoting on the command line**
|
|
573
|
+
>
|
|
574
|
+
> - **bash / zsh / PowerShell 7.3+**: wrap the JSON in single quotes: `--filter '{"name": ...}'`
|
|
575
|
+
> - **cmd.exe**: escape the inner quotes: `--filter "{\"name\": ...}"`
|
|
576
|
+
|
|
577
|
+
### Filter schema
|
|
578
|
+
|
|
579
|
+
**A single rule** (a *predicate*) has exactly four keys:
|
|
580
|
+
|
|
581
|
+
```json
|
|
582
|
+
{
|
|
583
|
+
"name": "string__eq",
|
|
584
|
+
"args": ["department", "IT"],
|
|
585
|
+
"kwargs": {},
|
|
586
|
+
"inverse": false
|
|
587
|
+
}
|
|
588
|
+
```
|
|
589
|
+
|
|
590
|
+
| Key | Meaning |
|
|
591
|
+
| --------- | ----------------------------------------------------------------------------------- |
|
|
592
|
+
| `name` | Rule name, see the [rules reference](#filter-rules-reference) |
|
|
593
|
+
| `args` | Positional arguments: **the column first**, then the value(s) |
|
|
594
|
+
| `kwargs` | The same arguments by name, e.g. `{"key": "salary", "value": 1400}`. Use `{}` otherwise |
|
|
595
|
+
| `inverse` | `true` negates the rule: "NOT equal", "does NOT contain", ... |
|
|
596
|
+
|
|
597
|
+
```bash
|
|
598
|
+
# IT only
|
|
599
|
+
templify s -t names.txt -d employees.xlsx -o out \
|
|
600
|
+
--filter '{"name": "string__eq", "args": ["department", "IT"], "kwargs": {}, "inverse": false}'
|
|
601
|
+
# → Rawaa Rama
|
|
602
|
+
|
|
603
|
+
# everyone except IT
|
|
604
|
+
templify s -t names.txt -d employees.xlsx -o out \
|
|
605
|
+
--filter '{"name": "string__eq", "args": ["department", "IT"], "kwargs": {}, "inverse": true}'
|
|
606
|
+
# → Abdullah Omar
|
|
607
|
+
|
|
608
|
+
# same rule, arguments by name
|
|
609
|
+
templify s -t names.txt -d employees.xlsx -o out \
|
|
610
|
+
--filter '{"name": "int__gt", "args": [], "kwargs": {"key": "salary", "value": 1400}, "inverse": false}'
|
|
611
|
+
# → Rawaa Rama
|
|
612
|
+
```
|
|
613
|
+
|
|
614
|
+
**Combine rules** with an *expression*: exactly two keys, `operator` and `expressions`.
|
|
615
|
+
|
|
616
|
+
| `operator` | Keeps a row when |
|
|
617
|
+
| ---------- | --------------------------------- |
|
|
618
|
+
| `all` | **every** expression matches (AND) |
|
|
619
|
+
| `any` | **at least one** matches (OR) |
|
|
620
|
+
|
|
621
|
+
```bash
|
|
622
|
+
# in Homs AND earning at least 1300
|
|
623
|
+
templify s -t names.txt -d employees.xlsx -o out --filter '{
|
|
624
|
+
"operator": "all",
|
|
625
|
+
"expressions": [
|
|
626
|
+
{"name": "string__eq", "args": ["city", "Homs"], "kwargs": {}, "inverse": false},
|
|
627
|
+
{"name": "int__ge", "args": ["salary", 1300], "kwargs": {}, "inverse": false}
|
|
628
|
+
]
|
|
629
|
+
}'
|
|
630
|
+
# → Rama
|
|
631
|
+
|
|
632
|
+
# in Aleppo OR earning more than 1700
|
|
633
|
+
templify s -t names.txt -d employees.xlsx -o out --filter '{
|
|
634
|
+
"operator": "any",
|
|
635
|
+
"expressions": [
|
|
636
|
+
{"name": "string__eq", "args": ["city", "Aleppo"], "kwargs": {}, "inverse": false},
|
|
637
|
+
{"name": "int__gt", "args": ["salary", 1700], "kwargs": {}, "inverse": false}
|
|
638
|
+
]
|
|
639
|
+
}'
|
|
640
|
+
# → Rawaa Omar
|
|
641
|
+
```
|
|
642
|
+
|
|
643
|
+
Expressions **nest** to any depth:
|
|
644
|
+
|
|
645
|
+
```bash
|
|
646
|
+
# IT AND (in Damascus OR hired since 2024)
|
|
647
|
+
templify s -t names.txt -d employees.xlsx -o out --filter '{
|
|
648
|
+
"operator": "all",
|
|
649
|
+
"expressions": [
|
|
650
|
+
{"name": "string__eq", "args": ["department", "IT"], "kwargs": {}, "inverse": false},
|
|
651
|
+
{
|
|
652
|
+
"operator": "any",
|
|
653
|
+
"expressions": [
|
|
654
|
+
{"name": "string__eq", "args": ["city", "Damascus"], "kwargs": {}, "inverse": false},
|
|
655
|
+
{"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}
|
|
656
|
+
]
|
|
657
|
+
}
|
|
658
|
+
]
|
|
659
|
+
}'
|
|
660
|
+
# → Rawaa Rama
|
|
661
|
+
```
|
|
662
|
+
|
|
663
|
+
> **Empty cells**: a comparison rule on an empty cell (e.g. `string__endswith` on a missing email) stops with
|
|
664
|
+
> `Filter failed on a data value (empty cell or wrong type?)`. Skip empty cells first by adding
|
|
665
|
+
> `{"name": "is_null", "args": ["email"], "kwargs": {}, "inverse": true}` to an `all` expression.
|
|
666
|
+
|
|
667
|
+
### Filter rules reference
|
|
668
|
+
|
|
669
|
+
The first argument is always the **column**. `value` is converted to the rule's type, so `"5"` works for `int__eq`.
|
|
670
|
+
|
|
671
|
+
#### Boolean & null
|
|
672
|
+
|
|
673
|
+
| Rule | Arguments | Keeps rows where |
|
|
674
|
+
| --------- | ---------- | -------------------------- |
|
|
675
|
+
| `is_true` | `[column]` | the value is `true` |
|
|
676
|
+
| `is_null` | `[column]` | the value is empty / `null` |
|
|
677
|
+
|
|
678
|
+
#### Numbers: `int__*`, `float__*`, `decimal__*`
|
|
679
|
+
|
|
680
|
+
| Suffix | Arguments | Keeps rows where |
|
|
681
|
+
| ------ | ----------------- | ---------------- |
|
|
682
|
+
| `eq` | `[column, value]` | `column == value` |
|
|
683
|
+
| `gt` | `[column, value]` | `column > value` |
|
|
684
|
+
| `ge` | `[column, value]` | `column >= value` |
|
|
685
|
+
| `lt` | `[column, value]` | `column < value` |
|
|
686
|
+
| `le` | `[column, value]` | `column <= value` |
|
|
687
|
+
|
|
688
|
+
For example: `int__ge`, `float__lt` and `decimal__eq`. For `decimal__*`, the value can be a string (`"10.50"`), an integer, or a float rounded to 2 decimals.
|
|
689
|
+
|
|
690
|
+
#### Strings: `string__*`
|
|
691
|
+
|
|
692
|
+
| Rule | Arguments | Keeps rows where |
|
|
693
|
+
| --------------------- | ------------------ | ---------------------------------------- |
|
|
694
|
+
| `string__eq` | `[column, text]` | equals `text` |
|
|
695
|
+
| `string__contains` | `[column, text]` | contains `text` |
|
|
696
|
+
| `string__icontains` | `[column, text]` | contains `text`, ignoring case |
|
|
697
|
+
| `string__startswith` | `[column, text]` | starts with `text` |
|
|
698
|
+
| `string__istartswith` | `[column, text]` | starts with `text`, ignoring case |
|
|
699
|
+
| `string__endswith` | `[column, text]` | ends with `text` |
|
|
700
|
+
| `string__iendswith` | `[column, text]` | ends with `text`, ignoring case |
|
|
701
|
+
| `string__is_in` | `[column, [a, b]]` | is one of the list |
|
|
702
|
+
| `string__iis_in` | `[column, [a, b]]` | is one of the list, ignoring case |
|
|
703
|
+
| `string__regex` | `[column, pattern]` | matches the [regular expression](https://docs.python.org/3/library/re.html) |
|
|
704
|
+
| `string__length_eq` | `[column, n]` | length `== n` (also `_gt`, `_ge`, `_lt`, `_le`) |
|
|
705
|
+
|
|
706
|
+
```bash
|
|
707
|
+
# lives in Homs or Aleppo
|
|
708
|
+
--filter '{"name": "string__is_in", "args": ["city", ["Homs", "Aleppo"]], "kwargs": {}, "inverse": false}'
|
|
709
|
+
# → Abdullah Rama Omar
|
|
710
|
+
|
|
711
|
+
# name starts with "Ra"
|
|
712
|
+
--filter '{"name": "string__regex", "args": ["name", "^Ra"], "kwargs": {}, "inverse": false}'
|
|
713
|
+
# → Rawaa Rama
|
|
714
|
+
```
|
|
715
|
+
|
|
716
|
+
#### Dates: `date__*` <a id="dates"></a>
|
|
717
|
+
|
|
718
|
+
`date__eq`, `date__gt`, `date__ge`, `date__lt`, `date__le`, with arguments `[column, "YYYY-MM-DD"]`.
|
|
719
|
+
|
|
720
|
+
They compare the **day only** and accept every form a date comes in:
|
|
721
|
+
|
|
722
|
+
- Excel date cells, where the time part is ignored
|
|
723
|
+
- ISO strings from JSON: `"2024-02-10"` or `"2024-02-10T08:30:00"`
|
|
724
|
+
|
|
725
|
+
```bash
|
|
726
|
+
# hired in 2024 or later (Excel dates)
|
|
727
|
+
templify s -t names.txt -d employees.xlsx -o out \
|
|
728
|
+
--filter '{"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}'
|
|
729
|
+
# → Rama Omar
|
|
730
|
+
|
|
731
|
+
# hired before 2024 (JSON string dates)
|
|
732
|
+
templify s -t names.txt -d employees.json -o out \
|
|
733
|
+
--filter '{"name": "date__lt", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}'
|
|
734
|
+
# → Abdullah Rawaa
|
|
735
|
+
|
|
736
|
+
# hired during 2024: combine two rules
|
|
737
|
+
--filter '{"operator": "all", "expressions": [
|
|
738
|
+
{"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false},
|
|
739
|
+
{"name": "date__le", "args": ["hired", "2024-12-31"], "kwargs": {}, "inverse": false}
|
|
740
|
+
]}'
|
|
741
|
+
```
|
|
742
|
+
|
|
743
|
+
#### Datetimes: `datetime__*`
|
|
744
|
+
|
|
745
|
+
`datetime__eq`, `datetime__gt`, `datetime__ge`, `datetime__lt`, `datetime__le`, with arguments `[column, "YYYY-MM-DDTHH:MM:SS"]`. They compare down to the second. The column must hold real datetimes, i.e. Excel date cells. For JSON string dates, use `date__*`.
|
|
746
|
+
|
|
747
|
+
#### UUIDs: `uuid__*`
|
|
748
|
+
|
|
749
|
+
`uuid__eq`, `uuid__gt`, `uuid__ge`, `uuid__lt`, `uuid__le`, with arguments `[column, "uuid-string"]`.
|
|
750
|
+
|
|
751
|
+
## Grouping
|
|
752
|
+
|
|
753
|
+
`--group-by <column>` merges rows that share the same value into **one group**. Each group is a new row holding:
|
|
754
|
+
|
|
755
|
+
- the group-by column(s), with the shared value
|
|
756
|
+
- `items` (rename it with `--group-items`), the list of the original rows in that group
|
|
757
|
+
|
|
758
|
+
```text
|
|
759
|
+
rows: groups (--group-by department):
|
|
760
|
+
{name: Abdullah, department: Sales} {department: Sales, items: [Abdullah, Omar]}
|
|
761
|
+
{name: Rawaa, department: IT} ──► {department: IT, items: [Rawaa, Rama]}
|
|
762
|
+
{name: Rama, department: IT}
|
|
763
|
+
{name: Omar, department: Sales}
|
|
764
|
+
```
|
|
765
|
+
|
|
766
|
+
Groups appear in the order their first row appears. Grouping runs **after** ordering and filtering, so `--order` also sorts the rows inside every group, and `--filter` decides which rows get grouped.
|
|
767
|
+
|
|
768
|
+
**One file per group**, with `multiple-templates`: `-k` can name files after the group column.
|
|
769
|
+
|
|
770
|
+
```bash
|
|
771
|
+
templify m -t department.html -d employees.xlsx -o departments --group-by department -k department
|
|
772
|
+
```
|
|
773
|
+
|
|
774
|
+
```text
|
|
775
|
+
departments/
|
|
776
|
+
├── Sales.html
|
|
777
|
+
└── IT.html
|
|
778
|
+
```
|
|
779
|
+
|
|
780
|
+
**One report of all groups**, with `single-template`: loop over groups, then over each group's rows.
|
|
781
|
+
|
|
782
|
+
`by-city.txt`:
|
|
783
|
+
|
|
784
|
+
```jinja
|
|
785
|
+
{% for group in data -%}
|
|
786
|
+
{{ group.city }} / {{ group.department }}:
|
|
787
|
+
{%- for e in group.people %} {{ e.name }}{% endfor %}
|
|
788
|
+
{% endfor %}
|
|
789
|
+
```
|
|
790
|
+
|
|
791
|
+
```bash
|
|
792
|
+
templify s -t by-city.txt -d employees.xlsx -o out \
|
|
793
|
+
--order city --group-by city --group-by department --group-items people
|
|
794
|
+
```
|
|
795
|
+
|
|
796
|
+
```text
|
|
797
|
+
Aleppo / Sales: Omar
|
|
798
|
+
Damascus / IT: Rawaa
|
|
799
|
+
Homs / Sales: Abdullah
|
|
800
|
+
Homs / IT: Rama
|
|
801
|
+
```
|
|
802
|
+
|
|
803
|
+
Useful group-level expressions:
|
|
804
|
+
|
|
805
|
+
```jinja
|
|
806
|
+
{{ items | length }} {# rows in the group #}
|
|
807
|
+
{{ items | sum(attribute="salary") }} {# total of a column #}
|
|
808
|
+
{{ items | map(attribute="name") | join(", ") }} {# "Rawaa, Rama" #}
|
|
809
|
+
{{ (items | sum(attribute="salary")) / (items | length) }} {# average #}
|
|
810
|
+
```
|
|
811
|
+
|
|
812
|
+
**Grouping errors**
|
|
813
|
+
|
|
814
|
+
| Problem | Message |
|
|
815
|
+
| -------------------------------------------------------- | --------------------------------------------------- |
|
|
816
|
+
| The column doesn't exist | `Key 'country' not found in data, Available keys: ...` |
|
|
817
|
+
| `--group-items` equals a group-by column | `Items key 'city' can not be one of the group by keys` |
|
|
818
|
+
| The column holds lists or objects (JSON) | `Can not group by unhashable values ...` |
|
|
819
|
+
|
|
820
|
+
## Cookbook
|
|
821
|
+
|
|
822
|
+
**Offer letters in Word, one per employee, numbered:**
|
|
823
|
+
|
|
824
|
+
```bash
|
|
825
|
+
templify m -t offer.docx -d employees.xlsx -o offers -k name -i
|
|
826
|
+
```
|
|
827
|
+
|
|
828
|
+
**Only employees hired this year, newest first:**
|
|
829
|
+
|
|
830
|
+
```bash
|
|
831
|
+
templify m -t offer.docx -d employees.xlsx -o new-hires -k name --order -hired \
|
|
832
|
+
--filter '{"name": "date__ge", "args": ["hired", "2024-01-01"], "kwargs": {}, "inverse": false}'
|
|
833
|
+
```
|
|
834
|
+
|
|
835
|
+
**Emails only for people who have an email address:**
|
|
836
|
+
|
|
837
|
+
```bash
|
|
838
|
+
templify m -t email.txt -d employees.xlsx -o emails -k email \
|
|
839
|
+
--filter '{"name": "is_null", "args": ["email"], "kwargs": {}, "inverse": true}'
|
|
840
|
+
```
|
|
841
|
+
|
|
842
|
+
**A Markdown salary report per department:**
|
|
843
|
+
|
|
844
|
+
`department.md`:
|
|
845
|
+
|
|
846
|
+
```jinja
|
|
847
|
+
# {{ department }}
|
|
848
|
+
|
|
849
|
+
{% for e in items -%}
|
|
850
|
+
- {{ e.name }}: {{ e.salary }}
|
|
851
|
+
{% endfor %}
|
|
852
|
+
Total: {{ items | sum(attribute="salary") }}
|
|
853
|
+
```
|
|
854
|
+
|
|
855
|
+
```bash
|
|
856
|
+
templify m -t department.md -d employees.xlsx -o reports -k department --group-by department --order -salary
|
|
857
|
+
```
|
|
858
|
+
|
|
859
|
+
**Convert Excel to JSON:**
|
|
860
|
+
|
|
861
|
+
```bash
|
|
862
|
+
templify s -t all.json -d employees.xlsx -o export -f employees
|
|
863
|
+
```
|
|
864
|
+
|
|
865
|
+
with `all.json` containing `{{ data | tojson(indent=2) }}`.
|
|
866
|
+
|
|
867
|
+
**One JSON file per record, for an API import:**
|
|
868
|
+
|
|
869
|
+
```bash
|
|
870
|
+
templify m -t profile.json -d employees.xlsx -o api -k email
|
|
871
|
+
```
|
|
872
|
+
|
|
873
|
+
**A single printable Word file, one page per employee:**
|
|
874
|
+
|
|
875
|
+
```bash
|
|
876
|
+
templify s -t all-offers.docx -d employees.xlsx -o print --order name
|
|
877
|
+
```
|
|
878
|
+
|
|
879
|
+
**Name files with two columns**: templify names files from one column, so add a combined column to your data (an Excel formula like `=A2&" - "&B2` works once the file is saved in Excel), then use `-k full_title`.
|
|
880
|
+
|
|
881
|
+
## Errors
|
|
882
|
+
|
|
883
|
+
templify reports problems as short messages and exits with code `2`:
|
|
884
|
+
|
|
885
|
+
| Problem | Example message |
|
|
886
|
+
| ------------------------------------------------ | ---------------------------------------------------------------------- |
|
|
887
|
+
| Unsupported template extension | `Template extension 'pdf' is not supported, supported: docx, htm, ...` |
|
|
888
|
+
| Unsupported data extension | `Extension csv is not supported` |
|
|
889
|
+
| File doesn't exist / is a folder | `File '...' does not exist.` |
|
|
890
|
+
| Jinja syntax error in the template | `Template Error: unexpected '}'` |
|
|
891
|
+
| Corrupted `.docx` template | `Could not load template 't.docx': ...` |
|
|
892
|
+
| Corrupted `.xlsx` / JSON not a list of objects | `Could not read data file 'data.json': JSON data must be a list of objects` |
|
|
893
|
+
| JSON template rendered invalid JSON | `Template Error: Rendered output is not valid JSON: ...` |
|
|
894
|
+
| `--order` / `--group-by` column doesn't exist | `Key 'salary' not found in data, Available keys: name, age` |
|
|
895
|
+
| `--filter` isn't valid JSON | `Expecting property name enclosed in double quotes: ...` |
|
|
896
|
+
| Unknown filter rule | `Rule 'nope' does not exist. Available rules: is_true, is_null, ...` |
|
|
897
|
+
| Invalid value for a rule | `Argument 'value' with value 'soon' failed to process, ...` |
|
|
898
|
+
| Filter hit an empty cell or wrong type | `Filter failed on a data value (empty cell or wrong type?): ...` |
|
|
899
|
+
|
|
900
|
+
## Extending templify
|
|
901
|
+
|
|
902
|
+
Each extension point is a registry filled with a decorator. Add your code, and the CLI picks it up automatically, including `--help` and the error messages.
|
|
903
|
+
|
|
904
|
+
### A new data source
|
|
905
|
+
|
|
906
|
+
`src/templify/readers.py`: a function that takes a path and returns a list of dicts.
|
|
907
|
+
|
|
908
|
+
```python
|
|
909
|
+
import csv
|
|
910
|
+
|
|
911
|
+
|
|
912
|
+
@readers.reader("csv")
|
|
913
|
+
def read_csv(filepath: Path) -> Data:
|
|
914
|
+
with filepath.open(encoding="utf-8", newline="") as f:
|
|
915
|
+
return list(csv.DictReader(f))
|
|
916
|
+
```
|
|
917
|
+
|
|
918
|
+
### A new template format
|
|
919
|
+
|
|
920
|
+
`src/templify/writers.py`: a class built from the template path that implements the `Writer` protocol, i.e. a `write(context, filepath)` method.
|
|
921
|
+
|
|
922
|
+
```python
|
|
923
|
+
class Writer(Protocol):
|
|
924
|
+
def write(self, context: Context, filepath: Path) -> None: ...
|
|
925
|
+
```
|
|
926
|
+
|
|
927
|
+
Text-based formats can simply be added to `TextWriter`:
|
|
928
|
+
|
|
929
|
+
```python
|
|
930
|
+
@writers.writer("txt", "md", "html", "htm", "xml", "csv")
|
|
931
|
+
class TextWriter: ...
|
|
932
|
+
```
|
|
933
|
+
|
|
934
|
+
A format with its own engine gets its own class:
|
|
935
|
+
|
|
936
|
+
```python
|
|
937
|
+
@writers.writer("pptx")
|
|
938
|
+
class PptxWriter:
|
|
939
|
+
def __init__(self, template_path: Path) -> None:
|
|
940
|
+
self.template_path = template_path
|
|
941
|
+
|
|
942
|
+
def write(self, context: Context, filepath: Path) -> None:
|
|
943
|
+
... # render context into the template and save to filepath
|
|
944
|
+
```
|
|
945
|
+
|
|
946
|
+
A format that needs validation can extend `TextWriter` and override `render`, the way `JsonWriter` does.
|
|
947
|
+
|
|
948
|
+
### A new filter rule
|
|
949
|
+
|
|
950
|
+
`src/templify/filter_rules.py`: the first two parameters are the row and the column. A `Process` marker on a parameter converts the value coming from the filter JSON.
|
|
951
|
+
|
|
952
|
+
```python
|
|
953
|
+
@rules.rule()
|
|
954
|
+
def float__between(d: dict[str, Any], key: str, low: FloatValue, high: FloatValue) -> bool:
|
|
955
|
+
return low <= d[key] <= high
|
|
956
|
+
```
|
|
957
|
+
|
|
958
|
+
```bash
|
|
959
|
+
--filter '{"name": "float__between", "args": ["salary", 1200, 1600], "kwargs": {}, "inverse": false}'
|
|
960
|
+
```
|
|
961
|
+
|
|
962
|
+
## Development
|
|
963
|
+
|
|
964
|
+
```bash
|
|
965
|
+
uv sync
|
|
966
|
+
```
|
|
967
|
+
|
|
968
|
+
Run the tests. Coverage (lines and branches) is printed after every run:
|
|
969
|
+
|
|
970
|
+
```bash
|
|
971
|
+
uv run pytest
|
|
972
|
+
```
|
|
973
|
+
|
|
974
|
+
Lint and format:
|
|
975
|
+
|
|
976
|
+
```bash
|
|
977
|
+
uvx ruff check src tests
|
|
978
|
+
```
|
|
979
|
+
|
|
980
|
+
```bash
|
|
981
|
+
uvx ruff format src tests
|
|
982
|
+
```
|
|
983
|
+
|
|
984
|
+
The demo GIFs are recorded with [VHS](https://github.com/charmbracelet/vhs) (`scoop install vhs`
|
|
985
|
+
or `brew install vhs`) and PowerShell (`pwsh`), from the repository root:
|
|
986
|
+
|
|
987
|
+
```bash
|
|
988
|
+
vhs docs/demo/schema.tape && vhs docs/demo/schema-list.tape
|
|
989
|
+
```
|
|
990
|
+
|
|
991
|
+
### Project structure
|
|
992
|
+
|
|
993
|
+
```text
|
|
994
|
+
src/templify/
|
|
995
|
+
├── models.py # Data / DataItem types
|
|
996
|
+
├── readers.py # data sources: ReaderRegistry, read_excel, read_json
|
|
997
|
+
├── writers.py # Writer protocol, WriterRegistry, Docx/Text/Json writers,
|
|
998
|
+
│ # write_single / write_multiple, file naming
|
|
999
|
+
├── transformers.py # order_by_data, filter_data, group_by_data
|
|
1000
|
+
├── filter_rules.py # every --filter rule
|
|
1001
|
+
└── cli/
|
|
1002
|
+
├── main.py # the commands
|
|
1003
|
+
├── help.py # long --help texts
|
|
1004
|
+
└── dependencies/
|
|
1005
|
+
├── data.py # -d, --order, --filter, --group-by pipeline
|
|
1006
|
+
├── template.py # -t (picks the writer) and -o
|
|
1007
|
+
└── console.py # rich console
|
|
1008
|
+
tests/
|
|
1009
|
+
├── test_readers.py
|
|
1010
|
+
├── test_writers.py
|
|
1011
|
+
├── test_transformers.py
|
|
1012
|
+
├── test_filter_rules.py
|
|
1013
|
+
└── test_cli.py # end-to-end user scenarios
|
|
1014
|
+
```
|
|
1015
|
+
|
|
1016
|
+
## License
|
|
1017
|
+
|
|
1018
|
+
templify is free software, released under the [GNU General Public License v3.0 or later](https://www.gnu.org/licenses/gpl-3.0.html) (see `LICENSE`).
|