task-harbor 0.7.0__tar.gz → 0.8.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- task_harbor-0.8.0/PKG-INFO +134 -0
- task_harbor-0.8.0/README.md +116 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/cli.py +20 -1
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/help.py +7 -0
- task_harbor-0.8.0/opus_manager/onboarding.py +139 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/operator_commands.py +7 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/reporting.py +42 -1
- {task_harbor-0.7.0 → task_harbor-0.8.0}/pyproject.toml +1 -1
- task_harbor-0.8.0/task_harbor.egg-info/PKG-INFO +134 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/task_harbor.egg-info/SOURCES.txt +2 -0
- task_harbor-0.8.0/tests/test_onboarding.py +74 -0
- task_harbor-0.7.0/PKG-INFO +0 -294
- task_harbor-0.7.0/README.md +0 -276
- task_harbor-0.7.0/task_harbor.egg-info/PKG-INFO +0 -294
- {task_harbor-0.7.0 → task_harbor-0.8.0}/LICENSE +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/__init__.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/__main__.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/agent.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/backlog.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/claude.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/codex.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/comparison.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/config.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/contracts.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/desktop_actions.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/evidence.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/gitops.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/models.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/offline.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/orchestrator.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/preflight.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/prompts.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/providers.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/state.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/tui.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/usage.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/opus_manager/verification.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/setup.cfg +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/task_harbor/__init__.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/task_harbor/__main__.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/task_harbor.egg-info/dependency_links.txt +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/task_harbor.egg-info/entry_points.txt +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/task_harbor.egg-info/requires.txt +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/task_harbor.egg-info/top_level.txt +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_backlog.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_claude.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_cli_ui.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_codex.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_desktop_actions.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_gitops.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_hardening.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_offline.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_orchestrator_integration.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_recovery.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_trust_workflows.py +0 -0
- {task_harbor-0.7.0 → task_harbor-0.8.0}/tests/test_tui.py +0 -0
|
@@ -0,0 +1,134 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: task-harbor
|
|
3
|
+
Version: 0.8.0
|
|
4
|
+
Summary: Claude and GPT backlog orchestrator for planning, implementation, QA, escalation, and periodic code review.
|
|
5
|
+
Author: rhit-nayeems
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Repository, https://github.com/rhit-nayeems/task-harbor
|
|
8
|
+
Project-URL: Issues, https://github.com/rhit-nayeems/task-harbor/issues
|
|
9
|
+
Requires-Python: >=3.11
|
|
10
|
+
Description-Content-Type: text/markdown
|
|
11
|
+
License-File: LICENSE
|
|
12
|
+
Requires-Dist: textual<2,>=1
|
|
13
|
+
Provides-Extra: dev
|
|
14
|
+
Requires-Dist: pytest>=8; extra == "dev"
|
|
15
|
+
Provides-Extra: ui
|
|
16
|
+
Requires-Dist: textual<2,>=1; extra == "ui"
|
|
17
|
+
Dynamic: license-file
|
|
18
|
+
|
|
19
|
+
# Task Harbor
|
|
20
|
+
|
|
21
|
+
Run a Markdown backlog with Claude Code or Codex. Task Harbor plans tasks,
|
|
22
|
+
implements them in Git worktrees, runs your checks, and collects the results
|
|
23
|
+
on a local branch for review. It does not push changes.
|
|
24
|
+
|
|
25
|
+
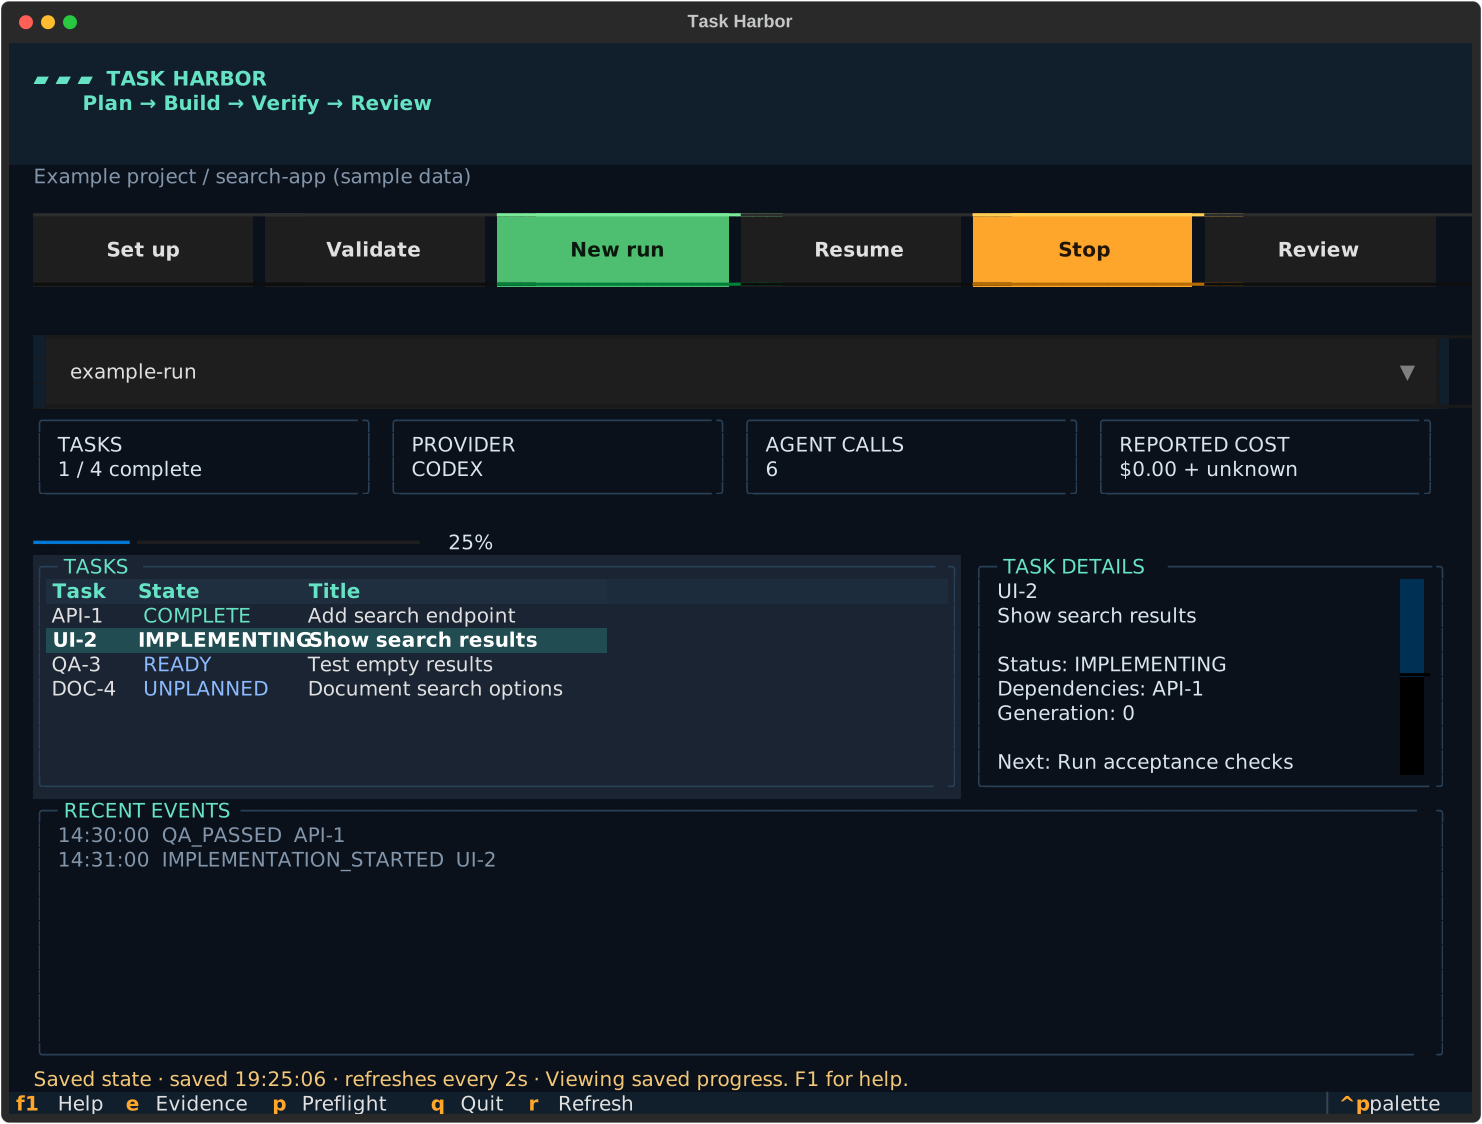
|
|
26
|
+
|
|
27
|
+
## Install
|
|
28
|
+
|
|
29
|
+
Requires Python 3.11+ and Git. To run agent tasks, install and sign in to
|
|
30
|
+
Claude Code or Codex.
|
|
31
|
+
|
|
32
|
+
```sh
|
|
33
|
+
python -m pip install task-harbor
|
|
34
|
+
```
|
|
35
|
+
|
|
36
|
+
Or use `pipx install task-harbor` for an isolated installation.
|
|
37
|
+
If the command isn't on PATH, use `python -m task_harbor` with the same arguments.
|
|
38
|
+
Upgrade with `python -m pip install --upgrade task-harbor` or `pipx upgrade task-harbor`.
|
|
39
|
+
|
|
40
|
+
## Quick start
|
|
41
|
+
|
|
42
|
+
Try a scripted bug fix first. No provider account or model calls are needed;
|
|
43
|
+
the demo creates a separate sample repository and runs real local tests:
|
|
44
|
+
|
|
45
|
+
```sh
|
|
46
|
+
task-harbor demo
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
From a Git repository with at least one commit and a configured Git author:
|
|
50
|
+
|
|
51
|
+
```sh
|
|
52
|
+
task-harbor setup
|
|
53
|
+
```
|
|
54
|
+
|
|
55
|
+
The wizard asks for your provider, model, test command, and call limit. It
|
|
56
|
+
requires verification and defaults to 20 calls per run. It creates
|
|
57
|
+
`.manager/config.json` and a sample `BACKLOG.md`, keeping any existing backlog.
|
|
58
|
+
Replace the sample with your tasks:
|
|
59
|
+
|
|
60
|
+
```markdown
|
|
61
|
+
## BUG-001 — Fix empty search results
|
|
62
|
+
- **Priority:** critical_bug
|
|
63
|
+
- **Status:** UNPLANNED
|
|
64
|
+
- **Dependencies:** —
|
|
65
|
+
- **Acceptance criteria:**
|
|
66
|
+
- An empty search shows a message instead of crashing
|
|
67
|
+
- Existing search tests pass
|
|
68
|
+
- **Next action:** Plan the task
|
|
69
|
+
```
|
|
70
|
+
|
|
71
|
+
You can change these settings in `.manager/config.json`. For GPT, use
|
|
72
|
+
`"provider": "codex"` and set both dollar-budget fields to `null`.
|
|
73
|
+
See [configuration](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/CONFIGURATION.md)
|
|
74
|
+
for the fields and provider setup.
|
|
75
|
+
|
|
76
|
+
For example, add these settings for a Python project:
|
|
77
|
+
|
|
78
|
+
```json
|
|
79
|
+
{
|
|
80
|
+
"verification_commands": ["python -m pytest"],
|
|
81
|
+
"max_agent_calls": 100,
|
|
82
|
+
"max_task_agent_calls": 20
|
|
83
|
+
}
|
|
84
|
+
```
|
|
85
|
+
|
|
86
|
+
Check the setup, then start:
|
|
87
|
+
|
|
88
|
+
```sh
|
|
89
|
+
task-harbor check
|
|
90
|
+
task-harbor manage
|
|
91
|
+
```
|
|
92
|
+
|
|
93
|
+
`check` reads local configuration without calling a model. `manage` starts agent
|
|
94
|
+
work and prints a run ID. Commit your project changes before starting; use
|
|
95
|
+
`task-harbor preflight --run-checks` to test your configured checks first.
|
|
96
|
+
`init` remains available for manual setup; its call limits default to unlimited.
|
|
97
|
+
|
|
98
|
+
Open the dashboard with `task-harbor`. It shows saved runs and task progress;
|
|
99
|
+
F1 opens help. Closing the dashboard does not stop a run.
|
|
100
|
+
|
|
101
|
+
## Review and resume
|
|
102
|
+
|
|
103
|
+
Replace `RUN_ID` with an ID from `task-harbor runs`:
|
|
104
|
+
|
|
105
|
+
```sh
|
|
106
|
+
task-harbor runs
|
|
107
|
+
task-harbor review --run-id RUN_ID --html review.html
|
|
108
|
+
task-harbor stop --run-id RUN_ID
|
|
109
|
+
task-harbor resume --run-id RUN_ID
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
The review report contains task evidence and verification results. Inspect the
|
|
113
|
+
changes on `manager/integration/RUN_ID` before merging into your own branch.
|
|
114
|
+
`stop` pauses after current calls finish; `resume` uses the saved task requirements.
|
|
115
|
+
|
|
116
|
+
Run `task-harbor guide` for setup help or `task-harbor --help` for all commands.
|
|
117
|
+
To work on another directory, put `--repo "path/to/project"` before the command.
|
|
118
|
+
|
|
119
|
+
Agents execute local commands. Git worktrees are not a security sandbox.
|
|
120
|
+
|
|
121
|
+
## Documentation
|
|
122
|
+
|
|
123
|
+
- [Configuration and providers](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/CONFIGURATION.md)
|
|
124
|
+
- [Checks, task agreements, and review](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/VERIFICATION.md)
|
|
125
|
+
- [Compare with a direct agent](https://github.com/rhit-nayeems/task-harbor/blob/main/EVALUATION.md)
|
|
126
|
+
- [Run a pilot](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/PILOT.md)
|
|
127
|
+
- [Architecture](https://github.com/rhit-nayeems/task-harbor/blob/main/ARCHITECTURE.md) · [Technical status](https://github.com/rhit-nayeems/task-harbor/blob/main/TECHNICAL_STATUS.md) · [Changelog](https://github.com/rhit-nayeems/task-harbor/blob/main/CHANGELOG.md)
|
|
128
|
+
|
|
129
|
+
## Contributing
|
|
130
|
+
|
|
131
|
+
Bug reports, fixes, and documentation improvements are welcome.
|
|
132
|
+
See [CONTRIBUTING.md](https://github.com/rhit-nayeems/task-harbor/blob/main/CONTRIBUTING.md) for development setup and tests.
|
|
133
|
+
|
|
134
|
+
[MIT License](https://github.com/rhit-nayeems/task-harbor/blob/main/LICENSE)
|
|
@@ -0,0 +1,116 @@
|
|
|
1
|
+
# Task Harbor
|
|
2
|
+
|
|
3
|
+
Run a Markdown backlog with Claude Code or Codex. Task Harbor plans tasks,
|
|
4
|
+
implements them in Git worktrees, runs your checks, and collects the results
|
|
5
|
+
on a local branch for review. It does not push changes.
|
|
6
|
+
|
|
7
|
+

|
|
8
|
+
|
|
9
|
+
## Install
|
|
10
|
+
|
|
11
|
+
Requires Python 3.11+ and Git. To run agent tasks, install and sign in to
|
|
12
|
+
Claude Code or Codex.
|
|
13
|
+
|
|
14
|
+
```sh
|
|
15
|
+
python -m pip install task-harbor
|
|
16
|
+
```
|
|
17
|
+
|
|
18
|
+
Or use `pipx install task-harbor` for an isolated installation.
|
|
19
|
+
If the command isn't on PATH, use `python -m task_harbor` with the same arguments.
|
|
20
|
+
Upgrade with `python -m pip install --upgrade task-harbor` or `pipx upgrade task-harbor`.
|
|
21
|
+
|
|
22
|
+
## Quick start
|
|
23
|
+
|
|
24
|
+
Try a scripted bug fix first. No provider account or model calls are needed;
|
|
25
|
+
the demo creates a separate sample repository and runs real local tests:
|
|
26
|
+
|
|
27
|
+
```sh
|
|
28
|
+
task-harbor demo
|
|
29
|
+
```
|
|
30
|
+
|
|
31
|
+
From a Git repository with at least one commit and a configured Git author:
|
|
32
|
+
|
|
33
|
+
```sh
|
|
34
|
+
task-harbor setup
|
|
35
|
+
```
|
|
36
|
+
|
|
37
|
+
The wizard asks for your provider, model, test command, and call limit. It
|
|
38
|
+
requires verification and defaults to 20 calls per run. It creates
|
|
39
|
+
`.manager/config.json` and a sample `BACKLOG.md`, keeping any existing backlog.
|
|
40
|
+
Replace the sample with your tasks:
|
|
41
|
+
|
|
42
|
+
```markdown
|
|
43
|
+
## BUG-001 — Fix empty search results
|
|
44
|
+
- **Priority:** critical_bug
|
|
45
|
+
- **Status:** UNPLANNED
|
|
46
|
+
- **Dependencies:** —
|
|
47
|
+
- **Acceptance criteria:**
|
|
48
|
+
- An empty search shows a message instead of crashing
|
|
49
|
+
- Existing search tests pass
|
|
50
|
+
- **Next action:** Plan the task
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
You can change these settings in `.manager/config.json`. For GPT, use
|
|
54
|
+
`"provider": "codex"` and set both dollar-budget fields to `null`.
|
|
55
|
+
See [configuration](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/CONFIGURATION.md)
|
|
56
|
+
for the fields and provider setup.
|
|
57
|
+
|
|
58
|
+
For example, add these settings for a Python project:
|
|
59
|
+
|
|
60
|
+
```json
|
|
61
|
+
{
|
|
62
|
+
"verification_commands": ["python -m pytest"],
|
|
63
|
+
"max_agent_calls": 100,
|
|
64
|
+
"max_task_agent_calls": 20
|
|
65
|
+
}
|
|
66
|
+
```
|
|
67
|
+
|
|
68
|
+
Check the setup, then start:
|
|
69
|
+
|
|
70
|
+
```sh
|
|
71
|
+
task-harbor check
|
|
72
|
+
task-harbor manage
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
`check` reads local configuration without calling a model. `manage` starts agent
|
|
76
|
+
work and prints a run ID. Commit your project changes before starting; use
|
|
77
|
+
`task-harbor preflight --run-checks` to test your configured checks first.
|
|
78
|
+
`init` remains available for manual setup; its call limits default to unlimited.
|
|
79
|
+
|
|
80
|
+
Open the dashboard with `task-harbor`. It shows saved runs and task progress;
|
|
81
|
+
F1 opens help. Closing the dashboard does not stop a run.
|
|
82
|
+
|
|
83
|
+
## Review and resume
|
|
84
|
+
|
|
85
|
+
Replace `RUN_ID` with an ID from `task-harbor runs`:
|
|
86
|
+
|
|
87
|
+
```sh
|
|
88
|
+
task-harbor runs
|
|
89
|
+
task-harbor review --run-id RUN_ID --html review.html
|
|
90
|
+
task-harbor stop --run-id RUN_ID
|
|
91
|
+
task-harbor resume --run-id RUN_ID
|
|
92
|
+
```
|
|
93
|
+
|
|
94
|
+
The review report contains task evidence and verification results. Inspect the
|
|
95
|
+
changes on `manager/integration/RUN_ID` before merging into your own branch.
|
|
96
|
+
`stop` pauses after current calls finish; `resume` uses the saved task requirements.
|
|
97
|
+
|
|
98
|
+
Run `task-harbor guide` for setup help or `task-harbor --help` for all commands.
|
|
99
|
+
To work on another directory, put `--repo "path/to/project"` before the command.
|
|
100
|
+
|
|
101
|
+
Agents execute local commands. Git worktrees are not a security sandbox.
|
|
102
|
+
|
|
103
|
+
## Documentation
|
|
104
|
+
|
|
105
|
+
- [Configuration and providers](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/CONFIGURATION.md)
|
|
106
|
+
- [Checks, task agreements, and review](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/VERIFICATION.md)
|
|
107
|
+
- [Compare with a direct agent](https://github.com/rhit-nayeems/task-harbor/blob/main/EVALUATION.md)
|
|
108
|
+
- [Run a pilot](https://github.com/rhit-nayeems/task-harbor/blob/main/docs/PILOT.md)
|
|
109
|
+
- [Architecture](https://github.com/rhit-nayeems/task-harbor/blob/main/ARCHITECTURE.md) · [Technical status](https://github.com/rhit-nayeems/task-harbor/blob/main/TECHNICAL_STATUS.md) · [Changelog](https://github.com/rhit-nayeems/task-harbor/blob/main/CHANGELOG.md)
|
|
110
|
+
|
|
111
|
+
## Contributing
|
|
112
|
+
|
|
113
|
+
Bug reports, fixes, and documentation improvements are welcome.
|
|
114
|
+
See [CONTRIBUTING.md](https://github.com/rhit-nayeems/task-harbor/blob/main/CONTRIBUTING.md) for development setup and tests.
|
|
115
|
+
|
|
116
|
+
[MIT License](https://github.com/rhit-nayeems/task-harbor/blob/main/LICENSE)
|
|
@@ -27,6 +27,10 @@ def build_parser() -> argparse.ArgumentParser:
|
|
|
27
27
|
description="Run a coding backlog with Claude or GPT. With no command, open the dashboard.",
|
|
28
28
|
formatter_class=argparse.RawDescriptionHelpFormatter,
|
|
29
29
|
epilog="""Quick start (inside your Git repository):
|
|
30
|
+
task-harbor demo Try a scripted example without a provider
|
|
31
|
+
task-harbor setup Guided setup: provider, checks, and call limit
|
|
32
|
+
|
|
33
|
+
Manual setup:
|
|
30
34
|
task-harbor init Create config and sample backlog
|
|
31
35
|
# Edit BACKLOG.md and .manager/config.json
|
|
32
36
|
task-harbor validate Check tasks without model calls
|
|
@@ -39,11 +43,18 @@ Dashboard keys: F1 help, Tab next pane, arrows select, r refresh, q quit.
|
|
|
39
43
|
Python fallback: python -m task_harbor
|
|
40
44
|
""",
|
|
41
45
|
)
|
|
42
|
-
p.add_argument("--version", action="version", version="%(prog)s 0.
|
|
46
|
+
p.add_argument("--version", action="version", version="%(prog)s 0.8.0")
|
|
43
47
|
p.add_argument("--repo", type=_repo, default=Path.cwd(), help="Target Git repository (default: current directory)")
|
|
44
48
|
sub = p.add_subparsers(dest="command")
|
|
45
49
|
p.set_defaults(command="tui", run_id=None)
|
|
46
50
|
sub.add_parser("guide", help="Show setup, usage, and troubleshooting instructions")
|
|
51
|
+
demo = sub.add_parser("demo", help="Try a scripted bug fix with real tests; no provider or account needed")
|
|
52
|
+
demo.add_argument("--output", type=Path, help="New directory for the sample repository (default: a temporary directory)")
|
|
53
|
+
setup = sub.add_parser("setup", help="Configure a first run with required checks and call limits; no model calls")
|
|
54
|
+
setup.add_argument("--provider", choices=["claude", "codex"])
|
|
55
|
+
setup.add_argument("--model", help="Model identifier available in your provider account")
|
|
56
|
+
setup.add_argument("--check", action="append", help="Verification command; repeat for multiple checks")
|
|
57
|
+
setup.add_argument("--max-agent-calls", type=int, help="Run-wide call limit (20 for a new configuration)")
|
|
47
58
|
tui = sub.add_parser("tui", help="Open the live terminal dashboard")
|
|
48
59
|
tui.add_argument("--run-id", help="Select a saved run")
|
|
49
60
|
|
|
@@ -95,6 +106,8 @@ Python fallback: python -m task_harbor
|
|
|
95
106
|
feedback.add_argument("--task", required=True)
|
|
96
107
|
feedback.add_argument("--outcome", choices=["accepted", "rejected", "needs_changes"], required=True)
|
|
97
108
|
feedback.add_argument("--minutes", type=float, required=True)
|
|
109
|
+
feedback.add_argument("--supervision-minutes", type=float, help="Active time preparing/guiding this task, excluding review and repair")
|
|
110
|
+
feedback.add_argument("--repair-minutes", type=float, help="Active time fixing this task, excluding review and supervision")
|
|
98
111
|
feedback.add_argument("--note", default="")
|
|
99
112
|
compare = sub.add_parser("compare", help="Prepare or run an opt-in direct-agent versus Task Harbor comparison")
|
|
100
113
|
compare.add_argument("--manifest", type=Path, required=True)
|
|
@@ -205,6 +218,12 @@ def main(argv: list[str] | None = None) -> int:
|
|
|
205
218
|
from .help import GUIDE
|
|
206
219
|
print(GUIDE)
|
|
207
220
|
return 0
|
|
221
|
+
if args.command == "demo":
|
|
222
|
+
from .onboarding import demo
|
|
223
|
+
return demo(args.output)
|
|
224
|
+
if args.command == "setup":
|
|
225
|
+
from .onboarding import setup
|
|
226
|
+
return setup(repo, args)
|
|
208
227
|
if args.command == "init":
|
|
209
228
|
return cmd_init(repo)
|
|
210
229
|
if getattr(args, "run_id", None) is not None and (not args.run_id or any(c not in "abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ0123456789_-" for c in args.run_id)):
|
|
@@ -1,5 +1,10 @@
|
|
|
1
1
|
GUIDE = """TASK HARBOR — GETTING STARTED
|
|
2
2
|
|
|
3
|
+
Try task-harbor demo first: a separate sample repository, a scripted fix,
|
|
4
|
+
real tests, and an offline review report. No provider account or model calls.
|
|
5
|
+
For guided configuration in your own repository, run task-harbor setup.
|
|
6
|
+
It requires checks and defaults to a 20-call run limit. Manual setup follows:
|
|
7
|
+
|
|
3
8
|
1. Open a terminal in your Git repository (with at least one commit).
|
|
4
9
|
task-harbor init
|
|
5
10
|
2. Edit BACKLOG.md: give each task an ID and acceptance criteria.
|
|
@@ -41,6 +46,8 @@ Press E in the dashboard to inspect a task, P for suggested checks.
|
|
|
41
46
|
task-harbor resume --run-id RUN_ID
|
|
42
47
|
Record your review outcome separately from model QA:
|
|
43
48
|
task-harbor feedback --run-id RUN_ID --task TASK_ID --outcome accepted --minutes 5
|
|
49
|
+
Add --supervision-minutes and --repair-minutes to measure total active effort.
|
|
50
|
+
Omitted values are unknown. Avoid counting the same minutes in multiple entries.
|
|
44
51
|
Compare against a direct agent with an operator-written task manifest:
|
|
45
52
|
task-harbor compare --manifest comparison.json --output prepared
|
|
46
53
|
Preparation calls no models. Add --live with a new output folder to run both arms.
|
|
@@ -0,0 +1,139 @@
|
|
|
1
|
+
"""First-run configuration and an explicitly scripted, provider-free example."""
|
|
2
|
+
from __future__ import annotations
|
|
3
|
+
|
|
4
|
+
import json
|
|
5
|
+
import sys
|
|
6
|
+
import tempfile
|
|
7
|
+
from dataclasses import asdict
|
|
8
|
+
from pathlib import Path
|
|
9
|
+
|
|
10
|
+
from .backlog import render_backlog, write_template
|
|
11
|
+
from .config import Config
|
|
12
|
+
from .evidence import change_evidence
|
|
13
|
+
from .gitops import ensure_local_exclude, ensure_repo, git, head
|
|
14
|
+
from .models import BacklogTask, ManagerState, TaskStatus
|
|
15
|
+
from .offline import read_config
|
|
16
|
+
from .preflight import suggestions
|
|
17
|
+
from .reporting import review_summary, run_report, write_html
|
|
18
|
+
from .state import atomic_write_json, save_state
|
|
19
|
+
from .verification import run_checks
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
def setup(repo: Path, args) -> int:
|
|
23
|
+
ensure_repo(repo)
|
|
24
|
+
cfg = read_config(repo) # Reading an existing configuration must not migrate it yet.
|
|
25
|
+
path = repo / ".manager/config.json"
|
|
26
|
+
existing = json.loads(path.read_text(encoding="utf-8")) if path.exists() else {}
|
|
27
|
+
interactive = sys.stdin.isatty()
|
|
28
|
+
|
|
29
|
+
def choose(value, question, default=None):
|
|
30
|
+
if value is not None:
|
|
31
|
+
return value
|
|
32
|
+
if not interactive:
|
|
33
|
+
if default is not None:
|
|
34
|
+
return default
|
|
35
|
+
raise ValueError("Supply --provider, --model and --check, or run setup in an interactive terminal.")
|
|
36
|
+
answer = input(f"{question}" + (f" [{default}]" if default is not None else "") + ": ").strip()
|
|
37
|
+
return answer or default
|
|
38
|
+
|
|
39
|
+
provider = choose(args.provider, "Provider (claude/codex)", cfg.provider)
|
|
40
|
+
# Do not silently carry a Claude model into a Codex configuration.
|
|
41
|
+
model_default = cfg.model if provider == cfg.provider else None
|
|
42
|
+
model = choose(args.model, "Model available in your account", model_default)
|
|
43
|
+
commands = args.check or cfg.verification_commands
|
|
44
|
+
if not commands:
|
|
45
|
+
hints = suggestions(repo)
|
|
46
|
+
if hints:
|
|
47
|
+
print("Detected commands (not executed): " + ", ".join(hints))
|
|
48
|
+
commands = [choose(None, "Test/check command")]
|
|
49
|
+
if not all(isinstance(c, str) and c.strip() for c in commands):
|
|
50
|
+
raise ValueError("At least one nonempty verification command is required.")
|
|
51
|
+
limit = args.max_agent_calls
|
|
52
|
+
if limit is None:
|
|
53
|
+
limit = int(choose(None, "Maximum agent calls per run", cfg.max_agent_calls or 20))
|
|
54
|
+
values = asdict(cfg)
|
|
55
|
+
values.update(provider=provider, model=model, verification_commands=commands,
|
|
56
|
+
require_verification=True, max_agent_calls=limit)
|
|
57
|
+
if provider != cfg.provider:
|
|
58
|
+
values.update(effort="medium", max_run_cost_usd=None, max_call_cost_usd=None)
|
|
59
|
+
configured = Config(**values) # Validate everything before writing anything.
|
|
60
|
+
ensure_local_exclude(repo, ".manager")
|
|
61
|
+
if configured.manager_dir != ".manager":
|
|
62
|
+
ensure_local_exclude(repo, configured.manager_dir)
|
|
63
|
+
backlog = repo / configured.backlog_file
|
|
64
|
+
if not backlog.exists():
|
|
65
|
+
backlog.parent.mkdir(parents=True, exist_ok=True)
|
|
66
|
+
write_template(backlog)
|
|
67
|
+
atomic_write_json(path, {**existing, **asdict(configured)})
|
|
68
|
+
print(f"Saved {path}. Required checks: {len(commands)}. Run call limit: {limit}.")
|
|
69
|
+
print("Harbor's local files are excluded through Git's local info/exclude; .gitignore was not changed.")
|
|
70
|
+
print(f"1. Replace the sample task in {configured.backlog_file} with one small, observable change.")
|
|
71
|
+
print("2. Run task-harbor check and resolve errors. Authentication is not tested.")
|
|
72
|
+
print("3. Commit your project changes, then run task-harbor preflight --run-checks.")
|
|
73
|
+
print("4. Run task-harbor manage when ready to use your provider account.")
|
|
74
|
+
print("No model calls or verification commands were executed. Call limits are not token or dollar limits.")
|
|
75
|
+
return 0
|
|
76
|
+
|
|
77
|
+
|
|
78
|
+
def demo(output: Path | None = None) -> int:
|
|
79
|
+
repo = output.expanduser().absolute() if output else Path(tempfile.mkdtemp(prefix="task-harbor-demo-"))
|
|
80
|
+
if output:
|
|
81
|
+
repo.mkdir(parents=True, exist_ok=False) # Never overwrite an existing directory.
|
|
82
|
+
print(f"Sample repository: {repo}")
|
|
83
|
+
print("Scripted demonstration: no agents, authentication, or model usage. Tests and Git commits are real.")
|
|
84
|
+
git(repo, "init", "-b", "main")
|
|
85
|
+
git(repo, "config", "user.name", "Task Harbor demo")
|
|
86
|
+
git(repo, "config", "user.email", "demo@example.invalid")
|
|
87
|
+
(repo / ".gitignore").write_text(".manager/\n__pycache__/\nreview.html\n", encoding="utf-8")
|
|
88
|
+
source = repo / "search.py"
|
|
89
|
+
source.write_text("def search(query):\n return query.split()[0]\n", encoding="utf-8")
|
|
90
|
+
(repo / "test_search.py").write_text(
|
|
91
|
+
"import unittest\nfrom search import search\n\nclass SearchTests(unittest.TestCase):\n"
|
|
92
|
+
" def test_empty(self):\n self.assertEqual(search(''), 'No results')\n"
|
|
93
|
+
" def test_normal(self):\n self.assertEqual(search('hello world'), 'hello')\n", encoding="utf-8")
|
|
94
|
+
task = BacklogTask("BUG-001", "Handle an empty search", acceptance_criteria=[
|
|
95
|
+
"Empty queries return 'No results'; normal queries still return their first word."])
|
|
96
|
+
render_backlog(repo / "BACKLOG.md", {task.task_id: task})
|
|
97
|
+
git(repo, "add", ".")
|
|
98
|
+
git(repo, "-c", "commit.gpgsign=false", "commit", "-m", "Sample search with an empty-query bug")
|
|
99
|
+
base = head(repo)
|
|
100
|
+
branch = "manager/integration/demo-001"
|
|
101
|
+
git(repo, "checkout", "-b", branch)
|
|
102
|
+
command = f'"{sys.executable}" -m unittest -v'
|
|
103
|
+
before = run_checks([command], repo, timeout=30, limit=12000)
|
|
104
|
+
print("1. Reproduced the bug: " + ("FAIL (expected)" if before[0]["exit_code"] else "unexpected PASS"))
|
|
105
|
+
source.write_text("def search(query):\n words = query.split()\n return words[0] if words else 'No results'\n", encoding="utf-8")
|
|
106
|
+
git(repo, "add", "search.py")
|
|
107
|
+
git(repo, "-c", "commit.gpgsign=false", "commit", "-m", "Handle empty queries")
|
|
108
|
+
checkpoint = head(repo)
|
|
109
|
+
checks = run_checks([command], repo, timeout=30, limit=12000)
|
|
110
|
+
if before[0]["exit_code"] == 0 or checks[0]["exit_code"] != 0:
|
|
111
|
+
raise RuntimeError("Demo checks did not produce the expected failure followed by a pass; inspect test_search.py.")
|
|
112
|
+
print("2. Applied the scripted fix; both tests pass at the recorded checkpoint.")
|
|
113
|
+
cfg = Config(verification_commands=[command], require_verification=True, max_agent_calls=20)
|
|
114
|
+
run_dir = repo / ".manager/runs/demo-001"
|
|
115
|
+
evidence_path = run_dir / "qa.json"
|
|
116
|
+
atomic_write_json(evidence_path, {
|
|
117
|
+
"checkpoint_commit": checkpoint, "verification_level": "deterministic_checks_only",
|
|
118
|
+
"summary": "The scripted fix handles empty input without changing normal search behavior.",
|
|
119
|
+
"harness_checks": checks, "acceptance": [{"criterion_id": "AC-1", "criterion": task.acceptance_criteria[0],
|
|
120
|
+
"status": "PASS", "evidence": "test_empty and test_normal passed in the local unittest run."}],
|
|
121
|
+
"reproduction": {"before": {"status": "FAIL", "checks": before}, "after": checks},
|
|
122
|
+
"changes": change_evidence(repo, base, checkpoint, cfg),
|
|
123
|
+
"risks": ["Scripted example only. No model QA ran. These two tests do not establish production correctness."]})
|
|
124
|
+
task.status = TaskStatus.COMPLETE
|
|
125
|
+
task.checkpoint_commit = checkpoint
|
|
126
|
+
task.last_qa_path = str(evidence_path)
|
|
127
|
+
task.next_action = "Inspect the diff and record your human review."
|
|
128
|
+
state = ManagerState("demo-001", str(repo), branch, str(repo), "main", base,
|
|
129
|
+
tasks={task.task_id: task}, stop_reason="Scripted demo finished; human review pending.")
|
|
130
|
+
save_state(run_dir / "state.json", state)
|
|
131
|
+
cfg.save(repo / ".manager/config.json")
|
|
132
|
+
report = run_report(run_dir)
|
|
133
|
+
write_html(report, repo / "review.html")
|
|
134
|
+
print("3. Review the evidence:\n" + "\n".join(review_summary(report["tasks"][0], [])))
|
|
135
|
+
print(f'\nOpen {repo / "review.html"} in your browser, or explore the dashboard:')
|
|
136
|
+
print(f'task-harbor --repo "{repo}" tui --run-id demo-001')
|
|
137
|
+
print(f'Full checks and diff: task-harbor --repo "{repo}" review --run-id demo-001')
|
|
138
|
+
print(f'For your own project: task-harbor --repo "path/to/project" setup')
|
|
139
|
+
return 0
|
|
@@ -74,9 +74,16 @@ def run_operator_command(args, repo, cfg):
|
|
|
74
74
|
else:
|
|
75
75
|
if not math.isfinite(args.minutes) or args.minutes < 0:
|
|
76
76
|
raise ValueError("Review minutes must be finite and nonnegative")
|
|
77
|
+
supervision = getattr(args, "supervision_minutes", None)
|
|
78
|
+
repair = getattr(args, "repair_minutes", None)
|
|
79
|
+
if any(value is not None and (not math.isfinite(value) or value < 0) for value in (supervision, repair)):
|
|
80
|
+
raise ValueError("Supervision and repair minutes must be finite and nonnegative")
|
|
77
81
|
path = run_dir / "feedback.json"
|
|
78
82
|
entries = json.loads(path.read_text(encoding="utf-8")) if path.exists() else []
|
|
79
83
|
entries.append({"task": args.task, "outcome": args.outcome, "active_review_minutes": args.minutes,
|
|
84
|
+
"active_supervision_minutes": supervision, "active_repair_minutes": repair,
|
|
85
|
+
"active_engineer_minutes": args.minutes + supervision + repair
|
|
86
|
+
if supervision is not None and repair is not None else None,
|
|
80
87
|
"note": args.note, "checkpoint": task.checkpoint_commit,
|
|
81
88
|
"time": datetime.now(timezone.utc).isoformat()})
|
|
82
89
|
atomic_write_json(path, entries)
|
|
@@ -18,6 +18,41 @@ def task_evidence(run_dir: Path, task) -> dict:
|
|
|
18
18
|
return json.loads(path.read_text(encoding="utf-8"))
|
|
19
19
|
|
|
20
20
|
|
|
21
|
+
def review_summary(task: dict, feedback: list) -> list[str]:
|
|
22
|
+
"""Describe recorded evidence without treating model claims as independent proof."""
|
|
23
|
+
evidence = task["evidence"]
|
|
24
|
+
files = evidence.get("changes", {}).get("files", [])
|
|
25
|
+
checks = evidence.get("harness_checks", [])
|
|
26
|
+
passed = sum(c.get("exit_code") == 0 and not c.get("timed_out") for c in checks)
|
|
27
|
+
checkpoint = evidence.get("checkpoint_commit")
|
|
28
|
+
matching = bool(checkpoint and checkpoint == task.get("checkpoint"))
|
|
29
|
+
lines = ["Changed files: " + (", ".join(f["path"] for f in files) or "No diff evidence recorded."),
|
|
30
|
+
f"Checks: {passed} passed, {len(checks) - passed} failed/timed out, {len(checks)} recorded.",
|
|
31
|
+
"Checkpoint evidence: " + ("matches the task checkpoint." if matching else "missing or does not match; verify before accepting.")]
|
|
32
|
+
if evidence.get("summary"):
|
|
33
|
+
lines.append("Recorded QA summary: " + str(evidence["summary"]))
|
|
34
|
+
acceptance = evidence.get("acceptance", [])
|
|
35
|
+
for index, criterion in enumerate(task.get("acceptance_criteria", []), 1):
|
|
36
|
+
item = next((a for a in acceptance if a.get("criterion_id") == f"AC-{index}" or a.get("criterion") == criterion), {})
|
|
37
|
+
lines.append(f"AC-{index}: {criterion}; recorded {item.get('status', 'NOT VERIFIED')}"
|
|
38
|
+
+ (f"; evidence: {item['evidence']}" if item.get("evidence") else "; no supporting evidence recorded."))
|
|
39
|
+
warnings = [f"{f['path']}: {flag}" for f in files for flag in f.get("warnings", [])]
|
|
40
|
+
if not checks:
|
|
41
|
+
lines.append("Needs attention: no executed checks recorded.")
|
|
42
|
+
for warning in warnings:
|
|
43
|
+
lines.append("Needs attention: " + warning)
|
|
44
|
+
for risk in evidence.get("risks", []):
|
|
45
|
+
lines.append("Needs attention: " + str(risk))
|
|
46
|
+
reviews = [f for f in feedback if f.get("task") == task["id"] and f.get("checkpoint") == task.get("checkpoint") and task.get("checkpoint")]
|
|
47
|
+
lines.append("Human review: " + (reviews[-1]["outcome"] + " for this checkpoint." if reviews else "pending for this checkpoint."))
|
|
48
|
+
if reviews:
|
|
49
|
+
total = reviews[-1].get("active_engineer_minutes")
|
|
50
|
+
lines.append("Recorded engineer time (latest feedback): " + (f"{total:g} minutes." if total is not None
|
|
51
|
+
else "incomplete; include supervision and repair minutes as well as review."))
|
|
52
|
+
lines.append("Next: inspect the diff and acceptance evidence, then record feedback. Passing checks do not prove correctness.")
|
|
53
|
+
return lines
|
|
54
|
+
|
|
55
|
+
|
|
21
56
|
def review_text(report: dict, task_id: str | None = None) -> str:
|
|
22
57
|
lines = [f'Task Harbor review: {report["run_id"]}', f'Branch: {report["integration_branch"]}']
|
|
23
58
|
selected = [t for t in report["tasks"] if task_id is None or t["id"] == task_id]
|
|
@@ -26,6 +61,7 @@ def review_text(report: dict, task_id: str | None = None) -> str:
|
|
|
26
61
|
for task in selected:
|
|
27
62
|
evidence = task["evidence"]
|
|
28
63
|
lines += ["", f'{task["id"]}: {task["title"]}', f'Status: {task["status"]}',
|
|
64
|
+
*review_summary(task, report.get("feedback", [])),
|
|
29
65
|
f'Checkpoint: {evidence.get("checkpoint_commit", "not recorded")}',
|
|
30
66
|
f'Verification: {evidence.get("verification_level", "legacy/unknown")}',
|
|
31
67
|
"Task agreement: " + json.dumps(task["contract"], indent=2),
|
|
@@ -58,6 +94,7 @@ def run_report(run_dir: Path) -> dict:
|
|
|
58
94
|
"dependencies": t.dependencies, "blocked_reason": t.blocked_reason,
|
|
59
95
|
"next_action": t.next_action, "generation": t.generation,
|
|
60
96
|
"checkpoint": t.checkpoint_commit,
|
|
97
|
+
"acceptance_criteria": t.acceptance_criteria,
|
|
61
98
|
"contract": t.metadata.get("contract", {}),
|
|
62
99
|
"evidence": task_evidence(run_dir, t),
|
|
63
100
|
"usage": summarize({"calls": [c for c in usage["calls"] if c.get("task") == t.task_id]})}
|
|
@@ -69,13 +106,17 @@ def write_html(report: dict, output: Path) -> None:
|
|
|
69
106
|
rows = "".join("<tr>" + "".join(f"<td>{esc(t[k])}</td>" for k in
|
|
70
107
|
("id", "title", "status", "blocked_reason", "next_action")) + "</tr>" for t in report["tasks"])
|
|
71
108
|
details = "".join(f'<details><summary>{esc(t["id"])}: {esc(t["title"])}</summary><pre>{esc(review_text(report, t["id"]))}</pre></details>' for t in report["tasks"])
|
|
109
|
+
summaries = "".join(f'<section><h3>{esc(t["id"])}: {esc(t["title"])}</h3><ul>' +
|
|
110
|
+
"".join(f"<li>{esc(line)}</li>" for line in review_summary(t, report.get("feedback", []))) +
|
|
111
|
+
"</ul></section>" for t in report["tasks"])
|
|
72
112
|
output.write_text(f'''<!doctype html><html lang="en"><meta charset="utf-8">
|
|
73
113
|
<meta name="viewport" content="width=device-width, initial-scale=1"><title>Task Harbor · Run report</title>
|
|
74
114
|
<style>body{{font:16px system-ui;margin:3rem;background:#101923;color:#e2eaf2}}h1{{color:#68debf}}
|
|
75
115
|
table{{border-collapse:collapse;width:100%}}td,th{{padding:1rem;text-align:left;border-bottom:1px solid #35414d}}
|
|
76
|
-
pre{{white-space:pre-wrap}}.scroll{{overflow:auto}}p{{line-height:1.7}}</style>
|
|
116
|
+
pre{{white-space:pre-wrap;overflow-wrap:anywhere}}.scroll{{overflow:auto}}p,li{{line-height:1.7}}body{{max-width:1100px;margin:2rem auto;padding:0 1rem}}section{{border:1px solid #35414d;padding:1rem;margin:1rem 0}}li{{overflow-wrap:anywhere}}</style>
|
|
77
117
|
<h1>Task Harbor</h1><p>Run {esc(report["run_id"])} · {report["completed"]}/{report["total"]} complete</p>
|
|
78
118
|
<p>{esc(report["integration_branch"])}<br>{esc(report["stop_reason"])}</p>
|
|
119
|
+
<h2>Review summary</h2>{summaries}
|
|
79
120
|
<h2>Usage</h2><pre>{esc(json.dumps(report["usage"], indent=2))}</pre>
|
|
80
121
|
<p>Costs are CLI estimates. Calls without reported cost are unknown, not free. Snapshot; regenerate to refresh.</p>
|
|
81
122
|
<div class="scroll"><table><thead><tr><th>Task</th><th>Title</th><th>Status</th><th>Blocked</th><th>Next action</th></tr></thead>
|
|
@@ -4,7 +4,7 @@ build-backend = "setuptools.build_meta"
|
|
|
4
4
|
|
|
5
5
|
[project]
|
|
6
6
|
name = "task-harbor"
|
|
7
|
-
version = "0.
|
|
7
|
+
version = "0.8.0"
|
|
8
8
|
description = "Claude and GPT backlog orchestrator for planning, implementation, QA, escalation, and periodic code review."
|
|
9
9
|
requires-python = ">=3.11"
|
|
10
10
|
authors = [{name = "rhit-nayeems"}]
|