stageload 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- stageload-0.1.0/.gitignore +13 -0
- stageload-0.1.0/LICENSE +21 -0
- stageload-0.1.0/PKG-INFO +247 -0
- stageload-0.1.0/README.md +216 -0
- stageload-0.1.0/pyproject.toml +56 -0
- stageload-0.1.0/src/stageload/__init__.py +23 -0
- stageload-0.1.0/src/stageload/__main__.py +3 -0
- stageload-0.1.0/src/stageload/cli.py +108 -0
- stageload-0.1.0/src/stageload/events.py +41 -0
- stageload-0.1.0/src/stageload/guard.py +328 -0
- stageload-0.1.0/src/stageload/hooks.py +50 -0
- stageload-0.1.0/src/stageload/meter.py +225 -0
- stageload-0.1.0/src/stageload/pixal3d/__init__.py +1 -0
- stageload-0.1.0/src/stageload/pixal3d/__main__.py +3 -0
- stageload-0.1.0/src/stageload/pixal3d/cli.py +118 -0
- stageload-0.1.0/src/stageload/pixal3d/plan.py +64 -0
- stageload-0.1.0/src/stageload/pixal3d/port.py +141 -0
- stageload-0.1.0/src/stageload/pixal3d/probe.py +101 -0
- stageload-0.1.0/src/stageload/pixal3d/staged.py +279 -0
- stageload-0.1.0/src/stageload/registry.py +193 -0
- stageload-0.1.0/src/stageload/release.py +129 -0
- stageload-0.1.0/src/stageload/rng.py +45 -0
- stageload-0.1.0/src/stageload/share.py +55 -0
- stageload-0.1.0/src/stageload/trace.py +101 -0
- stageload-0.1.0/src/stageload/units.py +27 -0
- stageload-0.1.0/tests/conftest.py +35 -0
- stageload-0.1.0/tests/fake_port/generate_mps.py +139 -0
- stageload-0.1.0/tests/fake_port/pixal3d/__init__.py +1 -0
- stageload-0.1.0/tests/fake_port/pixal3d/models.py +39 -0
- stageload-0.1.0/tests/fake_port/pixal3d/pipelines.py +167 -0
- stageload-0.1.0/tests/fake_port/pixal3d/trainers/__init__.py +1 -0
- stageload-0.1.0/tests/fake_port/pixal3d/trainers/flow_matching/__init__.py +1 -0
- stageload-0.1.0/tests/fake_port/pixal3d/trainers/flow_matching/mixins/__init__.py +1 -0
- stageload-0.1.0/tests/fake_port/pixal3d/trainers/flow_matching/mixins/image_conditioned_proj.py +41 -0
- stageload-0.1.0/tests/test_bench.py +115 -0
- stageload-0.1.0/tests/test_cli.py +40 -0
- stageload-0.1.0/tests/test_events.py +20 -0
- stageload-0.1.0/tests/test_guard.py +302 -0
- stageload-0.1.0/tests/test_hooks.py +64 -0
- stageload-0.1.0/tests/test_meter.py +102 -0
- stageload-0.1.0/tests/test_pixal3d_cli.py +117 -0
- stageload-0.1.0/tests/test_pixal3d_port.py +59 -0
- stageload-0.1.0/tests/test_pixal3d_probe.py +65 -0
- stageload-0.1.0/tests/test_pixal3d_staged.py +201 -0
- stageload-0.1.0/tests/test_readme.py +50 -0
- stageload-0.1.0/tests/test_registry.py +238 -0
- stageload-0.1.0/tests/test_release.py +85 -0
- stageload-0.1.0/tests/test_share.py +77 -0
- stageload-0.1.0/tests/test_trace.py +129 -0
- stageload-0.1.0/tests/test_units.py +31 -0
stageload-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
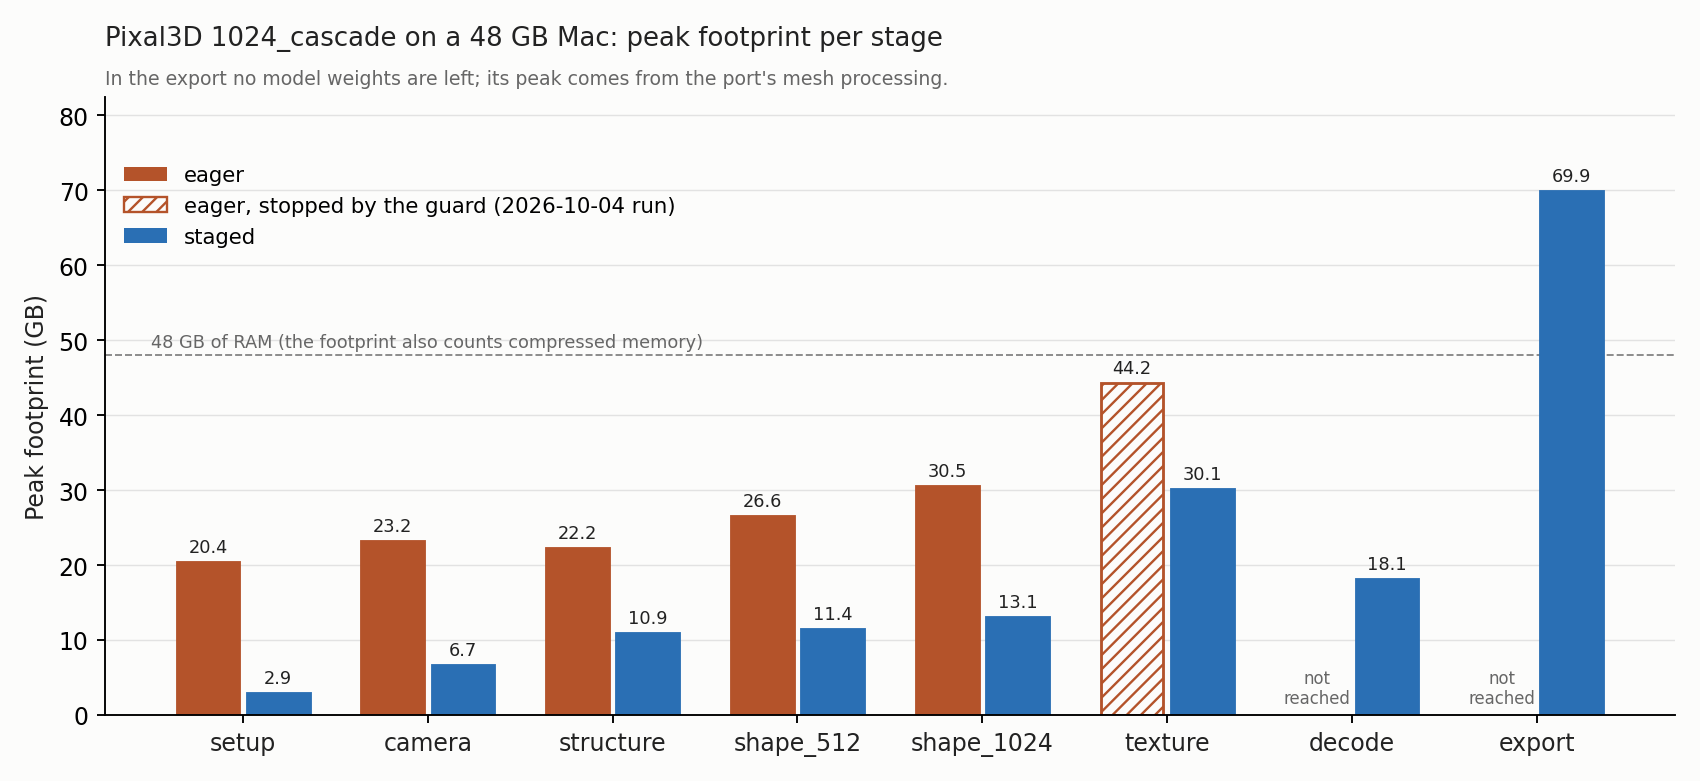
|
|
3
|
+
Copyright (c) 2026 Rodion Kazennov
|
|
4
|
+
|
|
5
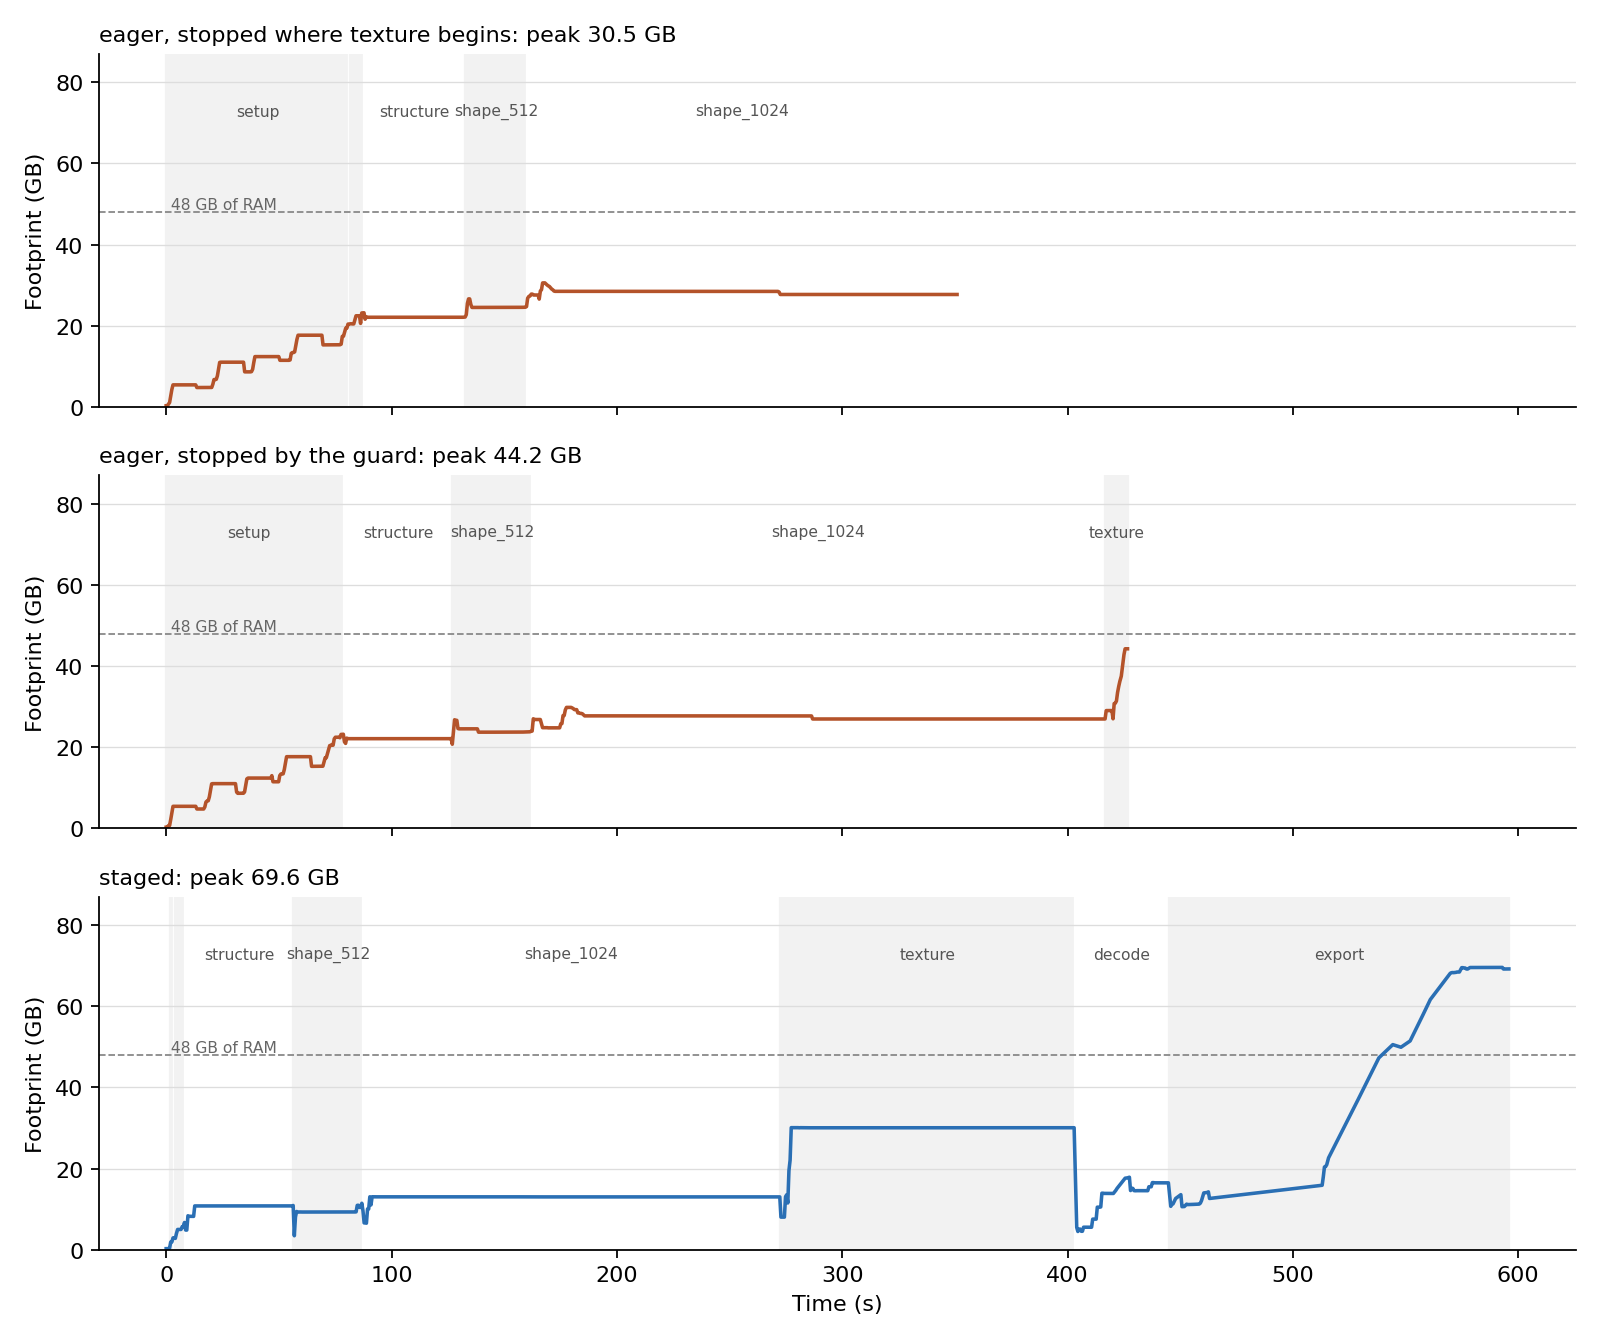
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
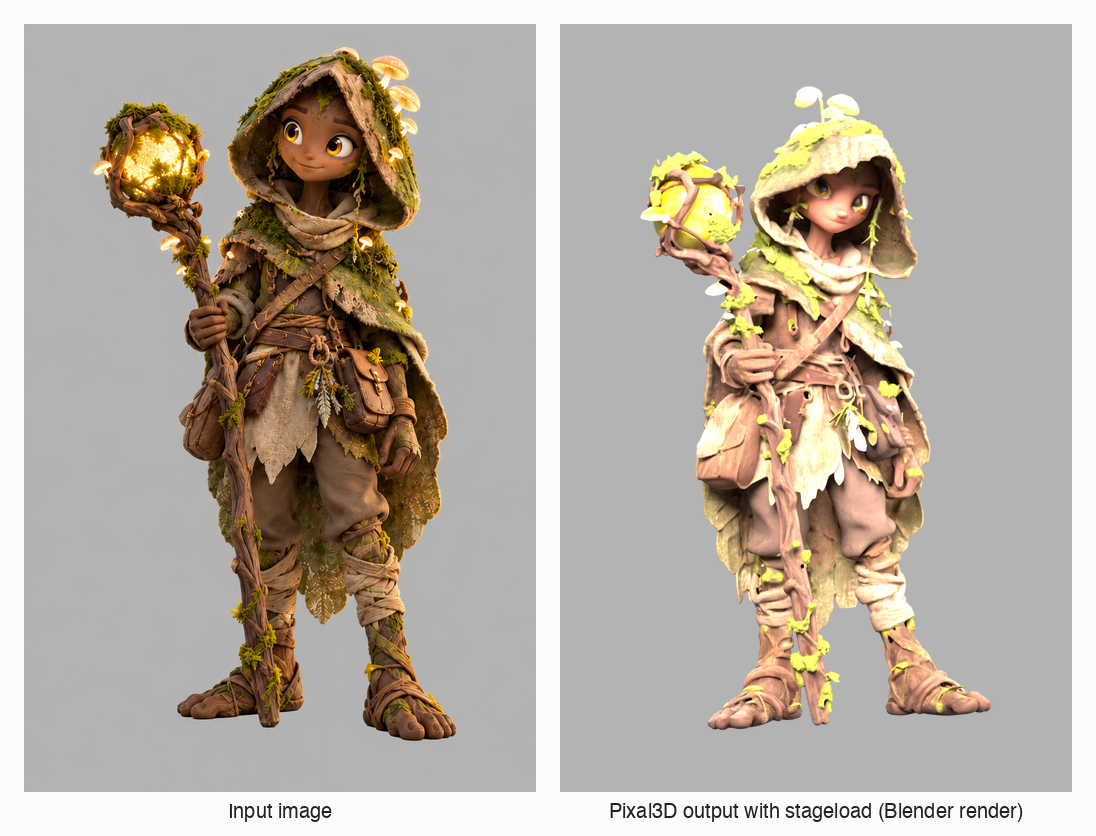
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
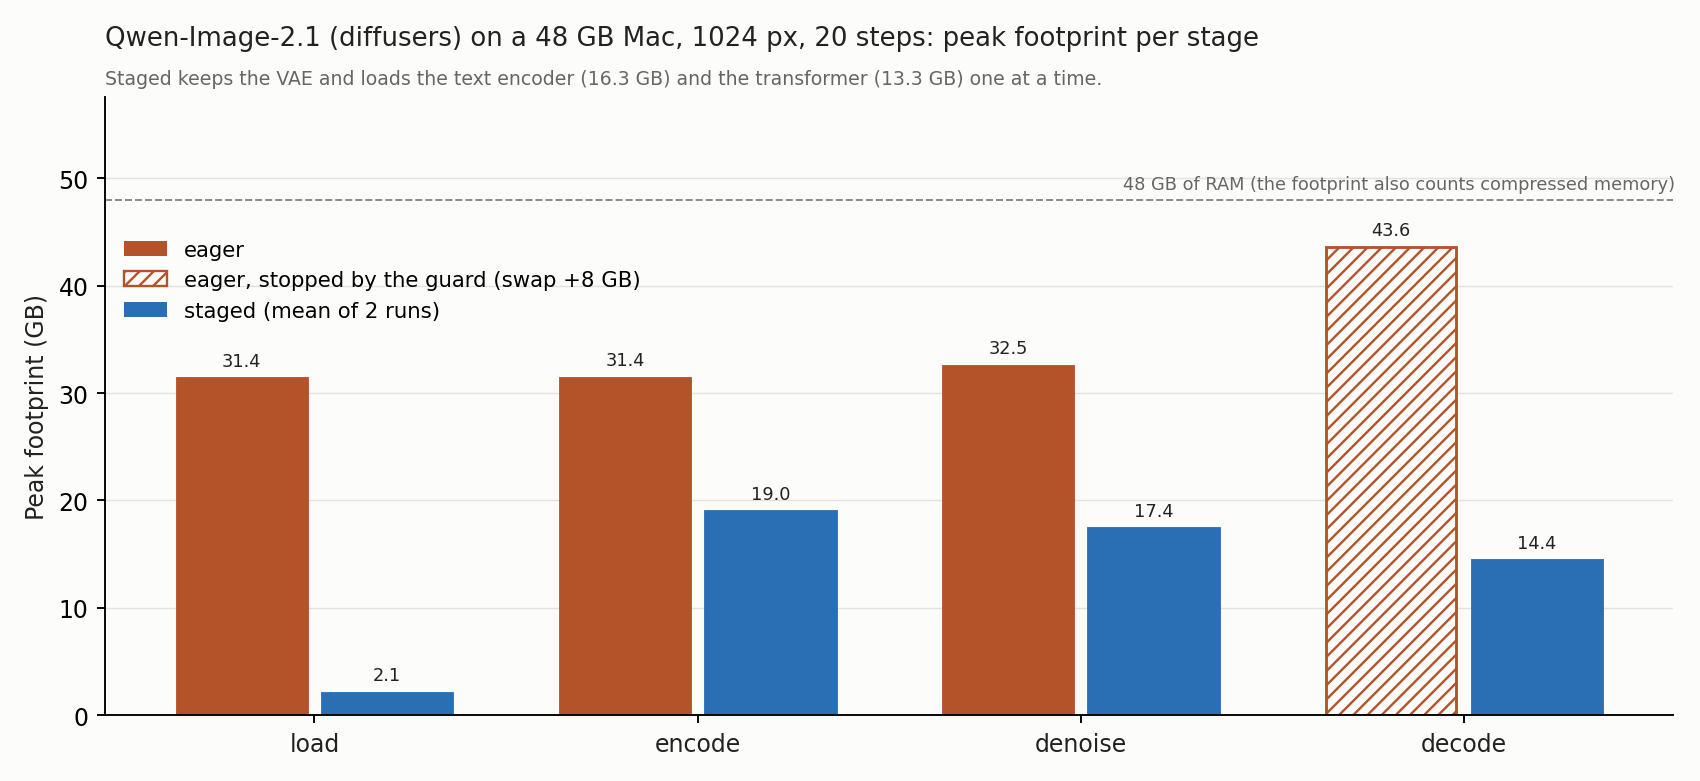
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
stageload-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,247 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: stageload
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Run multi-stage PyTorch pipelines on Apple Silicon with one stage's weights in memory at a time.
|
|
5
|
+
Project-URL: Homepage, https://github.com/nefayran/stageload
|
|
6
|
+
Project-URL: Issues, https://github.com/nefayran/stageload/issues
|
|
7
|
+
Author: Rodion Kazennov
|
|
8
|
+
License: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: apple-silicon,diffusers,inference,memory,mps,pytorch
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Intended Audience :: Developers
|
|
13
|
+
Classifier: Intended Audience :: Science/Research
|
|
14
|
+
Classifier: Operating System :: MacOS
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
17
|
+
Requires-Python: >=3.10
|
|
18
|
+
Requires-Dist: torch>=2.1
|
|
19
|
+
Provides-Extra: bench
|
|
20
|
+
Requires-Dist: matplotlib>=3.7; extra == 'bench'
|
|
21
|
+
Requires-Dist: numpy>=1.24; extra == 'bench'
|
|
22
|
+
Requires-Dist: pillow>=10; extra == 'bench'
|
|
23
|
+
Requires-Dist: trimesh>=4; extra == 'bench'
|
|
24
|
+
Provides-Extra: test
|
|
25
|
+
Requires-Dist: numpy>=1.24; extra == 'test'
|
|
26
|
+
Requires-Dist: pillow>=10; extra == 'test'
|
|
27
|
+
Requires-Dist: pytest>=7; extra == 'test'
|
|
28
|
+
Requires-Dist: ruff>=0.6; extra == 'test'
|
|
29
|
+
Requires-Dist: safetensors>=0.4; extra == 'test'
|
|
30
|
+
Description-Content-Type: text/markdown
|
|
31
|
+
|
|
32
|
+
# stageload
|
|
33
|
+
|
|
34
|
+
Run multi-stage PyTorch pipelines on Apple Silicon with only the current stage's weights in memory.
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
## Why
|
|
39
|
+
|
|
40
|
+
On Apple Silicon the CPU and the GPU share one pool of memory. The usual way to fit a big
|
|
41
|
+
pipeline, keeping idle models "on the CPU" and moving the active one to the GPU, frees nothing
|
|
42
|
+
there: both copies sit in the same RAM. Pixal3D runs in that mode by default (`low_vram` is on
|
|
43
|
+
unless its `pipeline.json` turns it off), so a `1024_cascade` run keeps all seven of its models
|
|
44
|
+
in memory for the whole run and copies the active one to MPS on top. It also loads the same
|
|
45
|
+
DINOv3 backbone four times, once per feature extractor.
|
|
46
|
+
|
|
47
|
+
stageload loads a model the first time a stage asks for it and releases it in place when the
|
|
48
|
+
pipeline moves to a stage that does not need it. Releasing moves the module's tensors to PyTorch's
|
|
49
|
+
`meta` device, which frees their storage even while other code still holds a reference to the
|
|
50
|
+
module. The design is in [docs/design/2026-10-04-stageload-design.md](https://github.com/nefayran/stageload/blob/main/docs/design/2026-10-04-stageload-design.md).
|
|
51
|
+
|
|
52
|
+
## Any pipeline that runs its models in turn
|
|
53
|
+
|
|
54
|
+
Nothing in the core knows about Pixal3D. A pipeline needs three things: a function that builds
|
|
55
|
+
each model on its own, the list of models each stage uses, and a call where each stage begins.
|
|
56
|
+
In code you own, that call is `models.enter("decode")`; in code you don't, `on_call` attaches it
|
|
57
|
+
to a method that already runs at that point, and the pipeline stays as it is. A text-to-image
|
|
58
|
+
pipeline (a text encoder, a denoiser and an image decoder, one after another) has the same shape;
|
|
59
|
+
Qwen-Image-2.1 through diffusers is the second pipeline measured
|
|
60
|
+
([results](#qwen-image-21-through-diffusers)). Pixal3D-mac is the first adapter;
|
|
61
|
+
[`bench/qwen_image.py`](https://github.com/nefayran/stageload/blob/main/bench/qwen_image.py) wires a diffusers pipeline without changing its
|
|
62
|
+
code, and [Use it in your own pipeline](#use-it-in-your-own-pipeline) shows the core on two models.
|
|
63
|
+
|
|
64
|
+
## Results
|
|
65
|
+
|
|
66
|
+
### Pixal3D
|
|
67
|
+
|
|
68
|
+
Pixal3D `1024_cascade` on an Apple M5 Pro with 48 GB, one image, seed 7, two runs per mode
|
|
69
|
+
([details and traces](https://github.com/nefayran/stageload/blob/main/bench/results/2026-10-05/README.md)):
|
|
70
|
+
|
|
71
|
+
| stage | eager, peak footprint | staged, peak footprint |
|
|
72
|
+
|---|---|---|
|
|
73
|
+
| setup | 20.4 GB | 2.9 GB |
|
|
74
|
+
| camera | 23.2 GB | 6.7 GB |
|
|
75
|
+
| structure | 22.2 GB | 10.9 GB |
|
|
76
|
+
| shape_512 | 26.6 GB | 11.4 to 11.5 GB |
|
|
77
|
+
| shape_1024 | 30.5 GB | 13.1 GB |
|
|
78
|
+
| texture | stopped by the guard at 44.2 GB (a run on 2026-10-04) | 30.1 GB |
|
|
79
|
+
| decode | – | 17.9 to 18.4 GB |
|
|
80
|
+
| export | – | 69.6 to 70.2 GB |
|
|
81
|
+
|
|
82
|
+
- Eager loading did not get through the texture stage on this machine. Within 10 s of entering
|
|
83
|
+
it the footprint rose from 27 to 44 GB, available memory fell to 6 % and swap reached 27 GB,
|
|
84
|
+
12 GB more than when the run started, so the guard stopped it. The other eager numbers come
|
|
85
|
+
from runs stopped where the texture stage begins. Both staged runs finished, in about ten
|
|
86
|
+
minutes each, of which 24 s went to loading models.
|
|
87
|
+
- Most of the texture stage's 30 GB is working memory, not weights: the texture model is 2.6 GB.
|
|
88
|
+
When decoding began, releasing it and emptying the MPS allocator's cache brought the footprint
|
|
89
|
+
down to 4.5 GB in one run and 8.0 GB in the other within two seconds.
|
|
90
|
+
- The highest staged footprint is the port's own mesh export, after every weight has been
|
|
91
|
+
released; stageload does not change it.
|
|
92
|
+
- Output: the first latent (the sparse structure) is the same bit for bit in every run. From the
|
|
93
|
+
next stage on, Pixal3D-mac does not repeat itself on MPS even with the same seed: the one pair
|
|
94
|
+
of eager runs differed by 1.77 in the 512 shape latent, and staged runs differ from eager runs
|
|
95
|
+
by 1.24 to 1.86. That shows any change from staged loading is no larger than the port's own
|
|
96
|
+
variation; it cannot show there is none.
|
|
97
|
+
|
|
98
|
+
A staged run on a character image, rendered in Blender ([`bench/render_glb.py`](https://github.com/nefayran/stageload/blob/main/bench/render_glb.py)):
|
|
99
|
+
|
|
100
|
+
|
|
101
|
+
|
|
102
|
+
The footprint over time, for an eager run stopped where the texture stage begins, the eager run
|
|
103
|
+
the guard stopped, and a staged run:
|
|
104
|
+
|
|
105
|
+
|
|
106
|
+
|
|
107
|
+
### Qwen-Image-2.1 through diffusers
|
|
108
|
+
|
|
109
|
+
Text to image at 1024 x 1024, 20 steps, seed 7, on the same Mac
|
|
110
|
+
([details and traces](https://github.com/nefayran/stageload/blob/main/bench/results/2026-10-06-qwen-image/README.md)). Eager is the usual
|
|
111
|
+
`QwenImage21Pipeline.from_pretrained(...).to("mps")`. Staged keeps the VAE and loads the text
|
|
112
|
+
encoder (16.3 GB) and the transformer (13.3 GB) one at a time; the pipeline's code is unchanged.
|
|
113
|
+
|
|
114
|
+
|
|
115
|
+
|
|
116
|
+
| stage | eager, peak footprint | staged, peak footprint |
|
|
117
|
+
|---|---|---|
|
|
118
|
+
| load | 31.4 GB | 2.1 GB |
|
|
119
|
+
| encode | 31.4 GB | 19.0 GB |
|
|
120
|
+
| denoise | 32.5 GB | 16.2 to 18.6 GB |
|
|
121
|
+
| decode | stopped by the guard at 43.6 GB | 14.4 GB |
|
|
122
|
+
|
|
123
|
+
- Eager ran all 20 steps. The VAE decode then took its footprint from 32.5 to 43.6 GB and swap
|
|
124
|
+
grew by 8 GB, so the guard stopped it before it wrote an image. Staged released the transformer
|
|
125
|
+
before the decode, and its swap did not grow in either of its two runs.
|
|
126
|
+
- A step costs the same: the second staged run's denoising took 79 s, eager's 77 s. Staged spent
|
|
127
|
+
13 s loading the two models.
|
|
128
|
+
- The two staged runs produced the same image, bit for bit. Eager produced none, so these runs do
|
|
129
|
+
not show that both modes give the same image.
|
|
130
|
+
|
|
131
|
+
## How it works
|
|
132
|
+
|
|
133
|
+
- `StagedModels` is a dictionary of models that loads each one on first access. `enter(stage)`
|
|
134
|
+
releases every loaded model the stage does not list. Checking `name in models`, `len()` and
|
|
135
|
+
iterating names never load anything.
|
|
136
|
+
- Loading a model leaves the random generators where they were: torch's CPU, MPS and CUDA
|
|
137
|
+
generators, Python's `random` and NumPy's global one. A pipeline that seeds once and draws noise
|
|
138
|
+
stage by stage would otherwise get different noise, and a different result, as soon as a model
|
|
139
|
+
is built in the middle of the run.
|
|
140
|
+
- `release(module)` moves every parameter and buffer to `meta`, collects garbage and empties the
|
|
141
|
+
MPS cache. Calling a released module raises `ReleasedModuleError` with its name and the stage
|
|
142
|
+
that released it, instead of PyTorch's error about meta tensors.
|
|
143
|
+
- `on_call(obj, method, before=..., after=...)` marks stage boundaries on an existing pipeline
|
|
144
|
+
object, so its own `run()` executes unchanged.
|
|
145
|
+
- `share(owner, "from_pretrained")` makes identical loads return one instance for the duration of
|
|
146
|
+
a block; the Pixal3D adapter uses it to give four extractors one DINOv3 backbone.
|
|
147
|
+
- `MemoryMeter` writes a JSONL trace: the process footprint (`phys_footprint`, the number
|
|
148
|
+
Activity Monitor shows), swap and `kern.memorystatus_level` every 0.5 s, plus every load,
|
|
149
|
+
release and stage change.
|
|
150
|
+
|
|
151
|
+
## Pixal3D-mac
|
|
152
|
+
|
|
153
|
+
Install [Pixal3D-mac](https://github.com/pawel-mazurkiewicz/Pixal3D-mac) with its own README, then
|
|
154
|
+
add stageload to the port's environment without touching its packages, and run it from there:
|
|
155
|
+
|
|
156
|
+
```bash
|
|
157
|
+
cd path/to/Pixal3D-mac
|
|
158
|
+
.venv/bin/pip install --no-deps git+https://github.com/nefayran/stageload
|
|
159
|
+
.venv/bin/stageload-pixal3d photo.png -o photo.glb
|
|
160
|
+
```
|
|
161
|
+
|
|
162
|
+
`--load eager` runs the port's own loading for comparison. Flags, stages and the bench are in
|
|
163
|
+
[docs/pixal3d.md](https://github.com/nefayran/stageload/blob/main/docs/pixal3d.md).
|
|
164
|
+
|
|
165
|
+
## The guard
|
|
166
|
+
|
|
167
|
+
`stageload guard` starts one command only when there is room for it, and stops it before swap
|
|
168
|
+
runs away. It needs no root, and the only processes it ever stops are the command and its process
|
|
169
|
+
group.
|
|
170
|
+
|
|
171
|
+
```bash
|
|
172
|
+
stageload guard --wait-free 40 --swap-budget 8G --busy 'ltx-2-mlx' -- python train.py
|
|
173
|
+
```
|
|
174
|
+
|
|
175
|
+
It waits until `kern.memorystatus_level` is at least `--wait-free` percent and no process has matched
|
|
176
|
+
a `--busy` pattern for `--quiet-for` (a minute by default, so the gap between two jobs of a chain
|
|
177
|
+
does not count as quiet), then runs the command. It stops the command if swap grows more than
|
|
178
|
+
`--swap-budget` over what was used at the start, or if available memory stays under `--kill-free`
|
|
179
|
+
(10 %) for two samples. Stopping means SIGTERM to the command's process group and, five seconds
|
|
180
|
+
later, SIGKILL to whatever of the group is left.
|
|
181
|
+
|
|
182
|
+
Exit code 3 means the guard stopped the command, 4 that it never found room to start it, and 127
|
|
183
|
+
that the command could not be started. If the guard itself gets Ctrl-C, SIGTERM or SIGHUP, it
|
|
184
|
+
stops the command first and exits with 128 plus the signal number; a second signal while the
|
|
185
|
+
command is shutting down sends SIGKILL at once. A signal the guard was started to ignore, such as
|
|
186
|
+
SIGHUP under `nohup`, stays ignored. Otherwise you get the command's own exit code, or 128 plus
|
|
187
|
+
the signal number if a signal ended it.
|
|
188
|
+
|
|
189
|
+
The `--busy` patterns match whole command lines, like `pgrep -f`. The guard leaves itself and the
|
|
190
|
+
shells that started it out, but any other process whose command line contains a pattern counts,
|
|
191
|
+
a shell running a script that mentions it included.
|
|
192
|
+
|
|
193
|
+
For a safety net across the whole machine, see
|
|
194
|
+
[macos-oom-guard](https://github.com/fl4p/macos-oom-guard), a root daemon that kills the largest
|
|
195
|
+
process before the kernel panics. The two do different jobs and can run together.
|
|
196
|
+
|
|
197
|
+
## Use it in your own pipeline
|
|
198
|
+
|
|
199
|
+
```python
|
|
200
|
+
import torch
|
|
201
|
+
from safetensors.torch import load_file
|
|
202
|
+
from stageload import StagedModels
|
|
203
|
+
|
|
204
|
+
DEVICE = "mps"
|
|
205
|
+
|
|
206
|
+
def loader(cls, path): # cls: one of your nn.Module classes
|
|
207
|
+
def load():
|
|
208
|
+
with torch.device(DEVICE): # built on the GPU, not on the CPU and then moved
|
|
209
|
+
model = cls()
|
|
210
|
+
model.load_state_dict(load_file(path, device=DEVICE))
|
|
211
|
+
return model.eval()
|
|
212
|
+
return load
|
|
213
|
+
|
|
214
|
+
models = StagedModels(
|
|
215
|
+
{"encoder": loader(Encoder, "encoder.safetensors"),
|
|
216
|
+
"decoder": loader(Decoder, "decoder.safetensors")},
|
|
217
|
+
stages={"encode": ["encoder"], "decode": ["decoder"]},
|
|
218
|
+
)
|
|
219
|
+
|
|
220
|
+
models.enter("encode")
|
|
221
|
+
latent = models["encoder"](image) # loaded here
|
|
222
|
+
models.enter("decode") # the encoder is released here
|
|
223
|
+
mesh = models["decoder"](latent)
|
|
224
|
+
models.close()
|
|
225
|
+
```
|
|
226
|
+
|
|
227
|
+
## Limits
|
|
228
|
+
|
|
229
|
+
- The meter and the guard read macOS counters (`libproc`, `sysctl`). The registry and `release`
|
|
230
|
+
work wherever PyTorch runs.
|
|
231
|
+
- One adapter so far: Pixal3D-mac, tested at commit `0be9e69`, and staged loading has a plan for
|
|
232
|
+
its `1024_cascade` pipeline only.
|
|
233
|
+
- A staged Pixal3D pipeline serves one image; the command builds a new one per image.
|
|
234
|
+
- The Qwen-Image wiring is a bench script for one pipeline, run with diffusers from main
|
|
235
|
+
(0.41.0.dev0), not a packaged adapter.
|
|
236
|
+
- stageload builds Pixal3D's models directly on MPS, where the port builds them on the CPU. The
|
|
237
|
+
sparse attention's rotary frequencies, computed when a model is built, then come out slightly
|
|
238
|
+
different (up to 6e-8 apart). Because the port does not repeat its sparse stages on MPS with the
|
|
239
|
+
same seed, a staged result can only be checked against eager within that run-to-run spread,
|
|
240
|
+
and the texture latent and the final GLB were not compared at all.
|
|
241
|
+
- The meter samples from a thread inside the process. While native code holds the interpreter
|
|
242
|
+
lock it takes no samples, so a short peak inside such a call can be missed.
|
|
243
|
+
|
|
244
|
+
## License
|
|
245
|
+
|
|
246
|
+
MIT. Pixal3D and Pixal3D-mac are MIT-licensed as well and are not included here; the adapter
|
|
247
|
+
imports the port at run time.
|
|
@@ -0,0 +1,216 @@
|
|
|
1
|
+
# stageload
|
|
2
|
+
|
|
3
|
+
Run multi-stage PyTorch pipelines on Apple Silicon with only the current stage's weights in memory.
|
|
4
|
+
|
|
5
|
+

|
|
6
|
+
|
|
7
|
+
## Why
|
|
8
|
+
|
|
9
|
+
On Apple Silicon the CPU and the GPU share one pool of memory. The usual way to fit a big
|
|
10
|
+
pipeline, keeping idle models "on the CPU" and moving the active one to the GPU, frees nothing
|
|
11
|
+
there: both copies sit in the same RAM. Pixal3D runs in that mode by default (`low_vram` is on
|
|
12
|
+
unless its `pipeline.json` turns it off), so a `1024_cascade` run keeps all seven of its models
|
|
13
|
+
in memory for the whole run and copies the active one to MPS on top. It also loads the same
|
|
14
|
+
DINOv3 backbone four times, once per feature extractor.
|
|
15
|
+
|
|
16
|
+
stageload loads a model the first time a stage asks for it and releases it in place when the
|
|
17
|
+
pipeline moves to a stage that does not need it. Releasing moves the module's tensors to PyTorch's
|
|
18
|
+
`meta` device, which frees their storage even while other code still holds a reference to the
|
|
19
|
+
module. The design is in [docs/design/2026-10-04-stageload-design.md](https://github.com/nefayran/stageload/blob/main/docs/design/2026-10-04-stageload-design.md).
|
|
20
|
+
|
|
21
|
+
## Any pipeline that runs its models in turn
|
|
22
|
+
|
|
23
|
+
Nothing in the core knows about Pixal3D. A pipeline needs three things: a function that builds
|
|
24
|
+
each model on its own, the list of models each stage uses, and a call where each stage begins.
|
|
25
|
+
In code you own, that call is `models.enter("decode")`; in code you don't, `on_call` attaches it
|
|
26
|
+
to a method that already runs at that point, and the pipeline stays as it is. A text-to-image
|
|
27
|
+
pipeline (a text encoder, a denoiser and an image decoder, one after another) has the same shape;
|
|
28
|
+
Qwen-Image-2.1 through diffusers is the second pipeline measured
|
|
29
|
+
([results](#qwen-image-21-through-diffusers)). Pixal3D-mac is the first adapter;
|
|
30
|
+
[`bench/qwen_image.py`](https://github.com/nefayran/stageload/blob/main/bench/qwen_image.py) wires a diffusers pipeline without changing its
|
|
31
|
+
code, and [Use it in your own pipeline](#use-it-in-your-own-pipeline) shows the core on two models.
|
|
32
|
+
|
|
33
|
+
## Results
|
|
34
|
+
|
|
35
|
+
### Pixal3D
|
|
36
|
+
|
|
37
|
+
Pixal3D `1024_cascade` on an Apple M5 Pro with 48 GB, one image, seed 7, two runs per mode
|
|
38
|
+
([details and traces](https://github.com/nefayran/stageload/blob/main/bench/results/2026-10-05/README.md)):
|
|
39
|
+
|
|
40
|
+
| stage | eager, peak footprint | staged, peak footprint |
|
|
41
|
+
|---|---|---|
|
|
42
|
+
| setup | 20.4 GB | 2.9 GB |
|
|
43
|
+
| camera | 23.2 GB | 6.7 GB |
|
|
44
|
+
| structure | 22.2 GB | 10.9 GB |
|
|
45
|
+
| shape_512 | 26.6 GB | 11.4 to 11.5 GB |
|
|
46
|
+
| shape_1024 | 30.5 GB | 13.1 GB |
|
|
47
|
+
| texture | stopped by the guard at 44.2 GB (a run on 2026-10-04) | 30.1 GB |
|
|
48
|
+
| decode | – | 17.9 to 18.4 GB |
|
|
49
|
+
| export | – | 69.6 to 70.2 GB |
|
|
50
|
+
|
|
51
|
+
- Eager loading did not get through the texture stage on this machine. Within 10 s of entering
|
|
52
|
+
it the footprint rose from 27 to 44 GB, available memory fell to 6 % and swap reached 27 GB,
|
|
53
|
+
12 GB more than when the run started, so the guard stopped it. The other eager numbers come
|
|
54
|
+
from runs stopped where the texture stage begins. Both staged runs finished, in about ten
|
|
55
|
+
minutes each, of which 24 s went to loading models.
|
|
56
|
+
- Most of the texture stage's 30 GB is working memory, not weights: the texture model is 2.6 GB.
|
|
57
|
+
When decoding began, releasing it and emptying the MPS allocator's cache brought the footprint
|
|
58
|
+
down to 4.5 GB in one run and 8.0 GB in the other within two seconds.
|
|
59
|
+
- The highest staged footprint is the port's own mesh export, after every weight has been
|
|
60
|
+
released; stageload does not change it.
|
|
61
|
+
- Output: the first latent (the sparse structure) is the same bit for bit in every run. From the
|
|
62
|
+
next stage on, Pixal3D-mac does not repeat itself on MPS even with the same seed: the one pair
|
|
63
|
+
of eager runs differed by 1.77 in the 512 shape latent, and staged runs differ from eager runs
|
|
64
|
+
by 1.24 to 1.86. That shows any change from staged loading is no larger than the port's own
|
|
65
|
+
variation; it cannot show there is none.
|
|
66
|
+
|
|
67
|
+
A staged run on a character image, rendered in Blender ([`bench/render_glb.py`](https://github.com/nefayran/stageload/blob/main/bench/render_glb.py)):
|
|
68
|
+
|
|
69
|
+

|
|
70
|
+
|
|
71
|
+
The footprint over time, for an eager run stopped where the texture stage begins, the eager run
|
|
72
|
+
the guard stopped, and a staged run:
|
|
73
|
+
|
|
74
|
+

|
|
75
|
+
|
|
76
|
+
### Qwen-Image-2.1 through diffusers
|
|
77
|
+
|
|
78
|
+
Text to image at 1024 x 1024, 20 steps, seed 7, on the same Mac
|
|
79
|
+
([details and traces](https://github.com/nefayran/stageload/blob/main/bench/results/2026-10-06-qwen-image/README.md)). Eager is the usual
|
|
80
|
+
`QwenImage21Pipeline.from_pretrained(...).to("mps")`. Staged keeps the VAE and loads the text
|
|
81
|
+
encoder (16.3 GB) and the transformer (13.3 GB) one at a time; the pipeline's code is unchanged.
|
|
82
|
+
|
|
83
|
+

|
|
84
|
+
|
|
85
|
+
| stage | eager, peak footprint | staged, peak footprint |
|
|
86
|
+
|---|---|---|
|
|
87
|
+
| load | 31.4 GB | 2.1 GB |
|
|
88
|
+
| encode | 31.4 GB | 19.0 GB |
|
|
89
|
+
| denoise | 32.5 GB | 16.2 to 18.6 GB |
|
|
90
|
+
| decode | stopped by the guard at 43.6 GB | 14.4 GB |
|
|
91
|
+
|
|
92
|
+
- Eager ran all 20 steps. The VAE decode then took its footprint from 32.5 to 43.6 GB and swap
|
|
93
|
+
grew by 8 GB, so the guard stopped it before it wrote an image. Staged released the transformer
|
|
94
|
+
before the decode, and its swap did not grow in either of its two runs.
|
|
95
|
+
- A step costs the same: the second staged run's denoising took 79 s, eager's 77 s. Staged spent
|
|
96
|
+
13 s loading the two models.
|
|
97
|
+
- The two staged runs produced the same image, bit for bit. Eager produced none, so these runs do
|
|
98
|
+
not show that both modes give the same image.
|
|
99
|
+
|
|
100
|
+
## How it works
|
|
101
|
+
|
|
102
|
+
- `StagedModels` is a dictionary of models that loads each one on first access. `enter(stage)`
|
|
103
|
+
releases every loaded model the stage does not list. Checking `name in models`, `len()` and
|
|
104
|
+
iterating names never load anything.
|
|
105
|
+
- Loading a model leaves the random generators where they were: torch's CPU, MPS and CUDA
|
|
106
|
+
generators, Python's `random` and NumPy's global one. A pipeline that seeds once and draws noise
|
|
107
|
+
stage by stage would otherwise get different noise, and a different result, as soon as a model
|
|
108
|
+
is built in the middle of the run.
|
|
109
|
+
- `release(module)` moves every parameter and buffer to `meta`, collects garbage and empties the
|
|
110
|
+
MPS cache. Calling a released module raises `ReleasedModuleError` with its name and the stage
|
|
111
|
+
that released it, instead of PyTorch's error about meta tensors.
|
|
112
|
+
- `on_call(obj, method, before=..., after=...)` marks stage boundaries on an existing pipeline
|
|
113
|
+
object, so its own `run()` executes unchanged.
|
|
114
|
+
- `share(owner, "from_pretrained")` makes identical loads return one instance for the duration of
|
|
115
|
+
a block; the Pixal3D adapter uses it to give four extractors one DINOv3 backbone.
|
|
116
|
+
- `MemoryMeter` writes a JSONL trace: the process footprint (`phys_footprint`, the number
|
|
117
|
+
Activity Monitor shows), swap and `kern.memorystatus_level` every 0.5 s, plus every load,
|
|
118
|
+
release and stage change.
|
|
119
|
+
|
|
120
|
+
## Pixal3D-mac
|
|
121
|
+
|
|
122
|
+
Install [Pixal3D-mac](https://github.com/pawel-mazurkiewicz/Pixal3D-mac) with its own README, then
|
|
123
|
+
add stageload to the port's environment without touching its packages, and run it from there:
|
|
124
|
+
|
|
125
|
+
```bash
|
|
126
|
+
cd path/to/Pixal3D-mac
|
|
127
|
+
.venv/bin/pip install --no-deps git+https://github.com/nefayran/stageload
|
|
128
|
+
.venv/bin/stageload-pixal3d photo.png -o photo.glb
|
|
129
|
+
```
|
|
130
|
+
|
|
131
|
+
`--load eager` runs the port's own loading for comparison. Flags, stages and the bench are in
|
|
132
|
+
[docs/pixal3d.md](https://github.com/nefayran/stageload/blob/main/docs/pixal3d.md).
|
|
133
|
+
|
|
134
|
+
## The guard
|
|
135
|
+
|
|
136
|
+
`stageload guard` starts one command only when there is room for it, and stops it before swap
|
|
137
|
+
runs away. It needs no root, and the only processes it ever stops are the command and its process
|
|
138
|
+
group.
|
|
139
|
+
|
|
140
|
+
```bash
|
|
141
|
+
stageload guard --wait-free 40 --swap-budget 8G --busy 'ltx-2-mlx' -- python train.py
|
|
142
|
+
```
|
|
143
|
+
|
|
144
|
+
It waits until `kern.memorystatus_level` is at least `--wait-free` percent and no process has matched
|
|
145
|
+
a `--busy` pattern for `--quiet-for` (a minute by default, so the gap between two jobs of a chain
|
|
146
|
+
does not count as quiet), then runs the command. It stops the command if swap grows more than
|
|
147
|
+
`--swap-budget` over what was used at the start, or if available memory stays under `--kill-free`
|
|
148
|
+
(10 %) for two samples. Stopping means SIGTERM to the command's process group and, five seconds
|
|
149
|
+
later, SIGKILL to whatever of the group is left.
|
|
150
|
+
|
|
151
|
+
Exit code 3 means the guard stopped the command, 4 that it never found room to start it, and 127
|
|
152
|
+
that the command could not be started. If the guard itself gets Ctrl-C, SIGTERM or SIGHUP, it
|
|
153
|
+
stops the command first and exits with 128 plus the signal number; a second signal while the
|
|
154
|
+
command is shutting down sends SIGKILL at once. A signal the guard was started to ignore, such as
|
|
155
|
+
SIGHUP under `nohup`, stays ignored. Otherwise you get the command's own exit code, or 128 plus
|
|
156
|
+
the signal number if a signal ended it.
|
|
157
|
+
|
|
158
|
+
The `--busy` patterns match whole command lines, like `pgrep -f`. The guard leaves itself and the
|
|
159
|
+
shells that started it out, but any other process whose command line contains a pattern counts,
|
|
160
|
+
a shell running a script that mentions it included.
|
|
161
|
+
|
|
162
|
+
For a safety net across the whole machine, see
|
|
163
|
+
[macos-oom-guard](https://github.com/fl4p/macos-oom-guard), a root daemon that kills the largest
|
|
164
|
+
process before the kernel panics. The two do different jobs and can run together.
|
|
165
|
+
|
|
166
|
+
## Use it in your own pipeline
|
|
167
|
+
|
|
168
|
+
```python
|
|
169
|
+
import torch
|
|
170
|
+
from safetensors.torch import load_file
|
|
171
|
+
from stageload import StagedModels
|
|
172
|
+
|
|
173
|
+
DEVICE = "mps"
|
|
174
|
+
|
|
175
|
+
def loader(cls, path): # cls: one of your nn.Module classes
|
|
176
|
+
def load():
|
|
177
|
+
with torch.device(DEVICE): # built on the GPU, not on the CPU and then moved
|
|
178
|
+
model = cls()
|
|
179
|
+
model.load_state_dict(load_file(path, device=DEVICE))
|
|
180
|
+
return model.eval()
|
|
181
|
+
return load
|
|
182
|
+
|
|
183
|
+
models = StagedModels(
|
|
184
|
+
{"encoder": loader(Encoder, "encoder.safetensors"),
|
|
185
|
+
"decoder": loader(Decoder, "decoder.safetensors")},
|
|
186
|
+
stages={"encode": ["encoder"], "decode": ["decoder"]},
|
|
187
|
+
)
|
|
188
|
+
|
|
189
|
+
models.enter("encode")
|
|
190
|
+
latent = models["encoder"](image) # loaded here
|
|
191
|
+
models.enter("decode") # the encoder is released here
|
|
192
|
+
mesh = models["decoder"](latent)
|
|
193
|
+
models.close()
|
|
194
|
+
```
|
|
195
|
+
|
|
196
|
+
## Limits
|
|
197
|
+
|
|
198
|
+
- The meter and the guard read macOS counters (`libproc`, `sysctl`). The registry and `release`
|
|
199
|
+
work wherever PyTorch runs.
|
|
200
|
+
- One adapter so far: Pixal3D-mac, tested at commit `0be9e69`, and staged loading has a plan for
|
|
201
|
+
its `1024_cascade` pipeline only.
|
|
202
|
+
- A staged Pixal3D pipeline serves one image; the command builds a new one per image.
|
|
203
|
+
- The Qwen-Image wiring is a bench script for one pipeline, run with diffusers from main
|
|
204
|
+
(0.41.0.dev0), not a packaged adapter.
|
|
205
|
+
- stageload builds Pixal3D's models directly on MPS, where the port builds them on the CPU. The
|
|
206
|
+
sparse attention's rotary frequencies, computed when a model is built, then come out slightly
|
|
207
|
+
different (up to 6e-8 apart). Because the port does not repeat its sparse stages on MPS with the
|
|
208
|
+
same seed, a staged result can only be checked against eager within that run-to-run spread,
|
|
209
|
+
and the texture latent and the final GLB were not compared at all.
|
|
210
|
+
- The meter samples from a thread inside the process. While native code holds the interpreter
|
|
211
|
+
lock it takes no samples, so a short peak inside such a call can be missed.
|
|
212
|
+
|
|
213
|
+
## License
|
|
214
|
+
|
|
215
|
+
MIT. Pixal3D and Pixal3D-mac are MIT-licensed as well and are not included here; the adapter
|
|
216
|
+
imports the port at run time.
|
|
@@ -0,0 +1,56 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["hatchling>=1.24"]
|
|
3
|
+
build-backend = "hatchling.build"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "stageload"
|
|
7
|
+
dynamic = ["version"]
|
|
8
|
+
description = "Run multi-stage PyTorch pipelines on Apple Silicon with one stage's weights in memory at a time."
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
license = { text = "MIT" }
|
|
11
|
+
requires-python = ">=3.10"
|
|
12
|
+
authors = [{ name = "Rodion Kazennov" }]
|
|
13
|
+
keywords = ["pytorch", "apple-silicon", "mps", "memory", "diffusers", "inference"]
|
|
14
|
+
classifiers = [
|
|
15
|
+
"Development Status :: 3 - Alpha",
|
|
16
|
+
"Intended Audience :: Developers",
|
|
17
|
+
"Intended Audience :: Science/Research",
|
|
18
|
+
"Operating System :: MacOS",
|
|
19
|
+
"Programming Language :: Python :: 3",
|
|
20
|
+
"Topic :: Scientific/Engineering :: Artificial Intelligence",
|
|
21
|
+
]
|
|
22
|
+
dependencies = ["torch>=2.1"]
|
|
23
|
+
|
|
24
|
+
[project.optional-dependencies]
|
|
25
|
+
test = ["pytest>=7", "ruff>=0.6", "numpy>=1.24", "pillow>=10", "safetensors>=0.4"]
|
|
26
|
+
bench = ["numpy>=1.24", "trimesh>=4", "matplotlib>=3.7", "pillow>=10"]
|
|
27
|
+
|
|
28
|
+
[project.scripts]
|
|
29
|
+
stageload = "stageload.cli:main"
|
|
30
|
+
stageload-pixal3d = "stageload.pixal3d.cli:main"
|
|
31
|
+
|
|
32
|
+
[project.urls]
|
|
33
|
+
Homepage = "https://github.com/nefayran/stageload"
|
|
34
|
+
Issues = "https://github.com/nefayran/stageload/issues"
|
|
35
|
+
|
|
36
|
+
[tool.hatch.version]
|
|
37
|
+
path = "src/stageload/__init__.py"
|
|
38
|
+
|
|
39
|
+
[tool.hatch.build.targets.wheel]
|
|
40
|
+
packages = ["src/stageload"]
|
|
41
|
+
|
|
42
|
+
# the bench folder holds local run outputs next to the tracked results; the sdist takes only the package and its tests
|
|
43
|
+
[tool.hatch.build.targets.sdist]
|
|
44
|
+
include = ["/src", "/tests", "/README.md", "/LICENSE", "/pyproject.toml"]
|
|
45
|
+
|
|
46
|
+
[tool.ruff]
|
|
47
|
+
line-length = 100
|
|
48
|
+
target-version = "py310"
|
|
49
|
+
extend-exclude = ["tests/fake_port"]
|
|
50
|
+
|
|
51
|
+
[tool.ruff.lint]
|
|
52
|
+
select = ["E", "F", "W", "I", "B", "UP"]
|
|
53
|
+
|
|
54
|
+
[tool.pytest.ini_options]
|
|
55
|
+
testpaths = ["tests"]
|
|
56
|
+
pythonpath = ["."]
|
|
@@ -0,0 +1,23 @@
|
|
|
1
|
+
"""Load a multi-stage PyTorch pipeline one stage at a time."""
|
|
2
|
+
|
|
3
|
+
from .events import Event, EventSink, ListSink
|
|
4
|
+
from .hooks import on_call
|
|
5
|
+
from .meter import MemoryMeter
|
|
6
|
+
from .registry import StagedModels
|
|
7
|
+
from .release import ReleasedModuleError, ReleaseStats, release
|
|
8
|
+
from .share import share
|
|
9
|
+
|
|
10
|
+
__version__ = "0.1.0"
|
|
11
|
+
|
|
12
|
+
__all__ = [
|
|
13
|
+
"Event",
|
|
14
|
+
"EventSink",
|
|
15
|
+
"ListSink",
|
|
16
|
+
"MemoryMeter",
|
|
17
|
+
"ReleaseStats",
|
|
18
|
+
"ReleasedModuleError",
|
|
19
|
+
"StagedModels",
|
|
20
|
+
"on_call",
|
|
21
|
+
"release",
|
|
22
|
+
"share",
|
|
23
|
+
]
|