specpair 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- specpair-0.1.0/.gitignore +44 -0
- specpair-0.1.0/CHANGELOG.md +19 -0
- specpair-0.1.0/LICENSE +21 -0
- specpair-0.1.0/PKG-INFO +349 -0
- specpair-0.1.0/README.ko.md +317 -0
- specpair-0.1.0/README.md +325 -0
- specpair-0.1.0/pyproject.toml +47 -0
- specpair-0.1.0/src/specpair/__init__.py +49 -0
- specpair-0.1.0/src/specpair/__main__.py +3 -0
- specpair-0.1.0/src/specpair/bench.py +281 -0
- specpair-0.1.0/src/specpair/cli.py +213 -0
- specpair-0.1.0/src/specpair/demo.py +76 -0
- specpair-0.1.0/src/specpair/demo_files/bench_replay.json +121 -0
- specpair-0.1.0/src/specpair/demo_files/broken.gguf +0 -0
- specpair-0.1.0/src/specpair/demo_files/draft-ok.gguf +0 -0
- specpair-0.1.0/src/specpair/demo_files/draft-other.gguf +0 -0
- specpair-0.1.0/src/specpair/demo_files/draft-spm.gguf +0 -0
- specpair-0.1.0/src/specpair/demo_files/draft-wide.gguf +0 -0
- specpair-0.1.0/src/specpair/demo_files/hf-draft/tokenizer.json +1035 -0
- specpair-0.1.0/src/specpair/demo_files/hf-draft/tokenizer_config.json +5 -0
- specpair-0.1.0/src/specpair/demo_files/target.gguf +0 -0
- specpair-0.1.0/src/specpair/errors.py +65 -0
- specpair-0.1.0/src/specpair/gguf_header.py +186 -0
- specpair-0.1.0/src/specpair/hf_tokenizer.py +112 -0
- specpair-0.1.0/src/specpair/i18n.py +399 -0
- specpair-0.1.0/src/specpair/replay.py +124 -0
- specpair-0.1.0/src/specpair/report.py +195 -0
- specpair-0.1.0/src/specpair/rules/llama.cpp-b12360.json +27 -0
- specpair-0.1.0/src/specpair/rules.py +206 -0
- specpair-0.1.0/src/specpair/ruleset.py +24 -0
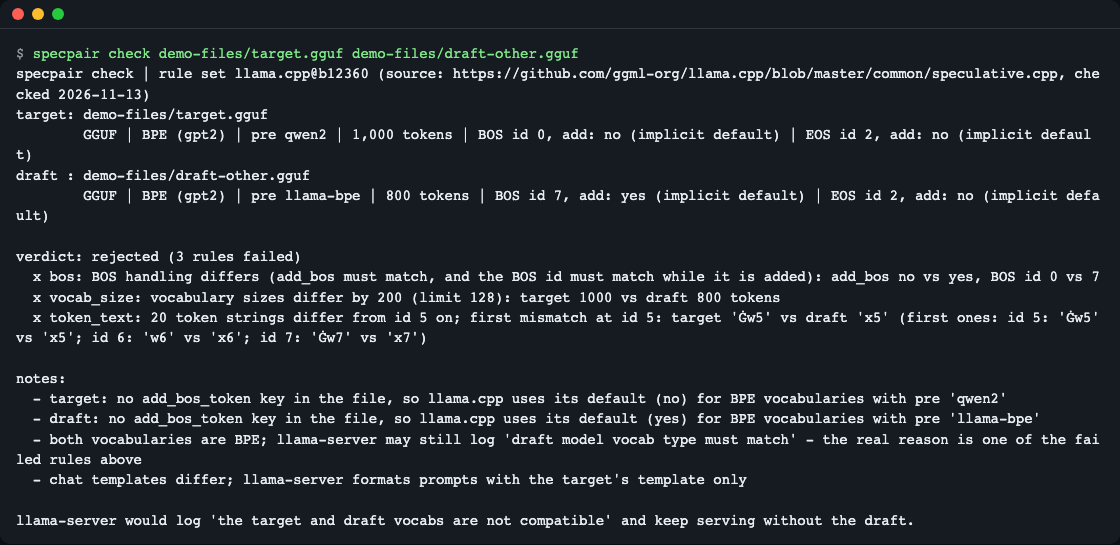
- specpair-0.1.0/src/specpair/scan.py +92 -0
- specpair-0.1.0/src/specpair/vocab.py +109 -0
- specpair-0.1.0/tests/conftest.py +98 -0
- specpair-0.1.0/tests/test_bench.py +243 -0
- specpair-0.1.0/tests/test_cli.py +124 -0
- specpair-0.1.0/tests/test_demo.py +54 -0
- specpair-0.1.0/tests/test_errors.py +145 -0
- specpair-0.1.0/tests/test_fixtures.py +42 -0
- specpair-0.1.0/tests/test_gguf_header.py +116 -0
- specpair-0.1.0/tests/test_hf_tokenizer.py +112 -0
- specpair-0.1.0/tests/test_i18n.py +141 -0
- specpair-0.1.0/tests/test_rules.py +152 -0
- specpair-0.1.0/tests/test_scan.py +92 -0
- specpair-0.1.0/tools/make_fixtures.py +218 -0
|
@@ -0,0 +1,44 @@
|
|
|
1
|
+
# Python
|
|
2
|
+
__pycache__/
|
|
3
|
+
*.py[cod]
|
|
4
|
+
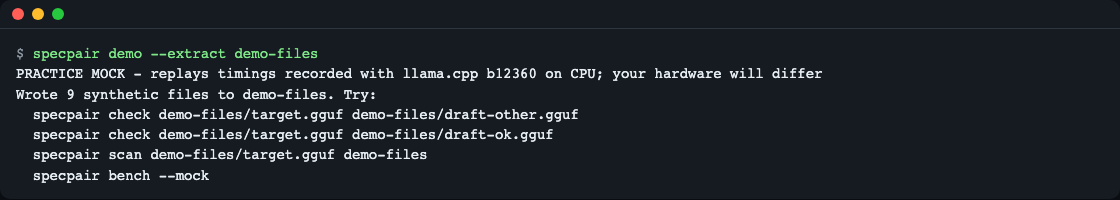
.venv/
|
|
5
|
+
.pytest_cache/
|
|
6
|
+
.ruff_cache/
|
|
7
|
+
.mypy_cache/
|
|
8
|
+
*.egg-info/
|
|
9
|
+
|
|
10
|
+
# Node
|
|
11
|
+
node_modules/
|
|
12
|
+
dist/
|
|
13
|
+
.next/
|
|
14
|
+
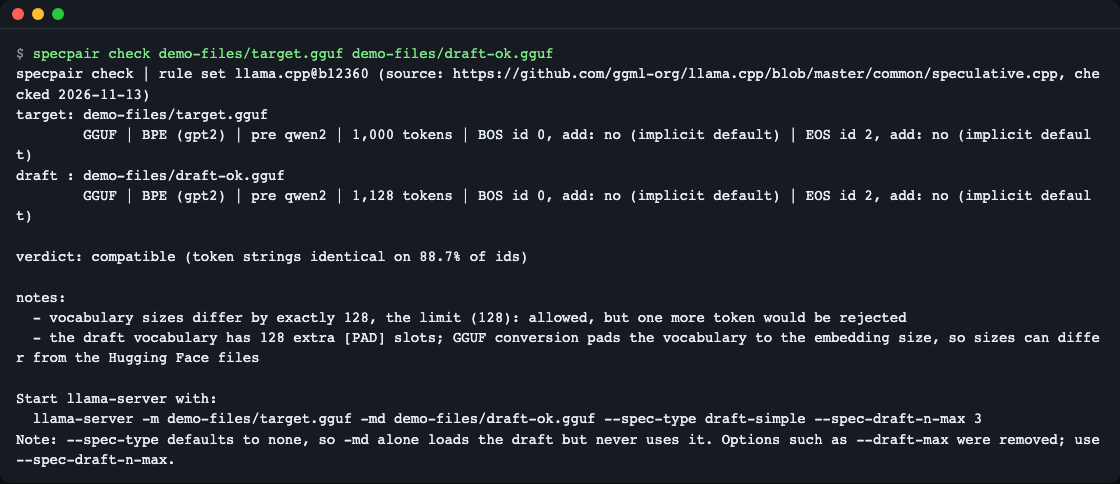
|
|
15
|
+
# 실행 산출물·모델·데이터 캐시
|
|
16
|
+
runs/
|
|
17
|
+
outputs/
|
|
18
|
+
.cache/
|
|
19
|
+
*.safetensors
|
|
20
|
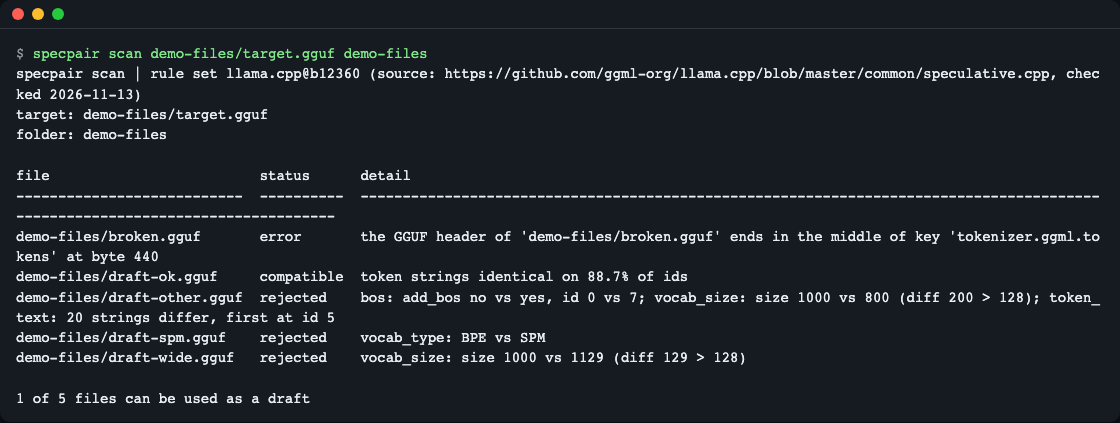
+
*.gguf
|
|
21
|
+
*.bin
|
|
22
|
+
|
|
23
|
+
# 환경·비밀
|
|
24
|
+
.env
|
|
25
|
+
.env.*
|
|
26
|
+
!.env.example
|
|
27
|
+
|
|
28
|
+
# OS·에디터
|
|
29
|
+
.DS_Store
|
|
30
|
+
.vscode/
|
|
31
|
+
.idea/
|
|
32
|
+
|
|
33
|
+
# Flutter·Dart
|
|
34
|
+
.dart_tool/
|
|
35
|
+
build/
|
|
36
|
+
.flutter-plugins
|
|
37
|
+
.flutter-plugins-dependencies
|
|
38
|
+
coverage/
|
|
39
|
+
|
|
40
|
+
# 번들 데모 파일(합성 헤더 전용 GGUF, 수 KB)은 추적한다
|
|
41
|
+
!src/specpair/demo_files/*.gguf
|
|
42
|
+
|
|
43
|
+
# 연습용 파일을 README 명령으로 꺼낸 폴더
|
|
44
|
+
/demo-files/
|
|
@@ -0,0 +1,19 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to this project are documented in this file.
|
|
4
|
+
The format follows [Keep a Changelog](https://keepachangelog.com/en/1.1.0/) and the project uses
|
|
5
|
+
[Semantic Versioning](https://semver.org/).
|
|
6
|
+
|
|
7
|
+
## [Unreleased]
|
|
8
|
+
|
|
9
|
+
## [0.1.0] - 2026-11-13
|
|
10
|
+
|
|
11
|
+
### Added
|
|
12
|
+
- `specpair check TARGET DRAFT`: pre-load verdict for the `llama.cpp@b12360` rule set from GGUF headers or
|
|
13
|
+
Hugging Face tokenizer folders, listing every failing rule with the first mismatching tokens.
|
|
14
|
+
- `specpair scan TARGET DIR`: verdicts for every GGUF in a folder; corrupt files become error rows.
|
|
15
|
+
- `specpair bench`: tokens/s, acceptance rate and speedup from llama-server timings, with warnings for a draft
|
|
16
|
+
that is not used and for settings that are slower than the baseline.
|
|
17
|
+
- `specpair demo` and `bench --mock`: offline practice mode with synthetic GGUF headers and replayed timings.
|
|
18
|
+
- English and Korean output (`--lang`, `SPECPAIR_LANG`, locale), `--json` output, stable exit codes.
|
|
19
|
+
- Small public Python API: `load_vocab`, `check_pair`, `recommended_command`, exception classes.
|
specpair-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 LeeGyeongPil
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
specpair-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,349 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: specpair
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Check whether a draft model can speculate for a target model (GGUF headers or HF tokenizers) and measure the real speedup on llama-server.
|
|
5
|
+
Project-URL: Homepage, https://github.com/LeeGyeongPil/specpair
|
|
6
|
+
Project-URL: Issues, https://github.com/LeeGyeongPil/specpair/issues
|
|
7
|
+
Project-URL: Changelog, https://github.com/LeeGyeongPil/specpair/blob/main/CHANGELOG.md
|
|
8
|
+
Author: LeeGyeongPil
|
|
9
|
+
License: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Keywords: draft-model,gguf,llama-server,llama.cpp,speculative-decoding,tokenizer
|
|
12
|
+
Classifier: Development Status :: 3 - Alpha
|
|
13
|
+
Classifier: Environment :: Console
|
|
14
|
+
Classifier: Intended Audience :: Developers
|
|
15
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
16
|
+
Classifier: Programming Language :: Python :: 3
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
21
|
+
Classifier: Topic :: Software Development :: Testing
|
|
22
|
+
Requires-Python: >=3.10
|
|
23
|
+
Description-Content-Type: text/markdown
|
|
24
|
+
|
|
25
|
+
# specpair
|
|
26
|
+
|
|
27
|
+
**English** | [한국어](https://github.com/LeeGyeongPil/specpair/blob/v0.1.0/README.ko.md)
|
|
28
|
+
|
|
29
|
+
specpair checks, before you load anything, whether a small draft model can speed up a big target model with speculative decoding in llama.cpp. It reads only the GGUF headers (or Hugging Face tokenizer files), applies the same rules llama-server applies, and lists every rule that fails. After you start the servers, `specpair bench` measures tokens per second and the draft acceptance rate, so you can see whether the draft really helped. It has no runtime dependencies and needs no model files to try (a practice mode ships with it).
|
|
30
|
+
|
|
31
|
+
|
|
32
|
+
*`specpair check` on a rejected pair: all three failing rules are shown at once, with the first mismatching token (practice files).*
|
|
33
|
+
|
|
34
|
+
## Why
|
|
35
|
+
|
|
36
|
+
Three things surprise people who add a draft model to llama-server (checked 2026-11-13 against [`common/speculative.cpp`](https://github.com/ggml-org/llama.cpp/blob/master/common/speculative.cpp) and the project's own probe on llama.cpp b12360):
|
|
37
|
+
|
|
38
|
+
- A rejected pair is not an error. llama-server logs `the target and draft vocabs are not compatible` and keeps serving at single-model speed, so you may not notice.
|
|
39
|
+
- `-md` alone does not use the draft: `--spec-type` defaults to `none`.
|
|
40
|
+
- A high acceptance rate does not guarantee a gain. In the recorded probe, a draft setting with 46.9% accepted draft tokens was 29.7% slower than no draft.
|
|
41
|
+
|
|
42
|
+
## Who it is for
|
|
43
|
+
|
|
44
|
+
- You run `llama-server` and want to pick a draft GGUF from a folder of downloads without loading each one.
|
|
45
|
+
- `llama-server` printed `draft model vocab type must match`, or your GUI shows an empty draft list, and you want the real reason.
|
|
46
|
+
- You added a draft model and the server did not get faster, and you want to know whether the draft was even used.
|
|
47
|
+
|
|
48
|
+
Think of two interpreters at a meeting: the fast one can only guess ahead if both use the same dictionary. The check compares the dictionaries (token lists); the benchmark measures whether guessing ahead actually saves time.
|
|
49
|
+
|
|
50
|
+
## Install
|
|
51
|
+
|
|
52
|
+
```bash
|
|
53
|
+
# uv (Python package runner): https://docs.astral.sh/uv/
|
|
54
|
+
curl -LsSf https://astral.sh/uv/install.sh | sh
|
|
55
|
+
# run without installing
|
|
56
|
+
uvx --from git+https://github.com/LeeGyeongPil/specpair specpair --version
|
|
57
|
+
# or install the command
|
|
58
|
+
uv tool install git+https://github.com/LeeGyeongPil/specpair
|
|
59
|
+
```
|
|
60
|
+
|
|
61
|
+
Python 3.10 or newer; no other packages. On a minimal Linux image you also need `git` and `curl` for the commands above. The rest of this page assumes the `specpair` command is on your PATH.
|
|
62
|
+
|
|
63
|
+
## Quick start (practice mock)
|
|
64
|
+
|
|
65
|
+
No model download needed. `specpair demo` runs everything on tiny synthetic GGUF headers and on timings recorded earlier, so it works offline in about a second.
|
|
66
|
+
|
|
67
|
+
```bash
|
|
68
|
+
specpair demo --extract demo-files
|
|
69
|
+
```
|
|
70
|
+
|
|
71
|
+
```text
|
|
72
|
+
PRACTICE MOCK - replays timings recorded with llama.cpp b12360 on CPU; your hardware will differ
|
|
73
|
+
Wrote 9 synthetic files to demo-files. Try:
|
|
74
|
+
specpair check demo-files/target.gguf demo-files/draft-other.gguf
|
|
75
|
+
specpair check demo-files/target.gguf demo-files/draft-ok.gguf
|
|
76
|
+
specpair scan demo-files/target.gguf demo-files
|
|
77
|
+
specpair bench --mock
|
|
78
|
+
```
|
|
79
|
+
|
|
80
|
+
|
|
81
|
+
*The practice files are copied to `demo-files/`. The files are real GGUF headers, so `check` and `scan` run the real rules on them.*
|
|
82
|
+
|
|
83
|
+
Plain `specpair demo` (without `--extract`) prints a guided tour of all the steps below.
|
|
84
|
+
|
|
85
|
+
What is real and what is mock in practice mode:
|
|
86
|
+
|
|
87
|
+
| Part | Practice mode |
|
|
88
|
+
|---|---|
|
|
89
|
+
| `check`, `scan` | Real code on synthetic GGUF headers (a few KB, no weights). |
|
|
90
|
+
| `bench --mock` | The real HTTP client and math, talking to a local replay server. The numbers are timings recorded from llama.cpp b12360 on a CPU (Qwen2.5-1.5B and 0.5B, q4_0), not measured on your machine. The `rejected` line is derived: it reuses the baseline timings and reports no `draft_n`, which reproduces what the recording showed for a rejected pair (llama-server kept serving at the single-model speed). |
|
|
91
|
+
|
|
92
|
+
## Usage
|
|
93
|
+
|
|
94
|
+
| Command | What it does |
|
|
95
|
+
|---|---|
|
|
96
|
+
| `specpair check TARGET DRAFT` | Pre-load verdict for one pair; GGUF files or tokenizer folders |
|
|
97
|
+
| `specpair scan TARGET DIR` | Verdict table for every GGUF in a folder (and its direct sub-folders) |
|
|
98
|
+
| `specpair bench --base URL --spec [LABEL=]URL` | Compare running llama-server instances on the same prompts |
|
|
99
|
+
| `specpair bench --mock` | Practice replay of recorded timings |
|
|
100
|
+
| `specpair demo [--extract DIR]` | Offline tour / copy practice files |
|
|
101
|
+
| `--json`, `--lang en\|ko` | Machine-readable output, screen language |
|
|
102
|
+
|
|
103
|
+
### Check a pair
|
|
104
|
+
|
|
105
|
+
```bash
|
|
106
|
+
specpair check demo-files/target.gguf demo-files/draft-other.gguf
|
|
107
|
+
```
|
|
108
|
+
|
|
109
|
+

|
|
110
|
+
*Rejected: the BOS handling, the vocabulary size and the token strings all differ. llama.cpp stops at the first failure; specpair shows all of them.*
|
|
111
|
+
|
|
112
|
+
Read it like this: `verdict: rejected (3 rules failed)` means llama-server would log `the target and draft vocabs are not compatible` and keep serving without the draft. Each `x` line names the rule and the numbers. The exit code is 1 for a rejected pair.
|
|
113
|
+
|
|
114
|
+
The five rules of the `llama.cpp@b12360` rule set:
|
|
115
|
+
|
|
116
|
+
| Rule | Fails when |
|
|
117
|
+
|---|---|
|
|
118
|
+
| `vocab_type` | The tokenizer kinds differ (BPE vs SPM and so on). |
|
|
119
|
+
| `bos` | The "add BOS" flags differ, or, while BOS is added, the BOS ids differ. |
|
|
120
|
+
| `eos` | Same, for EOS. |
|
|
121
|
+
| `vocab_size` | The vocabulary sizes differ by more than 128. |
|
|
122
|
+
| `token_text` | Any token string differs from id 5 on. |
|
|
123
|
+
|
|
124
|
+
A pair that passes:
|
|
125
|
+
|
|
126
|
+
```bash
|
|
127
|
+
specpair check demo-files/target.gguf demo-files/draft-ok.gguf
|
|
128
|
+
```
|
|
129
|
+
|
|
130
|
+
|
|
131
|
+
*Compatible. The size difference is exactly 128, the limit, so one more token would be rejected, and the output says so. It also prints the llama-server command to use.*
|
|
132
|
+
|
|
133
|
+
Note the line `--spec-type defaults to none, so -md alone loads the draft but never uses it`. Options such as `--draft-max` were removed in b12360; use `--spec-draft-n-max`.
|
|
134
|
+
|
|
135
|
+
The limit is easy to hit in real life: in the project's own probe, Qwen2.5-7B and Qwen2.5-0.5B GGUF files differ by exactly 128 tokens (152,064 vs 151,936). Hugging Face tokenizer files can show different sizes than GGUF files because conversion pads the vocabulary; specpair adds a note when it sees that, so confirm with the GGUF files. A tokenizer folder works as either side:
|
|
136
|
+
|
|
137
|
+
```bash
|
|
138
|
+
specpair check demo-files/target.gguf demo-files/hf-draft
|
|
139
|
+
```
|
|
140
|
+
|
|
141
|
+
```text
|
|
142
|
+
specpair check | rule set llama.cpp@b12360 (source: https://github.com/ggml-org/llama.cpp/blob/master/common/speculative.cpp, checked 2026-11-13)
|
|
143
|
+
target: demo-files/target.gguf
|
|
144
|
+
GGUF | BPE (gpt2) | pre qwen2 | 1,000 tokens | BOS id 0, add: no (implicit default) | EOS id 2, add: no (implicit default)
|
|
145
|
+
draft : demo-files/hf-draft
|
|
146
|
+
HF | BPE | 1,000 tokens | BOS id 0, add: no (implicit default) | EOS id 2, add: no (implicit default)
|
|
147
|
+
|
|
148
|
+
verdict: compatible (token strings identical on 100.0% of ids)
|
|
149
|
+
|
|
150
|
+
notes:
|
|
151
|
+
- a Hugging Face tokenizer folder was used; GGUF conversion can change the vocabulary size (padding) and the add_bos default, so confirm with the GGUF files
|
|
152
|
+
|
|
153
|
+
Compatible by tokenizer files. Convert both models to GGUF and check the GGUF files before building a command.
|
|
154
|
+
```
|
|
155
|
+
|
|
156
|
+
A split model (`...-00001-of-00002.gguf`) works with its first file; partial downloads are fine as long as the header is complete.
|
|
157
|
+
|
|
158
|
+
### Scan a folder
|
|
159
|
+
|
|
160
|
+
```bash
|
|
161
|
+
specpair scan demo-files/target.gguf demo-files
|
|
162
|
+
```
|
|
163
|
+
|
|
164
|
+
|
|
165
|
+
*One row per GGUF. The broken file becomes an `error` row with the byte position, and the scan continues.*
|
|
166
|
+
|
|
167
|
+
The exit code is 0 when at least one draft fits, 1 when none does.
|
|
168
|
+
|
|
169
|
+
### Measure with llama-server
|
|
170
|
+
|
|
171
|
+
A compatible pair is necessary, not sufficient. Start one baseline server and one or more draft servers (file names below are placeholders for your own GGUF files; the flags are the ones `check` prints):
|
|
172
|
+
|
|
173
|
+
```bash
|
|
174
|
+
llama-server -m target.gguf --port 8080
|
|
175
|
+
llama-server -m target.gguf -md draft.gguf --spec-type draft-simple --spec-draft-n-max 3 --port 8081
|
|
176
|
+
llama-server -m target.gguf -md draft.gguf --spec-type draft-simple --spec-draft-n-max 8 --port 8082
|
|
177
|
+
specpair bench --base http://127.0.0.1:8080 --spec n3=http://127.0.0.1:8081 --spec n8=http://127.0.0.1:8082
|
|
178
|
+
```
|
|
179
|
+
|
|
180
|
+
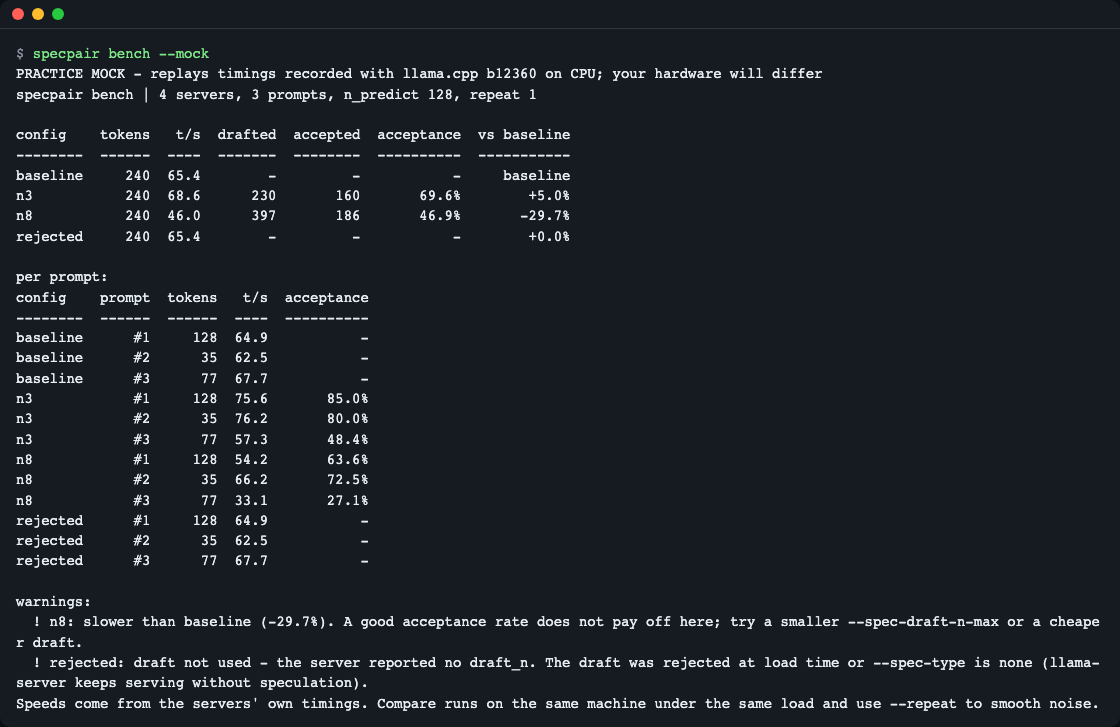
Each server must be up (`/health` answers) before `bench` starts. Run them on the same machine under the same load. `bench` sends the same prompts (3 built-in ones, or `--prompts FILE` with one prompt per line or JSONL), greedy decoding, 128 tokens by default (`--n-predict`), one warm-up request, and `--repeat N` smooths noise. It uses the timings the servers report, not wall-clock time. Real runs can take tens of seconds per server, more when the machine is busy.
|
|
181
|
+
|
|
182
|
+
The practice version replays recorded timings through the same code:
|
|
183
|
+
|
|
184
|
+
```bash
|
|
185
|
+
specpair bench --mock
|
|
186
|
+
```
|
|
187
|
+
|
|
188
|
+
|
|
189
|
+
*Practice mock. n3 is +5.0% faster, n8 is 29.7% slower even though 46.9% of its draft tokens were accepted, and `rejected` ran at baseline speed with no draft.*
|
|
190
|
+
|
|
191
|
+
How to read the table and the warnings:
|
|
192
|
+
|
|
193
|
+
| Column or warning | Meaning |
|
|
194
|
+
|---|---|
|
|
195
|
+
| `t/s` | Generated tokens per second, from the servers' own timings |
|
|
196
|
+
| `drafted`, `accepted`, `acceptance` | Draft tokens proposed, accepted by the target, and their ratio |
|
|
197
|
+
| `vs baseline` | Speed relative to the server without a draft |
|
|
198
|
+
| `slower than baseline` | The setting is more than 2% slower; a high acceptance rate does not guarantee a gain, try a smaller `--spec-draft-n-max` or a cheaper draft |
|
|
199
|
+
| `draft not used` | The server reported no `draft_n`: the draft was rejected at load time, or `--spec-type` is `none` |
|
|
200
|
+
| `output differs` | With greedy decoding the text should match the baseline; a difference is worth a look (does not change the exit code) |
|
|
201
|
+
|
|
202
|
+
## Settings
|
|
203
|
+
|
|
204
|
+
### Language
|
|
205
|
+
|
|
206
|
+
| Setting | Meaning |
|
|
207
|
+
|---|---|
|
|
208
|
+
| `--lang en\|ko` | Screen language. Before or after the sub-command. |
|
|
209
|
+
| `SPECPAIR_LANG=en\|ko` | Same, via environment. |
|
|
210
|
+
| `LC_ALL`, `LC_MESSAGES`, `LANG` | Used when nothing above is set: a value starting with `ko` selects Korean, anything else English. |
|
|
211
|
+
|
|
212
|
+
Order: `--lang`, then `SPECPAIR_LANG`, then the locale variables. Help (`--help`), tables, warnings and runtime errors are translated. Only argparse's usage-error messages stay English, for example `the following arguments are required: draft` and `invalid choice: ...`; in Korean mode the `오류:` prefix and the usage line are still Korean.
|
|
213
|
+
|
|
214
|
+
```bash
|
|
215
|
+
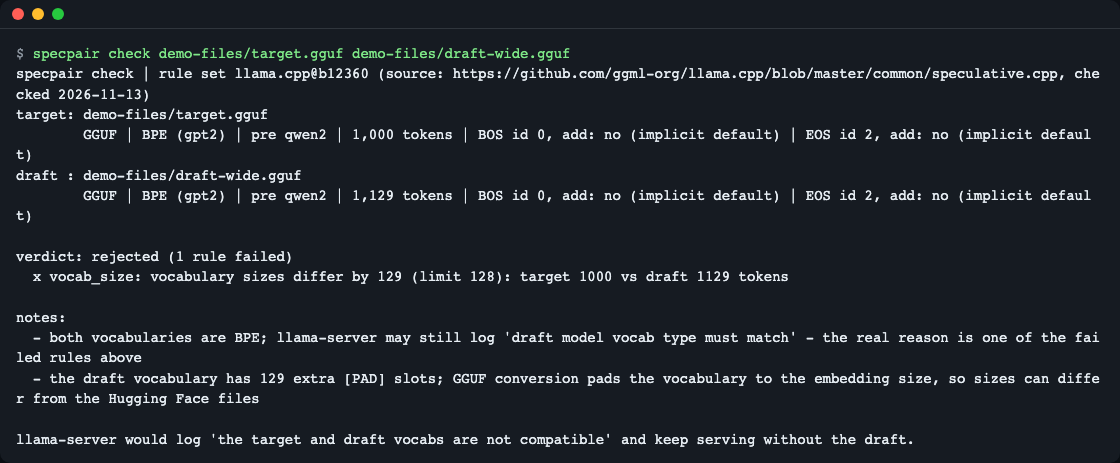
specpair check demo-files/target.gguf demo-files/draft-wide.gguf
|
|
216
|
+
```
|
|
217
|
+
|
|
218
|
+
|
|
219
|
+
*One rule fails: the vocabulary sizes differ by 129, one more than the limit. The screen language here is English (`SPECPAIR_LANG=en`).*
|
|
220
|
+
|
|
221
|
+
The same pair in Korean:
|
|
222
|
+
|
|
223
|
+
```bash
|
|
224
|
+
specpair --lang ko check demo-files/target.gguf demo-files/draft-wide.gguf
|
|
225
|
+
```
|
|
226
|
+
|
|
227
|
+
```text
|
|
228
|
+
specpair check | 규칙 세트 llama.cpp@b12360 (출처: https://github.com/ggml-org/llama.cpp/blob/master/common/speculative.cpp, 확인일 2026-11-13)
|
|
229
|
+
대상 : demo-files/target.gguf
|
|
230
|
+
GGUF | BPE (gpt2) | pre qwen2 | 토큰 1,000개 | BOS id 0, 추가: 아니오 (암묵 기본값) | EOS id 2, 추가: 아니오 (암묵 기본값)
|
|
231
|
+
드래프트: demo-files/draft-wide.gguf
|
|
232
|
+
GGUF | BPE (gpt2) | pre qwen2 | 토큰 1,129개 | BOS id 0, 추가: 아니오 (암묵 기본값) | EOS id 2, 추가: 아니오 (암묵 기본값)
|
|
233
|
+
|
|
234
|
+
판정: rejected (실패한 규칙 1개)
|
|
235
|
+
x vocab_size: 어휘 크기 차이가 129 입니다(상한 128): 대상 1000개 / 드래프트 1129개
|
|
236
|
+
|
|
237
|
+
참고:
|
|
238
|
+
- 두 어휘가 모두 BPE 입니다. llama-server 가 'draft model vocab type must match' 를 남기더라도 실제 원인은 위에서 실패한 규칙입니다
|
|
239
|
+
- 드래프트 어휘에 [PAD] 슬롯이 129개 더 있습니다. GGUF 변환은 어휘를 임베딩 크기까지 채우므로 Hugging Face 파일과 크기가 다를 수 있습니다
|
|
240
|
+
|
|
241
|
+
llama-server 는 'the target and draft vocabs are not compatible' 를 남기고 드래프트 없이 계속 서비스합니다.
|
|
242
|
+
```
|
|
243
|
+
|
|
244
|
+
The screenshots in this README were taken with `SPECPAIR_LANG=en`; the Korean README shows the same commands with `SPECPAIR_LANG=ko`. There are no keys and no network calls apart from `bench` talking to your own servers.
|
|
245
|
+
|
|
246
|
+
### JSON output and exit codes
|
|
247
|
+
|
|
248
|
+
`check`, `scan` and `bench` accept `--json`. Keys are English in every language; only `message` strings follow the language.
|
|
249
|
+
|
|
250
|
+
```bash
|
|
251
|
+
specpair check --json demo-files/target.gguf demo-files/draft-wide.gguf
|
|
252
|
+
```
|
|
253
|
+
|
|
254
|
+
```text
|
|
255
|
+
{
|
|
256
|
+
"schema_version": 1,
|
|
257
|
+
"runtime": "llama.cpp@b12360",
|
|
258
|
+
"verdict": "rejected",
|
|
259
|
+
"failures": [
|
|
260
|
+
{
|
|
261
|
+
"rule": "vocab_size",
|
|
262
|
+
"message": "vocabulary sizes differ by 129 (limit 128): target 1000 vs draft 1129 tokens",
|
|
263
|
+
"evidence": {
|
|
264
|
+
"target": 1000,
|
|
265
|
+
"draft": 1129,
|
|
266
|
+
"diff": 129,
|
|
267
|
+
"max": 128
|
|
268
|
+
}
|
|
269
|
+
}
|
|
270
|
+
],
|
|
271
|
+
...
|
|
272
|
+
```
|
|
273
|
+
|
|
274
|
+
(The output continues with `notes`, `target`, `draft`, `same_id_ratio` and `recommended_command`, which is `null` for a rejected pair.)
|
|
275
|
+
|
|
276
|
+
Exit codes: 0 fine, 1 a verdict failure (rejected pair, no usable draft in `scan`, or a `bench` warning such as `slower than baseline` or `draft not used`), 2 input or connection errors with a defined message and no traceback (for example an empty file: `'x.gguf' is empty (0 bytes). Download it again or pass the right file.`).
|
|
277
|
+
|
|
278
|
+
### Python API
|
|
279
|
+
|
|
280
|
+
Install it into your project environment first (the `uvx` and `uv tool install` commands above keep it in an isolated tool environment):
|
|
281
|
+
|
|
282
|
+
```bash
|
|
283
|
+
uv pip install git+https://github.com/LeeGyeongPil/specpair
|
|
284
|
+
```
|
|
285
|
+
|
|
286
|
+
```python
|
|
287
|
+
from specpair import check_pair, load_vocab
|
|
288
|
+
|
|
289
|
+
target = load_vocab("demo-files/target.gguf")
|
|
290
|
+
draft = load_vocab("demo-files/draft-wide.gguf")
|
|
291
|
+
result = check_pair(target, draft)
|
|
292
|
+
print(result.verdict, [f.rule for f in result.failures])
|
|
293
|
+
```
|
|
294
|
+
|
|
295
|
+
```text
|
|
296
|
+
rejected ['vocab_size']
|
|
297
|
+
```
|
|
298
|
+
|
|
299
|
+
`load_vocab` accepts a GGUF file or a tokenizer folder. Errors derive from `SpecpairError` (for example `InputNotFoundError`, `NotGGUFError`, `TruncatedHeaderError`).
|
|
300
|
+
|
|
301
|
+
## How it works
|
|
302
|
+
|
|
303
|
+
```mermaid
|
|
304
|
+
flowchart LR
|
|
305
|
+
A[GGUF header or<br/>tokenizer.json] --> B[load_vocab]
|
|
306
|
+
B --> C[5 rules<br/>llama.cpp@b12360]
|
|
307
|
+
C --> D[verdict +<br/>every failing rule]
|
|
308
|
+
E[llama-server<br/>/completion timings] --> F[bench]
|
|
309
|
+
F --> G[t/s, acceptance,<br/>vs baseline, warnings]
|
|
310
|
+
```
|
|
311
|
+
|
|
312
|
+
- The GGUF reader reads only the key-value area at the start of the file and skips big arrays, so a 4 GB file costs a few megabytes of reading and a truncated download is still usable.
|
|
313
|
+
- The rules live in a data file (`src/specpair/rules/llama.cpp-b12360.json`) with the source and the date they were checked; every output starts with the rule set name.
|
|
314
|
+
- `bench` takes `predicted_n`, `predicted_ms`, `draft_n` and `draft_n_accepted` from each server's response, so there is nothing to parse in logs.
|
|
315
|
+
|
|
316
|
+
## Rule set and versions
|
|
317
|
+
|
|
318
|
+
The rules follow llama.cpp build b12360 (`common/speculative.cpp`, checked 2026-11-13: https://github.com/ggml-org/llama.cpp/blob/master/common/speculative.cpp). Options and checks change between builds; the output header always names the rule set, and `--runtime` only accepts rule sets that exist. Not covered: vLLM, SGLang, MLX, dedicated draft heads (EAGLE-style, MTP), and drafts with a different vocabulary.
|
|
319
|
+
|
|
320
|
+
## When to use it
|
|
321
|
+
|
|
322
|
+
- Good fit: you serve GGUF models with llama-server and want to know, before downloading or loading, whether a draft pair is accepted, and afterwards whether it is faster.
|
|
323
|
+
- Other tools: LM Studio filters its draft list inside the app ([LM Studio](https://lmstudio.ai/)); for engines other than llama.cpp use that engine's own documentation, for example [vLLM](https://docs.vllm.ai/).
|
|
324
|
+
|
|
325
|
+
## Troubleshooting
|
|
326
|
+
|
|
327
|
+
| Symptom | Cause | Fix |
|
|
328
|
+
|---|---|---|
|
|
329
|
+
| Server runs but is not faster | `--spec-type` defaults to `none`, so `-md` alone does not use the draft | Add `--spec-type draft-simple --spec-draft-n-max 3` |
|
|
330
|
+
| `the argument has been removed` for `--draft-max` | The old option names were removed in b12360 | Use `--spec-draft-n-max`; `check` prints the current command |
|
|
331
|
+
| Log says `draft model vocab type must match`, but both are BPE | The message is misleading; the real reason is another rule | Run `specpair check` and read the failing rules |
|
|
332
|
+
| `bench`: `draft not used` | Draft rejected at load, or `--spec-type none` | Check the pair, then the flags |
|
|
333
|
+
| `bench`: `slower than baseline` | Too many draft tokens per step, or a draft that is too costly | Try a smaller `--spec-draft-n-max` or a cheaper draft |
|
|
334
|
+
| `is empty (0 bytes)` or `ends inside the fixed GGUF header` (exit 2) | The download is empty or cut before the header ends | Download it again |
|
|
335
|
+
| `error ... ends in the middle of key` | The GGUF file is cut inside the header | Download it again |
|
|
336
|
+
| `cannot reach llama-server` (exit 2) | The server is not running yet or the URL is wrong | Start it and wait for `/health` |
|
|
337
|
+
| The Hugging Face check says compatible, GGUF files say rejected | Conversion pads the vocabulary | Trust the GGUF check |
|
|
338
|
+
|
|
339
|
+
## Development
|
|
340
|
+
|
|
341
|
+
```bash
|
|
342
|
+
uv run pytest -q
|
|
343
|
+
```
|
|
344
|
+
|
|
345
|
+
The tests use synthetic files only; no model is downloaded. `uv run python tools/make_fixtures.py [OUT_DIR]` regenerates the bundled practice files byte for byte. Report bugs and ideas as issues. Changes are listed in [CHANGELOG.md](https://github.com/LeeGyeongPil/specpair/blob/v0.1.0/CHANGELOG.md).
|
|
346
|
+
|
|
347
|
+
## License
|
|
348
|
+
|
|
349
|
+
MIT. The practice files are synthetic, and the replayed timings are the project's own measurements with Qwen2.5-1.5B-Instruct and Qwen2.5-0.5B-Instruct (Apache-2.0) on llama.cpp b12360 (MIT); no model weights are included.
|