skillproof 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- skillproof-0.1.0/.github/workflows/action-selftest.yml +31 -0
- skillproof-0.1.0/.github/workflows/ci.yml +35 -0
- skillproof-0.1.0/.github/workflows/release.yml +76 -0
- skillproof-0.1.0/.gitignore +10 -0
- skillproof-0.1.0/CONTRIBUTING.md +65 -0
- skillproof-0.1.0/LICENSE +21 -0
- skillproof-0.1.0/PKG-INFO +262 -0
- skillproof-0.1.0/README.md +228 -0
- skillproof-0.1.0/RELEASING.md +51 -0
- skillproof-0.1.0/action/comment.js +38 -0
- skillproof-0.1.0/action/example-workflow.yml +27 -0
- skillproof-0.1.0/action/test/comment.test.js +64 -0
- skillproof-0.1.0/action.yml +164 -0
- skillproof-0.1.0/docs/demo.gif +0 -0
- skillproof-0.1.0/docs/demo.tape +41 -0
- skillproof-0.1.0/examples/README.md +28 -0
- skillproof-0.1.0/examples/over-eager-formatter/SKILL.md +15 -0
- skillproof-0.1.0/examples/over-eager-formatter/evals.yaml +27 -0
- skillproof-0.1.0/examples/over-eager-formatter/fixtures/greeter/greeting.py +6 -0
- skillproof-0.1.0/examples/over-eager-formatter/fixtures/greeter/legacy.py +3 -0
- skillproof-0.1.0/examples/python-style/SKILL.md +17 -0
- skillproof-0.1.0/examples/python-style/evals.yaml +25 -0
- skillproof-0.1.0/examples/python-style/fixtures/median-bug/stats.py +11 -0
- skillproof-0.1.0/examples/python-style/fixtures/median-bug/test_stats.py +18 -0
- skillproof-0.1.0/examples/release-notes/SKILL.md +36 -0
- skillproof-0.1.0/examples/release-notes/evals.yaml +39 -0
- skillproof-0.1.0/examples/release-notes/fixtures/release/RELEASE_DATE +1 -0
- skillproof-0.1.0/examples/release-notes/fixtures/release/RELEASE_NOTES.md +9 -0
- skillproof-0.1.0/examples/release-notes/fixtures/release/VERSION +1 -0
- skillproof-0.1.0/examples/release-notes/fixtures/release/merged_prs.txt +7 -0
- skillproof-0.1.0/examples/stale-docs/SKILL.md +21 -0
- skillproof-0.1.0/examples/stale-docs/evals.yaml +27 -0
- skillproof-0.1.0/examples/stale-docs/fixtures/report/acme_client.py +15 -0
- skillproof-0.1.0/leaderboard/.gitignore +1 -0
- skillproof-0.1.0/leaderboard/README.md +33 -0
- skillproof-0.1.0/leaderboard/evals/TEMPLATE.yaml +22 -0
- skillproof-0.1.0/leaderboard/leaderboard.py +206 -0
- skillproof-0.1.0/leaderboard/skills.yaml +32 -0
- skillproof-0.1.0/pyproject.toml +64 -0
- skillproof-0.1.0/src/skillproof/__init__.py +3 -0
- skillproof-0.1.0/src/skillproof/__main__.py +3 -0
- skillproof-0.1.0/src/skillproof/assertions/__init__.py +62 -0
- skillproof-0.1.0/src/skillproof/assertions/base.py +44 -0
- skillproof-0.1.0/src/skillproof/assertions/builtin.py +176 -0
- skillproof-0.1.0/src/skillproof/assertions/llm_judge.py +24 -0
- skillproof-0.1.0/src/skillproof/cli.py +313 -0
- skillproof-0.1.0/src/skillproof/config.py +188 -0
- skillproof-0.1.0/src/skillproof/engine.py +268 -0
- skillproof-0.1.0/src/skillproof/errors.py +72 -0
- skillproof-0.1.0/src/skillproof/estimate.py +83 -0
- skillproof-0.1.0/src/skillproof/judges/__init__.py +43 -0
- skillproof-0.1.0/src/skillproof/judges/anthropic_judge.py +59 -0
- skillproof-0.1.0/src/skillproof/judges/base.py +69 -0
- skillproof-0.1.0/src/skillproof/judges/mock.py +21 -0
- skillproof-0.1.0/src/skillproof/judges/openai_judge.py +58 -0
- skillproof-0.1.0/src/skillproof/parsers/__init__.py +6 -0
- skillproof-0.1.0/src/skillproof/parsers/claude_code.py +144 -0
- skillproof-0.1.0/src/skillproof/parsers/codex.py +112 -0
- skillproof-0.1.0/src/skillproof/report/__init__.py +34 -0
- skillproof-0.1.0/src/skillproof/report/badge.py +60 -0
- skillproof-0.1.0/src/skillproof/report/format.py +75 -0
- skillproof-0.1.0/src/skillproof/report/html_report.py +296 -0
- skillproof-0.1.0/src/skillproof/report/json_report.py +9 -0
- skillproof-0.1.0/src/skillproof/report/markdown.py +78 -0
- skillproof-0.1.0/src/skillproof/report/summary.py +216 -0
- skillproof-0.1.0/src/skillproof/report/terminal.py +89 -0
- skillproof-0.1.0/src/skillproof/results.py +88 -0
- skillproof-0.1.0/src/skillproof/runners/__init__.py +33 -0
- skillproof-0.1.0/src/skillproof/runners/base.py +102 -0
- skillproof-0.1.0/src/skillproof/runners/claude_code.py +117 -0
- skillproof-0.1.0/src/skillproof/runners/codex.py +133 -0
- skillproof-0.1.0/src/skillproof/runners/mock.py +91 -0
- skillproof-0.1.0/src/skillproof/runners/openai_compat.py +238 -0
- skillproof-0.1.0/src/skillproof/sandbox.py +85 -0
- skillproof-0.1.0/src/skillproof/scaffold.py +153 -0
- skillproof-0.1.0/src/skillproof/skill.py +97 -0
- skillproof-0.1.0/src/skillproof/stats.py +228 -0
- skillproof-0.1.0/tests/conftest.py +69 -0
- skillproof-0.1.0/tests/fixtures/claude_code_with_skill.json +447 -0
- skillproof-0.1.0/tests/fixtures/claude_code_without_skill.json +353 -0
- skillproof-0.1.0/tests/fixtures/codex_with_skill.json +65 -0
- skillproof-0.1.0/tests/fixtures/summary_template.json +55 -0
- skillproof-0.1.0/tests/selftest-skill/SKILL.md +8 -0
- skillproof-0.1.0/tests/selftest-skill/evals.yaml +24 -0
- skillproof-0.1.0/tests/test_assertions.py +118 -0
- skillproof-0.1.0/tests/test_claude_code.py +268 -0
- skillproof-0.1.0/tests/test_cli.py +262 -0
- skillproof-0.1.0/tests/test_codex.py +210 -0
- skillproof-0.1.0/tests/test_config.py +139 -0
- skillproof-0.1.0/tests/test_engine.py +269 -0
- skillproof-0.1.0/tests/test_estimate.py +87 -0
- skillproof-0.1.0/tests/test_judges.py +135 -0
- skillproof-0.1.0/tests/test_leaderboard.py +102 -0
- skillproof-0.1.0/tests/test_openai_compat.py +188 -0
- skillproof-0.1.0/tests/test_reports.py +167 -0
- skillproof-0.1.0/tests/test_skill.py +50 -0
- skillproof-0.1.0/tests/test_stats.py +165 -0
|
@@ -0,0 +1,31 @@
|
|
|
1
|
+
# Runs this repo's own action.yml on a mock skill (no API keys), including the
|
|
2
|
+
# PR comment, so changes to the action are tested end to end.
|
|
3
|
+
name: action self-test
|
|
4
|
+
|
|
5
|
+
on:
|
|
6
|
+
pull_request:
|
|
7
|
+
push:
|
|
8
|
+
branches: [main]
|
|
9
|
+
|
|
10
|
+
permissions:
|
|
11
|
+
contents: read
|
|
12
|
+
pull-requests: write
|
|
13
|
+
|
|
14
|
+
jobs:
|
|
15
|
+
selftest:
|
|
16
|
+
runs-on: ubuntu-latest
|
|
17
|
+
steps:
|
|
18
|
+
- uses: actions/checkout@v4
|
|
19
|
+
- id: skillproof
|
|
20
|
+
uses: ./
|
|
21
|
+
with:
|
|
22
|
+
path: tests/selftest-skill
|
|
23
|
+
min-lift: "20"
|
|
24
|
+
artifact-name: skillproof-selftest
|
|
25
|
+
- name: Check outputs
|
|
26
|
+
env:
|
|
27
|
+
VERDICT: ${{ steps.skillproof.outputs.verdict }}
|
|
28
|
+
LIFT: ${{ steps.skillproof.outputs.lift }}
|
|
29
|
+
run: |
|
|
30
|
+
echo "verdict=$VERDICT lift=$LIFT"
|
|
31
|
+
test "$VERDICT" = "helps"
|
|
@@ -0,0 +1,35 @@
|
|
|
1
|
+
name: ci
|
|
2
|
+
|
|
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
branches: [main]
|
|
6
|
+
pull_request:
|
|
7
|
+
|
|
8
|
+
permissions:
|
|
9
|
+
contents: read
|
|
10
|
+
|
|
11
|
+
jobs:
|
|
12
|
+
test:
|
|
13
|
+
runs-on: ubuntu-latest
|
|
14
|
+
strategy:
|
|
15
|
+
fail-fast: false
|
|
16
|
+
matrix:
|
|
17
|
+
python-version: ["3.10", "3.11", "3.12", "3.13"]
|
|
18
|
+
steps:
|
|
19
|
+
- uses: actions/checkout@v4
|
|
20
|
+
- uses: actions/setup-python@v5
|
|
21
|
+
with:
|
|
22
|
+
python-version: ${{ matrix.python-version }}
|
|
23
|
+
- run: python -m pip install -e ".[dev]"
|
|
24
|
+
- run: ruff check .
|
|
25
|
+
- run: ruff format --check .
|
|
26
|
+
- run: pytest -q
|
|
27
|
+
|
|
28
|
+
action-js:
|
|
29
|
+
runs-on: ubuntu-latest
|
|
30
|
+
steps:
|
|
31
|
+
- uses: actions/checkout@v4
|
|
32
|
+
- uses: actions/setup-node@v4
|
|
33
|
+
with:
|
|
34
|
+
node-version: "22"
|
|
35
|
+
- run: node --test action/test/comment.test.js
|
|
@@ -0,0 +1,76 @@
|
|
|
1
|
+
# Publish a release: push a tag like v0.1.0 and this workflow
|
|
2
|
+
# 1. builds the sdist and wheel and checks the tag matches the package version,
|
|
3
|
+
# 2. publishes them to PyPI with Trusted Publishing (no API token stored here),
|
|
4
|
+
# 3. creates a GitHub Release with the files and moves the major tag (v0) to it,
|
|
5
|
+
# so `uses: akhilgarg07/skillproof@v0` picks up the new action.
|
|
6
|
+
#
|
|
7
|
+
# One-time setup on PyPI: add a trusted publisher for project "skillproof",
|
|
8
|
+
# owner "Akhilgarg07", repository "skillproof", workflow "release.yml",
|
|
9
|
+
# environment "pypi". See RELEASING.md.
|
|
10
|
+
name: release
|
|
11
|
+
|
|
12
|
+
on:
|
|
13
|
+
push:
|
|
14
|
+
tags: ["v[0-9]+.[0-9]+.[0-9]+"]
|
|
15
|
+
|
|
16
|
+
permissions:
|
|
17
|
+
contents: read
|
|
18
|
+
|
|
19
|
+
jobs:
|
|
20
|
+
build:
|
|
21
|
+
runs-on: ubuntu-latest
|
|
22
|
+
steps:
|
|
23
|
+
- uses: actions/checkout@v4
|
|
24
|
+
- uses: actions/setup-python@v5
|
|
25
|
+
with:
|
|
26
|
+
python-version: "3.12"
|
|
27
|
+
- run: python -m pip install build twine
|
|
28
|
+
- name: Check the tag matches the package version
|
|
29
|
+
run: |
|
|
30
|
+
version=$(python -c "import re; print(re.search(r'__version__ = \"(.+)\"', open('src/skillproof/__init__.py').read()).group(1))")
|
|
31
|
+
if [ "v$version" != "$GITHUB_REF_NAME" ]; then
|
|
32
|
+
echo "Tag $GITHUB_REF_NAME does not match __version__ $version in src/skillproof/__init__.py"
|
|
33
|
+
exit 1
|
|
34
|
+
fi
|
|
35
|
+
- run: python -m build
|
|
36
|
+
- run: python -m twine check --strict dist/*
|
|
37
|
+
- uses: actions/upload-artifact@v4
|
|
38
|
+
with:
|
|
39
|
+
name: dist
|
|
40
|
+
path: dist/
|
|
41
|
+
|
|
42
|
+
publish:
|
|
43
|
+
needs: build
|
|
44
|
+
runs-on: ubuntu-latest
|
|
45
|
+
environment:
|
|
46
|
+
name: pypi
|
|
47
|
+
url: https://pypi.org/p/skillproof
|
|
48
|
+
permissions:
|
|
49
|
+
id-token: write # Trusted Publishing
|
|
50
|
+
steps:
|
|
51
|
+
- uses: actions/download-artifact@v4
|
|
52
|
+
with:
|
|
53
|
+
name: dist
|
|
54
|
+
path: dist/
|
|
55
|
+
- uses: pypa/gh-action-pypi-publish@release/v1
|
|
56
|
+
|
|
57
|
+
github-release:
|
|
58
|
+
needs: publish
|
|
59
|
+
runs-on: ubuntu-latest
|
|
60
|
+
permissions:
|
|
61
|
+
contents: write # create the release and move the major tag
|
|
62
|
+
steps:
|
|
63
|
+
- uses: actions/checkout@v4
|
|
64
|
+
- uses: actions/download-artifact@v4
|
|
65
|
+
with:
|
|
66
|
+
name: dist
|
|
67
|
+
path: dist/
|
|
68
|
+
- name: Create the GitHub Release
|
|
69
|
+
env:
|
|
70
|
+
GH_TOKEN: ${{ github.token }}
|
|
71
|
+
run: gh release create "$GITHUB_REF_NAME" dist/* --title "$GITHUB_REF_NAME" --generate-notes
|
|
72
|
+
- name: Move the major tag (e.g. v0) to this release
|
|
73
|
+
run: |
|
|
74
|
+
major="${GITHUB_REF_NAME%%.*}"
|
|
75
|
+
git tag -f "$major" "$GITHUB_REF_NAME"
|
|
76
|
+
git push -f origin "refs/tags/$major"
|
|
@@ -0,0 +1,65 @@
|
|
|
1
|
+
# Contributing to skillproof
|
|
2
|
+
|
|
3
|
+
Thanks for helping! skillproof is meant to stay small and easy to read: prefer
|
|
4
|
+
plain code over clever abstractions, and explain *why* in comments when the
|
|
5
|
+
code can't.
|
|
6
|
+
|
|
7
|
+
## Setup
|
|
8
|
+
|
|
9
|
+
```bash
|
|
10
|
+
git clone https://github.com/akhilgarg07/skillproof && cd skillproof
|
|
11
|
+
uv venv && uv pip install -e ".[dev]" # or: python -m venv .venv && pip install -e ".[dev]"
|
|
12
|
+
.venv/bin/pytest
|
|
13
|
+
.venv/bin/ruff check . && .venv/bin/ruff format --check .
|
|
14
|
+
node --test action/test/comment.test.js # only if you touch action/
|
|
15
|
+
```
|
|
16
|
+
|
|
17
|
+
Tests never call real APIs or agents. `tests/conftest.py` makes any test that
|
|
18
|
+
tries to start a real Claude Code or Codex session fail. Runner tests use
|
|
19
|
+
recorded transcripts in `tests/fixtures/` and fake executables or clients.
|
|
20
|
+
|
|
21
|
+
## Where things live
|
|
22
|
+
|
|
23
|
+
| path | what |
|
|
24
|
+
|---|---|
|
|
25
|
+
| `src/skillproof/cli.py` | the `skillproof` command (typer) |
|
|
26
|
+
| `src/skillproof/config.py` | the `evals.yaml` schema (pydantic) and loader |
|
|
27
|
+
| `src/skillproof/engine.py` | runs trials with/without the skill, sandboxes, fail-fast, saving |
|
|
28
|
+
| `src/skillproof/runners/` | one module per agent, plus `base.py` (the `Runner` interface) |
|
|
29
|
+
| `src/skillproof/parsers/` | turn an agent's transcript into an `AgentRun` (pure functions) |
|
|
30
|
+
| `src/skillproof/assertions/` | assertion types (`builtin.py`, `llm_judge.py`) |
|
|
31
|
+
| `src/skillproof/judges/` | judge models for `llm_judge` |
|
|
32
|
+
| `src/skillproof/stats.py` | pass rates, intervals, lift, verdicts |
|
|
33
|
+
| `src/skillproof/report/` | `summary.py` (all numbers, computed once) and one renderer per format |
|
|
34
|
+
| `action.yml`, `action/` | the GitHub Action |
|
|
35
|
+
| `examples/`, `leaderboard/` | example skills and the leaderboard tooling |
|
|
36
|
+
|
|
37
|
+
## Adding a runner (e.g. Gemini CLI)
|
|
38
|
+
|
|
39
|
+
1. Read the agent's **current** docs for its non-interactive mode, JSON output
|
|
40
|
+
and how it discovers skills. Agent CLIs change often: don't rely on memory.
|
|
41
|
+
2. Create `src/skillproof/runners/<agent>.py` with a `Runner` subclass. Read the
|
|
42
|
+
rules at the top of `runners/base.py`: only touch the sandbox, keep the user's
|
|
43
|
+
personal config out of *both* variants, put infrastructure failures in `error`.
|
|
44
|
+
3. Put transcript parsing in `src/skillproof/parsers/<agent>.py` as pure
|
|
45
|
+
functions, including trigger detection.
|
|
46
|
+
4. Register it in `RUNNERS` in `runners/__init__.py` and give it a sensible
|
|
47
|
+
entry in `DEFAULT_COST_PER_RUN` (`estimate.py`).
|
|
48
|
+
5. Record one real transcript with and without a skill, scrub paths and IDs, save
|
|
49
|
+
it under `tests/fixtures/`, and test the parser on it. Test the runner with a
|
|
50
|
+
fake CLI (see `tests/test_codex.py`) or a fake client.
|
|
51
|
+
6. Add a row to the runners table in the README, including how triggers are detected.
|
|
52
|
+
|
|
53
|
+
## Adding an assertion type
|
|
54
|
+
|
|
55
|
+
Add a `BaseAssertion` subclass in `assertions/builtin.py` with a unique
|
|
56
|
+
`type: Literal["..."]` and an async `check()`, add it to the `Assertion` union in
|
|
57
|
+
`assertions/__init__.py`, document it in the README table and in the `init`
|
|
58
|
+
template comments, and add tests to `tests/test_assertions.py`.
|
|
59
|
+
|
|
60
|
+
## Pull requests
|
|
61
|
+
|
|
62
|
+
- Keep each PR to one change, with tests.
|
|
63
|
+
- Run ruff and pytest locally; CI runs them on Python 3.10–3.13.
|
|
64
|
+
- If you change `summary.json` fields, keep old ones (it's a contract for CI users)
|
|
65
|
+
or bump `SCHEMA_VERSION` in `report/summary.py`.
|
skillproof-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Akhil Garg
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,262 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: skillproof
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: pytest for agent skills: prove your skill actually works.
|
|
5
|
+
Project-URL: Homepage, https://github.com/akhilgarg07/skillproof
|
|
6
|
+
Project-URL: Issues, https://github.com/akhilgarg07/skillproof/issues
|
|
7
|
+
Project-URL: Source, https://github.com/akhilgarg07/skillproof
|
|
8
|
+
Author: Akhil Garg
|
|
9
|
+
License-Expression: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Keywords: agent-skills,claude-code,codex,evals,llm,testing
|
|
12
|
+
Classifier: Development Status :: 3 - Alpha
|
|
13
|
+
Classifier: Environment :: Console
|
|
14
|
+
Classifier: Intended Audience :: Developers
|
|
15
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
16
|
+
Classifier: Programming Language :: Python :: 3
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
21
|
+
Classifier: Topic :: Software Development :: Testing
|
|
22
|
+
Requires-Python: >=3.10
|
|
23
|
+
Requires-Dist: anthropic>=1.15
|
|
24
|
+
Requires-Dist: claude-agent-sdk>=0.2.168
|
|
25
|
+
Requires-Dist: openai>=3.0
|
|
26
|
+
Requires-Dist: pydantic>=2.6
|
|
27
|
+
Requires-Dist: pyyaml>=6.0
|
|
28
|
+
Requires-Dist: rich>=13.7
|
|
29
|
+
Requires-Dist: typer>=0.12
|
|
30
|
+
Provides-Extra: dev
|
|
31
|
+
Requires-Dist: pytest>=8; extra == 'dev'
|
|
32
|
+
Requires-Dist: ruff>=0.6; extra == 'dev'
|
|
33
|
+
Description-Content-Type: text/markdown
|
|
34
|
+
|
|
35
|
+
# skillproof
|
|
36
|
+
|
|
37
|
+
**pytest for agent skills: prove your skill actually works.**
|
|
38
|
+
|
|
39
|
+
[](https://github.com/akhilgarg07/skillproof/actions/workflows/ci.yml)
|
|
40
|
+
[](https://github.com/akhilgarg07/skillproof/blob/main/LICENSE)
|
|
41
|
+
|
|
42
|
+
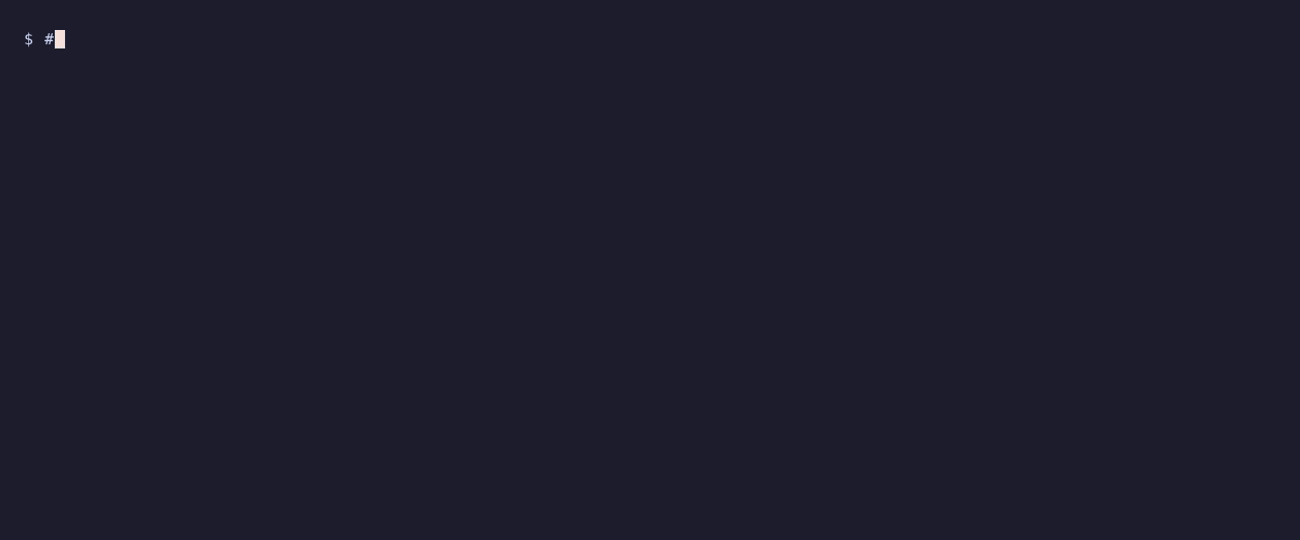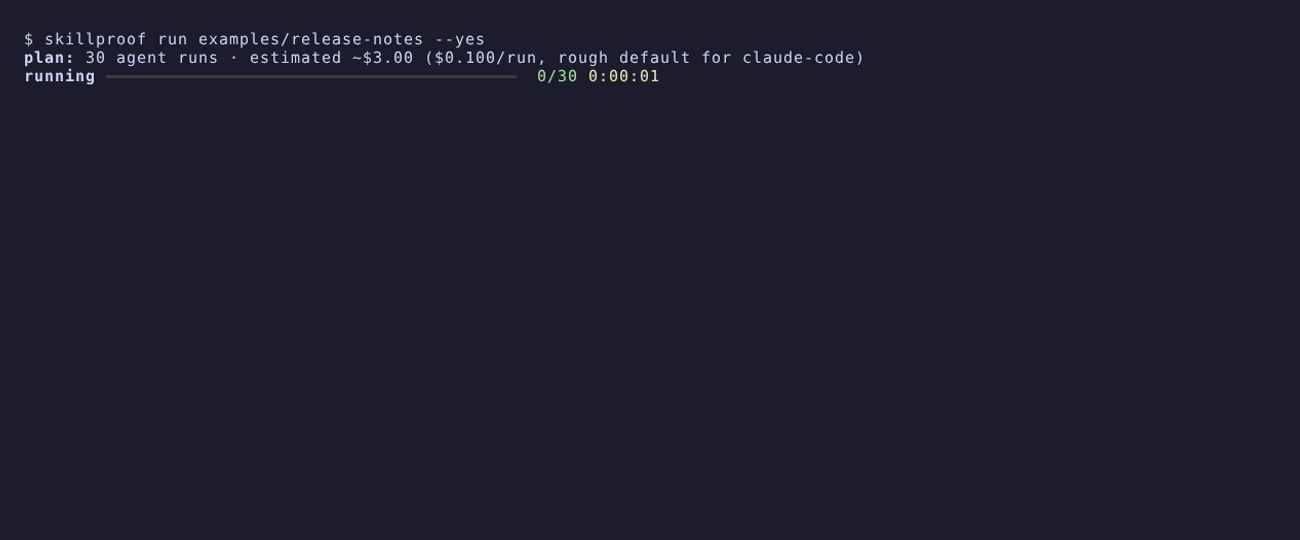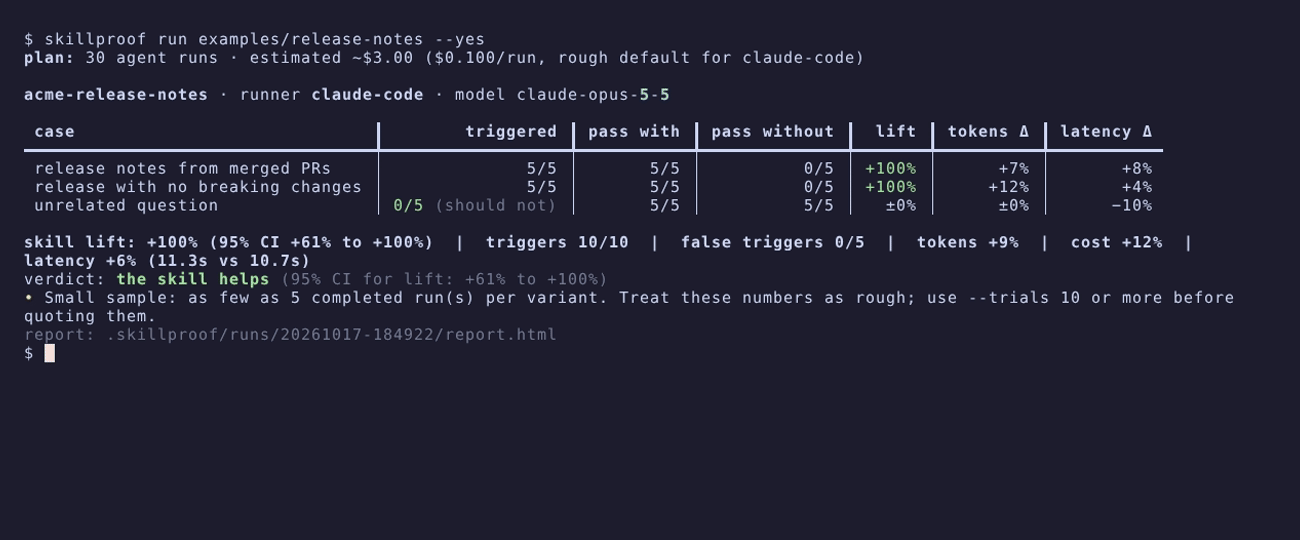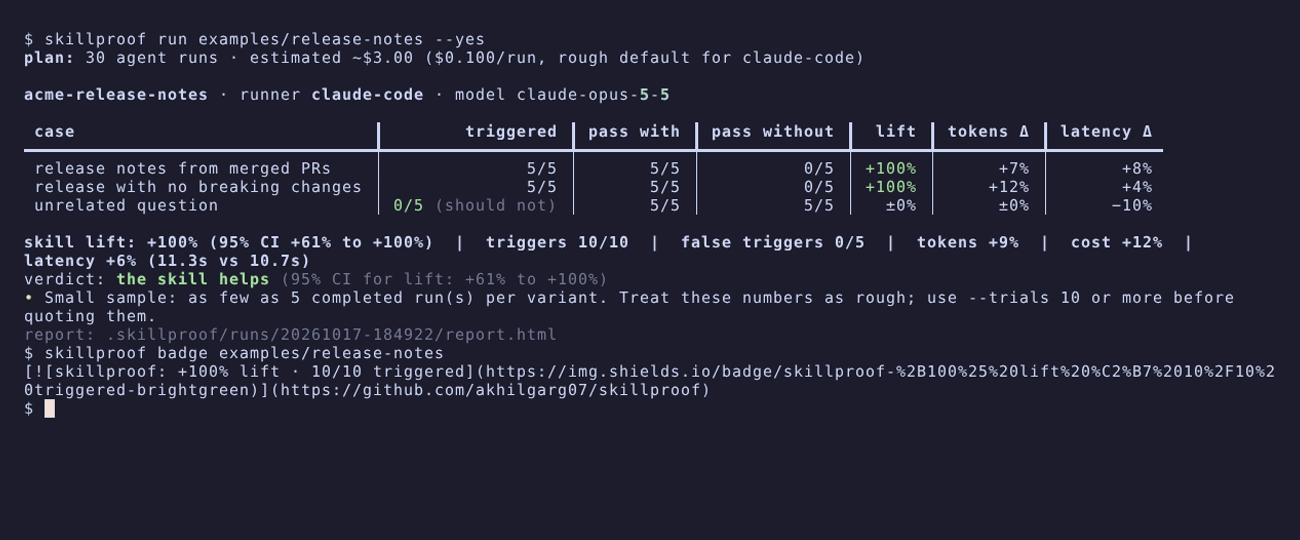
|
|
43
|
+
<!-- Record with: vhs docs/demo.tape -->
|
|
44
|
+
|
|
45
|
+
```bash
|
|
46
|
+
pip install skillproof
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
**Works with:** Claude Code · Codex · any OpenAI-compatible endpoint
|
|
50
|
+
|
|
51
|
+
---
|
|
52
|
+
|
|
53
|
+
Agent skills (`SKILL.md` folders for Claude Code, Codex, Cursor, Gemini CLI,
|
|
54
|
+
OpenCode...) are everywhere, but almost nobody can show that a skill helps. Often
|
|
55
|
+
it isn't even loaded: the agent never decides to use it. **skillproof** runs your
|
|
56
|
+
tasks N times **with** the skill installed and N times **without** it, then tells
|
|
57
|
+
you:
|
|
58
|
+
|
|
59
|
+
- **Trigger rate**: did the agent actually load the skill?
|
|
60
|
+
- **Lift**: pass rate with the skill minus pass rate without it, with a 95% confidence interval
|
|
61
|
+
- **Cost**: extra (or saved) tokens, dollars and seconds per run
|
|
62
|
+
- **A verdict**: *helps*, *hurts*, *no clear effect*, or *too few runs* to say
|
|
63
|
+
|
|
64
|
+
## 60-second quickstart
|
|
65
|
+
|
|
66
|
+
```bash
|
|
67
|
+
pip install skillproof
|
|
68
|
+
export ANTHROPIC_API_KEY=sk-ant-... # or use your `claude` login
|
|
69
|
+
|
|
70
|
+
skillproof init ./my-skill # writes my-skill/evals.yaml
|
|
71
|
+
# edit evals.yaml: 2-3 real tasks, how to check them, one task the skill should ignore
|
|
72
|
+
skillproof run ./my-skill # prints the plan and cost estimate, then runs
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
`uvx skillproof run ./my-skill` works too, without installing anything.
|
|
76
|
+
|
|
77
|
+
## Example output
|
|
78
|
+
|
|
79
|
+
This is a real run of the [`release-notes`](https://github.com/akhilgarg07/skillproof/blob/main/examples/release-notes/) example
|
|
80
|
+
(Claude Code, 5 trials per variant):
|
|
81
|
+
|
|
82
|
+
```
|
|
83
|
+
acme-release-notes · runner claude-code · model claude-opus-5-5
|
|
84
|
+
|
|
85
|
+
case ┃ triggered ┃ pass with ┃ pass without ┃ lift ┃ tokens Δ ┃ latency Δ
|
|
86
|
+
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━╇━━━━━━━━━━╇━━━━━━━━━━━
|
|
87
|
+
release notes from merged PRs │ 5/5 │ 5/5 │ 0/5 │ +100% │ +7% │ −3%
|
|
88
|
+
release with no breaking changes │ 5/5 │ 5/5 │ 0/5 │ +100% │ +7% │ +3%
|
|
89
|
+
unrelated question │ 0/5 (should not) │ 4/5 │ 5/5 │ −20% │ ±0% │ −2%
|
|
90
|
+
|
|
91
|
+
skill lift: +100% (95% CI +61% to +100%) | triggers 10/10 | false triggers 0/5 | tokens +7% | cost +10%
|
|
92
|
+
verdict: the skill helps (95% CI for lift: +61% to +100%)
|
|
93
|
+
• Small sample: as few as 5 completed run(s) per variant. Treat these numbers as rough; use --trials 10 or more
|
|
94
|
+
before quoting them.
|
|
95
|
+
```
|
|
96
|
+
|
|
97
|
+
Every run also saves a self-contained **HTML report** (with each run's checks and
|
|
98
|
+
answer), `report.md`, `summary.json` and the full transcripts under
|
|
99
|
+
`.skillproof/runs/<timestamp>/`.
|
|
100
|
+
|
|
101
|
+
[`examples/`](https://github.com/akhilgarg07/skillproof/blob/main/examples/) has skills that **help**, **do nothing** and **hurt**, so
|
|
102
|
+
you can see all three outcomes.
|
|
103
|
+
|
|
104
|
+
## How it works
|
|
105
|
+
|
|
106
|
+
```
|
|
107
|
+
for each case in evals.yaml, N trials, interleaved:
|
|
108
|
+
with skill: fresh temp dir + fixtures + skill installed -> agent -> checks
|
|
109
|
+
without skill: fresh temp dir + fixtures, no skill -> agent -> checks
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
- Every run gets a **fresh temp directory** with your fixtures copied in. Your
|
|
113
|
+
project is never touched.
|
|
114
|
+
- Your **personal** skills, settings and instructions (`~/.claude`, `~/.codex`,
|
|
115
|
+
`~/.agents`) are not loaded for either variant, so the only difference is the skill.
|
|
116
|
+
- The agent can't see your `evals.yaml` or its checks.
|
|
117
|
+
- Transcripts, token usage and tool calls are saved for every run, with API keys redacted.
|
|
118
|
+
|
|
119
|
+
## evals.yaml
|
|
120
|
+
|
|
121
|
+
```yaml
|
|
122
|
+
skill: ./ # folder containing SKILL.md
|
|
123
|
+
runner: claude-code # claude-code | codex | openai-compatible
|
|
124
|
+
# model: claude-sonnet-5-5 # optional; the agent's default otherwise
|
|
125
|
+
trials: 5 # runs per case, per variant
|
|
126
|
+
timeout: 300 # seconds per run
|
|
127
|
+
|
|
128
|
+
cases:
|
|
129
|
+
- name: "summarizes stack trace"
|
|
130
|
+
prompt: "Here is an error log in error.log. What's wrong?" # don't name the skill
|
|
131
|
+
fixtures: ./fixtures/case1/ # copied into each run's temp dir
|
|
132
|
+
assert:
|
|
133
|
+
- type: contains
|
|
134
|
+
value: "NullPointerException"
|
|
135
|
+
- type: file_exists
|
|
136
|
+
path: fix.patch
|
|
137
|
+
- type: command # runs in the temp dir; passes on exit code 0
|
|
138
|
+
run: "python -m pytest -q"
|
|
139
|
+
- type: max_tokens
|
|
140
|
+
value: 20000
|
|
141
|
+
- type: llm_judge # optional; graded by a model from another vendor
|
|
142
|
+
rubric: "States the root cause in the first sentence."
|
|
143
|
+
|
|
144
|
+
- name: "unrelated question" # catches skills that load when they shouldn't
|
|
145
|
+
prompt: "What's the capital of France?"
|
|
146
|
+
should_trigger: false
|
|
147
|
+
assert:
|
|
148
|
+
- {type: contains, value: "Paris"}
|
|
149
|
+
```
|
|
150
|
+
|
|
151
|
+
| assertion | passes when |
|
|
152
|
+
|---|---|
|
|
153
|
+
| `contains` / `not_contains` | the final answer contains / doesn't contain `value` (case-insensitive by default) |
|
|
154
|
+
| `regex` | the final answer matches `pattern` |
|
|
155
|
+
| `file_exists` / `file_contains` | a file in the temp dir exists / contains `value` |
|
|
156
|
+
| `command` | `run` exits 0 in the temp dir (API keys are removed from its environment) |
|
|
157
|
+
| `max_tokens` | the run used at most `value` tokens (input + output + cache) |
|
|
158
|
+
| `llm_judge` | a judge model says the answer meets `rubric` |
|
|
159
|
+
|
|
160
|
+
Use deterministic checks first. `llm_judge` defaults to a judge from a **different
|
|
161
|
+
vendor** than the agent (Claude agents are graded by an OpenAI model and vice
|
|
162
|
+
versa), so no model grades its own family. Change it with
|
|
163
|
+
`judge: {provider: anthropic, model: ...}`.
|
|
164
|
+
|
|
165
|
+
## Runners
|
|
166
|
+
|
|
167
|
+
| runner | how it runs | where the skill goes | how a trigger is detected |
|
|
168
|
+
|---|---|---|---|
|
|
169
|
+
| `claude-code` | [Claude Agent SDK](https://code.claude.com/docs/en/agent-sdk/overview) | `<temp>/.claude/skills/<name>/` | a `Skill` tool call naming the skill |
|
|
170
|
+
| `codex` | `codex exec --json` | `<temp>/.agents/skills/<name>/` | a shell command that reads the skill's folder |
|
|
171
|
+
| `openai-compatible` | a small tool-using loop over Chat Completions | SKILL.md pasted into the system prompt | not measured (**approximate**) |
|
|
172
|
+
|
|
173
|
+
Keys come from environment variables only: `ANTHROPIC_API_KEY` (or your `claude`
|
|
174
|
+
login), `CODEX_API_KEY` / `OPENAI_API_KEY` (or `codex login`). Runner settings go
|
|
175
|
+
under `runner_options:`; see each runner's module docstring.
|
|
176
|
+
|
|
177
|
+
## Reports, CI and badges
|
|
178
|
+
|
|
179
|
+
```bash
|
|
180
|
+
skillproof run ./my-skill --format md -o report.md # also: html, json (to stdout)
|
|
181
|
+
skillproof report # re-render the latest run
|
|
182
|
+
skillproof run ./my-skill --min-lift 0 --min-trigger-rate 80 # exit 1 if not met
|
|
183
|
+
skillproof run ./my-skill --dry-run # plan + cost estimate only
|
|
184
|
+
```
|
|
185
|
+
|
|
186
|
+
**Cost guard:** before every run skillproof prints the number of runs and an
|
|
187
|
+
estimate based on your previous runs. Above $5 it asks first; in CI it refuses
|
|
188
|
+
unless you pass `--yes`. If the first runs all fail (bad key, wrong model), it
|
|
189
|
+
stops and tells you what to fix.
|
|
190
|
+
|
|
191
|
+
**GitHub Action:** comments the results on pull requests and keeps the comment up to date.
|
|
192
|
+
|
|
193
|
+
```yaml
|
|
194
|
+
# .github/workflows/skillproof.yml (full example: action/example-workflow.yml)
|
|
195
|
+
on: pull_request
|
|
196
|
+
permissions: {contents: read, pull-requests: write}
|
|
197
|
+
jobs:
|
|
198
|
+
skillproof:
|
|
199
|
+
runs-on: ubuntu-latest
|
|
200
|
+
steps:
|
|
201
|
+
- uses: actions/checkout@v4
|
|
202
|
+
- uses: akhilgarg07/skillproof@v0
|
|
203
|
+
with: {path: my-skill, trials: "10", min-lift: "0"}
|
|
204
|
+
env: {ANTHROPIC_API_KEY: "${{ secrets.ANTHROPIC_API_KEY }}"}
|
|
205
|
+
```
|
|
206
|
+
|
|
207
|
+
**Badge for your skill's README:**
|
|
208
|
+
|
|
209
|
+
```bash
|
|
210
|
+
skillproof badge ./my-skill
|
|
211
|
+
# [](...)
|
|
212
|
+
```
|
|
213
|
+
|
|
214
|
+
It is green when the skill helps, red when it hurts and grey when the result is
|
|
215
|
+
not significant or comes from fewer than 5 runs per variant. `--json` prints a
|
|
216
|
+
[shields.io endpoint](https://shields.io/badges/endpoint-badge) file instead, so CI
|
|
217
|
+
can keep a badge up to date.
|
|
218
|
+
|
|
219
|
+
## Honest numbers: what this can and can't tell you
|
|
220
|
+
|
|
221
|
+
- **It measures your tasks, not the skill in general.** Lift depends on the prompts
|
|
222
|
+
and checks you write. Publish your `evals.yaml` next to any number you share.
|
|
223
|
+
- **Small samples are noisy.** Every rate comes with a 95% interval (Wilson for pass
|
|
224
|
+
rates, Newcombe for the lift). Below 5 runs per variant there's no verdict at all,
|
|
225
|
+
and below 10 the report says the numbers are rough.
|
|
226
|
+
- **Results depend on the agent and model.** Reports record the model that actually
|
|
227
|
+
ran. In our runs, Claude Code read a library's source, noticed that a skill's docs
|
|
228
|
+
were stale and ignored them ([`examples/stale-docs`](https://github.com/akhilgarg07/skillproof/blob/main/examples/stale-docs/)); a
|
|
229
|
+
weaker model may not.
|
|
230
|
+
- **Trigger detection is per agent and heuristic.** Claude Code has an explicit
|
|
231
|
+
`Skill` tool call. Codex reads skills with ordinary shell commands, so a "trigger"
|
|
232
|
+
there means a command touched the skill's folder.
|
|
233
|
+
- **The `openai-compatible` runner is an approximation.** It pastes SKILL.md into the
|
|
234
|
+
system prompt instead of letting the agent discover and load it, so it can't
|
|
235
|
+
measure trigger rate and overstates how often a skill is "used". Reports label it.
|
|
236
|
+
- **Token deltas include cache reads,** which are cheap. Look at the cost delta when
|
|
237
|
+
the agent reports cost (Claude Code does).
|
|
238
|
+
- **`llm_judge` is a model's opinion.** It's cross-vendor by default, but still noisy;
|
|
239
|
+
prefer deterministic checks.
|
|
240
|
+
- **Agents run real commands.** Runs happen in temp directories, but agents run
|
|
241
|
+
without permission prompts, so a command could still reach other files on your
|
|
242
|
+
machine. Test untrusted skills in a container or VM.
|
|
243
|
+
|
|
244
|
+
## Leaderboard
|
|
245
|
+
|
|
246
|
+
[`leaderboard/`](https://github.com/akhilgarg07/skillproof/blob/main/leaderboard/) runs skillproof over a list of public skills (using
|
|
247
|
+
evals you write, never the repo's own) and renders a markdown leaderboard.
|
|
248
|
+
|
|
249
|
+
## Contributing
|
|
250
|
+
|
|
251
|
+
Contributions are very welcome; see [CONTRIBUTING.md](https://github.com/akhilgarg07/skillproof/blob/main/CONTRIBUTING.md). Good first issues:
|
|
252
|
+
|
|
253
|
+
- **New runners:** Gemini CLI, Cursor (cursor-agent), OpenCode, Aider
|
|
254
|
+
- **New assertions:** `tool_called` (the agent used a given tool), `json_schema`,
|
|
255
|
+
`file_matches` (regex on a file), `max_cost_usd`
|
|
256
|
+
- **`skillproof compare`:** two versions of a skill head to head
|
|
257
|
+
- **Windows support** and a Docker sandbox option for untrusted skills
|
|
258
|
+
- **A local judge:** `llm_judge` over Chat Completions, for local models (Ollama, vLLM)
|
|
259
|
+
|
|
260
|
+
## License
|
|
261
|
+
|
|
262
|
+
MIT
|