scribe-eval 0.1.1__tar.gz → 0.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/PKG-INFO +94 -139
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/README.md +90 -135
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/pyproject.toml +9 -5
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/__init__.py +6 -3
- scribe_eval-0.2.0/src/scribe/batch_cli.py +564 -0
- scribe_eval-0.2.0/src/scribe/config/legal_terms.txt +428 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/constants.py +6 -5
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/domain_config.py +39 -2
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/measure_batch.py +76 -36
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/normalize.py +39 -2
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/reporting.py +22 -19
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/tokenize.py +15 -2
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/visualizer/app.py +14 -15
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe_eval.egg-info/PKG-INFO +94 -139
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe_eval.egg-info/SOURCES.txt +2 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe_eval.egg-info/entry_points.txt +1 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe_eval.egg-info/requires.txt +3 -3
- scribe_eval-0.2.0/tests/test_batch_cli.py +363 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_domain_config.py +56 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_imports.py +2 -1
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_measure.py +10 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_measure_batch.py +111 -27
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_normalize.py +27 -1
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_packaging.py +35 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_paper_cases.py +13 -7
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_reporting.py +30 -22
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_tokenize.py +83 -0
- scribe_eval-0.1.1/src/scribe/config/legal_terms.txt +0 -369
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/LICENSE +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/setup.cfg +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/align.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/analysis.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/charts.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/config/__init__.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/config/medical_terms.txt +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/config/technical_terms.txt +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/measure.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/visualizer/__init__.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe/visualizer/__main__.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe_eval.egg-info/dependency_links.txt +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/src/scribe_eval.egg-info/top_level.txt +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_align.py +0 -0
- {scribe_eval-0.1.1 → scribe_eval-0.2.0}/tests/test_analysis.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: scribe-eval
|
|
3
|
-
Version: 0.
|
|
3
|
+
Version: 0.2.0
|
|
4
4
|
Summary: Diagnostic ASR evaluation with sandhi-tolerant alignment and categorical error decomposition for Indic and domain-specific speech recognition.
|
|
5
5
|
Author: Kavya Manohar
|
|
6
6
|
License: Apache-2.0
|
|
@@ -23,13 +23,13 @@ Description-Content-Type: text/markdown
|
|
|
23
23
|
License-File: LICENSE
|
|
24
24
|
Requires-Dist: levenshtein>=0.27.1
|
|
25
25
|
Requires-Dist: tabulate>=0.9.0
|
|
26
|
-
|
|
27
|
-
Requires-Dist: matplotlib>=3.7.0; extra == "charts"
|
|
26
|
+
Requires-Dist: matplotlib>=3.7.0
|
|
28
27
|
Provides-Extra: visualizer
|
|
29
28
|
Requires-Dist: streamlit>=1.53.0; extra == "visualizer"
|
|
30
29
|
Requires-Dist: pandas>=2.0.0; extra == "visualizer"
|
|
31
|
-
Requires-Dist: matplotlib>=3.7.0; extra == "visualizer"
|
|
32
30
|
Requires-Dist: jiwer>=4.0.0; extra == "visualizer"
|
|
31
|
+
Provides-Extra: all
|
|
32
|
+
Requires-Dist: scribe-eval[visualizer]; extra == "all"
|
|
33
33
|
Dynamic: license-file
|
|
34
34
|
|
|
35
35
|
# SCRIBE — Diagnostic Evaluation for Indic & Domain-Specific ASR
|
|
@@ -40,7 +40,7 @@ Dynamic: license-file
|
|
|
40
40
|
|
|
41
41
|
`scribe-eval` is the open-source evaluation framework introduced in the SCRIBE
|
|
42
42
|
paper (*Diagnostic Evaluation and Rich Transcription Models for Indic ASR*,
|
|
43
|
-
|
|
43
|
+
[Interspeech 2026](https://doi.org/10.21437/Interspeech.2026-3436)). It provides fine-grained error metrics for
|
|
44
44
|
ASR systems on Indic languages (Malayalam, Kannada, Hindi, ...) and on
|
|
45
45
|
domain-specific transcription (legal, medical, technical).
|
|
46
46
|
|
|
@@ -50,27 +50,43 @@ terminology is shielded from incorrect splitting and tracked separately — so a
|
|
|
50
50
|
single misrecognized legal term doesn't inflate your general lexical
|
|
51
51
|
error rate (ER_LEX).
|
|
52
52
|
|
|
53
|
+
**Try it in the browser:** <https://adalat-ai-tech.github.io/scribe-eval/>
|
|
54
|
+
|
|
53
55
|
## Installation
|
|
54
56
|
|
|
55
57
|
```bash
|
|
56
|
-
pip install scribe-eval
|
|
57
|
-
pip install 'scribe-eval[visualizer]' # adds Streamlit UI
|
|
58
|
-
pip install 'scribe-eval[charts]' # adds matplotlib charts
|
|
58
|
+
pip install scribe-eval
|
|
59
59
|
```
|
|
60
60
|
|
|
61
|
-
|
|
62
|
-
|
|
61
|
+
This installs the library and the `scribe-batch` command. For the
|
|
62
|
+
interactive web UI, add the visualizer extra:
|
|
63
|
+
|
|
64
|
+
```bash
|
|
65
|
+
pip install 'scribe-eval[visualizer]'
|
|
66
|
+
```
|
|
63
67
|
|
|
64
68
|
To work on SCRIBE itself, install from source instead:
|
|
65
69
|
|
|
66
70
|
```bash
|
|
67
71
|
git clone https://github.com/adalat-ai-tech/scribe-eval.git
|
|
68
72
|
cd scribe-eval
|
|
69
|
-
pip install -e '.[
|
|
73
|
+
uv sync --all-extras # or: pip install -e '.[all]'
|
|
70
74
|
```
|
|
71
75
|
|
|
76
|
+
Tests, lint and layout are described in
|
|
77
|
+
[docs/development.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/development.md).
|
|
78
|
+
|
|
72
79
|
## Quick Start
|
|
73
80
|
|
|
81
|
+
Evaluate a JSONL file of predictions (one record per line with a `text`
|
|
82
|
+
reference and a `pred_text` hypothesis):
|
|
83
|
+
|
|
84
|
+
```bash
|
|
85
|
+
scribe-batch --input predictions.jsonl --output-dir results --analysis --chart
|
|
86
|
+
```
|
|
87
|
+
|
|
88
|
+
Or score a single pair in Python:
|
|
89
|
+
|
|
74
90
|
```python
|
|
75
91
|
from scribe import compute_cer_scribe, text_error_rates, DomainConfig
|
|
76
92
|
|
|
@@ -87,13 +103,54 @@ cer = compute_cer_scribe(ref, hyp, DomainConfig.legal())
|
|
|
87
103
|
print(f"CER_SCRIBE: {cer['cer_scribe']:.2%}")
|
|
88
104
|
```
|
|
89
105
|
|
|
106
|
+
### What you get
|
|
107
|
+
|
|
108
|
+
For this three-record `predictions.jsonl`:
|
|
109
|
+
|
|
110
|
+
```jsonl
|
|
111
|
+
{"text": "charged u/s 302 IPC on 22.05.2023", "pred_text": "charged u/s 303 IPC on 22-05-2023", "source_dataset": "legal-dictation"}
|
|
112
|
+
{"text": "witness PW1 deposed before the court", "pred_text": "witness PW 1 deposed before court", "source_dataset": "legal-dictation"}
|
|
113
|
+
{"text": "എനിക്ക് അറിയാം", "pred_text": "എനിക്കറിയാം", "source_dataset": "malayalam-read"}
|
|
114
|
+
```
|
|
115
|
+
|
|
116
|
+
`scribe-batch` prints the aggregate table and saves it to
|
|
117
|
+
`results/summary_report.txt`, one row overall and one per group
|
|
118
|
+
(`source_dataset` by default, any field with `--group-by`):
|
|
119
|
+
|
|
120
|
+
```
|
|
121
|
+
GROUP | ER_LEX | ER_DOMAIN | ER_NUM | ER_PUNCT | WER_SCRIBE | CER_SCRIBE | SANDHI
|
|
122
|
+
OVERALL | 6.67% | 0.00% | 6.67% | N/A | 13.33% | 9.52% | 1
|
|
123
|
+
legal-dictation | 7.69% | 0.00% | 7.69% | N/A | 15.38% | 7.14% | 0
|
|
124
|
+
malayalam-read | 0.00% | N/A | N/A | N/A | 0.00% | 21.43% | 1
|
|
125
|
+
```
|
|
126
|
+
|
|
127
|
+
`N/A` means the category had nothing to measure. The SANDHI column counts
|
|
128
|
+
merged or split compounds that were scored as matches, not errors.
|
|
129
|
+
|
|
130
|
+
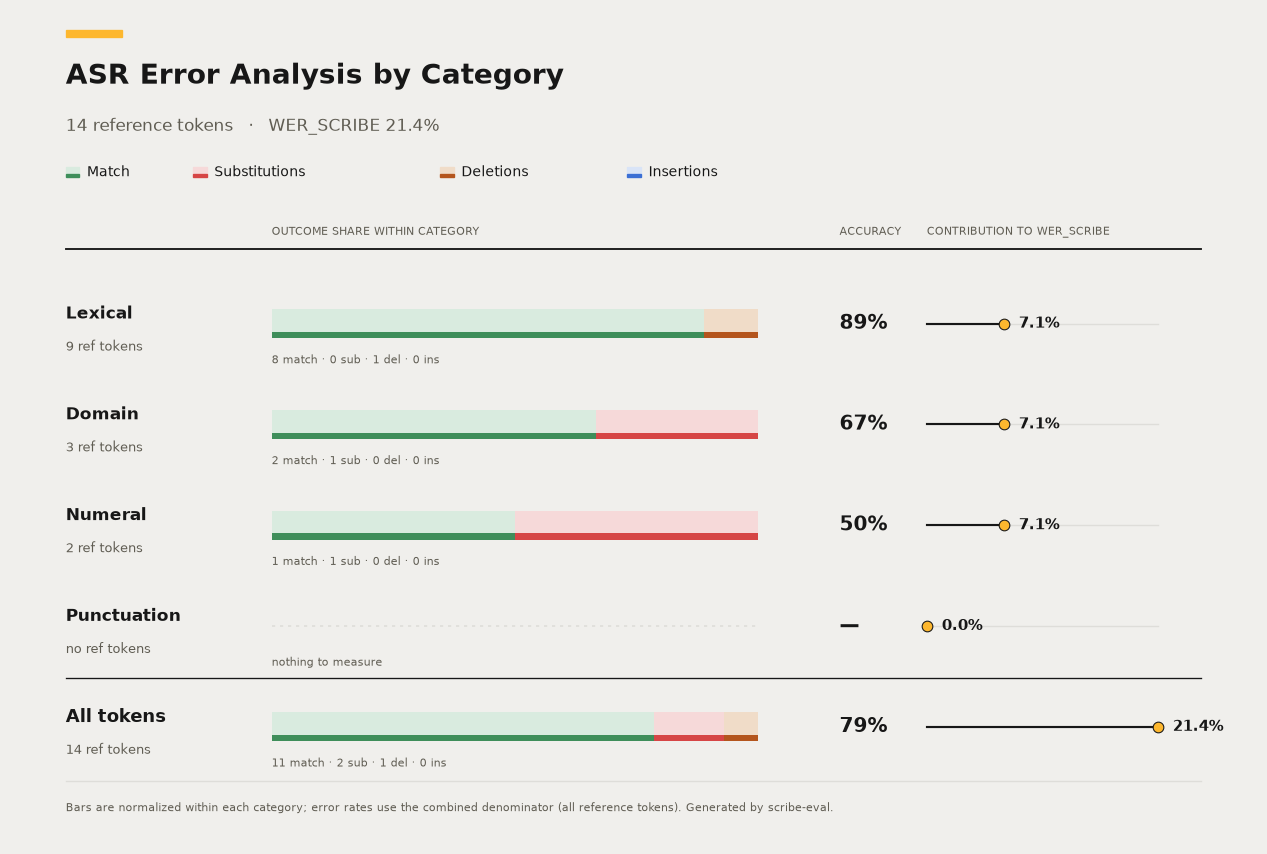
With `--analysis --chart` it also writes `analysis_report.txt` (accuracy,
|
|
131
|
+
WER_SCRIBE, per-category breakdown and every frequent substitution, deletion
|
|
132
|
+
and insertion), `evaluation-detailed.jsonl` (every record with its scores) and
|
|
133
|
+
`category_breakdown.png`:
|
|
134
|
+
|
|
135
|
+
|
|
136
|
+
|
|
137
|
+
Each row shows how many reference tokens in that category were matched,
|
|
138
|
+
substituted, deleted or inserted, the accuracy, and the category's share of
|
|
139
|
+
the overall WER_SCRIBE.
|
|
140
|
+
|
|
141
|
+
`scribe-batch --help` lists every flag with its default; other field names,
|
|
142
|
+
`--no-sandhi`, `--group-by`, domains and workers are covered with the Python
|
|
143
|
+
API in
|
|
144
|
+
[docs/batch-processing.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/batch-processing.md).
|
|
145
|
+
|
|
90
146
|
## Features
|
|
91
147
|
|
|
92
148
|
- **Domain-aware tokenization** — shield domain terms from punctuation splitting; track errors separately
|
|
93
149
|
- **Sandhi correction detection** — identifies merged/split words common in Indic ASR
|
|
94
150
|
- **Normalized error rates** — combined denominator prevents misleading metrics for sparse categories
|
|
95
151
|
- **CER_SCRIBE** — character error rate on normalized token streams; format variants cost nothing, and it needs no sandhi machinery to be robust to agglutination
|
|
96
|
-
-
|
|
152
|
+
- **`scribe-batch` CLI** — one command from JSONL to summary table, per-sample JSONL, full error analysis and chart, with a run-info line that makes the run reproducible
|
|
153
|
+
- **Batch evaluation API** — evaluate in-memory records (`evaluate_records`) or JSONL files with per-sample detail and per-group aggregation
|
|
97
154
|
- **Interactive visualizer** — Streamlit UI with color-coded alignment, WER_SCRIBE/CER_SCRIBE/Accuracy metric tiles, category breakdown chart, frequent-error tables, and per-sample drill-down
|
|
98
155
|
|
|
99
156
|
## Token Categories
|
|
@@ -116,25 +173,10 @@ Agglutination makes word boundaries unstable in Indic text: the same
|
|
|
116
173
|
speech can be written as one word or two. SCRIBE detects such two-word
|
|
117
174
|
merges and splits at alignment time and scores them as matches instead
|
|
118
175
|
of errors.
|
|
119
|
-
Real examples from evaluation data (each would count as 100% WER on its
|
|
120
|
-
phrase without detection):
|
|
121
|
-
|
|
122
|
-
| Language | Reference | Hypothesis | Junction |
|
|
123
|
-
|---|---|---|---|
|
|
124
|
-
| Malayalam | അന്യായ പട്ടിക | അന്യായപ്പട്ടിക | gemination |
|
|
125
|
-
| Malayalam | എനിക്ക് അറിയാം | എനിക്കറിയാം | vowel elision |
|
|
126
|
-
| Kannada | ಪ್ರಧಾನ ಮಂತ್ರಿಗಳ | ಪ್ರಧಾನಮಂತ್ರಿಗಳ | compound merge |
|
|
127
|
-
| Kannada | ಮಿತ್ರರಾಷ್ಟ್ರಗಳು | ಮಿತ್ರ ರಾಷ್ಟ್ರಗಳು | compound split |
|
|
128
|
-
| Hindi | भाई साहब | भाईसाहब | compound spacing |
|
|
129
|
-
| Hindi | उस में | उसमें | postposition merge |
|
|
130
|
-
|
|
131
|
-
On an internal benchmark of 48 Malayalam legal dictations (private
|
|
132
|
-
data, not distributed with this repository), sandhi detection recovers
|
|
133
|
-
**3.0 percentage points of WER_SCRIBE** across 377 events that would
|
|
134
|
-
otherwise masquerade as recognition errors. The paired examples above
|
|
135
|
-
are directly reproducible: score any row with `use_sandhi=True` vs
|
|
136
|
-
`use_sandhi=False` in `text_error_rates`.
|
|
137
176
|
|
|
177
|
+
Examples in Malayalam, Kannada and Hindi, and the measured effect on
|
|
178
|
+
WER_SCRIBE, are in
|
|
179
|
+
[docs/architecture.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md#sandhi-examples-from-evaluation-data).
|
|
138
180
|
Detection is an orthographic heuristic, not a linguistic analysis — it
|
|
139
181
|
is deliberately lenient and admits some false positives. See
|
|
140
182
|
[Sandhi detection: scope and limitations](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md#sandhi-detection-scope-and-limitations)
|
|
@@ -146,69 +188,17 @@ Factory methods for bundled domains: `DomainConfig.legal()`, `DomainConfig.medic
|
|
|
146
188
|
|
|
147
189
|
File-based and custom inline configs are also supported. See [docs/domain-configuration.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/domain-configuration.md).
|
|
148
190
|
|
|
149
|
-
##
|
|
150
|
-
|
|
151
|
-
Evaluate a dataset from JSONL, one record per line:
|
|
191
|
+
## Examples and Docs
|
|
152
192
|
|
|
153
|
-
|
|
154
|
-
|
|
155
|
-
|
|
156
|
-
|
|
157
|
-
|
|
158
|
-
|
|
159
|
-
|
|
160
|
-
|
|
161
|
-
|
|
162
|
-
results = compute_sample_errors(
|
|
163
|
-
"predictions.jsonl", domain_config=DomainConfig.legal(), collect_error_details=True
|
|
164
|
-
)
|
|
165
|
-
print_evaluation_summary(compute_aggregate_metrics(results))
|
|
166
|
-
```
|
|
167
|
-
|
|
168
|
-
```
|
|
169
|
-
DATASET | ER_LEX | ER_DOMAIN | ER_NUM | ER_PUNCT | WER_SCRIBE | CER_SCRIBE | SANDHI
|
|
170
|
-
OVERALL | 7.14% | 7.14% | 7.14% | N/A | 21.43% | 10.84% | 1
|
|
171
|
-
legal-dictation | 8.33% | 8.33% | 8.33% | N/A | 25.00% | 8.70% | 0
|
|
172
|
-
malayalam-read | 0.00% | N/A | N/A | N/A | 0.00% | 21.43% | 1
|
|
173
|
-
```
|
|
174
|
-
|
|
175
|
-
The Malayalam hypothesis merges a two-word compound; it is counted as a Sandhi
|
|
176
|
-
match, not as errors. `N/A` marks a category with no reference tokens and no
|
|
177
|
-
errors.
|
|
178
|
-
|
|
179
|
-
`evaluate_records()` accepts a list of dicts instead of a file path.
|
|
180
|
-
`output_file=` writes per-sample reports as JSONL. `workers=N` evaluates
|
|
181
|
-
samples in parallel.
|
|
182
|
-
|
|
183
|
-
### Charts
|
|
184
|
-
|
|
185
|
-
Continuing from `results` above, with the `[charts]` extra installed:
|
|
186
|
-
|
|
187
|
-
```python
|
|
188
|
-
from scribe import aggregate_error_details, compute_error_summary
|
|
189
|
-
from scribe.charts import category_breakdown_chart
|
|
190
|
-
|
|
191
|
-
summary = compute_error_summary(
|
|
192
|
-
compute_aggregate_metrics(results)["overall"], aggregate_error_details(results), top_n=10
|
|
193
|
-
)
|
|
194
|
-
category_breakdown_chart(summary["contributions"], output_path="breakdown.png")
|
|
195
|
-
```
|
|
196
|
-
|
|
197
|
-

|
|
198
|
-
|
|
199
|
-
One row per category: a normalized outcome bar, an accuracy figure, and that
|
|
200
|
-
category's contribution to WER_SCRIBE. Punctuation is marked "nothing to
|
|
201
|
-
measure" because the reference carries no punctuation tokens.
|
|
202
|
-
|
|
203
|
-
## Examples
|
|
204
|
-
|
|
205
|
-
Runnable scripts live in the repository under
|
|
206
|
-
[`examples/`](https://github.com/adalat-ai-tech/scribe-eval/tree/main/examples),
|
|
207
|
-
covering alignment, single-sample reports, domain configs, and a batch
|
|
208
|
-
command-line tool. They are not installed with the package, so clone the
|
|
209
|
-
repository to use them. See
|
|
210
|
-
[docs/batch-processing.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/batch-processing.md)
|
|
211
|
-
for the full batch API and output schema.
|
|
193
|
+
Short runnable scripts for alignment display, single-sample reports and
|
|
194
|
+
domain configs live in the repository's
|
|
195
|
+
[`examples/`](https://github.com/adalat-ai-tech/scribe-eval/tree/main/examples) directory (not installed with the package).
|
|
196
|
+
[`docs/`](https://github.com/adalat-ai-tech/scribe-eval/tree/main/docs) covers the
|
|
197
|
+
[batch workflow](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/batch-processing.md),
|
|
198
|
+
[domain configuration](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/domain-configuration.md),
|
|
199
|
+
the [visualizer](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/visualizer.md),
|
|
200
|
+
[development](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/development.md) and the
|
|
201
|
+
[architecture and glossary](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md).
|
|
212
202
|
|
|
213
203
|
## Interactive Visualizer
|
|
214
204
|
|
|
@@ -216,59 +206,24 @@ for the full batch API and output schema.
|
|
|
216
206
|
scribe-visualizer # requires the [visualizer] extra (see Installation)
|
|
217
207
|
```
|
|
218
208
|
|
|
209
|
+
A hosted demo runs at <https://adalat-ai-tech.github.io/scribe-eval/>.
|
|
219
210
|
See [docs/visualizer.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/visualizer.md).
|
|
220
211
|
|
|
221
|
-
## Dependencies
|
|
222
|
-
|
|
223
|
-
Core: `levenshtein>=0.27.1`, `tabulate>=0.9.0`
|
|
224
|
-
|
|
225
|
-
Optional extras: `matplotlib` (for `[charts]`), `streamlit`, `pandas`, `matplotlib`, and `jiwer` (for `[visualizer]` — jiwer powers the baseline WER/CER comparison tile).
|
|
226
|
-
|
|
227
|
-
## Development
|
|
228
|
-
|
|
229
|
-
```bash
|
|
230
|
-
git clone https://github.com/adalat-ai-tech/scribe-eval.git
|
|
231
|
-
cd scribe-eval
|
|
232
|
-
uv sync --all-extras # core + [charts] + [visualizer] + dev tooling
|
|
233
|
-
```
|
|
234
|
-
|
|
235
|
-
### Running tests
|
|
236
|
-
|
|
237
|
-
```bash
|
|
238
|
-
uv run pytest # full suite
|
|
239
|
-
uv run pytest tests/test_analysis.py # one file
|
|
240
|
-
uv run pytest -k sandhi # name pattern (-k matches by substring)
|
|
241
|
-
uv run pytest -v # verbose, with each test name
|
|
242
|
-
uv run pytest --cov=scribe # with coverage
|
|
243
|
-
```
|
|
244
|
-
|
|
245
|
-
Tests are organised one file per library module under [`tests/`](https://github.com/adalat-ai-tech/scribe-eval/blob/main/tests/), plus
|
|
246
|
-
[`tests/test_paper_cases.py`](https://github.com/adalat-ai-tech/scribe-eval/blob/main/tests/test_paper_cases.py) for end-to-end golden
|
|
247
|
-
cases from the SCRIBE paper. `pytest` itself is part of the `dev` dependency
|
|
248
|
-
group, which `uv sync` installs by default.
|
|
249
|
-
|
|
250
|
-
### Lint and format
|
|
251
|
-
|
|
252
|
-
```bash
|
|
253
|
-
uv run ruff check src tests examples # lint
|
|
254
|
-
uv run ruff format src tests examples # auto-format
|
|
255
|
-
```
|
|
256
|
-
|
|
257
|
-
See [`docs/architecture.md`](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md) for the module map and a
|
|
258
|
-
glossary of project-specific terminology (sandhi, combined denominator, WER_SCRIBE, CER_SCRIBE,
|
|
259
|
-
Accuracy, ...).
|
|
260
|
-
|
|
261
212
|
## Citation
|
|
262
213
|
|
|
263
|
-
The SCRIBE paper
|
|
264
|
-
|
|
214
|
+
The SCRIBE paper was presented at Interspeech 2026 and is published in the
|
|
215
|
+
ISCA Archive: <https://doi.org/10.21437/Interspeech.2026-3436>
|
|
216
|
+
(preprint: <https://arxiv.org/abs/2605.20712>).
|
|
265
217
|
|
|
266
218
|
```bibtex
|
|
267
|
-
@
|
|
268
|
-
title={SCRIBE: Diagnostic Evaluation and Rich Transcription Models for Indic ASR},
|
|
269
|
-
author={Manohar
|
|
270
|
-
|
|
271
|
-
|
|
219
|
+
@inproceedings{manohar26_interspeech,
|
|
220
|
+
title = {{SCRIBE: Diagnostic Evaluation and Rich Transcription Models for Indic ASR}},
|
|
221
|
+
author = {Kavya Manohar and Arghya Bhattacharya and Kush Juvekar and Kumarmanas Nethil},
|
|
222
|
+
year = {2026},
|
|
223
|
+
booktitle = {{Interspeech 2026}},
|
|
224
|
+
pages = {4773--4778},
|
|
225
|
+
doi = {10.21437/Interspeech.2026-3436},
|
|
226
|
+
issn = {2958-1796},
|
|
272
227
|
}
|
|
273
228
|
```
|
|
274
229
|
|
|
@@ -6,7 +6,7 @@
|
|
|
6
6
|
|
|
7
7
|
`scribe-eval` is the open-source evaluation framework introduced in the SCRIBE
|
|
8
8
|
paper (*Diagnostic Evaluation and Rich Transcription Models for Indic ASR*,
|
|
9
|
-
|
|
9
|
+
[Interspeech 2026](https://doi.org/10.21437/Interspeech.2026-3436)). It provides fine-grained error metrics for
|
|
10
10
|
ASR systems on Indic languages (Malayalam, Kannada, Hindi, ...) and on
|
|
11
11
|
domain-specific transcription (legal, medical, technical).
|
|
12
12
|
|
|
@@ -16,27 +16,43 @@ terminology is shielded from incorrect splitting and tracked separately — so a
|
|
|
16
16
|
single misrecognized legal term doesn't inflate your general lexical
|
|
17
17
|
error rate (ER_LEX).
|
|
18
18
|
|
|
19
|
+
**Try it in the browser:** <https://adalat-ai-tech.github.io/scribe-eval/>
|
|
20
|
+
|
|
19
21
|
## Installation
|
|
20
22
|
|
|
21
23
|
```bash
|
|
22
|
-
pip install scribe-eval
|
|
23
|
-
pip install 'scribe-eval[visualizer]' # adds Streamlit UI
|
|
24
|
-
pip install 'scribe-eval[charts]' # adds matplotlib charts
|
|
24
|
+
pip install scribe-eval
|
|
25
25
|
```
|
|
26
26
|
|
|
27
|
-
|
|
28
|
-
|
|
27
|
+
This installs the library and the `scribe-batch` command. For the
|
|
28
|
+
interactive web UI, add the visualizer extra:
|
|
29
|
+
|
|
30
|
+
```bash
|
|
31
|
+
pip install 'scribe-eval[visualizer]'
|
|
32
|
+
```
|
|
29
33
|
|
|
30
34
|
To work on SCRIBE itself, install from source instead:
|
|
31
35
|
|
|
32
36
|
```bash
|
|
33
37
|
git clone https://github.com/adalat-ai-tech/scribe-eval.git
|
|
34
38
|
cd scribe-eval
|
|
35
|
-
pip install -e '.[
|
|
39
|
+
uv sync --all-extras # or: pip install -e '.[all]'
|
|
36
40
|
```
|
|
37
41
|
|
|
42
|
+
Tests, lint and layout are described in
|
|
43
|
+
[docs/development.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/development.md).
|
|
44
|
+
|
|
38
45
|
## Quick Start
|
|
39
46
|
|
|
47
|
+
Evaluate a JSONL file of predictions (one record per line with a `text`
|
|
48
|
+
reference and a `pred_text` hypothesis):
|
|
49
|
+
|
|
50
|
+
```bash
|
|
51
|
+
scribe-batch --input predictions.jsonl --output-dir results --analysis --chart
|
|
52
|
+
```
|
|
53
|
+
|
|
54
|
+
Or score a single pair in Python:
|
|
55
|
+
|
|
40
56
|
```python
|
|
41
57
|
from scribe import compute_cer_scribe, text_error_rates, DomainConfig
|
|
42
58
|
|
|
@@ -53,13 +69,54 @@ cer = compute_cer_scribe(ref, hyp, DomainConfig.legal())
|
|
|
53
69
|
print(f"CER_SCRIBE: {cer['cer_scribe']:.2%}")
|
|
54
70
|
```
|
|
55
71
|
|
|
72
|
+
### What you get
|
|
73
|
+
|
|
74
|
+
For this three-record `predictions.jsonl`:
|
|
75
|
+
|
|
76
|
+
```jsonl
|
|
77
|
+
{"text": "charged u/s 302 IPC on 22.05.2023", "pred_text": "charged u/s 303 IPC on 22-05-2023", "source_dataset": "legal-dictation"}
|
|
78
|
+
{"text": "witness PW1 deposed before the court", "pred_text": "witness PW 1 deposed before court", "source_dataset": "legal-dictation"}
|
|
79
|
+
{"text": "എനിക്ക് അറിയാം", "pred_text": "എനിക്കറിയാം", "source_dataset": "malayalam-read"}
|
|
80
|
+
```
|
|
81
|
+
|
|
82
|
+
`scribe-batch` prints the aggregate table and saves it to
|
|
83
|
+
`results/summary_report.txt`, one row overall and one per group
|
|
84
|
+
(`source_dataset` by default, any field with `--group-by`):
|
|
85
|
+
|
|
86
|
+
```
|
|
87
|
+
GROUP | ER_LEX | ER_DOMAIN | ER_NUM | ER_PUNCT | WER_SCRIBE | CER_SCRIBE | SANDHI
|
|
88
|
+
OVERALL | 6.67% | 0.00% | 6.67% | N/A | 13.33% | 9.52% | 1
|
|
89
|
+
legal-dictation | 7.69% | 0.00% | 7.69% | N/A | 15.38% | 7.14% | 0
|
|
90
|
+
malayalam-read | 0.00% | N/A | N/A | N/A | 0.00% | 21.43% | 1
|
|
91
|
+
```
|
|
92
|
+
|
|
93
|
+
`N/A` means the category had nothing to measure. The SANDHI column counts
|
|
94
|
+
merged or split compounds that were scored as matches, not errors.
|
|
95
|
+
|
|
96
|
+
With `--analysis --chart` it also writes `analysis_report.txt` (accuracy,
|
|
97
|
+
WER_SCRIBE, per-category breakdown and every frequent substitution, deletion
|
|
98
|
+
and insertion), `evaluation-detailed.jsonl` (every record with its scores) and
|
|
99
|
+
`category_breakdown.png`:
|
|
100
|
+
|
|
101
|
+

|
|
102
|
+
|
|
103
|
+
Each row shows how many reference tokens in that category were matched,
|
|
104
|
+
substituted, deleted or inserted, the accuracy, and the category's share of
|
|
105
|
+
the overall WER_SCRIBE.
|
|
106
|
+
|
|
107
|
+
`scribe-batch --help` lists every flag with its default; other field names,
|
|
108
|
+
`--no-sandhi`, `--group-by`, domains and workers are covered with the Python
|
|
109
|
+
API in
|
|
110
|
+
[docs/batch-processing.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/batch-processing.md).
|
|
111
|
+
|
|
56
112
|
## Features
|
|
57
113
|
|
|
58
114
|
- **Domain-aware tokenization** — shield domain terms from punctuation splitting; track errors separately
|
|
59
115
|
- **Sandhi correction detection** — identifies merged/split words common in Indic ASR
|
|
60
116
|
- **Normalized error rates** — combined denominator prevents misleading metrics for sparse categories
|
|
61
117
|
- **CER_SCRIBE** — character error rate on normalized token streams; format variants cost nothing, and it needs no sandhi machinery to be robust to agglutination
|
|
62
|
-
-
|
|
118
|
+
- **`scribe-batch` CLI** — one command from JSONL to summary table, per-sample JSONL, full error analysis and chart, with a run-info line that makes the run reproducible
|
|
119
|
+
- **Batch evaluation API** — evaluate in-memory records (`evaluate_records`) or JSONL files with per-sample detail and per-group aggregation
|
|
63
120
|
- **Interactive visualizer** — Streamlit UI with color-coded alignment, WER_SCRIBE/CER_SCRIBE/Accuracy metric tiles, category breakdown chart, frequent-error tables, and per-sample drill-down
|
|
64
121
|
|
|
65
122
|
## Token Categories
|
|
@@ -82,25 +139,10 @@ Agglutination makes word boundaries unstable in Indic text: the same
|
|
|
82
139
|
speech can be written as one word or two. SCRIBE detects such two-word
|
|
83
140
|
merges and splits at alignment time and scores them as matches instead
|
|
84
141
|
of errors.
|
|
85
|
-
Real examples from evaluation data (each would count as 100% WER on its
|
|
86
|
-
phrase without detection):
|
|
87
|
-
|
|
88
|
-
| Language | Reference | Hypothesis | Junction |
|
|
89
|
-
|---|---|---|---|
|
|
90
|
-
| Malayalam | അന്യായ പട്ടിക | അന്യായപ്പട്ടിക | gemination |
|
|
91
|
-
| Malayalam | എനിക്ക് അറിയാം | എനിക്കറിയാം | vowel elision |
|
|
92
|
-
| Kannada | ಪ್ರಧಾನ ಮಂತ್ರಿಗಳ | ಪ್ರಧಾನಮಂತ್ರಿಗಳ | compound merge |
|
|
93
|
-
| Kannada | ಮಿತ್ರರಾಷ್ಟ್ರಗಳು | ಮಿತ್ರ ರಾಷ್ಟ್ರಗಳು | compound split |
|
|
94
|
-
| Hindi | भाई साहब | भाईसाहब | compound spacing |
|
|
95
|
-
| Hindi | उस में | उसमें | postposition merge |
|
|
96
|
-
|
|
97
|
-
On an internal benchmark of 48 Malayalam legal dictations (private
|
|
98
|
-
data, not distributed with this repository), sandhi detection recovers
|
|
99
|
-
**3.0 percentage points of WER_SCRIBE** across 377 events that would
|
|
100
|
-
otherwise masquerade as recognition errors. The paired examples above
|
|
101
|
-
are directly reproducible: score any row with `use_sandhi=True` vs
|
|
102
|
-
`use_sandhi=False` in `text_error_rates`.
|
|
103
142
|
|
|
143
|
+
Examples in Malayalam, Kannada and Hindi, and the measured effect on
|
|
144
|
+
WER_SCRIBE, are in
|
|
145
|
+
[docs/architecture.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md#sandhi-examples-from-evaluation-data).
|
|
104
146
|
Detection is an orthographic heuristic, not a linguistic analysis — it
|
|
105
147
|
is deliberately lenient and admits some false positives. See
|
|
106
148
|
[Sandhi detection: scope and limitations](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md#sandhi-detection-scope-and-limitations)
|
|
@@ -112,69 +154,17 @@ Factory methods for bundled domains: `DomainConfig.legal()`, `DomainConfig.medic
|
|
|
112
154
|
|
|
113
155
|
File-based and custom inline configs are also supported. See [docs/domain-configuration.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/domain-configuration.md).
|
|
114
156
|
|
|
115
|
-
##
|
|
116
|
-
|
|
117
|
-
Evaluate a dataset from JSONL, one record per line:
|
|
157
|
+
## Examples and Docs
|
|
118
158
|
|
|
119
|
-
|
|
120
|
-
|
|
121
|
-
|
|
122
|
-
|
|
123
|
-
|
|
124
|
-
|
|
125
|
-
|
|
126
|
-
|
|
127
|
-
|
|
128
|
-
results = compute_sample_errors(
|
|
129
|
-
"predictions.jsonl", domain_config=DomainConfig.legal(), collect_error_details=True
|
|
130
|
-
)
|
|
131
|
-
print_evaluation_summary(compute_aggregate_metrics(results))
|
|
132
|
-
```
|
|
133
|
-
|
|
134
|
-
```
|
|
135
|
-
DATASET | ER_LEX | ER_DOMAIN | ER_NUM | ER_PUNCT | WER_SCRIBE | CER_SCRIBE | SANDHI
|
|
136
|
-
OVERALL | 7.14% | 7.14% | 7.14% | N/A | 21.43% | 10.84% | 1
|
|
137
|
-
legal-dictation | 8.33% | 8.33% | 8.33% | N/A | 25.00% | 8.70% | 0
|
|
138
|
-
malayalam-read | 0.00% | N/A | N/A | N/A | 0.00% | 21.43% | 1
|
|
139
|
-
```
|
|
140
|
-
|
|
141
|
-
The Malayalam hypothesis merges a two-word compound; it is counted as a Sandhi
|
|
142
|
-
match, not as errors. `N/A` marks a category with no reference tokens and no
|
|
143
|
-
errors.
|
|
144
|
-
|
|
145
|
-
`evaluate_records()` accepts a list of dicts instead of a file path.
|
|
146
|
-
`output_file=` writes per-sample reports as JSONL. `workers=N` evaluates
|
|
147
|
-
samples in parallel.
|
|
148
|
-
|
|
149
|
-
### Charts
|
|
150
|
-
|
|
151
|
-
Continuing from `results` above, with the `[charts]` extra installed:
|
|
152
|
-
|
|
153
|
-
```python
|
|
154
|
-
from scribe import aggregate_error_details, compute_error_summary
|
|
155
|
-
from scribe.charts import category_breakdown_chart
|
|
156
|
-
|
|
157
|
-
summary = compute_error_summary(
|
|
158
|
-
compute_aggregate_metrics(results)["overall"], aggregate_error_details(results), top_n=10
|
|
159
|
-
)
|
|
160
|
-
category_breakdown_chart(summary["contributions"], output_path="breakdown.png")
|
|
161
|
-
```
|
|
162
|
-
|
|
163
|
-

|
|
164
|
-
|
|
165
|
-
One row per category: a normalized outcome bar, an accuracy figure, and that
|
|
166
|
-
category's contribution to WER_SCRIBE. Punctuation is marked "nothing to
|
|
167
|
-
measure" because the reference carries no punctuation tokens.
|
|
168
|
-
|
|
169
|
-
## Examples
|
|
170
|
-
|
|
171
|
-
Runnable scripts live in the repository under
|
|
172
|
-
[`examples/`](https://github.com/adalat-ai-tech/scribe-eval/tree/main/examples),
|
|
173
|
-
covering alignment, single-sample reports, domain configs, and a batch
|
|
174
|
-
command-line tool. They are not installed with the package, so clone the
|
|
175
|
-
repository to use them. See
|
|
176
|
-
[docs/batch-processing.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/batch-processing.md)
|
|
177
|
-
for the full batch API and output schema.
|
|
159
|
+
Short runnable scripts for alignment display, single-sample reports and
|
|
160
|
+
domain configs live in the repository's
|
|
161
|
+
[`examples/`](https://github.com/adalat-ai-tech/scribe-eval/tree/main/examples) directory (not installed with the package).
|
|
162
|
+
[`docs/`](https://github.com/adalat-ai-tech/scribe-eval/tree/main/docs) covers the
|
|
163
|
+
[batch workflow](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/batch-processing.md),
|
|
164
|
+
[domain configuration](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/domain-configuration.md),
|
|
165
|
+
the [visualizer](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/visualizer.md),
|
|
166
|
+
[development](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/development.md) and the
|
|
167
|
+
[architecture and glossary](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md).
|
|
178
168
|
|
|
179
169
|
## Interactive Visualizer
|
|
180
170
|
|
|
@@ -182,59 +172,24 @@ for the full batch API and output schema.
|
|
|
182
172
|
scribe-visualizer # requires the [visualizer] extra (see Installation)
|
|
183
173
|
```
|
|
184
174
|
|
|
175
|
+
A hosted demo runs at <https://adalat-ai-tech.github.io/scribe-eval/>.
|
|
185
176
|
See [docs/visualizer.md](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/visualizer.md).
|
|
186
177
|
|
|
187
|
-
## Dependencies
|
|
188
|
-
|
|
189
|
-
Core: `levenshtein>=0.27.1`, `tabulate>=0.9.0`
|
|
190
|
-
|
|
191
|
-
Optional extras: `matplotlib` (for `[charts]`), `streamlit`, `pandas`, `matplotlib`, and `jiwer` (for `[visualizer]` — jiwer powers the baseline WER/CER comparison tile).
|
|
192
|
-
|
|
193
|
-
## Development
|
|
194
|
-
|
|
195
|
-
```bash
|
|
196
|
-
git clone https://github.com/adalat-ai-tech/scribe-eval.git
|
|
197
|
-
cd scribe-eval
|
|
198
|
-
uv sync --all-extras # core + [charts] + [visualizer] + dev tooling
|
|
199
|
-
```
|
|
200
|
-
|
|
201
|
-
### Running tests
|
|
202
|
-
|
|
203
|
-
```bash
|
|
204
|
-
uv run pytest # full suite
|
|
205
|
-
uv run pytest tests/test_analysis.py # one file
|
|
206
|
-
uv run pytest -k sandhi # name pattern (-k matches by substring)
|
|
207
|
-
uv run pytest -v # verbose, with each test name
|
|
208
|
-
uv run pytest --cov=scribe # with coverage
|
|
209
|
-
```
|
|
210
|
-
|
|
211
|
-
Tests are organised one file per library module under [`tests/`](https://github.com/adalat-ai-tech/scribe-eval/blob/main/tests/), plus
|
|
212
|
-
[`tests/test_paper_cases.py`](https://github.com/adalat-ai-tech/scribe-eval/blob/main/tests/test_paper_cases.py) for end-to-end golden
|
|
213
|
-
cases from the SCRIBE paper. `pytest` itself is part of the `dev` dependency
|
|
214
|
-
group, which `uv sync` installs by default.
|
|
215
|
-
|
|
216
|
-
### Lint and format
|
|
217
|
-
|
|
218
|
-
```bash
|
|
219
|
-
uv run ruff check src tests examples # lint
|
|
220
|
-
uv run ruff format src tests examples # auto-format
|
|
221
|
-
```
|
|
222
|
-
|
|
223
|
-
See [`docs/architecture.md`](https://github.com/adalat-ai-tech/scribe-eval/blob/main/docs/architecture.md) for the module map and a
|
|
224
|
-
glossary of project-specific terminology (sandhi, combined denominator, WER_SCRIBE, CER_SCRIBE,
|
|
225
|
-
Accuracy, ...).
|
|
226
|
-
|
|
227
178
|
## Citation
|
|
228
179
|
|
|
229
|
-
The SCRIBE paper
|
|
230
|
-
|
|
180
|
+
The SCRIBE paper was presented at Interspeech 2026 and is published in the
|
|
181
|
+
ISCA Archive: <https://doi.org/10.21437/Interspeech.2026-3436>
|
|
182
|
+
(preprint: <https://arxiv.org/abs/2605.20712>).
|
|
231
183
|
|
|
232
184
|
```bibtex
|
|
233
|
-
@
|
|
234
|
-
title={SCRIBE: Diagnostic Evaluation and Rich Transcription Models for Indic ASR},
|
|
235
|
-
author={Manohar
|
|
236
|
-
|
|
237
|
-
|
|
185
|
+
@inproceedings{manohar26_interspeech,
|
|
186
|
+
title = {{SCRIBE: Diagnostic Evaluation and Rich Transcription Models for Indic ASR}},
|
|
187
|
+
author = {Kavya Manohar and Arghya Bhattacharya and Kush Juvekar and Kumarmanas Nethil},
|
|
188
|
+
year = {2026},
|
|
189
|
+
booktitle = {{Interspeech 2026}},
|
|
190
|
+
pages = {4773--4778},
|
|
191
|
+
doi = {10.21437/Interspeech.2026-3436},
|
|
192
|
+
issn = {2958-1796},
|
|
238
193
|
}
|
|
239
194
|
```
|
|
240
195
|
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
[project]
|
|
2
2
|
name = "scribe-eval"
|
|
3
|
-
version = "0.
|
|
3
|
+
version = "0.2.0"
|
|
4
4
|
description = "Diagnostic ASR evaluation with sandhi-tolerant alignment and categorical error decomposition for Indic and domain-specific speech recognition."
|
|
5
5
|
readme = "README.md"
|
|
6
6
|
license = { text = "Apache-2.0" }
|
|
@@ -32,14 +32,17 @@ classifiers = [
|
|
|
32
32
|
dependencies = [
|
|
33
33
|
"levenshtein>=0.27.1",
|
|
34
34
|
"tabulate>=0.9.0",
|
|
35
|
+
# Charts are part of the core batch workflow (`scribe-batch --chart`),
|
|
36
|
+
# so matplotlib ships with the base install.
|
|
37
|
+
"matplotlib>=3.7.0",
|
|
35
38
|
]
|
|
36
39
|
|
|
37
40
|
[project.optional-dependencies]
|
|
38
|
-
charts = ["matplotlib>=3.7.0"]
|
|
39
41
|
# jiwer powers the visualizer's independent baseline WER/CER tile; the
|
|
40
|
-
# core library computes its own metrics
|
|
41
|
-
|
|
42
|
-
|
|
42
|
+
# core library computes its own metrics and does not import it.
|
|
43
|
+
visualizer = ["streamlit>=1.53.0", "pandas>=2.0.0", "jiwer>=4.0.0"]
|
|
44
|
+
# Everything: core + every optional component.
|
|
45
|
+
all = ["scribe-eval[visualizer]"]
|
|
43
46
|
|
|
44
47
|
# Dev tooling is a PEP 735 dependency group, not a published extra:
|
|
45
48
|
# `uv sync` installs it by default, and it never appears as a
|
|
@@ -48,6 +51,7 @@ visualizer = ["streamlit>=1.53.0", "pandas>=2.0.0", "matplotlib>=3.7.0", "jiwer>
|
|
|
48
51
|
dev = ["pytest>=8.0", "pytest-cov", "ruff>=0.6", "mypy", "build", "twine"]
|
|
49
52
|
|
|
50
53
|
[project.scripts]
|
|
54
|
+
scribe-batch = "scribe.batch_cli:main"
|
|
51
55
|
scribe-visualizer = "scribe.visualizer.__main__:main"
|
|
52
56
|
|
|
53
57
|
[project.urls]
|