scigantic-empiar 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- scigantic_empiar-0.1.0/LICENSE +21 -0
- scigantic_empiar-0.1.0/PKG-INFO +85 -0
- scigantic_empiar-0.1.0/README.md +60 -0
- scigantic_empiar-0.1.0/pyproject.toml +32 -0
- scigantic_empiar-0.1.0/scigantic_empiar/__init__.py +51 -0
- scigantic_empiar-0.1.0/scigantic_empiar/catalog.py +86 -0
- scigantic_empiar-0.1.0/scigantic_empiar/config.py +35 -0
- scigantic_empiar-0.1.0/scigantic_empiar/mrc.py +119 -0
- scigantic_empiar-0.1.0/scigantic_empiar/reader.py +74 -0
- scigantic_empiar-0.1.0/scigantic_empiar/render.py +58 -0
- scigantic_empiar-0.1.0/scigantic_empiar/workspace.py +39 -0
- scigantic_empiar-0.1.0/scigantic_empiar.egg-info/PKG-INFO +85 -0
- scigantic_empiar-0.1.0/scigantic_empiar.egg-info/SOURCES.txt +19 -0
- scigantic_empiar-0.1.0/scigantic_empiar.egg-info/dependency_links.txt +1 -0
- scigantic_empiar-0.1.0/scigantic_empiar.egg-info/requires.txt +13 -0
- scigantic_empiar-0.1.0/scigantic_empiar.egg-info/top_level.txt +1 -0
- scigantic_empiar-0.1.0/setup.cfg +4 -0
- scigantic_empiar-0.1.0/tests/test_catalog.py +49 -0
- scigantic_empiar-0.1.0/tests/test_mrc.py +64 -0
- scigantic_empiar-0.1.0/tests/test_preview.py +35 -0
- scigantic_empiar-0.1.0/tests/test_reader.py +68 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
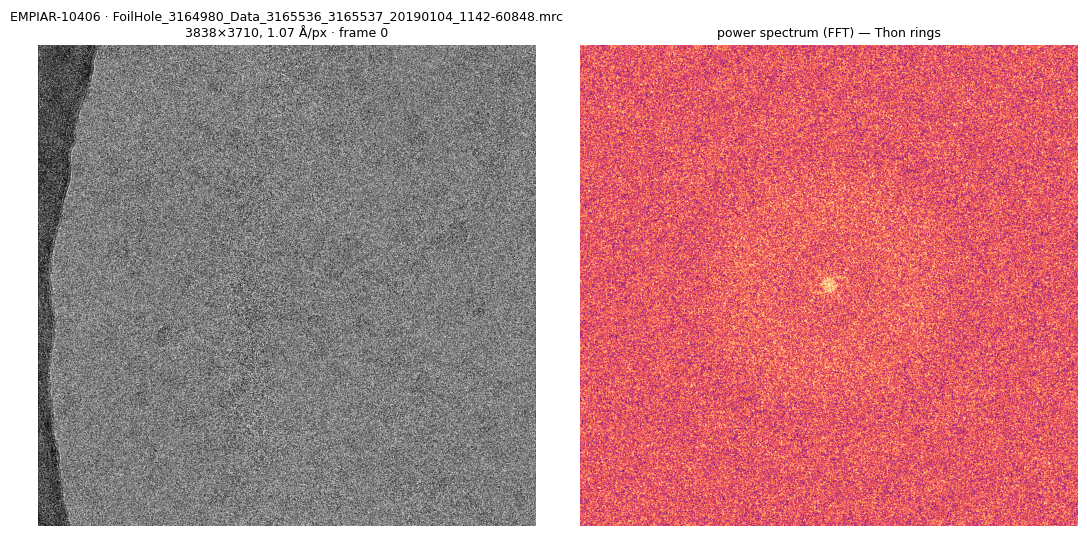
Copyright (c) 2026 Scigantic
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,85 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: scigantic-empiar
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Explore the EMPIAR cryo-EM archive from Python — stream any of ~3,000 datasets (8.9 PiB) over parallel HTTP range reads, nothing downloaded.
|
|
5
|
+
Author: Scigantic
|
|
6
|
+
License: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/scigantic/scigantic-empiar
|
|
8
|
+
Project-URL: EMPIAR, https://www.ebi.ac.uk/empiar/
|
|
9
|
+
Keywords: cryo-em,cryo-et,empiar,mrc,structural-biology,microscopy
|
|
10
|
+
Requires-Python: >=3.9
|
|
11
|
+
Description-Content-Type: text/markdown
|
|
12
|
+
License-File: LICENSE
|
|
13
|
+
Requires-Dist: numpy
|
|
14
|
+
Requires-Dist: requests
|
|
15
|
+
Provides-Extra: viz
|
|
16
|
+
Requires-Dist: matplotlib; extra == "viz"
|
|
17
|
+
Requires-Dist: pandas; extra == "viz"
|
|
18
|
+
Requires-Dist: pillow; extra == "viz"
|
|
19
|
+
Requires-Dist: ipython; extra == "viz"
|
|
20
|
+
Provides-Extra: dev
|
|
21
|
+
Requires-Dist: pytest; extra == "dev"
|
|
22
|
+
Requires-Dist: matplotlib; extra == "dev"
|
|
23
|
+
Requires-Dist: pandas; extra == "dev"
|
|
24
|
+
Dynamic: license-file
|
|
25
|
+
|
|
26
|
+
# scigantic_empiar
|
|
27
|
+
|
|
28
|
+
Explore [EMPIAR](https://www.ebi.ac.uk/empiar/) — EMBL-EBI's public archive of **raw cryo-EM / cryo-ET image data** (~3,000 datasets, ~8.9 PiB) — from Python, **without downloading anything**.
|
|
29
|
+
|
|
30
|
+
EMPIAR is served over EBI's public HTTPS at ~1.5 MB/s per connection. `scigantic_empiar` parallelises HTTP **range** reads (8-way ≈ 5–10 MB/s) so you can pull a single frame from a many-GB entry in seconds, decode the MRC, and render the micrograph + its power spectrum — nothing is copied to disk.
|
|
31
|
+
|
|
32
|
+
```python
|
|
33
|
+
import scigantic_empiar as se
|
|
34
|
+
|
|
35
|
+
se.preview(10406) # render the micrograph below, in seconds
|
|
36
|
+
se.EmpiarClient().summary(10406) # title, pixel size, method, DOI, EMDB/PDB cross-refs
|
|
37
|
+
se.EmpiarCatalog().search("ribosome") # search the whole archive by metadata (instant)
|
|
38
|
+
```
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
|
|
42
|
+
*One frame of EMPIAR-10406 (a 70S-ribosome dataset) pulled straight from EBI over parallel range reads — the carbon-foil edge, ice, and particles are visible at left; the FFT is at right. Nothing was downloaded to disk.*
|
|
43
|
+
|
|
44
|
+
## Install
|
|
45
|
+
|
|
46
|
+
```bash
|
|
47
|
+
pip install "scigantic-empiar[viz] @ git+https://github.com/scigantic/scigantic-empiar"
|
|
48
|
+
```
|
|
49
|
+
|
|
50
|
+
Core (`numpy`, `requests`) is enough for the readers; `[viz]` adds `matplotlib` / `pandas` / `pillow` for `preview()` and the catalog gallery.
|
|
51
|
+
|
|
52
|
+
## What it does
|
|
53
|
+
|
|
54
|
+
| | |
|
|
55
|
+
|---|---|
|
|
56
|
+
| `preview(id)` | micrograph / tomogram-slice + power spectrum, rendered from a lazy parallel-range read |
|
|
57
|
+
| `read_mrc_frame(id)` / `read_mrc_average(id)` | one frame / a mean of frames as a NumPy array + header |
|
|
58
|
+
| `thumbnail(id)` | small preview array (a few-MB central-strip read) — used to build catalogs |
|
|
59
|
+
| `find_mrc(id)` | resolve an entry's first MRC, recursing the (often nested) `data/` layout |
|
|
60
|
+
| `pread(url, off, len)` | the 8-way parallel HTTP range reader under it all |
|
|
61
|
+
| `EmpiarClient` | per-entry metadata from EMPIAR's REST API (cached) |
|
|
62
|
+
| `EmpiarCatalog` | search + a visual thumbnail gallery across all entries (from a prebuilt index) |
|
|
63
|
+
| `add_to_fast_workspace(id)` | mirror an entry to S3 for full-speed reprocessing (RELION/EMAN2) |
|
|
64
|
+
|
|
65
|
+
## Why parallel range reads
|
|
66
|
+
|
|
67
|
+
EBI throttles per connection (~1.5 MB/s) and past ~8 concurrent connections. `pread` splits a read into ~8 concurrent range requests, which aggregates to ~5–10 MB/s — enough to *look* at any entry interactively. For heavy reprocessing of a whole multi-hundred-GB dataset, mirror it to fast storage first (`add_to_fast_workspace`); streaming a full entry at 1.5 MB/s isn't practical.
|
|
68
|
+
|
|
69
|
+
## Existing work
|
|
70
|
+
|
|
71
|
+
The job splits in two: parse MRC, and read bytes from a remote file. Both have existing libraries; neither covers the specific case here.
|
|
72
|
+
|
|
73
|
+
- [`mrcfile`](https://github.com/ccpem/mrcfile) (CCP-EM) is the standard MRC reader. Its lazy mode is a numpy `memmap`, which needs a local filesystem path — it does not issue HTTP range requests. `scigantic_empiar` parses the 1024-byte header directly (`parse_mrc_header`) to seek to one frame of a remote file without a local copy.
|
|
74
|
+
- [`fsspec`](https://filesystem-spec.readthedocs.io/) `HTTPFileSystem` turns byte reads into HTTP range requests and can fetch many ranges concurrently ([`cat_ranges`](https://filesystem-spec.readthedocs.io/en/latest/async.html)). `pread` is a small equivalent, kept dependency-free and tuned to EBI's ~8-connection throttle; moving the transport onto `fsspec` is a reasonable later change.
|
|
75
|
+
- [`copick`](https://github.com/copick/copick) (CZI, [Protein Science 2026](https://onlinelibrary.wiley.com/doi/10.1002/pro.70578)) is the closest cryo-EM analog: an fsspec-backed, server-less dataset API with lazy reads. It assumes data stored as OME-Zarr (chunked, multiscale). EMPIAR entries are raw MRC/TIFF, so copick needs a per-entry zarr conversion first — the conversion that MRC's flat layout lets `scigantic_empiar` skip.
|
|
76
|
+
|
|
77
|
+
## Notes
|
|
78
|
+
|
|
79
|
+
- MRC/MRCS (movies, micrographs, tomograms, particle stacks) and some TIFF. Files often nest a couple subdir levels down; `find_mrc` handles that.
|
|
80
|
+
- Entry ids are opaque numbers — discover datasets by **metadata** (`EmpiarCatalog.search`, or the EMPIAR website), not by listing the tree.
|
|
81
|
+
- Inside a [Scigantic](https://scigantic.com) cryo-EM notebook this is preinstalled and the archive is also FUSE-mounted at `$SCIGANTIC_MOUNT_PATH`; standalone, it streams straight from EBI.
|
|
82
|
+
|
|
83
|
+
## License
|
|
84
|
+
|
|
85
|
+
MIT.
|
|
@@ -0,0 +1,60 @@
|
|
|
1
|
+
# scigantic_empiar
|
|
2
|
+
|
|
3
|
+
Explore [EMPIAR](https://www.ebi.ac.uk/empiar/) — EMBL-EBI's public archive of **raw cryo-EM / cryo-ET image data** (~3,000 datasets, ~8.9 PiB) — from Python, **without downloading anything**.
|
|
4
|
+
|
|
5
|
+
EMPIAR is served over EBI's public HTTPS at ~1.5 MB/s per connection. `scigantic_empiar` parallelises HTTP **range** reads (8-way ≈ 5–10 MB/s) so you can pull a single frame from a many-GB entry in seconds, decode the MRC, and render the micrograph + its power spectrum — nothing is copied to disk.
|
|
6
|
+
|
|
7
|
+
```python
|
|
8
|
+
import scigantic_empiar as se
|
|
9
|
+
|
|
10
|
+
se.preview(10406) # render the micrograph below, in seconds
|
|
11
|
+
se.EmpiarClient().summary(10406) # title, pixel size, method, DOI, EMDB/PDB cross-refs
|
|
12
|
+
se.EmpiarCatalog().search("ribosome") # search the whole archive by metadata (instant)
|
|
13
|
+
```
|
|
14
|
+
|
|
15
|
+

|
|
16
|
+
|
|
17
|
+
*One frame of EMPIAR-10406 (a 70S-ribosome dataset) pulled straight from EBI over parallel range reads — the carbon-foil edge, ice, and particles are visible at left; the FFT is at right. Nothing was downloaded to disk.*
|
|
18
|
+
|
|
19
|
+
## Install
|
|
20
|
+
|
|
21
|
+
```bash
|
|
22
|
+
pip install "scigantic-empiar[viz] @ git+https://github.com/scigantic/scigantic-empiar"
|
|
23
|
+
```
|
|
24
|
+
|
|
25
|
+
Core (`numpy`, `requests`) is enough for the readers; `[viz]` adds `matplotlib` / `pandas` / `pillow` for `preview()` and the catalog gallery.
|
|
26
|
+
|
|
27
|
+
## What it does
|
|
28
|
+
|
|
29
|
+
| | |
|
|
30
|
+
|---|---|
|
|
31
|
+
| `preview(id)` | micrograph / tomogram-slice + power spectrum, rendered from a lazy parallel-range read |
|
|
32
|
+
| `read_mrc_frame(id)` / `read_mrc_average(id)` | one frame / a mean of frames as a NumPy array + header |
|
|
33
|
+
| `thumbnail(id)` | small preview array (a few-MB central-strip read) — used to build catalogs |
|
|
34
|
+
| `find_mrc(id)` | resolve an entry's first MRC, recursing the (often nested) `data/` layout |
|
|
35
|
+
| `pread(url, off, len)` | the 8-way parallel HTTP range reader under it all |
|
|
36
|
+
| `EmpiarClient` | per-entry metadata from EMPIAR's REST API (cached) |
|
|
37
|
+
| `EmpiarCatalog` | search + a visual thumbnail gallery across all entries (from a prebuilt index) |
|
|
38
|
+
| `add_to_fast_workspace(id)` | mirror an entry to S3 for full-speed reprocessing (RELION/EMAN2) |
|
|
39
|
+
|
|
40
|
+
## Why parallel range reads
|
|
41
|
+
|
|
42
|
+
EBI throttles per connection (~1.5 MB/s) and past ~8 concurrent connections. `pread` splits a read into ~8 concurrent range requests, which aggregates to ~5–10 MB/s — enough to *look* at any entry interactively. For heavy reprocessing of a whole multi-hundred-GB dataset, mirror it to fast storage first (`add_to_fast_workspace`); streaming a full entry at 1.5 MB/s isn't practical.
|
|
43
|
+
|
|
44
|
+
## Existing work
|
|
45
|
+
|
|
46
|
+
The job splits in two: parse MRC, and read bytes from a remote file. Both have existing libraries; neither covers the specific case here.
|
|
47
|
+
|
|
48
|
+
- [`mrcfile`](https://github.com/ccpem/mrcfile) (CCP-EM) is the standard MRC reader. Its lazy mode is a numpy `memmap`, which needs a local filesystem path — it does not issue HTTP range requests. `scigantic_empiar` parses the 1024-byte header directly (`parse_mrc_header`) to seek to one frame of a remote file without a local copy.
|
|
49
|
+
- [`fsspec`](https://filesystem-spec.readthedocs.io/) `HTTPFileSystem` turns byte reads into HTTP range requests and can fetch many ranges concurrently ([`cat_ranges`](https://filesystem-spec.readthedocs.io/en/latest/async.html)). `pread` is a small equivalent, kept dependency-free and tuned to EBI's ~8-connection throttle; moving the transport onto `fsspec` is a reasonable later change.
|
|
50
|
+
- [`copick`](https://github.com/copick/copick) (CZI, [Protein Science 2026](https://onlinelibrary.wiley.com/doi/10.1002/pro.70578)) is the closest cryo-EM analog: an fsspec-backed, server-less dataset API with lazy reads. It assumes data stored as OME-Zarr (chunked, multiscale). EMPIAR entries are raw MRC/TIFF, so copick needs a per-entry zarr conversion first — the conversion that MRC's flat layout lets `scigantic_empiar` skip.
|
|
51
|
+
|
|
52
|
+
## Notes
|
|
53
|
+
|
|
54
|
+
- MRC/MRCS (movies, micrographs, tomograms, particle stacks) and some TIFF. Files often nest a couple subdir levels down; `find_mrc` handles that.
|
|
55
|
+
- Entry ids are opaque numbers — discover datasets by **metadata** (`EmpiarCatalog.search`, or the EMPIAR website), not by listing the tree.
|
|
56
|
+
- Inside a [Scigantic](https://scigantic.com) cryo-EM notebook this is preinstalled and the archive is also FUSE-mounted at `$SCIGANTIC_MOUNT_PATH`; standalone, it streams straight from EBI.
|
|
57
|
+
|
|
58
|
+
## License
|
|
59
|
+
|
|
60
|
+
MIT.
|
|
@@ -0,0 +1,32 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["setuptools>=61"]
|
|
3
|
+
build-backend = "setuptools.build_meta"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "scigantic-empiar"
|
|
7
|
+
version = "0.1.0"
|
|
8
|
+
description = "Explore the EMPIAR cryo-EM archive from Python — stream any of ~3,000 datasets (8.9 PiB) over parallel HTTP range reads, nothing downloaded."
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
requires-python = ">=3.9"
|
|
11
|
+
license = { text = "MIT" }
|
|
12
|
+
authors = [{ name = "Scigantic" }]
|
|
13
|
+
keywords = ["cryo-em", "cryo-et", "empiar", "mrc", "structural-biology", "microscopy"]
|
|
14
|
+
dependencies = [
|
|
15
|
+
"numpy",
|
|
16
|
+
"requests",
|
|
17
|
+
]
|
|
18
|
+
|
|
19
|
+
[project.optional-dependencies]
|
|
20
|
+
# Needed for preview() (rendering) and EmpiarCatalog gallery/search.
|
|
21
|
+
viz = ["matplotlib", "pandas", "pillow", "ipython"]
|
|
22
|
+
dev = ["pytest", "matplotlib", "pandas"]
|
|
23
|
+
|
|
24
|
+
[project.urls]
|
|
25
|
+
Homepage = "https://github.com/scigantic/scigantic-empiar"
|
|
26
|
+
"EMPIAR" = "https://www.ebi.ac.uk/empiar/"
|
|
27
|
+
|
|
28
|
+
[tool.setuptools]
|
|
29
|
+
packages = ["scigantic_empiar"]
|
|
30
|
+
|
|
31
|
+
[tool.pytest.ini_options]
|
|
32
|
+
testpaths = ["tests"]
|
|
@@ -0,0 +1,51 @@
|
|
|
1
|
+
"""scigantic_empiar — explore EMPIAR cryo-EM data over HTTP, without downloading.
|
|
2
|
+
|
|
3
|
+
import scigantic_empiar as se
|
|
4
|
+
se.preview(10002) # micrograph + power spectrum, in seconds
|
|
5
|
+
se.EmpiarCatalog().search("ribosome") # search the whole archive
|
|
6
|
+
|
|
7
|
+
The package is split into focused modules; this file re-exports the public API so
|
|
8
|
+
the flat ``se.<name>`` calls above keep working:
|
|
9
|
+
|
|
10
|
+
config locations + shared HTTP session (env-overridable)
|
|
11
|
+
reader parallel HTTP range reads (pread) + path/URL helpers
|
|
12
|
+
mrc MRC/MRCS parsing, file discovery, NumPy readers
|
|
13
|
+
catalog metadata client (EmpiarClient) + searchable catalog (EmpiarCatalog)
|
|
14
|
+
render inline micrograph + power-spectrum rendering (needs matplotlib)
|
|
15
|
+
workspace mirror an entry to fast storage for reprocessing
|
|
16
|
+
"""
|
|
17
|
+
from __future__ import annotations
|
|
18
|
+
|
|
19
|
+
from .catalog import EmpiarCatalog, EmpiarClient
|
|
20
|
+
from .config import API, CATALOG_URL, EBI, FAST_BUCKET, FAST_MNT, MOUNT
|
|
21
|
+
from .mrc import (
|
|
22
|
+
find_mrc,
|
|
23
|
+
parse_mrc_header,
|
|
24
|
+
power_spectrum,
|
|
25
|
+
read_mrc,
|
|
26
|
+
read_mrc_average,
|
|
27
|
+
read_mrc_frame,
|
|
28
|
+
thumbnail,
|
|
29
|
+
)
|
|
30
|
+
from .reader import entry_url, fast_path, list_files, pread
|
|
31
|
+
from .render import preview
|
|
32
|
+
from .workspace import add_to_fast_workspace
|
|
33
|
+
|
|
34
|
+
__version__ = "0.1.0"
|
|
35
|
+
|
|
36
|
+
__all__ = [
|
|
37
|
+
# rendering
|
|
38
|
+
"preview",
|
|
39
|
+
# readers
|
|
40
|
+
"read_mrc", "read_mrc_frame", "read_mrc_average", "thumbnail",
|
|
41
|
+
"find_mrc", "parse_mrc_header", "power_spectrum",
|
|
42
|
+
# transport
|
|
43
|
+
"pread", "list_files", "entry_url", "fast_path",
|
|
44
|
+
# metadata / catalog
|
|
45
|
+
"EmpiarClient", "EmpiarCatalog",
|
|
46
|
+
# fast workspace
|
|
47
|
+
"add_to_fast_workspace",
|
|
48
|
+
# config constants
|
|
49
|
+
"MOUNT", "EBI", "API", "CATALOG_URL", "FAST_BUCKET", "FAST_MNT",
|
|
50
|
+
"__version__",
|
|
51
|
+
]
|
|
@@ -0,0 +1,86 @@
|
|
|
1
|
+
"""EMPIAR metadata client + a searchable, visual catalog across all entries."""
|
|
2
|
+
from __future__ import annotations
|
|
3
|
+
import functools
|
|
4
|
+
import os
|
|
5
|
+
|
|
6
|
+
from .config import API, CATALOG_URL, MOUNT, session
|
|
7
|
+
|
|
8
|
+
|
|
9
|
+
class EmpiarClient:
|
|
10
|
+
"""Per-entry metadata from EMPIAR's REST API (cached)."""
|
|
11
|
+
|
|
12
|
+
@functools.lru_cache(maxsize=4096)
|
|
13
|
+
def entry(self, entry_id):
|
|
14
|
+
eid = str(entry_id).replace("EMPIAR-", "")
|
|
15
|
+
r = session.get(f"{API}/{eid}/", timeout=30)
|
|
16
|
+
r.raise_for_status()
|
|
17
|
+
d = r.json()
|
|
18
|
+
e = d.get(f"EMPIAR-{eid}") or (list(d.values())[0] if d else {})
|
|
19
|
+
return e if isinstance(e, dict) else {}
|
|
20
|
+
|
|
21
|
+
def summary(self, entry_id):
|
|
22
|
+
e = self.entry(entry_id)
|
|
23
|
+
iss = e.get("imagesets") or [{}]
|
|
24
|
+
i0 = iss[0] if isinstance(iss[0], dict) else {}
|
|
25
|
+
return dict(
|
|
26
|
+
id=str(entry_id).replace("EMPIAR-", ""),
|
|
27
|
+
title=e.get("title", ""),
|
|
28
|
+
size=e.get("dataset_size", ""),
|
|
29
|
+
format=i0.get("data_format") or i0.get("header_format"),
|
|
30
|
+
category=i0.get("category"),
|
|
31
|
+
release_date=e.get("release_date"),
|
|
32
|
+
doi=e.get("entry_doi"),
|
|
33
|
+
)
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
class EmpiarCatalog:
|
|
37
|
+
"""Searchable, visual catalog across the whole archive.
|
|
38
|
+
|
|
39
|
+
Loads a prebuilt index (id, title, size, method, thumbnail per entry) so
|
|
40
|
+
search/filter over all ~3,000 entries is instant. Falls back to the mount
|
|
41
|
+
listing when no index is available.
|
|
42
|
+
"""
|
|
43
|
+
|
|
44
|
+
def __init__(self, url=CATALOG_URL):
|
|
45
|
+
self.url = url
|
|
46
|
+
self._df = None
|
|
47
|
+
|
|
48
|
+
def load(self):
|
|
49
|
+
import pandas as pd
|
|
50
|
+
if self._df is not None:
|
|
51
|
+
return self._df
|
|
52
|
+
try:
|
|
53
|
+
self._df = pd.DataFrame(session.get(self.url, timeout=30).json())
|
|
54
|
+
except Exception:
|
|
55
|
+
ids = sorted(os.listdir(MOUNT)) if os.path.isdir(MOUNT) else []
|
|
56
|
+
self._df = pd.DataFrame({"id": ids})
|
|
57
|
+
return self._df
|
|
58
|
+
|
|
59
|
+
def search(self, query=None, method=None, max_gb=None, limit=50):
|
|
60
|
+
df = self.load().copy()
|
|
61
|
+
if query and "title" in df:
|
|
62
|
+
df = df[df["title"].str.contains(query, case=False, na=False)]
|
|
63
|
+
if method and "method" in df:
|
|
64
|
+
df = df[df["method"].str.contains(method, case=False, na=False)]
|
|
65
|
+
if max_gb and "size_gb" in df:
|
|
66
|
+
df = df[df["size_gb"].fillna(1e9) <= max_gb]
|
|
67
|
+
return df.head(limit)
|
|
68
|
+
|
|
69
|
+
def gallery(self, df=None, cols=4):
|
|
70
|
+
"""Render a thumbnail gallery (HTML) for a set of entries."""
|
|
71
|
+
from IPython.display import HTML
|
|
72
|
+
df = self.load() if df is None else df
|
|
73
|
+
cells = []
|
|
74
|
+
for _, r in df.iterrows():
|
|
75
|
+
thumb = r.get("thumbnail_url") or ""
|
|
76
|
+
img = (
|
|
77
|
+
f'<img src="{thumb}" style="width:100%;border-radius:6px">' if thumb
|
|
78
|
+
else '<div style="height:120px;background:#eee;border-radius:6px"></div>'
|
|
79
|
+
)
|
|
80
|
+
cells.append(
|
|
81
|
+
f'<div style="width:{100 // cols - 2}%;display:inline-block;vertical-align:top;'
|
|
82
|
+
f'margin:1%;font:11px sans-serif">{img}'
|
|
83
|
+
f'<b>EMPIAR-{r.get("id", "")}</b><br>{str(r.get("title", ""))[:70]}'
|
|
84
|
+
f'<br><span style="color:#888">{r.get("size", "")}</span></div>'
|
|
85
|
+
)
|
|
86
|
+
return HTML("<div>" + "".join(cells) + "</div>")
|
|
@@ -0,0 +1,35 @@
|
|
|
1
|
+
"""Locations + the shared HTTP session for scigantic_empiar.
|
|
2
|
+
|
|
3
|
+
Everything is overridable via env vars so a Scigantic notebook (mounted at
|
|
4
|
+
``$SCIGANTIC_MOUNT_PATH``, with its own catalog/fast buckets) and a standalone
|
|
5
|
+
install behave sensibly without config.
|
|
6
|
+
"""
|
|
7
|
+
from __future__ import annotations
|
|
8
|
+
import os
|
|
9
|
+
import requests
|
|
10
|
+
|
|
11
|
+
# The whole EMPIAR tree is FUSE-mounted here inside a Scigantic notebook. When
|
|
12
|
+
# absent (standalone use), the readers stream straight from EBI over HTTPS.
|
|
13
|
+
MOUNT = os.environ.get("SCIGANTIC_MOUNT_PATH", "/mnt/http-archive/data")
|
|
14
|
+
|
|
15
|
+
# EBI's public data endpoints.
|
|
16
|
+
EBI = "https://ftp.ebi.ac.uk/empiar/world_availability"
|
|
17
|
+
API = "https://www.ebi.ac.uk/empiar/api/entry"
|
|
18
|
+
|
|
19
|
+
# Prebuilt per-entry metadata + thumbnail index (id, title, size, method,
|
|
20
|
+
# thumbnail_url) that powers EmpiarCatalog search/gallery.
|
|
21
|
+
CATALOG_URL = os.environ.get(
|
|
22
|
+
"SCIGANTIC_EMPIAR_CATALOG",
|
|
23
|
+
"https://scigantic-empiar-catalog.s3.amazonaws.com/catalog.json",
|
|
24
|
+
)
|
|
25
|
+
|
|
26
|
+
# S3 fast-workspace: full-speed mirrored copies of chosen entries.
|
|
27
|
+
FAST_BUCKET = os.environ.get("SCIGANTIC_EMPIAR_FAST_BUCKET", "scigantic-empiar-fast")
|
|
28
|
+
FAST_MNT = os.environ.get("SCIGANTIC_EMPIAR_FAST_MNT", "/mnt/empiar-fast")
|
|
29
|
+
|
|
30
|
+
# Descriptive UA (contact) is the polite convention for automated EBI/NCBI
|
|
31
|
+
# access and avoids some abuse filters.
|
|
32
|
+
USER_AGENT = "scigantic-empiar/0.1 (+https://github.com/scigantic/scigantic-empiar; mailto:support@scigantic.com)"
|
|
33
|
+
|
|
34
|
+
session = requests.Session()
|
|
35
|
+
session.headers.update({"User-Agent": USER_AGENT})
|
|
@@ -0,0 +1,119 @@
|
|
|
1
|
+
"""MRC/MRCS parsing, file discovery, and NumPy array readers (no plotting)."""
|
|
2
|
+
from __future__ import annotations
|
|
3
|
+
import os
|
|
4
|
+
import struct
|
|
5
|
+
|
|
6
|
+
import numpy as np
|
|
7
|
+
|
|
8
|
+
from .reader import entry_url, fast_path, list_files, pread
|
|
9
|
+
|
|
10
|
+
MRC_EXT = (".mrcs", ".mrc", ".st", ".ali", ".rec", ".mrc.bz2")
|
|
11
|
+
# MRC mode -> numpy dtype (the common cryo-EM subset).
|
|
12
|
+
MODE_DTYPE = {0: np.int8, 1: np.int16, 2: np.float32, 6: np.uint16, 12: np.float16}
|
|
13
|
+
|
|
14
|
+
|
|
15
|
+
def parse_mrc_header(b: bytes) -> dict:
|
|
16
|
+
"""Parse a 1024-byte MRC header. Returns dims, dtype, extended-header size,
|
|
17
|
+
pixel size (Angstrom), and the byte offset where image data begins."""
|
|
18
|
+
nx, ny, nz, mode = struct.unpack("<4i", b[:16])
|
|
19
|
+
nsymbt = struct.unpack("<i", b[92:96])[0]
|
|
20
|
+
mx, my, mz = struct.unpack("<3i", b[28:40]) # grid
|
|
21
|
+
xlen, ylen, zlen = struct.unpack("<3f", b[40:52]) # cell (A)
|
|
22
|
+
apix = (xlen / mx) if mx else 0.0
|
|
23
|
+
dt = np.dtype(MODE_DTYPE.get(mode, np.float32))
|
|
24
|
+
return dict(
|
|
25
|
+
nx=nx, ny=ny, nz=nz, mode=mode, nsymbt=nsymbt, dtype=dt,
|
|
26
|
+
apix=round(apix, 3), frame_bytes=nx * ny * dt.itemsize,
|
|
27
|
+
data0=1024 + nsymbt,
|
|
28
|
+
)
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
def find_mrc(entry_id, subdir="data", depth=2):
|
|
32
|
+
"""First MRC-like file under an entry — checks ``data/`` then up to two
|
|
33
|
+
subdir levels (tomo tilt-series / particle stacks / per-session dirs nest
|
|
34
|
+
their MRCs a couple levels down). Returns a subdir-relative path, or None."""
|
|
35
|
+
entries = list_files(entry_id, subdir)
|
|
36
|
+
hits = [f for f in entries if f.lower().endswith(MRC_EXT)]
|
|
37
|
+
if hits:
|
|
38
|
+
return f"{subdir}/{hits[0]}"
|
|
39
|
+
if depth > 0:
|
|
40
|
+
subs = [f.rstrip("/") for f in entries if "." not in f.rstrip("/")] # dirs
|
|
41
|
+
for s in subs[:8]:
|
|
42
|
+
r = find_mrc(entry_id, f"{subdir}/{s}", depth - 1)
|
|
43
|
+
if r:
|
|
44
|
+
return r
|
|
45
|
+
return None
|
|
46
|
+
|
|
47
|
+
|
|
48
|
+
def read_mrc(entry_id, filename=None, subdir="data"):
|
|
49
|
+
"""Resolve an entry+file to ``(url, filename, header)``, reading only the
|
|
50
|
+
header. ``filename`` may be a path relative to the entry root; if omitted,
|
|
51
|
+
the first MRC found (recursing subdirs) is used."""
|
|
52
|
+
if filename is None:
|
|
53
|
+
rel = find_mrc(entry_id, subdir)
|
|
54
|
+
if not rel:
|
|
55
|
+
raise FileNotFoundError(f"no MRC files under EMPIAR-{entry_id}/{subdir}")
|
|
56
|
+
parts = rel.split("/")
|
|
57
|
+
subdir, filename = "/".join(parts[:-1]), parts[-1]
|
|
58
|
+
fp = fast_path(entry_id)
|
|
59
|
+
url = os.path.join(fp, subdir, filename) if fp else entry_url(entry_id, subdir, filename)
|
|
60
|
+
return url, filename, parse_mrc_header(pread(url, 0, 1024, 1))
|
|
61
|
+
|
|
62
|
+
|
|
63
|
+
def read_mrc_frame(entry_id, filename=None, frame=0, nthreads=8):
|
|
64
|
+
"""One 2D frame/slice as a float32 array (+ header)."""
|
|
65
|
+
url, fn, h = read_mrc(entry_id, filename)
|
|
66
|
+
off = h["data0"] + int(frame) * h["frame_bytes"]
|
|
67
|
+
buf = pread(url, off, h["frame_bytes"], nthreads)
|
|
68
|
+
arr = np.frombuffer(buf, dtype=h["dtype"]).astype(np.float32).reshape(h["ny"], h["nx"])
|
|
69
|
+
h["file"] = fn
|
|
70
|
+
return arr, h
|
|
71
|
+
|
|
72
|
+
|
|
73
|
+
def read_mrc_average(entry_id, filename=None, n_frames=4, nthreads=8):
|
|
74
|
+
"""Average the first ``n_frames`` — a poor-man's motion-corrected image
|
|
75
|
+
(much cleaner than one raw frame)."""
|
|
76
|
+
url, fn, h = read_mrc(entry_id, filename)
|
|
77
|
+
n = max(1, min(n_frames, h["nz"] or 1))
|
|
78
|
+
buf = pread(url, h["data0"], n * h["frame_bytes"], nthreads)
|
|
79
|
+
stack = np.frombuffer(buf, dtype=h["dtype"]).astype(np.float32).reshape(n, h["ny"], h["nx"])
|
|
80
|
+
h["file"] = fn
|
|
81
|
+
h["n_averaged"] = n
|
|
82
|
+
return stack.mean(0), h
|
|
83
|
+
|
|
84
|
+
|
|
85
|
+
def thumbnail(entry_id, filename=None, size=320, nthreads=8):
|
|
86
|
+
"""A small uint8 preview (central strip of the first MRC), reading only ~a
|
|
87
|
+
few MB — used to build catalogs. Returns (uint8 array, header)."""
|
|
88
|
+
url, fn, h = read_mrc(entry_id, filename)
|
|
89
|
+
rows = min(h["ny"], max(size, 256))
|
|
90
|
+
row0 = max(0, (h["ny"] - rows) // 2)
|
|
91
|
+
off = h["data0"] + row0 * h["nx"] * h["dtype"].itemsize
|
|
92
|
+
buf = pread(url, off, rows * h["nx"] * h["dtype"].itemsize, nthreads)
|
|
93
|
+
band = np.frombuffer(buf, dtype=h["dtype"]).astype(np.float32).reshape(rows, h["nx"])
|
|
94
|
+
f = max(1, max(band.shape) // size)
|
|
95
|
+
small = band[::f, ::f]
|
|
96
|
+
lo, hi = np.percentile(small, [2, 98])
|
|
97
|
+
small = np.clip((small - lo) / (hi - lo + 1e-9), 0, 1)
|
|
98
|
+
h["file"] = fn
|
|
99
|
+
return (small * 255).astype(np.uint8), h
|
|
100
|
+
|
|
101
|
+
|
|
102
|
+
def _hann2d(shape):
|
|
103
|
+
return np.outer(np.hanning(shape[0]), np.hanning(shape[1]))
|
|
104
|
+
|
|
105
|
+
|
|
106
|
+
def power_spectrum(arr, bin_to=1024):
|
|
107
|
+
"""Windowed, log-scaled, [0,1]-normalised power spectrum (Thon rings)."""
|
|
108
|
+
f = max(1, min(arr.shape) // bin_to)
|
|
109
|
+
a = arr[::f, ::f].astype(np.float32)
|
|
110
|
+
a = (a - a.mean()) / (a.std() + 1e-6)
|
|
111
|
+
a = a * _hann2d(a.shape)
|
|
112
|
+
ps = np.log1p(np.abs(np.fft.fftshift(np.fft.fft2(a))))
|
|
113
|
+
lo, hi = np.percentile(ps, [1, 99.5])
|
|
114
|
+
return np.clip((ps - lo) / (hi - lo + 1e-9), 0, 1)
|
|
115
|
+
|
|
116
|
+
|
|
117
|
+
def downsample(a, target=900):
|
|
118
|
+
f = max(1, min(a.shape) // target)
|
|
119
|
+
return a[::f, ::f]
|
|
@@ -0,0 +1,74 @@
|
|
|
1
|
+
"""The fast lane over EBI: parallel HTTP range reads, plus path/URL helpers.
|
|
2
|
+
|
|
3
|
+
EBI serves ~1.5 MB/s per connection and throttles past ~8, so ``pread`` splits a
|
|
4
|
+
read into up to 8 concurrent range requests, which aggregates to ~5-10 MB/s.
|
|
5
|
+
"""
|
|
6
|
+
from __future__ import annotations
|
|
7
|
+
import math
|
|
8
|
+
import os
|
|
9
|
+
import re
|
|
10
|
+
from concurrent.futures import ThreadPoolExecutor
|
|
11
|
+
|
|
12
|
+
from .config import EBI, FAST_MNT, MOUNT, session
|
|
13
|
+
|
|
14
|
+
|
|
15
|
+
def entry_url(entry_id, *parts) -> str:
|
|
16
|
+
"""EBI HTTPS URL for an entry (optionally a file/dir under it)."""
|
|
17
|
+
eid = str(entry_id).replace("EMPIAR-", "").lstrip("0") or "0"
|
|
18
|
+
tail = "/".join(str(p).strip("/") for p in parts if p is not None)
|
|
19
|
+
return f"{EBI}/{eid}/" + (tail if tail else "")
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
def fast_path(entry_id):
|
|
23
|
+
"""Local path to a mirrored (fast) copy of an entry, or None if not mirrored."""
|
|
24
|
+
eid = str(entry_id).replace("EMPIAR-", "")
|
|
25
|
+
p = os.path.join(FAST_MNT, eid)
|
|
26
|
+
return p if os.path.isdir(p) else None
|
|
27
|
+
|
|
28
|
+
|
|
29
|
+
def _get_range(url, start, end, retries=2) -> bytes:
|
|
30
|
+
last = None
|
|
31
|
+
for attempt in range(retries + 1):
|
|
32
|
+
try:
|
|
33
|
+
r = session.get(url, headers={"Range": f"bytes={start}-{end}"}, timeout=60)
|
|
34
|
+
r.raise_for_status()
|
|
35
|
+
return r.content
|
|
36
|
+
except Exception as exc: # noqa: BLE001 - retry any transient error
|
|
37
|
+
last = exc
|
|
38
|
+
raise last # type: ignore[misc]
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
def pread(url, offset, length, nthreads=8) -> bytes:
|
|
42
|
+
"""Read ``length`` bytes at ``offset`` from ``url`` via up to ``nthreads``
|
|
43
|
+
parallel range GETs. A local/``file://`` path is read directly (used when an
|
|
44
|
+
entry is mirrored to the fast workspace)."""
|
|
45
|
+
if url.startswith("/") or url.startswith("file:"):
|
|
46
|
+
with open(url.replace("file://", ""), "rb") as fh:
|
|
47
|
+
fh.seek(offset)
|
|
48
|
+
return fh.read(length)
|
|
49
|
+
if length <= 0:
|
|
50
|
+
return b""
|
|
51
|
+
n = max(1, min(nthreads, math.ceil(length / (1 << 20))))
|
|
52
|
+
step = math.ceil(length / n)
|
|
53
|
+
spans, o = [], offset
|
|
54
|
+
while o < offset + length:
|
|
55
|
+
end = min(o + step, offset + length) - 1
|
|
56
|
+
spans.append((o, end))
|
|
57
|
+
o = end + 1
|
|
58
|
+
if len(spans) == 1:
|
|
59
|
+
return _get_range(url, *spans[0])
|
|
60
|
+
with ThreadPoolExecutor(max_workers=len(spans)) as ex:
|
|
61
|
+
parts = list(ex.map(lambda s: _get_range(url, s[0], s[1]), spans))
|
|
62
|
+
return b"".join(parts)
|
|
63
|
+
|
|
64
|
+
|
|
65
|
+
def list_files(entry_id, subdir="data"):
|
|
66
|
+
"""Filenames under an entry's subdir — from the mount if present, else by
|
|
67
|
+
parsing EBI's autoindex HTML."""
|
|
68
|
+
eid = str(entry_id).replace("EMPIAR-", "")
|
|
69
|
+
local = os.path.join(MOUNT, eid, subdir)
|
|
70
|
+
if os.path.isdir(local):
|
|
71
|
+
return sorted(os.listdir(local))
|
|
72
|
+
html = session.get(entry_url(eid, subdir) + "/", timeout=30).text
|
|
73
|
+
out = [m for m in re.findall(r'href="([^"?/][^"]*)"', html) if not m.startswith("..")]
|
|
74
|
+
return sorted(set(out))
|
|
@@ -0,0 +1,58 @@
|
|
|
1
|
+
"""Inline visualization — micrograph/slice + power spectrum (needs matplotlib).
|
|
2
|
+
|
|
3
|
+
Named ``render`` (not ``preview``) to avoid colliding with the ``preview()``
|
|
4
|
+
function it exports, which the package surfaces as ``scigantic_empiar.preview``.
|
|
5
|
+
"""
|
|
6
|
+
from __future__ import annotations
|
|
7
|
+
|
|
8
|
+
import numpy as np
|
|
9
|
+
|
|
10
|
+
from .catalog import EmpiarClient
|
|
11
|
+
from .mrc import downsample, power_spectrum, read_mrc_average, read_mrc_frame
|
|
12
|
+
|
|
13
|
+
|
|
14
|
+
def preview(entry_id, filename=None, average=False, n_frames=4, cmap="gray",
|
|
15
|
+
apix=None, nthreads=8, figsize=(11, 5.3)):
|
|
16
|
+
"""Render a micrograph (or tomogram slice) + its power spectrum inline.
|
|
17
|
+
|
|
18
|
+
Reads only what it needs over parallel range requests — a single frame is a
|
|
19
|
+
few seconds even on a multi-hundred-GB entry, nothing downloaded. Never
|
|
20
|
+
raises: on any read error it prints the entry's metadata + how to drill in.
|
|
21
|
+
Pass ``average=True`` for a cleaner (heavier) mean-of-frames image.
|
|
22
|
+
"""
|
|
23
|
+
import matplotlib.pyplot as plt
|
|
24
|
+
|
|
25
|
+
eid = str(entry_id).replace("EMPIAR-", "")
|
|
26
|
+
try:
|
|
27
|
+
if average:
|
|
28
|
+
img, h = read_mrc_average(entry_id, filename, n_frames, nthreads)
|
|
29
|
+
sub = f"mean of {h.get('n_averaged', 1)} frames"
|
|
30
|
+
else:
|
|
31
|
+
img, h = read_mrc_frame(entry_id, filename, 0, nthreads)
|
|
32
|
+
sub = "frame 0"
|
|
33
|
+
except Exception as e: # noqa: BLE001 - never crash the caller/notebook
|
|
34
|
+
try:
|
|
35
|
+
s = EmpiarClient().summary(eid)
|
|
36
|
+
print(f"EMPIAR-{eid}: {s.get('title', '')} ({s.get('size', '?')}, {s.get('format', '?')})")
|
|
37
|
+
except Exception:
|
|
38
|
+
pass
|
|
39
|
+
print(f"Couldn't auto-locate an MRC to preview ({e}).")
|
|
40
|
+
print(f"Explore the layout: list_files({eid}) then list_files({eid}, 'data/<subdir>')")
|
|
41
|
+
print(f"Preview a specific file: preview({eid}, filename='<subdir>/<file>.mrc')")
|
|
42
|
+
return None
|
|
43
|
+
|
|
44
|
+
if not apix:
|
|
45
|
+
apix = h["apix"] if h["apix"] else None
|
|
46
|
+
px = f", {apix} Å/px" if apix else ""
|
|
47
|
+
disp = downsample(img, 900)
|
|
48
|
+
lo, hi = np.percentile(disp, [2, 98])
|
|
49
|
+
|
|
50
|
+
fig, ax = plt.subplots(1, 2, figsize=figsize)
|
|
51
|
+
ax[0].imshow(np.clip(disp, lo, hi), cmap=cmap)
|
|
52
|
+
ax[0].set_title(f"EMPIAR-{eid} · {h['file']}\n{h['nx']}×{h['ny']}{px} · {sub}", fontsize=9)
|
|
53
|
+
ax[0].axis("off")
|
|
54
|
+
ax[1].imshow(power_spectrum(img), cmap="magma")
|
|
55
|
+
ax[1].set_title("power spectrum (FFT) — Thon rings", fontsize=9)
|
|
56
|
+
ax[1].axis("off")
|
|
57
|
+
fig.tight_layout()
|
|
58
|
+
return fig
|
|
@@ -0,0 +1,39 @@
|
|
|
1
|
+
"""Tier 2: mirror a whole entry to fast storage for heavy reprocessing.
|
|
2
|
+
|
|
3
|
+
Streaming a full multi-hundred-GB entry from EBI at ~1.5 MB/s isn't practical,
|
|
4
|
+
so for RELION/EMAN2-style work you copy it once (via ``rclone``, which does its
|
|
5
|
+
own multi-connection transfer) to an S3 fast bucket, then read at local speed.
|
|
6
|
+
"""
|
|
7
|
+
from __future__ import annotations
|
|
8
|
+
import shutil
|
|
9
|
+
import subprocess
|
|
10
|
+
|
|
11
|
+
from .config import EBI, FAST_BUCKET, FAST_MNT
|
|
12
|
+
from .reader import entry_url, fast_path
|
|
13
|
+
|
|
14
|
+
|
|
15
|
+
def add_to_fast_workspace(entry_id, bucket=FAST_BUCKET, dry_run=False):
|
|
16
|
+
"""Mirror EMPIAR-<id> from EBI into the S3 fast bucket with ``rclone``.
|
|
17
|
+
|
|
18
|
+
Returns the ``s3://`` destination. If the entry is already visible under the
|
|
19
|
+
local fast mount, returns its path without recopying. ``dry_run=True`` returns
|
|
20
|
+
the command it would run (a list) instead of executing.
|
|
21
|
+
"""
|
|
22
|
+
eid = str(entry_id).replace("EMPIAR-", "")
|
|
23
|
+
existing = fast_path(eid)
|
|
24
|
+
if existing:
|
|
25
|
+
return existing
|
|
26
|
+
|
|
27
|
+
src = entry_url(eid).replace("https://", ":http:") # rclone :http: backend
|
|
28
|
+
dst = f":s3:{bucket}/{eid}"
|
|
29
|
+
cmd = ["rclone", "copy", "--http-url", EBI.rsplit("/", 1)[0],
|
|
30
|
+
"--transfers", "8", "--checkers", "8", src, dst]
|
|
31
|
+
if dry_run:
|
|
32
|
+
return cmd
|
|
33
|
+
if shutil.which("rclone") is None:
|
|
34
|
+
raise RuntimeError(
|
|
35
|
+
"rclone not found. Inside a Scigantic notebook this runs server-side; "
|
|
36
|
+
"standalone, install rclone and configure an :s3: remote."
|
|
37
|
+
)
|
|
38
|
+
subprocess.run(cmd, check=True)
|
|
39
|
+
return f"s3://{bucket}/{eid} (mount at {FAST_MNT}/{eid} to read locally)"
|
|
@@ -0,0 +1,85 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: scigantic-empiar
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Explore the EMPIAR cryo-EM archive from Python — stream any of ~3,000 datasets (8.9 PiB) over parallel HTTP range reads, nothing downloaded.
|
|
5
|
+
Author: Scigantic
|
|
6
|
+
License: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/scigantic/scigantic-empiar
|
|
8
|
+
Project-URL: EMPIAR, https://www.ebi.ac.uk/empiar/
|
|
9
|
+
Keywords: cryo-em,cryo-et,empiar,mrc,structural-biology,microscopy
|
|
10
|
+
Requires-Python: >=3.9
|
|
11
|
+
Description-Content-Type: text/markdown
|
|
12
|
+
License-File: LICENSE
|
|
13
|
+
Requires-Dist: numpy
|
|
14
|
+
Requires-Dist: requests
|
|
15
|
+
Provides-Extra: viz
|
|
16
|
+
Requires-Dist: matplotlib; extra == "viz"
|
|
17
|
+
Requires-Dist: pandas; extra == "viz"
|
|
18
|
+
Requires-Dist: pillow; extra == "viz"
|
|
19
|
+
Requires-Dist: ipython; extra == "viz"
|
|
20
|
+
Provides-Extra: dev
|
|
21
|
+
Requires-Dist: pytest; extra == "dev"
|
|
22
|
+
Requires-Dist: matplotlib; extra == "dev"
|
|
23
|
+
Requires-Dist: pandas; extra == "dev"
|
|
24
|
+
Dynamic: license-file
|
|
25
|
+
|
|
26
|
+
# scigantic_empiar
|
|
27
|
+
|
|
28
|
+
Explore [EMPIAR](https://www.ebi.ac.uk/empiar/) — EMBL-EBI's public archive of **raw cryo-EM / cryo-ET image data** (~3,000 datasets, ~8.9 PiB) — from Python, **without downloading anything**.
|
|
29
|
+
|
|
30
|
+
EMPIAR is served over EBI's public HTTPS at ~1.5 MB/s per connection. `scigantic_empiar` parallelises HTTP **range** reads (8-way ≈ 5–10 MB/s) so you can pull a single frame from a many-GB entry in seconds, decode the MRC, and render the micrograph + its power spectrum — nothing is copied to disk.
|
|
31
|
+
|
|
32
|
+
```python
|
|
33
|
+
import scigantic_empiar as se
|
|
34
|
+
|
|
35
|
+
se.preview(10406) # render the micrograph below, in seconds
|
|
36
|
+
se.EmpiarClient().summary(10406) # title, pixel size, method, DOI, EMDB/PDB cross-refs
|
|
37
|
+
se.EmpiarCatalog().search("ribosome") # search the whole archive by metadata (instant)
|
|
38
|
+
```
|
|
39
|
+
|
|
40
|
+

|
|
41
|
+
|
|
42
|
+
*One frame of EMPIAR-10406 (a 70S-ribosome dataset) pulled straight from EBI over parallel range reads — the carbon-foil edge, ice, and particles are visible at left; the FFT is at right. Nothing was downloaded to disk.*
|
|
43
|
+
|
|
44
|
+
## Install
|
|
45
|
+
|
|
46
|
+
```bash
|
|
47
|
+
pip install "scigantic-empiar[viz] @ git+https://github.com/scigantic/scigantic-empiar"
|
|
48
|
+
```
|
|
49
|
+
|
|
50
|
+
Core (`numpy`, `requests`) is enough for the readers; `[viz]` adds `matplotlib` / `pandas` / `pillow` for `preview()` and the catalog gallery.
|
|
51
|
+
|
|
52
|
+
## What it does
|
|
53
|
+
|
|
54
|
+
| | |
|
|
55
|
+
|---|---|
|
|
56
|
+
| `preview(id)` | micrograph / tomogram-slice + power spectrum, rendered from a lazy parallel-range read |
|
|
57
|
+
| `read_mrc_frame(id)` / `read_mrc_average(id)` | one frame / a mean of frames as a NumPy array + header |
|
|
58
|
+
| `thumbnail(id)` | small preview array (a few-MB central-strip read) — used to build catalogs |
|
|
59
|
+
| `find_mrc(id)` | resolve an entry's first MRC, recursing the (often nested) `data/` layout |
|
|
60
|
+
| `pread(url, off, len)` | the 8-way parallel HTTP range reader under it all |
|
|
61
|
+
| `EmpiarClient` | per-entry metadata from EMPIAR's REST API (cached) |
|
|
62
|
+
| `EmpiarCatalog` | search + a visual thumbnail gallery across all entries (from a prebuilt index) |
|
|
63
|
+
| `add_to_fast_workspace(id)` | mirror an entry to S3 for full-speed reprocessing (RELION/EMAN2) |
|
|
64
|
+
|
|
65
|
+
## Why parallel range reads
|
|
66
|
+
|
|
67
|
+
EBI throttles per connection (~1.5 MB/s) and past ~8 concurrent connections. `pread` splits a read into ~8 concurrent range requests, which aggregates to ~5–10 MB/s — enough to *look* at any entry interactively. For heavy reprocessing of a whole multi-hundred-GB dataset, mirror it to fast storage first (`add_to_fast_workspace`); streaming a full entry at 1.5 MB/s isn't practical.
|
|
68
|
+
|
|
69
|
+
## Existing work
|
|
70
|
+
|
|
71
|
+
The job splits in two: parse MRC, and read bytes from a remote file. Both have existing libraries; neither covers the specific case here.
|
|
72
|
+
|
|
73
|
+
- [`mrcfile`](https://github.com/ccpem/mrcfile) (CCP-EM) is the standard MRC reader. Its lazy mode is a numpy `memmap`, which needs a local filesystem path — it does not issue HTTP range requests. `scigantic_empiar` parses the 1024-byte header directly (`parse_mrc_header`) to seek to one frame of a remote file without a local copy.
|
|
74
|
+
- [`fsspec`](https://filesystem-spec.readthedocs.io/) `HTTPFileSystem` turns byte reads into HTTP range requests and can fetch many ranges concurrently ([`cat_ranges`](https://filesystem-spec.readthedocs.io/en/latest/async.html)). `pread` is a small equivalent, kept dependency-free and tuned to EBI's ~8-connection throttle; moving the transport onto `fsspec` is a reasonable later change.
|
|
75
|
+
- [`copick`](https://github.com/copick/copick) (CZI, [Protein Science 2026](https://onlinelibrary.wiley.com/doi/10.1002/pro.70578)) is the closest cryo-EM analog: an fsspec-backed, server-less dataset API with lazy reads. It assumes data stored as OME-Zarr (chunked, multiscale). EMPIAR entries are raw MRC/TIFF, so copick needs a per-entry zarr conversion first — the conversion that MRC's flat layout lets `scigantic_empiar` skip.
|
|
76
|
+
|
|
77
|
+
## Notes
|
|
78
|
+
|
|
79
|
+
- MRC/MRCS (movies, micrographs, tomograms, particle stacks) and some TIFF. Files often nest a couple subdir levels down; `find_mrc` handles that.
|
|
80
|
+
- Entry ids are opaque numbers — discover datasets by **metadata** (`EmpiarCatalog.search`, or the EMPIAR website), not by listing the tree.
|
|
81
|
+
- Inside a [Scigantic](https://scigantic.com) cryo-EM notebook this is preinstalled and the archive is also FUSE-mounted at `$SCIGANTIC_MOUNT_PATH`; standalone, it streams straight from EBI.
|
|
82
|
+
|
|
83
|
+
## License
|
|
84
|
+
|
|
85
|
+
MIT.
|
|
@@ -0,0 +1,19 @@
|
|
|
1
|
+
LICENSE
|
|
2
|
+
README.md
|
|
3
|
+
pyproject.toml
|
|
4
|
+
scigantic_empiar/__init__.py
|
|
5
|
+
scigantic_empiar/catalog.py
|
|
6
|
+
scigantic_empiar/config.py
|
|
7
|
+
scigantic_empiar/mrc.py
|
|
8
|
+
scigantic_empiar/reader.py
|
|
9
|
+
scigantic_empiar/render.py
|
|
10
|
+
scigantic_empiar/workspace.py
|
|
11
|
+
scigantic_empiar.egg-info/PKG-INFO
|
|
12
|
+
scigantic_empiar.egg-info/SOURCES.txt
|
|
13
|
+
scigantic_empiar.egg-info/dependency_links.txt
|
|
14
|
+
scigantic_empiar.egg-info/requires.txt
|
|
15
|
+
scigantic_empiar.egg-info/top_level.txt
|
|
16
|
+
tests/test_catalog.py
|
|
17
|
+
tests/test_mrc.py
|
|
18
|
+
tests/test_preview.py
|
|
19
|
+
tests/test_reader.py
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
scigantic_empiar
|
|
@@ -0,0 +1,49 @@
|
|
|
1
|
+
"""catalog.py — metadata client + searchable catalog (no network)."""
|
|
2
|
+
import pandas as pd
|
|
3
|
+
|
|
4
|
+
import scigantic_empiar as se
|
|
5
|
+
from scigantic_empiar.catalog import EmpiarClient
|
|
6
|
+
|
|
7
|
+
|
|
8
|
+
def _catalog():
|
|
9
|
+
cat = se.EmpiarCatalog()
|
|
10
|
+
cat._df = pd.DataFrame([
|
|
11
|
+
{"id": "10002", "title": "80S ribosome", "method": "SPA", "size_gb": 260},
|
|
12
|
+
{"id": "10406", "title": "HIV-1 tomogram", "method": "tomography", "size_gb": 40},
|
|
13
|
+
{"id": "11000", "title": "ribosome subunit", "method": "SPA", "size_gb": 5},
|
|
14
|
+
])
|
|
15
|
+
return cat
|
|
16
|
+
|
|
17
|
+
|
|
18
|
+
def test_search_by_title():
|
|
19
|
+
hits = _catalog().search(query="ribosome")
|
|
20
|
+
assert set(hits["id"]) == {"10002", "11000"}
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def test_search_by_method():
|
|
24
|
+
hits = _catalog().search(method="tomography")
|
|
25
|
+
assert list(hits["id"]) == ["10406"]
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
def test_search_by_size():
|
|
29
|
+
hits = _catalog().search(max_gb=50)
|
|
30
|
+
assert set(hits["id"]) == {"10406", "11000"} # excludes the 260 GB entry
|
|
31
|
+
|
|
32
|
+
|
|
33
|
+
def test_search_limit():
|
|
34
|
+
assert len(_catalog().search(limit=1)) == 1
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
def test_client_summary_shape(monkeypatch):
|
|
38
|
+
fake = {
|
|
39
|
+
"title": "80S ribosome",
|
|
40
|
+
"dataset_size": "260 GB",
|
|
41
|
+
"release_date": "2016-01-01",
|
|
42
|
+
"entry_doi": "10.6019/EMPIAR-10002",
|
|
43
|
+
"imagesets": [{"data_format": "MRC", "category": "micrographs"}],
|
|
44
|
+
}
|
|
45
|
+
monkeypatch.setattr(EmpiarClient, "entry", lambda self, eid: fake)
|
|
46
|
+
s = EmpiarClient().summary("EMPIAR-10002")
|
|
47
|
+
assert s["id"] == "10002" # prefix stripped
|
|
48
|
+
assert s["format"] == "MRC"
|
|
49
|
+
assert s["title"] == "80S ribosome"
|
|
@@ -0,0 +1,64 @@
|
|
|
1
|
+
"""mrc.py — header parsing, file discovery, and NumPy readers."""
|
|
2
|
+
import numpy as np
|
|
3
|
+
|
|
4
|
+
from conftest import make_mrc_header
|
|
5
|
+
|
|
6
|
+
import scigantic_empiar as se
|
|
7
|
+
from scigantic_empiar import mrc
|
|
8
|
+
|
|
9
|
+
|
|
10
|
+
def test_parse_mrc_header():
|
|
11
|
+
h = se.parse_mrc_header(make_mrc_header(nx=4, ny=3, nz=5, mode=2, mx=200, xlen=210.0))
|
|
12
|
+
assert (h["nx"], h["ny"], h["nz"], h["mode"]) == (4, 3, 5, 2)
|
|
13
|
+
assert h["dtype"] == np.float32
|
|
14
|
+
assert h["apix"] == 1.05
|
|
15
|
+
assert h["frame_bytes"] == 4 * 3 * 4 # nx*ny*itemsize
|
|
16
|
+
assert h["data0"] == 1024 # nsymbt == 0
|
|
17
|
+
|
|
18
|
+
|
|
19
|
+
def test_parse_mrc_header_extended_offset():
|
|
20
|
+
h = se.parse_mrc_header(make_mrc_header(mode=1, nsymbt=512))
|
|
21
|
+
assert h["dtype"] == np.int16 # mode 1
|
|
22
|
+
assert h["data0"] == 1024 + 512 # extended header shifts data start
|
|
23
|
+
|
|
24
|
+
|
|
25
|
+
def test_find_mrc_recurses_subdirs(monkeypatch):
|
|
26
|
+
listings = {
|
|
27
|
+
"data": ["notes.txt", "micrographs/"], # no MRC at top level
|
|
28
|
+
"data/micrographs": ["log.txt", "stack_0001.mrc"], # found one level down
|
|
29
|
+
}
|
|
30
|
+
monkeypatch.setattr(mrc, "list_files", lambda eid, subdir="data": listings[subdir])
|
|
31
|
+
assert se.find_mrc(10406) == "data/micrographs/stack_0001.mrc"
|
|
32
|
+
|
|
33
|
+
|
|
34
|
+
def test_find_mrc_returns_none_when_absent(monkeypatch):
|
|
35
|
+
monkeypatch.setattr(mrc, "list_files", lambda eid, subdir="data": ["readme.txt"])
|
|
36
|
+
assert se.find_mrc(1) is None
|
|
37
|
+
|
|
38
|
+
|
|
39
|
+
def test_read_mrc_frame_shapes_and_values(monkeypatch):
|
|
40
|
+
header = make_mrc_header(nx=4, ny=3, nz=5, mode=2)
|
|
41
|
+
|
|
42
|
+
def fake_pread(url, off, length, nthreads=8):
|
|
43
|
+
if length == 1024:
|
|
44
|
+
return header # header read
|
|
45
|
+
return np.arange(length // 4, dtype=np.float32).tobytes() # frame read
|
|
46
|
+
|
|
47
|
+
monkeypatch.setattr(mrc, "pread", fake_pread)
|
|
48
|
+
monkeypatch.setattr(mrc, "fast_path", lambda eid: None)
|
|
49
|
+
|
|
50
|
+
arr, h = se.read_mrc_frame(10002, filename="m.mrc", frame=0)
|
|
51
|
+
assert arr.shape == (3, 4) # (ny, nx)
|
|
52
|
+
assert arr.dtype == np.float32
|
|
53
|
+
assert np.allclose(arr.ravel(), np.arange(12))
|
|
54
|
+
assert h["file"] == "m.mrc"
|
|
55
|
+
|
|
56
|
+
|
|
57
|
+
def test_power_spectrum_and_downsample():
|
|
58
|
+
g = np.outer(np.sin(np.linspace(0, 12, 128)), np.sin(np.linspace(0, 9, 128)))
|
|
59
|
+
ps = se.power_spectrum(g.astype(np.float32))
|
|
60
|
+
assert ps.shape == (128, 128)
|
|
61
|
+
assert ps.min() >= 0.0 and ps.max() <= 1.0 # normalised to [0,1]
|
|
62
|
+
|
|
63
|
+
ds = mrc.downsample(g, target=64)
|
|
64
|
+
assert ds.shape == (64, 64) # stride-2 decimation
|
|
@@ -0,0 +1,35 @@
|
|
|
1
|
+
"""render.py — rendering, and the promise that preview() never raises."""
|
|
2
|
+
import matplotlib
|
|
3
|
+
|
|
4
|
+
matplotlib.use("Agg") # headless
|
|
5
|
+
import numpy as np
|
|
6
|
+
|
|
7
|
+
import scigantic_empiar as se
|
|
8
|
+
from scigantic_empiar import render
|
|
9
|
+
|
|
10
|
+
|
|
11
|
+
def test_preview_renders_two_panels(monkeypatch):
|
|
12
|
+
img = np.random.default_rng(0).standard_normal((256, 256)).astype(np.float32)
|
|
13
|
+
header = {"nx": 256, "ny": 256, "apix": 1.05, "file": "m.mrc"}
|
|
14
|
+
monkeypatch.setattr(render, "read_mrc_frame", lambda *a, **k: (img, header))
|
|
15
|
+
|
|
16
|
+
fig = se.preview(10002, filename="m.mrc")
|
|
17
|
+
assert fig is not None
|
|
18
|
+
assert len(fig.axes) == 2 # micrograph + power spectrum
|
|
19
|
+
|
|
20
|
+
|
|
21
|
+
def test_preview_never_raises_on_read_error(monkeypatch, capsys):
|
|
22
|
+
def boom(*a, **k):
|
|
23
|
+
raise OSError("404 from EBI")
|
|
24
|
+
|
|
25
|
+
monkeypatch.setattr(render, "read_mrc_frame", boom)
|
|
26
|
+
# metadata lookup also unavailable -> still must not raise
|
|
27
|
+
monkeypatch.setattr(
|
|
28
|
+
"scigantic_empiar.catalog.EmpiarClient.summary",
|
|
29
|
+
lambda self, eid: (_ for _ in ()).throw(RuntimeError("no api")),
|
|
30
|
+
)
|
|
31
|
+
|
|
32
|
+
result = se.preview(99999)
|
|
33
|
+
assert result is None # graceful, returns None
|
|
34
|
+
out = capsys.readouterr().out
|
|
35
|
+
assert "list_files" in out # prints how to drill in
|
|
@@ -0,0 +1,68 @@
|
|
|
1
|
+
"""reader.py — URL/path helpers and the parallel range reader."""
|
|
2
|
+
import numpy as np
|
|
3
|
+
import pytest
|
|
4
|
+
|
|
5
|
+
from conftest import BUFFER
|
|
6
|
+
|
|
7
|
+
import scigantic_empiar as se
|
|
8
|
+
from scigantic_empiar import reader
|
|
9
|
+
|
|
10
|
+
|
|
11
|
+
def test_entry_url_normalises_ids():
|
|
12
|
+
assert reader.entry_url(10002).endswith("/10002/")
|
|
13
|
+
# EMPIAR- prefix stripped, leading zeros trimmed
|
|
14
|
+
assert reader.entry_url("EMPIAR-00123").endswith("/123/")
|
|
15
|
+
# extra parts joined, no trailing slash
|
|
16
|
+
assert reader.entry_url(10002, "data", "m.mrc").endswith("/10002/data/m.mrc")
|
|
17
|
+
|
|
18
|
+
|
|
19
|
+
def test_fast_path(tmp_path, monkeypatch):
|
|
20
|
+
monkeypatch.setattr(reader, "FAST_MNT", str(tmp_path))
|
|
21
|
+
(tmp_path / "10002").mkdir()
|
|
22
|
+
assert reader.fast_path("10002") == str(tmp_path / "10002")
|
|
23
|
+
assert reader.fast_path("99999") is None
|
|
24
|
+
|
|
25
|
+
|
|
26
|
+
def test_pread_local_file(tmp_path):
|
|
27
|
+
p = tmp_path / "blob.bin"
|
|
28
|
+
p.write_bytes(BUFFER[:10000])
|
|
29
|
+
got = se.pread(str(p), 100, 250) # local path branch (no threads)
|
|
30
|
+
assert got == BUFFER[100:350]
|
|
31
|
+
|
|
32
|
+
|
|
33
|
+
def test_pread_splits_into_parallel_ranges(monkeypatch):
|
|
34
|
+
calls = []
|
|
35
|
+
|
|
36
|
+
def fake_get_range(url, start, end, retries=2):
|
|
37
|
+
calls.append((start, end))
|
|
38
|
+
return BUFFER[start:end + 1]
|
|
39
|
+
|
|
40
|
+
monkeypatch.setattr(reader, "_get_range", fake_get_range)
|
|
41
|
+
|
|
42
|
+
offset, length = 500, 2_500_000 # > 2 MB -> must fan out
|
|
43
|
+
got = se.pread("http://ebi.example/x.mrc", offset, length, nthreads=8)
|
|
44
|
+
|
|
45
|
+
assert got == BUFFER[offset:offset + length] # correct + correctly ordered
|
|
46
|
+
assert len(calls) > 1 # actually parallelised
|
|
47
|
+
spans = sorted(calls)
|
|
48
|
+
assert spans[0][0] == offset # covers the whole request...
|
|
49
|
+
assert spans[-1][1] == offset + length - 1
|
|
50
|
+
for (_, e), (s2, _) in zip(spans, spans[1:]): # ...contiguously, no gaps/overlap
|
|
51
|
+
assert s2 == e + 1
|
|
52
|
+
|
|
53
|
+
|
|
54
|
+
def test_pread_zero_length():
|
|
55
|
+
assert se.pread("http://x/y", 0, 0) == b""
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
def test_get_range_retries_then_raises(monkeypatch):
|
|
59
|
+
attempts = {"n": 0}
|
|
60
|
+
|
|
61
|
+
def always_fail(*a, **k):
|
|
62
|
+
attempts["n"] += 1
|
|
63
|
+
raise RuntimeError("boom")
|
|
64
|
+
|
|
65
|
+
monkeypatch.setattr(reader.session, "get", always_fail)
|
|
66
|
+
with pytest.raises(RuntimeError):
|
|
67
|
+
reader._get_range("http://x/y", 0, 10, retries=2)
|
|
68
|
+
assert attempts["n"] == 3 # initial try + 2 retries
|