scale-forecasting 1.0.0__tar.gz → 1.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- scale_forecasting-1.2.0/CHANGELOG.md +109 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/PKG-INFO +22 -48
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/README.md +11 -8
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/pyproject.toml +29 -9
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/__init__.py +9 -1
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/agent_surfaces.py +17 -10
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/capacity.py +1 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/config.py +74 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/dag.py +19 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/diagnostics.py +1076 -1
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/bigquery_engine.py +287 -4
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/bigquery_names.py +8 -3
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/bigquery_sql.py +590 -23
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/vertex_engine.py +13 -4
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/features.py +59 -8
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/mcp.py +68 -11
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/__init__.py +10 -1
- scale_forecasting-1.2.0/src/scale_forecasting/models/_foundation_base.py +576 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/base_model.py +1 -1
- scale_forecasting-1.2.0/src/scale_forecasting/models/bigquery_native.py +366 -0
- scale_forecasting-1.2.0/src/scale_forecasting/models/chronos2.py +165 -0
- scale_forecasting-1.2.0/src/scale_forecasting/models/chronos_bolt.py +129 -0
- scale_forecasting-1.2.0/src/scale_forecasting/models/timesfm_torch.py +390 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/playground.py +169 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/ids.py +6 -7
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/reads.py +52 -2
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/report.py +35 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/sdk.py +521 -0
- scale_forecasting-1.0.0/CHANGELOG.md +0 -52
- scale_forecasting-1.0.0/src/scale_forecasting/models/bigquery_native.py +0 -177
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/.gitignore +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/LICENSE +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/_entry.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/_infra_args.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/airflow_emit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/airflow_tasks.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/automl_submit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/backtest.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/batch_infra.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/batch_telemetry.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/calibration.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/cluster_deps.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/cluster_submit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/cluster_telemetry.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/code_delivery.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/commands.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/compute_fallback.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/data_gen/__init__.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/data_gen/generator.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/data_gen/seed_spark.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/dataproc_cluster.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/device_audit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/__init__.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/automl_engine.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/ray_engine.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/ray_io.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/spark_explode.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/engines/spark_io.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ensemble_run.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ensembler.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/errors.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/gce_submit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/gke_submit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/hardware.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/hpo.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/identity.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/job_launch.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/job_outcome.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/job_wait.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/launch_plan.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/main.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/__init__.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/_intervals.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/base_metric.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/bias.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/coverage.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/cv.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/interval_score.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/interval_width.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/maape.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/mae.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/mape.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/mase.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/mase_seasonal.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/mse.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/msis.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/msse.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/ope.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/pinball.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/r2.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/rmse.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/rmsle.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/rmsse.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/smape.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/metrics/wape.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/_lag_forecaster.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/_neuralforecast_base.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/_vertex_automl_base.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/auto_arima.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/auto_ces.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/auto_theta.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/autoets.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/catboost_model.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/croston.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/fft.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/holtwinters.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/kalman.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/lightgbm_model.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/naive_drift.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/naive_mean.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/naive_moving_average.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/naive_seasonal.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/neuralprophet_model.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/patchtst.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/prophet_model.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/random_forest.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/regression_lags.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/sarimax.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/stl_bagging.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/tbats_model.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/tft.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/theta.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/tide.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/tsmixer.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/ucm.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/vertex_l2l.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/vertex_seq2seq.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/vertex_tft.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/vertex_tide.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/models/xgboost_model.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/notebook_acceptance.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/probes/__init__.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/probes/cancel.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/probes/reconcile.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/probes/runtimes.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/probes/settle.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/probes/vocabulary.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/__init__.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/baseline.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/cost.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/measure.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/numeric.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/sampling.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/signature.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/source.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/profiling/stats.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/py.typed +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/quota.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ray_cluster.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ray_entry.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ray_infra.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ray_jobs.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ray_reaper.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ray_submit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/ray_telemetry.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/reconciliation.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/__init__.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/artifacts.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/cells.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/ddl.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/harvest.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/header.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/jobs.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/lifecycle.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/ops.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/params.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/rows.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/tables.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/views.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/registry/write_api.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/resources/__init__.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/resources/audit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/resources/catalog.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/resources/cluster.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/resources/fleet.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/resources/serverless.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/resources/slot.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/retry_policy.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/retry_run.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/review.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/router.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/scenarios.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/seasonality.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/settings.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/shared_clusters.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/smoke_run.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/spark_entry.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/staging.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/submit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/submitters.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/validation.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/vertex_entry.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/vertex_submit.py +0 -0
- {scale_forecasting-1.0.0 → scale_forecasting-1.2.0}/src/scale_forecasting/worker.py +0 -0
|
@@ -0,0 +1,109 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to `scale-forecasting` are documented in this file.
|
|
4
|
+
|
|
5
|
+
The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.1.0/),
|
|
6
|
+
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
|
|
7
|
+
|
|
8
|
+
---
|
|
9
|
+
|
|
10
|
+
## [Unreleased]
|
|
11
|
+
|
|
12
|
+
---
|
|
13
|
+
|
|
14
|
+
## [1.2.0] - 2026-10-14
|
|
15
|
+
|
|
16
|
+
### Added
|
|
17
|
+
|
|
18
|
+
- **Open-Weight Zero-Shot Foundation Model Suite (`[models-foundation]` extra; `34 → 37` models, `12 → 13` extras):**
|
|
19
|
+
- Added `[models-foundation]` (`chronos-forecasting>=2.2`, `timesfm[torch]>=3.0`) in [`pyproject.toml`](./pyproject.toml), separated from `[models-dl]` and composed into `[models]` and `[all]`. All three models run on CPU by default (`hardware = "cpu"`, `gpu_capable = True`) in `scale_forecasting.playground` and across all 5 Python cloud runtimes (`spark`, `ray`, `vertex`, `gce`, `gke`), automatically accelerating on NVIDIA `T4`, `L4`, `A100`, or `A100_80GB` GPUs when `use_gpu = True` or `hardware = "gpu"`:
|
|
20
|
+
1. **`chronos_bolt`** ([`src/scale_forecasting/models/chronos_bolt.py`](./src/scale_forecasting/models/chronos_bolt.py)): Amazon `ChronosBoltPipeline` (`amazon/chronos-bolt-base` default; `size="small" | "mini" | "tiny"` or `@small` / `@mini` / `@tiny` variant tags), univariate zero-shot inference with native multi-quantile heads (`0.1`–`0.9`), supporting both `local` and `global` batch modes.
|
|
21
|
+
2. **`chronos2`** ([`src/scale_forecasting/models/chronos2.py`](./src/scale_forecasting/models/chronos2.py)): Amazon `Chronos2Pipeline` (`amazon/chronos-2`), supporting univariate and 3-tier covariates (`future_covariates`, `past_covariates`, `static_covariates`) across `local` and `global` modes (`cross_learning = True` in `global` mode for cross-series group attention).
|
|
22
|
+
3. **`timesfm_torch`** ([`src/scale_forecasting/models/timesfm_torch.py`](./src/scale_forecasting/models/timesfm_torch.py)): Google `TimesFM 3.0` (`google/timesfm-3.0-pytorch` default via `timesfm3.TimesFM3Forecaster` with native Variate Attention for past, future, and static covariates, plus `version="2.5"` / `timesfm_torch@v2.5` option using `timesfm.TimesFM_2p5_200M_torch` and pure-NumPy in-context Ridge regression), supporting `local` and `global` modes.
|
|
23
|
+
- **BigQuery Managed Alias (`"bq_timesfm"`):**
|
|
24
|
+
- [`RunConfig._normalize`](./src/scale_forecasting/config.py) and [`models.base_model_name`](./src/scale_forecasting/models/__init__.py) accept `"bq_timesfm"` (and `"bq_timesfm@<tag>"`) as an explicit alias for BigQuery `AI.FORECAST` (`"timesfm"`), normalizing to `"timesfm"` without altering any `run_id`.
|
|
25
|
+
- **Shared-Instance Default for Zero-Shot Foundation Runs (`workers = 1`):**
|
|
26
|
+
- [`effective_worker_count`](./src/scale_forecasting/engines/vertex_engine.py) keeps `workers = 1` by default when `deep_learning` runs only zero-shot `[models-foundation]` models on `vertex` or `gke` (executing sequentially on a single shared VM/pod with automatic VRAM/RAM cleanup between models), while preserving automatic per-model multi-worker expansion (`1 → len(models)`) when trained `[models-dl]` models are present.
|
|
27
|
+
- **Operational Inventory & Replenishment Policy Translators (`diagnostics.py`, `sdk.py`, `playground.py`, `report.py`, `mcp.py`):**
|
|
28
|
+
- Added [`compute_inventory_policy()`](./src/scale_forecasting/diagnostics.py) and [`plot_inventory_policy()`](./src/scale_forecasting/diagnostics.py), exported at the top level of `scale_forecasting`, plus `Forecaster.inventory_policy_df(...)` / `Forecaster.plot_inventory_policy(...)`, `PlaygroundRun.inventory_policy_df(...)` / `PlaygroundRun.plot_inventory_policy(...)`, and `BakeOff.inventory_policy_df(...)` / `BakeOff.plot_inventory_policy(...)`.
|
|
29
|
+
- Translates calibrated forecast distributions (`yhat`, `yhat_lower`, `yhat_upper`) and out-of-fold backtest residuals (`backtest_oof`) into concrete per-SKU replenishment tables across **Continuous Review $(s, S)$** and **Periodic Review $(R, S)$** policies, **Cycle Service Level ($\text{CSL}$)**, **Unit Fill Rate ($\beta$ via inverse standard normal loss $G(z) = \sigma_P^{-1}(1-\beta)\mu_L$)**, and **Newsvendor Critical Fractile ($\alpha^* = c_u / (c_u + c_o)$)** targets, with **AR(1) autocorrelation-adjusted** + **stochastic lead-time ($\sigma_L$)** protection-window uncertainty ($\sigma_P = \sqrt{\sigma_{D,P}^2 + \bar{d}^2 \sigma_L^2}$), **Inventory Position ($IP = \text{on\_hand} + \text{on\_order} - \text{backorders}$)**, **EOQ / lot-sizing (`min_order_qty`, `order_multiple`)**, expected stockout units and holding/stockout cost, and per-SKU `overrides_df` support.
|
|
30
|
+
- Added a dedicated **"Inventory Policy (ROP / SS)"** interactive tab (`tab-inventory`) and `"inventory_policy"` JSON payload section in [`report.py`](./src/scale_forecasting/report.py) (wired automatically into `Forecaster.export_report()`), plus `include_inventory_policy` and `inventory_params` on the `run_playground` and `review_run` MCP tools in [`mcp.py`](./src/scale_forecasting/mcp.py).
|
|
31
|
+
|
|
32
|
+
### Changed
|
|
33
|
+
|
|
34
|
+
- **Cloud Worker Cache & Compilerless CUDA Hardening ([`src/scale_forecasting/models/_foundation_base.py`](./src/scale_forecasting/models/_foundation_base.py)):**
|
|
35
|
+
- `_ensure_writable_hf_cache()` and `_checkpoint_load_lock()` detect unwritable `$HOME/.cache` directories (such as YARN user `yarn` on Dataproc clusters), redirect `HF_HOME`, `HF_HUB_CACHE`, `TORCH_HOME`, `TRITON_CACHE_DIR`, and `huggingface_hub.constants` / `transformers.utils.hub` cache attributes to `<tempdir>/scale_forecasting_hf_cache`, and serialize concurrent worker weight downloads on the same host via `fcntl.flock`.
|
|
36
|
+
- `_ensure_torch_runtime_ready()` deregisters PyTorch 2.11's `('bmm', 'CUDA')` Triton JIT outer-product override (`torch._native.triton_utils.deregister_op_overrides()`) when no C compiler (`gcc` / `clang` / `cc`) is on `PATH`, dispatching `aten::bmm` directly to precompiled cuBLAS kernels; [`docker/Dockerfile`](./docker/Dockerfile) also includes `gcc` and `libc6-dev`.
|
|
37
|
+
- [`src/scale_forecasting/capacity.py`](./src/scale_forecasting/capacity.py) classifies transient GCE subnetwork contention (`400 The resource '.../subnetworks/...' is not ready`) under `_CAPACITY_MARKERS` so concurrent cluster launches automatically retry with backoff.
|
|
38
|
+
|
|
39
|
+
---
|
|
40
|
+
|
|
41
|
+
## [1.1.0] - 2026-10-13
|
|
42
|
+
|
|
43
|
+
### Added
|
|
44
|
+
|
|
45
|
+
- **BigQuery ML `ARIMA_PLUS_XREG` Exogenous Covariate & `ML.EXPLAIN_FORECAST` Explainability Parity (`native` family):**
|
|
46
|
+
- `arima_plus` ([`src/scale_forecasting/models/bigquery_native.py`](./src/scale_forecasting/models/bigquery_native.py)) now declares `supports_exog = True`, `supports_future_covariates = True`, and `supports_explainability = True`, and supports `"arima_plus_xreg"` (and `"arima_plus@xreg"`) as a first-class model entry in `RunConfig.models` and `model_params`. When `["arima_plus", "arima_plus_xreg"]` are listed together, `"arima_plus"` is automatically pinned to univariate `ARIMA_PLUS` while `"arima_plus_xreg"` normalizes to `"arima_plus@xreg"` (`ARIMA_PLUS_XREG`) for side-by-side Covariate FVA.
|
|
47
|
+
- When `features.future_covariates` (`known_future_covariates` / `exog`) is active, [`src/scale_forecasting/engines/bigquery_sql.py`](./src/scale_forecasting/engines/bigquery_sql.py) compiles `CREATE OR REPLACE MODEL ... OPTIONS(model_type = 'ARIMA_PLUS_XREG', ...)` with the exogenous regressors in `SELECT` and passes the future regressor table as the 3rd argument to `ML.FORECAST` and `ML.EXPLAIN_FORECAST`. Univariate configs and `arima_plus@univariate` ablation variants compile byte-identical `model_type = 'ARIMA_PLUS'` SQL.
|
|
48
|
+
- [`src/scale_forecasting/engines/bigquery_engine.py`](./src/scale_forecasting/engines/bigquery_engine.py) executes `ML.EXPLAIN_FORECAST` (`build_explain_forecast_query` + `extract_bqml_explanations`) to populate **Tier 1** global feature attributions (`forecast_metadata.fit_diagnostics["feature_attributions"]` across `trend`, `seasonal`, `holiday_effect`, and each `attribution_<col>` exogenous regressor) and **Tier 2** per-step forecast attributions (`forecast_predictions.explanations`).
|
|
49
|
+
- **BigQuery `AI.FORECAST` (`timesfm`) Multivariate Covariate Support (`TimesFM 3.0`):**
|
|
50
|
+
- `timesfm` ([`src/scale_forecasting/models/bigquery_native.py`](./src/scale_forecasting/models/bigquery_native.py)) now declares `supports_exog = True`, `supports_future_covariates = True`, and `supports_past_covariates = True` (bringing `future_covariates`-capable models to 19 and `past_covariates`-capable models to 18).
|
|
51
|
+
- When `future_covariates` or `past_covariates` are active on `timesfm`, `bigquery_sql.py` automatically targets `model => 'TimesFM 3.0'` with `target_cols => ['y']`, feeding future covariates through the future horizon window and masking past covariates (`CAST(NULL AS FLOAT64)`) across the future window so zero-shot `AI.FORECAST` conditions on historical + future covariates without data leakage. Univariate `timesfm` and `timesfm@univariate` continue to default to `TimesFM 2.5` with `data_col => 'y'`.
|
|
52
|
+
- **`model_params.arima_plus` Options & Multi-Series Guardrails:**
|
|
53
|
+
- `resolve_arima_plus_params` validates and renders `auto_arima_max_order` (`1..5`), `auto_arima_min_order` (`0..5`), `clean_spikes_and_dips`, `adjust_step_changes`, `decompose_time_series`, `holiday_region` (`str` or `list[str]`), `seasonalities`, `time_series_length_fraction`, `min_time_series_length`, `max_time_series_length`, and `trend_smoothing_window_size` into `CREATE MODEL ... OPTIONS(...)`.
|
|
54
|
+
- Explicitly rejects `forecast_limit_lower_bound` and `forecast_limit_upper_bound` with a `ConfigError` pointing to `output.floor` and `output.cap`, and rejects manual `auto_arima=False` / `non_seasonal_order` on multi-series `time_series_id_col` panels.
|
|
55
|
+
- **Per-Series `ML.ARIMA_EVALUATE` & `ML.ARIMA_COEFFICIENTS` Diagnostics:**
|
|
56
|
+
- `bigquery_engine.run` executes `build_arima_evaluate_query` and `build_arima_coefficients_query` (`extract_arima_diagnostics`) on the fitted `ARIMA_PLUS` / `ARIMA_PLUS_XREG` model and populates `forecast_metadata.fit_diagnostics["arima_diagnostics"]` per `ts_id` with `non_seasonal_order` (`[p, d, q]`), `has_drift`, `aic`, `log_likelihood`, `variance`, `seasonal_periods`, `has_holiday_effect`, `has_spikes_and_dips`, `has_step_changes`, `ar_coefficients`, `ma_coefficients`, `intercept_or_drift`, and linear `xreg_weights`.
|
|
57
|
+
- **Universal Time-Series Anomaly & Structural Change-Point Detection Across All 34 Models, 9 Ensembles, and Past Runs (`Forecaster`, `Registry`, `diagnostics.py`, `bigquery_sql.py`):**
|
|
58
|
+
- Added `build_detect_anomalies_query` (`ML.DETECT_ANOMALIES` for `arima_plus` / `arima_plus@xreg` and `AI.DETECT_ANOMALIES` for `timesfm`), `build_detect_change_points_query` (`ML.DETECT_CHANGE_POINTS` with gap-edge artifact filtering), pure offline `compute_anomalies` and `compute_change_points` ([`src/scale_forecasting/diagnostics.py`](./src/scale_forecasting/diagnostics.py)), and `Forecaster.detect_anomalies_df(...)` / `Forecaster.detect_change_points_df(...)` / `Registry.detect_anomalies_df(...)` / `Registry.detect_change_points_df(...)`.
|
|
59
|
+
- Adapts across all 34 models (`statistical`, `ml`, `deep_learning`, `automl`, `native`), all 9 ensembles (`ensemble_*`), `model_name="all"`, forward `actuals_df` scoring, model-free `engine="stl"`, and any historical `run_id` in the BigQuery registry without re-fitting.
|
|
60
|
+
- **Semantic Versioning Charter (`MAJOR.MINOR.PATCH`):** Documented the formal versioning policy in [`AGENTS.md`](./AGENTS.md) and [`CONTRIBUTING.md`](./CONTRIBUTING.md) defining `PATCH` (`1.0.x`), `MINOR` (`1.x.0`), and `MAJOR` (`x.0.0`) boundaries and release precheck gates.
|
|
61
|
+
|
|
62
|
+
### Changed
|
|
63
|
+
|
|
64
|
+
- **BigQuery Query Cache Prevention (`use_query_cache=False`):** `bigquery_engine._query` now sets `QueryJobConfig(use_query_cache=False)` so `native` wall-clock runtime measurements and fresh forecast queries never hit cached results.
|
|
65
|
+
- **PyPI Long-Description Mermaid Rendering (`hatch-fancy-pypi-readme`):** Configured `[tool.hatch.metadata.hooks.fancy-pypi-readme]` in [`pyproject.toml`](./pyproject.toml) so `README.md` retains its interactive ` ```mermaid ` architecture flowchart on GitHub and MkDocs while substituting the diagram with the high-resolution architecture card (`docs/assets/social_card.png`) in built wheel and sdist `METADATA` for `pypi.org`.
|
|
66
|
+
|
|
67
|
+
---
|
|
68
|
+
|
|
69
|
+
## [1.0.0] - 2026-10-12
|
|
70
|
+
|
|
71
|
+
### Added
|
|
72
|
+
|
|
73
|
+
- **Declarative Execution Contract (`RunConfig`):** One JSON/dict contract ([`src/scale_forecasting/config.py`](./src/scale_forecasting/config.py)) drives execution across Local CLI, Python SDK (`Forecaster`), Interactive Notebooks, Cloud Composer 3 DAGs (`--emit-airflow`), and Headless Cloud Batch containers, with deterministic content-addressed `run_id` and per-model `model_spec_hash` hashing ([`src/scale_forecasting/registry/ids.py`](./src/scale_forecasting/registry/ids.py)).
|
|
74
|
+
- **34 Forecasting Models Across 5 Families + Multi-Instance `<base_model>@<tag>` Variants:**
|
|
75
|
+
- `statistical` (`18`): `theta`, `auto_theta`, `holtwinters`, `autoets`, `auto_arima`, `sarimax`, `tbats`, `auto_ces`, `stl_bagging`, `ucm`, `kalman`, `prophet`, `croston` (`classic`, `sba`, `tsb`), `fft`, `naive_mean`, `naive_seasonal`, `naive_drift`, `naive_moving_average`.
|
|
76
|
+
- `ml` (`5`): `lightgbm`, `xgboost`, `catboost`, `random_forest`, `regression_lags` with both `"recursive"` and `"direct"` multi-step horizon strategies and customizable target `lags`.
|
|
77
|
+
- `deep_learning` (`5`): `tide`, `tft`, `tsmixer`, `patchtst`, `neuralprophet` across `local`, `global`, and `hybrid` panel regimes.
|
|
78
|
+
- `automl` (`4`): `vertex_l2l`, `vertex_tide`, `vertex_tft`, `vertex_seq2seq` via Vertex AI Tabular Workflows and managed AutoML training jobs.
|
|
79
|
+
- `native` (`2`): `arima_plus` and `timesfm` (`AI.FORECAST`) executed natively in BigQuery SQL with SQL-enforced `output` bounds and integer rounding.
|
|
80
|
+
- **21 Evaluation Metrics & Conformal Calibration:** 16 point metrics (`wape`, `smape`, `mape`, `maape`, `ope`, `mae`, `rmse`, `mse`, `rmsle`, `bias`, `mase`, `mase_seasonal`, `rmsse`, `msse`, `r2`, `cv`) and 5 interval metrics (`coverage`, `pinball`, `interval_score`, `interval_width`, `msis`), plus empirical conformal residual calibration ([`src/scale_forecasting/calibration.py`](./src/scale_forecasting/calibration.py)).
|
|
81
|
+
- **7 Google Cloud Compute Runtimes & Per-Family DAG Router:** Parallel per-family job dispatch ([`src/scale_forecasting/dag.py`](./src/scale_forecasting/dag.py)) across Dataproc Serverless / Cluster / Connect (`spark`), Ray on Vertex AI or GKE (`ray`), Vertex AI CustomJob (`vertex`), self-deleting Compute Engine Single-VM (`gce`), GKE Indexed Job (`gke`), Vertex AI AutoML (`vertex_automl`), and BigQuery ML (`bigquery`), supporting CPU and NVIDIA `T4`, `L4`, `A100`, and `A100_80GB` GPUs with BigQuery Storage Read API `[start_id, end_id]` worker sharding and LPT chunk scheduling.
|
|
82
|
+
- **Hierarchical Reconciliation, Smart Ensembles & Two-Tier Explainability:** All 8 Hyndman FPP3 reconciliation methods (`mint_shrink`, `mint_nonneg` active-set non-negative QP, `wls_var`, `wls_struct`, `ols`, `bottom_up`, `top_down`, `middle_out`), 9 ensemble strategies (`mean`, `median`, `trimmed_mean`, `inverse_error`, `champion`, `horizon_specialist`, `nnls`, `ridge`, `xgb`) with `top_k`, `parsimony_margin`, and `variant_policy` (`"all"`, `"best_per_base_model"`, `"primary_only"`), calibrated ensemble prediction intervals, cross-run ensembling (`ensemble_cross_runs`), and two-tier feature attributions (`feature_attributions()` and `explain()`).
|
|
83
|
+
- **Forecaster Decision Workbench (`Phases G.1–G.5`):**
|
|
84
|
+
- **Physical Bounds & Quantile/Newsvendor Targets (`output`):** Scalar and per-series bounds (`floor`, `cap`, `floor_col`, `cap_col`), integer rounding (`"none"`, `"round"`, `"ceil"`, `"floor"`, `"cumulative_round"`), monotone multi-percentile fans (`output.quantiles`), and Newsvendor asymmetric cost optimization (`underage_cost`, `overage_cost`, `target_quantile`).
|
|
85
|
+
- **Pre-Fit Data Hygiene & SBC Regime Routing (`data`, `features`):** Grid regularization (`grid_policy`), `trim_leading_zeros`, X-13 `trading_days`, fold-safe outlier despiking (`outlier_policy` / `outlier_handling`), censored stockout recovery (`censored_col`), and Syntetos–Boylan–Croston demand classification (`compute_demand_profile`) with optional `regime_routing`.
|
|
86
|
+
- **Econometric Diagnostics, Scenarios, Lifecycle Governance & HTML Reports (`diagnostics.py`, `scenarios.py`, `report.py`):** Multi-baseline Forecast Value Added (`compute_fva` with Total, Covariate, Drop-One, and Pooling FVA + Harvey–Leybourne–Newbold modified Diebold–Mariano & Wilcoxon $p$-values), horizon decay (`compute_horizon_decay`), directional bias & Trigg Tracking Signal audits (`compute_bias_report`), AR(1) autocorrelation-aware temporal rollups (`rollup_time`), date-scoped promo/price scenario simulation with revenue impact (`simulate_scenarios`), realized accuracy vs. new actuals (`compute_realized_accuracy`), cross-run revision stability (`compute_revision_stability`), Top-$N$ exception triage queues (`compute_exceptions_queue`), and single-file interactive HTML/JSON executive reports (`export_report`).
|
|
87
|
+
- **Ablation Ladders & Snapshot-Verified Cross-Run Cell Borrowing (`reuse_prior_runs`):** Declarative `ablation_modes` (`cov_ladder`, `cov_by_tier`, `cov_by_column`, `cov_drop_one`, `scope_ladder`, `transform_ladder`) and server-side BigQuery cell borrowing (`ops.find_reusable_models`, `ops.borrow_model_results`) that skips cloud compute for invariant models.
|
|
88
|
+
- **BigQuery Registry & Analytical SQL Views:** 4 source tables, 5 registry tables (`run_registry`, `run_jobs`, `forecast_metadata`, `forecast_predictions`, `backtest_oof`), and 5 analytical SQL views (`v_model_leaderboard`, `v_model_leaderboard_comparable`, `v_backtest_coverage`, `v_run_summary` with per-job time ledger, and `v_run_jobs`), plus surgical per-cell repair ([`src/scale_forecasting/retry_run.py`](./src/scale_forecasting/retry_run.py)) and `Registry.doctor()`.
|
|
89
|
+
- **Two-Stage Terraform Infrastructure, 11 Notebooks & 42 Live Smoke Configs:** Complete bootstrap + main Terraform modules ([`terraform/`](./terraform/README.md)), 11 interactive notebooks across 4 learning tracks ([`notebooks/`](./notebooks/README.md)), and 42 live-validated smoke configurations + 4 full-breadth multi-runtime verification runs recorded in [`docs/validation.md`](./docs/validation.md).
|
|
90
|
+
- **Agent-First Surfaces (`SKILL.md`, Built-in `stdio` MCP Server, JSON Schema, `llms.txt` & Cloud Shell Tutorial):** Portable Agent Skill ([`skills/scale-forecasting/SKILL.md`](./skills/scale-forecasting/SKILL.md)) with workspace auto-discovery ([`.agents/skills.json`](./.agents/skills.json) and `.agents/skills/scale-forecasting`), zero-extra JSON-RPC 2.0 MCP server ([`src/scale_forecasting/mcp.py`](./src/scale_forecasting/mcp.py)) exposing 7 `forecast://*` resources and 9 tools with `--allow-launch` safety gating, published `RunConfig` JSON Schema ([`docs/schemas/run_config.schema.json`](./docs/schemas/run_config.schema.json)), `llms.txt` / `llms-full.txt`, Google Antigravity [`plugin.json`](./plugin.json) + [`mcp_config.json`](./mcp_config.json), portable [`.mcp.json`](./.mcp.json), [`cloudshell_tutorial.md`](./cloudshell_tutorial.md), and pre-commit zero-drift synthesis ([`src/scale_forecasting/agent_surfaces.py`](./src/scale_forecasting/agent_surfaces.py)).
|
|
91
|
+
|
|
92
|
+
### Changed
|
|
93
|
+
|
|
94
|
+
- **Modular Dependency Extras (`pyproject.toml`):** Core `pip install scale-forecasting` installs only the pure offline forecasting layer with zero Google Cloud clients. All Google Cloud SDKs live in `[gcp]`, with composable `[notebook]`, `[spark]`, `[ray]`, `[submit]`, `[models-stats]`, `[models-trees]`, `[models-prophet]`, `[models-dl]`, `[models-automl]`, `[models]`, and `[all]` extras and actionable `MissingExtraError` guidance at every cloud and plotting entry point.
|
|
95
|
+
- **Static Typing, Logging & Test Ratchet:** Added PEP 561 `py.typed` marker with zero `mypy` errors across all 181 source modules, library-safe `NullHandler` logging (`configure_cli_logging` on CLI entry points), widened Ruff lint families (`SIM`, `C4`, `PIE`, `PERF`, `RUF`, `BLE`), and enforced an 85 % offline line-coverage ratchet in CI (`4,960` offline unit tests).
|
|
96
|
+
- **Python 3.11–3.12 Package Support:** `requires-python` widened from `>=3.11,<3.12` to `>=3.11,<3.13` with `3.12` classifiers and a per-interpreter CI `core-install` matrix; the cloud stack stays pinned to `3.11.15` (`.python-version`) for Spark Connect and Ray on Vertex pickle parity ([`docs/version_matrix.md`](./docs/version_matrix.md)). 3.13 waits on the `numpy<2` pin `neuralprophet` still needs.
|
|
97
|
+
- **Per-Job Provisioning vs. Execution Telemetry:** `run_jobs.job_telemetry.$.platform` (`provision_s`, `execute_s`, `total_wall_s`) is stamped from one probe read of each finished Dataproc Serverless batch or Vertex `CustomJob` (`batch_telemetry.platform_phases`), and `v_run_jobs` projects it as `provision_seconds` / `execute_seconds` beside `runtime_seconds`; the Serverless header telemetry carries the same split.
|
|
98
|
+
- **One BigQuery Client Factory:** Every `bigquery.Client(...)` in the package (73 sites) now goes through `registry.tables.bigquery_client`, which guards on `google.cloud.bigquery` alone via the new `errors.require_modules` so an on-cluster worker that never holds the launch clients still reaches the registry, and a core-only install gets the `[gcp]` install line instead of a `ModuleNotFoundError`.
|
|
99
|
+
- **`DataConfig` Identifier Validation:** `source_table` must be `table`, `dataset.table`, or `project.dataset.table` with no backticks, whitespace, or control characters, and `ts_id_col` / `date_col` / `target_col` must be BigQuery column names — checked once at config load, where the values are interpolated into backticked SQL. No field is added, so no `run_id` moves.
|
|
100
|
+
|
|
101
|
+
### Security
|
|
102
|
+
|
|
103
|
+
- **HTML Report Hardening (`report.py`):** The inline `EXPLORER_DATA` JSON escapes `<`, `>`, and `&` as `\u003c` / `\u003e` / `\u0026` so a series id containing `</script>` cannot close the script block, and the fan-chart label is HTML-escaped (`escHtml`) before `innerHTML` assignment.
|
|
104
|
+
- **FIPS-Safe Content Addressing:** `code_delivery` tags staged code archives with `hashlib.md5(..., usedforsecurity=False)` (a content-address, not a digest), so staging works on FIPS-enforced hosts.
|
|
105
|
+
|
|
106
|
+
[Unreleased]: https://github.com/statmike/scale-forecasting/compare/v1.2.0...HEAD
|
|
107
|
+
[1.2.0]: https://github.com/statmike/scale-forecasting/compare/v1.1.0...v1.2.0
|
|
108
|
+
[1.1.0]: https://github.com/statmike/scale-forecasting/compare/v1.0.0...v1.1.0
|
|
109
|
+
[1.0.0]: https://github.com/statmike/scale-forecasting/releases/tag/v1.0.0
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: scale-forecasting
|
|
3
|
-
Version: 1.
|
|
3
|
+
Version: 1.2.0
|
|
4
4
|
Summary: Time-series forecasting on Google Cloud at any scale: one JSON configuration runs every model family on Dataproc Serverless, Ray, Vertex AI, GKE, Compute Engine, or BigQuery ML and writes forecasts and leaderboards back to BigQuery.
|
|
5
5
|
Project-URL: Homepage, https://github.com/statmike/scale-forecasting
|
|
6
6
|
Project-URL: Documentation, https://statmike.github.io/scale-forecasting/
|
|
@@ -10,7 +10,7 @@ Project-URL: Issues, https://github.com/statmike/scale-forecasting/issues
|
|
|
10
10
|
Author: scale-forecasting contributors
|
|
11
11
|
License: Apache-2.0
|
|
12
12
|
License-File: LICENSE
|
|
13
|
-
Keywords: automl,bigquery,dataproc,forecasting,gke,google-cloud,ray,spark,time-series,timesfm,vertex-ai
|
|
13
|
+
Keywords: automl,bigquery,chronos,dataproc,forecasting,gke,google-cloud,ray,spark,time-series,timesfm,vertex-ai
|
|
14
14
|
Classifier: Development Status :: 5 - Production/Stable
|
|
15
15
|
Classifier: Intended Audience :: Developers
|
|
16
16
|
Classifier: Intended Audience :: Science/Research
|
|
@@ -36,6 +36,7 @@ Requires-Dist: statsmodels>=0.14
|
|
|
36
36
|
Requires-Dist: threadpoolctl>=3.1
|
|
37
37
|
Provides-Extra: all
|
|
38
38
|
Requires-Dist: catboost>=1.2; extra == 'all'
|
|
39
|
+
Requires-Dist: chronos-forecasting>=2.2; extra == 'all'
|
|
39
40
|
Requires-Dist: dataproc-spark-connect<1.0,>=0.7; extra == 'all'
|
|
40
41
|
Requires-Dist: db-dtypes>=1.2; extra == 'all'
|
|
41
42
|
Requires-Dist: google-api-core>=2.19; extra == 'all'
|
|
@@ -57,6 +58,7 @@ Requires-Dist: protobuf>=4.25; extra == 'all'
|
|
|
57
58
|
Requires-Dist: pyspark>=3.5; extra == 'all'
|
|
58
59
|
Requires-Dist: ray[default]>=2.52; extra == 'all'
|
|
59
60
|
Requires-Dist: statsforecast>=2.0; extra == 'all'
|
|
61
|
+
Requires-Dist: timesfm[torch]>=3.0; extra == 'all'
|
|
60
62
|
Requires-Dist: torch<2.14,>=2.13; extra == 'all'
|
|
61
63
|
Requires-Dist: xgboost>=2.0; extra == 'all'
|
|
62
64
|
Provides-Extra: gcp
|
|
@@ -71,6 +73,7 @@ Requires-Dist: google-cloud-storage>=2.17; extra == 'gcp'
|
|
|
71
73
|
Requires-Dist: protobuf>=4.25; extra == 'gcp'
|
|
72
74
|
Provides-Extra: models
|
|
73
75
|
Requires-Dist: catboost>=1.2; extra == 'models'
|
|
76
|
+
Requires-Dist: chronos-forecasting>=2.2; extra == 'models'
|
|
74
77
|
Requires-Dist: db-dtypes>=1.2; extra == 'models'
|
|
75
78
|
Requires-Dist: google-api-core>=2.19; extra == 'models'
|
|
76
79
|
Requires-Dist: google-auth>=2.30; extra == 'models'
|
|
@@ -86,6 +89,7 @@ Requires-Dist: neuralprophet>=0.9; extra == 'models'
|
|
|
86
89
|
Requires-Dist: prophet>=1.1.5; extra == 'models'
|
|
87
90
|
Requires-Dist: protobuf>=4.25; extra == 'models'
|
|
88
91
|
Requires-Dist: statsforecast>=2.0; extra == 'models'
|
|
92
|
+
Requires-Dist: timesfm[torch]>=3.0; extra == 'models'
|
|
89
93
|
Requires-Dist: torch<2.14,>=2.13; extra == 'models'
|
|
90
94
|
Requires-Dist: xgboost>=2.0; extra == 'models'
|
|
91
95
|
Provides-Extra: models-automl
|
|
@@ -103,6 +107,9 @@ Provides-Extra: models-dl
|
|
|
103
107
|
Requires-Dist: neuralforecast>=1.7; extra == 'models-dl'
|
|
104
108
|
Requires-Dist: neuralprophet>=0.9; extra == 'models-dl'
|
|
105
109
|
Requires-Dist: torch<2.14,>=2.13; extra == 'models-dl'
|
|
110
|
+
Provides-Extra: models-foundation
|
|
111
|
+
Requires-Dist: chronos-forecasting>=2.2; extra == 'models-foundation'
|
|
112
|
+
Requires-Dist: timesfm[torch]>=3.0; extra == 'models-foundation'
|
|
106
113
|
Provides-Extra: models-prophet
|
|
107
114
|
Requires-Dist: prophet>=1.1.5; extra == 'models-prophet'
|
|
108
115
|
Provides-Extra: models-stats
|
|
@@ -166,45 +173,9 @@ Description-Content-Type: text/markdown
|
|
|
166
173
|
[](https://github.com/statmike/scale-forecasting/blob/main/terraform/README.md)
|
|
167
174
|
[](https://github.com/statmike/scale-forecasting/blob/main/LICENSE)
|
|
168
175
|
|
|
169
|
-
`
|
|
170
|
-
|
|
171
|
-
|
|
172
|
-
flowchart LR
|
|
173
|
-
subgraph IN["Your data in BigQuery"]
|
|
174
|
-
SRC["Source table<br/>series · timestamps · covariates"]
|
|
175
|
-
end
|
|
176
|
-
CFG["One RunConfig (JSON)<br/>what to forecast · horizon · models · metrics"]
|
|
177
|
-
subgraph ROUTE["Family DAG router"]
|
|
178
|
-
R["One job per active model family<br/>statistical · ml · deep_learning · automl · native"]
|
|
179
|
-
end
|
|
180
|
-
subgraph RUN["Zero-idle compute on Google Cloud (chosen per family)"]
|
|
181
|
-
S["Dataproc Serverless Spark"]
|
|
182
|
-
RY["Ray on Vertex AI or GKE"]
|
|
183
|
-
V["Vertex AI CustomJob"]
|
|
184
|
-
G["Compute Engine single VM<br/>(self-deleting)"]
|
|
185
|
-
K["GKE Indexed Job"]
|
|
186
|
-
A["Vertex AI AutoML and<br/>Tabular Workflows"]
|
|
187
|
-
B["BigQuery ML<br/>ARIMA_PLUS · AI.FORECAST"]
|
|
188
|
-
end
|
|
189
|
-
subgraph OUT["Results back in BigQuery"]
|
|
190
|
-
REG["5 registry tables<br/>forecasts · backtests · metadata · runs · jobs"]
|
|
191
|
-
VIEWS["5 analytical views<br/>leaderboard · coverage · run summary"]
|
|
192
|
-
end
|
|
193
|
-
USE["Notebooks · Python SDK · Looker · Cloud Composer DAGs"]
|
|
194
|
-
|
|
195
|
-
SRC --> CFG --> R
|
|
196
|
-
R --> S & RY & V & G & K & A & B
|
|
197
|
-
S & RY & V & G & K & A & B --> REG --> VIEWS --> USE
|
|
198
|
-
|
|
199
|
-
classDef data fill:#E8F0FE,stroke:#4285F4,color:#174EA6
|
|
200
|
-
classDef config fill:#FEF7E0,stroke:#F9AB00,color:#7A5A00
|
|
201
|
-
classDef route fill:#FCE8E6,stroke:#EA4335,color:#A50E0E
|
|
202
|
-
classDef compute fill:#E6F4EA,stroke:#34A853,color:#0D652D
|
|
203
|
-
class SRC,REG,VIEWS,USE data
|
|
204
|
-
class CFG config
|
|
205
|
-
class R route
|
|
206
|
-
class S,RY,V,G,K,A,B compute
|
|
207
|
-
```
|
|
176
|
+
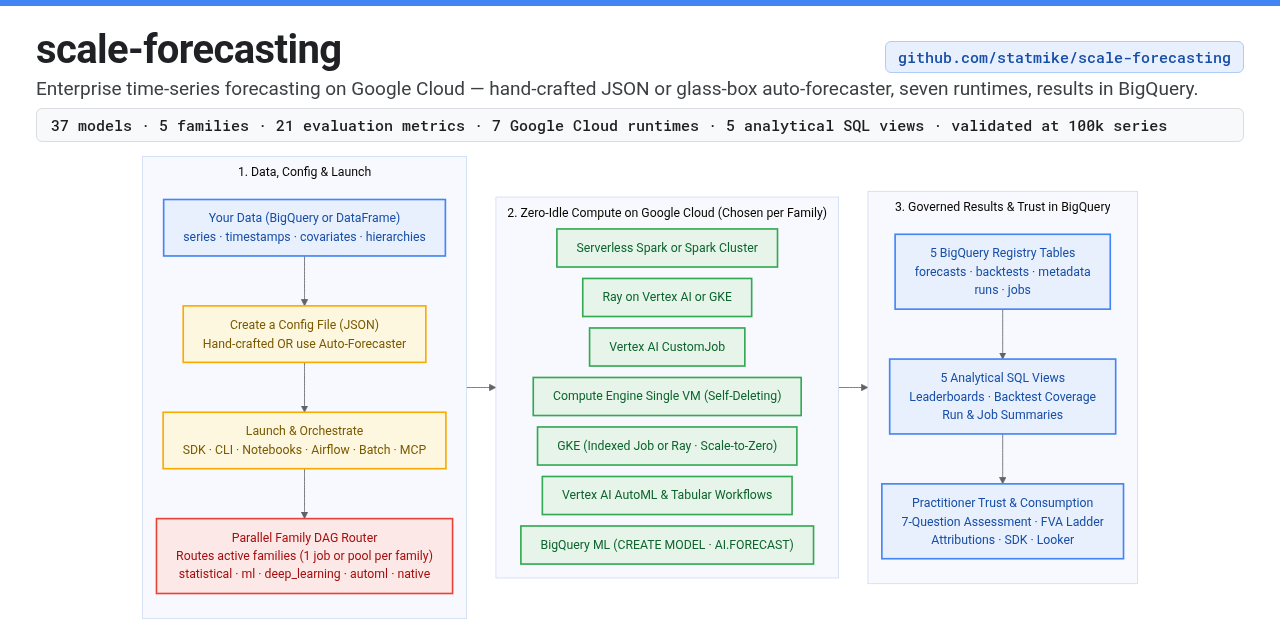
`37 models` · `5 families` · `21 evaluation metrics` · `7 Google Cloud runtimes` · `5 Analytical SQL Views` · `validated at 100k series`
|
|
177
|
+
|
|
178
|
+
|
|
208
179
|
|
|
209
180
|
---
|
|
210
181
|
|
|
@@ -212,8 +183,8 @@ flowchart LR
|
|
|
212
183
|
|
|
213
184
|
You describe *what* to forecast in one JSON file — the BigQuery table, the horizon, the models, the covariates, and the evaluation metrics. `scale-forecasting` decides *how*: it splits active models into up to five family jobs, dispatches each family in parallel to the Google Cloud runtime you chose for it, scores every model with rolling-origin backtesting and conformal prediction intervals, blends the winners into ensembles, reconciles hierarchical trees, and streams forecasts, leaderboards, and feature attributions back to BigQuery. When the run ends, the compute is gone.
|
|
214
185
|
|
|
215
|
-
- **Use `scale-forecasting` when** you want to evaluate or operate multiple model families (statistical, gradient-boosted trees, PyTorch deep learning, Vertex AI AutoML, and BigQuery ML) under one schema, one backtest contract, and one BigQuery leaderboard — from a handful of series to 100,000+.
|
|
216
|
-
- **Use a simpler path when** a single SQL query (`AI.FORECAST` or `ARIMA_PLUS` directly in BigQuery) already answers the question; you can still adopt `scale-forecasting` later to benchmark that SQL baseline against
|
|
186
|
+
- **Use `scale-forecasting` when** you want to evaluate or operate multiple model families (statistical, gradient-boosted trees, PyTorch deep learning & open-weight foundation models, Vertex AI AutoML, and BigQuery ML) under one schema, one backtest contract, and one BigQuery leaderboard — from a handful of series to 100,000+.
|
|
187
|
+
- **Use a simpler path when** a single SQL query (`AI.FORECAST` or `ARIMA_PLUS` directly in BigQuery) already answers the question; you can still adopt `scale-forecasting` later to benchmark that SQL baseline against 35 Python and AutoML models on the same holdout folds.
|
|
217
188
|
|
|
218
189
|
---
|
|
219
190
|
|
|
@@ -314,7 +285,7 @@ Every run is a validated [`RunConfig`](https://github.com/statmike/scale-forecas
|
|
|
314
285
|
| **Data stays in BigQuery** | Workers read source tables via the BigQuery Storage Read API with contiguous per-worker `[start_id, end_id]` pushdown and stream results back through the Storage Write API. | [`docs/reading_source_data.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/reading_source_data.md) · [`docs/writing_results.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/writing_results.md) |
|
|
315
286
|
| **Compute only while it runs** | Active model families launch in parallel (`dag.py`); fast CPU families tear down immediately while GPU families finish; single-VM GCE enforces triple-redundant self-deletion. | [`docs/runtimes_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/runtimes_reference.md) · [`docs/architecture.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/architecture.md) |
|
|
316
287
|
| **Seven runtimes, one contract** | Run `spark`, `ray`, `vertex`, `gce`, `gke`, `vertex_automl`, and `bigquery` concurrently under one `run_id` across CPU and NVIDIA `T4`, `L4`, `A100`, `A100_80GB` GPUs. | [`docs/runtimes_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/runtimes_reference.md) · [`docs/validation.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/validation.md) |
|
|
317
|
-
| **Managed and open models on one leaderboard** | Benchmark BigQuery ML (`ARIMA_PLUS`, `AI.FORECAST` / `
|
|
288
|
+
| **Managed and open models on one leaderboard** | Benchmark BigQuery ML (`ARIMA_PLUS`, `AI.FORECAST` / `timesfm` / `bq_timesfm`) and Vertex AI AutoML alongside 31 open-source statistical, tree, deep learning, and foundation models (`chronos_bolt`, `chronos2`, `timesfm_torch`) on identical folds. | [`docs/models_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/models_reference.md) · [`docs/output_schemas.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/output_schemas.md) |
|
|
318
289
|
| **Governed by construction** | Content-addressed `run_id`, snapshot-pinned reads, 5 registry tables, 5 analytical SQL views, surgical cell repair (`retry_run`), and 42 live-validated smoke configurations. | [`docs/output_schemas.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/output_schemas.md) · [`docs/operations.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/operations.md) · [`docs/validation.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/validation.md) |
|
|
319
290
|
| **Modular install & 1-file extensibility** | `pip install scale-forecasting` has zero Google Cloud dependencies; `[gcp]`, `[spark]`, `[ray]`, `[models]`, and `[all]` are opt-in extras; new models ship in 1 file with no image rebuild. | [`docs/runtime_dependencies.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/runtime_dependencies.md) · [`docs/adding_a_model.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/adding_a_model.md) |
|
|
320
291
|
|
|
@@ -322,17 +293,17 @@ Every run is a validated [`RunConfig`](https://github.com/statmike/scale-forecas
|
|
|
322
293
|
|
|
323
294
|
## What's inside
|
|
324
295
|
|
|
325
|
-
| Family | Models (`
|
|
296
|
+
| Family | Models (`37` total) | Runtimes | Highlights |
|
|
326
297
|
| :--- | :--- | :--- | :--- |
|
|
327
298
|
| **`statistical`** (`18`) | `theta`, `auto_theta`, `holtwinters`, `autoets`, `auto_arima`, `sarimax`, `tbats`, `auto_ces`, `stl_bagging`, `ucm`, `kalman`, `prophet`, `croston`, `fft`, `naive_mean`, `naive_seasonal`, `naive_drift`, `naive_moving_average` | `spark`, `ray`, `vertex`, `gce`, `gke` | Fast local baselines, state-space, intermittent demand, and harmonic decomposition. |
|
|
328
299
|
| **`ml`** (`5`) | `lightgbm`, `xgboost`, `catboost`, `random_forest`, `regression_lags` | `spark`, `ray`, `vertex`, `gce`, `gke` | Lag/calendar/exogenous features plus Tier 1 & Tier 2 TreeSHAP / linear / deviation attributions. |
|
|
329
|
-
| **`deep_learning`** (`
|
|
300
|
+
| **`deep_learning`** (`8`) | `tide`, `tft`, `tsmixer`, `patchtst`, `neuralprophet`, `chronos_bolt`, `chronos2`, `timesfm_torch` | `spark`, `ray`, `vertex`, `gce`, `gke` | Trained PyTorch (`[models-dl]`) and open-weight zero-shot foundation (`[models-foundation]`) models across `local`, `global`, and `hybrid` regimes on CPU or GPU. |
|
|
330
301
|
| **`automl`** (`4`) | `vertex_l2l`, `vertex_tide`, `vertex_tft`, `vertex_seq2seq` | `vertex_automl` | Managed Vertex AI Tabular Workflows & AutoML training jobs with Stage-1 HPO reuse and baseline attributions. |
|
|
331
|
-
| **`native`** (`2`) | `arima_plus
|
|
302
|
+
| **`native`** (`2`) | `arima_plus` (`ARIMA_PLUS` / `ARIMA_PLUS_XREG`), `timesfm` / `bq_timesfm` (`AI.FORECAST`) | `bigquery` | Pure BigQuery SQL execution with future covariates (`ARIMA_PLUS_XREG`), `ML.EXPLAIN_FORECAST` attributions, and zero cluster provisioning. |
|
|
332
303
|
|
|
333
304
|
- **Evaluation, quantiles & calibration:** **21 evaluation metrics** (16 point + 5 interval: `wape`, `smape`, `mape`, `maape`, `ope`, `mae`, `rmse`, `mse`, `rmsle`, `bias`, `mase`, `mase_seasonal`, `rmsse`, `msse`, `r2`, `cv`, `coverage`, `pinball`, `interval_score`, `interval_width`, `msis`), empirical conformal prediction intervals, monotone multi-percentile fans (`output.quantiles` with Chernozhukov rearrangement), and Newsvendor asymmetric cost targets (`underage_cost` / `overage_cost`) ([`docs/metrics_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/metrics_reference.md)).
|
|
334
305
|
- **Hierarchy, smart ensembles & explainability:** All 8 Hyndman FPP3 reconciliation methods (including active-set non-negative `"mint_nonneg"` alongside `mint_shrink`, `wls_var`, `wls_struct`, `ols`, `bottom_up`, `top_down`, `middle_out`), 8 ensemble strategies (`mean`, `median`, `inverse_error`, `champion`, `horizon_specialist`, `nnls`, `ridge`, `xgb`) with `top_k` & `parsimony_margin` pruning and calibrated ensemble intervals, physical bounds (`floor`, `cap`, `cumulative_round`), and two-tier feature attributions (`attributions_df` / `plot_attributions`).
|
|
335
|
-
- **Forecaster workbench, econometrics & executive reports:** Pre-fit data hygiene & SBC demand regime routing (`smooth`, `erratic`, `intermittent`, `lumpy`), Forecast Value Added (`compute_fva`) with Harvey–Leybourne–Newbold (1997) modified Diebold–Mariano $p$-values, lead-time horizon decay, Trigg tracking-signal bias audits, AR(1)-aware time rollups (`rollup_time`), counterfactual promo/price scenario simulation (`simulate_scenarios`), live drift & whipsaw stability scoring, Top-$N$ exception triage (`exceptions_df`), and self-contained interactive HTML/JSON reports (`python -m scale_forecasting.report`) ([`docs/forecaster_workbench.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/forecaster_workbench.md)).
|
|
306
|
+
- **Forecaster workbench, econometrics, inventory policy & executive reports:** Pre-fit data hygiene & SBC demand regime routing (`smooth`, `erratic`, `intermittent`, `lumpy`), Forecast Value Added (`compute_fva`) with Harvey–Leybourne–Newbold (1997) modified Diebold–Mariano $p$-values, lead-time horizon decay, Trigg tracking-signal bias audits, AR(1)-aware time rollups (`rollup_time`) and replenishment policy translators (`compute_inventory_policy` / `inventory_policy_df` for $(s, S)$, $(R, S)$, Fill Rate, and Newsvendor safety stock, reorder point, and EOQ), counterfactual promo/price scenario simulation (`simulate_scenarios`), live drift & whipsaw stability scoring, Top-$N$ exception triage (`exceptions_df`), and self-contained interactive HTML/JSON reports (`python -m scale_forecasting.report`) ([`docs/forecaster_workbench.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/forecaster_workbench.md)).
|
|
336
307
|
|
|
337
308
|
---
|
|
338
309
|
|
|
@@ -359,3 +330,6 @@ All notebooks in [`notebooks/`](https://github.com/statmike/scale-forecasting/bl
|
|
|
359
330
|
## License
|
|
360
331
|
|
|
361
332
|
Apache-2.0 — see [`LICENSE`](https://github.com/statmike/scale-forecasting/blob/main/LICENSE).
|
|
333
|
+
|
|
334
|
+
This is not an officially supported Google product. It is built on Google products and is neither
|
|
335
|
+
endorsed nor supported by Google.
|
|
@@ -12,7 +12,7 @@
|
|
|
12
12
|
[](https://github.com/statmike/scale-forecasting/blob/main/terraform/README.md)
|
|
13
13
|
[](https://github.com/statmike/scale-forecasting/blob/main/LICENSE)
|
|
14
14
|
|
|
15
|
-
`
|
|
15
|
+
`37 models` · `5 families` · `21 evaluation metrics` · `7 Google Cloud runtimes` · `5 Analytical SQL Views` · `validated at 100k series`
|
|
16
16
|
|
|
17
17
|
```mermaid
|
|
18
18
|
flowchart LR
|
|
@@ -58,8 +58,8 @@ flowchart LR
|
|
|
58
58
|
|
|
59
59
|
You describe *what* to forecast in one JSON file — the BigQuery table, the horizon, the models, the covariates, and the evaluation metrics. `scale-forecasting` decides *how*: it splits active models into up to five family jobs, dispatches each family in parallel to the Google Cloud runtime you chose for it, scores every model with rolling-origin backtesting and conformal prediction intervals, blends the winners into ensembles, reconciles hierarchical trees, and streams forecasts, leaderboards, and feature attributions back to BigQuery. When the run ends, the compute is gone.
|
|
60
60
|
|
|
61
|
-
- **Use `scale-forecasting` when** you want to evaluate or operate multiple model families (statistical, gradient-boosted trees, PyTorch deep learning, Vertex AI AutoML, and BigQuery ML) under one schema, one backtest contract, and one BigQuery leaderboard — from a handful of series to 100,000+.
|
|
62
|
-
- **Use a simpler path when** a single SQL query (`AI.FORECAST` or `ARIMA_PLUS` directly in BigQuery) already answers the question; you can still adopt `scale-forecasting` later to benchmark that SQL baseline against
|
|
61
|
+
- **Use `scale-forecasting` when** you want to evaluate or operate multiple model families (statistical, gradient-boosted trees, PyTorch deep learning & open-weight foundation models, Vertex AI AutoML, and BigQuery ML) under one schema, one backtest contract, and one BigQuery leaderboard — from a handful of series to 100,000+.
|
|
62
|
+
- **Use a simpler path when** a single SQL query (`AI.FORECAST` or `ARIMA_PLUS` directly in BigQuery) already answers the question; you can still adopt `scale-forecasting` later to benchmark that SQL baseline against 35 Python and AutoML models on the same holdout folds.
|
|
63
63
|
|
|
64
64
|
---
|
|
65
65
|
|
|
@@ -160,7 +160,7 @@ Every run is a validated [`RunConfig`](https://github.com/statmike/scale-forecas
|
|
|
160
160
|
| **Data stays in BigQuery** | Workers read source tables via the BigQuery Storage Read API with contiguous per-worker `[start_id, end_id]` pushdown and stream results back through the Storage Write API. | [`docs/reading_source_data.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/reading_source_data.md) · [`docs/writing_results.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/writing_results.md) |
|
|
161
161
|
| **Compute only while it runs** | Active model families launch in parallel (`dag.py`); fast CPU families tear down immediately while GPU families finish; single-VM GCE enforces triple-redundant self-deletion. | [`docs/runtimes_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/runtimes_reference.md) · [`docs/architecture.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/architecture.md) |
|
|
162
162
|
| **Seven runtimes, one contract** | Run `spark`, `ray`, `vertex`, `gce`, `gke`, `vertex_automl`, and `bigquery` concurrently under one `run_id` across CPU and NVIDIA `T4`, `L4`, `A100`, `A100_80GB` GPUs. | [`docs/runtimes_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/runtimes_reference.md) · [`docs/validation.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/validation.md) |
|
|
163
|
-
| **Managed and open models on one leaderboard** | Benchmark BigQuery ML (`ARIMA_PLUS`, `AI.FORECAST` / `
|
|
163
|
+
| **Managed and open models on one leaderboard** | Benchmark BigQuery ML (`ARIMA_PLUS`, `AI.FORECAST` / `timesfm` / `bq_timesfm`) and Vertex AI AutoML alongside 31 open-source statistical, tree, deep learning, and foundation models (`chronos_bolt`, `chronos2`, `timesfm_torch`) on identical folds. | [`docs/models_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/models_reference.md) · [`docs/output_schemas.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/output_schemas.md) |
|
|
164
164
|
| **Governed by construction** | Content-addressed `run_id`, snapshot-pinned reads, 5 registry tables, 5 analytical SQL views, surgical cell repair (`retry_run`), and 42 live-validated smoke configurations. | [`docs/output_schemas.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/output_schemas.md) · [`docs/operations.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/operations.md) · [`docs/validation.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/validation.md) |
|
|
165
165
|
| **Modular install & 1-file extensibility** | `pip install scale-forecasting` has zero Google Cloud dependencies; `[gcp]`, `[spark]`, `[ray]`, `[models]`, and `[all]` are opt-in extras; new models ship in 1 file with no image rebuild. | [`docs/runtime_dependencies.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/runtime_dependencies.md) · [`docs/adding_a_model.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/adding_a_model.md) |
|
|
166
166
|
|
|
@@ -168,17 +168,17 @@ Every run is a validated [`RunConfig`](https://github.com/statmike/scale-forecas
|
|
|
168
168
|
|
|
169
169
|
## What's inside
|
|
170
170
|
|
|
171
|
-
| Family | Models (`
|
|
171
|
+
| Family | Models (`37` total) | Runtimes | Highlights |
|
|
172
172
|
| :--- | :--- | :--- | :--- |
|
|
173
173
|
| **`statistical`** (`18`) | `theta`, `auto_theta`, `holtwinters`, `autoets`, `auto_arima`, `sarimax`, `tbats`, `auto_ces`, `stl_bagging`, `ucm`, `kalman`, `prophet`, `croston`, `fft`, `naive_mean`, `naive_seasonal`, `naive_drift`, `naive_moving_average` | `spark`, `ray`, `vertex`, `gce`, `gke` | Fast local baselines, state-space, intermittent demand, and harmonic decomposition. |
|
|
174
174
|
| **`ml`** (`5`) | `lightgbm`, `xgboost`, `catboost`, `random_forest`, `regression_lags` | `spark`, `ray`, `vertex`, `gce`, `gke` | Lag/calendar/exogenous features plus Tier 1 & Tier 2 TreeSHAP / linear / deviation attributions. |
|
|
175
|
-
| **`deep_learning`** (`
|
|
175
|
+
| **`deep_learning`** (`8`) | `tide`, `tft`, `tsmixer`, `patchtst`, `neuralprophet`, `chronos_bolt`, `chronos2`, `timesfm_torch` | `spark`, `ray`, `vertex`, `gce`, `gke` | Trained PyTorch (`[models-dl]`) and open-weight zero-shot foundation (`[models-foundation]`) models across `local`, `global`, and `hybrid` regimes on CPU or GPU. |
|
|
176
176
|
| **`automl`** (`4`) | `vertex_l2l`, `vertex_tide`, `vertex_tft`, `vertex_seq2seq` | `vertex_automl` | Managed Vertex AI Tabular Workflows & AutoML training jobs with Stage-1 HPO reuse and baseline attributions. |
|
|
177
|
-
| **`native`** (`2`) | `arima_plus
|
|
177
|
+
| **`native`** (`2`) | `arima_plus` (`ARIMA_PLUS` / `ARIMA_PLUS_XREG`), `timesfm` / `bq_timesfm` (`AI.FORECAST`) | `bigquery` | Pure BigQuery SQL execution with future covariates (`ARIMA_PLUS_XREG`), `ML.EXPLAIN_FORECAST` attributions, and zero cluster provisioning. |
|
|
178
178
|
|
|
179
179
|
- **Evaluation, quantiles & calibration:** **21 evaluation metrics** (16 point + 5 interval: `wape`, `smape`, `mape`, `maape`, `ope`, `mae`, `rmse`, `mse`, `rmsle`, `bias`, `mase`, `mase_seasonal`, `rmsse`, `msse`, `r2`, `cv`, `coverage`, `pinball`, `interval_score`, `interval_width`, `msis`), empirical conformal prediction intervals, monotone multi-percentile fans (`output.quantiles` with Chernozhukov rearrangement), and Newsvendor asymmetric cost targets (`underage_cost` / `overage_cost`) ([`docs/metrics_reference.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/metrics_reference.md)).
|
|
180
180
|
- **Hierarchy, smart ensembles & explainability:** All 8 Hyndman FPP3 reconciliation methods (including active-set non-negative `"mint_nonneg"` alongside `mint_shrink`, `wls_var`, `wls_struct`, `ols`, `bottom_up`, `top_down`, `middle_out`), 8 ensemble strategies (`mean`, `median`, `inverse_error`, `champion`, `horizon_specialist`, `nnls`, `ridge`, `xgb`) with `top_k` & `parsimony_margin` pruning and calibrated ensemble intervals, physical bounds (`floor`, `cap`, `cumulative_round`), and two-tier feature attributions (`attributions_df` / `plot_attributions`).
|
|
181
|
-
- **Forecaster workbench, econometrics & executive reports:** Pre-fit data hygiene & SBC demand regime routing (`smooth`, `erratic`, `intermittent`, `lumpy`), Forecast Value Added (`compute_fva`) with Harvey–Leybourne–Newbold (1997) modified Diebold–Mariano $p$-values, lead-time horizon decay, Trigg tracking-signal bias audits, AR(1)-aware time rollups (`rollup_time`), counterfactual promo/price scenario simulation (`simulate_scenarios`), live drift & whipsaw stability scoring, Top-$N$ exception triage (`exceptions_df`), and self-contained interactive HTML/JSON reports (`python -m scale_forecasting.report`) ([`docs/forecaster_workbench.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/forecaster_workbench.md)).
|
|
181
|
+
- **Forecaster workbench, econometrics, inventory policy & executive reports:** Pre-fit data hygiene & SBC demand regime routing (`smooth`, `erratic`, `intermittent`, `lumpy`), Forecast Value Added (`compute_fva`) with Harvey–Leybourne–Newbold (1997) modified Diebold–Mariano $p$-values, lead-time horizon decay, Trigg tracking-signal bias audits, AR(1)-aware time rollups (`rollup_time`) and replenishment policy translators (`compute_inventory_policy` / `inventory_policy_df` for $(s, S)$, $(R, S)$, Fill Rate, and Newsvendor safety stock, reorder point, and EOQ), counterfactual promo/price scenario simulation (`simulate_scenarios`), live drift & whipsaw stability scoring, Top-$N$ exception triage (`exceptions_df`), and self-contained interactive HTML/JSON reports (`python -m scale_forecasting.report`) ([`docs/forecaster_workbench.md`](https://github.com/statmike/scale-forecasting/blob/main/docs/forecaster_workbench.md)).
|
|
182
182
|
|
|
183
183
|
---
|
|
184
184
|
|
|
@@ -205,3 +205,6 @@ All notebooks in [`notebooks/`](https://github.com/statmike/scale-forecasting/bl
|
|
|
205
205
|
## License
|
|
206
206
|
|
|
207
207
|
Apache-2.0 — see [`LICENSE`](https://github.com/statmike/scale-forecasting/blob/main/LICENSE).
|
|
208
|
+
|
|
209
|
+
This is not an officially supported Google product. It is built on Google products and is neither
|
|
210
|
+
endorsed nor supported by Google.
|
|
@@ -1,8 +1,8 @@
|
|
|
1
1
|
[project]
|
|
2
2
|
name = "scale-forecasting"
|
|
3
|
-
version = "1.
|
|
3
|
+
version = "1.2.0"
|
|
4
4
|
description = "Time-series forecasting on Google Cloud at any scale: one JSON configuration runs every model family on Dataproc Serverless, Ray, Vertex AI, GKE, Compute Engine, or BigQuery ML and writes forecasts and leaderboards back to BigQuery."
|
|
5
|
-
|
|
5
|
+
dynamic = ["readme"]
|
|
6
6
|
# Two different pins, on purpose. `requires-python` is what *the package* installs on: the pure
|
|
7
7
|
# layer (models, metrics, backtests, the playground) and the clients run on 3.11 and 3.12, and the
|
|
8
8
|
# CI `core-install` job proves the bare install on each; 3.13 waits on the numpy<2 pin below (1.26
|
|
@@ -26,6 +26,7 @@ keywords = [
|
|
|
26
26
|
"gke",
|
|
27
27
|
"automl",
|
|
28
28
|
"timesfm",
|
|
29
|
+
"chronos",
|
|
29
30
|
]
|
|
30
31
|
classifiers = [
|
|
31
32
|
"Development Status :: 5 - Production/Stable",
|
|
@@ -42,7 +43,7 @@ classifiers = [
|
|
|
42
43
|
"Typing :: Typed",
|
|
43
44
|
]
|
|
44
45
|
|
|
45
|
-
# Core dependencies: the pure forecasting layer — config, the
|
|
46
|
+
# Core dependencies: the pure forecasting layer — config, the 37 model plugins' shared base, the 21
|
|
46
47
|
# metrics, features, backtests, calibration, reconciliation, ensembling, HPO, the worker, and the
|
|
47
48
|
# playground. Nothing here talks to a cloud API. A bare `pip install scale-forecasting` is enough to
|
|
48
49
|
# run `python -m scale_forecasting.playground` on synthetic data with no project, no billing, and
|
|
@@ -160,8 +161,8 @@ submit = [
|
|
|
160
161
|
]
|
|
161
162
|
# Granular model extras for environment agility — install individual model libraries
|
|
162
163
|
# when enterprise environments restrict specific packages, or install `models` for the full suite.
|
|
163
|
-
# 15 of the
|
|
164
|
-
# these extras add the
|
|
164
|
+
# 15 of the 37 models run on the core install alone (numpy / scipy / statsmodels / scikit-learn);
|
|
165
|
+
# these extras add the 20 that need a third-party or cloud library, and the two BigQuery ML models
|
|
165
166
|
# need [gcp]. docs/models_reference.md maps each extra to its models.
|
|
166
167
|
models-stats = [
|
|
167
168
|
"statsforecast>=2.0",
|
|
@@ -185,6 +186,14 @@ models-dl = [
|
|
|
185
186
|
# compatibility lets a 12.6-built wheel run on the 535 driver.
|
|
186
187
|
"torch>=2.13,<2.14",
|
|
187
188
|
]
|
|
189
|
+
# Zero-shot pretrained foundation models (`chronos_bolt`, `chronos2`, `timesfm_torch`). Separated
|
|
190
|
+
# from `models-dl` so users who only want pretrained zero-shot inference (CPU-default, GPU-optional)
|
|
191
|
+
# do not need `neuralprophet` or `neuralforecast`, and vice versa. Both packages depend on `torch`
|
|
192
|
+
# transitively (whose version floor is declared in `models-dl`).
|
|
193
|
+
models-foundation = [
|
|
194
|
+
"chronos-forecasting>=2.2",
|
|
195
|
+
"timesfm[torch]>=3.0",
|
|
196
|
+
]
|
|
188
197
|
# The four Vertex AI AutoML models (vertex_l2l / tide / tft / seq2seq) run as Tabular Workflow
|
|
189
198
|
# pipelines or managed training jobs. The Vertex SDK is in [gcp]; this adds the pipeline components
|
|
190
199
|
# the Tabular Workflow path compiles against.
|
|
@@ -192,10 +201,10 @@ models-automl = [
|
|
|
192
201
|
"scale-forecasting[gcp]",
|
|
193
202
|
"google-cloud-pipeline-components>=2.14",
|
|
194
203
|
]
|
|
195
|
-
# Full optional model suite (statistical + boosted-tree + Prophet + deep-learning +
|
|
196
|
-
# composed from the family extras so every version floor is declared exactly once.
|
|
204
|
+
# Full optional model suite (statistical + boosted-tree + Prophet + deep-learning + foundation +
|
|
205
|
+
# Vertex AutoML), composed from the family extras so every version floor is declared exactly once.
|
|
197
206
|
models = [
|
|
198
|
-
"scale-forecasting[models-stats,models-trees,models-prophet,models-dl,models-automl]",
|
|
207
|
+
"scale-forecasting[models-stats,models-trees,models-prophet,models-dl,models-foundation,models-automl]",
|
|
199
208
|
]
|
|
200
209
|
# Everything: every client, every model library, both on-cluster runtimes, the notebook kernel.
|
|
201
210
|
# This is what `uv sync --all-extras` (CI, `make sync`) resolves to, spelled as one installable name.
|
|
@@ -283,9 +292,16 @@ torch = [
|
|
|
283
292
|
]
|
|
284
293
|
|
|
285
294
|
[build-system]
|
|
286
|
-
requires = ["hatchling"]
|
|
295
|
+
requires = ["hatchling", "hatch-fancy-pypi-readme>=24.1"]
|
|
287
296
|
build-backend = "hatchling.build"
|
|
288
297
|
|
|
298
|
+
[tool.hatch.metadata.hooks.fancy-pypi-readme]
|
|
299
|
+
content-type = "text/markdown"
|
|
300
|
+
fragments = [{ path = "README.md" }]
|
|
301
|
+
substitutions = [
|
|
302
|
+
{ pattern = '```mermaid[\s\S]*?```', replacement = '' },
|
|
303
|
+
]
|
|
304
|
+
|
|
289
305
|
[tool.hatch.build.targets.wheel]
|
|
290
306
|
packages = ["src/scale_forecasting"]
|
|
291
307
|
exclude = ["src/scale_forecasting/**/README.md"]
|
|
@@ -293,6 +309,7 @@ exclude = ["src/scale_forecasting/**/README.md"]
|
|
|
293
309
|
[tool.hatch.build.targets.sdist]
|
|
294
310
|
only-include = [
|
|
295
311
|
"src/scale_forecasting",
|
|
312
|
+
"README.md",
|
|
296
313
|
"CHANGELOG.md",
|
|
297
314
|
]
|
|
298
315
|
exclude = ["src/scale_forecasting/**/README.md"]
|
|
@@ -347,6 +364,9 @@ module = [
|
|
|
347
364
|
"prophet.*",
|
|
348
365
|
"neuralprophet.*",
|
|
349
366
|
"neuralforecast.*",
|
|
367
|
+
"chronos.*",
|
|
368
|
+
"timesfm.*",
|
|
369
|
+
"timesfm3.*",
|
|
350
370
|
"sklearn.*",
|
|
351
371
|
"google_cloud_pipeline_components.*",
|
|
352
372
|
"kfp.*",
|
|
@@ -53,7 +53,7 @@ from .settings import Settings
|
|
|
53
53
|
try:
|
|
54
54
|
__version__: str = _pkg_version("scale-forecasting")
|
|
55
55
|
except PackageNotFoundError: # pragma: no cover - zip-staged cloud worker without .dist-info
|
|
56
|
-
__version__ = "1.
|
|
56
|
+
__version__ = "1.2.0"
|
|
57
57
|
|
|
58
58
|
# Lazy (heavy): name -> (module, attribute). Resolved on first access by ``__getattr__`` (PEP 562)
|
|
59
59
|
# so the model modules (statsmodels et al., ~5s) load only when a caller actually reaches for the
|
|
@@ -136,9 +136,13 @@ _LAZY: dict[str, tuple[str, str]] = {
|
|
|
136
136
|
"compute_realized_accuracy": (".diagnostics", "compute_realized_accuracy"),
|
|
137
137
|
"compute_revision_stability": (".diagnostics", "compute_revision_stability"),
|
|
138
138
|
"compute_exceptions_queue": (".diagnostics", "compute_exceptions_queue"),
|
|
139
|
+
"compute_anomalies": (".diagnostics", "compute_anomalies"),
|
|
140
|
+
"compute_change_points": (".diagnostics", "compute_change_points"),
|
|
141
|
+
"compute_inventory_policy": (".diagnostics", "compute_inventory_policy"),
|
|
139
142
|
"rollup_time": (".diagnostics", "rollup_time"),
|
|
140
143
|
"plot_fva": (".diagnostics", "plot_fva"),
|
|
141
144
|
"plot_horizon_decay": (".diagnostics", "plot_horizon_decay"),
|
|
145
|
+
"plot_inventory_policy": (".diagnostics", "plot_inventory_policy"),
|
|
142
146
|
"apply_scenario_shocks": (".scenarios", "apply_scenario_shocks"),
|
|
143
147
|
"simulate_scenarios": (".scenarios", "simulate_scenarios"),
|
|
144
148
|
"summarize_scenarios": (".scenarios", "summarize_scenarios"),
|
|
@@ -172,15 +176,19 @@ if TYPE_CHECKING: # so IDEs / type-checkers see the lazy names as real imports
|
|
|
172
176
|
from .agent_surfaces import probe_environment # noqa: F401
|
|
173
177
|
from .dag import DagNode # noqa: F401
|
|
174
178
|
from .diagnostics import ( # noqa: F401
|
|
179
|
+
compute_anomalies,
|
|
175
180
|
compute_bias_report,
|
|
181
|
+
compute_change_points,
|
|
176
182
|
compute_exceptions_queue,
|
|
177
183
|
compute_fva,
|
|
178
184
|
compute_horizon_decay,
|
|
185
|
+
compute_inventory_policy,
|
|
179
186
|
compute_realized_accuracy,
|
|
180
187
|
compute_revision_stability,
|
|
181
188
|
diebold_mariano_test,
|
|
182
189
|
plot_fva,
|
|
183
190
|
plot_horizon_decay,
|
|
191
|
+
plot_inventory_policy,
|
|
184
192
|
rollup_time,
|
|
185
193
|
wilcoxon_pvalue,
|
|
186
194
|
)
|