readystack-robots-txt-ai-crawler-audit 0.1.8__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- readystack_robots_txt_ai_crawler_audit-0.1.8/LICENSE.txt +2 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/PKG-INFO +84 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/README.md +64 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/pyproject.toml +29 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/setup.cfg +4 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/__init__.py +1 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/__main__.py +12 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/js/cli.js +164 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/js/license.js +103 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/js/package.json +38 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/js/rules.json +119 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/js/strings.json +10 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit.egg-info/PKG-INFO +84 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit.egg-info/SOURCES.txt +16 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit.egg-info/dependency_links.txt +1 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit.egg-info/entry_points.txt +2 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit.egg-info/requires.txt +1 -0
- readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit.egg-info/top_level.txt +1 -0
|
@@ -0,0 +1,84 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: readystack-robots-txt-ai-crawler-audit
|
|
3
|
+
Version: 0.1.8
|
|
4
|
+
Summary: Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing. (bundled Node.js runtime)
|
|
5
|
+
Author-email: ReadyStack <support@getreadystack.com>
|
|
6
|
+
License: Proprietary - see LICENSE.txt
|
|
7
|
+
Project-URL: Homepage, https://getreadystack.com/tools/robots-txt-ai-crawler-audit?ref=pypi
|
|
8
|
+
Project-URL: Documentation, https://getreadystack.com/tools/robots-txt-ai-crawler-audit?ref=pypi
|
|
9
|
+
Project-URL: Support, https://getreadystack.com/support
|
|
10
|
+
Keywords: robots.txt,AI crawler,GPTBot,Google-Extended,SEO
|
|
11
|
+
Classifier: Programming Language :: Python :: 3
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Topic :: Software Development :: Quality Assurance
|
|
14
|
+
Classifier: Operating System :: OS Independent
|
|
15
|
+
Requires-Python: >=3.9
|
|
16
|
+
Description-Content-Type: text/markdown
|
|
17
|
+
License-File: LICENSE.txt
|
|
18
|
+
Requires-Dist: nodejs-wheel-binaries>=20
|
|
19
|
+
Dynamic: license-file
|
|
20
|
+
|
|
21
|
+
# AI Crawler Rules - robots.txt Audit for AI Search
|
|
22
|
+
|
|
23
|
+
> Runs the same checker as the npm package `@readystack/robots-txt-ai-crawler-audit` on a Node.js runtime that pip installs for you (`nodejs-wheel-binaries`) - no system Node.js needed. Your files are checked locally.
|
|
24
|
+
|
|
25
|
+
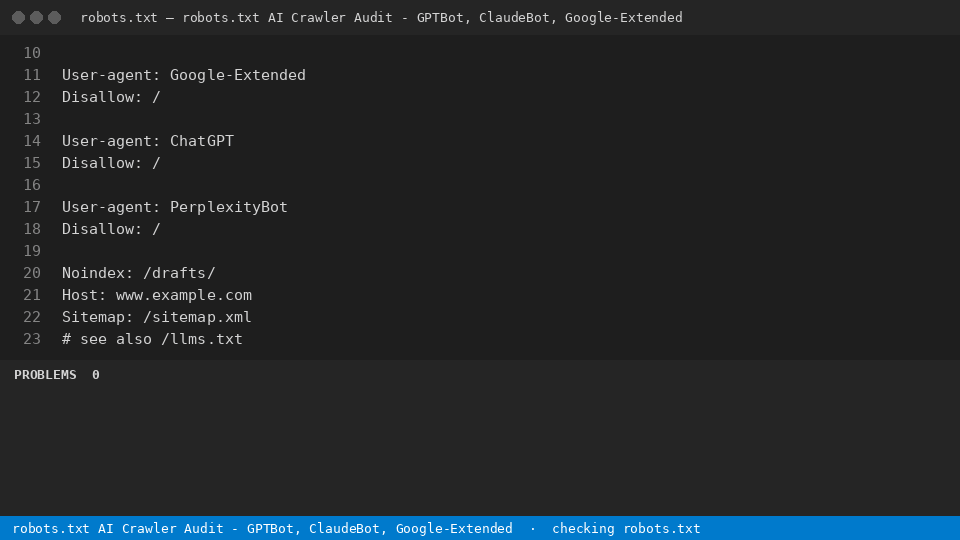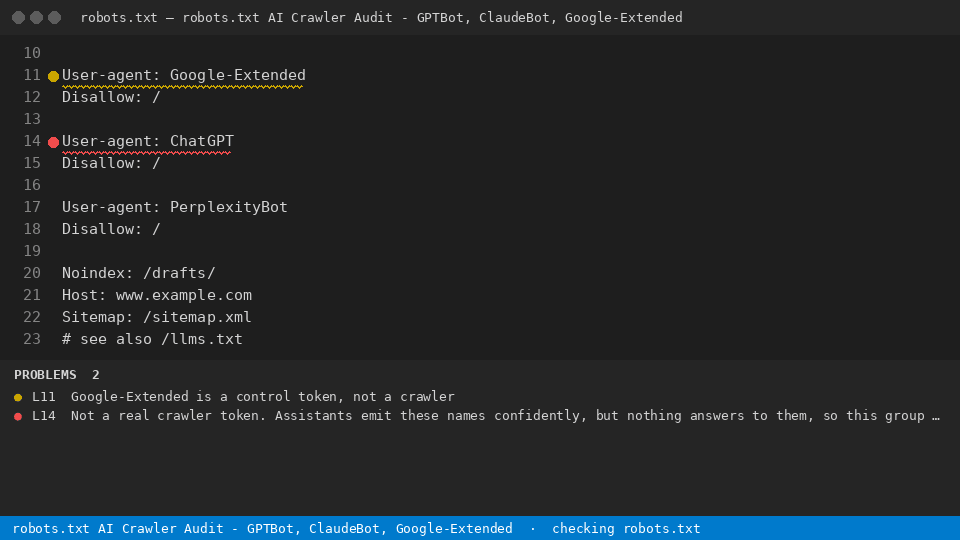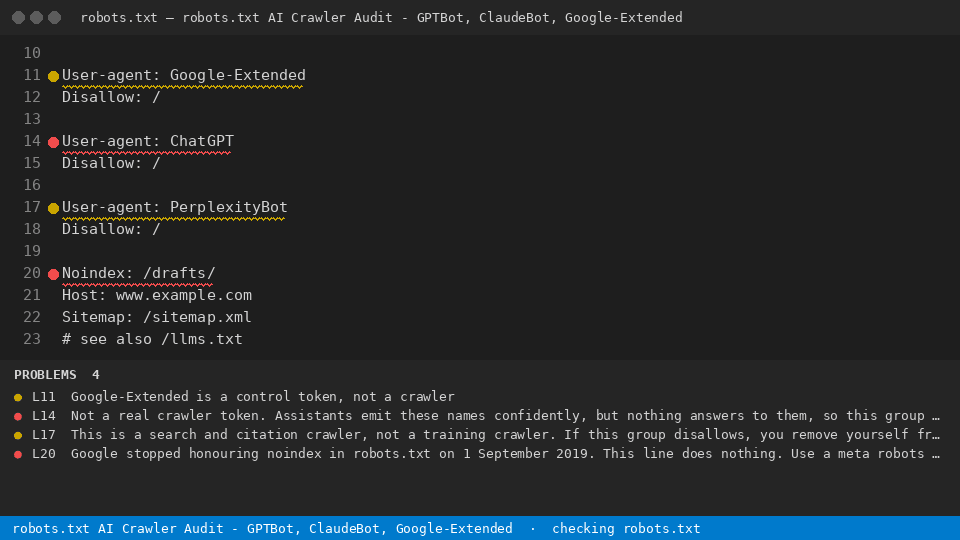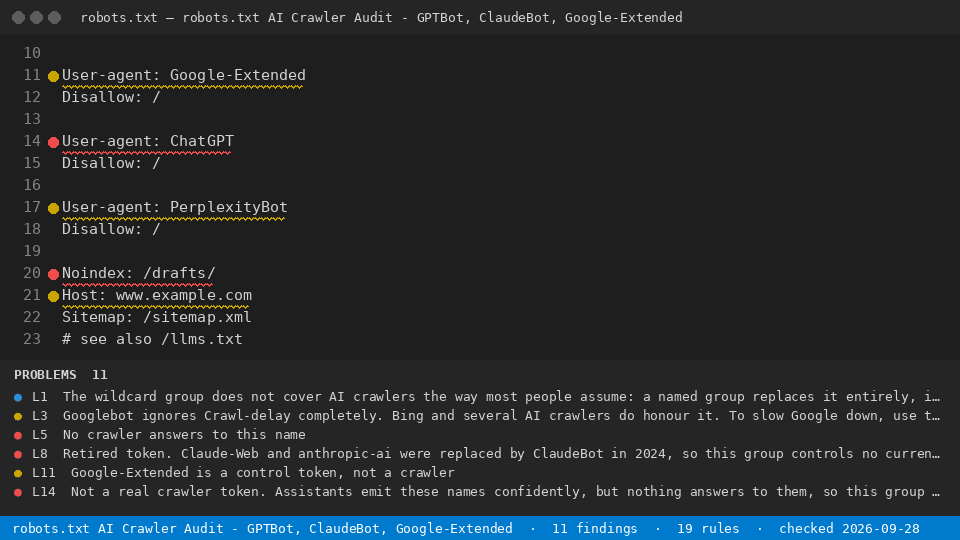
|
|
26
|
+
|
|
27
|
+
Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing.
|
|
28
|
+
|
|
29
|
+
## Install
|
|
30
|
+
|
|
31
|
+
```
|
|
32
|
+
robots-txt-ai-crawler-audit file
|
|
33
|
+
```
|
|
34
|
+
|
|
35
|
+
Node 18+. The same 19 rules as the VS Code extension, from a terminal or CI.
|
|
36
|
+
|
|
37
|
+
## Free
|
|
38
|
+
|
|
39
|
+
- Check the open robots.txt against every rule - full results, nothing withheld; Check only the lines you highlight; See every rule and what each AI token controls; Reopen the last report
|
|
40
|
+
- `--rules` lists every rule
|
|
41
|
+
|
|
42
|
+
## With a licence ($29 once)
|
|
43
|
+
|
|
44
|
+
- Scan every robots.txt in the workspace; Export the report as CSV, JSON or HTML; CI output that fails the build on errors; Add your own agency policy tokens; Re-check automatically on every save
|
|
45
|
+
|
|
46
|
+
```
|
|
47
|
+
@readystack/robots-txt-ai-crawler-audit --dir ./templates --report html --out report.html
|
|
48
|
+
```
|
|
49
|
+
|
|
50
|
+
A freelance technical SEO consultant bills roughly $100-150 an hour, and an AI-crawler robots.txt review is a one-to-two hour job.
|
|
51
|
+
|
|
52
|
+
## Use from an AI agent (MCP)
|
|
53
|
+
|
|
54
|
+
Claude Code · Cursor · Windsurf · any MCP client - add to your MCP config:
|
|
55
|
+
|
|
56
|
+
```json
|
|
57
|
+
{ "mcpServers": { "robots-txt-ai-crawler-audit": { "command": "npx", "args": ["-y", "@readystack/robots-txt-ai-crawler-audit", "--mcp"] } } }
|
|
58
|
+
```
|
|
59
|
+
|
|
60
|
+
Tools: `check_text` and `check_file` (free) · `check_dir` (licence). The agent gets every finding with the line number.
|
|
61
|
+
|
|
62
|
+
## Use in CI
|
|
63
|
+
|
|
64
|
+
```yaml
|
|
65
|
+
- name: AI Crawler Rules - robots.txt Audit for AI Search
|
|
66
|
+
run: npx -y @readystack/robots-txt-ai-crawler-audit --dir . --ci
|
|
67
|
+
```
|
|
68
|
+
|
|
69
|
+
(container: `docker run --rm -v "$PWD:/work" getreadystack/robots-txt-ai-crawler-audit --dir /work --ci`)
|
|
70
|
+
|
|
71
|
+
The folder sweep, reports and CI mode need one licence — one payment, no subscription. Set `READYSTACK_LICENSE=<key>` or run `--license <key>` once.
|
|
72
|
+
|
|
73
|
+
[Get a licence](https://getreadystack.com/api/buy/cl/polar_cl_I8R8AzowzmASHy45ujvewcvtcl4wBBfC2Fe7r3fZwpr)
|
|
74
|
+
|
|
75
|
+
|
|
76
|
+
<!-- ai crawler rules for robots txt -->
|
|
77
|
+
|
|
78
|
+
|
|
79
|
+
## Install (PyPI)
|
|
80
|
+
|
|
81
|
+
```
|
|
82
|
+
pip install readystack-robots-txt-ai-crawler-audit
|
|
83
|
+
robots-txt-ai-crawler-audit --help
|
|
84
|
+
```
|
|
@@ -0,0 +1,64 @@
|
|
|
1
|
+
# AI Crawler Rules - robots.txt Audit for AI Search
|
|
2
|
+
|
|
3
|
+
> Runs the same checker as the npm package `@readystack/robots-txt-ai-crawler-audit` on a Node.js runtime that pip installs for you (`nodejs-wheel-binaries`) - no system Node.js needed. Your files are checked locally.
|
|
4
|
+
|
|
5
|
+

|
|
6
|
+
|
|
7
|
+
Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing.
|
|
8
|
+
|
|
9
|
+
## Install
|
|
10
|
+
|
|
11
|
+
```
|
|
12
|
+
robots-txt-ai-crawler-audit file
|
|
13
|
+
```
|
|
14
|
+
|
|
15
|
+
Node 18+. The same 19 rules as the VS Code extension, from a terminal or CI.
|
|
16
|
+
|
|
17
|
+
## Free
|
|
18
|
+
|
|
19
|
+
- Check the open robots.txt against every rule - full results, nothing withheld; Check only the lines you highlight; See every rule and what each AI token controls; Reopen the last report
|
|
20
|
+
- `--rules` lists every rule
|
|
21
|
+
|
|
22
|
+
## With a licence ($29 once)
|
|
23
|
+
|
|
24
|
+
- Scan every robots.txt in the workspace; Export the report as CSV, JSON or HTML; CI output that fails the build on errors; Add your own agency policy tokens; Re-check automatically on every save
|
|
25
|
+
|
|
26
|
+
```
|
|
27
|
+
@readystack/robots-txt-ai-crawler-audit --dir ./templates --report html --out report.html
|
|
28
|
+
```
|
|
29
|
+
|
|
30
|
+
A freelance technical SEO consultant bills roughly $100-150 an hour, and an AI-crawler robots.txt review is a one-to-two hour job.
|
|
31
|
+
|
|
32
|
+
## Use from an AI agent (MCP)
|
|
33
|
+
|
|
34
|
+
Claude Code · Cursor · Windsurf · any MCP client - add to your MCP config:
|
|
35
|
+
|
|
36
|
+
```json
|
|
37
|
+
{ "mcpServers": { "robots-txt-ai-crawler-audit": { "command": "npx", "args": ["-y", "@readystack/robots-txt-ai-crawler-audit", "--mcp"] } } }
|
|
38
|
+
```
|
|
39
|
+
|
|
40
|
+
Tools: `check_text` and `check_file` (free) · `check_dir` (licence). The agent gets every finding with the line number.
|
|
41
|
+
|
|
42
|
+
## Use in CI
|
|
43
|
+
|
|
44
|
+
```yaml
|
|
45
|
+
- name: AI Crawler Rules - robots.txt Audit for AI Search
|
|
46
|
+
run: npx -y @readystack/robots-txt-ai-crawler-audit --dir . --ci
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
(container: `docker run --rm -v "$PWD:/work" getreadystack/robots-txt-ai-crawler-audit --dir /work --ci`)
|
|
50
|
+
|
|
51
|
+
The folder sweep, reports and CI mode need one licence — one payment, no subscription. Set `READYSTACK_LICENSE=<key>` or run `--license <key>` once.
|
|
52
|
+
|
|
53
|
+
[Get a licence](https://getreadystack.com/api/buy/cl/polar_cl_I8R8AzowzmASHy45ujvewcvtcl4wBBfC2Fe7r3fZwpr)
|
|
54
|
+
|
|
55
|
+
|
|
56
|
+
<!-- ai crawler rules for robots txt -->
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
## Install (PyPI)
|
|
60
|
+
|
|
61
|
+
```
|
|
62
|
+
pip install readystack-robots-txt-ai-crawler-audit
|
|
63
|
+
robots-txt-ai-crawler-audit --help
|
|
64
|
+
```
|
|
@@ -0,0 +1,29 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["setuptools>=68"]
|
|
3
|
+
build-backend = "setuptools.build_meta"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "readystack-robots-txt-ai-crawler-audit"
|
|
7
|
+
version = "0.1.8"
|
|
8
|
+
description = "Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing. (bundled Node.js runtime)"
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
requires-python = ">=3.9"
|
|
11
|
+
dependencies = ["nodejs-wheel-binaries>=20"]
|
|
12
|
+
license = {text = "Proprietary - see LICENSE.txt"}
|
|
13
|
+
keywords = ["robots.txt", "AI crawler", "GPTBot", "Google-Extended", "SEO"]
|
|
14
|
+
authors = [{name = "ReadyStack", email = "support@getreadystack.com"}]
|
|
15
|
+
classifiers = ["Programming Language :: Python :: 3", "Environment :: Console", "Topic :: Software Development :: Quality Assurance", "Operating System :: OS Independent"]
|
|
16
|
+
|
|
17
|
+
[project.urls]
|
|
18
|
+
Homepage = "https://getreadystack.com/tools/robots-txt-ai-crawler-audit?ref=pypi"
|
|
19
|
+
Documentation = "https://getreadystack.com/tools/robots-txt-ai-crawler-audit?ref=pypi"
|
|
20
|
+
Support = "https://getreadystack.com/support"
|
|
21
|
+
|
|
22
|
+
[project.scripts]
|
|
23
|
+
"robots-txt-ai-crawler-audit" = "readystack_robots_txt_ai_crawler_audit.__main__:main"
|
|
24
|
+
|
|
25
|
+
[tool.setuptools.packages.find]
|
|
26
|
+
where = ["src"]
|
|
27
|
+
|
|
28
|
+
[tool.setuptools.package-data]
|
|
29
|
+
"readystack_robots_txt_ai_crawler_audit" = ["js/*"]
|
readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
1
|
+
__version__ = '0.1.8'
|
readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/__main__.py
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
1
|
+
import os, sys
|
|
2
|
+
|
|
3
|
+
|
|
4
|
+
def main():
|
|
5
|
+
# Runs the same checker as the npm package on the Node.js runtime installed with this package (nodejs-wheel-binaries).
|
|
6
|
+
from nodejs_wheel import node
|
|
7
|
+
here = os.path.dirname(os.path.abspath(__file__))
|
|
8
|
+
return node([os.path.join(here, "js", "cli.js")] + sys.argv[1:])
|
|
9
|
+
|
|
10
|
+
|
|
11
|
+
if __name__ == "__main__":
|
|
12
|
+
sys.exit(main())
|
readystack_robots_txt_ai_crawler_audit-0.1.8/src/readystack_robots_txt_ai_crawler_audit/js/cli.js
ADDED
|
@@ -0,0 +1,164 @@
|
|
|
1
|
+
#!/usr/bin/env node
|
|
2
|
+
// cli.js — the same rules as the VS Code extension, run from a terminal or a container. Generated by adapters.py.
|
|
3
|
+
'use strict';
|
|
4
|
+
const fs = require('fs'), path = require('path');
|
|
5
|
+
const RULES = require('./rules.json');
|
|
6
|
+
const S = require('./strings.json');
|
|
7
|
+
const lic = require('./license.js');
|
|
8
|
+
function scan(text) {
|
|
9
|
+
const lines = String(text).split(/\r?\n/); const hits = [];
|
|
10
|
+
for (let i = 0; i < lines.length; i++) {
|
|
11
|
+
for (const r of RULES) {
|
|
12
|
+
let re; try { re = new RegExp(r.pattern, r.flags || ''); } catch (e) { continue; }
|
|
13
|
+
if (re.test(lines[i])) hits.push({ line: i + 1, msg: r.message, fix: r.fix || null, sev: r.sev || 'warn' });
|
|
14
|
+
}
|
|
15
|
+
}
|
|
16
|
+
return hits;
|
|
17
|
+
}
|
|
18
|
+
function isText(p) { try { const b = fs.readFileSync(p); if (b.length > 2 * 1024 * 1024) return false; const s = b.subarray(0, 4096); for (const x of s) if (x === 0) return false; return true; } catch (e) { return false; } }
|
|
19
|
+
function walk(dir, exts, out) {
|
|
20
|
+
let ents = []; try { ents = fs.readdirSync(dir, { withFileTypes: true }); } catch (e) { return out; }
|
|
21
|
+
for (const e of ents) {
|
|
22
|
+
if (['node_modules', '.git', '.hg', '.svn', '.venv', 'venv', '.tox', '.cache', '.next', '.nuxt', '.terraform', '__pycache__'].includes(e.name)) continue; // s158 — .github · .gitlab-ci.yml · .env · .well-known 은 본다 (옛 줄은 점으로 시작하는 것을 전부 건너뛰어 워크플로 검사기가 .github/workflows 를 못 봤다)
|
|
23
|
+
const p = path.join(dir, e.name);
|
|
24
|
+
if (e.isDirectory()) walk(p, exts, out);
|
|
25
|
+
else if ((!exts.length || exts.includes(path.extname(e.name).toLowerCase())) && isText(p)) out.push(p);
|
|
26
|
+
}
|
|
27
|
+
return out;
|
|
28
|
+
}
|
|
29
|
+
function esc(s) { return String(s).replace(/&/g, '&').replace(/</g, '<').replace(/>/g, '>'); }
|
|
30
|
+
function csvq(s) { return '"' + String(s == null ? '' : s).replace(/"/g, '""') + '"'; }
|
|
31
|
+
function render(rows, fmt) {
|
|
32
|
+
if (fmt === 'json') return JSON.stringify({ tool: S.name, rules: RULES.length, files: rows }, null, 1);
|
|
33
|
+
if (fmt === 'csv') { const o = ['file,line,severity,message,fix']; for (const r of rows) for (const h of r.hits) o.push([csvq(r.file), h.line, h.sev, csvq(h.msg), csvq(h.fix)].join(',')); return o.join('\n') + '\n'; }
|
|
34
|
+
if (fmt === 'html') {
|
|
35
|
+
const n = rows.reduce((a, r) => a + r.hits.length, 0);
|
|
36
|
+
let o = '<!doctype html><meta charset="utf-8"><title>' + esc(S.name) + ' report</title><style>body{font:14px system-ui;margin:24px}table{border-collapse:collapse}td,th{border:1px solid #ddd;padding:4px 8px;font-size:13px}code{font-family:ui-monospace,monospace}</style>';
|
|
37
|
+
o += '<h1>' + esc(S.name) + '</h1><p>' + rows.length + ' files · ' + n + ' findings · ' + RULES.length + ' rules</p><table><tr><th>file</th><th>line</th><th>sev</th><th>message</th><th>fix</th></tr>';
|
|
38
|
+
for (const r of rows) for (const h of r.hits) o += '<tr><td><code>' + esc(r.file) + '</code></td><td>' + h.line + '</td><td>' + esc(h.sev) + '</td><td>' + esc(h.msg) + '</td><td>' + esc(h.fix || '') + '</td></tr>';
|
|
39
|
+
return o + '</table>';
|
|
40
|
+
}
|
|
41
|
+
let o = ''; for (const r of rows) { o += r.file + '\n'; for (const h of r.hits) o += ' ' + String(h.line).padStart(5) + ' ' + h.sev.padEnd(5) + ' ' + h.msg + (h.fix ? '\n -> ' + h.fix : '') + '\n'; if (!r.hits.length) o += ' (no findings)\n'; }
|
|
42
|
+
return o;
|
|
43
|
+
}
|
|
44
|
+
function trialState() {
|
|
45
|
+
// s158 — ⚑7일 무료 없음: 새 체험은 ⛔열지 않는다 · 이미 시작된 체험(trial.json)만 끝까지 지킨다 (읽기 전용)
|
|
46
|
+
if (process.env.READYSTACK_NO_TRIAL) return { active: false };
|
|
47
|
+
try {
|
|
48
|
+
const p = path.join(path.dirname(lic.storePath()), S.bin + '.trial.json');
|
|
49
|
+
const t = JSON.parse(fs.readFileSync(p, 'utf8'));
|
|
50
|
+
return { active: !!(t && t.until) && new Date(t.until + 'T23:59:59Z').getTime() > Date.now(), until: t && t.until };
|
|
51
|
+
} catch (e) { return { active: false }; }
|
|
52
|
+
}
|
|
53
|
+
// ★s158 2026-09-23 — the free run SPEAKS about the rest of the folder (vsix: auto.js · crx: welcome tab).
|
|
54
|
+
// The answer for the named files is complete and free; the next step is shown with the user's OWN numbers:
|
|
55
|
+
// "this folder has N more matching files - M issues in K of them" + the one command that sweeps them.
|
|
56
|
+
// Never blocks, never starts a trial (s158: no free trial - the free answer on the named files is the "try it"), human seat only, 400 files / 1.5 s cap.
|
|
57
|
+
function folderHint(done) {
|
|
58
|
+
if (!process.stderr.isTTY || process.env.CI || process.env.READYSTACK_NO_HINT || !done.length) return;
|
|
59
|
+
const base = path.dirname(path.resolve(done[0]));
|
|
60
|
+
const seen = new Set(done.map((f) => path.resolve(f)));
|
|
61
|
+
const all = walk(base, S.exts || [], []).filter((f) => !seen.has(path.resolve(f)));
|
|
62
|
+
if (!all.length) return;
|
|
63
|
+
const t0 = Date.now(); let issues = 0, hitFiles = 0, scanned = 0;
|
|
64
|
+
for (const f of all.slice(0, 400)) { if (Date.now() - t0 > 1500) break; let t = ''; try { t = fs.readFileSync(f, 'utf8'); } catch (e) { continue; } scanned++; const h = scan(t, f); if (h.length) { issues += h.length; hitFiles++; } }
|
|
65
|
+
const rel = path.relative(process.cwd(), base) || '.';
|
|
66
|
+
const tail = trialState().active ? 'free during your trial' : '$' + S.price + ' once';
|
|
67
|
+
const more = all.length + ' more matching file' + (all.length > 1 ? 's' : '');
|
|
68
|
+
const found = issues ? ' - ' + (scanned < all.length ? 'at least ' : '') + issues + ' issue' + (issues > 1 ? 's' : '') + ' in ' + hitFiles + ' of them' : ' - no issues found in them';
|
|
69
|
+
process.stderr.write('\n' + (rel === '.' ? 'This folder' : rel) + ' has ' + more + found + '.\n' + (issues ? 'Sweep them all: ' + S.bin + ' --dir ' + (/\s/.test(rel) ? JSON.stringify(rel) : rel) + ' (' + tail + ')\n' : ''));
|
|
70
|
+
}
|
|
71
|
+
let _usePinged = false;
|
|
72
|
+
function pingUse() {
|
|
73
|
+
try {
|
|
74
|
+
if (_usePinged) return; _usePinged = true;
|
|
75
|
+
if (process.env.DO_NOT_TRACK === '1' || process.env.READYSTACK_NO_TELEMETRY || process.env.CI) return;
|
|
76
|
+
if (!(process.stdout.isTTY || process.stdin.isTTY)) return; // human seat only (s152)
|
|
77
|
+
const https = require('https');
|
|
78
|
+
const body = JSON.stringify({ t: 'use', slug: S.bin, src: 'cli', why: 'free' });
|
|
79
|
+
const req = https.request({ hostname: 'getreadystack.com', path: '/api/ev', method: 'POST', timeout: 3000,
|
|
80
|
+
headers: { 'content-type': 'application/json', 'content-length': Buffer.byteLength(body), 'user-agent': 'readystack-cli/' + S.bin } }, function (res) { res.resume(); });
|
|
81
|
+
req.on('timeout', function () { req.destroy(); }); req.on('error', function () {});
|
|
82
|
+
req.write(body); req.end();
|
|
83
|
+
} catch (e) {}
|
|
84
|
+
}
|
|
85
|
+
function mcpServe() {
|
|
86
|
+
process.env.READYSTACK_MCP = '1'; // s152 - 에이전트(Claude Code·Cursor)가 부른 세션은 사람 자리다 · 키 판 핑 src=mcp
|
|
87
|
+
// s144 — MCP server over stdio (newline-delimited JSON-RPC · no dependencies). Free: check_text · check_file. Licence (s158: no free trial): check_dir.
|
|
88
|
+
const rl = require('readline').createInterface({ input: process.stdin });
|
|
89
|
+
const send = (o) => process.stdout.write(JSON.stringify(o) + '\n');
|
|
90
|
+
const tools = [
|
|
91
|
+
{ name: 'check_text', description: S.name + ' - run all ' + RULES.length + ' checks on a text (free)', inputSchema: { type: 'object', properties: { text: { type: 'string', description: 'file contents' }, path: { type: 'string', description: 'optional file name for context' } }, required: ['text'] } },
|
|
92
|
+
{ name: 'check_file', description: S.name + ' - run all checks on one file by path (free)', inputSchema: { type: 'object', properties: { path: { type: 'string' } }, required: ['path'] } },
|
|
93
|
+
{ name: 'check_dir', description: S.name + ' - sweep a folder and return every finding (licence; $' + S.price + ' once)', inputSchema: { type: 'object', properties: { dir: { type: 'string' }, ext: { type: 'string', description: 'optional extension filter, e.g. .html' } }, required: ['dir'] } }
|
|
94
|
+
];
|
|
95
|
+
const result = (id, rows) => send({ jsonrpc: '2.0', id, result: { content: [{ type: 'text', text: render(rows, 'text') }], structuredContent: { tool: S.name, rules: RULES.length, files: rows } } });
|
|
96
|
+
const fail = (id, text) => send({ jsonrpc: '2.0', id, result: { content: [{ type: 'text', text }], isError: true } });
|
|
97
|
+
rl.on('line', async (line) => {
|
|
98
|
+
let m; try { m = JSON.parse(line); } catch (e) { return; }
|
|
99
|
+
const id = m.id, method = m.method;
|
|
100
|
+
if (method === 'initialize') return send({ jsonrpc: '2.0', id, result: { protocolVersion: '2025-06-18', capabilities: { tools: {} }, serverInfo: { name: '@readystack/' + S.bin, version: '1.0.0' } } });
|
|
101
|
+
if (method === 'notifications/initialized' || method === 'ping') { if (id !== undefined) send({ jsonrpc: '2.0', id, result: {} }); return; }
|
|
102
|
+
if (method === 'tools/list') return send({ jsonrpc: '2.0', id, result: { tools } });
|
|
103
|
+
if (method === 'tools/call') {
|
|
104
|
+
const name = (m.params || {}).name, args = (m.params || {}).arguments || {};
|
|
105
|
+
try {
|
|
106
|
+
if (name === 'check_text') return result(id, [{ file: args.path || '(text)', hits: scan(String(args.text || ''), args.path || '') }]);
|
|
107
|
+
if (name === 'check_file') return result(id, [{ file: args.path, hits: scan(fs.readFileSync(args.path, 'utf8'), args.path) }]);
|
|
108
|
+
if (name === 'check_dir') {
|
|
109
|
+
const r = await lic.ensure();
|
|
110
|
+
if (!r.ok && !trialState().active) return fail(id, S.need_key + ' Get a licence ($' + S.price + ', once): ' + lic.BUY_URL);
|
|
111
|
+
const files = walk(args.dir, args.ext ? [args.ext] : (S.exts || []), []);
|
|
112
|
+
return result(id, files.map((f) => { let t = ''; try { t = fs.readFileSync(f, 'utf8'); } catch (e) { return { file: f, hits: [], error: String(e.message) }; } return { file: f, hits: scan(t, f) }; }));
|
|
113
|
+
}
|
|
114
|
+
return send({ jsonrpc: '2.0', id, error: { code: -32601, message: 'unknown tool ' + name } });
|
|
115
|
+
} catch (e) { return fail(id, String(e && e.message || e)); }
|
|
116
|
+
}
|
|
117
|
+
if (id !== undefined) send({ jsonrpc: '2.0', id, error: { code: -32601, message: 'method not found: ' + method } });
|
|
118
|
+
});
|
|
119
|
+
}
|
|
120
|
+
function help() {
|
|
121
|
+
return [S.name + ' - ' + S.subtitle, '', 'Usage: ' + S.bin + ' <file> [more files] check the files you name (free, every rule)',
|
|
122
|
+
' ' + S.bin + ' --dir <folder> [--ext .html] scan a whole folder (licence)',
|
|
123
|
+
' ' + S.bin + ' ... --report csv|json|html [--out file] export a report (licence)',
|
|
124
|
+
' ' + S.bin + ' ... --ci exit 1 when an error-level finding exists (licence)',
|
|
125
|
+
' ' + S.bin + ' --license <key> store your licence key (or set READYSTACK_LICENSE)',
|
|
126
|
+
' ' + S.bin + ' --rules list the ' + RULES.length + ' rules',
|
|
127
|
+
' ' + S.bin + ' --mcp run as an MCP server (stdio) for Claude Code / Cursor / Windsurf - free checks, folder sweep needs a licence', '',
|
|
128
|
+
'Free: ' + S.free, 'Licence ($' + S.price + ', once): ' + S.paid, 'Get a licence: ' + lic.BUY_URL, ''].join('\n');
|
|
129
|
+
}
|
|
130
|
+
(async function main() {
|
|
131
|
+
try { const _feed = await lic.pullFeed(); if (_feed && Array.isArray(_feed.rules)) { for (const r of _feed.rules) RULES.push(r); } } catch (e) {} // ★s134 구독 피드 병합 (키 있는 손님만)
|
|
132
|
+
const a = process.argv.slice(2);
|
|
133
|
+
const get = (k) => { const i = a.indexOf(k); return i >= 0 ? a[i + 1] : null; };
|
|
134
|
+
if (a.includes('--mcp')) { mcpServe(); return; }
|
|
135
|
+
if (!a.length || a.includes('--help') || a.includes('-h')) { process.stdout.write(help()); return; }
|
|
136
|
+
if (a.includes('--rules')) { process.stdout.write(RULES.map((r, i) => String(i + 1).padStart(3) + ' [' + (r.sev || 'warn') + '] ' + r.message).join('\n') + '\n'); return; }
|
|
137
|
+
if (a.includes('--license')) { const r = await lic.ensure(get('--license')); process.stdout.write(r.ok ? 'Licence stored: ' + lic.storePath() + '\n' : 'Licence not accepted (' + r.why + '). Get one: ' + lic.BUY_URL + '\n'); process.exit(r.ok ? 0 : 2); }
|
|
138
|
+
const dir = get('--dir'), fmt = get('--report'), out = get('--out'), ci = a.includes('--ci');
|
|
139
|
+
const exts = a.includes('--ext') ? [get('--ext')] : (S.exts || []);
|
|
140
|
+
const paid = !!(dir || fmt || ci);
|
|
141
|
+
if (paid) {
|
|
142
|
+
const r = await lic.ensure();
|
|
143
|
+
if (!r.ok) {
|
|
144
|
+
const t = trialState(); // s158 — ⚑7일 무료 없음 · 이미 시작된 체험만 지킨다
|
|
145
|
+
if (t.active) process.stderr.write('Trial: the full run is free until ' + t.until + ' — after that $' + S.price + ' once. Get a licence: ' + lic.BUY_URL + '\n');
|
|
146
|
+
else {
|
|
147
|
+
// s158 — the key is asked WITH the customer's own count (endowment · open loop): how many issues this folder holds.
|
|
148
|
+
let own = '';
|
|
149
|
+
if (dir) { try { const all = walk(dir, exts, []); let n = 0, k = 0, sc = 0; const t0 = Date.now();
|
|
150
|
+
for (const f of all.slice(0, 2000)) { if (Date.now() - t0 > 4000) break; let tx = ''; try { tx = fs.readFileSync(f, 'utf8'); } catch (e) { continue; } sc++; const h = scan(tx, f); if (h.length) { n += h.length; k++; } }
|
|
151
|
+
if (n) own = dir + ': ' + (sc < all.length ? 'at least ' : '') + n + ' issue' + (n > 1 ? 's' : '') + ' in ' + k + ' of ' + all.length + ' files.\n'; } catch (e) {} }
|
|
152
|
+
process.stderr.write(own + S.need_key + '\n set READYSTACK_LICENSE=<key> or ' + S.bin + ' --license <key>\n Get a licence ($' + S.price + ' once): ' + lic.BUY_URL + '\n'); process.exit(2);
|
|
153
|
+
}
|
|
154
|
+
}
|
|
155
|
+
}
|
|
156
|
+
const files = dir ? walk(dir, exts, []) : a.filter((x, i) => !x.startsWith('--') && !['--dir', '--report', '--out', '--ext', '--license'].includes(a[i - 1]));
|
|
157
|
+
if (!files.length) { process.stderr.write('No files. ' + S.bin + ' --help\n'); process.exit(2); }
|
|
158
|
+
const rows = files.map((f) => { let t = ''; try { t = fs.readFileSync(f, 'utf8'); } catch (e) { return { file: f, hits: [], error: String(e.message) }; } return { file: f, hits: scan(t) }; });
|
|
159
|
+
const text = render(rows, fmt || 'text');
|
|
160
|
+
if (out) fs.writeFileSync(out, text); else process.stdout.write(text.endsWith('\n') ? text : text + '\n');
|
|
161
|
+
if (!paid) { try { folderHint(files); } catch (e) {} pingUse(); } // s158 — a free run ends with the user's own folder count + one anonymous 'used' count (human seat only)
|
|
162
|
+
const errors = rows.reduce((n, r) => n + r.hits.filter((h) => h.sev === 'error').length, 0);
|
|
163
|
+
if (ci && errors) process.exit(1);
|
|
164
|
+
})().catch((e) => { process.stderr.write(String(e && e.stack || e) + '\n'); process.exit(3); });
|
|
@@ -0,0 +1,103 @@
|
|
|
1
|
+
// license.js — Polar licence check for the CLI / container. Generated by adapters.py; do not edit by hand.
|
|
2
|
+
'use strict';
|
|
3
|
+
const https = require('https'), fs = require('fs'), path = require('path'), os = require('os');
|
|
4
|
+
const ORG_ID = 'a5cdf664-d8e7-4f87-8895-056717aaba17';
|
|
5
|
+
const BENEFIT_ID = '6ddfd3d5-8a8c-4426-8dce-b18957fd3a44'; // s142 — this product's Polar benefit (s140 law: ask with benefit_id, or one key opens every product)
|
|
6
|
+
const BUY_URL = 'https://getreadystack.com/api/buy/cl/polar_cl_I8R8AzowzmASHy45ujvewcvtcl4wBBfC2Fe7r3fZwpr';
|
|
7
|
+
const SLUG = 'robots-txt-ai-crawler-audit';
|
|
8
|
+
const GRACE_MS = 30 * 24 * 3600 * 1000; // after a successful check, 30 days work offline
|
|
9
|
+
const RECHECK_MS = 7 * 24 * 3600 * 1000; // re-ask Polar every 7 days (refunds / cancellations)
|
|
10
|
+
function storePath() { return path.join(process.env.READYSTACK_HOME || path.join(os.homedir(), '.config', 'readystack'), SLUG + '.json'); }
|
|
11
|
+
function load() { try { return JSON.parse(fs.readFileSync(storePath(), 'utf8')); } catch (e) { return {}; } }
|
|
12
|
+
function save(o) { try { fs.mkdirSync(path.dirname(storePath()), { recursive: true }); fs.writeFileSync(storePath(), JSON.stringify(o)); } catch (e) { /* read-only home: still works for this run */ } }
|
|
13
|
+
const ALL_BENEFIT_ID = '22692551-5203-4467-b1a3-e33cdba6589d'; // s149 2026-09-17 — 팀 키(전 린터 한 키 · Polar benefit) · 상품 benefit 다음에 한 번 더 묻는다
|
|
14
|
+
// s170 2026-09-29 — ask OUR worker first (/api/lic): keys bought on Whop open here (a price-tier key binds to the first tool it opens · the team key opens every tool). Then the old Polar check.
|
|
15
|
+
function validate(key) {
|
|
16
|
+
return validateHub(key).then(function (h) {
|
|
17
|
+
if (h.ok) return h;
|
|
18
|
+
return validate1(key, BENEFIT_ID).then(function (r) { return (r.ok || r.offline || !/^[0-9a-f-]{36}$/.test(ALL_BENEFIT_ID)) ? r : validate1(key, ALL_BENEFIT_ID); })
|
|
19
|
+
.then(function (r) { return r.ok ? r : { ok: false, offline: !!(h.offline || r.offline) }; });
|
|
20
|
+
});
|
|
21
|
+
}
|
|
22
|
+
function validateHub(key) {
|
|
23
|
+
return new Promise(function (resolve) {
|
|
24
|
+
const req = https.request({ hostname: 'getreadystack.com', path: '/api/lic?key=' + encodeURIComponent(key) + '&slug=' + encodeURIComponent(SLUG),
|
|
25
|
+
method: 'GET', timeout: 8000, headers: { 'accept': 'application/json', 'user-agent': 'readystack-cli/' + SLUG } }, function (res) {
|
|
26
|
+
let buf = ''; res.on('data', function (d) { buf += d; });
|
|
27
|
+
res.on('end', function () {
|
|
28
|
+
if (res.statusCode !== 200) return resolve({ ok: false, offline: res.statusCode >= 500 });
|
|
29
|
+
try { const j = JSON.parse(buf); resolve({ ok: !!(j && j.ok), offline: false }); } catch (e) { resolve({ ok: false, offline: false }); }
|
|
30
|
+
});
|
|
31
|
+
});
|
|
32
|
+
req.on('timeout', function () { req.destroy(); resolve({ ok: false, offline: true }); });
|
|
33
|
+
req.on('error', function () { resolve({ ok: false, offline: true }); });
|
|
34
|
+
req.end();
|
|
35
|
+
});
|
|
36
|
+
}
|
|
37
|
+
function validate1(key, ben) {
|
|
38
|
+
return new Promise(function (resolve) {
|
|
39
|
+
if (!ORG_ID) return resolve({ ok: false, offline: false });
|
|
40
|
+
const body = JSON.stringify(/^[0-9a-f-]{36}$/.test(ben) ? { key: key, organization_id: ORG_ID, benefit_id: ben } : { key: key, organization_id: ORG_ID });
|
|
41
|
+
const req = https.request({ hostname: 'api.polar.sh', path: '/v1/customer-portal/license-keys/validate', method: 'POST', timeout: 8000,
|
|
42
|
+
headers: { 'content-type': 'application/json', 'polar-version': '2026-04', 'content-length': Buffer.byteLength(body) } }, function (res) {
|
|
43
|
+
let buf = ''; res.on('data', function (d) { buf += d; });
|
|
44
|
+
res.on('end', function () {
|
|
45
|
+
if (res.statusCode !== 200) return resolve({ ok: false, offline: false });
|
|
46
|
+
try { const j = JSON.parse(buf); resolve({ ok: j && (j.status === 'granted' || j.valid === true || !!j.id), offline: false }); }
|
|
47
|
+
catch (e) { resolve({ ok: false, offline: false }); }
|
|
48
|
+
});
|
|
49
|
+
});
|
|
50
|
+
req.on('timeout', function () { req.destroy(); resolve({ ok: false, offline: true }); });
|
|
51
|
+
req.on('error', function () { resolve({ ok: false, offline: true }); });
|
|
52
|
+
req.write(body); req.end();
|
|
53
|
+
});
|
|
54
|
+
}
|
|
55
|
+
// ★s151 2026-09-19 — 키 판(키가 없거나 거절된 순간)을 익명으로 센다 (슬러그·출처·이유만) · DO_NOT_TRACK=1 · READYSTACK_NO_TELEMETRY 면 안 보낸다 · 실패는 조용히 · 프로세스당 한 번.
|
|
56
|
+
let _pinged = false;
|
|
57
|
+
function pingPaywall(why) {
|
|
58
|
+
try {
|
|
59
|
+
if (_pinged) return; _pinged = true;
|
|
60
|
+
if (process.env.DO_NOT_TRACK === '1' || process.env.READYSTACK_NO_TELEMETRY || process.env.CI) return; // s151: CI(깃허브 액션 등)와 우리 빌드는 손님이 아니다
|
|
61
|
+
if (!(process.stdout.isTTY || process.stdin.isTTY || process.env.READYSTACK_MCP === '1')) return; // s152: 사람 자리(터미널·MCP 세션)에서만 센다 - 발행 1분 뒤 남의 실행기(JP · 우리 3대는 US)가 돌린 no_key 13건은 손님이 아니다
|
|
62
|
+
const body = JSON.stringify({ t: 'paywall', slug: SLUG, src: process.env.READYSTACK_MCP === '1' ? 'mcp' : 'cli', why: why || 'no_key' });
|
|
63
|
+
const req = https.request({ hostname: 'getreadystack.com', path: '/api/ev', method: 'POST', timeout: 3000,
|
|
64
|
+
headers: { 'content-type': 'application/json', 'content-length': Buffer.byteLength(body), 'user-agent': 'readystack-cli/' + SLUG } }, function (res) { res.resume(); });
|
|
65
|
+
req.on('timeout', function () { req.destroy(); }); req.on('error', function () {});
|
|
66
|
+
req.write(body); req.end();
|
|
67
|
+
} catch (e) { /* 세는 것이 실패해도 상품은 돈다 */ }
|
|
68
|
+
}
|
|
69
|
+
async function ensure(explicitKey) {
|
|
70
|
+
const st = load();
|
|
71
|
+
const key = explicitKey || process.env.READYSTACK_LICENSE || st.key;
|
|
72
|
+
if (!key) { pingPaywall('no_key'); return { ok: false, why: 'no_key' }; } // s151
|
|
73
|
+
const age = Date.now() - (st.okAt || 0);
|
|
74
|
+
if (!explicitKey && st.key === key && age < RECHECK_MS) return { ok: true, cached: true };
|
|
75
|
+
const r = await validate(String(key).trim());
|
|
76
|
+
if (r.ok) { save({ key: String(key).trim(), okAt: Date.now() }); return { ok: true }; }
|
|
77
|
+
if (r.offline && st.key === key && age < GRACE_MS) return { ok: true, offline: true };
|
|
78
|
+
if (!r.offline) pingPaywall('invalid'); // s151
|
|
79
|
+
return { ok: false, why: r.offline ? 'offline' : 'invalid' };
|
|
80
|
+
}
|
|
81
|
+
// ★s134 — 구독 규칙 피드(층3 "바뀌면 업데이트"): 키 있는 손님만 · 7일마다 · 오프라인은 캐시. 워커 GET /api/rules/<slug>?key=
|
|
82
|
+
const FEED_URL = 'https://getreadystack.com/api/rules/';
|
|
83
|
+
function pullFeed() {
|
|
84
|
+
const st = load(); const key = process.env.READYSTACK_LICENSE || st.key; const cached = st.feed || null;
|
|
85
|
+
if (!key) return Promise.resolve(cached);
|
|
86
|
+
if (cached && (Date.now() - (st.feedAt || 0)) < RECHECK_MS) return Promise.resolve(cached);
|
|
87
|
+
return new Promise(function (resolve) {
|
|
88
|
+
let req;
|
|
89
|
+
try {
|
|
90
|
+
req = https.get(FEED_URL + encodeURIComponent(SLUG) + '?key=' + encodeURIComponent(key), { timeout: 8000, headers: { 'user-agent': 'readystack-cli' } }, function (res) {
|
|
91
|
+
let buf = ''; res.on('data', function (d) { buf += d; });
|
|
92
|
+
res.on('end', function () {
|
|
93
|
+
if (res.statusCode !== 200) return resolve(cached);
|
|
94
|
+
try { const j = JSON.parse(buf); if (!j || !Array.isArray(j.rules)) return resolve(cached); save(Object.assign(load(), { feed: j, feedAt: Date.now() })); resolve(j); }
|
|
95
|
+
catch (e) { resolve(cached); }
|
|
96
|
+
});
|
|
97
|
+
});
|
|
98
|
+
} catch (e) { return resolve(cached); }
|
|
99
|
+
req.on('timeout', function () { req.destroy(); resolve(cached); });
|
|
100
|
+
req.on('error', function () { resolve(cached); });
|
|
101
|
+
});
|
|
102
|
+
}
|
|
103
|
+
module.exports = { ensure, BUY_URL, storePath, pullFeed };
|
|
@@ -0,0 +1,38 @@
|
|
|
1
|
+
{
|
|
2
|
+
"name": "@readystack/robots-txt-ai-crawler-audit",
|
|
3
|
+
"version": "0.1.8",
|
|
4
|
+
"description": "Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing.",
|
|
5
|
+
"license": "SEE LICENSE IN LICENSE.txt",
|
|
6
|
+
"publishConfig": {
|
|
7
|
+
"access": "public"
|
|
8
|
+
},
|
|
9
|
+
"keywords": [
|
|
10
|
+
"robots.txt",
|
|
11
|
+
"AI crawler",
|
|
12
|
+
"GPTBot",
|
|
13
|
+
"Google-Extended",
|
|
14
|
+
"SEO"
|
|
15
|
+
],
|
|
16
|
+
"homepage": "https://getreadystack.com",
|
|
17
|
+
"funding": "https://getreadystack.com/api/buy/cl/polar_cl_I8R8AzowzmASHy45ujvewcvtcl4wBBfC2Fe7r3fZwpr",
|
|
18
|
+
"bin": {
|
|
19
|
+
"robots-txt-ai-crawler-audit": "cli.js"
|
|
20
|
+
},
|
|
21
|
+
"engines": {
|
|
22
|
+
"node": ">=18"
|
|
23
|
+
},
|
|
24
|
+
"mcpName": "io.github.jmshinhwa/robots-txt-ai-crawler-audit",
|
|
25
|
+
"repository": {
|
|
26
|
+
"type": "git",
|
|
27
|
+
"url": "https://github.com/jmshinhwa/readystack-themes.git",
|
|
28
|
+
"directory": "robots-txt-ai-crawler-audit"
|
|
29
|
+
},
|
|
30
|
+
"files": [
|
|
31
|
+
"cli.js",
|
|
32
|
+
"license.js",
|
|
33
|
+
"rules.json",
|
|
34
|
+
"strings.json",
|
|
35
|
+
"README.md",
|
|
36
|
+
"LICENSE.txt"
|
|
37
|
+
]
|
|
38
|
+
}
|
|
@@ -0,0 +1,119 @@
|
|
|
1
|
+
[
|
|
2
|
+
{
|
|
3
|
+
"pattern": "^\\s*User-agent:\\s*(Claude-Web|anthropic-ai)\\s*(#.*)?$",
|
|
4
|
+
"flags": "i",
|
|
5
|
+
"sev": "error",
|
|
6
|
+
"message": "Retired token. Claude-Web and anthropic-ai were replaced by ClaudeBot in 2024, so this group controls no current Claude traffic. Use ClaudeBot (training), Claude-SearchBot (citation in Claude) or Claude-User (user-triggered fetch).",
|
|
7
|
+
"fix": "User-agent: ClaudeBot"
|
|
8
|
+
},
|
|
9
|
+
{
|
|
10
|
+
"pattern": "^\\s*User-agent:\\s*(GPT-Bot|Claude-Bot|Perplexity-Bot|Amazon-Bot|Google-Bot|Bing-Bot|Apple-Bot|Byte-Spider)\\s*(#.*)?$",
|
|
11
|
+
"flags": "i",
|
|
12
|
+
"sev": "error",
|
|
13
|
+
"message": "No crawler answers to this name - the real token has no hyphen (GPTBot, ClaudeBot, PerplexityBot, Amazonbot, Googlebot, Bingbot, Applebot, Bytespider). robots.txt ignores unknown tokens silently, so this group is dead weight.",
|
|
14
|
+
"fix": "User-agent: GPTBot"
|
|
15
|
+
},
|
|
16
|
+
{
|
|
17
|
+
"pattern": "^\\s*User-agent:\\s*(ChatGPT-Bot|ChatGPTBot|ChatGPT|OpenAI-Bot|OpenAI-Crawler|OpenAI|Bard|Google-Bard|Gemini|Gemini-Bot|Meta-AI|LLaMA|Copilot-Bot|AI-Bot|AIBot|GPT-4|GPT4)\\s*(#.*)?$",
|
|
18
|
+
"flags": "i",
|
|
19
|
+
"sev": "error",
|
|
20
|
+
"message": "Not a real crawler token. Assistants emit these names confidently, but nothing answers to them, so this group blocks nothing at all. The documented tokens are GPTBot, OAI-SearchBot, ChatGPT-User, OAI-AdsBot, ClaudeBot, Claude-SearchBot, Claude-User, Google-Extended and PerplexityBot.",
|
|
21
|
+
"fix": "User-agent: GPTBot"
|
|
22
|
+
},
|
|
23
|
+
{
|
|
24
|
+
"pattern": "^\\s*Noindex\\s*:",
|
|
25
|
+
"flags": "i",
|
|
26
|
+
"sev": "error",
|
|
27
|
+
"message": "Google stopped honouring noindex in robots.txt on 1 September 2019. This line does nothing. Use a meta robots noindex tag on the page, or an X-Robots-Tag HTTP header.",
|
|
28
|
+
"fix": "# move to: <meta name=\"robots\" content=\"noindex\">"
|
|
29
|
+
},
|
|
30
|
+
{
|
|
31
|
+
"pattern": "^\\s*Disallow:\\s*\\*\\s*(#.*)?$",
|
|
32
|
+
"sev": "error",
|
|
33
|
+
"message": "Disallow: * is not a valid path value. To block a whole group write Disallow: / - as written this is widely parsed as an empty path, which allows the entire site rather than blocking it.",
|
|
34
|
+
"fix": "Disallow: /"
|
|
35
|
+
},
|
|
36
|
+
{
|
|
37
|
+
"pattern": "^\\s*Sitemap:\\s*(?!https?://)\\S",
|
|
38
|
+
"flags": "i",
|
|
39
|
+
"sev": "error",
|
|
40
|
+
"message": "Sitemap must be an absolute URL including scheme and host. A relative path is ignored, so your sitemap is not being announced here.",
|
|
41
|
+
"fix": "Sitemap: https://example.com/sitemap.xml"
|
|
42
|
+
},
|
|
43
|
+
{
|
|
44
|
+
"pattern": "^\\s*User-agent:\\s*(Google-Extended)\\s*(#.*)?$",
|
|
45
|
+
"flags": "i",
|
|
46
|
+
"sev": "warn",
|
|
47
|
+
"message": "Google-Extended is a control token, not a crawler - it only opts content out of Gemini model training and grounding. Google documents that it does NOT affect inclusion in Google Search and is not a ranking signal, and AI Overviews are served from Googlebot. Blocking this to escape AI Overviews does not work."
|
|
48
|
+
},
|
|
49
|
+
{
|
|
50
|
+
"pattern": "^\\s*User-agent:\\s*(Applebot-Extended)\\s*(#.*)?$",
|
|
51
|
+
"flags": "i",
|
|
52
|
+
"sev": "warn",
|
|
53
|
+
"message": "Applebot-Extended is a control token, not a crawler - it only opts content out of Apple model training. Apple Search and Siri still use Applebot, so this line does not change your visibility there. You will never see it as a request in server logs."
|
|
54
|
+
},
|
|
55
|
+
{
|
|
56
|
+
"pattern": "^\\s*User-agent:\\s*(OAI-SearchBot|Claude-SearchBot|PerplexityBot|Amzn-SearchBot)\\s*(#.*)?$",
|
|
57
|
+
"flags": "i",
|
|
58
|
+
"sev": "warn",
|
|
59
|
+
"message": "This is a search and citation crawler, not a training crawler. If this group disallows, you remove yourself from the answers ChatGPT, Claude, Perplexity or Amazon show - while your content can still be trained on through GPTBot or ClaudeBot. Training and citation are separate controls."
|
|
60
|
+
},
|
|
61
|
+
{
|
|
62
|
+
"pattern": "^\\s*User-agent:\\s*(Googlebot)\\s*(#.*)?$",
|
|
63
|
+
"flags": "i",
|
|
64
|
+
"sev": "warn",
|
|
65
|
+
"message": "Googlebot is the search crawler and it is also what feeds AI Overviews. Disallowing this group removes you from Google Search itself. There is currently no supported way to stay in Search but out of AI Overviews."
|
|
66
|
+
},
|
|
67
|
+
{
|
|
68
|
+
"pattern": "^\\s*Crawl-delay\\s*:",
|
|
69
|
+
"flags": "i",
|
|
70
|
+
"sev": "warn",
|
|
71
|
+
"message": "Googlebot ignores Crawl-delay completely. Bing and several AI crawlers do honour it. To slow Google down, use the crawl rate setting in Search Console instead of this line."
|
|
72
|
+
},
|
|
73
|
+
{
|
|
74
|
+
"pattern": "^\\s*Host\\s*:",
|
|
75
|
+
"flags": "i",
|
|
76
|
+
"sev": "warn",
|
|
77
|
+
"message": "Host: is not part of the robots.txt standard and is ignored by Google and Bing. Set your canonical host with redirects and rel=canonical instead."
|
|
78
|
+
},
|
|
79
|
+
{
|
|
80
|
+
"pattern": "^\\s*Disallow:\\s*/\\*\\s*(#.*)?$",
|
|
81
|
+
"sev": "warn",
|
|
82
|
+
"message": "Disallow: /* matches every path, exactly like Disallow: /. If you meant to block a pattern, put the literal part first, for example Disallow: /draft*."
|
|
83
|
+
},
|
|
84
|
+
{
|
|
85
|
+
"pattern": "^\\s*User-agent:\\s*(Perplexity-User)\\s*(#.*)?$",
|
|
86
|
+
"flags": "i",
|
|
87
|
+
"sev": "warn",
|
|
88
|
+
"message": "Perplexity-User is a user-triggered fetcher and Perplexity documents that it generally does not follow robots.txt. Treat this group as advisory: if you must stop it, block at the edge or by IP rather than relying on this line."
|
|
89
|
+
},
|
|
90
|
+
{
|
|
91
|
+
"pattern": "^\\s*User-agent:\\s*(GPTBot|ClaudeBot|CCBot|Bytespider|Amazonbot|Meta-ExternalAgent|meta-externalagent)\\s*(#.*)?$",
|
|
92
|
+
"flags": "i",
|
|
93
|
+
"sev": "info",
|
|
94
|
+
"message": "Training crawler. Disallowing it keeps your pages out of model training data and does NOT affect whether you are cited in AI search, which runs on OAI-SearchBot, Claude-SearchBot and PerplexityBot. Blocking GPTBot alone does not remove you from ChatGPT."
|
|
95
|
+
},
|
|
96
|
+
{
|
|
97
|
+
"pattern": "^\\s*User-agent:\\s*(ChatGPT-User|Claude-User|Amzn-User|Meta-ExternalFetcher)\\s*(#.*)?$",
|
|
98
|
+
"flags": "i",
|
|
99
|
+
"sev": "info",
|
|
100
|
+
"message": "User-triggered fetcher: it loads the page only when a person asks the assistant to open your link. Disallowing it means a reader who deliberately pastes your URL gets an empty answer, while training access is unaffected."
|
|
101
|
+
},
|
|
102
|
+
{
|
|
103
|
+
"pattern": "^\\s*User-agent:\\s*(OAI-AdsBot)\\s*(#.*)?$",
|
|
104
|
+
"flags": "i",
|
|
105
|
+
"sev": "info",
|
|
106
|
+
"message": "OAI-AdsBot only validates the safety of pages submitted as ads in ChatGPT, and OpenAI documents that it is not used for model training. Blocking it can stop your own ads from being verified."
|
|
107
|
+
},
|
|
108
|
+
{
|
|
109
|
+
"pattern": "^\\s*User-agent:\\s*\\*\\s*(#.*)?$",
|
|
110
|
+
"sev": "info",
|
|
111
|
+
"message": "The wildcard group does not cover AI crawlers the way most people assume: a named group replaces it entirely, it is not merged. If GPTBot has its own group, GPTBot ignores every rule written here. Name each AI token you actually care about."
|
|
112
|
+
},
|
|
113
|
+
{
|
|
114
|
+
"pattern": "llms\\.txt",
|
|
115
|
+
"flags": "i",
|
|
116
|
+
"sev": "info",
|
|
117
|
+
"message": "llms.txt is a proposed convention, not an honoured standard - no major AI crawler currently reads it. Keep real access rules in robots.txt and treat llms.txt as documentation only."
|
|
118
|
+
}
|
|
119
|
+
]
|
|
@@ -0,0 +1,10 @@
|
|
|
1
|
+
{
|
|
2
|
+
"name": "AI Crawler Rules - robots.txt Audit for AI Search",
|
|
3
|
+
"subtitle": "Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing.",
|
|
4
|
+
"bin": "robots-txt-ai-crawler-audit",
|
|
5
|
+
"price": 29,
|
|
6
|
+
"free": "Check the open robots.txt against every rule - full results, nothing withheld; Check only the lines you highlight; See every rule and what each AI token controls; Reopen the last report",
|
|
7
|
+
"paid": "Scan every robots.txt in the workspace; Export the report as CSV, JSON or HTML; CI output that fails the build on errors; Add your own agency policy tokens; Re-check automatically on every save",
|
|
8
|
+
"need_key": "This option needs a licence (AI Crawler Rules - robots.txt Audit for AI Search).",
|
|
9
|
+
"exts": []
|
|
10
|
+
}
|
|
@@ -0,0 +1,84 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: readystack-robots-txt-ai-crawler-audit
|
|
3
|
+
Version: 0.1.8
|
|
4
|
+
Summary: Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing. (bundled Node.js runtime)
|
|
5
|
+
Author-email: ReadyStack <support@getreadystack.com>
|
|
6
|
+
License: Proprietary - see LICENSE.txt
|
|
7
|
+
Project-URL: Homepage, https://getreadystack.com/tools/robots-txt-ai-crawler-audit?ref=pypi
|
|
8
|
+
Project-URL: Documentation, https://getreadystack.com/tools/robots-txt-ai-crawler-audit?ref=pypi
|
|
9
|
+
Project-URL: Support, https://getreadystack.com/support
|
|
10
|
+
Keywords: robots.txt,AI crawler,GPTBot,Google-Extended,SEO
|
|
11
|
+
Classifier: Programming Language :: Python :: 3
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Topic :: Software Development :: Quality Assurance
|
|
14
|
+
Classifier: Operating System :: OS Independent
|
|
15
|
+
Requires-Python: >=3.9
|
|
16
|
+
Description-Content-Type: text/markdown
|
|
17
|
+
License-File: LICENSE.txt
|
|
18
|
+
Requires-Dist: nodejs-wheel-binaries>=20
|
|
19
|
+
Dynamic: license-file
|
|
20
|
+
|
|
21
|
+
# AI Crawler Rules - robots.txt Audit for AI Search
|
|
22
|
+
|
|
23
|
+
> Runs the same checker as the npm package `@readystack/robots-txt-ai-crawler-audit` on a Node.js runtime that pip installs for you (`nodejs-wheel-binaries`) - no system Node.js needed. Your files are checked locally.
|
|
24
|
+
|
|
25
|
+

|
|
26
|
+
|
|
27
|
+
Checks robots.txt line by line and says what each AI crawler token actually controls - training, AI-search citation, or user fetch - and which lines silently do nothing.
|
|
28
|
+
|
|
29
|
+
## Install
|
|
30
|
+
|
|
31
|
+
```
|
|
32
|
+
robots-txt-ai-crawler-audit file
|
|
33
|
+
```
|
|
34
|
+
|
|
35
|
+
Node 18+. The same 19 rules as the VS Code extension, from a terminal or CI.
|
|
36
|
+
|
|
37
|
+
## Free
|
|
38
|
+
|
|
39
|
+
- Check the open robots.txt against every rule - full results, nothing withheld; Check only the lines you highlight; See every rule and what each AI token controls; Reopen the last report
|
|
40
|
+
- `--rules` lists every rule
|
|
41
|
+
|
|
42
|
+
## With a licence ($29 once)
|
|
43
|
+
|
|
44
|
+
- Scan every robots.txt in the workspace; Export the report as CSV, JSON or HTML; CI output that fails the build on errors; Add your own agency policy tokens; Re-check automatically on every save
|
|
45
|
+
|
|
46
|
+
```
|
|
47
|
+
@readystack/robots-txt-ai-crawler-audit --dir ./templates --report html --out report.html
|
|
48
|
+
```
|
|
49
|
+
|
|
50
|
+
A freelance technical SEO consultant bills roughly $100-150 an hour, and an AI-crawler robots.txt review is a one-to-two hour job.
|
|
51
|
+
|
|
52
|
+
## Use from an AI agent (MCP)
|
|
53
|
+
|
|
54
|
+
Claude Code · Cursor · Windsurf · any MCP client - add to your MCP config:
|
|
55
|
+
|
|
56
|
+
```json
|
|
57
|
+
{ "mcpServers": { "robots-txt-ai-crawler-audit": { "command": "npx", "args": ["-y", "@readystack/robots-txt-ai-crawler-audit", "--mcp"] } } }
|
|
58
|
+
```
|
|
59
|
+
|
|
60
|
+
Tools: `check_text` and `check_file` (free) · `check_dir` (licence). The agent gets every finding with the line number.
|
|
61
|
+
|
|
62
|
+
## Use in CI
|
|
63
|
+
|
|
64
|
+
```yaml
|
|
65
|
+
- name: AI Crawler Rules - robots.txt Audit for AI Search
|
|
66
|
+
run: npx -y @readystack/robots-txt-ai-crawler-audit --dir . --ci
|
|
67
|
+
```
|
|
68
|
+
|
|
69
|
+
(container: `docker run --rm -v "$PWD:/work" getreadystack/robots-txt-ai-crawler-audit --dir /work --ci`)
|
|
70
|
+
|
|
71
|
+
The folder sweep, reports and CI mode need one licence — one payment, no subscription. Set `READYSTACK_LICENSE=<key>` or run `--license <key>` once.
|
|
72
|
+
|
|
73
|
+
[Get a licence](https://getreadystack.com/api/buy/cl/polar_cl_I8R8AzowzmASHy45ujvewcvtcl4wBBfC2Fe7r3fZwpr)
|
|
74
|
+
|
|
75
|
+
|
|
76
|
+
<!-- ai crawler rules for robots txt -->
|
|
77
|
+
|
|
78
|
+
|
|
79
|
+
## Install (PyPI)
|
|
80
|
+
|
|
81
|
+
```
|
|
82
|
+
pip install readystack-robots-txt-ai-crawler-audit
|
|
83
|
+
robots-txt-ai-crawler-audit --help
|
|
84
|
+
```
|
|
@@ -0,0 +1,16 @@
|
|
|
1
|
+
LICENSE.txt
|
|
2
|
+
README.md
|
|
3
|
+
pyproject.toml
|
|
4
|
+
src/readystack_robots_txt_ai_crawler_audit/__init__.py
|
|
5
|
+
src/readystack_robots_txt_ai_crawler_audit/__main__.py
|
|
6
|
+
src/readystack_robots_txt_ai_crawler_audit.egg-info/PKG-INFO
|
|
7
|
+
src/readystack_robots_txt_ai_crawler_audit.egg-info/SOURCES.txt
|
|
8
|
+
src/readystack_robots_txt_ai_crawler_audit.egg-info/dependency_links.txt
|
|
9
|
+
src/readystack_robots_txt_ai_crawler_audit.egg-info/entry_points.txt
|
|
10
|
+
src/readystack_robots_txt_ai_crawler_audit.egg-info/requires.txt
|
|
11
|
+
src/readystack_robots_txt_ai_crawler_audit.egg-info/top_level.txt
|
|
12
|
+
src/readystack_robots_txt_ai_crawler_audit/js/cli.js
|
|
13
|
+
src/readystack_robots_txt_ai_crawler_audit/js/license.js
|
|
14
|
+
src/readystack_robots_txt_ai_crawler_audit/js/package.json
|
|
15
|
+
src/readystack_robots_txt_ai_crawler_audit/js/rules.json
|
|
16
|
+
src/readystack_robots_txt_ai_crawler_audit/js/strings.json
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
nodejs-wheel-binaries>=20
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
readystack_robots_txt_ai_crawler_audit
|