pgalign 1.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- pgalign-1.1.0/CITATION.cff +39 -0
- pgalign-1.1.0/LICENSE +21 -0
- pgalign-1.1.0/MANIFEST.in +6 -0
- pgalign-1.1.0/PKG-INFO +318 -0
- pgalign-1.1.0/README.md +279 -0
- pgalign-1.1.0/images/pgalign_workflow.png +0 -0
- pgalign-1.1.0/pgalign/AnnDataMALDI.py +476 -0
- pgalign-1.1.0/pgalign/PeakCalling.py +282 -0
- pgalign-1.1.0/pgalign/__init__.py +87 -0
- pgalign-1.1.0/pgalign/cli.py +84 -0
- pgalign-1.1.0/pgalign/data/mouse_pancreas_toy.npz +0 -0
- pgalign-1.1.0/pgalign/datasets.py +39 -0
- pgalign-1.1.0/pgalign/pipeline.py +153 -0
- pgalign-1.1.0/pgalign/readers.py +130 -0
- pgalign-1.1.0/pgalign/util.py +135 -0
- pgalign-1.1.0/pgalign.egg-info/PKG-INFO +318 -0
- pgalign-1.1.0/pgalign.egg-info/SOURCES.txt +32 -0
- pgalign-1.1.0/pgalign.egg-info/dependency_links.txt +1 -0
- pgalign-1.1.0/pgalign.egg-info/entry_points.txt +2 -0
- pgalign-1.1.0/pgalign.egg-info/requires.txt +12 -0
- pgalign-1.1.0/pgalign.egg-info/top_level.txt +1 -0
- pgalign-1.1.0/pyproject.toml +72 -0
- pgalign-1.1.0/setup.cfg +4 -0
- pgalign-1.1.0/tests/test_align.py +60 -0
- pgalign-1.1.0/tests/test_alignment.py +30 -0
- pgalign-1.1.0/tests/test_ambiguity.py +159 -0
- pgalign-1.1.0/tests/test_checks.py +65 -0
- pgalign-1.1.0/tests/test_cli.py +45 -0
- pgalign-1.1.0/tests/test_deprecation.py +58 -0
- pgalign-1.1.0/tests/test_import.py +32 -0
- pgalign-1.1.0/tests/test_peak_calling.py +15 -0
- pgalign-1.1.0/tests/test_readers.py +104 -0
- pgalign-1.1.0/tests/test_toy_dataset.py +26 -0
- pgalign-1.1.0/tests/test_toy_outputs.py +65 -0
|
@@ -0,0 +1,39 @@
|
|
|
1
|
+
cff-version: 1.2.0
|
|
2
|
+
message: "If you use PGAlign in your research, please cite the accompanying paper."
|
|
3
|
+
title: "PGAlign: peak group alignment of mass spectrometry data"
|
|
4
|
+
type: software
|
|
5
|
+
version: "1.1.0"
|
|
6
|
+
authors:
|
|
7
|
+
- family-names: Deng
|
|
8
|
+
given-names: Anji
|
|
9
|
+
affiliation: "Department of Epidemiology, Biostatistics, and Occupational Health, McGill University"
|
|
10
|
+
- family-names: Zhang
|
|
11
|
+
given-names: Yuyang
|
|
12
|
+
affiliation: "Department of Epidemiology, Biostatistics, and Occupational Health, McGill University"
|
|
13
|
+
- family-names: Zhang
|
|
14
|
+
given-names: Qihuang
|
|
15
|
+
email: qihuang.zhang@mcgill.ca
|
|
16
|
+
affiliation: "Department of Epidemiology, Biostatistics, and Occupational Health, McGill University"
|
|
17
|
+
orcid: "https://orcid.org/0000-0003-1455-2159"
|
|
18
|
+
repository-code: "https://github.com/StaGill/PGAlign"
|
|
19
|
+
url: "https://stagill.github.io/PGAlign/"
|
|
20
|
+
keywords:
|
|
21
|
+
- MALDI
|
|
22
|
+
- mass spectrometry
|
|
23
|
+
- spatial metabolomics
|
|
24
|
+
- alignment
|
|
25
|
+
- imaging
|
|
26
|
+
license: MIT
|
|
27
|
+
preferred-citation:
|
|
28
|
+
type: unpublished
|
|
29
|
+
title: "PGAlign: peak group alignment of mass spectrometry data"
|
|
30
|
+
authors:
|
|
31
|
+
- family-names: Deng
|
|
32
|
+
given-names: Anji
|
|
33
|
+
- family-names: Zhang
|
|
34
|
+
given-names: Yuyang
|
|
35
|
+
- family-names: Zhang
|
|
36
|
+
given-names: Qihuang
|
|
37
|
+
email: qihuang.zhang@mcgill.ca
|
|
38
|
+
year: 2026
|
|
39
|
+
notes: "Under review at the Journal of Proteome Research. Please contact the corresponding author for the current preprint."
|
pgalign-1.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2023 Qihuang Zhang
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
pgalign-1.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,318 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: pgalign
|
|
3
|
+
Version: 1.1.0
|
|
4
|
+
Summary: PGAlign: peak group alignment of mass spectrometry data for imaging and spatial metabolomics.
|
|
5
|
+
Author: Anji Deng, Yuyang Zhang
|
|
6
|
+
Author-email: Qihuang Zhang <qihuang.zhang@mcgill.ca>
|
|
7
|
+
Maintainer-email: Qihuang Zhang <qihuang.zhang@mcgill.ca>
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
Project-URL: Homepage, https://stagill.github.io/PGAlign/
|
|
10
|
+
Project-URL: Documentation, https://stagill.github.io/PGAlign/
|
|
11
|
+
Project-URL: Repository, https://github.com/StaGill/PGAlign
|
|
12
|
+
Project-URL: Issues, https://github.com/StaGill/PGAlign/issues
|
|
13
|
+
Keywords: MALDI,mass spectrometry,spatial metabolomics,alignment,imaging,bioinformatics
|
|
14
|
+
Classifier: Development Status :: 4 - Beta
|
|
15
|
+
Classifier: Intended Audience :: Science/Research
|
|
16
|
+
Classifier: Operating System :: OS Independent
|
|
17
|
+
Classifier: Programming Language :: Python :: 3
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.9
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
22
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
23
|
+
Classifier: Programming Language :: Python :: 3.14
|
|
24
|
+
Classifier: Topic :: Scientific/Engineering :: Bio-Informatics
|
|
25
|
+
Requires-Python: >=3.9
|
|
26
|
+
Description-Content-Type: text/markdown
|
|
27
|
+
License-File: LICENSE
|
|
28
|
+
Requires-Dist: numpy>=1.20
|
|
29
|
+
Requires-Dist: scipy>=1.7
|
|
30
|
+
Requires-Dist: pandas>=1.3
|
|
31
|
+
Requires-Dist: scanpy>=1.9.2
|
|
32
|
+
Requires-Dist: anndata>=0.8
|
|
33
|
+
Requires-Dist: tqdm
|
|
34
|
+
Provides-Extra: test
|
|
35
|
+
Requires-Dist: pytest>=7.0; extra == "test"
|
|
36
|
+
Provides-Extra: imzml
|
|
37
|
+
Requires-Dist: pyimzML>=1.5; extra == "imzml"
|
|
38
|
+
Dynamic: license-file
|
|
39
|
+
|
|
40
|
+
<p align="center">
|
|
41
|
+
<picture>
|
|
42
|
+
<source media="(prefers-color-scheme: dark)" srcset="https://raw.githubusercontent.com/StaGill/PGAlign/main/images/pgalign_logo_dark.svg">
|
|
43
|
+
<img src="https://raw.githubusercontent.com/StaGill/PGAlign/main/images/pgalign_logo.svg" alt="PGAlign" width="420">
|
|
44
|
+
</picture>
|
|
45
|
+
</p>
|
|
46
|
+
|
|
47
|
+
<p align="center">
|
|
48
|
+
<a href="https://github.com/StaGill/PGAlign/actions/workflows/tests.yml"><img src="https://github.com/StaGill/PGAlign/actions/workflows/tests.yml/badge.svg?branch=main" alt="tests"></a>
|
|
49
|
+
<a href="https://stagill.github.io/PGAlign/"><img src="https://github.com/StaGill/PGAlign/actions/workflows/docs.yml/badge.svg?branch=main" alt="docs"></a>
|
|
50
|
+
<a href="https://github.com/StaGill/PGAlign/releases"><img src="https://img.shields.io/github/v/release/StaGill/PGAlign" alt="release"></a>
|
|
51
|
+
<a href="https://github.com/StaGill/PGAlign/blob/main/LICENSE"><img src="https://img.shields.io/github/license/StaGill/PGAlign" alt="license"></a>
|
|
52
|
+
</p>
|
|
53
|
+
|
|
54
|
+
**PGAlign (Peak-Group Alignment of mass spectrometry data)** is a peak-group-based
|
|
55
|
+
algorithm for aligning mass spectrometry (MS) spectra onto a common m/z grid.
|
|
56
|
+
It is designed for imaging and spatial metabolomics data such as MALDI-MS,
|
|
57
|
+
where spectra from different runs or tissues often exhibit small m/z shifts
|
|
58
|
+
that prevent direct comparison.
|
|
59
|
+
|
|
60
|
+
Anji Deng, Yuyang Zhang, and Qihuang Zhang\*
|
|
61
|
+
McGill University (corresponding author: <qihuang.zhang@mcgill.ca>)
|
|
62
|
+
|
|
63
|
+
**Documentation:** <https://stagill.github.io/PGAlign/>
|
|
64
|
+
|
|
65
|
+
|
|
66
|
+
|
|
67
|
+
By aligning an "unknown" spectrum (or dataset) to a reference while *forcing*
|
|
68
|
+
matched spectra to share the same m/z values, PGAlign enables downstream
|
|
69
|
+
analyses such as:
|
|
70
|
+
|
|
71
|
+
- joint spatial segmentation across tissues or time points
|
|
72
|
+
- classification using combined datasets
|
|
73
|
+
- other multi-sample analyses that require a common m/z grid
|
|
74
|
+
|
|
75
|
+
This repository contains the reference Python implementation accompanying the
|
|
76
|
+
PGAlign manuscript (Deng, Zhang & Zhang, 2026; under peer review).
|
|
77
|
+
|
|
78
|
+
---
|
|
79
|
+
|
|
80
|
+
## Repository layout
|
|
81
|
+
|
|
82
|
+
- `pgalign/`: Core Python implementation of PGAlign (alignment and peak-group functions).
|
|
83
|
+
- `CodeInPaper/`: Scripts that reproduce the figures and results in the manuscript. See `CodeInPaper/README.md`.
|
|
84
|
+
- `Tutorial_PGAlign.ipynb`: A Jupyter notebook that walks through aligning two MALDI datasets (e.g., Week 2 and Week 5 macrophage samples) and preparing them for joint segmentation.
|
|
85
|
+
- `tests/`: Smoke tests (`pytest`).
|
|
86
|
+
- `CITATION.cff`: Citation metadata.
|
|
87
|
+
- `LICENSE`: MIT license.
|
|
88
|
+
|
|
89
|
+
---
|
|
90
|
+
|
|
91
|
+
## Installation
|
|
92
|
+
|
|
93
|
+
```bash
|
|
94
|
+
pip install pgalign # or "pgalign[imzml]" to read imzML files
|
|
95
|
+
```
|
|
96
|
+
|
|
97
|
+
To work from the source, clone the repository and install it with `pip`:
|
|
98
|
+
|
|
99
|
+
```bash
|
|
100
|
+
git clone https://github.com/StaGill/PGAlign.git
|
|
101
|
+
cd PGAlign
|
|
102
|
+
pip install -e .
|
|
103
|
+
```
|
|
104
|
+
|
|
105
|
+
The package's importable name is `pgalign`:
|
|
106
|
+
|
|
107
|
+
```python
|
|
108
|
+
import pgalign as pg
|
|
109
|
+
print(pg.__version__)
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
---
|
|
113
|
+
|
|
114
|
+
## API at a glance
|
|
115
|
+
|
|
116
|
+
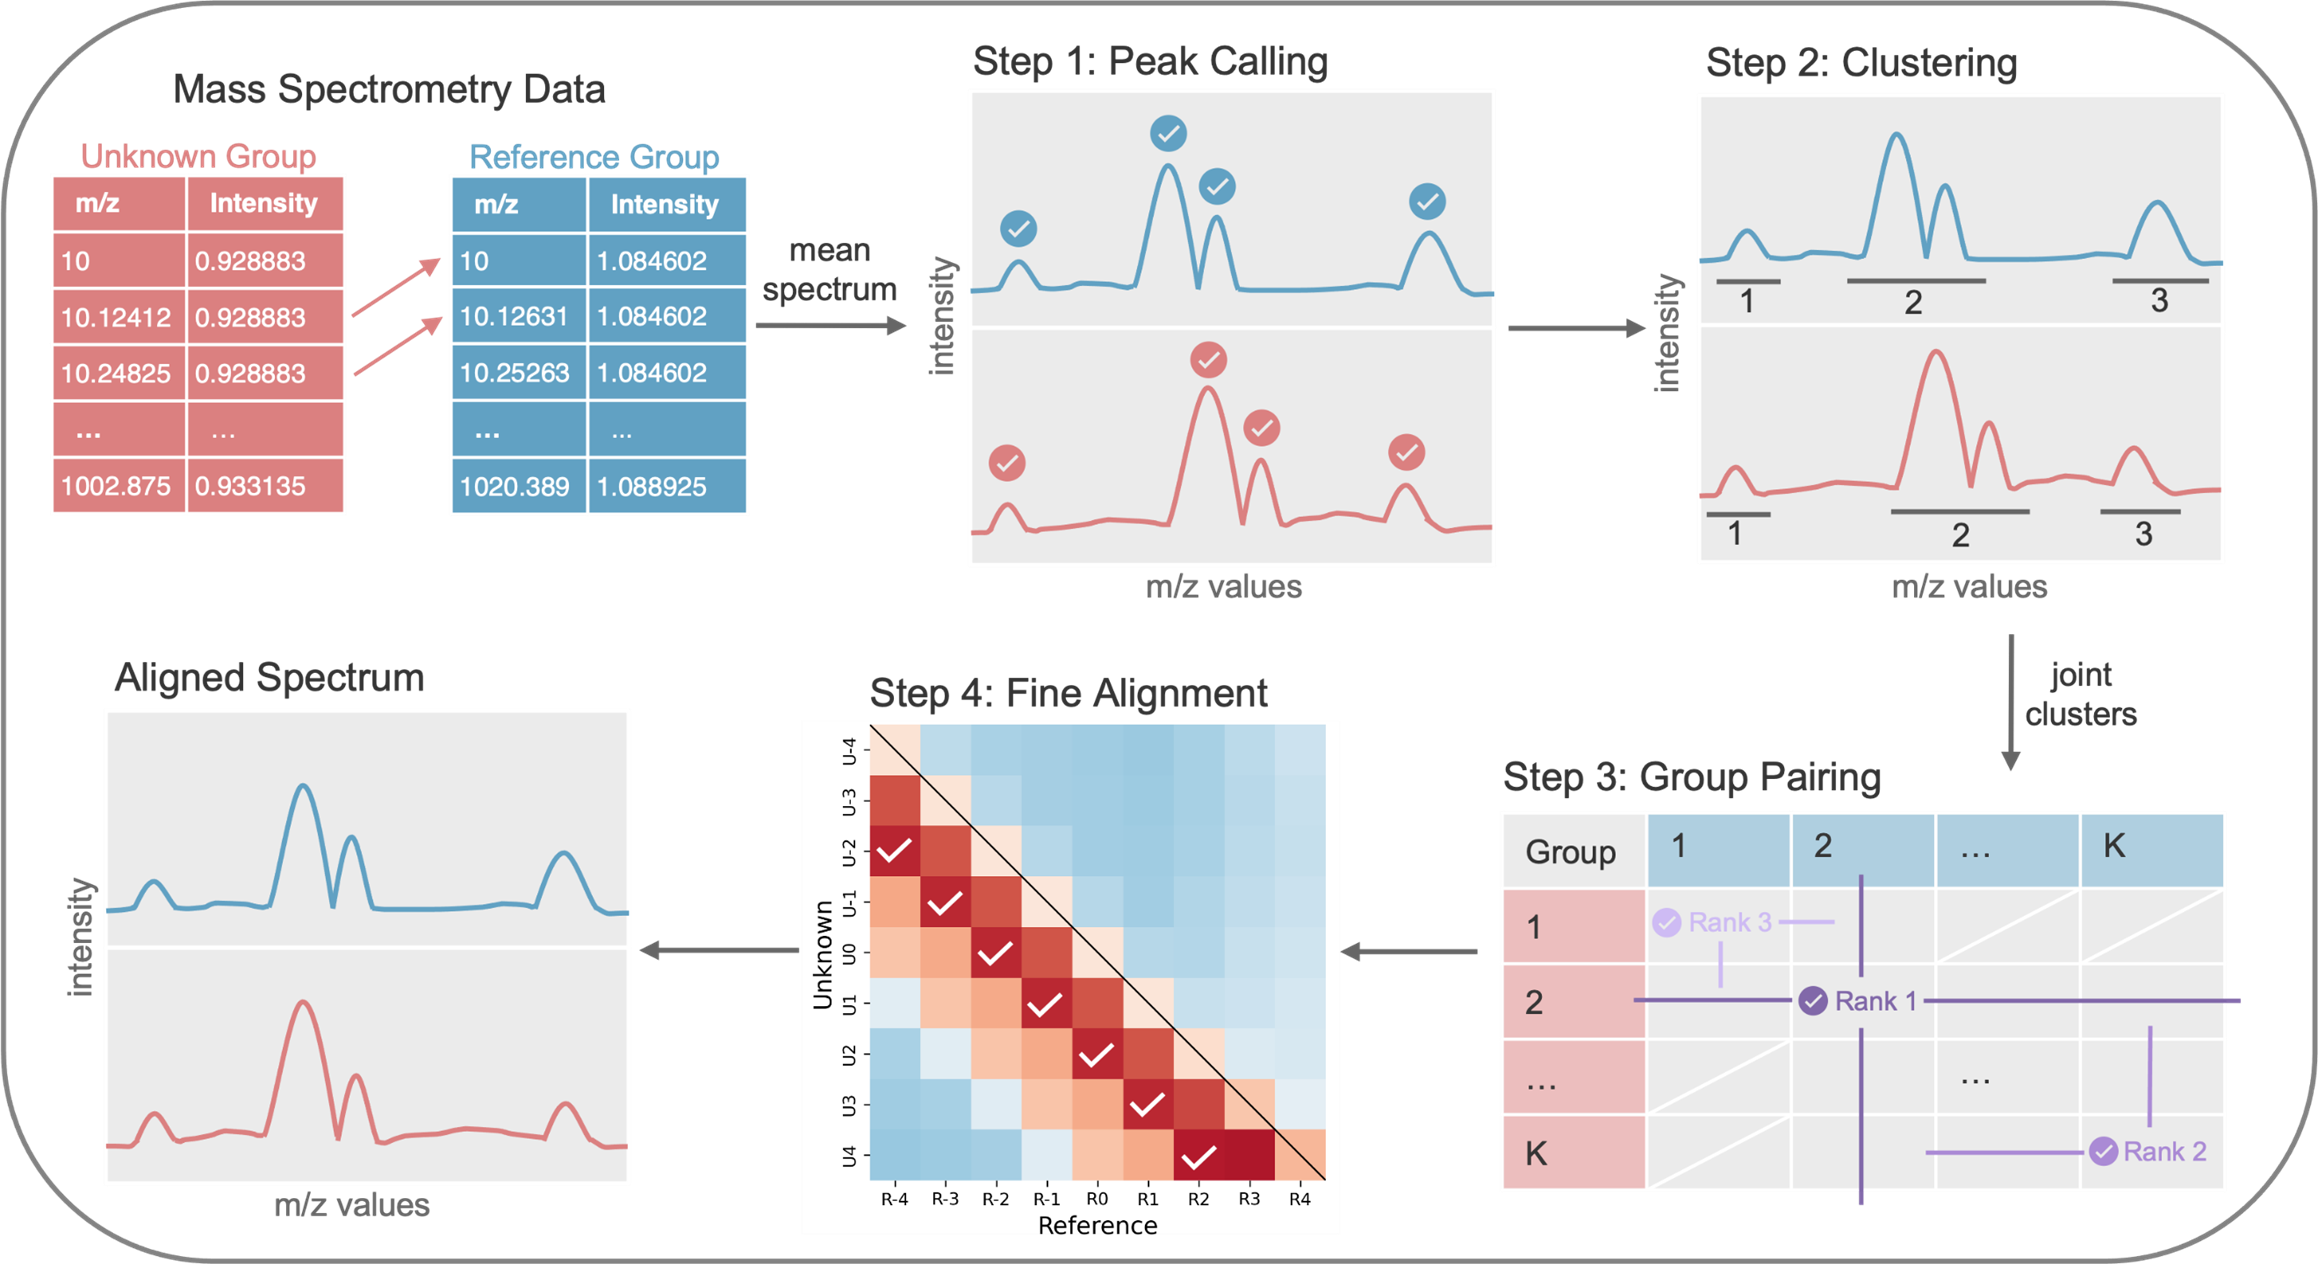
The four-step pipeline in the paper maps to the following public methods:
|
|
117
|
+
|
|
118
|
+
| Step | Manuscript section | Object · method |
|
|
119
|
+
|-----:|-----------------------------|---------------------------------------------------|
|
|
120
|
+
| 1 | Peak Calling | `PeakCalling.peak_calling(threshold=0.9)` |
|
|
121
|
+
| 2 | Peak Grouping | `PeakCalling.peak_grouping(percentile=0.9)` |
|
|
122
|
+
| 3 | Peak Group Pairing | `AnnDataMALDI.peak_group_pairing(criteria=0)` |
|
|
123
|
+
| 4 | Fine Alignment Assessment | `AnnDataMALDI.fine_alignment_assessment(threshold=0.2)` |
|
|
124
|
+
|
|
125
|
+
Similarity is measured with Pearson's correlation; Step 3 uses a sliding
|
|
126
|
+
window of +/- 4 grid points (see Methods of the paper). `pg.align(unk, ref)`
|
|
127
|
+
runs all four steps in one call (see Quick start).
|
|
128
|
+
|
|
129
|
+
The pre-2026 method names (`callpeak`, `grouppeaks`, `greedy_match`,
|
|
130
|
+
`fine_align`) are kept as deprecated aliases and emit `DeprecationWarning`.
|
|
131
|
+
|
|
132
|
+
---
|
|
133
|
+
|
|
134
|
+
## Toy data
|
|
135
|
+
|
|
136
|
+
A 120-spectrum / 601-m/z-bin slice of the public mouse pancreas dataset
|
|
137
|
+
(Prade et al., 2020, Zenodo 10.5281/zenodo.3607915, CC BY 4.0) ships with the
|
|
138
|
+
package for tutorials and tests:
|
|
139
|
+
|
|
140
|
+
```python
|
|
141
|
+
import pgalign as pg
|
|
142
|
+
unk, ref = pg.datasets.load_mouse_pancreas_toy()
|
|
143
|
+
```
|
|
144
|
+
|
|
145
|
+
The "unknown" spectrum has a planted +2-bin rigid shift relative to the
|
|
146
|
+
reference, so PGAlign should recover a shift of about +2 m/z bins.
|
|
147
|
+
|
|
148
|
+
---
|
|
149
|
+
|
|
150
|
+
## Reading your data
|
|
151
|
+
|
|
152
|
+
```python
|
|
153
|
+
unk = pg.read_imzml("unknown.imzML", increment=0.25) # pip install "pgalign[imzml]"
|
|
154
|
+
ref = pg.read_imzml("reference.imzML", increment=0.25)
|
|
155
|
+
```
|
|
156
|
+
|
|
157
|
+
`pg.read_imzml` reads continuous imzML as it is and puts processed imzML, where
|
|
158
|
+
each spectrum carries its own m/z values, on a common grid. `pg.read_scils_csv`
|
|
159
|
+
reads SCiLS Lab CSV exports, and `pg.read_h5ad` reads `.h5ad` files. Each gives an
|
|
160
|
+
`AnnData` with the m/z values in `var["m/z"]`, ready for `pg.align`. Save results
|
|
161
|
+
with `pg.write_h5ad(res.aligned, "aligned.h5ad")`: anndata 0.13 and later cannot write a column named `m/z`, so `pg.write_h5ad` stores
|
|
162
|
+
it as `mz` and `pg.read_h5ad` restores it.
|
|
163
|
+
|
|
164
|
+
---
|
|
165
|
+
|
|
166
|
+
## Command line
|
|
167
|
+
|
|
168
|
+
```bash
|
|
169
|
+
pgalign align unknown.imzML reference.imzML -o aligned.h5ad --increment 0.25
|
|
170
|
+
```
|
|
171
|
+
|
|
172
|
+
This prints the summary line and writes the aligned unknown spectra to
|
|
173
|
+
`aligned.h5ad`, the reference on the same bins to `aligned_reference.h5ad`, and
|
|
174
|
+
the two tables to `aligned_shifts.csv` and `aligned_ambiguity.csv`; read the
|
|
175
|
+
`.h5ad` files back with `pg.read_h5ad`. Inputs can be
|
|
176
|
+
`.imzML`, `.h5ad` or SCiLS `.csv` exports. `pgalign align --help` lists the
|
|
177
|
+
options, which mirror those of `pg.align`.
|
|
178
|
+
|
|
179
|
+
---
|
|
180
|
+
|
|
181
|
+
## Quick start
|
|
182
|
+
|
|
183
|
+
```python
|
|
184
|
+
import pgalign as pg
|
|
185
|
+
|
|
186
|
+
unk, ref = pg.datasets.load_mouse_pancreas_toy() # or your own two AnnData objects
|
|
187
|
+
res = pg.align(unk, ref)
|
|
188
|
+
print(res.summary()) # 7 groups paired, 7 shifted, 0 flagged at tau = 0.1
|
|
189
|
+
aligned = res.aligned # the unknown spectra on the reference m/z grid
|
|
190
|
+
```
|
|
191
|
+
|
|
192
|
+
`pg.align` normalizes each spectrum, runs the four steps with the manuscript's
|
|
193
|
+
defaults and returns the aligned dataset with two tables: `res.shifts`, one row
|
|
194
|
+
per paired peak group with its offset, and `res.ambiguity`, the diagnostic
|
|
195
|
+
described under [Flagging ambiguous alignments](https://github.com/StaGill/PGAlign#flagging-ambiguous-alignments).
|
|
196
|
+
By default it calls peaks on the three-point moving average described in the
|
|
197
|
+
Methods; pass `smooth=False` for the peak caller used in the simulation study
|
|
198
|
+
and the canine sarcoma analysis. The inputs are not modified.
|
|
199
|
+
|
|
200
|
+
### Step by step
|
|
201
|
+
|
|
202
|
+
The notebooks under `CodeInPaper/` run the pipeline one step at a time, and
|
|
203
|
+
`Tutorial_PGAlign.ipynb` gives a worked example. The basic workflow is:
|
|
204
|
+
|
|
205
|
+
1. Load two MALDI datasets (e.g., two time points or two tissues) with optional spatial coordinates.
|
|
206
|
+
2. Wrap them as `AnnData` objects (via `scanpy` / `anndata`).
|
|
207
|
+
3. Normalize intensities per spectrum.
|
|
208
|
+
4. Run the four PGAlign steps.
|
|
209
|
+
5. Extract the aligned spectra for joint downstream analyses (e.g., PCA + Harmony + clustering).
|
|
210
|
+
|
|
211
|
+
```python
|
|
212
|
+
import scanpy as sc
|
|
213
|
+
import pgalign as pg
|
|
214
|
+
|
|
215
|
+
# X = spectra, var = m/z table, obs = coordinates (see Tutorial_PGAlign.ipynb)
|
|
216
|
+
MALDIdataAnn1 = ... # unknown spectrum
|
|
217
|
+
MALDIdataAnn2 = ... # reference spectrum
|
|
218
|
+
|
|
219
|
+
# Per-spectrum normalisation
|
|
220
|
+
sc.pp.normalize_per_cell(MALDIdataAnn1)
|
|
221
|
+
sc.pp.normalize_per_cell(MALDIdataAnn2)
|
|
222
|
+
|
|
223
|
+
# Step 1 + Step 2: peak calling and peak grouping
|
|
224
|
+
PeakGroup = pg.PeakCalling(MALDIdataAnn1, MALDIdataAnn2) # pg.align uses pg.PeakCallingmv by default
|
|
225
|
+
PeakGroup.peak_calling(threshold=0.9)
|
|
226
|
+
PeakGroup.peak_grouping(percentile=0.9)
|
|
227
|
+
|
|
228
|
+
# Step 3: peak group pairing
|
|
229
|
+
ExactAlign = pg.AnnDataMALDI(MALDIdataAnn1, MALDIdataAnn2)
|
|
230
|
+
ExactAlign.get_corr_peakgroup_refined(PeakGroup.jointcluster)
|
|
231
|
+
ExactAlign.peak_group_pairing(criteria=0)
|
|
232
|
+
|
|
233
|
+
# Step 4: fine alignment assessment
|
|
234
|
+
ExactAlign.fine_alignment_assessment(threshold=0.2, ignore=True)
|
|
235
|
+
ExactAlign.summarize()
|
|
236
|
+
|
|
237
|
+
# The aligned dataset: the unknown spectra on the reference m/z grid
|
|
238
|
+
MALDIdataAnn1_aligned = pg.PGmzalign(ExactAlign).getAnnSim()
|
|
239
|
+
```
|
|
240
|
+
|
|
241
|
+
`getAnnSim()` returns the unknown spectra as an `AnnData` whose `var["m/z"]`
|
|
242
|
+
are the reference's m/z values, so it can be analysed jointly with the
|
|
243
|
+
reference. Despite the method's name, nothing is simulated. The result is cut
|
|
244
|
+
to the shorter of the two m/z axes, so it can lack a few bins at the top of the
|
|
245
|
+
range.
|
|
246
|
+
|
|
247
|
+
Please refer to `Tutorial_PGAlign.ipynb` for a fully worked example with real
|
|
248
|
+
data and plots.
|
|
249
|
+
|
|
250
|
+
### Flagging ambiguous alignments
|
|
251
|
+
|
|
252
|
+
A shifted peak group always has one alternative: staying at its original
|
|
253
|
+
position. After Step 4, `flag_ambiguous_alignments` flags a shifted group when
|
|
254
|
+
staying scores within `delta` (default 0.1) of the chosen alignment, using the
|
|
255
|
+
pairing similarity for groups matched to a different reference group and the
|
|
256
|
+
zero-offset diagonal for groups moved by a non-zero offset. Flagged groups are
|
|
257
|
+
reported with both scores, so you can inspect them before downstream analysis.
|
|
258
|
+
|
|
259
|
+
```python
|
|
260
|
+
ExactAlign.fine_alignment_assessment(threshold=0.2, ignore=True)
|
|
261
|
+
table = ExactAlign.flag_ambiguous_alignments(delta=0.1)
|
|
262
|
+
print(table[table["flagged"]])
|
|
263
|
+
print(f"{table['flagged'].sum()} of {len(table)} shifted groups flagged")
|
|
264
|
+
print(table.groupby("rule")["flagged"].agg(["sum", "size"]))
|
|
265
|
+
```
|
|
266
|
+
|
|
267
|
+
The `rule` column says which comparison a row was assessed by: `"group"` for
|
|
268
|
+
a group paired with a different reference group, `"offset"` for a group
|
|
269
|
+
paired at its own position but moved by a non-zero offset.
|
|
270
|
+
|
|
271
|
+
---
|
|
272
|
+
|
|
273
|
+
## Reproducing results from the manuscript
|
|
274
|
+
|
|
275
|
+
Release v1.0.1 is the version that accompanies the manuscript. Later releases
|
|
276
|
+
may change the results, so install that version to reproduce them:
|
|
277
|
+
|
|
278
|
+
```bash
|
|
279
|
+
pip install "git+https://github.com/StaGill/PGAlign@v1.0.1"
|
|
280
|
+
```
|
|
281
|
+
|
|
282
|
+
The notebooks under `CodeInPaper/` reproduce the main analyses; run them from a
|
|
283
|
+
checkout of the same release (`git checkout v1.0.1`). Each subfolder has its
|
|
284
|
+
own `README.md` with dataset access instructions:
|
|
285
|
+
|
|
286
|
+
- **Simulation study (mouse pancreas MALDI)**: alignment error under
|
|
287
|
+
controlled peak shifts and noise. See `CodeInPaper/MousePancreate.ipynb`.
|
|
288
|
+
- **Macrophage metabolomics (atherosclerosis regression)**: aligns Week 5
|
|
289
|
+
MALDI spectra to Week 2 and performs joint spatial segmentation. See
|
|
290
|
+
`CodeInPaper/Maaike/`.
|
|
291
|
+
- **Canine sarcoma classification**: aligns cancer tissue spectra to normal
|
|
292
|
+
tissue and assesses classification performance before/after alignment. See
|
|
293
|
+
`CodeInPaper/Sarcomas/`.
|
|
294
|
+
|
|
295
|
+
**Data sources:**
|
|
296
|
+
|
|
297
|
+
- Mouse pancreas MALDI: <https://doi.org/10.5281/zenodo.3607915>
|
|
298
|
+
- Atherosclerosis regression MALDI: mean spectra on Zenodo (<https://zenodo.org/records/20533948>); the per-spot
|
|
299
|
+
spectra that the notebooks read are available from the data owners upon reasonable request.
|
|
300
|
+
- Canine sarcoma MALDI: ProteomeXchange PRIDE accession `PXD010990` (<https://proteomecentral.proteomexchange.org/cgi/GetDataset?ID=PXD010990>).
|
|
301
|
+
|
|
302
|
+
---
|
|
303
|
+
|
|
304
|
+
## Citation
|
|
305
|
+
|
|
306
|
+
The PGAlign manuscript is currently under peer review. If you use PGAlign in
|
|
307
|
+
your research, please cite this repository (see `CITATION.cff`, which GitHub
|
|
308
|
+
renders as a "Cite this repository" button) and contact the corresponding
|
|
309
|
+
author for the latest preprint:
|
|
310
|
+
|
|
311
|
+
> Deng A, Zhang Y, Zhang Q. *PGAlign: peak group alignment of mass spectrometry data*.
|
|
312
|
+
> Under review at the *Journal of Proteome Research*, 2026.
|
|
313
|
+
|
|
314
|
+
---
|
|
315
|
+
|
|
316
|
+
## License
|
|
317
|
+
|
|
318
|
+
MIT (see `LICENSE`).
|
pgalign-1.1.0/README.md
ADDED
|
@@ -0,0 +1,279 @@
|
|
|
1
|
+
<p align="center">
|
|
2
|
+
<picture>
|
|
3
|
+
<source media="(prefers-color-scheme: dark)" srcset="https://raw.githubusercontent.com/StaGill/PGAlign/main/images/pgalign_logo_dark.svg">
|
|
4
|
+
<img src="https://raw.githubusercontent.com/StaGill/PGAlign/main/images/pgalign_logo.svg" alt="PGAlign" width="420">
|
|
5
|
+
</picture>
|
|
6
|
+
</p>
|
|
7
|
+
|
|
8
|
+
<p align="center">
|
|
9
|
+
<a href="https://github.com/StaGill/PGAlign/actions/workflows/tests.yml"><img src="https://github.com/StaGill/PGAlign/actions/workflows/tests.yml/badge.svg?branch=main" alt="tests"></a>
|
|
10
|
+
<a href="https://stagill.github.io/PGAlign/"><img src="https://github.com/StaGill/PGAlign/actions/workflows/docs.yml/badge.svg?branch=main" alt="docs"></a>
|
|
11
|
+
<a href="https://github.com/StaGill/PGAlign/releases"><img src="https://img.shields.io/github/v/release/StaGill/PGAlign" alt="release"></a>
|
|
12
|
+
<a href="https://github.com/StaGill/PGAlign/blob/main/LICENSE"><img src="https://img.shields.io/github/license/StaGill/PGAlign" alt="license"></a>
|
|
13
|
+
</p>
|
|
14
|
+
|
|
15
|
+
**PGAlign (Peak-Group Alignment of mass spectrometry data)** is a peak-group-based
|
|
16
|
+
algorithm for aligning mass spectrometry (MS) spectra onto a common m/z grid.
|
|
17
|
+
It is designed for imaging and spatial metabolomics data such as MALDI-MS,
|
|
18
|
+
where spectra from different runs or tissues often exhibit small m/z shifts
|
|
19
|
+
that prevent direct comparison.
|
|
20
|
+
|
|
21
|
+
Anji Deng, Yuyang Zhang, and Qihuang Zhang\*
|
|
22
|
+
McGill University (corresponding author: <qihuang.zhang@mcgill.ca>)
|
|
23
|
+
|
|
24
|
+
**Documentation:** <https://stagill.github.io/PGAlign/>
|
|
25
|
+
|
|
26
|
+

|
|
27
|
+
|
|
28
|
+
By aligning an "unknown" spectrum (or dataset) to a reference while *forcing*
|
|
29
|
+
matched spectra to share the same m/z values, PGAlign enables downstream
|
|
30
|
+
analyses such as:
|
|
31
|
+
|
|
32
|
+
- joint spatial segmentation across tissues or time points
|
|
33
|
+
- classification using combined datasets
|
|
34
|
+
- other multi-sample analyses that require a common m/z grid
|
|
35
|
+
|
|
36
|
+
This repository contains the reference Python implementation accompanying the
|
|
37
|
+
PGAlign manuscript (Deng, Zhang & Zhang, 2026; under peer review).
|
|
38
|
+
|
|
39
|
+
---
|
|
40
|
+
|
|
41
|
+
## Repository layout
|
|
42
|
+
|
|
43
|
+
- `pgalign/`: Core Python implementation of PGAlign (alignment and peak-group functions).
|
|
44
|
+
- `CodeInPaper/`: Scripts that reproduce the figures and results in the manuscript. See `CodeInPaper/README.md`.
|
|
45
|
+
- `Tutorial_PGAlign.ipynb`: A Jupyter notebook that walks through aligning two MALDI datasets (e.g., Week 2 and Week 5 macrophage samples) and preparing them for joint segmentation.
|
|
46
|
+
- `tests/`: Smoke tests (`pytest`).
|
|
47
|
+
- `CITATION.cff`: Citation metadata.
|
|
48
|
+
- `LICENSE`: MIT license.
|
|
49
|
+
|
|
50
|
+
---
|
|
51
|
+
|
|
52
|
+
## Installation
|
|
53
|
+
|
|
54
|
+
```bash
|
|
55
|
+
pip install pgalign # or "pgalign[imzml]" to read imzML files
|
|
56
|
+
```
|
|
57
|
+
|
|
58
|
+
To work from the source, clone the repository and install it with `pip`:
|
|
59
|
+
|
|
60
|
+
```bash
|
|
61
|
+
git clone https://github.com/StaGill/PGAlign.git
|
|
62
|
+
cd PGAlign
|
|
63
|
+
pip install -e .
|
|
64
|
+
```
|
|
65
|
+
|
|
66
|
+
The package's importable name is `pgalign`:
|
|
67
|
+
|
|
68
|
+
```python
|
|
69
|
+
import pgalign as pg
|
|
70
|
+
print(pg.__version__)
|
|
71
|
+
```
|
|
72
|
+
|
|
73
|
+
---
|
|
74
|
+
|
|
75
|
+
## API at a glance
|
|
76
|
+
|
|
77
|
+
The four-step pipeline in the paper maps to the following public methods:
|
|
78
|
+
|
|
79
|
+
| Step | Manuscript section | Object · method |
|
|
80
|
+
|-----:|-----------------------------|---------------------------------------------------|
|
|
81
|
+
| 1 | Peak Calling | `PeakCalling.peak_calling(threshold=0.9)` |
|
|
82
|
+
| 2 | Peak Grouping | `PeakCalling.peak_grouping(percentile=0.9)` |
|
|
83
|
+
| 3 | Peak Group Pairing | `AnnDataMALDI.peak_group_pairing(criteria=0)` |
|
|
84
|
+
| 4 | Fine Alignment Assessment | `AnnDataMALDI.fine_alignment_assessment(threshold=0.2)` |
|
|
85
|
+
|
|
86
|
+
Similarity is measured with Pearson's correlation; Step 3 uses a sliding
|
|
87
|
+
window of +/- 4 grid points (see Methods of the paper). `pg.align(unk, ref)`
|
|
88
|
+
runs all four steps in one call (see Quick start).
|
|
89
|
+
|
|
90
|
+
The pre-2026 method names (`callpeak`, `grouppeaks`, `greedy_match`,
|
|
91
|
+
`fine_align`) are kept as deprecated aliases and emit `DeprecationWarning`.
|
|
92
|
+
|
|
93
|
+
---
|
|
94
|
+
|
|
95
|
+
## Toy data
|
|
96
|
+
|
|
97
|
+
A 120-spectrum / 601-m/z-bin slice of the public mouse pancreas dataset
|
|
98
|
+
(Prade et al., 2020, Zenodo 10.5281/zenodo.3607915, CC BY 4.0) ships with the
|
|
99
|
+
package for tutorials and tests:
|
|
100
|
+
|
|
101
|
+
```python
|
|
102
|
+
import pgalign as pg
|
|
103
|
+
unk, ref = pg.datasets.load_mouse_pancreas_toy()
|
|
104
|
+
```
|
|
105
|
+
|
|
106
|
+
The "unknown" spectrum has a planted +2-bin rigid shift relative to the
|
|
107
|
+
reference, so PGAlign should recover a shift of about +2 m/z bins.
|
|
108
|
+
|
|
109
|
+
---
|
|
110
|
+
|
|
111
|
+
## Reading your data
|
|
112
|
+
|
|
113
|
+
```python
|
|
114
|
+
unk = pg.read_imzml("unknown.imzML", increment=0.25) # pip install "pgalign[imzml]"
|
|
115
|
+
ref = pg.read_imzml("reference.imzML", increment=0.25)
|
|
116
|
+
```
|
|
117
|
+
|
|
118
|
+
`pg.read_imzml` reads continuous imzML as it is and puts processed imzML, where
|
|
119
|
+
each spectrum carries its own m/z values, on a common grid. `pg.read_scils_csv`
|
|
120
|
+
reads SCiLS Lab CSV exports, and `pg.read_h5ad` reads `.h5ad` files. Each gives an
|
|
121
|
+
`AnnData` with the m/z values in `var["m/z"]`, ready for `pg.align`. Save results
|
|
122
|
+
with `pg.write_h5ad(res.aligned, "aligned.h5ad")`: anndata 0.13 and later cannot write a column named `m/z`, so `pg.write_h5ad` stores
|
|
123
|
+
it as `mz` and `pg.read_h5ad` restores it.
|
|
124
|
+
|
|
125
|
+
---
|
|
126
|
+
|
|
127
|
+
## Command line
|
|
128
|
+
|
|
129
|
+
```bash
|
|
130
|
+
pgalign align unknown.imzML reference.imzML -o aligned.h5ad --increment 0.25
|
|
131
|
+
```
|
|
132
|
+
|
|
133
|
+
This prints the summary line and writes the aligned unknown spectra to
|
|
134
|
+
`aligned.h5ad`, the reference on the same bins to `aligned_reference.h5ad`, and
|
|
135
|
+
the two tables to `aligned_shifts.csv` and `aligned_ambiguity.csv`; read the
|
|
136
|
+
`.h5ad` files back with `pg.read_h5ad`. Inputs can be
|
|
137
|
+
`.imzML`, `.h5ad` or SCiLS `.csv` exports. `pgalign align --help` lists the
|
|
138
|
+
options, which mirror those of `pg.align`.
|
|
139
|
+
|
|
140
|
+
---
|
|
141
|
+
|
|
142
|
+
## Quick start
|
|
143
|
+
|
|
144
|
+
```python
|
|
145
|
+
import pgalign as pg
|
|
146
|
+
|
|
147
|
+
unk, ref = pg.datasets.load_mouse_pancreas_toy() # or your own two AnnData objects
|
|
148
|
+
res = pg.align(unk, ref)
|
|
149
|
+
print(res.summary()) # 7 groups paired, 7 shifted, 0 flagged at tau = 0.1
|
|
150
|
+
aligned = res.aligned # the unknown spectra on the reference m/z grid
|
|
151
|
+
```
|
|
152
|
+
|
|
153
|
+
`pg.align` normalizes each spectrum, runs the four steps with the manuscript's
|
|
154
|
+
defaults and returns the aligned dataset with two tables: `res.shifts`, one row
|
|
155
|
+
per paired peak group with its offset, and `res.ambiguity`, the diagnostic
|
|
156
|
+
described under [Flagging ambiguous alignments](https://github.com/StaGill/PGAlign#flagging-ambiguous-alignments).
|
|
157
|
+
By default it calls peaks on the three-point moving average described in the
|
|
158
|
+
Methods; pass `smooth=False` for the peak caller used in the simulation study
|
|
159
|
+
and the canine sarcoma analysis. The inputs are not modified.
|
|
160
|
+
|
|
161
|
+
### Step by step
|
|
162
|
+
|
|
163
|
+
The notebooks under `CodeInPaper/` run the pipeline one step at a time, and
|
|
164
|
+
`Tutorial_PGAlign.ipynb` gives a worked example. The basic workflow is:
|
|
165
|
+
|
|
166
|
+
1. Load two MALDI datasets (e.g., two time points or two tissues) with optional spatial coordinates.
|
|
167
|
+
2. Wrap them as `AnnData` objects (via `scanpy` / `anndata`).
|
|
168
|
+
3. Normalize intensities per spectrum.
|
|
169
|
+
4. Run the four PGAlign steps.
|
|
170
|
+
5. Extract the aligned spectra for joint downstream analyses (e.g., PCA + Harmony + clustering).
|
|
171
|
+
|
|
172
|
+
```python
|
|
173
|
+
import scanpy as sc
|
|
174
|
+
import pgalign as pg
|
|
175
|
+
|
|
176
|
+
# X = spectra, var = m/z table, obs = coordinates (see Tutorial_PGAlign.ipynb)
|
|
177
|
+
MALDIdataAnn1 = ... # unknown spectrum
|
|
178
|
+
MALDIdataAnn2 = ... # reference spectrum
|
|
179
|
+
|
|
180
|
+
# Per-spectrum normalisation
|
|
181
|
+
sc.pp.normalize_per_cell(MALDIdataAnn1)
|
|
182
|
+
sc.pp.normalize_per_cell(MALDIdataAnn2)
|
|
183
|
+
|
|
184
|
+
# Step 1 + Step 2: peak calling and peak grouping
|
|
185
|
+
PeakGroup = pg.PeakCalling(MALDIdataAnn1, MALDIdataAnn2) # pg.align uses pg.PeakCallingmv by default
|
|
186
|
+
PeakGroup.peak_calling(threshold=0.9)
|
|
187
|
+
PeakGroup.peak_grouping(percentile=0.9)
|
|
188
|
+
|
|
189
|
+
# Step 3: peak group pairing
|
|
190
|
+
ExactAlign = pg.AnnDataMALDI(MALDIdataAnn1, MALDIdataAnn2)
|
|
191
|
+
ExactAlign.get_corr_peakgroup_refined(PeakGroup.jointcluster)
|
|
192
|
+
ExactAlign.peak_group_pairing(criteria=0)
|
|
193
|
+
|
|
194
|
+
# Step 4: fine alignment assessment
|
|
195
|
+
ExactAlign.fine_alignment_assessment(threshold=0.2, ignore=True)
|
|
196
|
+
ExactAlign.summarize()
|
|
197
|
+
|
|
198
|
+
# The aligned dataset: the unknown spectra on the reference m/z grid
|
|
199
|
+
MALDIdataAnn1_aligned = pg.PGmzalign(ExactAlign).getAnnSim()
|
|
200
|
+
```
|
|
201
|
+
|
|
202
|
+
`getAnnSim()` returns the unknown spectra as an `AnnData` whose `var["m/z"]`
|
|
203
|
+
are the reference's m/z values, so it can be analysed jointly with the
|
|
204
|
+
reference. Despite the method's name, nothing is simulated. The result is cut
|
|
205
|
+
to the shorter of the two m/z axes, so it can lack a few bins at the top of the
|
|
206
|
+
range.
|
|
207
|
+
|
|
208
|
+
Please refer to `Tutorial_PGAlign.ipynb` for a fully worked example with real
|
|
209
|
+
data and plots.
|
|
210
|
+
|
|
211
|
+
### Flagging ambiguous alignments
|
|
212
|
+
|
|
213
|
+
A shifted peak group always has one alternative: staying at its original
|
|
214
|
+
position. After Step 4, `flag_ambiguous_alignments` flags a shifted group when
|
|
215
|
+
staying scores within `delta` (default 0.1) of the chosen alignment, using the
|
|
216
|
+
pairing similarity for groups matched to a different reference group and the
|
|
217
|
+
zero-offset diagonal for groups moved by a non-zero offset. Flagged groups are
|
|
218
|
+
reported with both scores, so you can inspect them before downstream analysis.
|
|
219
|
+
|
|
220
|
+
```python
|
|
221
|
+
ExactAlign.fine_alignment_assessment(threshold=0.2, ignore=True)
|
|
222
|
+
table = ExactAlign.flag_ambiguous_alignments(delta=0.1)
|
|
223
|
+
print(table[table["flagged"]])
|
|
224
|
+
print(f"{table['flagged'].sum()} of {len(table)} shifted groups flagged")
|
|
225
|
+
print(table.groupby("rule")["flagged"].agg(["sum", "size"]))
|
|
226
|
+
```
|
|
227
|
+
|
|
228
|
+
The `rule` column says which comparison a row was assessed by: `"group"` for
|
|
229
|
+
a group paired with a different reference group, `"offset"` for a group
|
|
230
|
+
paired at its own position but moved by a non-zero offset.
|
|
231
|
+
|
|
232
|
+
---
|
|
233
|
+
|
|
234
|
+
## Reproducing results from the manuscript
|
|
235
|
+
|
|
236
|
+
Release v1.0.1 is the version that accompanies the manuscript. Later releases
|
|
237
|
+
may change the results, so install that version to reproduce them:
|
|
238
|
+
|
|
239
|
+
```bash
|
|
240
|
+
pip install "git+https://github.com/StaGill/PGAlign@v1.0.1"
|
|
241
|
+
```
|
|
242
|
+
|
|
243
|
+
The notebooks under `CodeInPaper/` reproduce the main analyses; run them from a
|
|
244
|
+
checkout of the same release (`git checkout v1.0.1`). Each subfolder has its
|
|
245
|
+
own `README.md` with dataset access instructions:
|
|
246
|
+
|
|
247
|
+
- **Simulation study (mouse pancreas MALDI)**: alignment error under
|
|
248
|
+
controlled peak shifts and noise. See `CodeInPaper/MousePancreate.ipynb`.
|
|
249
|
+
- **Macrophage metabolomics (atherosclerosis regression)**: aligns Week 5
|
|
250
|
+
MALDI spectra to Week 2 and performs joint spatial segmentation. See
|
|
251
|
+
`CodeInPaper/Maaike/`.
|
|
252
|
+
- **Canine sarcoma classification**: aligns cancer tissue spectra to normal
|
|
253
|
+
tissue and assesses classification performance before/after alignment. See
|
|
254
|
+
`CodeInPaper/Sarcomas/`.
|
|
255
|
+
|
|
256
|
+
**Data sources:**
|
|
257
|
+
|
|
258
|
+
- Mouse pancreas MALDI: <https://doi.org/10.5281/zenodo.3607915>
|
|
259
|
+
- Atherosclerosis regression MALDI: mean spectra on Zenodo (<https://zenodo.org/records/20533948>); the per-spot
|
|
260
|
+
spectra that the notebooks read are available from the data owners upon reasonable request.
|
|
261
|
+
- Canine sarcoma MALDI: ProteomeXchange PRIDE accession `PXD010990` (<https://proteomecentral.proteomexchange.org/cgi/GetDataset?ID=PXD010990>).
|
|
262
|
+
|
|
263
|
+
---
|
|
264
|
+
|
|
265
|
+
## Citation
|
|
266
|
+
|
|
267
|
+
The PGAlign manuscript is currently under peer review. If you use PGAlign in
|
|
268
|
+
your research, please cite this repository (see `CITATION.cff`, which GitHub
|
|
269
|
+
renders as a "Cite this repository" button) and contact the corresponding
|
|
270
|
+
author for the latest preprint:
|
|
271
|
+
|
|
272
|
+
> Deng A, Zhang Y, Zhang Q. *PGAlign: peak group alignment of mass spectrometry data*.
|
|
273
|
+
> Under review at the *Journal of Proteome Research*, 2026.
|
|
274
|
+
|
|
275
|
+
---
|
|
276
|
+
|
|
277
|
+
## License
|
|
278
|
+
|
|
279
|
+
MIT (see `LICENSE`).
|
|
Binary file
|