perfectclone 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- perfectclone-0.1.0/LICENSE +21 -0
- perfectclone-0.1.0/PKG-INFO +192 -0
- perfectclone-0.1.0/README.md +164 -0
- perfectclone-0.1.0/pyproject.toml +52 -0
- perfectclone-0.1.0/setup.cfg +4 -0
- perfectclone-0.1.0/src/perfectclone/__init__.py +2 -0
- perfectclone-0.1.0/src/perfectclone/__main__.py +3 -0
- perfectclone-0.1.0/src/perfectclone/cli.py +112 -0
- perfectclone-0.1.0/src/perfectclone/crawl.py +161 -0
- perfectclone-0.1.0/src/perfectclone/edit.py +109 -0
- perfectclone-0.1.0/src/perfectclone/flight.py +113 -0
- perfectclone-0.1.0/src/perfectclone/mirror.py +168 -0
- perfectclone-0.1.0/src/perfectclone/serve.py +102 -0
- perfectclone-0.1.0/src/perfectclone/trackers.py +93 -0
- perfectclone-0.1.0/src/perfectclone/util.py +25 -0
- perfectclone-0.1.0/src/perfectclone.egg-info/PKG-INFO +192 -0
- perfectclone-0.1.0/src/perfectclone.egg-info/SOURCES.txt +24 -0
- perfectclone-0.1.0/src/perfectclone.egg-info/dependency_links.txt +1 -0
- perfectclone-0.1.0/src/perfectclone.egg-info/entry_points.txt +2 -0
- perfectclone-0.1.0/src/perfectclone.egg-info/requires.txt +6 -0
- perfectclone-0.1.0/src/perfectclone.egg-info/top_level.txt +1 -0
- perfectclone-0.1.0/tests/test_edit.py +56 -0
- perfectclone-0.1.0/tests/test_flight.py +28 -0
- perfectclone-0.1.0/tests/test_mirror.py +59 -0
- perfectclone-0.1.0/tests/test_serve.py +67 -0
- perfectclone-0.1.0/tests/test_trackers.py +31 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
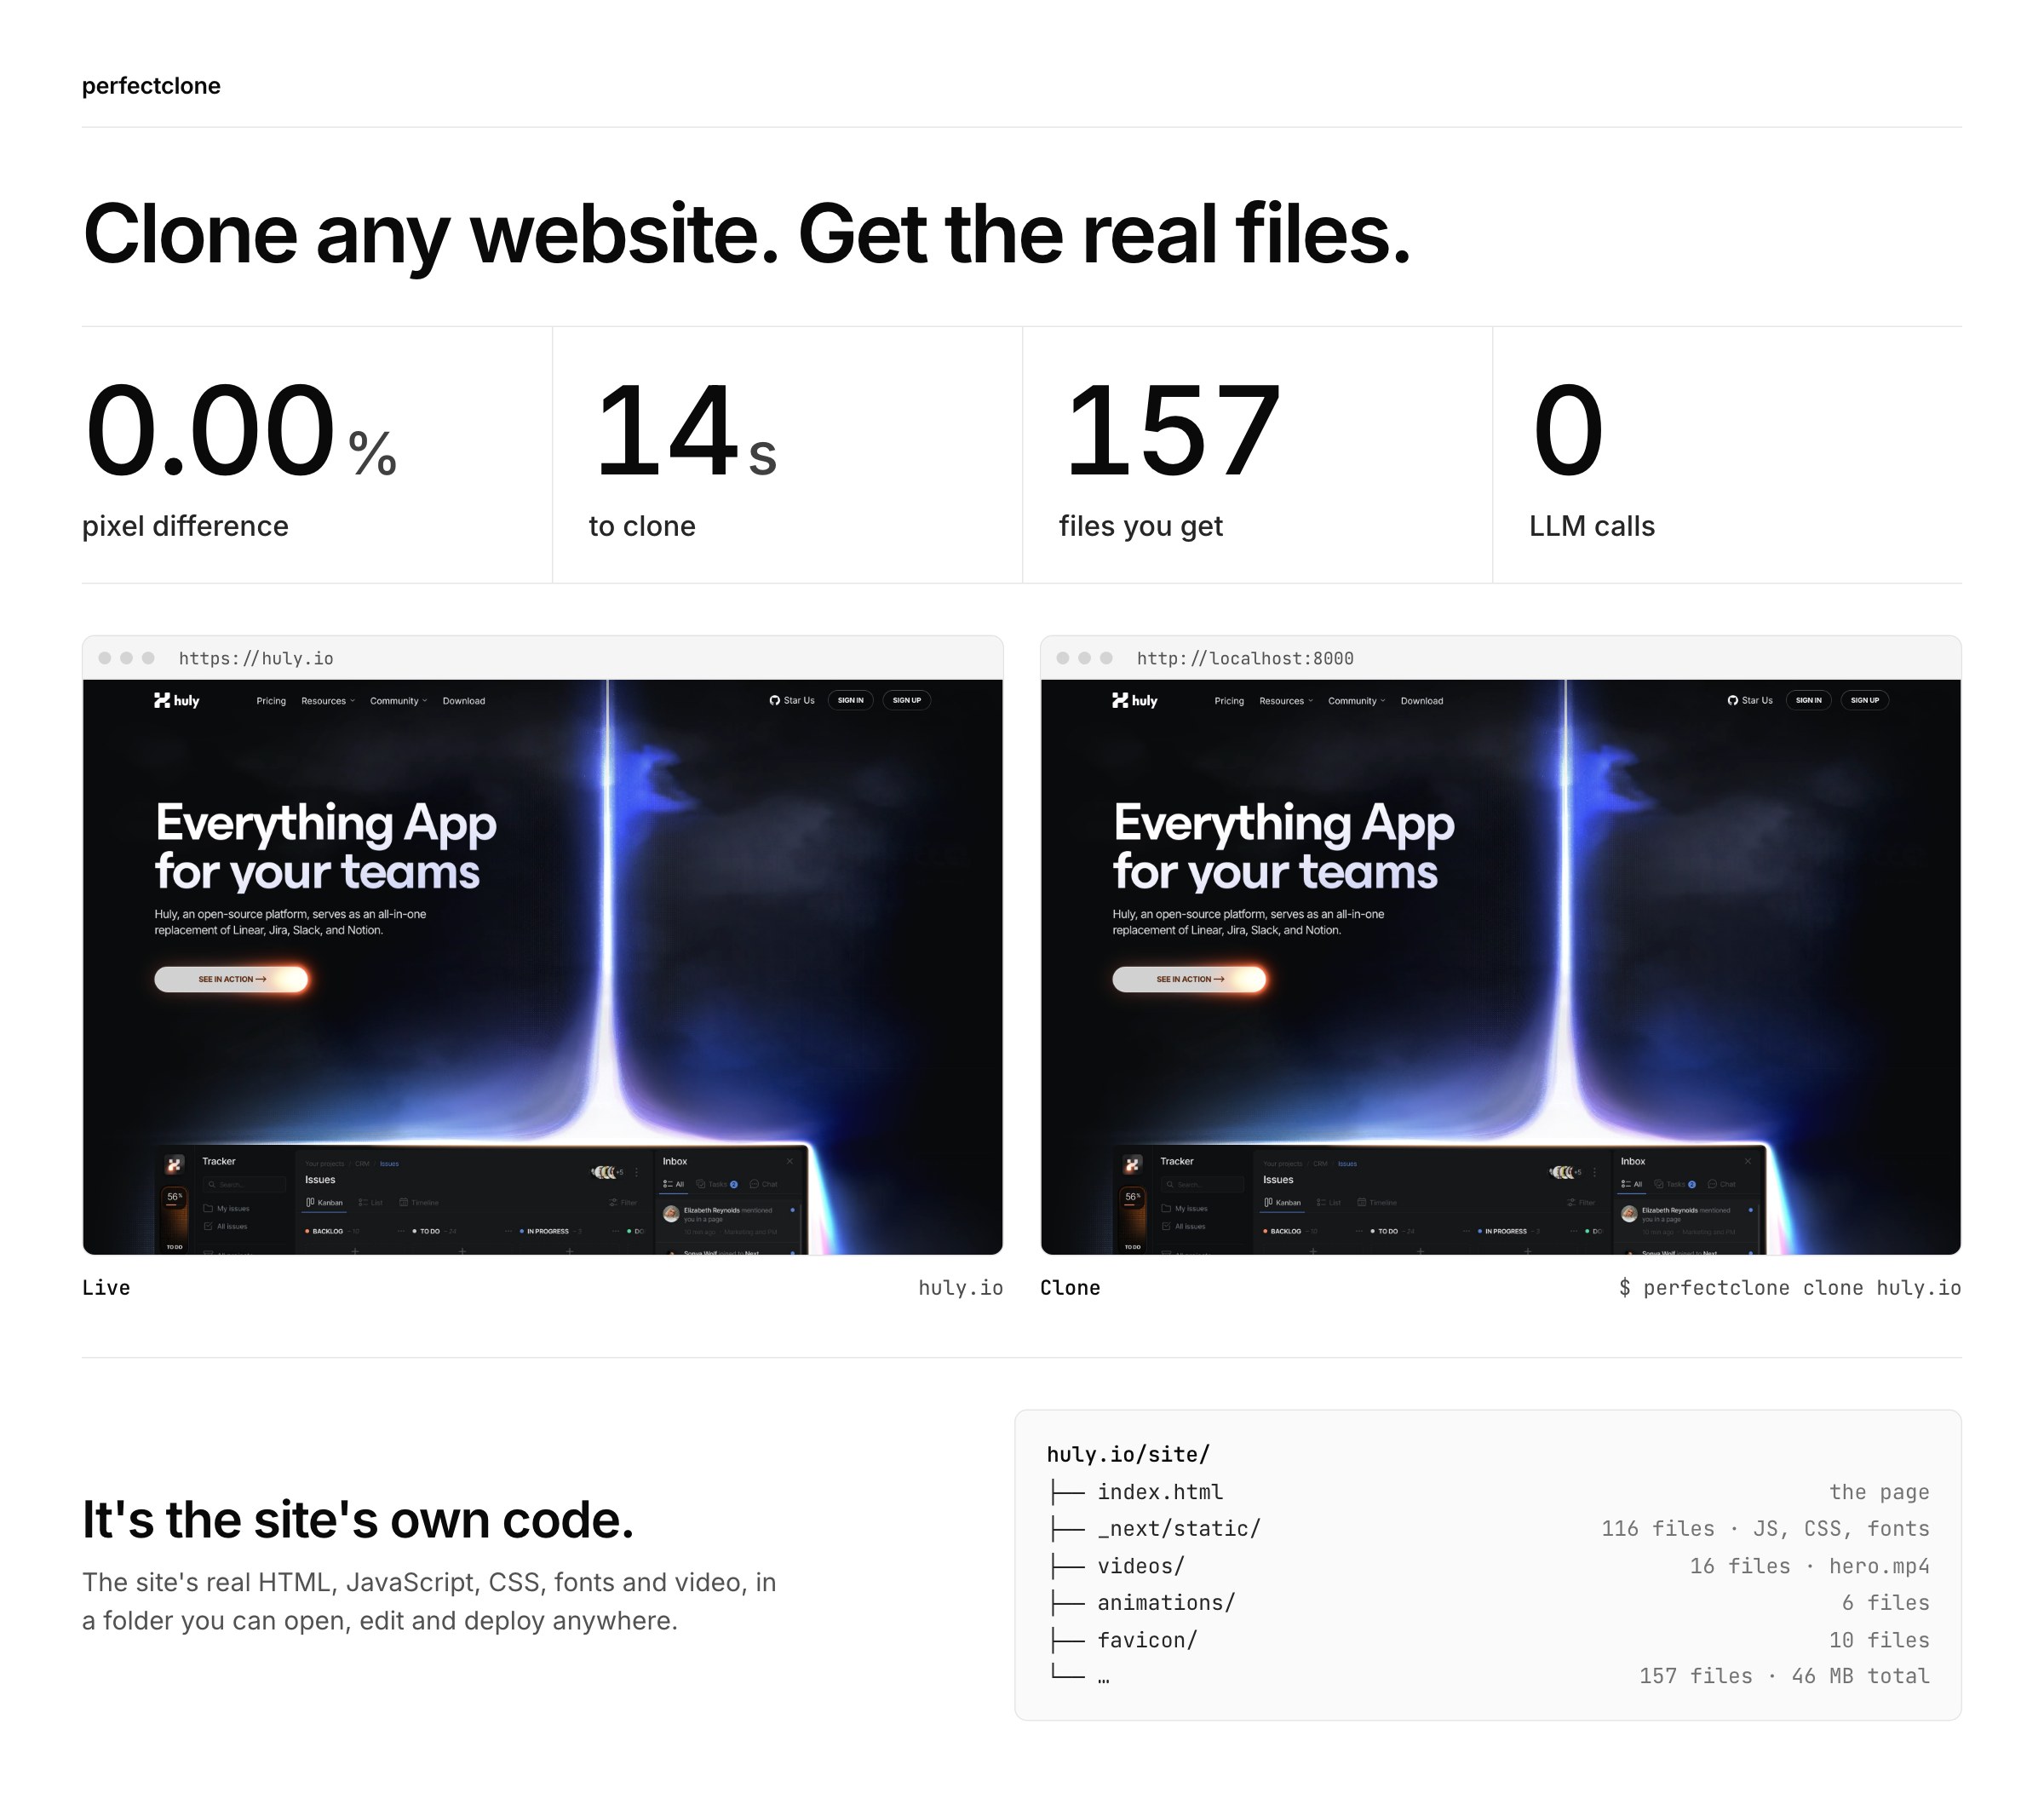
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Eshaan Gulati
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
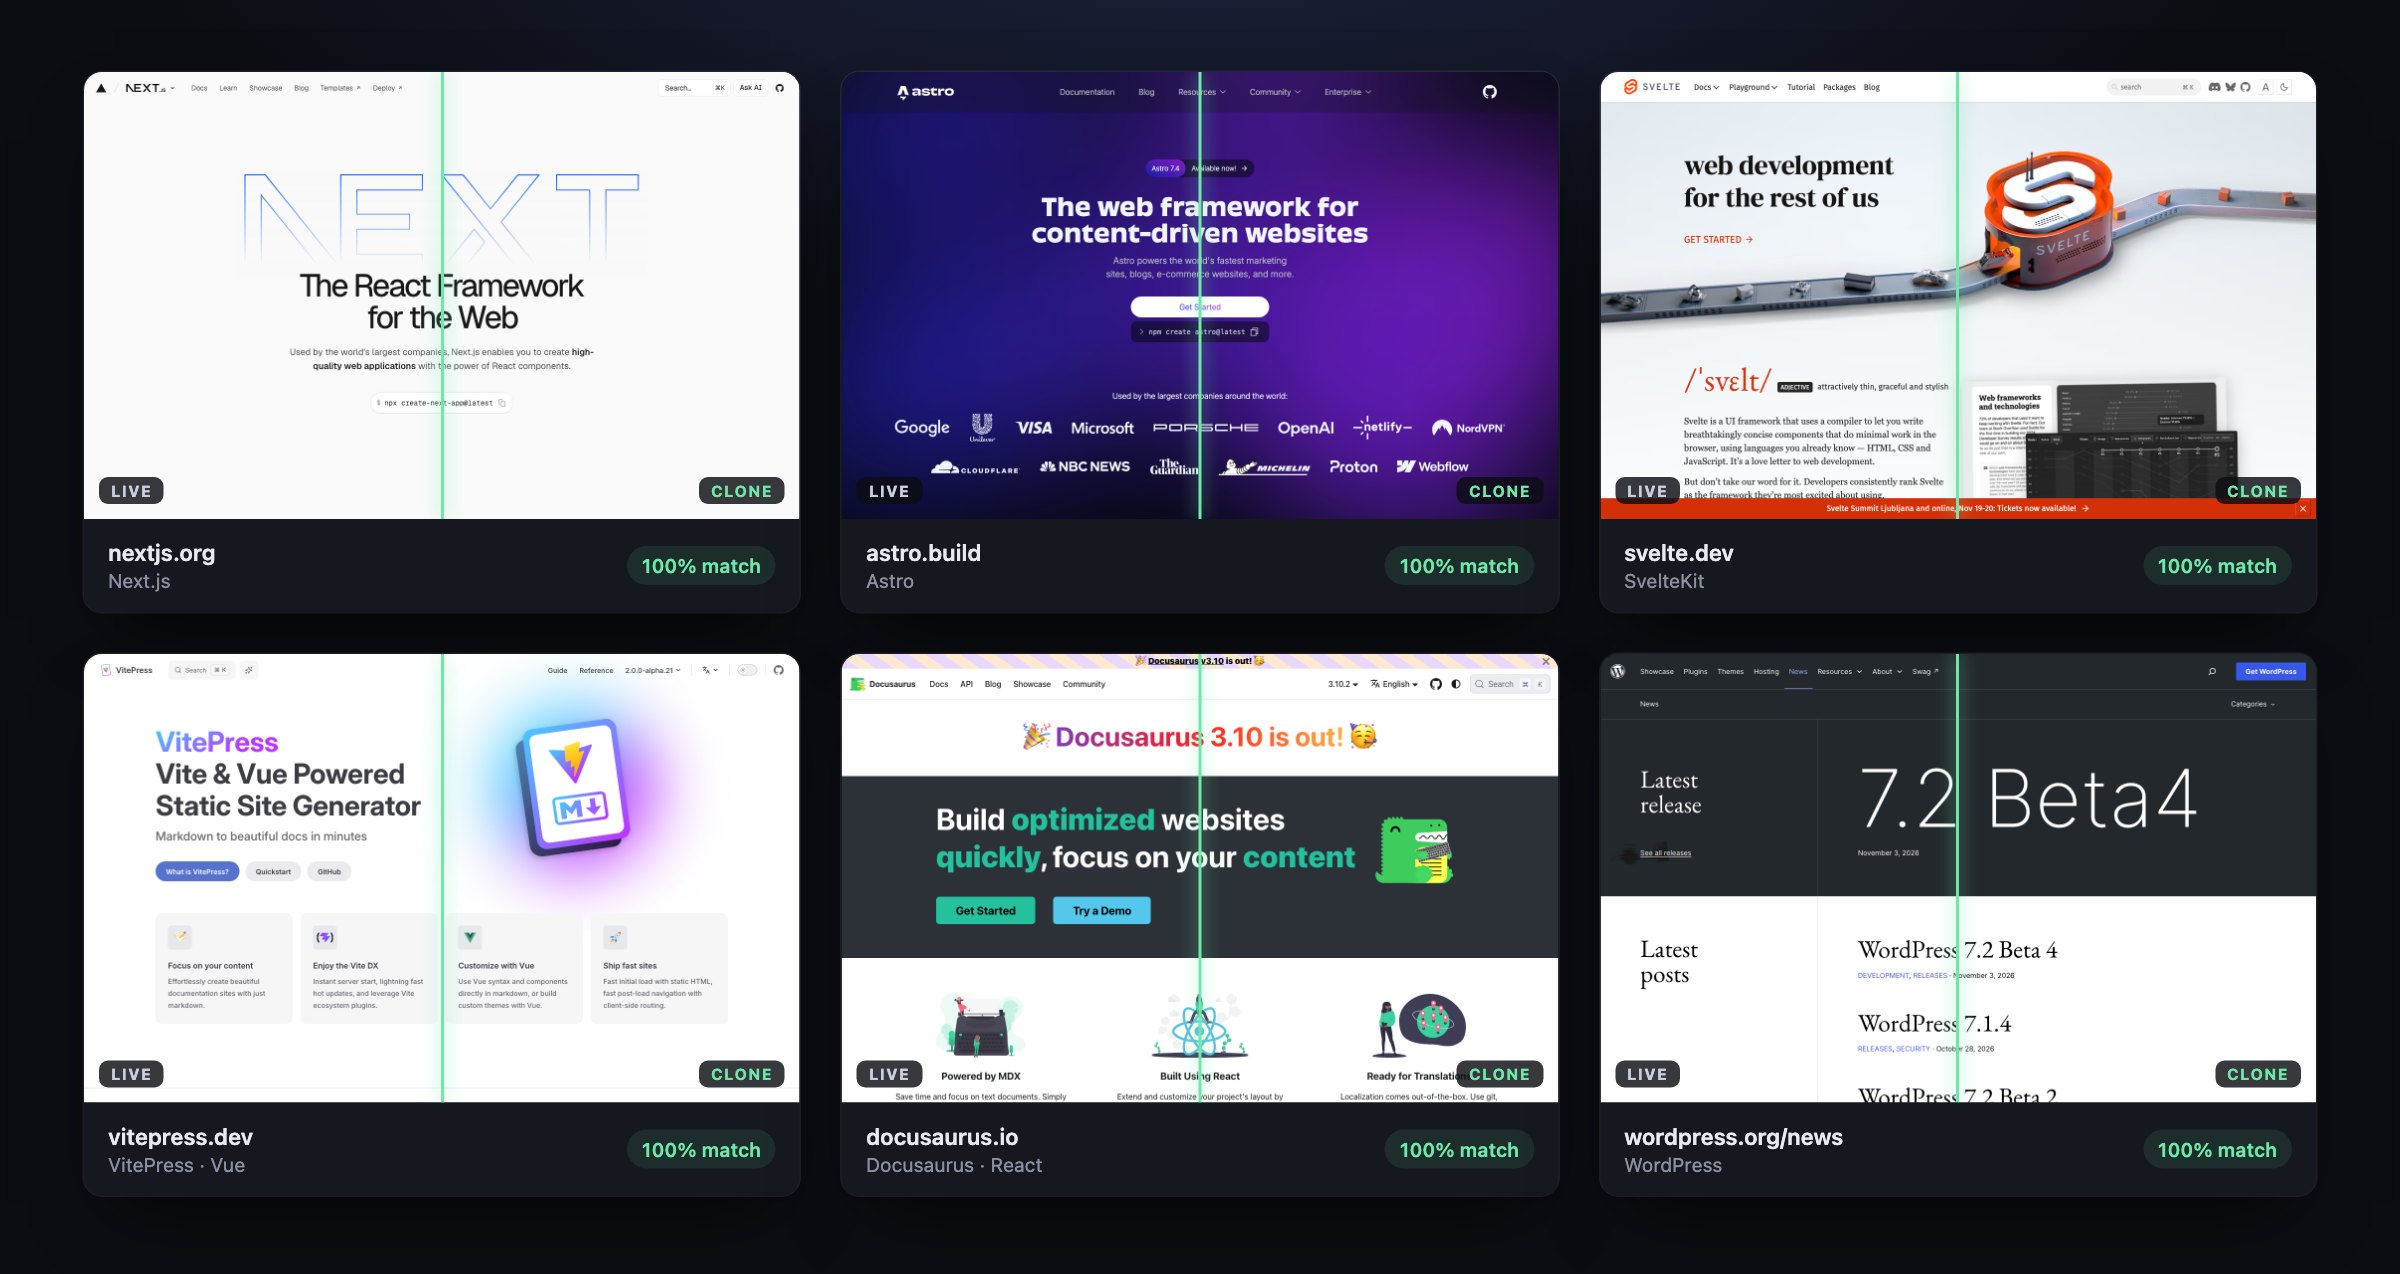
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,192 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: perfectclone
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Clone any website 1:1 with a real browser, then edit it safely.
|
|
5
|
+
Author: Eshaan Gulati
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/eshaangulati123/perfectclone-website-cloner
|
|
8
|
+
Project-URL: Issues, https://github.com/eshaangulati123/perfectclone-website-cloner/issues
|
|
9
|
+
Project-URL: Changelog, https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/CHANGELOG.md
|
|
10
|
+
Keywords: website cloner,clone website,website copier,website mirror,playwright,nextjs,httrack alternative,web scraping
|
|
11
|
+
Classifier: Development Status :: 4 - Beta
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Operating System :: OS Independent
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
17
|
+
Classifier: Topic :: Internet :: WWW/HTTP :: Site Management
|
|
18
|
+
Classifier: Topic :: Software Development :: Build Tools
|
|
19
|
+
Requires-Python: >=3.10
|
|
20
|
+
Description-Content-Type: text/markdown
|
|
21
|
+
License-File: LICENSE
|
|
22
|
+
Requires-Dist: playwright>=1.40
|
|
23
|
+
Provides-Extra: dev
|
|
24
|
+
Requires-Dist: pytest; extra == "dev"
|
|
25
|
+
Requires-Dist: pillow; extra == "dev"
|
|
26
|
+
Requires-Dist: ruff; extra == "dev"
|
|
27
|
+
Dynamic: license-file
|
|
28
|
+
|
|
29
|
+
# perfectclone: website cloner that copies the real site, 1:1
|
|
30
|
+
|
|
31
|
+
**Pull the real frontend of any public site in ~15 seconds. No AI, no tokens.**
|
|
32
|
+
|
|
33
|
+
|
|
34
|
+
|
|
35
|
+
perfectclone clones any website 1:1. It crawls the site with a real browser (Playwright),
|
|
36
|
+
downloads the site's own HTML, JavaScript, CSS, fonts and images, and gives you a folder you can
|
|
37
|
+
serve, edit and deploy. Then it lets you rebrand it, rehost it and strip the original owner's
|
|
38
|
+
trackers without breaking it, including Next.js sites that hydrate on load.
|
|
39
|
+
|
|
40
|
+
```bash
|
|
41
|
+
pip install perfectclone
|
|
42
|
+
|
|
43
|
+
perfectclone clone example.com
|
|
44
|
+
perfectclone serve example.com # → http://localhost:8000
|
|
45
|
+
```
|
|
46
|
+
|
|
47
|
+
That's it. Chromium is downloaded automatically the first time you clone. Requires Python 3.10+.
|
|
48
|
+
|
|
49
|
+
Or try it without installing anything, using [uv](https://docs.astral.sh/uv/):
|
|
50
|
+
|
|
51
|
+
```bash
|
|
52
|
+
uvx perfectclone clone example.com
|
|
53
|
+
```
|
|
54
|
+
|
|
55
|
+
## Why not an AI cloner?
|
|
56
|
+
|
|
57
|
+
Most "clone any website" tools today regenerate the site: an AI agent looks at screenshots or
|
|
58
|
+
scraped markup, writes a new React/Next.js app, and compares the result against the original
|
|
59
|
+
with a visual-similarity score until it's close enough. That gets you a lookalike. The code is
|
|
60
|
+
new, the behaviour is approximate, and there are always gaps.
|
|
61
|
+
|
|
62
|
+
perfectclone doesn't regenerate anything. It mirrors the bytes the site actually serves, so
|
|
63
|
+
the clone *is* the site: same markup, same bundles, same animations, same JavaScript running.
|
|
64
|
+
Sometimes the real solution is the simple one.
|
|
65
|
+
|
|
66
|
+
| | AI cloners | wget / HTTrack | perfectclone |
|
|
67
|
+
| --------------------------------------- | :--------: | :------------: | :----------: |
|
|
68
|
+
| Copies the site's real files | ❌ | ✅ | ✅ |
|
|
69
|
+
| Pixel-identical on modern JS sites | ❌ | ❌ | ✅ |
|
|
70
|
+
| Catches lazy-loaded JS, fonts, images | — | ❌ | ✅ |
|
|
71
|
+
| React / Next.js sites still run | — | ❌ | ✅ |
|
|
72
|
+
| Rebrand without breaking the site | ✅ | ⚠️ | ✅ |
|
|
73
|
+
| Strips the original site's trackers | — | ❌ | ✅ |
|
|
74
|
+
| Works without an LLM or API key | ❌ | ✅ | ✅ |
|
|
75
|
+
|
|
76
|
+
## Tested on real sites
|
|
77
|
+
|
|
78
|
+
Each card is one site split down the middle: the live site on the left, the clone on the right.
|
|
79
|
+
|
|
80
|
+
|
|
81
|
+
|
|
82
|
+
`scripts/compat.py` clones each site, serves the copy, and compares its home page with the live
|
|
83
|
+
one at 1440×900, with animations and videos paused on the same frame:
|
|
84
|
+
|
|
85
|
+
| Site | Built with | Pixel match | Hydration errors | Notes |
|
|
86
|
+
| --- | --- | --- | --- | --- |
|
|
87
|
+
| huly.io | Next.js | 100% | 0 | |
|
|
88
|
+
| nextjs.org | Next.js | 100% | 0 | |
|
|
89
|
+
| astro.build | Astro | 100% | 0 | |
|
|
90
|
+
| svelte.dev | SvelteKit | 100% | 0 | |
|
|
91
|
+
| vitepress.dev | VitePress (Vue) | 100% | 0 | |
|
|
92
|
+
| docusaurus.io | Docusaurus (React) | 100% | 0 | |
|
|
93
|
+
| wordpress.org/news | WordPress | 100% | 0 | |
|
|
94
|
+
| paulgraham.com | Hand-written HTML | 100% | 0 | |
|
|
95
|
+
| example.com | Static HTML | 100% | 0 | |
|
|
96
|
+
| framer.com | Framer | 96% | 0 | Cookie banner needs Framer's backend |
|
|
97
|
+
| webflow.com | Webflow | 93% | 0 | Cookie banner won't run on localhost; carousel caught mid-scroll |
|
|
98
|
+
|
|
99
|
+
Every clone loaded with zero requests to trackers. Run it yourself with
|
|
100
|
+
`python scripts/compat.py`, and please open an issue for any site that doesn't come out right.
|
|
101
|
+
|
|
102
|
+
## Commands
|
|
103
|
+
|
|
104
|
+
```bash
|
|
105
|
+
perfectclone clone <url> [-o out] [--max-pages 200] [--extract] [--keep-trackers] [--ignore-robots]
|
|
106
|
+
perfectclone serve <site> [-p 8000]
|
|
107
|
+
perfectclone replace <site> <old> <new> [--exact-case] [--substring]
|
|
108
|
+
perfectclone rehost <site> <old-origin> <new-origin>
|
|
109
|
+
perfectclone strip-trackers <site>
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
- **clone** writes `out/site/` (the working copy) and `out/manifest.json` (pages, failures,
|
|
113
|
+
third-party hosts the site uses). `--extract` also saves each page's text, metadata
|
|
114
|
+
(headings, links, images, forms, JSON-LD) and a full-page screenshot to `out/extract/`.
|
|
115
|
+
Trackers are stripped by default.
|
|
116
|
+
- **replace** renames text everywhere: HTML, JS, CSS, JSON, SVG. It also handles the UPPER,
|
|
117
|
+
lower and Capitalized variants, and leaves URLs and asset paths alone so nothing 404s.
|
|
118
|
+
- **rehost** points canonical, Open Graph, JSON-LD and sitemap URLs at your domain.
|
|
119
|
+
- **serve** works like a static host: clean URLs (`/about` → `/about/index.html`), and
|
|
120
|
+
`/_next/image` requests are served from the mirrored originals.
|
|
121
|
+
|
|
122
|
+
Rebrand a clone and put it online:
|
|
123
|
+
|
|
124
|
+
```bash
|
|
125
|
+
perfectclone clone acme.com -o acme
|
|
126
|
+
perfectclone replace acme "Acme" "Globex"
|
|
127
|
+
perfectclone rehost acme https://acme.com https://globex.com
|
|
128
|
+
npx netlify-cli deploy --dir acme/site --prod # or any static host
|
|
129
|
+
```
|
|
130
|
+
|
|
131
|
+
## How it works
|
|
132
|
+
|
|
133
|
+
1. **Crawl with a real browser.** Each page is rendered in Chromium and scrolled to the bottom,
|
|
134
|
+
and every response is recorded. That catches what static mirrors miss: code-split JS chunks,
|
|
135
|
+
fonts requested from CSS, images behind lazy loading. Links are followed breadth-first,
|
|
136
|
+
seeded from the sitemap. robots.txt is respected unless you pass `--ignore-robots`.
|
|
137
|
+
2. **Mirror the server's bytes.** Pages are saved as the HTML the *server* sends, not the
|
|
138
|
+
rendered DOM, because that's what the site's JavaScript expects to hydrate. Assets keep
|
|
139
|
+
their URL paths, and CSS/JS are scanned for further references (`url()`, `srcset`, chunk
|
|
140
|
+
paths) until nothing new turns up.
|
|
141
|
+
3. **Edit without breaking hydration.** A Next.js App Router page ships its HTML *and* a
|
|
142
|
+
serialized copy of the React tree in `self.__next_f.push(...)` script chunks. Change one and
|
|
143
|
+
not the other, and React throws a hydration error and re-renders from the payload, undoing
|
|
144
|
+
your edit. perfectclone decodes the payload stream, edits it row by row, recomputes the
|
|
145
|
+
UTF-8 byte lengths of length-prefixed text rows (`<id>:T<hex>,…`), rejoins rows that span
|
|
146
|
+
chunks, and writes it back next to the matching HTML edit.
|
|
147
|
+
4. **Strip trackers.** Google Analytics/Tag Manager, the Meta pixel, LinkedIn Insight, Hotjar,
|
|
148
|
+
Clarity, Segment, PostHog, HubSpot, TikTok, Reddit, X, Cloudflare Web Analytics, RB2B and
|
|
149
|
+
more. They're removed from `<script>`/`<noscript>` tags, from preload hints, and from Next.js
|
|
150
|
+
`next/script` elements that only exist in the payload.
|
|
151
|
+
|
|
152
|
+
## Limits
|
|
153
|
+
|
|
154
|
+
- **No backend.** Forms, logins, search and API calls still go to the original servers (or
|
|
155
|
+
fail). perfectclone copies the front end.
|
|
156
|
+
- **Next.js client-side navigation** needs each page's RSC payload answered for `?_rsc=`
|
|
157
|
+
requests. perfectclone mirrors them and `perfectclone serve` routes them. On a plain static
|
|
158
|
+
host, internal links fall back to full page loads: everything still works, just without the
|
|
159
|
+
instant transitions.
|
|
160
|
+
- **Chunks that are only requested after a click** (say, a modal's code) are captured if the
|
|
161
|
+
crawl triggered them or a bundle names them as a string. A bundle can also assemble a chunk
|
|
162
|
+
URL at runtime, and that one may be missed.
|
|
163
|
+
- **Bot protection** (CAPTCHAs, aggressive Cloudflare rules) can block the crawl. perfectclone
|
|
164
|
+
does not try to get around it.
|
|
165
|
+
- Embeds (YouTube, Cal.com, maps) and third-party CDNs keep loading from their own hosts.
|
|
166
|
+
|
|
167
|
+
## Roadmap
|
|
168
|
+
|
|
169
|
+
**Clone apps behind a login, like dashboards.** Today perfectclone sees what an anonymous visitor
|
|
170
|
+
sees, and data that loads from APIs after the page renders isn't kept. The plan, for apps you
|
|
171
|
+
have an account on:
|
|
172
|
+
|
|
173
|
+
- **Crawl as you.** Sign in once in a browser window; perfectclone saves the session and
|
|
174
|
+
crawls with it.
|
|
175
|
+
- **Record API responses.** Keep every JSON response the app fetches during the crawl and have
|
|
176
|
+
`perfectclone serve` replay them, so charts, tables and lists show real data offline.
|
|
177
|
+
- **Explore by clicking.** Click through navigation, tabs and menus to reach views that only
|
|
178
|
+
exist in client-side routing.
|
|
179
|
+
|
|
180
|
+
The result is a clickable snapshot of the UI and its data at capture time. Saving, server-side
|
|
181
|
+
filtering and live updates still need the real backend.
|
|
182
|
+
|
|
183
|
+
Other ideas: hydration-aware editing for Nuxt, SvelteKit and Remix payloads, and a deploy
|
|
184
|
+
helper that writes `_redirects` / `vercel.json` rules so `?_rsc=` and `/_next/image` work on
|
|
185
|
+
static hosts. Contributions welcome.
|
|
186
|
+
|
|
187
|
+
## Contributing
|
|
188
|
+
|
|
189
|
+
perfectclone is open source under the [MIT License](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/LICENSE). Issues and pull requests are
|
|
190
|
+
welcome, especially reports of sites that don't clone cleanly. See
|
|
191
|
+
[CONTRIBUTING.md](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/CONTRIBUTING.md), and please follow the [Code of Conduct](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/CODE_OF_CONDUCT.md).
|
|
192
|
+
Report security issues privately as described in [SECURITY.md](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/SECURITY.md).
|
|
@@ -0,0 +1,164 @@
|
|
|
1
|
+
# perfectclone: website cloner that copies the real site, 1:1
|
|
2
|
+
|
|
3
|
+
**Pull the real frontend of any public site in ~15 seconds. No AI, no tokens.**
|
|
4
|
+
|
|
5
|
+

|
|
6
|
+
|
|
7
|
+
perfectclone clones any website 1:1. It crawls the site with a real browser (Playwright),
|
|
8
|
+
downloads the site's own HTML, JavaScript, CSS, fonts and images, and gives you a folder you can
|
|
9
|
+
serve, edit and deploy. Then it lets you rebrand it, rehost it and strip the original owner's
|
|
10
|
+
trackers without breaking it, including Next.js sites that hydrate on load.
|
|
11
|
+
|
|
12
|
+
```bash
|
|
13
|
+
pip install perfectclone
|
|
14
|
+
|
|
15
|
+
perfectclone clone example.com
|
|
16
|
+
perfectclone serve example.com # → http://localhost:8000
|
|
17
|
+
```
|
|
18
|
+
|
|
19
|
+
That's it. Chromium is downloaded automatically the first time you clone. Requires Python 3.10+.
|
|
20
|
+
|
|
21
|
+
Or try it without installing anything, using [uv](https://docs.astral.sh/uv/):
|
|
22
|
+
|
|
23
|
+
```bash
|
|
24
|
+
uvx perfectclone clone example.com
|
|
25
|
+
```
|
|
26
|
+
|
|
27
|
+
## Why not an AI cloner?
|
|
28
|
+
|
|
29
|
+
Most "clone any website" tools today regenerate the site: an AI agent looks at screenshots or
|
|
30
|
+
scraped markup, writes a new React/Next.js app, and compares the result against the original
|
|
31
|
+
with a visual-similarity score until it's close enough. That gets you a lookalike. The code is
|
|
32
|
+
new, the behaviour is approximate, and there are always gaps.
|
|
33
|
+
|
|
34
|
+
perfectclone doesn't regenerate anything. It mirrors the bytes the site actually serves, so
|
|
35
|
+
the clone *is* the site: same markup, same bundles, same animations, same JavaScript running.
|
|
36
|
+
Sometimes the real solution is the simple one.
|
|
37
|
+
|
|
38
|
+
| | AI cloners | wget / HTTrack | perfectclone |
|
|
39
|
+
| --------------------------------------- | :--------: | :------------: | :----------: |
|
|
40
|
+
| Copies the site's real files | ❌ | ✅ | ✅ |
|
|
41
|
+
| Pixel-identical on modern JS sites | ❌ | ❌ | ✅ |
|
|
42
|
+
| Catches lazy-loaded JS, fonts, images | — | ❌ | ✅ |
|
|
43
|
+
| React / Next.js sites still run | — | ❌ | ✅ |
|
|
44
|
+
| Rebrand without breaking the site | ✅ | ⚠️ | ✅ |
|
|
45
|
+
| Strips the original site's trackers | — | ❌ | ✅ |
|
|
46
|
+
| Works without an LLM or API key | ❌ | ✅ | ✅ |
|
|
47
|
+
|
|
48
|
+
## Tested on real sites
|
|
49
|
+
|
|
50
|
+
Each card is one site split down the middle: the live site on the left, the clone on the right.
|
|
51
|
+
|
|
52
|
+

|
|
53
|
+
|
|
54
|
+
`scripts/compat.py` clones each site, serves the copy, and compares its home page with the live
|
|
55
|
+
one at 1440×900, with animations and videos paused on the same frame:
|
|
56
|
+
|
|
57
|
+
| Site | Built with | Pixel match | Hydration errors | Notes |
|
|
58
|
+
| --- | --- | --- | --- | --- |
|
|
59
|
+
| huly.io | Next.js | 100% | 0 | |
|
|
60
|
+
| nextjs.org | Next.js | 100% | 0 | |
|
|
61
|
+
| astro.build | Astro | 100% | 0 | |
|
|
62
|
+
| svelte.dev | SvelteKit | 100% | 0 | |
|
|
63
|
+
| vitepress.dev | VitePress (Vue) | 100% | 0 | |
|
|
64
|
+
| docusaurus.io | Docusaurus (React) | 100% | 0 | |
|
|
65
|
+
| wordpress.org/news | WordPress | 100% | 0 | |
|
|
66
|
+
| paulgraham.com | Hand-written HTML | 100% | 0 | |
|
|
67
|
+
| example.com | Static HTML | 100% | 0 | |
|
|
68
|
+
| framer.com | Framer | 96% | 0 | Cookie banner needs Framer's backend |
|
|
69
|
+
| webflow.com | Webflow | 93% | 0 | Cookie banner won't run on localhost; carousel caught mid-scroll |
|
|
70
|
+
|
|
71
|
+
Every clone loaded with zero requests to trackers. Run it yourself with
|
|
72
|
+
`python scripts/compat.py`, and please open an issue for any site that doesn't come out right.
|
|
73
|
+
|
|
74
|
+
## Commands
|
|
75
|
+
|
|
76
|
+
```bash
|
|
77
|
+
perfectclone clone <url> [-o out] [--max-pages 200] [--extract] [--keep-trackers] [--ignore-robots]
|
|
78
|
+
perfectclone serve <site> [-p 8000]
|
|
79
|
+
perfectclone replace <site> <old> <new> [--exact-case] [--substring]
|
|
80
|
+
perfectclone rehost <site> <old-origin> <new-origin>
|
|
81
|
+
perfectclone strip-trackers <site>
|
|
82
|
+
```
|
|
83
|
+
|
|
84
|
+
- **clone** writes `out/site/` (the working copy) and `out/manifest.json` (pages, failures,
|
|
85
|
+
third-party hosts the site uses). `--extract` also saves each page's text, metadata
|
|
86
|
+
(headings, links, images, forms, JSON-LD) and a full-page screenshot to `out/extract/`.
|
|
87
|
+
Trackers are stripped by default.
|
|
88
|
+
- **replace** renames text everywhere: HTML, JS, CSS, JSON, SVG. It also handles the UPPER,
|
|
89
|
+
lower and Capitalized variants, and leaves URLs and asset paths alone so nothing 404s.
|
|
90
|
+
- **rehost** points canonical, Open Graph, JSON-LD and sitemap URLs at your domain.
|
|
91
|
+
- **serve** works like a static host: clean URLs (`/about` → `/about/index.html`), and
|
|
92
|
+
`/_next/image` requests are served from the mirrored originals.
|
|
93
|
+
|
|
94
|
+
Rebrand a clone and put it online:
|
|
95
|
+
|
|
96
|
+
```bash
|
|
97
|
+
perfectclone clone acme.com -o acme
|
|
98
|
+
perfectclone replace acme "Acme" "Globex"
|
|
99
|
+
perfectclone rehost acme https://acme.com https://globex.com
|
|
100
|
+
npx netlify-cli deploy --dir acme/site --prod # or any static host
|
|
101
|
+
```
|
|
102
|
+
|
|
103
|
+
## How it works
|
|
104
|
+
|
|
105
|
+
1. **Crawl with a real browser.** Each page is rendered in Chromium and scrolled to the bottom,
|
|
106
|
+
and every response is recorded. That catches what static mirrors miss: code-split JS chunks,
|
|
107
|
+
fonts requested from CSS, images behind lazy loading. Links are followed breadth-first,
|
|
108
|
+
seeded from the sitemap. robots.txt is respected unless you pass `--ignore-robots`.
|
|
109
|
+
2. **Mirror the server's bytes.** Pages are saved as the HTML the *server* sends, not the
|
|
110
|
+
rendered DOM, because that's what the site's JavaScript expects to hydrate. Assets keep
|
|
111
|
+
their URL paths, and CSS/JS are scanned for further references (`url()`, `srcset`, chunk
|
|
112
|
+
paths) until nothing new turns up.
|
|
113
|
+
3. **Edit without breaking hydration.** A Next.js App Router page ships its HTML *and* a
|
|
114
|
+
serialized copy of the React tree in `self.__next_f.push(...)` script chunks. Change one and
|
|
115
|
+
not the other, and React throws a hydration error and re-renders from the payload, undoing
|
|
116
|
+
your edit. perfectclone decodes the payload stream, edits it row by row, recomputes the
|
|
117
|
+
UTF-8 byte lengths of length-prefixed text rows (`<id>:T<hex>,…`), rejoins rows that span
|
|
118
|
+
chunks, and writes it back next to the matching HTML edit.
|
|
119
|
+
4. **Strip trackers.** Google Analytics/Tag Manager, the Meta pixel, LinkedIn Insight, Hotjar,
|
|
120
|
+
Clarity, Segment, PostHog, HubSpot, TikTok, Reddit, X, Cloudflare Web Analytics, RB2B and
|
|
121
|
+
more. They're removed from `<script>`/`<noscript>` tags, from preload hints, and from Next.js
|
|
122
|
+
`next/script` elements that only exist in the payload.
|
|
123
|
+
|
|
124
|
+
## Limits
|
|
125
|
+
|
|
126
|
+
- **No backend.** Forms, logins, search and API calls still go to the original servers (or
|
|
127
|
+
fail). perfectclone copies the front end.
|
|
128
|
+
- **Next.js client-side navigation** needs each page's RSC payload answered for `?_rsc=`
|
|
129
|
+
requests. perfectclone mirrors them and `perfectclone serve` routes them. On a plain static
|
|
130
|
+
host, internal links fall back to full page loads: everything still works, just without the
|
|
131
|
+
instant transitions.
|
|
132
|
+
- **Chunks that are only requested after a click** (say, a modal's code) are captured if the
|
|
133
|
+
crawl triggered them or a bundle names them as a string. A bundle can also assemble a chunk
|
|
134
|
+
URL at runtime, and that one may be missed.
|
|
135
|
+
- **Bot protection** (CAPTCHAs, aggressive Cloudflare rules) can block the crawl. perfectclone
|
|
136
|
+
does not try to get around it.
|
|
137
|
+
- Embeds (YouTube, Cal.com, maps) and third-party CDNs keep loading from their own hosts.
|
|
138
|
+
|
|
139
|
+
## Roadmap
|
|
140
|
+
|
|
141
|
+
**Clone apps behind a login, like dashboards.** Today perfectclone sees what an anonymous visitor
|
|
142
|
+
sees, and data that loads from APIs after the page renders isn't kept. The plan, for apps you
|
|
143
|
+
have an account on:
|
|
144
|
+
|
|
145
|
+
- **Crawl as you.** Sign in once in a browser window; perfectclone saves the session and
|
|
146
|
+
crawls with it.
|
|
147
|
+
- **Record API responses.** Keep every JSON response the app fetches during the crawl and have
|
|
148
|
+
`perfectclone serve` replay them, so charts, tables and lists show real data offline.
|
|
149
|
+
- **Explore by clicking.** Click through navigation, tabs and menus to reach views that only
|
|
150
|
+
exist in client-side routing.
|
|
151
|
+
|
|
152
|
+
The result is a clickable snapshot of the UI and its data at capture time. Saving, server-side
|
|
153
|
+
filtering and live updates still need the real backend.
|
|
154
|
+
|
|
155
|
+
Other ideas: hydration-aware editing for Nuxt, SvelteKit and Remix payloads, and a deploy
|
|
156
|
+
helper that writes `_redirects` / `vercel.json` rules so `?_rsc=` and `/_next/image` work on
|
|
157
|
+
static hosts. Contributions welcome.
|
|
158
|
+
|
|
159
|
+
## Contributing
|
|
160
|
+
|
|
161
|
+
perfectclone is open source under the [MIT License](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/LICENSE). Issues and pull requests are
|
|
162
|
+
welcome, especially reports of sites that don't clone cleanly. See
|
|
163
|
+
[CONTRIBUTING.md](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/CONTRIBUTING.md), and please follow the [Code of Conduct](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/CODE_OF_CONDUCT.md).
|
|
164
|
+
Report security issues privately as described in [SECURITY.md](https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/SECURITY.md).
|
|
@@ -0,0 +1,52 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["setuptools>=77"]
|
|
3
|
+
build-backend = "setuptools.build_meta"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "perfectclone"
|
|
7
|
+
dynamic = ["version"]
|
|
8
|
+
description = "Clone any website 1:1 with a real browser, then edit it safely."
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
license = "MIT"
|
|
11
|
+
license-files = ["LICENSE"]
|
|
12
|
+
authors = [{ name = "Eshaan Gulati" }]
|
|
13
|
+
requires-python = ">=3.10"
|
|
14
|
+
dependencies = ["playwright>=1.40"]
|
|
15
|
+
keywords = ["website cloner", "clone website", "website copier", "website mirror", "playwright", "nextjs", "httrack alternative", "web scraping"]
|
|
16
|
+
classifiers = [
|
|
17
|
+
"Development Status :: 4 - Beta",
|
|
18
|
+
"Environment :: Console",
|
|
19
|
+
"Intended Audience :: Developers",
|
|
20
|
+
"Operating System :: OS Independent",
|
|
21
|
+
"Programming Language :: Python :: 3",
|
|
22
|
+
"Programming Language :: Python :: 3 :: Only",
|
|
23
|
+
"Topic :: Internet :: WWW/HTTP :: Site Management",
|
|
24
|
+
"Topic :: Software Development :: Build Tools",
|
|
25
|
+
]
|
|
26
|
+
|
|
27
|
+
[project.urls]
|
|
28
|
+
Homepage = "https://github.com/eshaangulati123/perfectclone-website-cloner"
|
|
29
|
+
Issues = "https://github.com/eshaangulati123/perfectclone-website-cloner/issues"
|
|
30
|
+
Changelog = "https://github.com/eshaangulati123/perfectclone-website-cloner/blob/main/CHANGELOG.md"
|
|
31
|
+
|
|
32
|
+
[project.optional-dependencies]
|
|
33
|
+
dev = ["pytest", "pillow", "ruff"]
|
|
34
|
+
|
|
35
|
+
[project.scripts]
|
|
36
|
+
perfectclone = "perfectclone.cli:main"
|
|
37
|
+
|
|
38
|
+
[tool.setuptools.dynamic]
|
|
39
|
+
version = { attr = "perfectclone.__version__" }
|
|
40
|
+
|
|
41
|
+
[tool.setuptools.packages.find]
|
|
42
|
+
where = ["src"]
|
|
43
|
+
|
|
44
|
+
[tool.pytest.ini_options]
|
|
45
|
+
testpaths = ["tests"]
|
|
46
|
+
|
|
47
|
+
[tool.ruff]
|
|
48
|
+
line-length = 130
|
|
49
|
+
target-version = "py310"
|
|
50
|
+
|
|
51
|
+
[tool.ruff.lint]
|
|
52
|
+
select = ["E", "F", "W", "I", "B", "UP"]
|
|
@@ -0,0 +1,112 @@
|
|
|
1
|
+
"""perfectclone command line."""
|
|
2
|
+
import argparse
|
|
3
|
+
import json
|
|
4
|
+
import sys
|
|
5
|
+
from pathlib import Path
|
|
6
|
+
from urllib.parse import urlparse
|
|
7
|
+
|
|
8
|
+
from . import __version__
|
|
9
|
+
from .edit import localize, rehost, replace
|
|
10
|
+
from .serve import serve
|
|
11
|
+
from .trackers import strip
|
|
12
|
+
from .util import site_dir
|
|
13
|
+
|
|
14
|
+
|
|
15
|
+
def cmd_clone(a):
|
|
16
|
+
# Imported here so the editing commands don't pay for loading Playwright.
|
|
17
|
+
from .crawl import crawl
|
|
18
|
+
from .mirror import mirror
|
|
19
|
+
|
|
20
|
+
out = Path(a.out)
|
|
21
|
+
site = out / "site"
|
|
22
|
+
print(f"Crawling {a.url}")
|
|
23
|
+
pages, assets, external, skipped = crawl(
|
|
24
|
+
a.url, max_pages=a.max_pages, respect_robots=not a.ignore_robots,
|
|
25
|
+
extract_dir=out / "extract" if a.extract else None,
|
|
26
|
+
)
|
|
27
|
+
if not pages:
|
|
28
|
+
sys.exit("No pages could be loaded." + (f" First problem: {skipped[0]}" if skipped else ""))
|
|
29
|
+
print(f"Mirroring into {site}")
|
|
30
|
+
saved, fetched, failures = mirror(pages, assets, site)
|
|
31
|
+
localize(site, a.url)
|
|
32
|
+
if a.strip_trackers:
|
|
33
|
+
print("Removing trackers")
|
|
34
|
+
strip(site)
|
|
35
|
+
manifest = {
|
|
36
|
+
"source": a.url, "pages": pages, "assets_fetched": fetched, "failures": failures,
|
|
37
|
+
"skipped": skipped, "external_hosts": external,
|
|
38
|
+
}
|
|
39
|
+
(out / "manifest.json").write_text(json.dumps(manifest, indent=2))
|
|
40
|
+
print(f"\nDone: {saved} pages, {fetched} assets → {site}")
|
|
41
|
+
if failures:
|
|
42
|
+
print(f" {len(failures)} URLs failed to download (see {out / 'manifest.json'})")
|
|
43
|
+
if external:
|
|
44
|
+
print(f" The original also used these hosts (embeds, CDNs, analytics): {', '.join(external)}")
|
|
45
|
+
print(f"\nPreview it: perfectclone serve {out}")
|
|
46
|
+
|
|
47
|
+
|
|
48
|
+
def cmd_serve(a):
|
|
49
|
+
serve(a.site, a.port)
|
|
50
|
+
|
|
51
|
+
|
|
52
|
+
def cmd_replace(a):
|
|
53
|
+
replace(site_dir(a.site), a.old, a.new, variants=not a.exact_case, whole_word=not a.substring)
|
|
54
|
+
|
|
55
|
+
|
|
56
|
+
def cmd_rehost(a):
|
|
57
|
+
rehost(site_dir(a.site), a.old_origin, a.new_origin)
|
|
58
|
+
|
|
59
|
+
|
|
60
|
+
def cmd_strip(a):
|
|
61
|
+
strip(site_dir(a.site))
|
|
62
|
+
|
|
63
|
+
|
|
64
|
+
def main(argv=None):
|
|
65
|
+
p = argparse.ArgumentParser(
|
|
66
|
+
prog="perfectclone", description="Clone any website 1:1 with a real browser, then edit it safely.")
|
|
67
|
+
p.add_argument("--version", action="version", version=__version__)
|
|
68
|
+
sub = p.add_subparsers(dest="cmd", required=True)
|
|
69
|
+
|
|
70
|
+
c = sub.add_parser("clone", help="crawl a site and save a working local copy")
|
|
71
|
+
c.add_argument("url")
|
|
72
|
+
c.add_argument("-o", "--out", default=None, help="output folder (default: the site's hostname)")
|
|
73
|
+
c.add_argument("--max-pages", type=int, default=200)
|
|
74
|
+
c.add_argument("--extract", action="store_true", help="also save each page's text, metadata and a full-page screenshot")
|
|
75
|
+
c.add_argument("--keep-trackers", dest="strip_trackers", action="store_false", help="keep the original analytics/ad pixels")
|
|
76
|
+
c.add_argument("--ignore-robots", action="store_true", help="crawl pages robots.txt disallows")
|
|
77
|
+
c.set_defaults(fn=cmd_clone)
|
|
78
|
+
|
|
79
|
+
s = sub.add_parser("serve", help="serve a clone locally")
|
|
80
|
+
s.add_argument("site")
|
|
81
|
+
s.add_argument("-p", "--port", type=int, default=8000)
|
|
82
|
+
s.set_defaults(fn=cmd_serve)
|
|
83
|
+
|
|
84
|
+
r = sub.add_parser("replace", help="replace text across the clone (skips URLs, Next.js-safe)")
|
|
85
|
+
r.add_argument("site")
|
|
86
|
+
r.add_argument("old")
|
|
87
|
+
r.add_argument("new")
|
|
88
|
+
r.add_argument("--exact-case", action="store_true", help="don't also replace UPPER/lower/Capitalized variants")
|
|
89
|
+
r.add_argument("--substring", action="store_true", help="match inside words too")
|
|
90
|
+
r.set_defaults(fn=cmd_replace)
|
|
91
|
+
|
|
92
|
+
h = sub.add_parser("rehost", help="point canonical/og/sitemap URLs at a new origin")
|
|
93
|
+
h.add_argument("site")
|
|
94
|
+
h.add_argument("old_origin")
|
|
95
|
+
h.add_argument("new_origin")
|
|
96
|
+
h.set_defaults(fn=cmd_rehost)
|
|
97
|
+
|
|
98
|
+
t = sub.add_parser("strip-trackers", help="remove analytics and ad pixels")
|
|
99
|
+
t.add_argument("site")
|
|
100
|
+
t.set_defaults(fn=cmd_strip)
|
|
101
|
+
|
|
102
|
+
a = p.parse_args(argv)
|
|
103
|
+
if a.cmd == "clone":
|
|
104
|
+
if "://" not in a.url:
|
|
105
|
+
a.url = "https://" + a.url
|
|
106
|
+
if not a.out:
|
|
107
|
+
a.out = urlparse(a.url).netloc.removeprefix("www.") or "clone"
|
|
108
|
+
a.fn(a)
|
|
109
|
+
|
|
110
|
+
|
|
111
|
+
if __name__ == "__main__":
|
|
112
|
+
main()
|