peplocus 0.5.6__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- peplocus-0.5.6/LICENSE +21 -0
- peplocus-0.5.6/MANIFEST.in +12 -0
- peplocus-0.5.6/PKG-INFO +90 -0
- peplocus-0.5.6/README.md +68 -0
- peplocus-0.5.6/pyproject.toml +31 -0
- peplocus-0.5.6/setup.cfg +4 -0
- peplocus-0.5.6/src/peplocus/__init__.py +11 -0
- peplocus-0.5.6/src/peplocus/__main__.py +3 -0
- peplocus-0.5.6/src/peplocus/annotation.py +103 -0
- peplocus-0.5.6/src/peplocus/api.py +43 -0
- peplocus-0.5.6/src/peplocus/cli.py +232 -0
- peplocus-0.5.6/src/peplocus/digestion.py +83 -0
- peplocus-0.5.6/src/peplocus/discovery.py +169 -0
- peplocus-0.5.6/src/peplocus/io.py +143 -0
- peplocus-0.5.6/src/peplocus/junctions.py +164 -0
- peplocus-0.5.6/src/peplocus/output.py +145 -0
- peplocus-0.5.6/src/peplocus/pipeline.py +242 -0
- peplocus-0.5.6/src/peplocus/rescue.py +172 -0
- peplocus-0.5.6/src/peplocus/rescue_output.py +29 -0
- peplocus-0.5.6/src/peplocus/rescue_pipeline.py +93 -0
- peplocus-0.5.6/src/peplocus/search.py +82 -0
- peplocus-0.5.6/src/peplocus/sequence.py +66 -0
- peplocus-0.5.6/src/peplocus.egg-info/PKG-INFO +90 -0
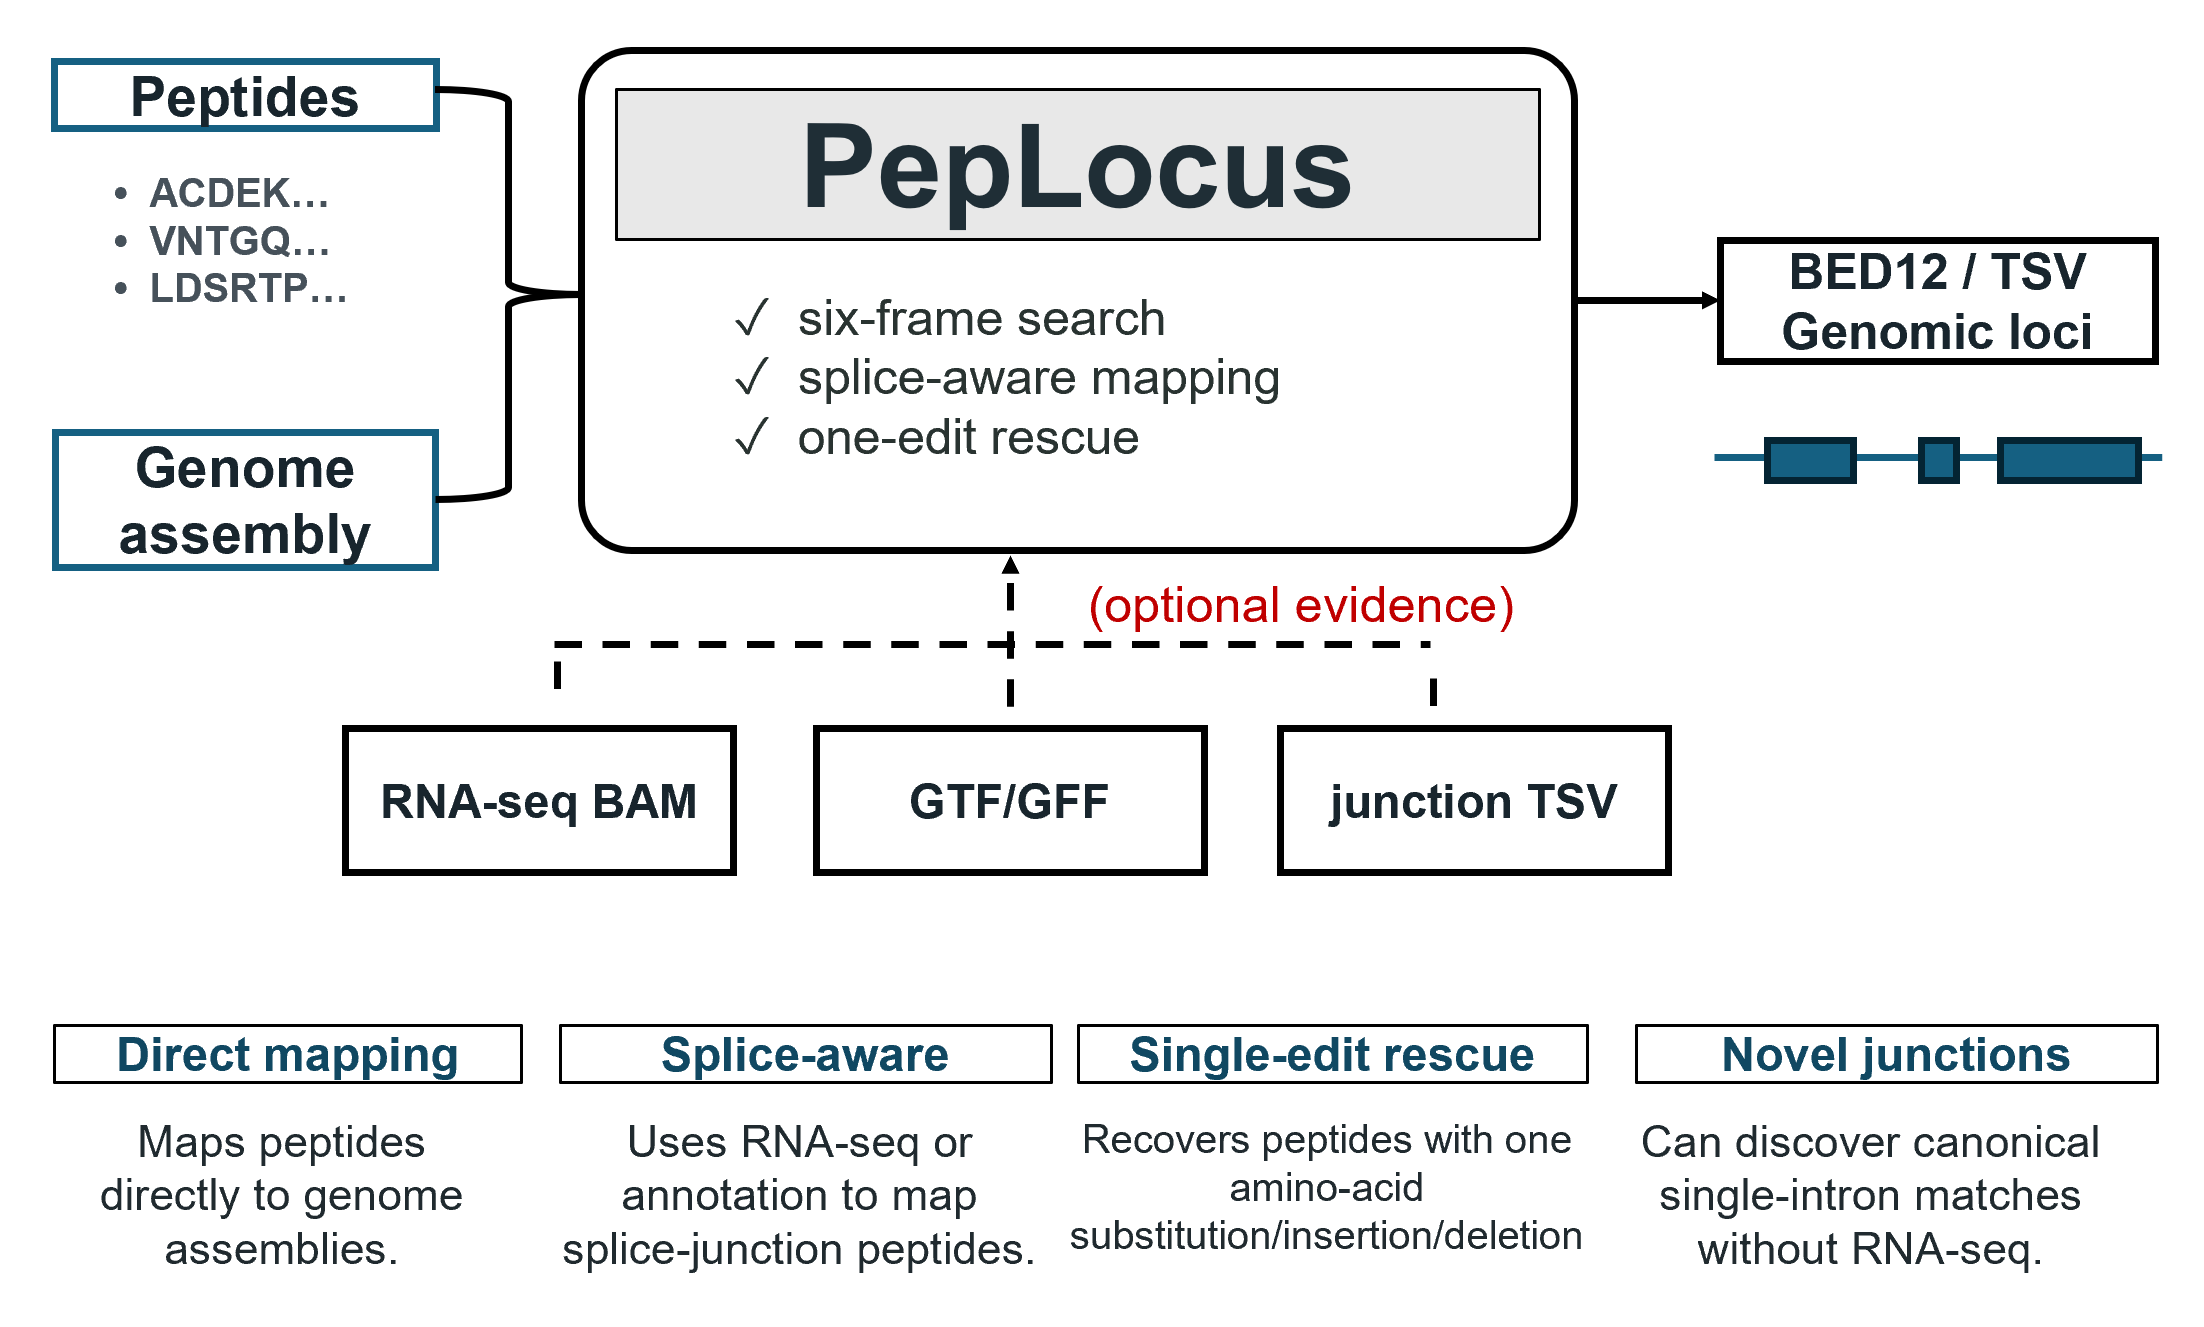
- peplocus-0.5.6/src/peplocus.egg-info/SOURCES.txt +26 -0
- peplocus-0.5.6/src/peplocus.egg-info/dependency_links.txt +1 -0
- peplocus-0.5.6/src/peplocus.egg-info/entry_points.txt +2 -0
- peplocus-0.5.6/src/peplocus.egg-info/requires.txt +4 -0
- peplocus-0.5.6/src/peplocus.egg-info/top_level.txt +1 -0
peplocus-0.5.6/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Qussai Abbas
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
peplocus-0.5.6/PKG-INFO
ADDED
|
@@ -0,0 +1,90 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: peplocus
|
|
3
|
+
Version: 0.5.6
|
|
4
|
+
Summary: Fast peptide-to-genome mapping with splice-junction support and one-edit rescue
|
|
5
|
+
Author: Qussai Abbas
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/qussai96/PepLocus
|
|
8
|
+
Project-URL: Source, https://github.com/qussai96/PepLocus
|
|
9
|
+
Project-URL: Issues, https://github.com/qussai96/PepLocus/issues
|
|
10
|
+
Keywords: proteogenomics,peptides,genome,splicing,BED12
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Programming Language :: Python :: 3
|
|
13
|
+
Classifier: Topic :: Scientific/Engineering :: Bio-Informatics
|
|
14
|
+
Requires-Python: >=3.9
|
|
15
|
+
Description-Content-Type: text/markdown
|
|
16
|
+
License-File: LICENSE
|
|
17
|
+
Requires-Dist: numpy>=1.23
|
|
18
|
+
Requires-Dist: biopython>=1.80
|
|
19
|
+
Requires-Dist: pyahocorasick>=2.0
|
|
20
|
+
Requires-Dist: pysam>=0.22
|
|
21
|
+
Dynamic: license-file
|
|
22
|
+
|
|
23
|
+
# PepLocus
|
|
24
|
+
|
|
25
|
+
Map mass-spectrometry peptides directly to eukaryotic genome assemblies, including splice-junction peptides. PepLocus searches all six reading frames, always treats I/L as equivalent, and can use GTF/GFF annotations or RNA-seq BAM evidence.
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
|
|
29
|
+
## Install
|
|
30
|
+
|
|
31
|
+
Requires Python 3.9 or newer. Linux and macOS are recommended.
|
|
32
|
+
|
|
33
|
+
```bash
|
|
34
|
+
python -m pip install "git+https://github.com/qussai96/PepLocus.git"
|
|
35
|
+
```
|
|
36
|
+
|
|
37
|
+
Once published on PyPI:
|
|
38
|
+
|
|
39
|
+
```bash
|
|
40
|
+
python -m pip install peplocus
|
|
41
|
+
```
|
|
42
|
+
|
|
43
|
+
Dependencies are installed automatically; no external aligner is needed.
|
|
44
|
+
|
|
45
|
+
## Run
|
|
46
|
+
|
|
47
|
+
Map a peptide list to an assembly:
|
|
48
|
+
|
|
49
|
+
```bash
|
|
50
|
+
peplocus -a assembly.fa -p peptides.tsv --out results
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
Add annotation and/or RNA-seq evidence to find splice-junction placements:
|
|
54
|
+
|
|
55
|
+
```bash
|
|
56
|
+
peplocus -a assembly.fa -p peptides.tsv -g models.gtf -b rnaseq.bam --out results_spliced
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
`-g` accepts GTF or GFF. Either `-g` or `-b` can be used alone. A BAM index is not required.
|
|
60
|
+
|
|
61
|
+
Optional one-edit rescue searches peptides with no exact match for one amino-acid substitution, insertion or deletion:
|
|
62
|
+
|
|
63
|
+
```bash
|
|
64
|
+
peplocus -a assembly.fa -p peptides.tsv -g models.gtf --rescue-one-edit --out results_rescue
|
|
65
|
+
```
|
|
66
|
+
|
|
67
|
+
The default is **8 workers** (`--threads`). Rescue uses a minimum query length of **9 aa**; short candidates can be highly ambiguous. Use `--min-rescue-length 12` for a more conservative search. `--discover-junctions` optionally searches for bounded canonical single-intron matches without supplied evidence.
|
|
68
|
+
|
|
69
|
+
Peptides can be a plain list, FASTA, CSV or TSV; FragPipe's `Peptide Sequence` column is recognised automatically. Assembly FASTA may be plain or gzip-compressed. Use a fresh output directory for each run.
|
|
70
|
+
|
|
71
|
+
```bash
|
|
72
|
+
peplocus -h
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
## Results
|
|
76
|
+
|
|
77
|
+
| File | Contents |
|
|
78
|
+
|---|---|
|
|
79
|
+
| `all_mappings.bed` | Exact and I/L-equivalent placements |
|
|
80
|
+
| `tryptic_mappings.bed` | Placements with compatible tryptic or possible protein-terminal contexts |
|
|
81
|
+
| `mappings.tsv` | Coordinates, sequences, evidence, cleavage contexts and mapping counts |
|
|
82
|
+
| `peptides.tsv` | Per-peptide exact and rescue counts and status |
|
|
83
|
+
| `unmapped.tsv` | Peptides with no exact match, including labeled rescue candidates |
|
|
84
|
+
| `summary.json` | Parameters, counts, timings and search limits |
|
|
85
|
+
|
|
86
|
+
BED files use standard BED12 coordinates, with peptide names in biological N-to-C orientation on both strands. Rescue candidates are kept separately in `rescue/`, with their own all/tryptic BED files and detailed TSV. A reusable `junctions.tsv` is also saved when splice evidence is supplied.
|
|
87
|
+
|
|
88
|
+
Contiguous matching is exhaustive for the chosen translation table. Splice mapping depends on available junctions and search limits. Placements show sequence compatibility; one-edit candidates are not confirmed variants, and tryptic compatibility alone does not establish biological origin.
|
|
89
|
+
|
|
90
|
+
[Report an issue](https://github.com/qussai96/PepLocus/issues) · [MIT license](https://github.com/qussai96/PepLocus/blob/main/LICENSE)
|
peplocus-0.5.6/README.md
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
1
|
+
# PepLocus
|
|
2
|
+
|
|
3
|
+
Map mass-spectrometry peptides directly to eukaryotic genome assemblies, including splice-junction peptides. PepLocus searches all six reading frames, always treats I/L as equivalent, and can use GTF/GFF annotations or RNA-seq BAM evidence.
|
|
4
|
+
|
|
5
|
+

|
|
6
|
+
|
|
7
|
+
## Install
|
|
8
|
+
|
|
9
|
+
Requires Python 3.9 or newer. Linux and macOS are recommended.
|
|
10
|
+
|
|
11
|
+
```bash
|
|
12
|
+
python -m pip install "git+https://github.com/qussai96/PepLocus.git"
|
|
13
|
+
```
|
|
14
|
+
|
|
15
|
+
Once published on PyPI:
|
|
16
|
+
|
|
17
|
+
```bash
|
|
18
|
+
python -m pip install peplocus
|
|
19
|
+
```
|
|
20
|
+
|
|
21
|
+
Dependencies are installed automatically; no external aligner is needed.
|
|
22
|
+
|
|
23
|
+
## Run
|
|
24
|
+
|
|
25
|
+
Map a peptide list to an assembly:
|
|
26
|
+
|
|
27
|
+
```bash
|
|
28
|
+
peplocus -a assembly.fa -p peptides.tsv --out results
|
|
29
|
+
```
|
|
30
|
+
|
|
31
|
+
Add annotation and/or RNA-seq evidence to find splice-junction placements:
|
|
32
|
+
|
|
33
|
+
```bash
|
|
34
|
+
peplocus -a assembly.fa -p peptides.tsv -g models.gtf -b rnaseq.bam --out results_spliced
|
|
35
|
+
```
|
|
36
|
+
|
|
37
|
+
`-g` accepts GTF or GFF. Either `-g` or `-b` can be used alone. A BAM index is not required.
|
|
38
|
+
|
|
39
|
+
Optional one-edit rescue searches peptides with no exact match for one amino-acid substitution, insertion or deletion:
|
|
40
|
+
|
|
41
|
+
```bash
|
|
42
|
+
peplocus -a assembly.fa -p peptides.tsv -g models.gtf --rescue-one-edit --out results_rescue
|
|
43
|
+
```
|
|
44
|
+
|
|
45
|
+
The default is **8 workers** (`--threads`). Rescue uses a minimum query length of **9 aa**; short candidates can be highly ambiguous. Use `--min-rescue-length 12` for a more conservative search. `--discover-junctions` optionally searches for bounded canonical single-intron matches without supplied evidence.
|
|
46
|
+
|
|
47
|
+
Peptides can be a plain list, FASTA, CSV or TSV; FragPipe's `Peptide Sequence` column is recognised automatically. Assembly FASTA may be plain or gzip-compressed. Use a fresh output directory for each run.
|
|
48
|
+
|
|
49
|
+
```bash
|
|
50
|
+
peplocus -h
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
## Results
|
|
54
|
+
|
|
55
|
+
| File | Contents |
|
|
56
|
+
|---|---|
|
|
57
|
+
| `all_mappings.bed` | Exact and I/L-equivalent placements |
|
|
58
|
+
| `tryptic_mappings.bed` | Placements with compatible tryptic or possible protein-terminal contexts |
|
|
59
|
+
| `mappings.tsv` | Coordinates, sequences, evidence, cleavage contexts and mapping counts |
|
|
60
|
+
| `peptides.tsv` | Per-peptide exact and rescue counts and status |
|
|
61
|
+
| `unmapped.tsv` | Peptides with no exact match, including labeled rescue candidates |
|
|
62
|
+
| `summary.json` | Parameters, counts, timings and search limits |
|
|
63
|
+
|
|
64
|
+
BED files use standard BED12 coordinates, with peptide names in biological N-to-C orientation on both strands. Rescue candidates are kept separately in `rescue/`, with their own all/tryptic BED files and detailed TSV. A reusable `junctions.tsv` is also saved when splice evidence is supplied.
|
|
65
|
+
|
|
66
|
+
Contiguous matching is exhaustive for the chosen translation table. Splice mapping depends on available junctions and search limits. Placements show sequence compatibility; one-edit candidates are not confirmed variants, and tryptic compatibility alone does not establish biological origin.
|
|
67
|
+
|
|
68
|
+
[Report an issue](https://github.com/qussai96/PepLocus/issues) · [MIT license](https://github.com/qussai96/PepLocus/blob/main/LICENSE)
|
|
@@ -0,0 +1,31 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["setuptools>=77.0.3", "wheel"]
|
|
3
|
+
build-backend = "setuptools.build_meta"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "peplocus"
|
|
7
|
+
version = "0.5.6"
|
|
8
|
+
description = "Fast peptide-to-genome mapping with splice-junction support and one-edit rescue"
|
|
9
|
+
readme = "README.md"
|
|
10
|
+
requires-python = ">=3.9"
|
|
11
|
+
license = "MIT"
|
|
12
|
+
license-files = ["LICENSE"]
|
|
13
|
+
authors = [{name = "Qussai Abbas"}]
|
|
14
|
+
keywords = ["proteogenomics", "peptides", "genome", "splicing", "BED12"]
|
|
15
|
+
classifiers = [
|
|
16
|
+
"Development Status :: 3 - Alpha",
|
|
17
|
+
"Programming Language :: Python :: 3",
|
|
18
|
+
"Topic :: Scientific/Engineering :: Bio-Informatics",
|
|
19
|
+
]
|
|
20
|
+
dependencies = ["numpy>=1.23", "biopython>=1.80", "pyahocorasick>=2.0", "pysam>=0.22"]
|
|
21
|
+
|
|
22
|
+
[project.urls]
|
|
23
|
+
Homepage = "https://github.com/qussai96/PepLocus"
|
|
24
|
+
Source = "https://github.com/qussai96/PepLocus"
|
|
25
|
+
Issues = "https://github.com/qussai96/PepLocus/issues"
|
|
26
|
+
|
|
27
|
+
[project.scripts]
|
|
28
|
+
peplocus = "peplocus.cli:main"
|
|
29
|
+
|
|
30
|
+
[tool.setuptools.packages.find]
|
|
31
|
+
where = ["src"]
|
peplocus-0.5.6/setup.cfg
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
1
|
+
"""PepLocus: peptide coordinates directly from genome assemblies."""
|
|
2
|
+
__version__ = "0.5.6"
|
|
3
|
+
|
|
4
|
+
|
|
5
|
+
def map_peptides(assembly=None, peptides=None, out=None, **options):
|
|
6
|
+
"""Map peptide-file paths with CLI-equivalent options; return summary dict."""
|
|
7
|
+
from .api import map_peptides as run
|
|
8
|
+
return run(assembly, peptides, out, **options)
|
|
9
|
+
|
|
10
|
+
|
|
11
|
+
__all__ = ["__version__", "map_peptides"]
|
|
@@ -0,0 +1,103 @@
|
|
|
1
|
+
"""Read transcript exon structures from GTF and GFF3-style Helixer annotations."""
|
|
2
|
+
from collections import Counter, defaultdict
|
|
3
|
+
import gzip
|
|
4
|
+
import re
|
|
5
|
+
from urllib.parse import unquote
|
|
6
|
+
|
|
7
|
+
from .junctions import Junction, motif
|
|
8
|
+
|
|
9
|
+
|
|
10
|
+
_ATTRIBUTE = re.compile(
|
|
11
|
+
r'(?:^|;)\s*([^\s=;]+)\s*(?:=\s*|\s+)'
|
|
12
|
+
r'("(?:[^"\\]|\\.)*"|\'(?:[^\'\\]|\\.)*\'|[^;]*)'
|
|
13
|
+
)
|
|
14
|
+
|
|
15
|
+
|
|
16
|
+
def annotation_parents(attributes):
|
|
17
|
+
"""Read GTF/GFF2/GFF3 relationships without grouping separate isoforms by gene.
|
|
18
|
+
|
|
19
|
+
Split GFF3 Parent lists before URL decoding: an encoded comma is part of an ID.
|
|
20
|
+
Protein-only and bare transcript labels support older predictor output.
|
|
21
|
+
"""
|
|
22
|
+
attrs = {}
|
|
23
|
+
for match in _ATTRIBUTE.finditer(attributes):
|
|
24
|
+
key, value = match.groups()
|
|
25
|
+
value = value.strip()
|
|
26
|
+
quoted = len(value) >= 2 and value[0] == value[-1] and value[0] in {'"', "'"}
|
|
27
|
+
if quoted:
|
|
28
|
+
value = re.sub(r'\\([\\"\'])', r'\1', value[1:-1])
|
|
29
|
+
attrs[key.lower()] = value
|
|
30
|
+
for key in ('transcript_id', 'parent', 'protein_id'):
|
|
31
|
+
value = attrs.get(key)
|
|
32
|
+
if value and value != '.':
|
|
33
|
+
parts = value.split(',') if key == 'parent' else [value]
|
|
34
|
+
return [unquote(part.strip()) for part in parts if part.strip()]
|
|
35
|
+
bare = attributes.strip().rstrip(';').strip()
|
|
36
|
+
if re.fullmatch(r'[\w.:%+|/-]+', bare) and bare != '.':
|
|
37
|
+
return [unquote(bare)]
|
|
38
|
+
return []
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
def read_annotation(path, fasta, lengths):
|
|
42
|
+
"""Return exon-adjacency junctions, without pretending annotation is read support.
|
|
43
|
+
|
|
44
|
+
Exons are preferred per transcript; CDS intervals are a fallback when exons
|
|
45
|
+
are absent. CDS phase is not trimmed: every junction is searched in all frames,
|
|
46
|
+
preserving codons split across introns. Annotated introns are not BAM-filtered.
|
|
47
|
+
"""
|
|
48
|
+
transcripts = defaultdict(lambda: {"exon": set(), "CDS": set()})
|
|
49
|
+
identities = {}
|
|
50
|
+
stats = Counter()
|
|
51
|
+
opener = gzip.open if str(path).endswith('.gz') else open
|
|
52
|
+
with opener(path, 'rt') as handle:
|
|
53
|
+
for number, line in enumerate(handle, 1):
|
|
54
|
+
if line.startswith('##FASTA'):
|
|
55
|
+
break
|
|
56
|
+
if not line.strip() or line.startswith('#'):
|
|
57
|
+
continue
|
|
58
|
+
fields = line.rstrip('\n').split('\t')
|
|
59
|
+
if len(fields) != 9:
|
|
60
|
+
raise ValueError(f"annotation line {number}: expected 9 GTF/GFF columns")
|
|
61
|
+
chrom, _, feature, start, end, _, strand, _, attributes = fields
|
|
62
|
+
feature = feature.lower()
|
|
63
|
+
if feature not in {'exon', 'cds'}:
|
|
64
|
+
continue
|
|
65
|
+
feature = 'CDS' if feature == 'cds' else 'exon'
|
|
66
|
+
stats['feature_rows'] += 1
|
|
67
|
+
if chrom not in lengths:
|
|
68
|
+
stats['feature_rows_unknown_contig'] += 1
|
|
69
|
+
continue
|
|
70
|
+
start, end = int(start)-1, int(end)
|
|
71
|
+
if not 0 <= start < end <= lengths[chrom]:
|
|
72
|
+
raise ValueError(f"annotation line {number}: interval outside assembly")
|
|
73
|
+
if strand not in {'+', '-'}:
|
|
74
|
+
raise ValueError(f"annotation line {number}: exon/CDS requires + or - strand")
|
|
75
|
+
parents = annotation_parents(attributes)
|
|
76
|
+
if not parents:
|
|
77
|
+
raise ValueError(f"annotation line {number}: exon/CDS lacks transcript_id or Parent (or protein_id/bare transcript label); gene-only features cannot resolve isoforms")
|
|
78
|
+
for parent in parents:
|
|
79
|
+
identity = (chrom, strand)
|
|
80
|
+
if parent in identities and identities[parent] != identity:
|
|
81
|
+
raise ValueError(f"annotation transcript {parent!r} appears on conflicting contigs/strands")
|
|
82
|
+
identities[parent] = identity
|
|
83
|
+
transcripts[(chrom, strand, parent)][feature].add((start, end))
|
|
84
|
+
if not transcripts:
|
|
85
|
+
raise ValueError('annotation contains no usable exon/CDS transcripts on assembly contigs')
|
|
86
|
+
junctions = {}
|
|
87
|
+
for (chrom, strand, parent), features in transcripts.items():
|
|
88
|
+
exons = sorted(features['exon'] or features['CDS'])
|
|
89
|
+
stats['transcripts'] += 1
|
|
90
|
+
stats['transcripts_exon' if features['exon'] else 'transcripts_cds_fallback'] += 1
|
|
91
|
+
# Merge touching/overlapping segments; they do not define an intron.
|
|
92
|
+
merged = []
|
|
93
|
+
for a,b in exons:
|
|
94
|
+
if merged and a <= merged[-1][1]:
|
|
95
|
+
merged[-1] = (merged[-1][0], max(b, merged[-1][1]))
|
|
96
|
+
else:
|
|
97
|
+
merged.append((a,b))
|
|
98
|
+
for left, right in zip(merged, merged[1:]):
|
|
99
|
+
start, end = left[1], right[0]
|
|
100
|
+
key = (chrom, start, end, strand)
|
|
101
|
+
junctions[key] = Junction(chrom, start, end, strand, 0, 'annotation', motif(fasta, chrom, start, end, strand))
|
|
102
|
+
stats['junctions_retained'] = len(junctions)
|
|
103
|
+
return sorted(junctions.values()), dict(stats)
|
|
@@ -0,0 +1,43 @@
|
|
|
1
|
+
"""Python entry point using exactly the same defaults as the command line."""
|
|
2
|
+
import argparse
|
|
3
|
+
|
|
4
|
+
|
|
5
|
+
def map_peptides(assembly=None, peptides=None, out=None, *, threads=8, **options):
|
|
6
|
+
"""Map a peptide file; return the run summary dictionary.
|
|
7
|
+
|
|
8
|
+
Keyword options use CLI names with underscores, e.g. gtf=..., bam=...,
|
|
9
|
+
rescue_one_edit=True, min_rescue_length=9, chunk_size=2000000.
|
|
10
|
+
Invalid options raise ValueError. Inputs are paths, never modified in place.
|
|
11
|
+
"""
|
|
12
|
+
if "genome" in options:
|
|
13
|
+
if assembly is not None:
|
|
14
|
+
raise ValueError("use assembly only; genome is a legacy alias")
|
|
15
|
+
assembly=options.pop("genome")
|
|
16
|
+
if assembly is None or peptides is None or out is None:
|
|
17
|
+
raise ValueError("assembly, peptides and out are required")
|
|
18
|
+
from .cli import parser, validate_arguments
|
|
19
|
+
root=parser()
|
|
20
|
+
def error(message):raise ValueError(message)
|
|
21
|
+
root.error=error
|
|
22
|
+
actions={action.dest:action for action in root._actions if action.option_strings}
|
|
23
|
+
if "min_rescue_length" in options:
|
|
24
|
+
if "rescue_min_length" in options:
|
|
25
|
+
raise ValueError("use only min_rescue_length (rescue_min_length is a legacy alias)")
|
|
26
|
+
options["rescue_min_length"]=options.pop("min_rescue_length")
|
|
27
|
+
if "il_equivalent" in options and options["il_equivalent"] is not True:
|
|
28
|
+
raise ValueError("I/L equivalence is always enabled; il_equivalent must be True")
|
|
29
|
+
values=dict(options,threads=threads)
|
|
30
|
+
argv=["--assembly",str(assembly),"--peptides",str(peptides),"--out",str(out)]
|
|
31
|
+
for key,value in values.items():
|
|
32
|
+
if key not in actions or key in {"help","help_advanced","version","genome","peptides","out"}:
|
|
33
|
+
raise ValueError("unknown or reserved mapping option: "+key)
|
|
34
|
+
action=actions[key]
|
|
35
|
+
flag=action.option_strings[0]
|
|
36
|
+
if isinstance(action,argparse._StoreTrueAction):
|
|
37
|
+
if not isinstance(value,bool):raise ValueError(key+" must be boolean")
|
|
38
|
+
if value:argv.append(flag)
|
|
39
|
+
elif value is not None:
|
|
40
|
+
argv.extend([flag,str(value)])
|
|
41
|
+
args=root.parse_args(argv)
|
|
42
|
+
validate_arguments(args)
|
|
43
|
+
return args.func(args)
|
|
@@ -0,0 +1,232 @@
|
|
|
1
|
+
"""PepLocus command-line interface."""
|
|
2
|
+
import argparse
|
|
3
|
+
import csv
|
|
4
|
+
import json
|
|
5
|
+
import logging
|
|
6
|
+
from pathlib import Path
|
|
7
|
+
import sys
|
|
8
|
+
import tempfile
|
|
9
|
+
|
|
10
|
+
import pysam
|
|
11
|
+
|
|
12
|
+
from . import __version__
|
|
13
|
+
from .io import prepare_reference
|
|
14
|
+
from .junctions import extract_bam, write_junctions
|
|
15
|
+
from .annotation import read_annotation
|
|
16
|
+
from .output import EDIT_FIELDS
|
|
17
|
+
from .pipeline import map_peptides
|
|
18
|
+
from .rescue import one_edit
|
|
19
|
+
from .sequence import canonical, join_blocks, translate
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
class _HelpParser(argparse.ArgumentParser):
|
|
23
|
+
"""Keep tuning flags parseable while presenting a small everyday interface."""
|
|
24
|
+
def _view(self, render):
|
|
25
|
+
hidden=[] if getattr(self,"_show_advanced",False) else getattr(self,"_advanced_actions",[])
|
|
26
|
+
saved=[(action,action.help) for action in hidden]
|
|
27
|
+
try:
|
|
28
|
+
for action,_ in saved:action.help=argparse.SUPPRESS
|
|
29
|
+
return render()
|
|
30
|
+
finally:
|
|
31
|
+
for action,help_text in saved:action.help=help_text
|
|
32
|
+
|
|
33
|
+
def parse_args(self, args=None, namespace=None):
|
|
34
|
+
args=list(sys.argv[1:] if args is None else args)
|
|
35
|
+
if args[:1]==["map"]:args=args[1:] # compatibility with older scripts
|
|
36
|
+
return super().parse_args(args, namespace)
|
|
37
|
+
|
|
38
|
+
def format_help(self):return self._view(super().format_help)
|
|
39
|
+
def format_usage(self):return self._view(super().format_usage)
|
|
40
|
+
|
|
41
|
+
|
|
42
|
+
class _AdvancedHelp(argparse.Action):
|
|
43
|
+
def __call__(self, parser, namespace, values, option_string=None):
|
|
44
|
+
parser._show_advanced=True
|
|
45
|
+
parser.print_help()
|
|
46
|
+
parser.exit()
|
|
47
|
+
|
|
48
|
+
|
|
49
|
+
def positive(text):
|
|
50
|
+
value = int(text)
|
|
51
|
+
if value < 1:
|
|
52
|
+
raise argparse.ArgumentTypeError("must be a positive integer")
|
|
53
|
+
return value
|
|
54
|
+
|
|
55
|
+
|
|
56
|
+
def nonnegative(text):
|
|
57
|
+
value = int(text)
|
|
58
|
+
if value < 0:
|
|
59
|
+
raise argparse.ArgumentTypeError("must be zero or a positive integer")
|
|
60
|
+
return value
|
|
61
|
+
|
|
62
|
+
|
|
63
|
+
def junction_options(parser):
|
|
64
|
+
parser.add_argument("--min-mapq", type=nonnegative, default=10, help="minimum BAM mapping quality (default: 10)")
|
|
65
|
+
parser.add_argument("--min-read-anchor", type=positive, default=8, help="aligned bases on each side of a BAM intron (default: 8)")
|
|
66
|
+
parser.add_argument("--min-junction-support", type=positive, default=2, help="minimum primary, nonduplicate alignment observations per junction (default: 2)")
|
|
67
|
+
parser.add_argument("--min-intron", type=positive, default=20, help="minimum BAM/discovery intron length in bp (default: 20)")
|
|
68
|
+
parser.add_argument("--max-intron", type=positive, default=500000, help="maximum BAM/discovery intron length in bp (default: 500000)")
|
|
69
|
+
|
|
70
|
+
|
|
71
|
+
def run_junctions(args):
|
|
72
|
+
out = Path(args.out)
|
|
73
|
+
if out.exists():
|
|
74
|
+
raise ValueError(f"output already exists: {out}")
|
|
75
|
+
out.parent.mkdir(parents=True, exist_ok=True)
|
|
76
|
+
with tempfile.TemporaryDirectory(prefix="peplocus-junctions-") as cache:
|
|
77
|
+
genome, index, lengths = prepare_reference(args.genome, cache)
|
|
78
|
+
with pysam.FastaFile(genome, filepath_index=index) as fasta:
|
|
79
|
+
junctions, stats = [], {}
|
|
80
|
+
if args.bam:
|
|
81
|
+
junctions, bam_stats = extract_bam(args.bam, fasta, lengths, args.min_mapq, args.min_read_anchor, args.min_junction_support, args.min_intron, args.max_intron)
|
|
82
|
+
stats["bam"] = bam_stats
|
|
83
|
+
if args.gtf:
|
|
84
|
+
annotation_junctions, annotation_stats = read_annotation(args.gtf, fasta, lengths)
|
|
85
|
+
junctions.extend(annotation_junctions)
|
|
86
|
+
stats["annotation"] = annotation_stats
|
|
87
|
+
write_junctions(out, junctions)
|
|
88
|
+
print(json.dumps(stats, indent=2))
|
|
89
|
+
|
|
90
|
+
|
|
91
|
+
def run_verify(args):
|
|
92
|
+
count = 0
|
|
93
|
+
with tempfile.TemporaryDirectory(prefix="peplocus-verify-") as cache:
|
|
94
|
+
genome, index, lengths = prepare_reference(args.genome, cache)
|
|
95
|
+
with pysam.FastaFile(genome, filepath_index=index) as fasta, open(args.mappings) as handle:
|
|
96
|
+
reader = csv.DictReader(handle, delimiter="\t")
|
|
97
|
+
if not {"peptide", "chrom", "strand", "blocks", "matched_sequence"} <= set(reader.fieldnames or []):
|
|
98
|
+
raise ValueError("expected a PepLocus mappings.tsv file")
|
|
99
|
+
for row in reader:
|
|
100
|
+
if not all(isinstance(row.get(name),str) and row[name] for name in ("peptide","chrom","strand","blocks","matched_sequence")):
|
|
101
|
+
raise ValueError("mapping row has empty required fields")
|
|
102
|
+
blocks = json.loads(row["blocks"])
|
|
103
|
+
if not isinstance(blocks,list) or not all(isinstance(block,list) and len(block)==2 and
|
|
104
|
+
all(type(value) is int for value in block) for block in blocks):
|
|
105
|
+
raise ValueError("mapping blocks must be a list of integer coordinate pairs")
|
|
106
|
+
if row["strand"] not in {"+", "-"} or row["chrom"] not in lengths or not blocks:
|
|
107
|
+
raise ValueError(f"invalid mapping: {row}")
|
|
108
|
+
previous = -1
|
|
109
|
+
for a,b in blocks:
|
|
110
|
+
if not 0 <= a < b <= lengths[row["chrom"]] or a < previous:
|
|
111
|
+
raise ValueError(f"invalid genomic blocks: {blocks}")
|
|
112
|
+
previous = b
|
|
113
|
+
if sum(b-a for a,b in blocks) != 3*len(row["matched_sequence"]):
|
|
114
|
+
raise ValueError("mapping blocks do not span complete matched codons")
|
|
115
|
+
if "start" in row and (int(row["start"])!=blocks[0][0] or int(row["end"])!=blocks[-1][1]):
|
|
116
|
+
raise ValueError("mapping start/end disagree with blocks")
|
|
117
|
+
observed = translate(join_blocks(fasta, row["chrom"], row["strand"], blocks), args.genetic_code)
|
|
118
|
+
if row.get("match_type") == "one_edit":
|
|
119
|
+
edit = one_edit(row["peptide"], observed, args.il_equivalent)
|
|
120
|
+
valid = (observed == row["matched_sequence"] and edit is not None
|
|
121
|
+
and row.get("edit_distance") == "1"
|
|
122
|
+
and all(str(edit[key]) == row.get(key) for key in
|
|
123
|
+
EDIT_FIELDS))
|
|
124
|
+
else:
|
|
125
|
+
valid = observed == row["matched_sequence"] and canonical(observed,args.il_equivalent) == canonical(row["peptide"],args.il_equivalent)
|
|
126
|
+
if not valid:
|
|
127
|
+
raise ValueError(f"mapping does not reproduce peptide/alignment: {row['peptide']} at {row['chrom']}:{blocks}")
|
|
128
|
+
count += 1
|
|
129
|
+
print(json.dumps({"verified_loci": count, "valid": True}))
|
|
130
|
+
|
|
131
|
+
|
|
132
|
+
def parser(command=None):
|
|
133
|
+
if command in {"junctions", "verify"}:
|
|
134
|
+
return utility_parser(command)
|
|
135
|
+
mapping = _HelpParser(prog="peplocus",
|
|
136
|
+
description=None,
|
|
137
|
+
epilog="For tuning controls: peplocus --help-advanced",
|
|
138
|
+
formatter_class=argparse.RawDescriptionHelpFormatter)
|
|
139
|
+
mapping.add_argument("--version", action="version", version=f"PepLocus {__version__}")
|
|
140
|
+
mapping.add_argument("--help-advanced", action=_AdvancedHelp, nargs=0,
|
|
141
|
+
help="show advanced controls and exit")
|
|
142
|
+
mapping.add_argument("-a", "--assembly", "--genome", dest="genome", metavar="ASSEMBLY", required=True, help="assembly FASTA (plain or gzip)")
|
|
143
|
+
mapping.add_argument("-p", "--peptides", required=True, help="peptide list, FASTA, CSV or TSV")
|
|
144
|
+
mapping.add_argument("--peptide-column", help="column name in CSV/TSV input")
|
|
145
|
+
mapping.add_argument("--out", required=True, help="output directory without existing PepLocus results")
|
|
146
|
+
mapping.add_argument("-g", "--gtf", "--gff", dest="gtf", help="annotation supplying splice junctions (GTF/GFF)")
|
|
147
|
+
mapping.add_argument("-b", "--bam", help="optional RNA-seq BAM; no index required")
|
|
148
|
+
mapping.add_argument("--junctions", help="optional reusable PepLocus junction TSV")
|
|
149
|
+
mapping.add_argument("--threads", type=positive, default=8, help="worker processes (default: 8)")
|
|
150
|
+
mapping.add_argument("--chunk-size", type=positive, default=2000000, help="genomic bases per worker task (default: 2000000)")
|
|
151
|
+
mapping.add_argument("--min-length", type=positive, default=1, help="minimum peptide length; short matches can be highly ambiguous")
|
|
152
|
+
mapping.add_argument("--il-equivalent", action="store_true", default=True, help=argparse.SUPPRESS)
|
|
153
|
+
mapping.add_argument("--genetic-code", type=positive, default=1, help="NCBI translation table; applies to every contig (default: 1)")
|
|
154
|
+
mapping.add_argument("--rescue-one-edit", action="store_true", help="rescue exact-unmapped peptides with one amino-acid edit")
|
|
155
|
+
mapping.add_argument("--min-rescue-length", dest="rescue_min_length", metavar="MIN_LENGTH", type=positive, default=9, help="minimum query length for one-edit rescue (default: 9)")
|
|
156
|
+
mapping.add_argument("--igv-display-bed", action="store_true", help="also write a display-only BED with reversed negative-strand labels and GAPMS-style colors")
|
|
157
|
+
mapping.add_argument("--no-verify", action="store_true", help="skip final extraction/translation verification (enabled by default)")
|
|
158
|
+
junction_options(mapping)
|
|
159
|
+
mapping.add_argument("--max-junctions", type=positive, default=3, help="maximum introns crossed by a supported peptide path (default: 3)")
|
|
160
|
+
mapping.add_argument("--max-paths-per-junction", type=nonnegative, default=1000, help="splice graph path cap per first intron; 0 means unlimited")
|
|
161
|
+
mapping.add_argument("--discover-junctions", action="store_true", help="discover bounded single-intron alignments without annotation")
|
|
162
|
+
mapping.add_argument("--discover-all", action="store_true", help="run discovery for mapped peptides too (requires --discover-junctions)")
|
|
163
|
+
mapping.add_argument("--novel-anchor", type=positive, default=4, help="amino acids required at each terminal discovery anchor (default: 4)")
|
|
164
|
+
mapping.add_argument("--novel-cache-mb", type=nonnegative, default=256, help="memory budget for caching small contigs during discovery; 0 disables it (default: 256 MiB)")
|
|
165
|
+
mapping.add_argument("--max-seed-hits", type=nonnegative, default=2000, help="discovery seed-hit cap per contig/strand; 0 means unlimited")
|
|
166
|
+
mapping.add_argument("--max-novel-pairs", type=nonnegative, default=10000, help="discovery candidate-junction cap per peptide/contig/strand; 0 means unlimited")
|
|
167
|
+
common={"help","version","help_advanced","genome","peptides","out","gtf","bam","threads",
|
|
168
|
+
"rescue_min_length","rescue_one_edit","discover_junctions"}
|
|
169
|
+
mapping._advanced_actions=[action for action in mapping._actions if action.dest not in common]
|
|
170
|
+
advanced=mapping.add_argument_group("Advanced controls")
|
|
171
|
+
for action in mapping._advanced_actions:
|
|
172
|
+
for group in mapping._action_groups:
|
|
173
|
+
if group is not advanced and action in group._group_actions:group._group_actions.remove(action)
|
|
174
|
+
advanced._group_actions.append(action)
|
|
175
|
+
mapping.set_defaults(func=map_peptides, command="map")
|
|
176
|
+
return mapping
|
|
177
|
+
|
|
178
|
+
|
|
179
|
+
def utility_parser(command):
|
|
180
|
+
"""Legacy utilities, kept for existing scripts; mapping needs no subcommand."""
|
|
181
|
+
junction = argparse.ArgumentParser(prog="peplocus junctions")
|
|
182
|
+
junction.add_argument("-a", "--assembly", "--genome", dest="genome", metavar="ASSEMBLY", required=True)
|
|
183
|
+
junction.add_argument("-b", "--bam", help="RNA-seq BAM")
|
|
184
|
+
junction.add_argument("-g", "--gtf", "--gff", dest="gtf", help="GTF or Helixer GFF3-style annotation")
|
|
185
|
+
junction.add_argument("--out", required=True, help="new junction TSV path")
|
|
186
|
+
junction_options(junction)
|
|
187
|
+
junction.set_defaults(func=run_junctions, command="junctions")
|
|
188
|
+
verify = argparse.ArgumentParser(prog="peplocus verify")
|
|
189
|
+
verify.add_argument("-a", "--assembly", "--genome", dest="genome", metavar="ASSEMBLY", required=True)
|
|
190
|
+
verify.add_argument("--mappings", required=True)
|
|
191
|
+
verify.add_argument("--il-equivalent", action="store_true", default=True, help=argparse.SUPPRESS)
|
|
192
|
+
verify.add_argument("--genetic-code", type=positive, default=1)
|
|
193
|
+
verify.set_defaults(func=run_verify, command="verify")
|
|
194
|
+
return junction if command == "junctions" else verify
|
|
195
|
+
|
|
196
|
+
|
|
197
|
+
def validate_arguments(args):
|
|
198
|
+
if args.command == "junctions" and not (args.bam or args.gtf):
|
|
199
|
+
raise ValueError("junctions requires --bam and/or --gtf")
|
|
200
|
+
if hasattr(args,"min_intron") and args.min_intron > args.max_intron:
|
|
201
|
+
raise ValueError("--min-intron cannot exceed --max-intron")
|
|
202
|
+
if getattr(args,"discover_all",False) and not args.discover_junctions:
|
|
203
|
+
raise ValueError("--discover-all requires --discover-junctions")
|
|
204
|
+
from Bio.Data import CodonTable
|
|
205
|
+
if getattr(args,"genetic_code",1) not in CodonTable.unambiguous_dna_by_id:
|
|
206
|
+
raise ValueError("--genetic-code must be a valid NCBI DNA translation-table number")
|
|
207
|
+
code=CodonTable.unambiguous_dna_by_id[getattr(args,"genetic_code",1)]
|
|
208
|
+
if set(code.stop_codons) & set(code.forward_table):
|
|
209
|
+
raise ValueError("context-dependent stop codons are unsupported for --genetic-code; choose a table with unambiguous stop semantics")
|
|
210
|
+
if getattr(args,"rescue_min_length",2) < 2:
|
|
211
|
+
raise ValueError("--min-rescue-length must be at least 2")
|
|
212
|
+
|
|
213
|
+
|
|
214
|
+
def main(argv=None):
|
|
215
|
+
argv=list(sys.argv[1:] if argv is None else argv)
|
|
216
|
+
command=argv.pop(0) if argv[:1] and argv[0] in {"junctions", "verify"} else None
|
|
217
|
+
root = parser(command)
|
|
218
|
+
args = root.parse_args(argv)
|
|
219
|
+
logging.basicConfig(level=logging.INFO, format="%(asctime)s %(levelname)s %(message)s")
|
|
220
|
+
try:
|
|
221
|
+
validate_arguments(args)
|
|
222
|
+
except ValueError as error:
|
|
223
|
+
root.error(str(error))
|
|
224
|
+
try:
|
|
225
|
+
args.func(args)
|
|
226
|
+
except (ValueError, OSError, KeyError) as error:
|
|
227
|
+
logging.getLogger("peplocus").error("%s", error)
|
|
228
|
+
return 2
|
|
229
|
+
except KeyboardInterrupt:
|
|
230
|
+
logging.getLogger("peplocus").error("Interrupted; no completed result summary was published")
|
|
231
|
+
return 130
|
|
232
|
+
return 0
|