pdfexorcist 0.1.1__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- pdfexorcist-0.1.1/CHANGELOG.md +17 -0
- pdfexorcist-0.1.1/LICENSE +21 -0
- pdfexorcist-0.1.1/MANIFEST.in +8 -0
- pdfexorcist-0.1.1/PKG-INFO +583 -0
- pdfexorcist-0.1.1/README.md +515 -0
- pdfexorcist-0.1.1/examples/census_iips_district/iips_district_projection.py +110 -0
- pdfexorcist-0.1.1/examples/census_iips_district/recipe.toml +36 -0
- pdfexorcist-0.1.1/examples/census_mohfw_state/mohfw_state_projection.py +91 -0
- pdfexorcist-0.1.1/examples/census_mohfw_state/recipe.toml +47 -0
- pdfexorcist-0.1.1/examples/crime_in_india.toml +47 -0
- pdfexorcist-0.1.1/examples/crs_state_tables/crs_state_table.py +87 -0
- pdfexorcist-0.1.1/examples/crs_state_tables/recipe.toml +45 -0
- pdfexorcist-0.1.1/examples/crs_state_tables/table4.toml +35 -0
- pdfexorcist-0.1.1/examples/lake_photo/bmc_lake_report.py +89 -0
- pdfexorcist-0.1.1/examples/lake_photo/recipe.toml +33 -0
- pdfexorcist-0.1.1/examples/mccd/mccd_table4.py +248 -0
- pdfexorcist-0.1.1/examples/mccd/mccd_tables.py +108 -0
- pdfexorcist-0.1.1/examples/mccd/table2.toml +43 -0
- pdfexorcist-0.1.1/examples/mccd/table4.toml +56 -0
- pdfexorcist-0.1.1/examples/mccd/table5.toml +47 -0
- pdfexorcist-0.1.1/examples/mccd/table9.toml +44 -0
- pdfexorcist-0.1.1/examples/mccd/unfitted.toml +44 -0
- pdfexorcist-0.1.1/examples/nfhs5/README.md +169 -0
- pdfexorcist-0.1.1/examples/nfhs5/clean.py +6 -0
- pdfexorcist-0.1.1/examples/nfhs5/district.toml +36 -0
- pdfexorcist-0.1.1/examples/nfhs5/families.toml +32 -0
- pdfexorcist-0.1.1/examples/nfhs5/nfhs5_factsheet.py +205 -0
- pdfexorcist-0.1.1/examples/nfhs5/numbers.toml +33 -0
- pdfexorcist-0.1.1/examples/nfhs5/state.toml +38 -0
- pdfexorcist-0.1.1/examples/nfhs6/README.md +176 -0
- pdfexorcist-0.1.1/examples/nfhs6/district.toml +37 -0
- pdfexorcist-0.1.1/examples/nfhs6/nfhs6_factsheet.py +174 -0
- pdfexorcist-0.1.1/examples/nfhs6/state.toml +42 -0
- pdfexorcist-0.1.1/examples/nfhs6/unanimous.toml +35 -0
- pdfexorcist-0.1.1/examples/nta_notice/nta_notice.py +127 -0
- pdfexorcist-0.1.1/examples/nta_notice/recipe.toml +66 -0
- pdfexorcist-0.1.1/examples/nta_toppers/nta_toppers.py +128 -0
- pdfexorcist-0.1.1/examples/nta_toppers/recipe.toml +37 -0
- pdfexorcist-0.1.1/examples/pravah_dams/pravah_dams.py +92 -0
- pdfexorcist-0.1.1/examples/pravah_dams/recipe.toml +42 -0
- pdfexorcist-0.1.1/examples/settings/cii_columns.toml +33 -0
- pdfexorcist-0.1.1/examples/settings/cii_population.toml +30 -0
- pdfexorcist-0.1.1/examples/settings/cii_rows.toml +33 -0
- pdfexorcist-0.1.1/examples/settings/cleaning.toml +43 -0
- pdfexorcist-0.1.1/examples/settings/cleaning_ocr.toml +37 -0
- pdfexorcist-0.1.1/examples/settings/numbers.py +9 -0
- pdfexorcist-0.1.1/examples/srs_life_table/recipe.toml +31 -0
- pdfexorcist-0.1.1/examples/srs_life_table/srs_life_table.py +83 -0
- pdfexorcist-0.1.1/pdfexorcist/__init__.py +71 -0
- pdfexorcist-0.1.1/pdfexorcist/__main__.py +6 -0
- pdfexorcist-0.1.1/pdfexorcist/_cli_app.py +182 -0
- pdfexorcist-0.1.1/pdfexorcist/_cli_extract.py +164 -0
- pdfexorcist-0.1.1/pdfexorcist/_cli_recipe.py +242 -0
- pdfexorcist-0.1.1/pdfexorcist/_info.py +175 -0
- pdfexorcist-0.1.1/pdfexorcist/_ocr_engines.py +207 -0
- pdfexorcist-0.1.1/pdfexorcist/_output.py +269 -0
- pdfexorcist-0.1.1/pdfexorcist/_progress.py +77 -0
- pdfexorcist-0.1.1/pdfexorcist/_recipe_error.py +27 -0
- pdfexorcist-0.1.1/pdfexorcist/_recipe_load.py +369 -0
- pdfexorcist-0.1.1/pdfexorcist/_recipe_model.py +266 -0
- pdfexorcist-0.1.1/pdfexorcist/_recipe_text.py +107 -0
- pdfexorcist-0.1.1/pdfexorcist/_registry.py +34 -0
- pdfexorcist-0.1.1/pdfexorcist/_run.py +328 -0
- pdfexorcist-0.1.1/pdfexorcist/_show_cli.py +141 -0
- pdfexorcist-0.1.1/pdfexorcist/_show_frames.py +85 -0
- pdfexorcist-0.1.1/pdfexorcist/_show_layout.py +134 -0
- pdfexorcist-0.1.1/pdfexorcist/_text_engines.py +265 -0
- pdfexorcist-0.1.1/pdfexorcist/_ui.py +282 -0
- pdfexorcist-0.1.1/pdfexorcist/_usercode.py +89 -0
- pdfexorcist-0.1.1/pdfexorcist/_vision_worker.py +39 -0
- pdfexorcist-0.1.1/pdfexorcist/_vlm_engines.py +174 -0
- pdfexorcist-0.1.1/pdfexorcist/_wizard.py +238 -0
- pdfexorcist-0.1.1/pdfexorcist/_wizard_ask.py +206 -0
- pdfexorcist-0.1.1/pdfexorcist/_wizard_toml.py +149 -0
- pdfexorcist-0.1.1/pdfexorcist/cells.py +63 -0
- pdfexorcist-0.1.1/pdfexorcist/checks.py +94 -0
- pdfexorcist-0.1.1/pdfexorcist/cli.py +190 -0
- pdfexorcist-0.1.1/pdfexorcist/doctor.py +171 -0
- pdfexorcist-0.1.1/pdfexorcist/extractors.py +43 -0
- pdfexorcist-0.1.1/pdfexorcist/fetch.py +278 -0
- pdfexorcist-0.1.1/pdfexorcist/pages.py +122 -0
- pdfexorcist-0.1.1/pdfexorcist/py.typed +0 -0
- pdfexorcist-0.1.1/pdfexorcist/readings.py +106 -0
- pdfexorcist-0.1.1/pdfexorcist/recipe.py +36 -0
- pdfexorcist-0.1.1/pdfexorcist/rows.py +161 -0
- pdfexorcist-0.1.1/pdfexorcist/show.py +294 -0
- pdfexorcist-0.1.1/pdfexorcist/show_assets.py +342 -0
- pdfexorcist-0.1.1/pdfexorcist/show_html.py +129 -0
- pdfexorcist-0.1.1/pdfexorcist/show_png.py +190 -0
- pdfexorcist-0.1.1/pdfexorcist/vote.py +421 -0
- pdfexorcist-0.1.1/pdfexorcist.egg-info/PKG-INFO +583 -0
- pdfexorcist-0.1.1/pdfexorcist.egg-info/SOURCES.txt +259 -0
- pdfexorcist-0.1.1/pdfexorcist.egg-info/dependency_links.txt +1 -0
- pdfexorcist-0.1.1/pdfexorcist.egg-info/entry_points.txt +2 -0
- pdfexorcist-0.1.1/pdfexorcist.egg-info/requires.txt +54 -0
- pdfexorcist-0.1.1/pdfexorcist.egg-info/top_level.txt +1 -0
- pdfexorcist-0.1.1/pyproject.toml +124 -0
- pdfexorcist-0.1.1/setup.cfg +4 -0
- pdfexorcist-0.1.1/tests/adsi_state_table.py +271 -0
- pdfexorcist-0.1.1/tests/cii_state_table.py +220 -0
- pdfexorcist-0.1.1/tests/cli_helpers.py +36 -0
- pdfexorcist-0.1.1/tests/conftest.py +33 -0
- pdfexorcist-0.1.1/tests/fixtures/adsi/1995_t2A_p6.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/adsi/2023_t1.2_p35.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/adsi/2024_t1.2_p35.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/adsi/2024_t2.2_p238.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/adsi/expected.csv +737 -0
- pdfexorcist-0.1.1/tests/fixtures/adsi/make_fixtures.py +140 -0
- pdfexorcist-0.1.1/tests/fixtures/adsi/manifest.csv +5 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-01-12.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-01-12.json +125 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-07-28.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-07-28.json +128 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-08-20.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-08-20.json +127 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-09-15.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2024-09-15.json +124 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2025-07-10.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2025-07-10.json +128 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2025-07-28.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2025-07-28.json +128 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2025-09-15.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2025-09-15.json +125 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-07-03.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-07-03.json +239 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-07-15.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-07-15.json +248 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-07-28.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-07-28.json +250 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-08-05.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-08-05.json +250 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-08-19.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-08-19.json +250 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-08-26.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-08-26.json +250 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-09-05.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-09-05.json +250 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-09-15.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-09-15.json +250 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-09-28.jpg +0 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/2026-09-28.json +250 -0
- pdfexorcist-0.1.1/tests/fixtures/bmc/manifest.csv +17 -0
- pdfexorcist-0.1.1/tests/fixtures/cii/cii_2021_1A.1_p43.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/cii/cii_2023_1A.4_p47.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/cii/cii_2024_1C.2_p264.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/cii/expected.csv +897 -0
- pdfexorcist-0.1.1/tests/fixtures/cii/make_fixtures.py +139 -0
- pdfexorcist-0.1.1/tests/fixtures/cii/manifest.csv +4 -0
- pdfexorcist-0.1.1/tests/fixtures/crs/crs_2023_t1_t4.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/crs/expected.csv +649 -0
- pdfexorcist-0.1.1/tests/fixtures/crs/make_fixtures.py +59 -0
- pdfexorcist-0.1.1/tests/fixtures/crs/manifest.csv +3 -0
- pdfexorcist-0.1.1/tests/fixtures/cwc/cwc_2018-02-01_p4.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/iips/expected.csv +2321 -0
- pdfexorcist-0.1.1/tests/fixtures/iips/iips_p1125_andhra_prakasam.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/iips/iips_p240_delhi_west.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/iips/iips_p281_rajasthan_sirohi.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/iips/iips_p603_manipur_imphal_east.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/iips/make_fixtures.py +78 -0
- pdfexorcist-0.1.1/tests/fixtures/iips/manifest.csv +5 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/make_tables_fixtures.py +90 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/manifest.csv +4 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2009.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2009_expected.csv +58 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2011.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2011_expected.csv +55 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2014.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2014_expected.csv +64 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2018_t5_p104.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2019_t2_p68-69.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_2019_t9_p194.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_tables_expected.csv +3423 -0
- pdfexorcist-0.1.1/tests/fixtures/mccd/mccd_tables_manifest.csv +4 -0
- pdfexorcist-0.1.1/tests/fixtures/mohfw/expected.csv +613 -0
- pdfexorcist-0.1.1/tests/fixtures/mohfw/make_fixtures.py +66 -0
- pdfexorcist-0.1.1/tests/fixtures/mohfw/manifest.csv +4 -0
- pdfexorcist-0.1.1/tests/fixtures/mohfw/mohfw_india_p165-166.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mohfw/mohfw_uttar_pradesh_p198.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/mohfw/mohfw_uttarakhand_p182.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_district/expected.csv +417 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_district/make_fixtures.py +100 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_district/manifest.csv +5 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_district/nfhs5_kangra_p31-33.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_district/nfhs5_mahisagar_p121-123.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_district/nfhs5_north_middle_andaman_p19-21.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_district/nfhs5_raigarh_p169-171.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/VERIFICATION.md +188 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/bellary_94-97.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/bihar_literacy_2020.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/bihar_literacy_2021.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/chamba_31.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/chitradurga_94-97.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/dhule_101.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/kangra_16.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/koppal_94-97.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/mahisagar_9-12.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/raigarh_97.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/evidence/wardha_9-12.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/expected.csv +394 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/make_fixtures.py +120 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/manifest.csv +4 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/nfhs5_bihar_p3-6.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/nfhs5_chandigarh_p3-6.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs5_state/nfhs5_india_p3-6.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_district/expected.csv +373 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_district/make_fixtures.py +76 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_district/manifest.csv +5 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_district/nfhs6_anantapur_p15-17.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_district/nfhs6_gaurela_pendra_marwahi_p59-61.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_district/nfhs6_jhargram_p51-53.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_district/nfhs6_mumbai_p79-81.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_state/expected.csv +1030 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_state/make_fixtures.py +121 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_state/manifest.csv +5 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_state/nfhs6_bihar_p43-45.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_state/nfhs6_chandigarh_p145-147.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_state/nfhs6_india_p26-28.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nfhs6_state/nfhs6_tamil_nadu_p115.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nta/expected.csv +58 -0
- pdfexorcist-0.1.1/tests/fixtures/nta/make_fixtures.py +25 -0
- pdfexorcist-0.1.1/tests/fixtures/nta/manifest.csv +2 -0
- pdfexorcist-0.1.1/tests/fixtures/nta/neet_2026_top138_p1-2.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/nta_notice/expected.csv +616 -0
- pdfexorcist-0.1.1/tests/fixtures/nta_notice/make_fixtures.py +26 -0
- pdfexorcist-0.1.1/tests/fixtures/nta_notice/manifest.csv +2 -0
- pdfexorcist-0.1.1/tests/fixtures/nta_notice/nta_notice_2024_p2-6.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/pravah/expected.csv +99 -0
- pdfexorcist-0.1.1/tests/fixtures/pravah/make_fixtures.py +84 -0
- pdfexorcist-0.1.1/tests/fixtures/pravah/manifest.csv +2 -0
- pdfexorcist-0.1.1/tests/fixtures/pravah/pravah_2026-10-03_p5-8.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/srs/expected.csv +229 -0
- pdfexorcist-0.1.1/tests/fixtures/srs/manifest.csv +5 -0
- pdfexorcist-0.1.1/tests/fixtures/srs/srs_2010-14_uttrakhand.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/srs/srs_2019-23.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/synthetic/cleaning.pdf +0 -0
- pdfexorcist-0.1.1/tests/fixtures/synthetic/cleaning.png +0 -0
- pdfexorcist-0.1.1/tests/fixtures/synthetic/make_fixtures.py +37 -0
- pdfexorcist-0.1.1/tests/test_adsi_state_table.py +123 -0
- pdfexorcist-0.1.1/tests/test_bmc_lake_report.py +169 -0
- pdfexorcist-0.1.1/tests/test_cii_state_table.py +94 -0
- pdfexorcist-0.1.1/tests/test_cli.py +301 -0
- pdfexorcist-0.1.1/tests/test_crs_state_table.py +73 -0
- pdfexorcist-0.1.1/tests/test_examples_gallery.py +108 -0
- pdfexorcist-0.1.1/tests/test_fetch.py +218 -0
- pdfexorcist-0.1.1/tests/test_iips_district_projection.py +121 -0
- pdfexorcist-0.1.1/tests/test_jobs.py +121 -0
- pdfexorcist-0.1.1/tests/test_mccd_table4.py +77 -0
- pdfexorcist-0.1.1/tests/test_mccd_tables.py +117 -0
- pdfexorcist-0.1.1/tests/test_mohfw_state_projection.py +107 -0
- pdfexorcist-0.1.1/tests/test_nfhs5_examples.py +61 -0
- pdfexorcist-0.1.1/tests/test_nfhs5_factsheet.py +237 -0
- pdfexorcist-0.1.1/tests/test_nfhs6_examples.py +51 -0
- pdfexorcist-0.1.1/tests/test_nfhs6_factsheet.py +314 -0
- pdfexorcist-0.1.1/tests/test_nta_notice.py +88 -0
- pdfexorcist-0.1.1/tests/test_nta_toppers.py +153 -0
- pdfexorcist-0.1.1/tests/test_pdfexorcist.py +347 -0
- pdfexorcist-0.1.1/tests/test_pravah_dams.py +82 -0
- pdfexorcist-0.1.1/tests/test_recipe.py +348 -0
- pdfexorcist-0.1.1/tests/test_recipe_docs_examples.py +162 -0
- pdfexorcist-0.1.1/tests/test_show.py +264 -0
- pdfexorcist-0.1.1/tests/test_srs_life_table.py +102 -0
|
@@ -0,0 +1,17 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to pdfexorcist are listed here. The format follows
|
|
4
|
+
[Keep a Changelog](https://keepachangelog.com/en/1.1.0/), and versions follow
|
|
5
|
+
[PEP 440](https://peps.python.org/pep-0440/) (`1.2.0`, `1.2.0rc1`).
|
|
6
|
+
|
|
7
|
+
Add each change under [Unreleased] as you make it. The Prepare release
|
|
8
|
+
workflow moves those entries into a dated section.
|
|
9
|
+
|
|
10
|
+
## [0.1.1 - 4 Oct 2026]
|
|
11
|
+
|
|
12
|
+
### Added
|
|
13
|
+
|
|
14
|
+
Initial release:
|
|
15
|
+
- pdfexorcist also runs in the browser (`web/`) with pyodide! at <https://saketkc.github.io/pdfexorcist/>:
|
|
16
|
+
- pdfexorcist is a new package for extracting tables from pdfs (both text and scanned ones)
|
|
17
|
+
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Saket Choudhary
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,8 @@
|
|
|
1
|
+
# The sdist carries the full test suite (parsers, fixtures) and the example
|
|
2
|
+
# recipes, so it can be tested where it is built. The wheel holds only the
|
|
3
|
+
# package ([tool.setuptools] packages in pyproject.toml).
|
|
4
|
+
include CHANGELOG.md
|
|
5
|
+
graft tests
|
|
6
|
+
graft examples
|
|
7
|
+
global-exclude __pycache__ *.py[cod] .DS_Store
|
|
8
|
+
prune web
|
|
@@ -0,0 +1,583 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: pdfexorcist
|
|
3
|
+
Version: 0.1.1
|
|
4
|
+
Summary: Extract tables from PDFs, scans and photos by majority vote across independent engines
|
|
5
|
+
Author-email: Saket Choudhary <saketc@iitb.ac.in>
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/saketkc/pdfexorcist
|
|
8
|
+
Project-URL: Documentation, https://saketkc.github.io/pdfexorcist/cli/
|
|
9
|
+
Project-URL: Repository, https://github.com/saketkc/pdfexorcist
|
|
10
|
+
Project-URL: Issues, https://github.com/saketkc/pdfexorcist/issues
|
|
11
|
+
Project-URL: Changelog, https://saketkc.github.io/pdfexorcist/cli/changelog.html
|
|
12
|
+
Keywords: pdf,tables,extraction,ocr,scraping,majority vote
|
|
13
|
+
Classifier: Development Status :: 3 - Alpha
|
|
14
|
+
Classifier: Environment :: Console
|
|
15
|
+
Classifier: Intended Audience :: Science/Research
|
|
16
|
+
Classifier: Operating System :: OS Independent
|
|
17
|
+
Classifier: Programming Language :: Python :: 3
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
22
|
+
Classifier: Programming Language :: Python :: 3.14
|
|
23
|
+
Classifier: Topic :: Scientific/Engineering :: Information Analysis
|
|
24
|
+
Classifier: Topic :: Text Processing :: General
|
|
25
|
+
Classifier: Typing :: Typed
|
|
26
|
+
Requires-Python: >=3.10
|
|
27
|
+
Description-Content-Type: text/markdown
|
|
28
|
+
License-File: LICENSE
|
|
29
|
+
Requires-Dist: pandas
|
|
30
|
+
Requires-Dist: pdfplumber
|
|
31
|
+
Requires-Dist: pymupdf
|
|
32
|
+
Requires-Dist: pypdfium2
|
|
33
|
+
Requires-Dist: camelot-py
|
|
34
|
+
Requires-Dist: typer>=0.12
|
|
35
|
+
Requires-Dist: rich>=13
|
|
36
|
+
Requires-Dist: tomli; python_version < "3.11"
|
|
37
|
+
Provides-Extra: tabula
|
|
38
|
+
Requires-Dist: tabula-py; extra == "tabula"
|
|
39
|
+
Requires-Dist: jpype1; extra == "tabula"
|
|
40
|
+
Provides-Extra: chandra
|
|
41
|
+
Requires-Dist: chandra-ocr; extra == "chandra"
|
|
42
|
+
Requires-Dist: torch; extra == "chandra"
|
|
43
|
+
Requires-Dist: torchvision; extra == "chandra"
|
|
44
|
+
Requires-Dist: transformers; extra == "chandra"
|
|
45
|
+
Requires-Dist: accelerate; extra == "chandra"
|
|
46
|
+
Requires-Dist: pillow; extra == "chandra"
|
|
47
|
+
Provides-Extra: paddleocr
|
|
48
|
+
Requires-Dist: paddleocr>=3; extra == "paddleocr"
|
|
49
|
+
Requires-Dist: paddlepaddle; extra == "paddleocr"
|
|
50
|
+
Requires-Dist: pillow; extra == "paddleocr"
|
|
51
|
+
Provides-Extra: ocrmac
|
|
52
|
+
Requires-Dist: ocrmac; sys_platform == "darwin" and extra == "ocrmac"
|
|
53
|
+
Requires-Dist: pillow; extra == "ocrmac"
|
|
54
|
+
Provides-Extra: glmocr
|
|
55
|
+
Requires-Dist: mlx-vlm; (sys_platform == "darwin" and platform_machine == "arm64") and extra == "glmocr"
|
|
56
|
+
Requires-Dist: pillow; extra == "glmocr"
|
|
57
|
+
Provides-Extra: all
|
|
58
|
+
Requires-Dist: pdfexorcist[chandra,glmocr,ocrmac,paddleocr,tabula]; extra == "all"
|
|
59
|
+
Provides-Extra: ocr
|
|
60
|
+
Requires-Dist: pdfexorcist[chandra]; extra == "ocr"
|
|
61
|
+
Provides-Extra: paddle
|
|
62
|
+
Requires-Dist: pdfexorcist[paddleocr]; extra == "paddle"
|
|
63
|
+
Provides-Extra: mac
|
|
64
|
+
Requires-Dist: pdfexorcist[ocrmac]; extra == "mac"
|
|
65
|
+
Provides-Extra: mlx
|
|
66
|
+
Requires-Dist: pdfexorcist[glmocr]; extra == "mlx"
|
|
67
|
+
Dynamic: license-file
|
|
68
|
+
|
|
69
|
+
# pdfexorcist <img src="https://raw.githubusercontent.com/saketkc/pdfexorcist/main/docs/assets/logo/logo.png" align="right" width="140" alt="pdfexorcist logo">
|
|
70
|
+
|
|
71
|
+
[](https://pypi.org/project/pdfexorcist/)
|
|
72
|
+
[](https://pypi.org/project/pdfexorcist/)
|
|
73
|
+
[](https://github.com/saketkc/pdfexorcist/actions/workflows/ci.yml)
|
|
74
|
+
[](https://saketkc.github.io/pdfexorcist/cli/)
|
|
75
|
+
[](https://github.com/saketkc/pdfexorcist/blob/main/LICENSE)
|
|
76
|
+
|
|
77
|
+
`pdfexorcist` extracts tables from PDFs, scans and photos. It runs
|
|
78
|
+
severalenginges to read a cell and uses a majority vote to decide its value.
|
|
79
|
+
|
|
80
|
+
```bash
|
|
81
|
+
uvx pdfexorcist extract report.pdf # writes report.csv
|
|
82
|
+
```
|
|
83
|
+
|
|
84
|
+
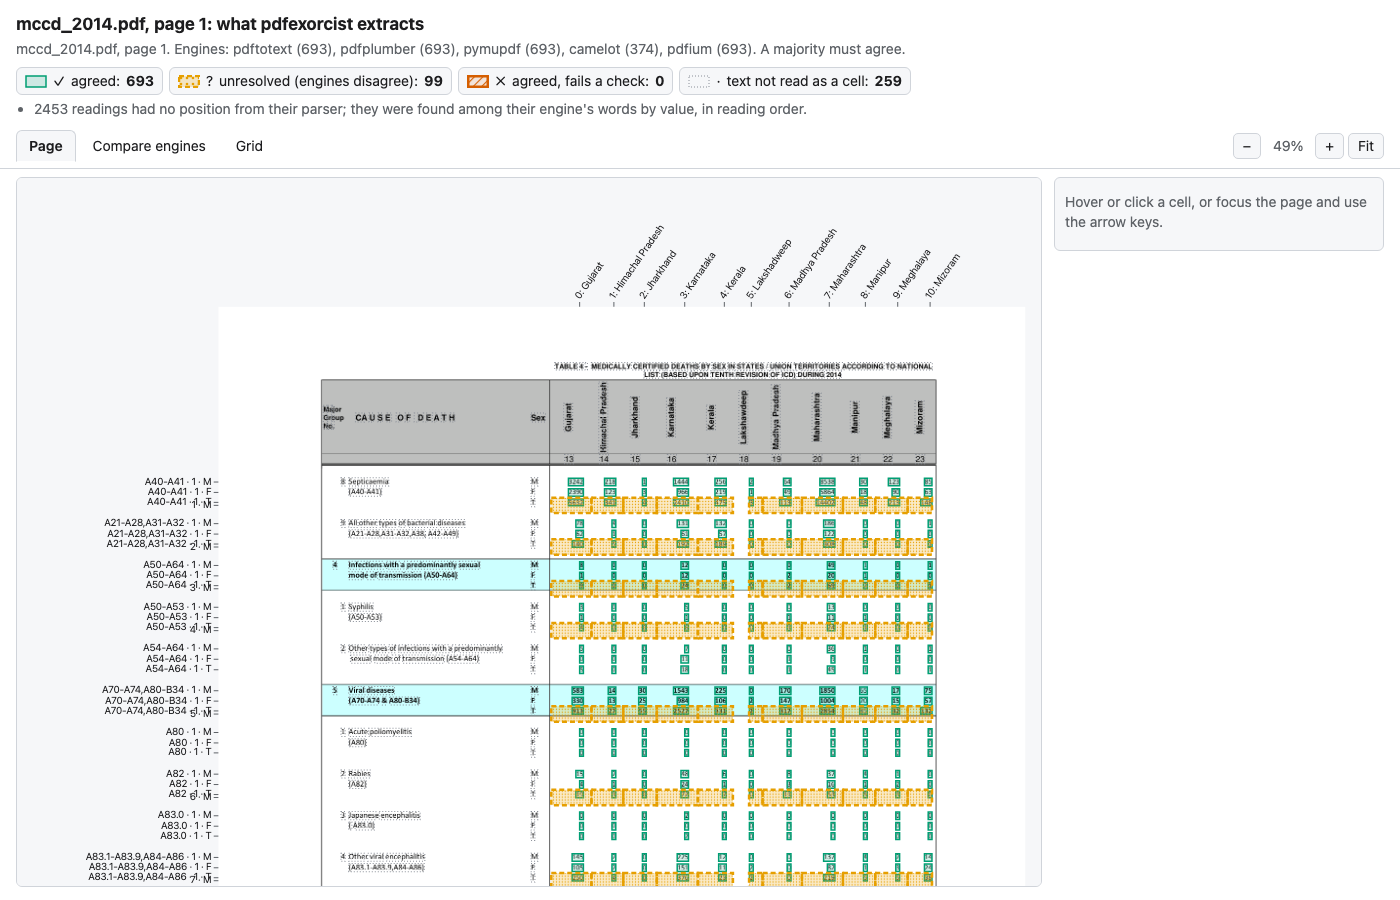
|
|
85
|
+
|
|
86
|
+
|
|
87
|
+
Try it in your browser, nothing to install: https://saketkc.github.io/pdfexorcist/
|
|
88
|
+
|
|
89
|
+
Docs: https://saketkc.github.io/pdfexorcist/cli/
|
|
90
|
+
|
|
91
|
+
|
|
92
|
+
## Install with uv
|
|
93
|
+
|
|
94
|
+
With [uv](https://docs.astral.sh/uv/) (`pip install` works the same):
|
|
95
|
+
|
|
96
|
+
```bash
|
|
97
|
+
curl -LsSf https://astral.sh/uv/install.sh | sh # macOS/Linux; Windows: winget install astral-sh.uv
|
|
98
|
+
uv tool install pdfexorcist # puts the pdfexorcist command on your PATH
|
|
99
|
+
uv tool install "pdfexorcist[all]" # with every engine (or pick: [paddleocr,ocrmac])
|
|
100
|
+
uvx pdfexorcist report.pdf # or run once without installing
|
|
101
|
+
uv add pdfexorcist # as a library in a uv project
|
|
102
|
+
```
|
|
103
|
+
|
|
104
|
+
`pdftotext` requires Poppler (`brew install poppler`, `apt install poppler-utils`).
|
|
105
|
+
|
|
106
|
+
|
|
107
|
+
## Examples
|
|
108
|
+
|
|
109
|
+
### NFHS-6 fact sheet
|
|
110
|
+
|
|
111
|
+
```bash
|
|
112
|
+
URL='https://www.nfhsiips.in/downloadFile.php?link=NFHS-6_StateFact_Chandigarh+%28UT%29__Chandigarh+Compendium.pdf&path=assets%2Fpublication%2FNFHS-6%2FStateFact%2FChandigarh+%28UT%29%2F'
|
|
113
|
+
|
|
114
|
+
pdfexorcist inspect "$URL" # which pages are text, and what to run
|
|
115
|
+
pdfexorcist extract "$URL" --pages 9-12 # generic parser
|
|
116
|
+
pdfexorcist extract "$URL" --recipe examples/nfhs6/district.toml # from a checkout
|
|
117
|
+
```
|
|
118
|
+
|
|
119
|
+
The recipe keys rows by printed indicator number and names the columns.
|
|
120
|
+
|
|
121
|
+
```
|
|
122
|
+
pdftotext 404 readings 0.0s
|
|
123
|
+
pdfplumber 404 readings 0.4s
|
|
124
|
+
pymupdf 404 readings 0.0s
|
|
125
|
+
camelot 384 readings 1.1s
|
|
126
|
+
pdfium 384 readings 0.1s
|
|
127
|
+
|
|
128
|
+
Agreed 404 100.0% of cells
|
|
129
|
+
Unresolved 0
|
|
130
|
+
Checks 2 rules all passed
|
|
131
|
+
|
|
132
|
+
Wrote NFHS-6_StateFact_Chandigarh (UT)__Chandigarh Compendium.csv (table layout, 101 rows).
|
|
133
|
+
```
|
|
134
|
+
|
|
135
|
+
```
|
|
136
|
+
geo,indicator_no,level,nfhs6_urban,nfhs6_rural,nfhs6_total,nfhs5_total
|
|
137
|
+
Chandigarh,1,state,6.1,6.1,6.1,5.9
|
|
138
|
+
Chandigarh,2,state,20.6,21.2,20.7,23.3
|
|
139
|
+
Chandigarh,3,state,11.0,8.6,10.9,10.9
|
|
140
|
+
```
|
|
141
|
+
|
|
142
|
+
`examples/nfhs5/state.toml` reads NFHS-5 fact sheets.
|
|
143
|
+
|
|
144
|
+
### A tweeted photo
|
|
145
|
+
|
|
146
|
+
BMC posts Mumbai lake levels as a photo:
|
|
147
|
+
|
|
148
|
+
```bash
|
|
149
|
+
pdfexorcist extract https://x.com/mybmc/status/2106224821864698086 \
|
|
150
|
+
--recipe examples/lake_photo/recipe.toml # needs OCR engines: [all]
|
|
151
|
+
```
|
|
152
|
+
|
|
153
|
+
```
|
|
154
|
+
Reading tweet_2106224821864698086_1.jpg with 4 engines (3 must agree)
|
|
155
|
+
Agreed 125 100.0% of cells
|
|
156
|
+
Unresolved 0
|
|
157
|
+
```
|
|
158
|
+
|
|
159
|
+
```
|
|
160
|
+
lake,year,level,rise_fall_24h,useful_content_ml,pct_useful_content,today_rain_mm,total_rain_mm
|
|
161
|
+
Upper Vaitarna,2026,603.27,0.0,219332.0,96.6,0.0,3896.0
|
|
162
|
+
Modak Sagar,2026,159.48,-0.25,99153.0,76.91,0.0,3260.0
|
|
163
|
+
Tansa,2026,128.2,-0.03,136822.0,94.31,0.0,2970.0
|
|
164
|
+
```
|
|
165
|
+
|
|
166
|
+
The recipe uses `min_unopposed = 2` for values two engines agree on when no
|
|
167
|
+
engine disagrees.
|
|
168
|
+
|
|
169
|
+
### Daily government report
|
|
170
|
+
|
|
171
|
+
Maharashtra's Water Resources Department publishes dam storage at one link:
|
|
172
|
+
|
|
173
|
+
```bash
|
|
174
|
+
pdfexorcist extract https://mwrdpravah.in/damsafety/control/pdfLatestReportEng \
|
|
175
|
+
--recipe examples/pravah_dams/recipe.toml -o pravah.csv
|
|
176
|
+
```
|
|
177
|
+
|
|
178
|
+
```
|
|
179
|
+
Agreed 1,380 100.0% of cells
|
|
180
|
+
Unresolved 0
|
|
181
|
+
Checks 2 rules all passed
|
|
182
|
+
```
|
|
183
|
+
|
|
184
|
+
```
|
|
185
|
+
dam,region,district,sr,date,time,dead,live_cap,gross_cap,live,gross,pct_live,pct_live_last_year
|
|
186
|
+
Bhatsa,Kokan,Thane,2,02/10/2026,07:26 AM,34.00,942.10,976.10,929.20,963.20,98.63,98.63
|
|
187
|
+
Modaksagar,Kokan,Thane,4,02/10/2026,07:33 AM,76.06,128.92,204.98,101.17,177.23,78.48,99.97
|
|
188
|
+
Tansa,Kokan,Thane,5,02/10/2026,07:35 AM,12.08,172.52,184.60,164.83,176.91,95.54,99.55
|
|
189
|
+
```
|
|
190
|
+
|
|
191
|
+
Details: [Pravah example](https://saketkc.github.io/pdfexorcist/cli/examples/pravah.html).
|
|
192
|
+
|
|
193
|
+
### Several tables in one PDF
|
|
194
|
+
|
|
195
|
+
One recipe reads the NEET (UG) 2024 result press release tables.
|
|
196
|
+
|
|
197
|
+
```bash
|
|
198
|
+
pdfexorcist extract https://www.nta.ac.in/Download/Notice/Notice_20240604195244.pdf \
|
|
199
|
+
--recipe examples/nta_notice/recipe.toml -o neet2024.csv
|
|
200
|
+
```
|
|
201
|
+
|
|
202
|
+
```
|
|
203
|
+
Agreed 615 100.0% of cells
|
|
204
|
+
Unresolved 0
|
|
205
|
+
Failed checks 6 agreed values that break a rule
|
|
206
|
+
x Table 1: registered >= categories: 6 cells
|
|
207
|
+
```
|
|
208
|
+
|
|
209
|
+
```
|
|
210
|
+
table,row,2019,2020,2021,2022,2023,2024
|
|
211
|
+
highlights,Number of Candidates registered,1519375,1597435,1614777,1872343,2087462,2406079
|
|
212
|
+
highlights,Un-Reserved,534072,475534,46-853,565964,592110,647260
|
|
213
|
+
language,English,1204968,1263273,1265520,1476024,1672914,1892355
|
|
214
|
+
|
|
215
|
+
table,row,2023_registered,2023_appeared,2023_qualified,2024_registered,2024_appeared,2024_qualified
|
|
216
|
+
gender,Female,1184513,1156618,655599,1376863,1334982,769222
|
|
217
|
+
state,Total,2087462,2038596,1145976,2406079,2333297,1316268
|
|
218
|
+
```
|
|
219
|
+
|
|
220
|
+
The recipe reports the printed `46-853` value as a failed check. Details:
|
|
221
|
+
[NEET 2024 example](https://saketkc.github.io/pdfexorcist/cli/examples/nta-notice.html).
|
|
222
|
+
|
|
223
|
+
### A scanned list
|
|
224
|
+
|
|
225
|
+
OCR reads the NTA NEET (UG) 2026 toppers scan.
|
|
226
|
+
|
|
227
|
+
```bash
|
|
228
|
+
pdfexorcist extract https://cdnbbsr.s3waas.gov.in/s37bc1ec1d9c3426357e69acd5bf320061/uploads/2026/07/20260716180970800.pdf \
|
|
229
|
+
--recipe examples/nta_toppers/recipe.toml --pages 1-6 -o neet_top138.csv
|
|
230
|
+
```
|
|
231
|
+
|
|
232
|
+
```
|
|
233
|
+
paddleocr 966 readings 253.2s
|
|
234
|
+
ocrmac 928 readings 7.5s
|
|
235
|
+
glmocr 845 readings 5.4s
|
|
236
|
+
|
|
237
|
+
Agreed 965 99.9% of cells
|
|
238
|
+
Unresolved 1 engines disagreed: left blank, not guessed
|
|
239
|
+
Checks 2 rules all passed
|
|
240
|
+
```
|
|
241
|
+
|
|
242
|
+
```
|
|
243
|
+
sr_no,rank,percentile,category,state
|
|
244
|
+
1,1,99.9999,General,PUNJAB
|
|
245
|
+
5,5,99.99965,OBC-NCL (Central List),MAHARASHTRA
|
|
246
|
+
44,44,99.9976999,General,CHANDIGARH (UT)
|
|
247
|
+
```
|
|
248
|
+
|
|
249
|
+
The checks require ranks to rise and percentiles to fall. Details:
|
|
250
|
+
[NEET toppers example](https://saketkc.github.io/pdfexorcist/cli/examples/nta.html).
|
|
251
|
+
|
|
252
|
+
`pdfexorcist.extract(url)` accepts file links and downloads into
|
|
253
|
+
`$PDFEXORCIST_CACHE` (default `~/.cache/pdfexorcist`).
|
|
254
|
+
|
|
255
|
+
## Command line
|
|
256
|
+
|
|
257
|
+
Install it, then run it on a PDF:
|
|
258
|
+
|
|
259
|
+
```bash
|
|
260
|
+
pip install pdfexorcist # the fifth text engine, pdftotext, also needs poppler: brew install poppler
|
|
261
|
+
pdfexorcist # a welcome screen with the common commands
|
|
262
|
+
```
|
|
263
|
+
|
|
264
|
+
Common commands:
|
|
265
|
+
|
|
266
|
+
```bash
|
|
267
|
+
pdfexorcist inspect report.pdf # text or scan? and which command to run
|
|
268
|
+
pdfexorcist extract report.pdf # writes report.csv next to the PDF
|
|
269
|
+
pdfexorcist engines # which engines are installed, and how to add more
|
|
270
|
+
```
|
|
271
|
+
|
|
272
|
+
`extract` writes an agreed-value grid and a `report.review.csv` file for
|
|
273
|
+
unresolved cells. It requires `--force` to overwrite an output file.
|
|
274
|
+
|
|
275
|
+
| Option | What it does |
|
|
276
|
+
|---|---|
|
|
277
|
+
| `--pages 3-5` | read only these pages (`"1-3,7"`, `"10-"`) |
|
|
278
|
+
| `--ocr` | also read the pixels with the installed OCR engines: use it for scans and photos (an image turns it on by itself) |
|
|
279
|
+
| `-o out.xlsx` | where to write; the ending picks the format (csv, xlsx, parquet, json); a name without one is a folder |
|
|
280
|
+
| `--layout cells` | one row per cell with every engine's reading |
|
|
281
|
+
| `--engines a,b,c` / `--min-agree 3` | choose the engines, and how many must agree |
|
|
282
|
+
| `--jobs 4` | use 4 worker processes: engines at once, and each engine's pages in chunks |
|
|
283
|
+
| `--json --quiet` | a machine-readable summary on stdout, for scripts |
|
|
284
|
+
|
|
285
|
+
`python -m pdfexorcist` also works. `pdfexorcist report.pdf` means
|
|
286
|
+
`pdfexorcist extract report.pdf`.
|
|
287
|
+
|
|
288
|
+
### Recipes: save the settings for a tricky table
|
|
289
|
+
|
|
290
|
+
A recipe is a TOML file with parsing and validation settings:
|
|
291
|
+
|
|
292
|
+
```bash
|
|
293
|
+
pdfexorcist recipe new report.pdf # asks; or script it with --yes and options
|
|
294
|
+
pdfexorcist recipe show report.recipe.toml
|
|
295
|
+
pdfexorcist recipe check report.recipe.toml
|
|
296
|
+
pdfexorcist extract next_year.pdf --recipe report.recipe.toml
|
|
297
|
+
```
|
|
298
|
+
|
|
299
|
+
Settings: [recipe reference](#recipe-reference).
|
|
300
|
+
|
|
301
|
+
### Inspect extracted cells
|
|
302
|
+
|
|
303
|
+
```bash
|
|
304
|
+
pdfexorcist show report.pdf --page 3 # writes report.p3.show.html
|
|
305
|
+
pdfexorcist show report.pdf -p 3 --recipe mccd.toml --open
|
|
306
|
+
pdfexorcist show photo.jpg --png # also a static annotated PNG
|
|
307
|
+
pdfexorcist compare report.pdf --page 3 # opens on the engines side by side
|
|
308
|
+
```
|
|
309
|
+
|
|
310
|
+
## Plug-in points
|
|
311
|
+
|
|
312
|
+
`pdfexorcist` has 3 steps that you can replace with a function that you write.
|
|
313
|
+
These steps are the plug-in points.
|
|
314
|
+
The default steps work for most tables.
|
|
315
|
+
Use a plug-in point only when a default step gives incorrect results for your PDF.
|
|
316
|
+
|
|
317
|
+
| Plug-in point | Use it when | Your function | Give it to `extract()` with |
|
|
318
|
+
|---|---|---|---|
|
|
319
|
+
| 1. Extractor | No installed engine can read your PDF. | Reads the PDF and yields the lines of each page. | `@register("name")` and `methods=[...]` |
|
|
320
|
+
| 2. Parser | The default parser gives incorrect keys for your table layout. | Changes the lines into rows with key columns and a `value`. | `parse=` and `key=` |
|
|
321
|
+
| 3. Validator | You know a rule that the values must obey, for example a total. | Gives `True` for each row that fails the rule. | `checks=[...]` |
|
|
322
|
+
|
|
323
|
+
### 1. Extractor
|
|
324
|
+
|
|
325
|
+
An extractor is one engine that reads the PDF.
|
|
326
|
+
The vote compares the values that all the engines read.
|
|
327
|
+
|
|
328
|
+
To add an extractor, do these steps:
|
|
329
|
+
|
|
330
|
+
1. Write a function that receives the path of the PDF.
|
|
331
|
+
2. For each page, yield the page number and a list of lines. The first page is page 1.
|
|
332
|
+
3. Make each line a list of `(x, text)` cells. `x` is the horizontal position of the cell.
|
|
333
|
+
4. Use one unit for `x` in one engine. You can use points or character columns.
|
|
334
|
+
5. Put `@register("my_ocr")` above the function.
|
|
335
|
+
6. Give the name of the engine in `methods=[...]`, or in `--engines` on the command line.
|
|
336
|
+
|
|
337
|
+
`@register` also adds the engine to the default engines.
|
|
338
|
+
To prevent this, write `@register("my_ocr", default=False)`.
|
|
339
|
+
|
|
340
|
+
If you know the box of each cell, yield `pdfexorcist.cells.BoxCell(x, "text", (x0, y0, x1, y1))`. Do not yield `(x, "text")`.
|
|
341
|
+
`pdfexorcist show` uses the box to mark the cell on the page.
|
|
342
|
+
|
|
343
|
+
Two engines that use the same OCR model make the same errors.
|
|
344
|
+
If your engine uses the same model as a different engine, put the two engines in one group of `families`.
|
|
345
|
+
The two engines then have one vote.
|
|
346
|
+
|
|
347
|
+
### 2. Parser
|
|
348
|
+
|
|
349
|
+
The parser gives a key to each value.
|
|
350
|
+
The vote compares only values that have the same key.
|
|
351
|
+
The default parser, `parse_rows`, uses the key `(page, row, col)`.
|
|
352
|
+
`row` is the row label, and `col` is the position of the value in the row.
|
|
353
|
+
|
|
354
|
+
To write a parser, do these steps:
|
|
355
|
+
|
|
356
|
+
1. Write a function that receives the pages from one engine. Each page is `(page_no, lines)`.
|
|
357
|
+
2. For each value, yield one `dict`. Put the key columns and a `"value"` item in the `dict`.
|
|
358
|
+
3. Give the function in `parse=`.
|
|
359
|
+
4. Give the names of the key columns in `key=`.
|
|
360
|
+
|
|
361
|
+
Make sure that a value gets the same key from all the engines.
|
|
362
|
+
If the key changes between engines, the engines cannot agree.
|
|
363
|
+
|
|
364
|
+
### 3. Validator
|
|
365
|
+
|
|
366
|
+
A validator is a rule that the values must obey.
|
|
367
|
+
The validators examine the values after the vote.
|
|
368
|
+
A validator does not remove rows.
|
|
369
|
+
It writes its name in the `failed` column of each row that fails.
|
|
370
|
+
|
|
371
|
+
To write a validator, do these steps:
|
|
372
|
+
|
|
373
|
+
1. Write a function that receives the result `DataFrame`.
|
|
374
|
+
2. Return a `bool` Series. `True` shows that the row fails the rule.
|
|
375
|
+
3. Put `@check("name of the rule")` above the function. The name goes into the `failed` column.
|
|
376
|
+
4. Give the function in `checks=[...]`.
|
|
377
|
+
|
|
378
|
+
For a rule of type "total = sum of the parts", use `total_check`. You do not have to write a function.
|
|
379
|
+
|
|
380
|
+
### Example
|
|
381
|
+
|
|
382
|
+
This example uses the 3 plug-in points together:
|
|
383
|
+
|
|
384
|
+
```python
|
|
385
|
+
from pdfexorcist import extract, register, check, total_check
|
|
386
|
+
|
|
387
|
+
|
|
388
|
+
# 1. extractor: an OCR engine for scanned pages
|
|
389
|
+
@register("my_ocr")
|
|
390
|
+
def my_ocr(pdf):
|
|
391
|
+
yield page_no, [[(x, "text"), ...], ...] # lines of (x, text) cells
|
|
392
|
+
|
|
393
|
+
|
|
394
|
+
# 2. parser: one key for each value in your layout
|
|
395
|
+
def my_parser(pages):
|
|
396
|
+
for page_no, lines in pages:
|
|
397
|
+
...
|
|
398
|
+
yield {
|
|
399
|
+
"page": page_no,
|
|
400
|
+
"cause": "A40-A41",
|
|
401
|
+
"sex": "M",
|
|
402
|
+
"col": 3,
|
|
403
|
+
"value": "51210",
|
|
404
|
+
}
|
|
405
|
+
|
|
406
|
+
|
|
407
|
+
# 3. validator: a rule that the values must obey
|
|
408
|
+
@check("septicaemia <= its chapter")
|
|
409
|
+
def septic(df):
|
|
410
|
+
return df.value.astype(float) > ... # True = row fails
|
|
411
|
+
|
|
412
|
+
|
|
413
|
+
res = extract(
|
|
414
|
+
"report.pdf",
|
|
415
|
+
parse=my_parser,
|
|
416
|
+
key=["page", "cause", "sex", "col"],
|
|
417
|
+
checks=[septic, total_check("sex", "T", ["M", "F"], by=["cause", "col"], op=">=")],
|
|
418
|
+
)
|
|
419
|
+
res[res.failed != ""] # values that failed a rule
|
|
420
|
+
```
|
|
421
|
+
|
|
422
|
+
## Scanned PDFs
|
|
423
|
+
|
|
424
|
+
`pdfexorcist` also handles PDFs whose text layer comes from OCR.
|
|
425
|
+
|
|
426
|
+
```python
|
|
427
|
+
extract(
|
|
428
|
+
"scan.pdf",
|
|
429
|
+
methods=["pdfplumber", "tesseract", "chandra"],
|
|
430
|
+
parse=parse_by_columns,
|
|
431
|
+
families={"tesseract": ["pdfplumber", "tesseract"]},
|
|
432
|
+
)
|
|
433
|
+
```
|
|
434
|
+
|
|
435
|
+
### Images (photos, screenshots, tweeted scans)
|
|
436
|
+
|
|
437
|
+
`extract()` accepts image files with OCR engines:
|
|
438
|
+
|
|
439
|
+
```python
|
|
440
|
+
extract(
|
|
441
|
+
"report.jpg",
|
|
442
|
+
methods=["chandra", "glmocr", "paddleocr", "ocrmac"],
|
|
443
|
+
min_agree=3,
|
|
444
|
+
parse=my_parser,
|
|
445
|
+
)
|
|
446
|
+
```
|
|
447
|
+
|
|
448
|
+
## Recipe reference
|
|
449
|
+
|
|
450
|
+
A recipe is a TOML file: `key = value` lines under `[section]` headers, text
|
|
451
|
+
in quotes, lists in brackets, `#` starts a comment. Every section is optional;
|
|
452
|
+
a missing setting keeps the default, as `pdfexorcist extract` does without a
|
|
453
|
+
recipe. `pdfexorcist recipe check FILE` names the line of any
|
|
454
|
+
mistake. Command-line options (`--pages`, `--engines`, ...) override the recipe.
|
|
455
|
+
Every setting is shown below; a real recipe uses a few (some exclude others, e.g.
|
|
456
|
+
`function` and `key` belong to `type = "custom"`).
|
|
457
|
+
|
|
458
|
+
```toml
|
|
459
|
+
name = "Crime in India: State/UT table"
|
|
460
|
+
description = "Cases by State/UT"
|
|
461
|
+
sample = "report.pdf" # the file it was made with (for your reference)
|
|
462
|
+
|
|
463
|
+
[pages] # default: every page
|
|
464
|
+
select = "3-5, 9" # page numbers; "21-" runs to the last page
|
|
465
|
+
start = 'TABLE\s*4\s*[-:.].*STATES' # or: from the first page whose text matches,
|
|
466
|
+
stop = 'TABLE\s*5' # up to (not including) the next page that matches
|
|
467
|
+
match = 'All India' # only pages whose text matches
|
|
468
|
+
fit_boxes = false # default true: widen a page to cover text drawn outside
|
|
469
|
+
# it; false when that text is another page's
|
|
470
|
+
|
|
471
|
+
[engines]
|
|
472
|
+
use = ["pdfplumber", "pymupdf", "pdfium"] # default: the installed default engines
|
|
473
|
+
ocr = false # true: add the installed OCR engines (when use is not given)
|
|
474
|
+
min_agree = 3 # default: a strict majority, at least 3 (2 with families or only OCR engines)
|
|
475
|
+
min_unopposed = 2 # also accept a value this many read when none read another (off)
|
|
476
|
+
families = { ocr_layer = ["pdfplumber", "pymupdf"] } # engines that are not independent vote once
|
|
477
|
+
|
|
478
|
+
[normalize] # rewrite every value before the vote
|
|
479
|
+
remove_commas = true # "1,020" -> "1020"
|
|
480
|
+
remove_footnote_marks = true # "490*" -> "490" (a lone "*" placeholder stays)
|
|
481
|
+
raised_dots = true # "65·3" -> "65.3"
|
|
482
|
+
minus_signs = true # "−4" -> "-4"
|
|
483
|
+
function = "clean.py:fix" # your own: value -> new value, or None to drop it
|
|
484
|
+
|
|
485
|
+
[parser]
|
|
486
|
+
type = "rows" # "rows": a label, then values in reading order (default)
|
|
487
|
+
# "columns": values placed by their position (scans, photos, blank cells)
|
|
488
|
+
# "custom": your own function (below)
|
|
489
|
+
min_values = 2 # skip lines with fewer values (titles, footnotes)
|
|
490
|
+
tolerance = 0.45 # "columns" only: how far from a column a value may sit
|
|
491
|
+
function = "my_parser.py:parse" # "custom": pages -> one dict per value
|
|
492
|
+
key = ["page", "code", "sex", "col"] # "custom": the columns that identify a cell
|
|
493
|
+
|
|
494
|
+
[[checks]] # one [[checks]] block per rule; repeat it for more
|
|
495
|
+
column = "label" # the column naming the total and its parts
|
|
496
|
+
rule = "TOTAL ALL INDIA = TOTAL STATE(S) + TOTAL UT(S)"
|
|
497
|
+
by = ["page", "col"] # checked separately within each of these
|
|
498
|
+
where = "col <= 2" # optional: only the cells this pandas query keeps
|
|
499
|
+
tolerance = 0.01 # optional: allowed relative gap (1%)
|
|
500
|
+
abs_tolerance = 0.15 # optional: allowed absolute gap (rounded numbers)
|
|
501
|
+
missing = "fail" # optional: a listed part that is missing fails (default "skip")
|
|
502
|
+
name = "States + UTs = India" # optional: the name written in the failed column
|
|
503
|
+
|
|
504
|
+
[[checks]] # the same rule as total and parts, for a total column:
|
|
505
|
+
column = "col"
|
|
506
|
+
total = 0 # the total's name (text or a number)
|
|
507
|
+
parts = [3, 6] # its parts; leave out for "every other"
|
|
508
|
+
op = "=" # =, >= or <= (default =); not used with rule
|
|
509
|
+
value = "value" # the column holding the numbers (default "value")
|
|
510
|
+
|
|
511
|
+
[[checks]]
|
|
512
|
+
function = "my_checks.py:rules" # your own check, a list of checks, or a function returning them
|
|
513
|
+
|
|
514
|
+
[postprocess]
|
|
515
|
+
function = "my_parser.py:name_states" # after the vote: (cells, pdf) -> cells, e.g. add a State column
|
|
516
|
+
|
|
517
|
+
[output]
|
|
518
|
+
layout = "table" # "table": a grid of agreed values (default); "cells": one row per cell
|
|
519
|
+
columns = "col" # the column spread across the grid (default "col")
|
|
520
|
+
rows = ["code", "sex"] # the columns that name a grid row (default: the rest of the key)
|
|
521
|
+
format = "csv" # csv, xlsx, parquet or json
|
|
522
|
+
```
|
|
523
|
+
|
|
524
|
+
**Rules.** `rule` is the total, then `=`, `>=` or `<=`, then its parts joined
|
|
525
|
+
by `+`: `"T = M + F"`, `"T >= M + F"` (the total may exceed its parts), or
|
|
526
|
+
`"All India = rest"` for every other row of the group. Values that break a
|
|
527
|
+
rule are kept, named in the `failed` column and listed for review, and the run
|
|
528
|
+
exits with code 1. A rule whose total or parts never appear is reported, so a
|
|
529
|
+
typo cannot pass as "all checks passed". The generic parsers name cells by
|
|
530
|
+
`page`, `row`, `col` (the value's place in its line, from 0) and `label` (the
|
|
531
|
+
line's text): a total row is `column = "label"`, a total column is
|
|
532
|
+
`column = "col"` with `by = ["page", "row"]`.
|
|
533
|
+
|
|
534
|
+
**Your own Python.** `function = "file.py:name"` loads `name` from a `.py`
|
|
535
|
+
file in the recipe's folder (or below it); that file may import its
|
|
536
|
+
neighbours. The functions have the library's signatures: a parser takes
|
|
537
|
+
`(page_no, lines)` pairs and yields dicts with the key columns and `value`
|
|
538
|
+
(see `examples/mccd/mccd_table4.py`); a check takes the agreed cells
|
|
539
|
+
and returns True where a row fails (see `checks.py`); a postprocess step takes
|
|
540
|
+
the cells and the PDF the engines read (only the recipe's pages, numbered from
|
|
541
|
+
1) and returns the cells. Page numbers in the output are the original ones. A
|
|
542
|
+
recipe that names a `.py` file runs that code: only use recipes you trust.
|
|
543
|
+
|
|
544
|
+
## Engines
|
|
545
|
+
|
|
546
|
+
| Engine | Reads | Default |
|
|
547
|
+
|--------|-------|---------|
|
|
548
|
+
| `pdftotext` (poppler) | text layer | yes |
|
|
549
|
+
| `pdfplumber` (pdfminer) | text layer | yes |
|
|
550
|
+
| `pymupdf` (MuPDF) | text layer | yes |
|
|
551
|
+
| `pdfium` (PDFium, Chrome's engine) | text layer | yes |
|
|
552
|
+
| `camelot` (stream tables) | text layer | yes |
|
|
553
|
+
| `tesseract` | rendered page (OCR, CPU) | opt-in |
|
|
554
|
+
| `chandra` (Chandra OCR 2 VLM, MPS/CUDA) | rendered page | opt-in, `pip install "pdfexorcist[chandra]"` |
|
|
555
|
+
| `paddleocr` (PP-OCR, Linux/macOS/Windows, CPU) | rendered page | opt-in, `pip install "pdfexorcist[paddleocr]"` |
|
|
556
|
+
| `ocrmac` (Apple Vision, macOS only) | rendered page | opt-in, `pip install "pdfexorcist[ocrmac]"` |
|
|
557
|
+
| `glmocr` (GLM-OCR 0.9B VLM via MLX, Apple Silicon; tables only) | rendered page | opt-in, `pip install "pdfexorcist[glmocr]"` |
|
|
558
|
+
|
|
559
|
+
|
|
560
|
+
|
|
561
|
+
## Development and releases
|
|
562
|
+
|
|
563
|
+
Use `uv pip install -e . --group dev`. See [CHANGELOG.md](https://github.com/saketkc/pdfexorcist/blob/main/CHANGELOG.md).
|
|
564
|
+
|
|
565
|
+
### From a checkout (local testing)
|
|
566
|
+
|
|
567
|
+
```bash
|
|
568
|
+
git clone https://github.com/saketkc/pdfexorcist && cd pdfexorcist
|
|
569
|
+
uv venv && source .venv/bin/activate # Windows: .venv\Scripts\activate
|
|
570
|
+
uv pip install -e . --group dev # editable install + pytest, ruff, mypy, parquet/xlsx writers
|
|
571
|
+
uv pip install -e ".[paddleocr,ocrmac]" # optional: OCR engines to test
|
|
572
|
+
|
|
573
|
+
pdfexorcist extract tests/fixtures/srs/srs_2019-23.pdf --recipe examples/srs_life_table/recipe.toml
|
|
574
|
+
uvx --from . pdfexorcist --help # or run the checkout without a venv
|
|
575
|
+
|
|
576
|
+
pytest -q tests # the suite; OCR tests are skipped
|
|
577
|
+
PDFEXORCIST_OCR_TESTS=1 pytest -q tests # also the slow OCR tests (needs the OCR extras)
|
|
578
|
+
ruff check pdfexorcist tests examples .github/scripts # lint, as CI runs it
|
|
579
|
+
ruff format --check pdfexorcist tests examples .github/scripts
|
|
580
|
+
mypy pdfexorcist
|
|
581
|
+
```
|
|
582
|
+
|
|
583
|
+
Each `examples/` recipe runs on a fixture in `tests/fixtures/`.
|