particlegan 0.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- particlegan-0.2.0/PKG-INFO +467 -0
- particlegan-0.2.0/README.md +444 -0
- particlegan-0.2.0/particlegan/__init__.py +17 -0
- particlegan-0.2.0/particlegan/conditioning.py +94 -0
- particlegan-0.2.0/particlegan/diffusion.py +97 -0
- particlegan-0.2.0/particlegan/gan_loss.py +189 -0
- particlegan-0.2.0/particlegan/grad_regularizers.py +366 -0
- particlegan-0.2.0/particlegan/particle_prior.py +246 -0
- particlegan-0.2.0/particlegan/recipes.py +140 -0
- particlegan-0.2.0/particlegan/vicreg_loss.py +62 -0
- particlegan-0.2.0/particlegan.egg-info/PKG-INFO +467 -0
- particlegan-0.2.0/particlegan.egg-info/SOURCES.txt +33 -0
- particlegan-0.2.0/particlegan.egg-info/dependency_links.txt +1 -0
- particlegan-0.2.0/particlegan.egg-info/requires.txt +19 -0
- particlegan-0.2.0/particlegan.egg-info/top_level.txt +1 -0
- particlegan-0.2.0/pyproject.toml +38 -0
- particlegan-0.2.0/setup.cfg +4 -0
- particlegan-0.2.0/tests/test_api_dogfood.py +74 -0
- particlegan-0.2.0/tests/test_api_integration.py +155 -0
- particlegan-0.2.0/tests/test_api_primitives.py +222 -0
- particlegan-0.2.0/tests/test_cifar_api.py +95 -0
- particlegan-0.2.0/tests/test_cifar_resume.py +75 -0
- particlegan-0.2.0/tests/test_cifar_speed.py +86 -0
- particlegan-0.2.0/tests/test_config.py +92 -0
- particlegan-0.2.0/tests/test_denoising.py +146 -0
- particlegan-0.2.0/tests/test_denoising_api.py +60 -0
- particlegan-0.2.0/tests/test_image_ddgan.py +79 -0
- particlegan-0.2.0/tests/test_image_moonshots.py +124 -0
- particlegan-0.2.0/tests/test_image_ncsnpp.py +45 -0
- particlegan-0.2.0/tests/test_prior_controls.py +166 -0
- particlegan-0.2.0/tests/test_regularizers.py +506 -0
- particlegan-0.2.0/tests/test_run_grid.py +368 -0
- particlegan-0.2.0/tests/test_sparse.py +198 -0
- particlegan-0.2.0/tests/test_toy_metrics.py +57 -0
- particlegan-0.2.0/tests/test_trajectory.py +167 -0
|
@@ -0,0 +1,467 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: particlegan
|
|
3
|
+
Version: 0.2.0
|
|
4
|
+
Summary: Composable PyTorch primitives for learnable particle priors, GANs, and DDGAN
|
|
5
|
+
Project-URL: Repository, https://github.com/255BITS/ParticleGAN
|
|
6
|
+
Project-URL: Documentation, https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md
|
|
7
|
+
Requires-Python: >=3.10
|
|
8
|
+
Description-Content-Type: text/markdown
|
|
9
|
+
Requires-Dist: torch<3,>=2.6
|
|
10
|
+
Provides-Extra: experiments
|
|
11
|
+
Requires-Dist: numpy<3,>=1.26; extra == "experiments"
|
|
12
|
+
Requires-Dist: matplotlib<4,>=3.8; extra == "experiments"
|
|
13
|
+
Requires-Dist: PyYAML<7,>=6; extra == "experiments"
|
|
14
|
+
Requires-Dist: POT<0.10,>=0.9.5; extra == "experiments"
|
|
15
|
+
Requires-Dist: tomli<3,>=2; python_version < "3.11" and extra == "experiments"
|
|
16
|
+
Provides-Extra: dev
|
|
17
|
+
Requires-Dist: pytest<10,>=8; extra == "dev"
|
|
18
|
+
Provides-Extra: images
|
|
19
|
+
Requires-Dist: torchvision<1,>=0.21; extra == "images"
|
|
20
|
+
Requires-Dist: torch-fidelity==0.3.0; extra == "images"
|
|
21
|
+
Requires-Dist: scipy<1.18,>=1.10; extra == "images"
|
|
22
|
+
Requires-Dist: tqdm<5,>=4.60; extra == "images"
|
|
23
|
+
|
|
24
|
+
# ParticleGAN
|
|
25
|
+
|
|
26
|
+
**Learnable particle priors and GAN building blocks for PyTorch.**
|
|
27
|
+
|
|
28
|
+
[API reference](https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md) · [Minimal GAN loop](https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md#a-minimal-training-loop) ·
|
|
29
|
+
[Minimal DDGAN + UCD loop](https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md#a-minimal-ddgan--ucd-loop)
|
|
30
|
+
|
|
31
|
+
[](https://github.com/255BITS/ParticleGAN/actions/workflows/tests.yml)
|
|
32
|
+
|
|
33
|
+
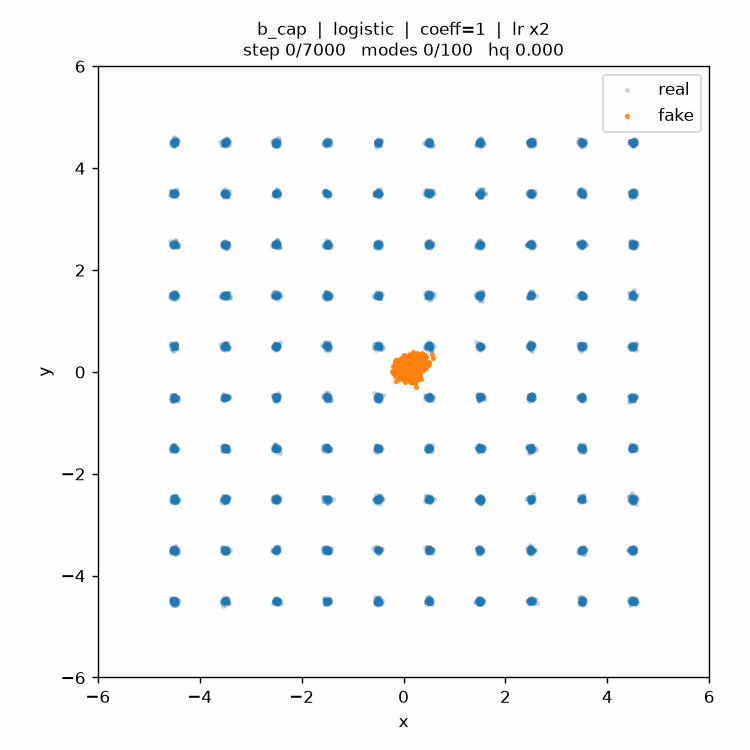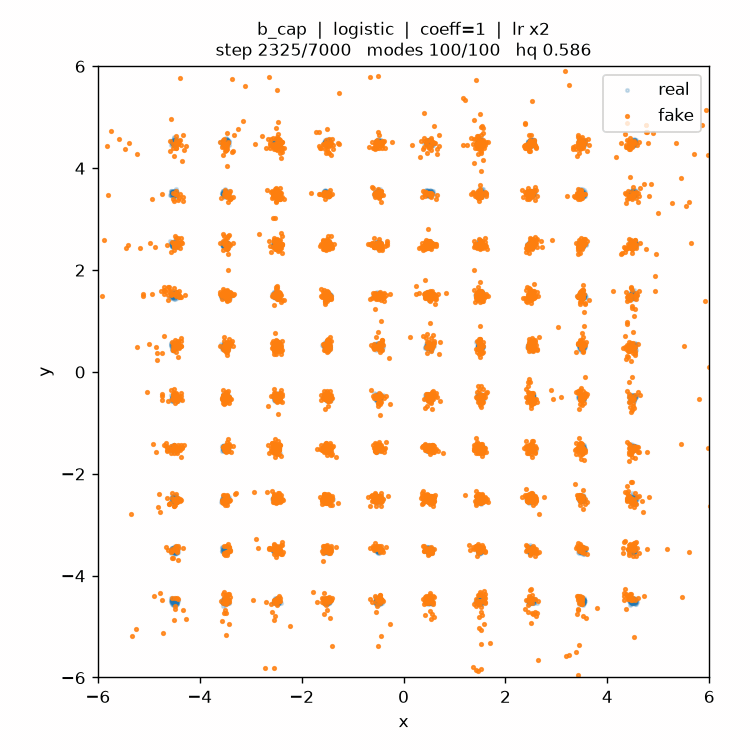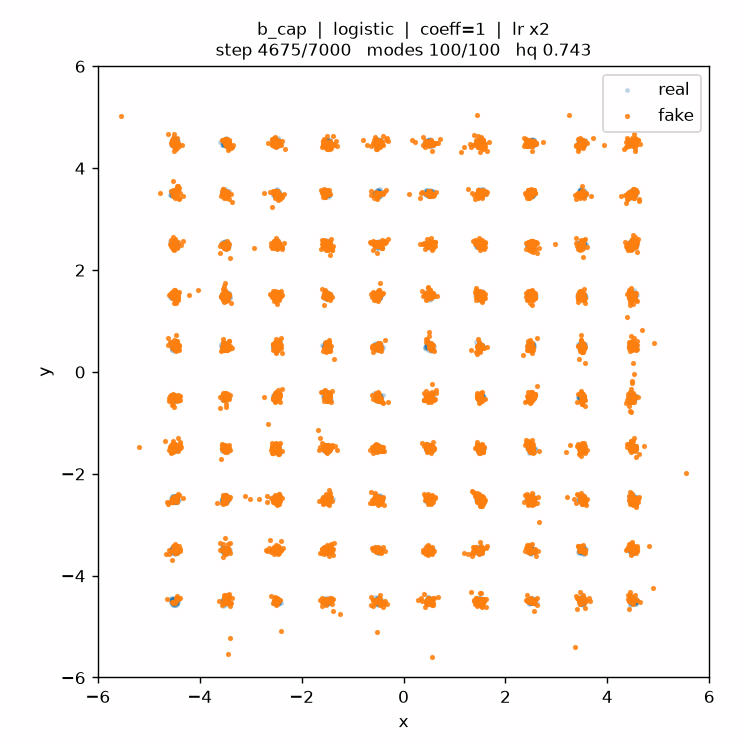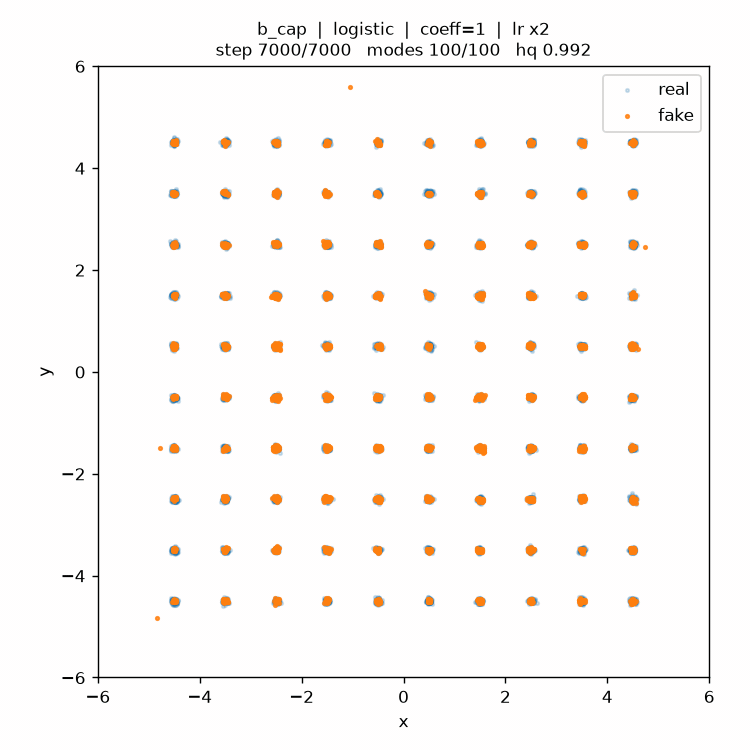
|
|
34
|
+
|
|
35
|
+
## Installation
|
|
36
|
+
|
|
37
|
+
Requires Python 3.10+ and PyTorch. Install from PyPI:
|
|
38
|
+
|
|
39
|
+
```bash
|
|
40
|
+
python -m pip install particlegan
|
|
41
|
+
```
|
|
42
|
+
|
|
43
|
+
For development and the repository's research experiments:
|
|
44
|
+
|
|
45
|
+
```bash
|
|
46
|
+
git clone https://github.com/255BITS/ParticleGAN.git
|
|
47
|
+
cd ParticleGAN
|
|
48
|
+
python -m pip install -e '.[experiments,dev]'
|
|
49
|
+
# Image experiments also need the images extra:
|
|
50
|
+
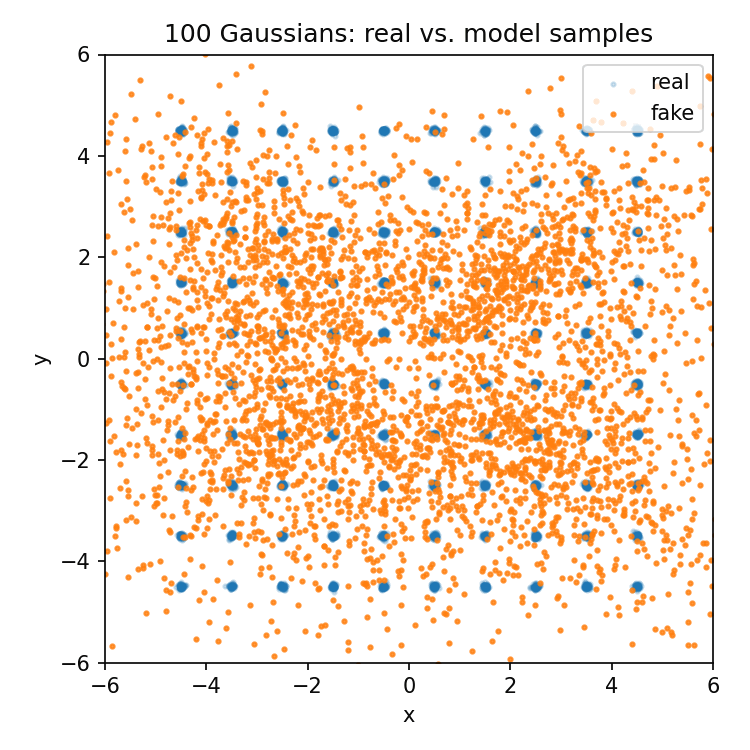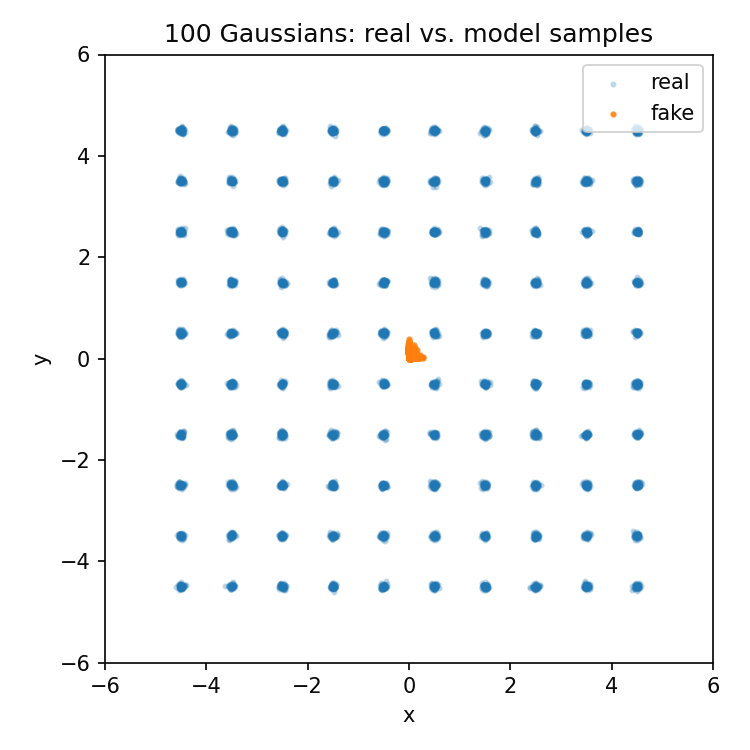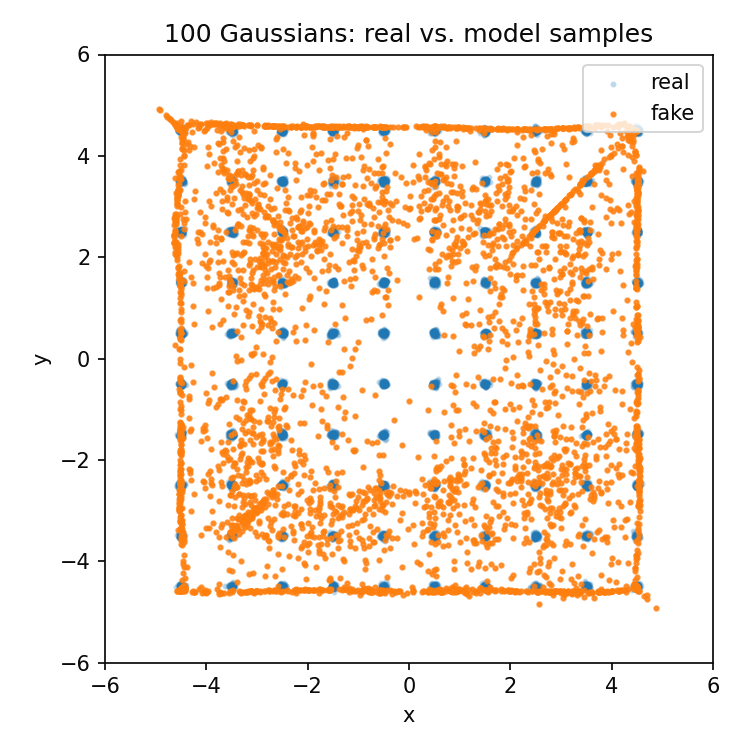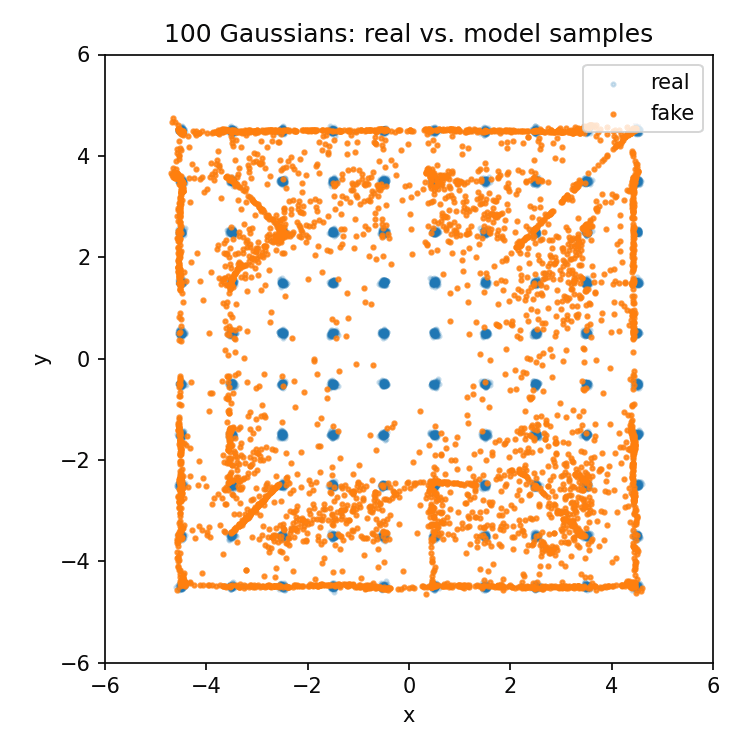
# python -m pip install -e '.[experiments,images,dev]'
|
|
51
|
+
```
|
|
52
|
+
|
|
53
|
+
CI tests Python 3.10–3.12 and builds installable distributions. See
|
|
54
|
+
[CI and PyPI releases](https://github.com/255BITS/ParticleGAN/blob/master/docs/releasing.md) for the automated publishing setup.
|
|
55
|
+
|
|
56
|
+
## Use in your PyTorch project
|
|
57
|
+
|
|
58
|
+
Use individual components in your existing loop. You own the networks, data,
|
|
59
|
+
optimizers, backward calls, devices, logging, and checkpoints. No trainer is
|
|
60
|
+
required, and the loss helpers never call backward or step an optimizer.
|
|
61
|
+
|
|
62
|
+
See the [minimal GAN loop](https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md#a-minimal-training-loop),
|
|
63
|
+
[minimal DDGAN + UCD loop](https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md#a-minimal-ddgan--ucd-loop), and
|
|
64
|
+
[API reference](https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md#reference-index) for complete examples and contracts.
|
|
65
|
+
|
|
66
|
+
Our examples and experiment trainers consume these same public primitives and
|
|
67
|
+
recipe factories. See the [migration and compatibility checks](https://github.com/255BITS/ParticleGAN/blob/master/reports/api-dogfood.md)
|
|
68
|
+
for existing-config GPU smoke tests and checkpoint comparisons.
|
|
69
|
+
|
|
70
|
+
```python
|
|
71
|
+
from particlegan import ParticlePrior, GANLoss, GradientPenalty, ParticleRegularizer
|
|
72
|
+
|
|
73
|
+
prior = ParticlePrior().to(device) # 20,000 learnable particles, z_dim=4
|
|
74
|
+
adversarial = GANLoss() # relativistic-paired logistic loss
|
|
75
|
+
penalty = GradientPenalty() # exact L2 cap penalty, weight=1, cap=1
|
|
76
|
+
spread = ParticleRegularizer() # variance/covariance regularization, weight=1
|
|
77
|
+
|
|
78
|
+
# Customize with ordinary keyword arguments:
|
|
79
|
+
prior = ParticlePrior(num_particles=4096, z_dim=16).to(device)
|
|
80
|
+
adversarial = GANLoss(loss_type="hinge", mode="vanilla")
|
|
81
|
+
```
|
|
82
|
+
|
|
83
|
+
`prior.sample(batch_size)` returns `(z, indices)`, with `z` shaped `[B, z_dim]`.
|
|
84
|
+
Include `prior.parameters()` in your generator optimizer to learn the particles.
|
|
85
|
+
Use `GaussianPrior(z_dim=16)` for fresh Gaussian samples with the same sampling
|
|
86
|
+
interface; its indices are `None` and it needs no particle regularization.
|
|
87
|
+
|
|
88
|
+
### Add a loss to an existing pipeline
|
|
89
|
+
|
|
90
|
+
Components are independent. For example, add a critic penalty or a particle
|
|
91
|
+
spread term to losses your pipeline already computes:
|
|
92
|
+
|
|
93
|
+
```python
|
|
94
|
+
# In your discriminator update:
|
|
95
|
+
d_loss = existing_d_loss + penalty(D, real, fake.detach(), step=step)
|
|
96
|
+
|
|
97
|
+
# In your generator/prior update, when sampled particle indices are available:
|
|
98
|
+
g_loss = existing_g_loss + spread(prior(indices.unique()))
|
|
99
|
+
# Your code calls backward() and optimizer.step().
|
|
100
|
+
```
|
|
101
|
+
|
|
102
|
+
To use the adversarial objective itself, call
|
|
103
|
+
`adversarial.d_loss(D(real), D(fake.detach()))` for D and
|
|
104
|
+
`adversarial.g_loss(D(fake), D(real).detach())` for G. Freeze D's parameters
|
|
105
|
+
for the G update while retaining gradients through `D(fake)`.
|
|
106
|
+
|
|
107
|
+
### Selected defaults, with easy overrides
|
|
108
|
+
|
|
109
|
+
```python
|
|
110
|
+
from particlegan import get_recipe
|
|
111
|
+
|
|
112
|
+
recipe = get_recipe() # Recommended GAN defaults.
|
|
113
|
+
recipe = recipe.replace(z_dim=16, num_particles=4096, lr=3e-4)
|
|
114
|
+
prior = recipe.make_prior().to(device)
|
|
115
|
+
adversarial = recipe.make_loss()
|
|
116
|
+
penalty = recipe.make_gradient_penalty()
|
|
117
|
+
spread = recipe.make_prior_regularizer()
|
|
118
|
+
opt_g, opt_d = recipe.make_optimizers(G, D, prior) # after moving modules to device
|
|
119
|
+
print(recipe.to_dict()) # inspect every resolved value
|
|
120
|
+
```
|
|
121
|
+
|
|
122
|
+
The optional optimizer helper returns ordinary Adam optimizers. The G optimizer
|
|
123
|
+
has separate generator and particle groups. You can build your own optimizers
|
|
124
|
+
using the recipe's fields instead. Recipes are immutable; `.replace(...)`
|
|
125
|
+
returns a new one. Unknown options raise errors.
|
|
126
|
+
|
|
127
|
+
| Default | `get_recipe()` / `gan` | `ddgan` |
|
|
128
|
+
| --- | --- | --- |
|
|
129
|
+
| Generation | One-shot GAN | Four-step DDGAN |
|
|
130
|
+
| Prior | 20,000 learned particles, dimension 4 | Same |
|
|
131
|
+
| GAN loss / critic penalty | Rp logistic / exact L2 cap, weight 1 | Same |
|
|
132
|
+
| Particle regularizer | VICReg, weight 1, unique sampled rows | Same |
|
|
133
|
+
| Adam learning rates: G / D / prior | 0.0006 / 0.0009 / 0.006 | Same |
|
|
134
|
+
| Adam betas / EMA decay | (0, 0.999) / 0.995 | Same |
|
|
135
|
+
| Schedule | Hold 60%, cosine to 5% | Same |
|
|
136
|
+
| Batch size / training updates | 256 / 7,000 | 256 / 56,000 |
|
|
137
|
+
| Conditioning | Unconditional | Class-only UCD, 4 classes, CE weight 0.02 |
|
|
138
|
+
|
|
139
|
+
These defaults come from the selected 100-Gaussians and denoising experiments.
|
|
140
|
+
Networks remain application choices: the reference toy benchmarks use MLPs and
|
|
141
|
+
two Fourier frequencies in D. Changing the architecture or dataset changes the
|
|
142
|
+
experiment; the recipe alone does not establish convergence on a new problem.
|
|
143
|
+
|
|
144
|
+
[The executable PyTorch loop](https://github.com/255BITS/ParticleGAN/blob/master/examples/pytorch_loop.py) shows optimizer setup,
|
|
145
|
+
D freezing/restoration, unique-particle regularization, the learning-rate
|
|
146
|
+
schedule, and EMA for G and the prior. It uses small MLPs and synthetic data,
|
|
147
|
+
requires no research dependencies, and writes one flushed JSON record per log
|
|
148
|
+
line:
|
|
149
|
+
|
|
150
|
+
```bash
|
|
151
|
+
mkdir -p runs/api
|
|
152
|
+
python -u examples/pytorch_loop.py --steps 5 --batch-size 16 > runs/api/smoke.log 2>&1
|
|
153
|
+
# In another terminal while a longer run is active:
|
|
154
|
+
tail -f runs/api/smoke.log
|
|
155
|
+
```
|
|
156
|
+
|
|
157
|
+
### TOML is just constructor arguments
|
|
158
|
+
|
|
159
|
+
Load TOML with your preferred parser and unpack a section into a constructor.
|
|
160
|
+
The library does not require a parser or configuration framework:
|
|
161
|
+
|
|
162
|
+
```toml
|
|
163
|
+
[particlegan]
|
|
164
|
+
# Omit name for GAN defaults; use name = "ddgan" for DDGAN + UCD.
|
|
165
|
+
z_dim = 16
|
|
166
|
+
num_particles = 4096
|
|
167
|
+
lr = 0.0003
|
|
168
|
+
|
|
169
|
+
# Alternatively, configure independent primitives:
|
|
170
|
+
[prior]
|
|
171
|
+
z_dim = 16
|
|
172
|
+
num_particles = 4096
|
|
173
|
+
|
|
174
|
+
[loss]
|
|
175
|
+
loss_type = "logistic"
|
|
176
|
+
mode = "rp"
|
|
177
|
+
```
|
|
178
|
+
|
|
179
|
+
```python
|
|
180
|
+
try:
|
|
181
|
+
import tomllib # Python 3.11+
|
|
182
|
+
except ModuleNotFoundError:
|
|
183
|
+
import tomli as tomllib # Python 3.10: pip install tomli
|
|
184
|
+
|
|
185
|
+
with open("model.toml", "rb") as f:
|
|
186
|
+
config = tomllib.load(f)
|
|
187
|
+
|
|
188
|
+
recipe = get_recipe(**config["particlegan"])
|
|
189
|
+
# Or construct components directly:
|
|
190
|
+
prior = ParticlePrior(**config["prior"])
|
|
191
|
+
adversarial = GANLoss(**config["loss"])
|
|
192
|
+
# Explicit code overrides are ordinary dictionary merges:
|
|
193
|
+
recipe = get_recipe(**{**config["particlegan"], "lr": 1e-4})
|
|
194
|
+
```
|
|
195
|
+
|
|
196
|
+
`toml.load(...)` dictionaries work too. Choose either recipe-owned values or
|
|
197
|
+
per-component sections for your application. Try the supplied configuration:
|
|
198
|
+
|
|
199
|
+
```bash
|
|
200
|
+
python -u examples/pytorch_loop.py --config examples/api.toml --steps 5
|
|
201
|
+
```
|
|
202
|
+
|
|
203
|
+
The primary research trainers also accept TOML or YAML using their existing flat
|
|
204
|
+
experiment schema (separate from the constructor sections above):
|
|
205
|
+
|
|
206
|
+
```bash
|
|
207
|
+
python experiments/train_100gaussians.py --config configs/100gaussians/default.toml
|
|
208
|
+
python experiments/train_denoising.py --config configs/denoising/default.toml
|
|
209
|
+
```
|
|
210
|
+
|
|
211
|
+
Running `python experiments/train_denoising.py` with no arguments loads
|
|
212
|
+
`configs/denoising/default.toml`. Install the `experiments` extra for these
|
|
213
|
+
trainers; the denoising trainer requires CUDA. See the
|
|
214
|
+
[experiment runner guide](https://github.com/255BITS/ParticleGAN/blob/master/docs/experiment-runner.md) for grids and recorded
|
|
215
|
+
effective configurations.
|
|
216
|
+
|
|
217
|
+
### DDGAN and UCD compose independently
|
|
218
|
+
|
|
219
|
+
`DDGAN` supplies Gaussian forward pairs and reverse transitions. `UCD` selects
|
|
220
|
+
class scores from a logit network; it does not inject class labels into that
|
|
221
|
+
network. Neither owns your training loop. Here is the D-loss portion of a
|
|
222
|
+
conditional denoising pipeline, with caller-defined `G`, `logit_network`, data,
|
|
223
|
+
labels, and device:
|
|
224
|
+
|
|
225
|
+
```python
|
|
226
|
+
import torch
|
|
227
|
+
from particlegan import DDGAN, UCD, ucd_loss
|
|
228
|
+
|
|
229
|
+
recipe = get_recipe("ddgan", num_classes=4)
|
|
230
|
+
prior = recipe.make_prior().to(device)
|
|
231
|
+
adversarial = recipe.make_loss()
|
|
232
|
+
penalty = recipe.make_gradient_penalty()
|
|
233
|
+
process = DDGAN(alpha_bar=recipe.alpha_bar).to(device)
|
|
234
|
+
critic = UCD(logit_network, num_classes=recipe.num_classes).to(device)
|
|
235
|
+
|
|
236
|
+
t = torch.randint(1, process.steps + 1, (len(real),), device=device)
|
|
237
|
+
rng = torch.Generator(device=device).manual_seed(123)
|
|
238
|
+
x_prev, xt = process.forward_pair(real, t, rng)
|
|
239
|
+
z, indices = prior.sample(len(real), generator=rng)
|
|
240
|
+
x0_hat = G(z, labels, xt=xt, t=t) # G predicts clean data
|
|
241
|
+
fake_prev = process.reverse(x0_hat, xt, t, torch.randn_like(xt))
|
|
242
|
+
real_score, real_logits = critic(x_prev, labels, xt=xt, t=t)
|
|
243
|
+
fake_score, fake_logits = critic(fake_prev.detach(), labels, xt=xt, t=t)
|
|
244
|
+
d_loss = adversarial.d_loss(real_score, fake_score)
|
|
245
|
+
d_loss += ucd_loss(real_logits, fake_logits, critic.ucd_labels(labels, t),
|
|
246
|
+
weight=recipe.ucd_weight)
|
|
247
|
+
d_loss += penalty(lambda x: critic(x, labels, xt=xt, t=t)[0],
|
|
248
|
+
x_prev, fake_prev.detach())
|
|
249
|
+
```
|
|
250
|
+
|
|
251
|
+
For class-only UCD, the network receives `network(x, xt=xt, t=t)` and returns
|
|
252
|
+
`[B, C]` logits. Labels and times are `[B]` long tensors; times run from 1 to T.
|
|
253
|
+
For joint time/class heads, use `UCD(network, num_classes=C,
|
|
254
|
+
target="time_class", num_steps=T)`; the network receives `network(x, xt=xt)`
|
|
255
|
+
and returns `[B, T*C]` logits. UCD also works without diffusion as
|
|
256
|
+
`critic(x, labels)` over a network that accepts only `x`.
|
|
257
|
+
|
|
258
|
+
Recompute critic scores after its update, freeze critic parameters, and keep
|
|
259
|
+
`fake_prev` attached for the G/prior adversarial loss. Class CE belongs to D.
|
|
260
|
+
The default schedule is `(1, .9, .5, .05, .0001)`; corruption and reverse noise
|
|
261
|
+
are Gaussian and separate from learned latent particles. See
|
|
262
|
+
[the API reference](https://github.com/255BITS/ParticleGAN/blob/master/docs/api.md#ddgan) for the full composition rules.
|
|
263
|
+
|
|
264
|
+
### Teacher/student pipelines
|
|
265
|
+
|
|
266
|
+
A teacher can produce the target batch in your existing training pipeline.
|
|
267
|
+
Use matching conditioning for a paired supervised loss:
|
|
268
|
+
|
|
269
|
+
```python
|
|
270
|
+
teacher.eval()
|
|
271
|
+
with torch.no_grad():
|
|
272
|
+
targets = teacher(inputs)
|
|
273
|
+
z, indices = prior.sample(len(inputs))
|
|
274
|
+
fake = student(z, inputs)
|
|
275
|
+
# Update your critic using targets as reals and fake.detach() as fakes.
|
|
276
|
+
# Then freeze the updated critic's parameters for this student/prior loss:
|
|
277
|
+
student_loss = supervised_weight * supervised_loss(fake, targets)
|
|
278
|
+
student_loss += adversarial_weight * adversarial.g_loss(
|
|
279
|
+
D(fake), D(targets).detach(),
|
|
280
|
+
)
|
|
281
|
+
student_loss += spread(prior(indices.unique()))
|
|
282
|
+
# Your student/prior optimizer performs backward and step; restore D afterward.
|
|
283
|
+
```
|
|
284
|
+
|
|
285
|
+
The teacher, supervised objective, loss weights, and update order belong to your
|
|
286
|
+
application. You can also use only the prior or regularizers without an
|
|
287
|
+
adversarial objective.
|
|
288
|
+
|
|
289
|
+
### Inference without a critic or optimizer
|
|
290
|
+
|
|
291
|
+
Save G and the learned prior, ideally their EMA states. Keep the architecture
|
|
292
|
+
configuration needed to reconstruct G alongside the checkpoint:
|
|
293
|
+
|
|
294
|
+
```python
|
|
295
|
+
torch.save({"generator": G.state_dict(), "prior": prior.state_dict()}, "model.pt")
|
|
296
|
+
|
|
297
|
+
# In another application, reconstruct your generator architecture and prior:
|
|
298
|
+
G = build_generator(z_dim=16).to(device)
|
|
299
|
+
prior = ParticlePrior(num_particles=4096, z_dim=16).to(device)
|
|
300
|
+
state = torch.load("model.pt", map_location=device, weights_only=True)
|
|
301
|
+
G.load_state_dict(state["generator"])
|
|
302
|
+
prior.load_state_dict(state["prior"])
|
|
303
|
+
G.eval()
|
|
304
|
+
prior.eval()
|
|
305
|
+
with torch.inference_mode():
|
|
306
|
+
z, _ = prior.sample(64)
|
|
307
|
+
samples = G(z)
|
|
308
|
+
```
|
|
309
|
+
|
|
310
|
+
Use the same particle count and latent dimension as training. Conditional G
|
|
311
|
+
also receives labels or inputs. DDGAN inference additionally reconstructs its
|
|
312
|
+
schedule (or loads its `state_dict`) and starts from Gaussian `x_T`; loop over
|
|
313
|
+
`T, ..., 1`, drawing fresh latent samples and reverse noise at each step:
|
|
314
|
+
`x = process.reverse(G(z, labels, xt=x, t=t), x, t, noise)`. There is no critic
|
|
315
|
+
or optimizer in inference.
|
|
316
|
+
|
|
317
|
+
|
|
318
|
+
## The Problem
|
|
319
|
+
|
|
320
|
+
GANs can suffer from **mode collapse**: the generator produces only a subset of the data distribution. This project explores whether optimizing a finite latent particle cloud alongside the generator improves coverage on small, highly multimodal benchmarks.
|
|
321
|
+
|
|
322
|
+
## The Insight
|
|
323
|
+
|
|
324
|
+
**What if the prior could move too?**
|
|
325
|
+
|
|
326
|
+
We introduce learnable "particles" in latent space. Both the generator and these latent vectors are optimized during training. The experiments examine how that extra flexibility interacts with discriminator regularization, optimizer dynamics, and sample quality. The results are empirical observations on these benchmarks, not a guarantee against collapse.
|
|
327
|
+
|
|
328
|
+
### Historical Gaussian example
|
|
329
|
+
|
|
330
|
+
|
|
331
|
+
|
|
332
|
+
*Historical visualization from the older Gaussian example. Its architecture and training recipe differ from the particle example above, so these GIFs are not a matched prior comparison.*
|
|
333
|
+
|
|
334
|
+
## Evidence and controls
|
|
335
|
+
|
|
336
|
+
The historical [regularizer study](https://github.com/255BITS/ParticleGAN/blob/master/FINDINGS.md) compares discriminator penalties within the particle model. It does not establish that a fixed Gaussian prior necessarily collapses. The current examples share one training loop and matched defaults; the only training change for the Gaussian controls is removing the learned prior and its regularizer.
|
|
337
|
+
|
|
338
|
+
For a reproducible three-way comparison, run:
|
|
339
|
+
|
|
340
|
+
```bash
|
|
341
|
+
python experiments/compare_priors.py --study-dir runs/prior_comparison --run --device cuda:0
|
|
342
|
+
```
|
|
343
|
+
|
|
344
|
+
This runs learned particles, a frozen Gaussian table, and fresh Gaussian noise on paired seeds 23001–23003. It records configs, source revision, final samples, coverage, transport distances, and per-mode radial and covariance shape diagnostics. See [prior controls and interpretation](https://github.com/255BITS/ParticleGAN/blob/master/docs/prior-controls.md) and [reproducing the project](https://github.com/255BITS/ParticleGAN/blob/master/docs/reproducing.md).
|
|
345
|
+
|
|
346
|
+
The completed [nine-run matched comparison](https://github.com/255BITS/ParticleGAN/blob/master/reports/prior-comparison/README.md) reached 100/100 high-quality modes on every learned-prior seed, with a mean high-quality fraction of 98.6%, versus 8.1% for the frozen table and 6.4% for fresh Gaussian noise. This establishes a concentration advantage under this recipe. The report also shows remaining tail and covariance distortion, finite output support, and transport-metric tradeoffs; it does not establish complete Gaussian calibration or a general guarantee against collapse.
|
|
347
|
+
|
|
348
|
+
## How It Works
|
|
349
|
+
|
|
350
|
+
1. **Particle Prior**: Instead of sampling z ~ N(0, I), we maintain a set of learnable latent vectors (particles). During training, we sample from this discrete set.
|
|
351
|
+
|
|
352
|
+
2. **Joint Optimization**: Particles are optimized alongside G and D. Their positions can adapt to the data modes.
|
|
353
|
+
|
|
354
|
+
3. **VICReg Regularization**: We apply variance-covariance regularization to prevent particles from collapsing to a single point, while allowing arbitrary topology (clusters, gaps, etc.).
|
|
355
|
+
|
|
356
|
+
## Examples
|
|
357
|
+
|
|
358
|
+
### Five Modes (Text Generation)
|
|
359
|
+
|
|
360
|
+
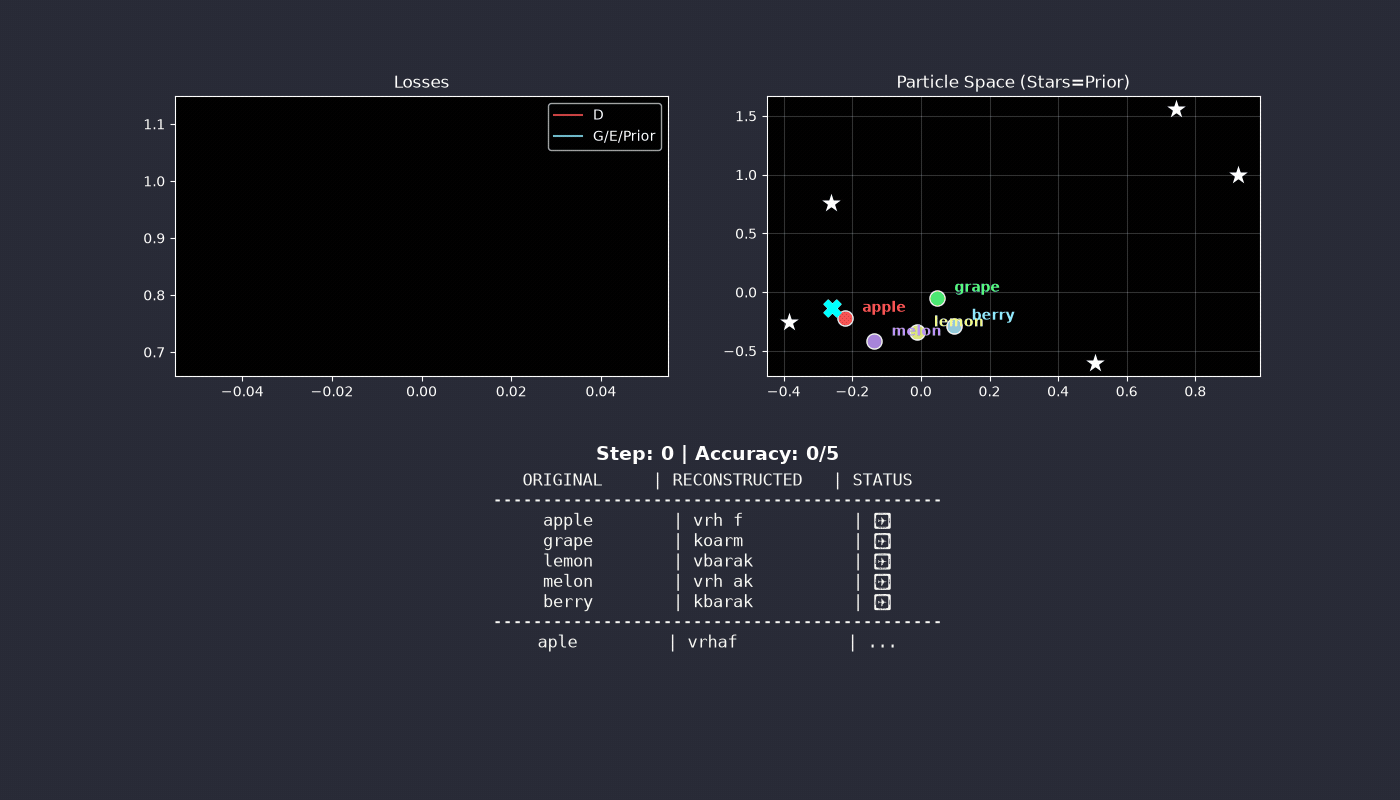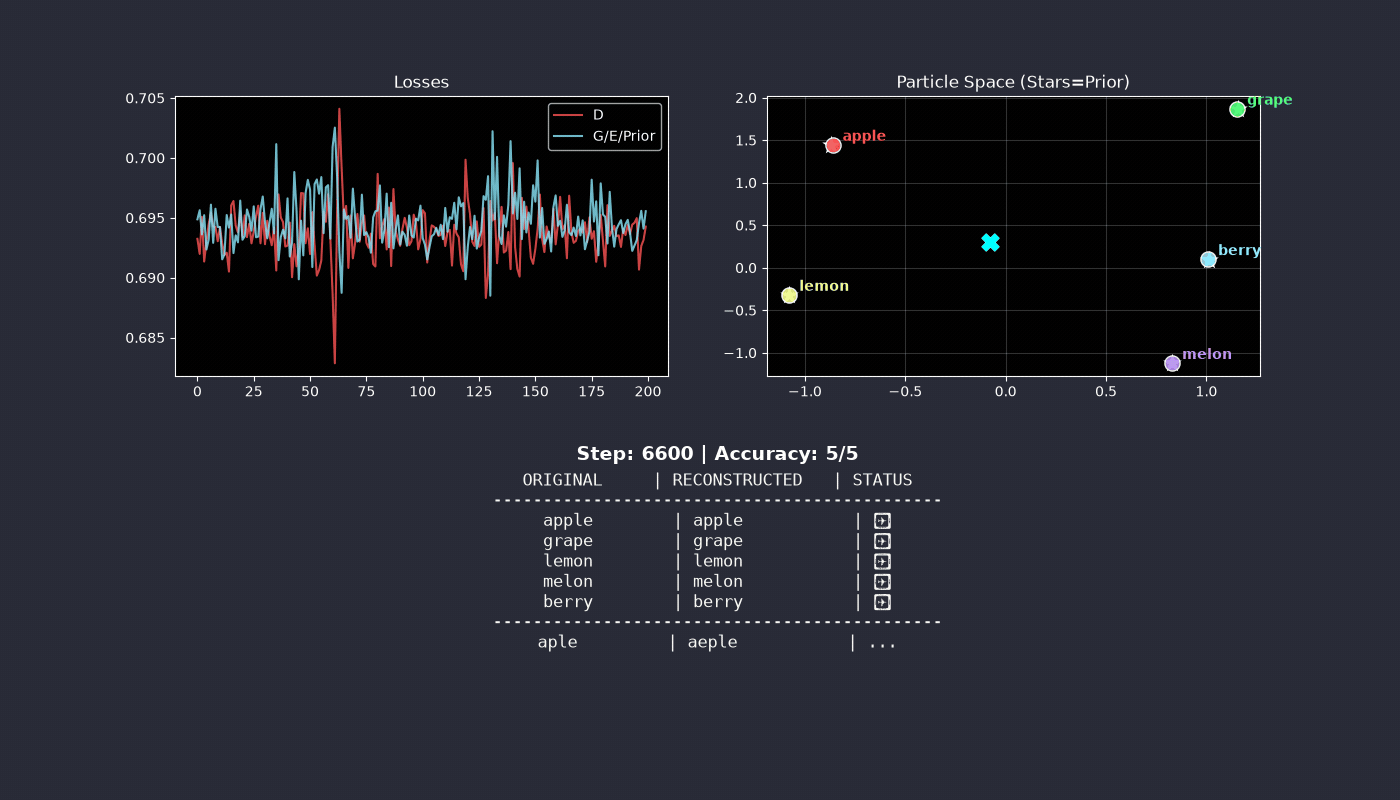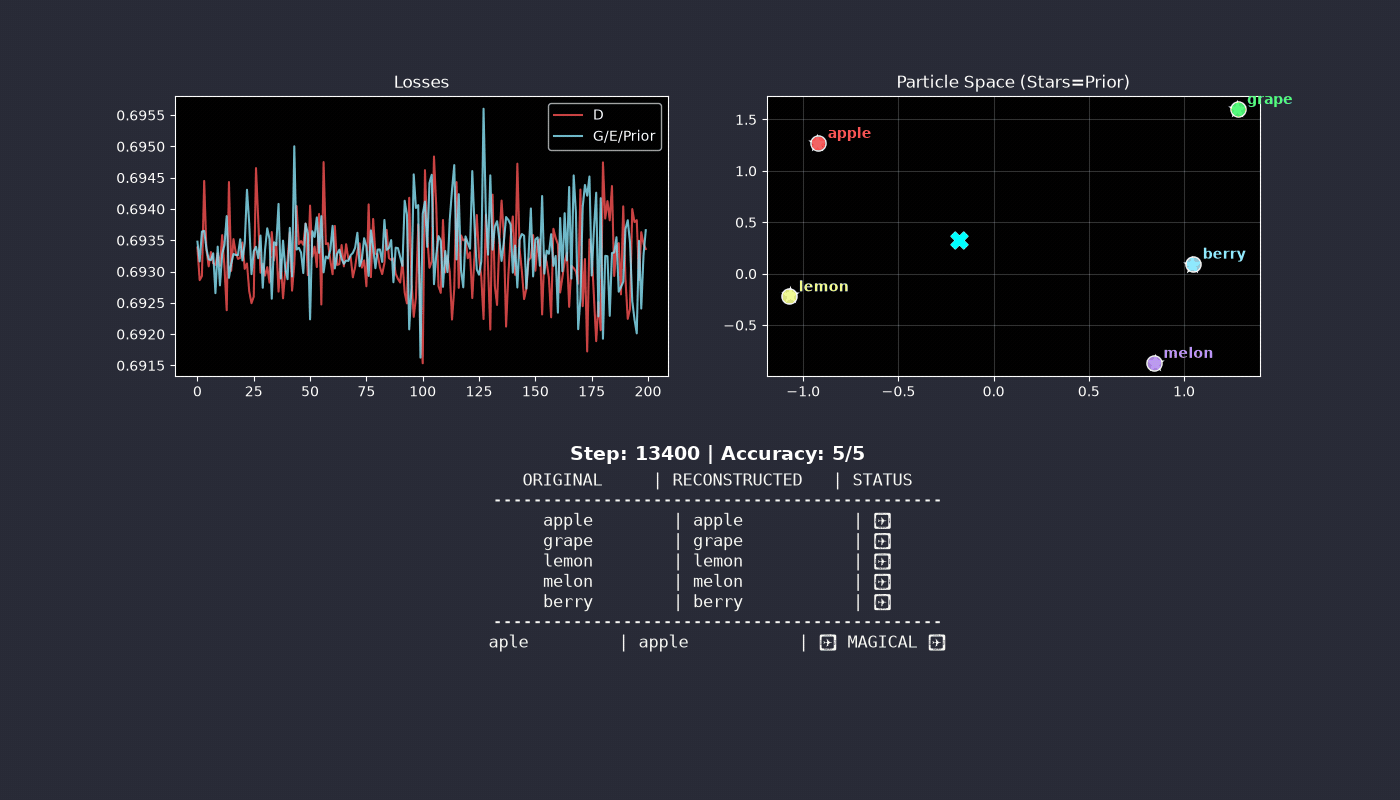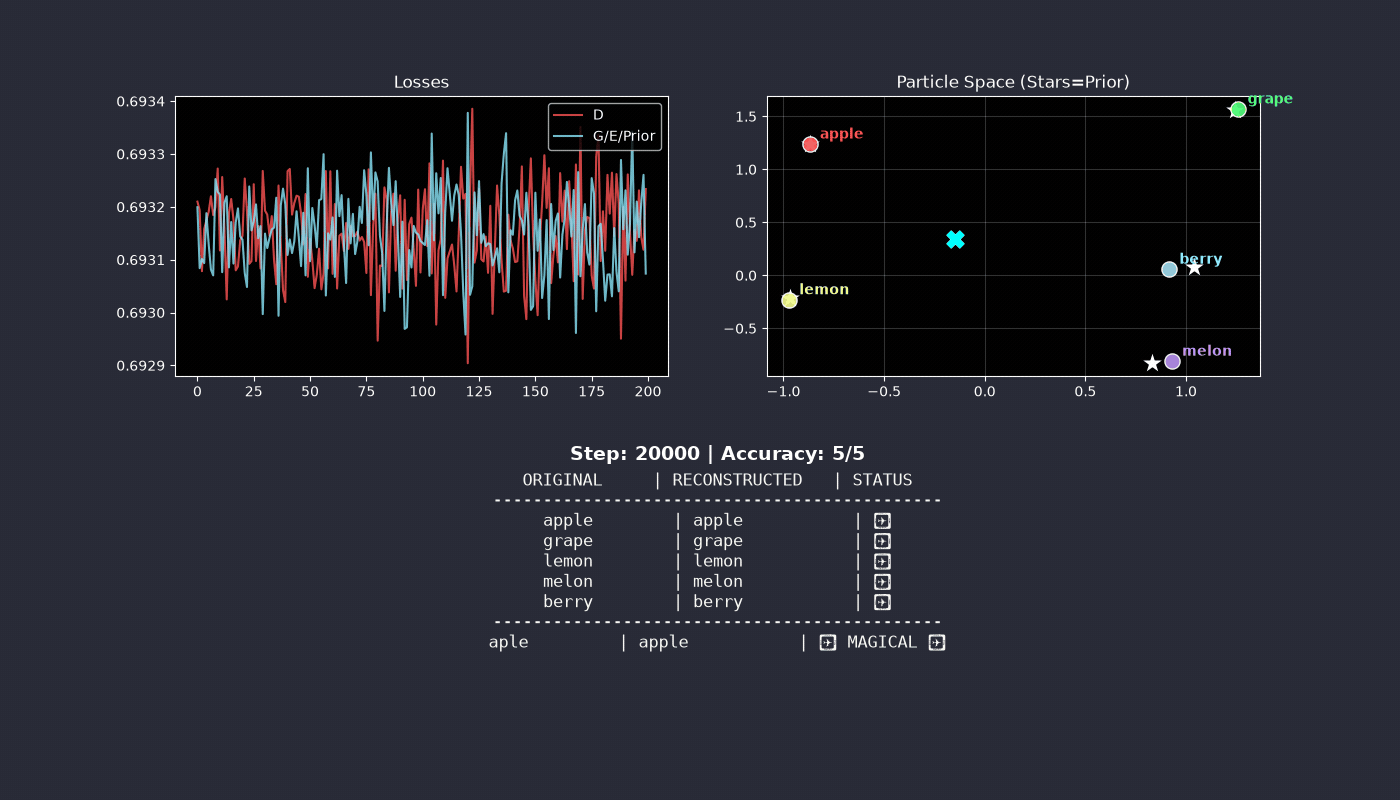
A minimal example demonstrating the core idea. Five words ("apple", "grape", "lemon", "melon", "berry") are encoded into a 2D latent space. Each word gets one particle.
|
|
361
|
+
|
|
362
|
+
|
|
363
|
+
|
|
364
|
+
```bash
|
|
365
|
+
python examples/five_modes.py
|
|
366
|
+
```
|
|
367
|
+
|
|
368
|
+
The visualization shows:
|
|
369
|
+
- **Left**: Loss curves for D and G/E/Prior
|
|
370
|
+
- **Center**: 2D latent space with particle positions (white stars) and encoded words (colored dots)
|
|
371
|
+
- **Right**: Reconstruction quality over training
|
|
372
|
+
|
|
373
|
+
### 100 Gaussians (2D Distribution)
|
|
374
|
+
|
|
375
|
+
The main benchmark. 100 Gaussian modes arranged on a 10×10 grid. This is a stress test for mode coverage.
|
|
376
|
+
|
|
377
|
+
```bash
|
|
378
|
+
python examples/100gaussians.py
|
|
379
|
+
```
|
|
380
|
+
|
|
381
|
+
The historical particle study reports runs with 100/100 modes and approximately 99% of samples within 3σ of a center after 7k steps. Coverage alone does not establish that the within-mode distribution is correct; the trainer also records shape and transport metrics.
|
|
382
|
+
|
|
383
|
+
The default recipe is RpGAN (relativistic, logistic) + a one-sided cap gradient penalty on D (`relu(‖∇ₓD‖ − 1)²` on reals and fakes, coeff 1.0), Fourier-feature D, EMA evaluation, Adam β1=0, base LR 6e-4 with a delayed cosine anneal. The cap won a 420-run bake-off against the zero-centered R1/R2 penalty, which is still available with `--reg_arm a_r1r2 --reg_coeff 0.02`. See [FINDINGS.md](https://github.com/255BITS/ParticleGAN/blob/master/FINDINGS.md) for the study and [docs/convergence-tips.md](https://github.com/255BITS/ParticleGAN/blob/master/docs/convergence-tips.md) for the transferable reasoning behind each ingredient.
|
|
384
|
+
|
|
385
|
+
**Without particle prior** (baseline):
|
|
386
|
+
```bash
|
|
387
|
+
python examples/100gaussians_no_particle_prior.py
|
|
388
|
+
```
|
|
389
|
+
|
|
390
|
+
This entrypoint uses the same architecture, losses, learning rates, schedule, and EMA as the particle example, with fresh Gaussian noise. Use `--prior frozen_gaussian` for a finite frozen-table control. The outcome depends on the recipe and seed; the baseline does not assume collapse.
|
|
391
|
+
|
|
392
|
+
## Project Structure
|
|
393
|
+
|
|
394
|
+
```
|
|
395
|
+
ParticleGAN/
|
|
396
|
+
├── particlegan/ # Installable PyTorch primitives and recipe helpers
|
|
397
|
+
│ ├── particle_prior.py # Learnable particle cloud (nn.Module)
|
|
398
|
+
│ ├── gan_loss.py # Flexible GAN losses (hinge, logistic, Wasserstein, LSGAN)
|
|
399
|
+
│ ├── grad_regularizers.py # D gradient penalties (cap, R1/R2, eikonal, ...)
|
|
400
|
+
│ ├── vicreg_loss.py # Variance-covariance regularization
|
|
401
|
+
│ ├── diffusion.py # DDGAN forward/reverse transitions
|
|
402
|
+
│ ├── conditioning.py # UCD scores and class supervision
|
|
403
|
+
│ └── recipes.py # Inspectable defaults and optional factories
|
|
404
|
+
├── lib/ # Repository compatibility imports and research helpers
|
|
405
|
+
├── examples/
|
|
406
|
+
│ ├── pytorch_loop.py # Minimal caller-owned loop (Torch only)
|
|
407
|
+
│ ├── api.toml # Constructor/recipe configuration
|
|
408
|
+
│ ├── five_modes.py # Text generation toy problem
|
|
409
|
+
│ ├── 100gaussians.py # 100-mode benchmark (with particles)
|
|
410
|
+
│ └── 100gaussians_no_particle_prior.py # Baseline (without particles)
|
|
411
|
+
└── README.md
|
|
412
|
+
```
|
|
413
|
+
|
|
414
|
+
The grid-search infrastructure behind the study — config generation, the per-arm trainer, grid runner, and the analysis/leaderboard scripts — lives in `experiments/`, with the generated per-run configs in `configs/`.
|
|
415
|
+
|
|
416
|
+
The [CIFAR DDGAN experiment](https://github.com/255BITS/ParticleGAN/blob/master/reports/cifar-ddgan/README.md) scales the particle
|
|
417
|
+
recipe to images. Its [speed study](https://github.com/255BITS/ParticleGAN/blob/master/reports/cifar-ddgan/speed/READOUT.md) compares
|
|
418
|
+
exact/lazy/finite-difference bcap and backports the shared implementation to both
|
|
419
|
+
toy trainers. The faster CIFAR default retains exact derivatives; FD is optional.
|
|
420
|
+
|
|
421
|
+
## Notes
|
|
422
|
+
|
|
423
|
+
- The text experiments (`five_modes.py`) use the same recipe (RpGAN + one-sided cap penalty on the joint critic ∇₍ₓ,𝓏₎D, EMA, β1=0, cosine anneal)
|
|
424
|
+
- The 100-Gaussian experiments use the one-sided cap penalty (`--reg_arm`, default `b_cap`); a gradient penalty is what lets the sharp Fourier discriminator keep full mode coverage
|
|
425
|
+
- Particles use a higher learning rate (10×) than G/D for faster adaptation
|
|
426
|
+
|
|
427
|
+
## Changelog
|
|
428
|
+
|
|
429
|
+
Versions before 0.2 tracked the default recipe of `examples/100gaussians.py`.
|
|
430
|
+
|
|
431
|
+
### 0.2.0 — unreleased
|
|
432
|
+
|
|
433
|
+
- Adds the installable `particlegan` namespace, independent PyTorch primitives,
|
|
434
|
+
immutable recipes, and direct use of loaded TOML dictionaries.
|
|
435
|
+
- Core runtime requires only Torch; research dependencies use the `experiments` extra.
|
|
436
|
+
- Repository trainers use the shared package while retaining their own loops.
|
|
437
|
+
|
|
438
|
+
### 0.1.2 — 2026-08-22
|
|
439
|
+
|
|
440
|
+
- Default gradient penalty switched to the one-sided cap (`b_cap`, `relu(‖∇ₓD‖ − 1)²`, coeff 1.0) via `lib/grad_regularizers.py`; base LR 3e-4 → 6e-4; run length 5k → 7k steps.
|
|
441
|
+
- Chosen by a 420-run controlled study ([FINDINGS.md](https://github.com/255BITS/ParticleGAN/blob/master/FINDINGS.md)): same game-damping as R1/R2, sharper modes (hq 0.986 vs a ~0.94 ceiling), honest per-mode core width (0.87), zero collapses. R1/R2 stays available via `--reg_arm a_r1r2`.
|
|
442
|
+
- Adds the `experiments/` study infrastructure and the deterministic video renderer.
|
|
443
|
+
|
|
444
|
+
### 0.1.1
|
|
445
|
+
|
|
446
|
+
- R3GAN-style defaults (previously undocumented; commit `b5529cb`): RpGAN logistic objective + zero-centered R1+R2 (γ=0.02) + Fourier-2 features on D + EMA(0.995) on G and prior + Adam β1=0 + delayed cosine LR anneal + z_dim 4.
|
|
447
|
+
- Full coverage with ≥90% hq in ~3.5k steps.
|
|
448
|
+
|
|
449
|
+
### 0.1.0
|
|
450
|
+
|
|
451
|
+
- Original example: vanilla/hinge GAN, no gradient regularizer, plain MLP D, z_dim 2, Adam β1=0.5, no EMA, no LR anneal.
|
|
452
|
+
- Never converged on the 100-Gaussians benchmark: ~86–92/100 modes, ~30% hq at 12k steps (baseline row in [docs/convergence-tips.md](https://github.com/255BITS/ParticleGAN/blob/master/docs/convergence-tips.md)).
|
|
453
|
+
|
|
454
|
+
## Citation
|
|
455
|
+
|
|
456
|
+
```bibtex
|
|
457
|
+
@software{particlegan2025,
|
|
458
|
+
author = {Martyn Garcia},
|
|
459
|
+
title = {ParticleGAN: Learnable Priors for Stable GANs},
|
|
460
|
+
year = {2025},
|
|
461
|
+
url = {https://github.com/255BITS/ParticleGAN}
|
|
462
|
+
}
|
|
463
|
+
```
|
|
464
|
+
|
|
465
|
+
## License
|
|
466
|
+
|
|
467
|
+
MIT
|