overfitlab 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- overfitlab-0.1.0/.gitignore +55 -0
- overfitlab-0.1.0/LICENSE +21 -0
- overfitlab-0.1.0/PKG-INFO +178 -0
- overfitlab-0.1.0/README.md +148 -0
- overfitlab-0.1.0/pyproject.toml +130 -0
- overfitlab-0.1.0/src/overfitlab/__init__.py +119 -0
- overfitlab-0.1.0/src/overfitlab/_arrays.py +124 -0
- overfitlab-0.1.0/src/overfitlab/_normal.py +92 -0
- overfitlab-0.1.0/src/overfitlab/bootstrap.py +137 -0
- overfitlab-0.1.0/src/overfitlab/cli.py +379 -0
- overfitlab-0.1.0/src/overfitlab/cv.py +376 -0
- overfitlab-0.1.0/src/overfitlab/deflated.py +212 -0
- overfitlab-0.1.0/src/overfitlab/factory.py +364 -0
- overfitlab-0.1.0/src/overfitlab/haircut.py +230 -0
- overfitlab-0.1.0/src/overfitlab/pbo.py +245 -0
- overfitlab-0.1.0/src/overfitlab/py.typed +0 -0
- overfitlab-0.1.0/src/overfitlab/results.py +99 -0
- overfitlab-0.1.0/src/overfitlab/sharpe.py +347 -0
- overfitlab-0.1.0/src/overfitlab/snooping.py +399 -0
- overfitlab-0.1.0/src/overfitlab/synth.py +425 -0
- overfitlab-0.1.0/src/overfitlab/trial_log_schema.json +37 -0
- overfitlab-0.1.0/src/overfitlab/triallog.py +1451 -0
- overfitlab-0.1.0/src/overfitlab/verdict.py +322 -0
- overfitlab-0.1.0/study/README.md +3 -0
- overfitlab-0.1.0/study/pyproject.toml +34 -0
|
@@ -0,0 +1,55 @@
|
|
|
1
|
+
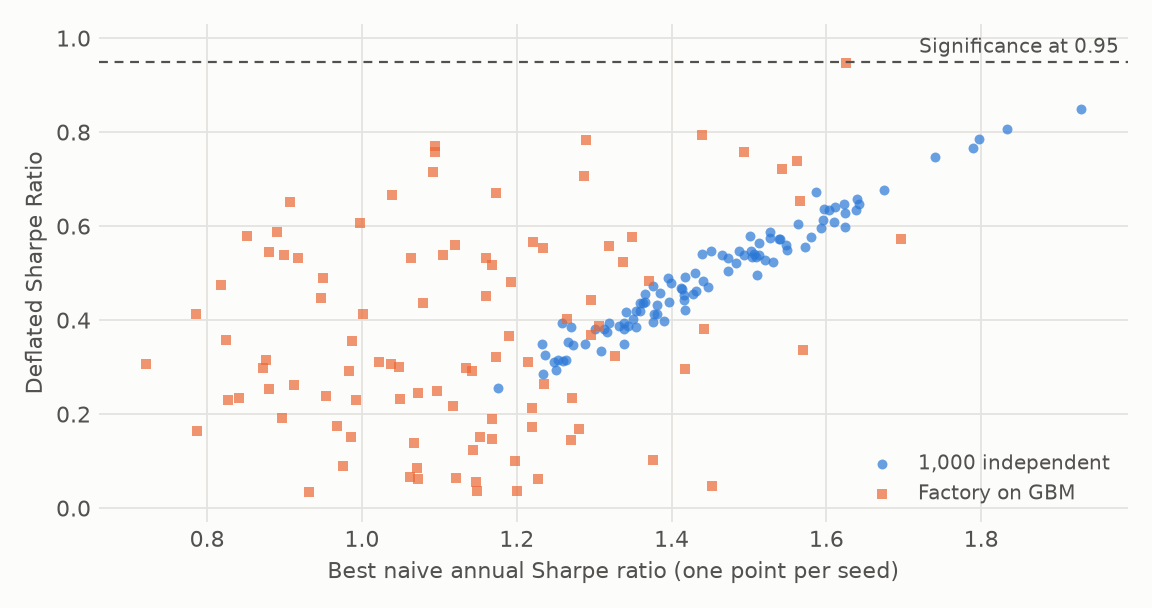
# Data: never commit raw or licensed data
|
|
2
|
+
data/
|
|
3
|
+
*.parquet
|
|
4
|
+
*.feather
|
|
5
|
+
*.h5
|
|
6
|
+
*.itch
|
|
7
|
+
*.pcap
|
|
8
|
+
*.gz
|
|
9
|
+
*.zst
|
|
10
|
+
|
|
11
|
+
# Python
|
|
12
|
+
__pycache__/
|
|
13
|
+
*.py[cod]
|
|
14
|
+
.venv/
|
|
15
|
+
venv/
|
|
16
|
+
.ipynb_checkpoints/
|
|
17
|
+
.pytest_cache/
|
|
18
|
+
.mypy_cache/
|
|
19
|
+
.ruff_cache/
|
|
20
|
+
*.egg-info/
|
|
21
|
+
dist/
|
|
22
|
+
|
|
23
|
+
# C++ / Rust / CUDA builds
|
|
24
|
+
build/
|
|
25
|
+
cmake-build-*/
|
|
26
|
+
target/
|
|
27
|
+
*.o
|
|
28
|
+
*.obj
|
|
29
|
+
*.so
|
|
30
|
+
*.dll
|
|
31
|
+
*.pyd
|
|
32
|
+
*.exe
|
|
33
|
+
|
|
34
|
+
# Editors, OS, secrets
|
|
35
|
+
.vscode/
|
|
36
|
+
.idea/
|
|
37
|
+
.DS_Store
|
|
38
|
+
Thumbs.db
|
|
39
|
+
.env
|
|
40
|
+
|
|
41
|
+
# Local build spec (kept out of the public repo)
|
|
42
|
+
SPEC.html
|
|
43
|
+
|
|
44
|
+
# Run logs and tool output (added in M1)
|
|
45
|
+
results/logs/
|
|
46
|
+
results/sims/
|
|
47
|
+
.hypothesis/
|
|
48
|
+
.benchmarks/
|
|
49
|
+
.coverage
|
|
50
|
+
.coverage.*
|
|
51
|
+
coverage.xml
|
|
52
|
+
site/
|
|
53
|
+
|
|
54
|
+
# The ingest package is code, not data; the data/ rule above would hide it.
|
|
55
|
+
!study/src/overfitlab_study/data/
|
overfitlab-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 avmhdt
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,178 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: overfitlab
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Statistics that separate a real trading signal from a lucky one: PSR, DSR, PBO, purged CV and data-snooping tests.
|
|
5
|
+
Project-URL: Homepage, https://avmhdt.github.io/backtest-overfitting-lab/
|
|
6
|
+
Project-URL: Repository, https://github.com/avmhdt/backtest-overfitting-lab
|
|
7
|
+
Author: avmhdt
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: backtest,cross-validation,deflated-sharpe,multiple-testing,overfitting
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Intended Audience :: Financial and Insurance Industry
|
|
13
|
+
Classifier: Intended Audience :: Science/Research
|
|
14
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
15
|
+
Classifier: Operating System :: Microsoft :: Windows
|
|
16
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
19
|
+
Classifier: Topic :: Office/Business :: Financial :: Investment
|
|
20
|
+
Classifier: Typing :: Typed
|
|
21
|
+
Requires-Python: >=3.12
|
|
22
|
+
Requires-Dist: numba>=0.61
|
|
23
|
+
Requires-Dist: numpy>=2.0
|
|
24
|
+
Requires-Dist: pyarrow>=17
|
|
25
|
+
Requires-Dist: scipy>=1.13
|
|
26
|
+
Requires-Dist: typer>=0.12
|
|
27
|
+
Provides-Extra: polars
|
|
28
|
+
Requires-Dist: polars>=1.10; extra == 'polars'
|
|
29
|
+
Description-Content-Type: text/markdown
|
|
30
|
+
|
|
31
|
+
# Backtest overfitting study
|
|
32
|
+
|
|
33
|
+
> The statistics that tell a real trading signal from a lucky one, packaged as a library and turned on real research.
|
|
34
|
+
|
|
35
|
+
`overfitlab` deflates a backtest for the search behind it. Run 1,000 strategies on pure noise and the best shows a median annual Sharpe ratio of 1.43. It looks publishable, and it's nothing. This project implements the tests that catch that, checks them against the papers and simulations, and applies them to public data and to the owner's own trial logs.
|
|
36
|
+
|
|
37
|
+
The [ten-minute memo](https://avmhdt.github.io/backtest-overfitting-lab/memo/) gives the argument. The [docs site](https://avmhdt.github.io/backtest-overfitting-lab/) has the API, the theory and a [calculator](https://avmhdt.github.io/backtest-overfitting-lab/calculator/).
|
|
38
|
+
|
|
39
|
+
## Quickstart
|
|
40
|
+
|
|
41
|
+
```bash
|
|
42
|
+
pip install overfitlab
|
|
43
|
+
```
|
|
44
|
+
|
|
45
|
+
```python
|
|
46
|
+
import overfitlab as ol
|
|
47
|
+
|
|
48
|
+
# A 2.5 annual Sharpe ratio over five years, the best of 100 trials.
|
|
49
|
+
sr = 2.5 / 250**0.5
|
|
50
|
+
result = ol.deflated_sharpe_ratio(
|
|
51
|
+
sr, 1250, n_trials=100, var_trials=0.5 / 250, skew=-3.0, kurtosis=10.0
|
|
52
|
+
)
|
|
53
|
+
print(round(result.dsr, 4)) # 0.9004
|
|
54
|
+
```
|
|
55
|
+
|
|
56
|
+
That Sharpe ratio misses the 0.95 bar once its 100 trials and fat left tail are counted. [Getting started](https://avmhdt.github.io/backtest-overfitting-lab/getting-started/) covers trial logs, cross-validation and the verdict gate.
|
|
57
|
+
|
|
58
|
+
## The problem
|
|
59
|
+
|
|
60
|
+
Researchers run many backtests and report the best. The best of many noisy trials has a high Sharpe ratio even when no trial has an edge, and a backtest report doesn't show how many trials stood behind it. The hypothesis here is that a small set of published corrections, applied with an honest trial count, separates luck from signal, and that each has failure modes worth measuring.
|
|
61
|
+
|
|
62
|
+
## Data
|
|
63
|
+
|
|
64
|
+
Raw and licensed data live in `data/`, which is git-ignored. Only download scripts, aggregates and small synthetic fixtures are committed.
|
|
65
|
+
|
|
66
|
+
| Dataset | Cost | What it gives |
|
|
67
|
+
|---|---|---|
|
|
68
|
+
| Synthetic returns (GBM, block bootstrap) | Free | Ground truth for validating every test. |
|
|
69
|
+
| [Stooq bulk daily data](https://stooq.com/db/h/) and Sharadar | Free, and the owner's bundle | Daily prices for 12 ETFs, 2006 to 2026. |
|
|
70
|
+
| [Ken French data library](https://mba.tuck.dartmouth.edu/pages/faculty/ken.french/data_library.html) and [AQR datasets](https://www.aqr.com/Insights/Datasets) | Free | 56 long factor histories for multiple-testing case studies. |
|
|
71
|
+
|
|
72
|
+
AQR data: Century of Factor Premia, Time Series Momentum, Betting Against Beta and Quality Minus Junk, from [AQR Capital Management](https://www.aqr.com/Insights/Datasets), used with AQR's written permission. This repository publishes aggregate statistics and charts only, not AQR's files or series.
|
|
73
|
+
| [Open Source Asset Pricing](https://www.openassetpricing.com) | Free | A real "many signals" universe of 212 predictors, release 2026.10. |
|
|
74
|
+
|
|
75
|
+
## Method
|
|
76
|
+
|
|
77
|
+
| Method | Question it answers |
|
|
78
|
+
|---|---|
|
|
79
|
+
| PSR and MinTRL | Is this Sharpe ratio real, given its length and return shape? |
|
|
80
|
+
| DSR and MinBTL | Is it real, given how many trials produced it? |
|
|
81
|
+
| PBO via CSCV | Does in-sample selection carry over out of sample? |
|
|
82
|
+
| Reality Check, SPA, StepM | Does anything in this set beat the benchmark, and which? |
|
|
83
|
+
| Harvey–Liu haircut | What is the Sharpe ratio worth after multiple testing? |
|
|
84
|
+
| Purged k-fold and CPCV | How do I cross-validate overlapping labels without leaking? |
|
|
85
|
+
|
|
86
|
+
A verdict gate requires the DSR, PBO, SPA, StepM and the haircut to pass together. Trial logs follow a frozen [contract](https://avmhdt.github.io/backtest-overfitting-lab/trial-log/), so N and V come from a record and not from memory.
|
|
87
|
+
|
|
88
|
+
Each method is checked three ways: against the papers' printed examples, against closed-form power, and against independent implementations. [Validation](https://avmhdt.github.io/backtest-overfitting-lab/validation/) has the details.
|
|
89
|
+
|
|
90
|
+
## Results
|
|
91
|
+
|
|
92
|
+
| Experiment | Result |
|
|
93
|
+
|---|---|
|
|
94
|
+
| Best of 1,000 on noise, 100 seeds | Median best Sharpe 1.43. Naive PSR significant in 100 seeds, DSR in 0. Median PBO 0.50. |
|
|
95
|
+
| 1,034 factory variants on noise | Median best Sharpe 1.13. DSR significant in 0 seeds. Median PBO 0.52. |
|
|
96
|
+
| Leakage on noise, 20-day labels | Shuffled k-fold accuracy 0.703, purged 0.495. Gap 0.208. |
|
|
97
|
+
| Factory on 12 ETFs, 1,034 trials | Sharpe 0.76 against a bar of 0.83. DSR 0.39, PBO 0.31, verdict FAIL. Holdout Sharpe 0.68. |
|
|
98
|
+
| 56 factors from Ken French and AQR | 30 survive StepM. |
|
|
99
|
+
| 212 OSAP predictors, full history | 173 at t > 1.96, 134 at t > 3, 149 after BHY, 96 after StepM. |
|
|
100
|
+
| 208 OSAP predictors, after publication | 54 at t > 1.96, 24 at t > 3, 9 after BHY, 8 after StepM. |
|
|
101
|
+
|
|
102
|
+
|
|
103
|
+
|
|
104
|
+
Detection takes a long record. With a true Sharpe ratio of 1 among 100 trials, the Reality Check, SPA and StepM need 20 years for 80% power, and the DSR doesn't reach it within the 20-year grid. See the [power curves](https://avmhdt.github.io/backtest-overfitting-lab/theory/power/).
|
|
105
|
+
|
|
106
|
+
### The owner's own trials
|
|
107
|
+
|
|
108
|
+
Only one of the six projects, `equity-factor-pipeline`, has a trial log so far.
|
|
109
|
+
|
|
110
|
+
| Family | Own N | Sharpe | SR₀ | DSR | Verdict | DSR at N = 613 |
|
|
111
|
+
|---|---:|---:|---:|---:|---|---:|
|
|
112
|
+
| composite | 305 | 1.25 | 2.34 | 0.000 | FAIL | 0.000 |
|
|
113
|
+
| investment | 32 | 1.00 | 0.70 | 0.952 | PASS | 0.429 |
|
|
114
|
+
| low_risk | 32 | 0.80 | 0.45 | 0.957 | PASS | 0.734 |
|
|
115
|
+
| momentum | 66 | 0.60 | 0.73 | 0.261 | FAIL | 0.036 |
|
|
116
|
+
| quality | 44 | 0.98 | 0.63 | 0.951 | PASS | 0.678 |
|
|
117
|
+
| replication | 86 | 0.81 | 0.60 | 0.840 | FAIL | 0.595 |
|
|
118
|
+
| size | 8 | 0.09 | 0.05 | 0.588 | FAIL | 0.469 |
|
|
119
|
+
| value | 40 | 0.68 | 0.51 | 0.802 | FAIL | 0.412 |
|
|
120
|
+
|
|
121
|
+
Three families pass when each is judged alone. They were not found alone: the project ran 613 trials. At that count, no family reaches 0.95. `investment` fails outright, because the bar of 1.03 is above its Sharpe ratio of 1.00. Which count applies depends on whether the families were independent ideas or one search, so this table can't settle whether they're real. It does show that the verdict turns on that choice.
|
|
122
|
+
|
|
123
|
+
## What failed
|
|
124
|
+
|
|
125
|
+
- **DSR power (AC-W-02).** The DSR rejects less often than its reference: 0.036 against 0.168, 0.149 against 0.207, and 0.003 against 0.056 at the three cells that miss. V is estimated from the same trials as the planted winner, which raises its own bar. A version given the true V matches. This is kept as a finding, and no limit was changed.
|
|
126
|
+
- **G-03c.** One of the 40 paper examples misses its tolerance by 5e-6. It's a documented exception.
|
|
127
|
+
- **Studentised SPA check (AC-W-07).** Against `bsds.m`, 19 of 20 cases agree within 0.013, and StepM agrees in all 20. Case 2 has no positive mean, and `bsds.m` has no floor there, so it reports p = 1.
|
|
128
|
+
- **Own-projects coverage (AC-H-02).** One of six projects has a trial log.
|
|
129
|
+
- **Holm and BHY on the calculator (FR-34).** Deferred. The page gives the exact Bonferroni haircut.
|
|
130
|
+
|
|
131
|
+
## Limitations
|
|
132
|
+
|
|
133
|
+
- A trial log records what was run, not what was thought about, so N is a lower bound.
|
|
134
|
+
- The tests here compare with zero. A long-only ETF strategy can beat zero on the equity premium alone, which is why the factory case passes SPA and StepM and still fails the DSR.
|
|
135
|
+
- Fewer predictors survive after publication partly because those samples are shorter, so that drop isn't all decay.
|
|
136
|
+
- PBO measures whether rankings persist, not whether money is made. An edge that died halfway through scores near 0. See [when PBO misleads](https://avmhdt.github.io/backtest-overfitting-lab/theory/pbo/).
|
|
137
|
+
- Power curves assume independent strategies with one planted signal.
|
|
138
|
+
|
|
139
|
+
## How to reproduce
|
|
140
|
+
|
|
141
|
+
```bash
|
|
142
|
+
uv sync
|
|
143
|
+
uv run olab-study all
|
|
144
|
+
```
|
|
145
|
+
|
|
146
|
+
The full run takes about an hour and regenerates every table and figure from the data in `data/`. Without that data, the real-data steps are skipped with a message. `--quick` runs a reduced version in about two minutes. Each run adds rows to `results/experiment_log.csv`.
|
|
147
|
+
|
|
148
|
+
## Requirements
|
|
149
|
+
|
|
150
|
+
- [x] Purged k-fold with embargo and combinatorial purged CV (CPCV), handling overlapping multi-day labels. (FR-08, FR-09)
|
|
151
|
+
- [x] Probabilistic and Deflated Sharpe Ratio (Bailey and López de Prado), adjusting for skew, kurtosis and the number and variance of trials. (FR-03, FR-05)
|
|
152
|
+
- [x] Probability of Backtest Overfitting via CSCV (Bailey, Borwein, López de Prado and Zhu). (FR-10)
|
|
153
|
+
- [x] Data-snooping tests: White's Reality Check, Hansen's SPA, and the Romano–Wolf stepdown. (FR-12, FR-13, FR-14)
|
|
154
|
+
- [x] Minimum backtest length and a Sharpe ratio haircut calculator (Harvey and Liu). (FR-06, FR-07, FR-33)
|
|
155
|
+
- [x] A strategy factory that generates thousands of parameter variants (crossovers, breakouts, mean reversion) to test against. (FR-15)
|
|
156
|
+
- [x] A synthetic data generator with known ground truth: pure noise, and noise with a planted signal of chosen strength. (FR-16)
|
|
157
|
+
|
|
158
|
+
## Success criteria
|
|
159
|
+
|
|
160
|
+
### Correct and reproducible
|
|
161
|
+
|
|
162
|
+
- [x] On pure noise, the best of 1,000 strategies shows a high naive Sharpe while the DSR is not significant and PBO is near or above 0.5. (AC-W-01)
|
|
163
|
+
- [ ] On planted-signal data, each test detects the signal at roughly its theoretical power. (AC-W-02: met for PSR, RC, SPA and StepM, missed for the DSR)
|
|
164
|
+
- [x] Implementations reproduce the numerical examples in the original papers to three decimals. (AC-W-03, with G-03c as a documented exception)
|
|
165
|
+
- [x] A simulation shows the accuracy gap between standard k-fold and purged k-fold on overlapping labels. (AC-W-04)
|
|
166
|
+
|
|
167
|
+
### Depth
|
|
168
|
+
|
|
169
|
+
- [x] Power curves: how large a true Sharpe, and how long a backtest, each test needs before it detects a signal. (AC-H-01)
|
|
170
|
+
- [ ] A table of naive vs deflated Sharpe for your own projects ([equity-factor-pipeline](https://github.com/avmhdt/equity-factor-pipeline), [llm-text-alpha](https://github.com/avmhdt/llm-text-alpha), [stat-arb-pairs](https://github.com/avmhdt/stat-arb-pairs)). (AC-H-02: one of six projects so far)
|
|
171
|
+
- [ ] Packaged as a pip-installable library with docs and an interactive Sharpe-haircut page. (AC-H-03: docs and calculator are live, and the install from PyPI comes with the first release)
|
|
172
|
+
- [x] A short paper-style writeup a PM could read in ten minutes. (AC-H-04)
|
|
173
|
+
|
|
174
|
+
## Questions this project must answer
|
|
175
|
+
|
|
176
|
+
- [Why does the DSR use the variance of trial Sharpes, not just the count?](https://avmhdt.github.io/backtest-overfitting-lab/theory/psr-dsr/)
|
|
177
|
+
- [When is PBO misleading?](https://avmhdt.github.io/backtest-overfitting-lab/theory/pbo/)
|
|
178
|
+
- [How do you count trials honestly when you iterated by hand?](https://avmhdt.github.io/backtest-overfitting-lab/theory/trial-counting/)
|
|
@@ -0,0 +1,148 @@
|
|
|
1
|
+
# Backtest overfitting study
|
|
2
|
+
|
|
3
|
+
> The statistics that tell a real trading signal from a lucky one, packaged as a library and turned on real research.
|
|
4
|
+
|
|
5
|
+
`overfitlab` deflates a backtest for the search behind it. Run 1,000 strategies on pure noise and the best shows a median annual Sharpe ratio of 1.43. It looks publishable, and it's nothing. This project implements the tests that catch that, checks them against the papers and simulations, and applies them to public data and to the owner's own trial logs.
|
|
6
|
+
|
|
7
|
+
The [ten-minute memo](https://avmhdt.github.io/backtest-overfitting-lab/memo/) gives the argument. The [docs site](https://avmhdt.github.io/backtest-overfitting-lab/) has the API, the theory and a [calculator](https://avmhdt.github.io/backtest-overfitting-lab/calculator/).
|
|
8
|
+
|
|
9
|
+
## Quickstart
|
|
10
|
+
|
|
11
|
+
```bash
|
|
12
|
+
pip install overfitlab
|
|
13
|
+
```
|
|
14
|
+
|
|
15
|
+
```python
|
|
16
|
+
import overfitlab as ol
|
|
17
|
+
|
|
18
|
+
# A 2.5 annual Sharpe ratio over five years, the best of 100 trials.
|
|
19
|
+
sr = 2.5 / 250**0.5
|
|
20
|
+
result = ol.deflated_sharpe_ratio(
|
|
21
|
+
sr, 1250, n_trials=100, var_trials=0.5 / 250, skew=-3.0, kurtosis=10.0
|
|
22
|
+
)
|
|
23
|
+
print(round(result.dsr, 4)) # 0.9004
|
|
24
|
+
```
|
|
25
|
+
|
|
26
|
+
That Sharpe ratio misses the 0.95 bar once its 100 trials and fat left tail are counted. [Getting started](https://avmhdt.github.io/backtest-overfitting-lab/getting-started/) covers trial logs, cross-validation and the verdict gate.
|
|
27
|
+
|
|
28
|
+
## The problem
|
|
29
|
+
|
|
30
|
+
Researchers run many backtests and report the best. The best of many noisy trials has a high Sharpe ratio even when no trial has an edge, and a backtest report doesn't show how many trials stood behind it. The hypothesis here is that a small set of published corrections, applied with an honest trial count, separates luck from signal, and that each has failure modes worth measuring.
|
|
31
|
+
|
|
32
|
+
## Data
|
|
33
|
+
|
|
34
|
+
Raw and licensed data live in `data/`, which is git-ignored. Only download scripts, aggregates and small synthetic fixtures are committed.
|
|
35
|
+
|
|
36
|
+
| Dataset | Cost | What it gives |
|
|
37
|
+
|---|---|---|
|
|
38
|
+
| Synthetic returns (GBM, block bootstrap) | Free | Ground truth for validating every test. |
|
|
39
|
+
| [Stooq bulk daily data](https://stooq.com/db/h/) and Sharadar | Free, and the owner's bundle | Daily prices for 12 ETFs, 2006 to 2026. |
|
|
40
|
+
| [Ken French data library](https://mba.tuck.dartmouth.edu/pages/faculty/ken.french/data_library.html) and [AQR datasets](https://www.aqr.com/Insights/Datasets) | Free | 56 long factor histories for multiple-testing case studies. |
|
|
41
|
+
|
|
42
|
+
AQR data: Century of Factor Premia, Time Series Momentum, Betting Against Beta and Quality Minus Junk, from [AQR Capital Management](https://www.aqr.com/Insights/Datasets), used with AQR's written permission. This repository publishes aggregate statistics and charts only, not AQR's files or series.
|
|
43
|
+
| [Open Source Asset Pricing](https://www.openassetpricing.com) | Free | A real "many signals" universe of 212 predictors, release 2026.10. |
|
|
44
|
+
|
|
45
|
+
## Method
|
|
46
|
+
|
|
47
|
+
| Method | Question it answers |
|
|
48
|
+
|---|---|
|
|
49
|
+
| PSR and MinTRL | Is this Sharpe ratio real, given its length and return shape? |
|
|
50
|
+
| DSR and MinBTL | Is it real, given how many trials produced it? |
|
|
51
|
+
| PBO via CSCV | Does in-sample selection carry over out of sample? |
|
|
52
|
+
| Reality Check, SPA, StepM | Does anything in this set beat the benchmark, and which? |
|
|
53
|
+
| Harvey–Liu haircut | What is the Sharpe ratio worth after multiple testing? |
|
|
54
|
+
| Purged k-fold and CPCV | How do I cross-validate overlapping labels without leaking? |
|
|
55
|
+
|
|
56
|
+
A verdict gate requires the DSR, PBO, SPA, StepM and the haircut to pass together. Trial logs follow a frozen [contract](https://avmhdt.github.io/backtest-overfitting-lab/trial-log/), so N and V come from a record and not from memory.
|
|
57
|
+
|
|
58
|
+
Each method is checked three ways: against the papers' printed examples, against closed-form power, and against independent implementations. [Validation](https://avmhdt.github.io/backtest-overfitting-lab/validation/) has the details.
|
|
59
|
+
|
|
60
|
+
## Results
|
|
61
|
+
|
|
62
|
+
| Experiment | Result |
|
|
63
|
+
|---|---|
|
|
64
|
+
| Best of 1,000 on noise, 100 seeds | Median best Sharpe 1.43. Naive PSR significant in 100 seeds, DSR in 0. Median PBO 0.50. |
|
|
65
|
+
| 1,034 factory variants on noise | Median best Sharpe 1.13. DSR significant in 0 seeds. Median PBO 0.52. |
|
|
66
|
+
| Leakage on noise, 20-day labels | Shuffled k-fold accuracy 0.703, purged 0.495. Gap 0.208. |
|
|
67
|
+
| Factory on 12 ETFs, 1,034 trials | Sharpe 0.76 against a bar of 0.83. DSR 0.39, PBO 0.31, verdict FAIL. Holdout Sharpe 0.68. |
|
|
68
|
+
| 56 factors from Ken French and AQR | 30 survive StepM. |
|
|
69
|
+
| 212 OSAP predictors, full history | 173 at t > 1.96, 134 at t > 3, 149 after BHY, 96 after StepM. |
|
|
70
|
+
| 208 OSAP predictors, after publication | 54 at t > 1.96, 24 at t > 3, 9 after BHY, 8 after StepM. |
|
|
71
|
+
|
|
72
|
+

|
|
73
|
+
|
|
74
|
+
Detection takes a long record. With a true Sharpe ratio of 1 among 100 trials, the Reality Check, SPA and StepM need 20 years for 80% power, and the DSR doesn't reach it within the 20-year grid. See the [power curves](https://avmhdt.github.io/backtest-overfitting-lab/theory/power/).
|
|
75
|
+
|
|
76
|
+
### The owner's own trials
|
|
77
|
+
|
|
78
|
+
Only one of the six projects, `equity-factor-pipeline`, has a trial log so far.
|
|
79
|
+
|
|
80
|
+
| Family | Own N | Sharpe | SR₀ | DSR | Verdict | DSR at N = 613 |
|
|
81
|
+
|---|---:|---:|---:|---:|---|---:|
|
|
82
|
+
| composite | 305 | 1.25 | 2.34 | 0.000 | FAIL | 0.000 |
|
|
83
|
+
| investment | 32 | 1.00 | 0.70 | 0.952 | PASS | 0.429 |
|
|
84
|
+
| low_risk | 32 | 0.80 | 0.45 | 0.957 | PASS | 0.734 |
|
|
85
|
+
| momentum | 66 | 0.60 | 0.73 | 0.261 | FAIL | 0.036 |
|
|
86
|
+
| quality | 44 | 0.98 | 0.63 | 0.951 | PASS | 0.678 |
|
|
87
|
+
| replication | 86 | 0.81 | 0.60 | 0.840 | FAIL | 0.595 |
|
|
88
|
+
| size | 8 | 0.09 | 0.05 | 0.588 | FAIL | 0.469 |
|
|
89
|
+
| value | 40 | 0.68 | 0.51 | 0.802 | FAIL | 0.412 |
|
|
90
|
+
|
|
91
|
+
Three families pass when each is judged alone. They were not found alone: the project ran 613 trials. At that count, no family reaches 0.95. `investment` fails outright, because the bar of 1.03 is above its Sharpe ratio of 1.00. Which count applies depends on whether the families were independent ideas or one search, so this table can't settle whether they're real. It does show that the verdict turns on that choice.
|
|
92
|
+
|
|
93
|
+
## What failed
|
|
94
|
+
|
|
95
|
+
- **DSR power (AC-W-02).** The DSR rejects less often than its reference: 0.036 against 0.168, 0.149 against 0.207, and 0.003 against 0.056 at the three cells that miss. V is estimated from the same trials as the planted winner, which raises its own bar. A version given the true V matches. This is kept as a finding, and no limit was changed.
|
|
96
|
+
- **G-03c.** One of the 40 paper examples misses its tolerance by 5e-6. It's a documented exception.
|
|
97
|
+
- **Studentised SPA check (AC-W-07).** Against `bsds.m`, 19 of 20 cases agree within 0.013, and StepM agrees in all 20. Case 2 has no positive mean, and `bsds.m` has no floor there, so it reports p = 1.
|
|
98
|
+
- **Own-projects coverage (AC-H-02).** One of six projects has a trial log.
|
|
99
|
+
- **Holm and BHY on the calculator (FR-34).** Deferred. The page gives the exact Bonferroni haircut.
|
|
100
|
+
|
|
101
|
+
## Limitations
|
|
102
|
+
|
|
103
|
+
- A trial log records what was run, not what was thought about, so N is a lower bound.
|
|
104
|
+
- The tests here compare with zero. A long-only ETF strategy can beat zero on the equity premium alone, which is why the factory case passes SPA and StepM and still fails the DSR.
|
|
105
|
+
- Fewer predictors survive after publication partly because those samples are shorter, so that drop isn't all decay.
|
|
106
|
+
- PBO measures whether rankings persist, not whether money is made. An edge that died halfway through scores near 0. See [when PBO misleads](https://avmhdt.github.io/backtest-overfitting-lab/theory/pbo/).
|
|
107
|
+
- Power curves assume independent strategies with one planted signal.
|
|
108
|
+
|
|
109
|
+
## How to reproduce
|
|
110
|
+
|
|
111
|
+
```bash
|
|
112
|
+
uv sync
|
|
113
|
+
uv run olab-study all
|
|
114
|
+
```
|
|
115
|
+
|
|
116
|
+
The full run takes about an hour and regenerates every table and figure from the data in `data/`. Without that data, the real-data steps are skipped with a message. `--quick` runs a reduced version in about two minutes. Each run adds rows to `results/experiment_log.csv`.
|
|
117
|
+
|
|
118
|
+
## Requirements
|
|
119
|
+
|
|
120
|
+
- [x] Purged k-fold with embargo and combinatorial purged CV (CPCV), handling overlapping multi-day labels. (FR-08, FR-09)
|
|
121
|
+
- [x] Probabilistic and Deflated Sharpe Ratio (Bailey and López de Prado), adjusting for skew, kurtosis and the number and variance of trials. (FR-03, FR-05)
|
|
122
|
+
- [x] Probability of Backtest Overfitting via CSCV (Bailey, Borwein, López de Prado and Zhu). (FR-10)
|
|
123
|
+
- [x] Data-snooping tests: White's Reality Check, Hansen's SPA, and the Romano–Wolf stepdown. (FR-12, FR-13, FR-14)
|
|
124
|
+
- [x] Minimum backtest length and a Sharpe ratio haircut calculator (Harvey and Liu). (FR-06, FR-07, FR-33)
|
|
125
|
+
- [x] A strategy factory that generates thousands of parameter variants (crossovers, breakouts, mean reversion) to test against. (FR-15)
|
|
126
|
+
- [x] A synthetic data generator with known ground truth: pure noise, and noise with a planted signal of chosen strength. (FR-16)
|
|
127
|
+
|
|
128
|
+
## Success criteria
|
|
129
|
+
|
|
130
|
+
### Correct and reproducible
|
|
131
|
+
|
|
132
|
+
- [x] On pure noise, the best of 1,000 strategies shows a high naive Sharpe while the DSR is not significant and PBO is near or above 0.5. (AC-W-01)
|
|
133
|
+
- [ ] On planted-signal data, each test detects the signal at roughly its theoretical power. (AC-W-02: met for PSR, RC, SPA and StepM, missed for the DSR)
|
|
134
|
+
- [x] Implementations reproduce the numerical examples in the original papers to three decimals. (AC-W-03, with G-03c as a documented exception)
|
|
135
|
+
- [x] A simulation shows the accuracy gap between standard k-fold and purged k-fold on overlapping labels. (AC-W-04)
|
|
136
|
+
|
|
137
|
+
### Depth
|
|
138
|
+
|
|
139
|
+
- [x] Power curves: how large a true Sharpe, and how long a backtest, each test needs before it detects a signal. (AC-H-01)
|
|
140
|
+
- [ ] A table of naive vs deflated Sharpe for your own projects ([equity-factor-pipeline](https://github.com/avmhdt/equity-factor-pipeline), [llm-text-alpha](https://github.com/avmhdt/llm-text-alpha), [stat-arb-pairs](https://github.com/avmhdt/stat-arb-pairs)). (AC-H-02: one of six projects so far)
|
|
141
|
+
- [ ] Packaged as a pip-installable library with docs and an interactive Sharpe-haircut page. (AC-H-03: docs and calculator are live, and the install from PyPI comes with the first release)
|
|
142
|
+
- [x] A short paper-style writeup a PM could read in ten minutes. (AC-H-04)
|
|
143
|
+
|
|
144
|
+
## Questions this project must answer
|
|
145
|
+
|
|
146
|
+
- [Why does the DSR use the variance of trial Sharpes, not just the count?](https://avmhdt.github.io/backtest-overfitting-lab/theory/psr-dsr/)
|
|
147
|
+
- [When is PBO misleading?](https://avmhdt.github.io/backtest-overfitting-lab/theory/pbo/)
|
|
148
|
+
- [How do you count trials honestly when you iterated by hand?](https://avmhdt.github.io/backtest-overfitting-lab/theory/trial-counting/)
|
|
@@ -0,0 +1,130 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "overfitlab"
|
|
3
|
+
version = "0.1.0"
|
|
4
|
+
description = "Statistics that separate a real trading signal from a lucky one: PSR, DSR, PBO, purged CV and data-snooping tests."
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
license-files = ["LICENSE"]
|
|
8
|
+
requires-python = ">=3.12"
|
|
9
|
+
authors = [{ name = "avmhdt" }]
|
|
10
|
+
keywords = ["backtest", "overfitting", "deflated-sharpe", "cross-validation", "multiple-testing"]
|
|
11
|
+
classifiers = [
|
|
12
|
+
"Development Status :: 3 - Alpha",
|
|
13
|
+
"Intended Audience :: Financial and Insurance Industry",
|
|
14
|
+
"Intended Audience :: Science/Research",
|
|
15
|
+
"License :: OSI Approved :: MIT License",
|
|
16
|
+
"Operating System :: Microsoft :: Windows",
|
|
17
|
+
"Operating System :: POSIX :: Linux",
|
|
18
|
+
"Programming Language :: Python :: 3.12",
|
|
19
|
+
"Programming Language :: Python :: 3.13",
|
|
20
|
+
"Topic :: Office/Business :: Financial :: Investment",
|
|
21
|
+
"Typing :: Typed",
|
|
22
|
+
]
|
|
23
|
+
dependencies = [
|
|
24
|
+
"numpy>=2.0",
|
|
25
|
+
"scipy>=1.13",
|
|
26
|
+
"numba>=0.61",
|
|
27
|
+
"pyarrow>=17",
|
|
28
|
+
"typer>=0.12",
|
|
29
|
+
]
|
|
30
|
+
|
|
31
|
+
[project.optional-dependencies]
|
|
32
|
+
polars = ["polars>=1.10"]
|
|
33
|
+
|
|
34
|
+
[project.scripts]
|
|
35
|
+
overfitlab = "overfitlab.cli:app"
|
|
36
|
+
|
|
37
|
+
[project.urls]
|
|
38
|
+
Homepage = "https://avmhdt.github.io/backtest-overfitting-lab/"
|
|
39
|
+
Repository = "https://github.com/avmhdt/backtest-overfitting-lab"
|
|
40
|
+
|
|
41
|
+
[build-system]
|
|
42
|
+
requires = ["hatchling>=1.25"]
|
|
43
|
+
build-backend = "hatchling.build"
|
|
44
|
+
|
|
45
|
+
[tool.hatch.build.targets.wheel]
|
|
46
|
+
packages = ["src/overfitlab"]
|
|
47
|
+
|
|
48
|
+
[tool.hatch.build.targets.sdist]
|
|
49
|
+
include = ["src/overfitlab", "README.md", "LICENSE", "pyproject.toml"]
|
|
50
|
+
|
|
51
|
+
[tool.uv.workspace]
|
|
52
|
+
members = ["study"]
|
|
53
|
+
|
|
54
|
+
[tool.uv.sources]
|
|
55
|
+
overfitlab-study = { workspace = true }
|
|
56
|
+
|
|
57
|
+
[dependency-groups]
|
|
58
|
+
dev = [
|
|
59
|
+
"overfitlab-study",
|
|
60
|
+
"polars>=1.10",
|
|
61
|
+
"ruff>=0.7",
|
|
62
|
+
"mypy>=1.13",
|
|
63
|
+
"scipy-stubs>=1.13",
|
|
64
|
+
"pytest>=8.3",
|
|
65
|
+
"pytest-cov>=5",
|
|
66
|
+
"pytest-benchmark>=4",
|
|
67
|
+
"hypothesis>=6.112",
|
|
68
|
+
"pre-commit>=4.0",
|
|
69
|
+
"mkdocs-material>=9.5",
|
|
70
|
+
"mkdocstrings[python]>=0.26",
|
|
71
|
+
"types-pyyaml>=6.0.12.20261030",
|
|
72
|
+
"types-openpyxl>=3.1.5.20261017",
|
|
73
|
+
]
|
|
74
|
+
|
|
75
|
+
[tool.ruff]
|
|
76
|
+
line-length = 100
|
|
77
|
+
target-version = "py312"
|
|
78
|
+
src = ["src", "study/src"]
|
|
79
|
+
|
|
80
|
+
[tool.ruff.lint]
|
|
81
|
+
select = ["E", "F", "W", "I", "B", "UP", "NPY", "PLE", "PLW", "PLC", "D"]
|
|
82
|
+
ignore = ["D105", "D107"]
|
|
83
|
+
|
|
84
|
+
[tool.ruff.lint.flake8-bugbear]
|
|
85
|
+
extend-immutable-calls = ["overfitlab.verdict.VerdictConfig"]
|
|
86
|
+
|
|
87
|
+
[tool.ruff.lint.pydocstyle]
|
|
88
|
+
convention = "numpy"
|
|
89
|
+
|
|
90
|
+
[tool.ruff.lint.per-file-ignores]
|
|
91
|
+
"tests/**" = ["D"]
|
|
92
|
+
"study/**" = ["D"]
|
|
93
|
+
"scripts/**" = ["D"]
|
|
94
|
+
# Typer needs its option metadata in argument defaults.
|
|
95
|
+
"**/cli.py" = ["B008"]
|
|
96
|
+
# PyArrow is imported on use, so that import overfitlab stays light (NFR-11).
|
|
97
|
+
"src/overfitlab/triallog.py" = ["PLC0415"]
|
|
98
|
+
|
|
99
|
+
[tool.ruff.format]
|
|
100
|
+
quote-style = "double"
|
|
101
|
+
line-ending = "lf"
|
|
102
|
+
|
|
103
|
+
[tool.mypy]
|
|
104
|
+
python_version = "3.12"
|
|
105
|
+
strict = true
|
|
106
|
+
files = ["src/overfitlab", "study/src"]
|
|
107
|
+
mypy_path = "src:study/src"
|
|
108
|
+
explicit_package_bases = true
|
|
109
|
+
|
|
110
|
+
[[tool.mypy.overrides]]
|
|
111
|
+
module = ["numba.*", "arch.*", "sklearn.*", "pyarrow.*", "plotly.*"]
|
|
112
|
+
ignore_missing_imports = true
|
|
113
|
+
|
|
114
|
+
[tool.pytest.ini_options]
|
|
115
|
+
testpaths = ["tests"]
|
|
116
|
+
addopts = "--strict-markers --import-mode=importlib"
|
|
117
|
+
markers = [
|
|
118
|
+
"golden: numbers transcribed from the original papers",
|
|
119
|
+
"xcheck: cross-checks against the independent arch package",
|
|
120
|
+
"slow: quick versions of the study simulations",
|
|
121
|
+
"data: needs real raw data files (local only)",
|
|
122
|
+
"bench: performance benchmarks (local only)",
|
|
123
|
+
]
|
|
124
|
+
|
|
125
|
+
[tool.coverage.run]
|
|
126
|
+
source_pkgs = ["overfitlab", "overfitlab_study"]
|
|
127
|
+
branch = false
|
|
128
|
+
|
|
129
|
+
[tool.coverage.report]
|
|
130
|
+
exclude_also = ["if TYPE_CHECKING:", "raise NotImplementedError"]
|
|
@@ -0,0 +1,119 @@
|
|
|
1
|
+
"""overfitlab: statistics that separate a real trading signal from a lucky one."""
|
|
2
|
+
|
|
3
|
+
from overfitlab._normal import EULER_GAMMA
|
|
4
|
+
from overfitlab.bootstrap import optimal_block_length, stationary_bootstrap_indices
|
|
5
|
+
from overfitlab.cv import CombinatorialPurgedCV, PurgedKFold, assemble_paths
|
|
6
|
+
from overfitlab.deflated import (
|
|
7
|
+
deflated_sharpe_ratio,
|
|
8
|
+
dsr_from_returns,
|
|
9
|
+
expected_max_sharpe,
|
|
10
|
+
min_backtest_length,
|
|
11
|
+
)
|
|
12
|
+
from overfitlab.factory import StrategySpec, run_strategies, strategy_grid
|
|
13
|
+
from overfitlab.haircut import haircut_sharpe, sharpe_to_tstat
|
|
14
|
+
from overfitlab.pbo import PBOResult, pbo_cscv
|
|
15
|
+
from overfitlab.results import DSRResult, HaircutResult, ReturnMoments
|
|
16
|
+
from overfitlab.sharpe import (
|
|
17
|
+
annualize_sharpe,
|
|
18
|
+
min_track_record_length,
|
|
19
|
+
probabilistic_sharpe_ratio,
|
|
20
|
+
psr_from_returns,
|
|
21
|
+
return_moments,
|
|
22
|
+
sharpe_ratio,
|
|
23
|
+
sharpe_std,
|
|
24
|
+
)
|
|
25
|
+
from overfitlab.snooping import (
|
|
26
|
+
SnoopResult,
|
|
27
|
+
SPAResult,
|
|
28
|
+
StepMResult,
|
|
29
|
+
reality_check,
|
|
30
|
+
romano_wolf_stepdown,
|
|
31
|
+
spa_test,
|
|
32
|
+
)
|
|
33
|
+
from overfitlab.synth import (
|
|
34
|
+
SynthResult,
|
|
35
|
+
block_bootstrap_returns,
|
|
36
|
+
gaussian_noise,
|
|
37
|
+
gbm_prices,
|
|
38
|
+
planted_signal_matrix,
|
|
39
|
+
planted_signal_prices,
|
|
40
|
+
student_t_noise,
|
|
41
|
+
)
|
|
42
|
+
from overfitlab.triallog import (
|
|
43
|
+
TRIAL_LOG_COLUMNS,
|
|
44
|
+
TRIAL_LOG_VERSION,
|
|
45
|
+
TrialLog,
|
|
46
|
+
TrialLogError,
|
|
47
|
+
TrialLogger,
|
|
48
|
+
TrialLogIssue,
|
|
49
|
+
TrialLogReport,
|
|
50
|
+
TrialSharpes,
|
|
51
|
+
add_manual_trial,
|
|
52
|
+
canonical_params_json,
|
|
53
|
+
evaluate_trial_log,
|
|
54
|
+
read_trial_log,
|
|
55
|
+
validate_trial_log,
|
|
56
|
+
)
|
|
57
|
+
from overfitlab.verdict import VerdictConfig, VerdictReport, evaluate
|
|
58
|
+
|
|
59
|
+
__version__ = "0.1.0"
|
|
60
|
+
|
|
61
|
+
__all__ = [
|
|
62
|
+
"EULER_GAMMA",
|
|
63
|
+
"CombinatorialPurgedCV",
|
|
64
|
+
"DSRResult",
|
|
65
|
+
"HaircutResult",
|
|
66
|
+
"PBOResult",
|
|
67
|
+
"PurgedKFold",
|
|
68
|
+
"ReturnMoments",
|
|
69
|
+
"SPAResult",
|
|
70
|
+
"SnoopResult",
|
|
71
|
+
"StepMResult",
|
|
72
|
+
"StrategySpec",
|
|
73
|
+
"SynthResult",
|
|
74
|
+
"TRIAL_LOG_COLUMNS",
|
|
75
|
+
"TRIAL_LOG_VERSION",
|
|
76
|
+
"TrialLog",
|
|
77
|
+
"TrialLogError",
|
|
78
|
+
"TrialLogIssue",
|
|
79
|
+
"TrialLogReport",
|
|
80
|
+
"TrialLogger",
|
|
81
|
+
"TrialSharpes",
|
|
82
|
+
"VerdictConfig",
|
|
83
|
+
"VerdictReport",
|
|
84
|
+
"__version__",
|
|
85
|
+
"add_manual_trial",
|
|
86
|
+
"annualize_sharpe",
|
|
87
|
+
"assemble_paths",
|
|
88
|
+
"block_bootstrap_returns",
|
|
89
|
+
"canonical_params_json",
|
|
90
|
+
"deflated_sharpe_ratio",
|
|
91
|
+
"dsr_from_returns",
|
|
92
|
+
"evaluate",
|
|
93
|
+
"evaluate_trial_log",
|
|
94
|
+
"expected_max_sharpe",
|
|
95
|
+
"gaussian_noise",
|
|
96
|
+
"gbm_prices",
|
|
97
|
+
"haircut_sharpe",
|
|
98
|
+
"min_backtest_length",
|
|
99
|
+
"min_track_record_length",
|
|
100
|
+
"optimal_block_length",
|
|
101
|
+
"pbo_cscv",
|
|
102
|
+
"planted_signal_matrix",
|
|
103
|
+
"planted_signal_prices",
|
|
104
|
+
"probabilistic_sharpe_ratio",
|
|
105
|
+
"psr_from_returns",
|
|
106
|
+
"read_trial_log",
|
|
107
|
+
"reality_check",
|
|
108
|
+
"return_moments",
|
|
109
|
+
"romano_wolf_stepdown",
|
|
110
|
+
"run_strategies",
|
|
111
|
+
"sharpe_ratio",
|
|
112
|
+
"sharpe_std",
|
|
113
|
+
"sharpe_to_tstat",
|
|
114
|
+
"spa_test",
|
|
115
|
+
"stationary_bootstrap_indices",
|
|
116
|
+
"strategy_grid",
|
|
117
|
+
"student_t_noise",
|
|
118
|
+
"validate_trial_log",
|
|
119
|
+
]
|