normalize-tabular-data 0.1.3__tar.gz → 0.1.4__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/PKG-INFO +48 -67
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/README.md +47 -66
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/pyproject.toml +1 -1
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/pyproject.toml.orig +1 -1
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/__init__.py +1 -1
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/LICENSE +0 -0
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/__main__.py +0 -0
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/app.py +0 -0
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/io.py +0 -0
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/ops.py +0 -0
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/screens.py +0 -0
- {normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/widgets.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: normalize-tabular-data
|
|
3
|
-
Version: 0.1.
|
|
3
|
+
Version: 0.1.4
|
|
4
4
|
Summary: TUI for normalizing tabular data with Polars
|
|
5
5
|
Author: David Mertz, Ph.D.
|
|
6
6
|
Author-email: David Mertz, Ph.D. <mertz@gnosis.cx>
|
|
@@ -15,55 +15,77 @@ Requires-Dist: platformdirs>=3.0
|
|
|
15
15
|
Requires-Python: >=3.14
|
|
16
16
|
Description-Content-Type: text/markdown
|
|
17
17
|
|
|
18
|
-
# normalize-tabular-data
|
|
18
|
+
# normalize-tabular-data (NTD)
|
|
19
19
|
|
|
20
20
|
A terminal UI (Textual) for interactively normalizing tabular data, backed by
|
|
21
21
|
[polars](https://pola.rs) for speed and
|
|
22
22
|
[gnosis-date-parser](https://pypi.org/project/gnosis-date-parser/) for fuzzy
|
|
23
23
|
date parsing at Rust speed.
|
|
24
24
|
|
|
25
|
+
NTD also supports purely command-line operations for use in scripting, launched
|
|
26
|
+
with `uvx` with no other requirements that are not dynamically downloaded.
|
|
27
|
+
|
|
25
28
|
Load a file, see a preview, build up a pipeline of normalization operations
|
|
26
29
|
(normalize messy dates, trim whitespace, rename a column, deduplicate,
|
|
27
|
-
combine/split columns, drop columns), then save the
|
|
28
|
-
cleaned result.
|
|
30
|
+
combine/split columns, drop columns), then save the cleaned result.
|
|
29
31
|
|
|
30
|
-
|
|
32
|
+
## Formats
|
|
31
33
|
|
|
32
|
-
|
|
34
|
+
Reads: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`/`.xls` — first sheet).
|
|
35
|
+
Writes: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`).
|
|
33
36
|
|
|
34
|
-
|
|
37
|
+
Large files are previewed with a random sample of 250 rows; every operation
|
|
38
|
+
still runs on the full data.
|
|
35
39
|
|
|
36
|
-
|
|
37
|
-
uv tool install normalize-tabular-data
|
|
38
|
-
# upgrade later with:
|
|
39
|
-
uv tool upgrade normalize-tabular-data
|
|
40
|
-
```
|
|
40
|
+
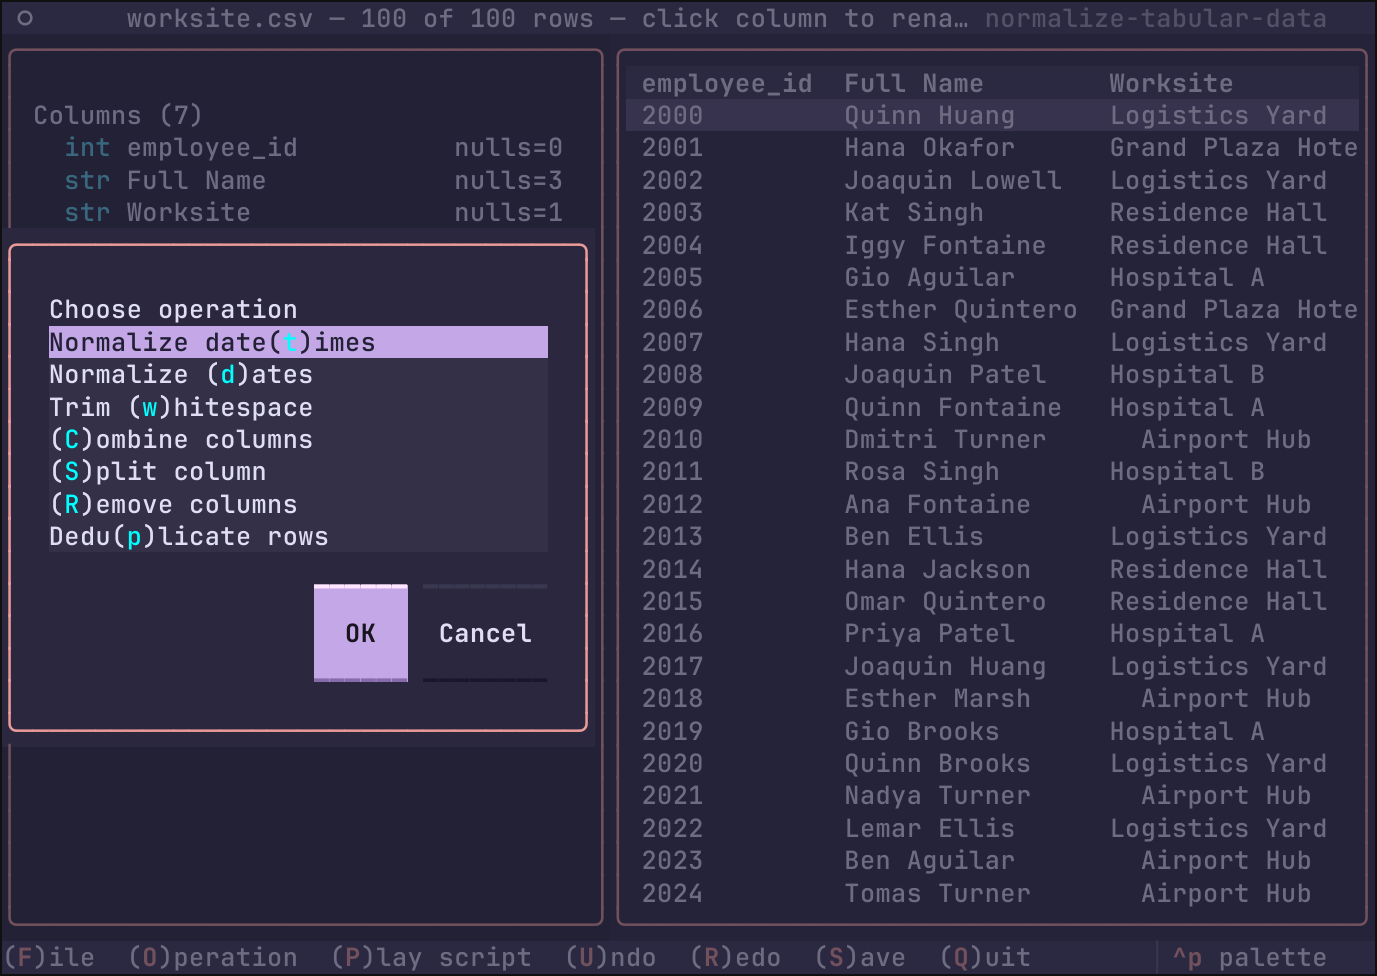
## Running the Text User Interface
|
|
41
41
|
|
|
42
|
-
|
|
42
|
+
|
|
43
43
|
|
|
44
|
-
|
|
44
|
+
Installation and launch options — persistent install, ephemeral `uvx`
|
|
45
|
+
runs, running from a git checkout, the single-file launchers for
|
|
46
|
+
Linux/macOS/Windows, and installing them as desktop icons — are
|
|
47
|
+
described in [docs/running-the-tool.md](docs/running-the-tool.md).
|
|
45
48
|
|
|
46
|
-
|
|
47
|
-
uvx normalize-tabular-data
|
|
48
|
-
# pin a specific version:
|
|
49
|
-
uvx normalize-tabular-data==0.1.1
|
|
50
|
-
```
|
|
49
|
+
## Capabilities in the TUI
|
|
51
50
|
|
|
52
|
-
|
|
51
|
+
Launch with `uvx normalize-tabular-data` (or a launcher). Keys:
|
|
53
52
|
|
|
54
|
-
Within the directory of the cloned repository:
|
|
55
53
|
|
|
56
|
-
|
|
57
|
-
|
|
58
|
-
|
|
54
|
+
| Key | Action |
|
|
55
|
+
|-----|------------------------------|
|
|
56
|
+
| `f` | (F)ile — open a file |
|
|
57
|
+
| `o` | (O)peration — choose an op |
|
|
58
|
+
| `p` | (P)lay script — apply `.ntd` |
|
|
59
|
+
| `u` | (U)ndo last applied step |
|
|
60
|
+
| `r` | (R)edo |
|
|
61
|
+
| `s` | (S)ave the data in a format |
|
|
62
|
+
| `q` | (Q)uit |
|
|
59
63
|
|
|
60
|
-
##
|
|
64
|
+
## Operations
|
|
65
|
+
|
|
66
|
+
- **Normalize date(t)imes** — parse a messy date column of *any* input
|
|
67
|
+
format into canonical UTC datetimes at millisecond resolution;
|
|
68
|
+
unparseable values become null. CSV/TSV/JSONLines export serializes
|
|
69
|
+
datetime columns as second-resolution `year-month-dayThh:mm:ss`
|
|
70
|
+
strings; Parquet and Excel keep the real datetime values.
|
|
71
|
+
- **Normalize (d)ates** — the same match-anything parsing, condensed to
|
|
72
|
+
the UTC calendar date: the column becomes date-only ISO-8601
|
|
73
|
+
(`year-month-day`); unparseable values become null.
|
|
74
|
+
- **Trim whitespace** — strip edges and collapse internal whitespace runs,
|
|
75
|
+
per selected columns.
|
|
76
|
+
- Rename a column — click its header in the preview and type the new name.
|
|
77
|
+
- **Combine columns** — concatenate two or more columns with a separator.
|
|
78
|
+
- **Split column** — break one column into `{col}_1..{col}_k`; a blank
|
|
79
|
+
delimiter splits on runs of whitespace.
|
|
80
|
+
- **Remove columns** — drop selected columns entirely.
|
|
81
|
+
- **Deduplicate rows** — on all or selected columns, keeping first or last.
|
|
82
|
+
|
|
83
|
+
## Command line usage
|
|
61
84
|
|
|
62
85
|
An optional `FILE` argument names a table to open at startup, as if you
|
|
63
86
|
had picked it from the in-app dialog.
|
|
64
87
|
|
|
65
88
|
```bash
|
|
66
|
-
normalize-tabular-data data/members.csv # or with uvx/uv run
|
|
67
89
|
uvx normalize-tabular-data data/members.tsv
|
|
68
90
|
```
|
|
69
91
|
|
|
@@ -104,47 +126,6 @@ to stdout itself and the step lines are suppressed, so stdout carries
|
|
|
104
126
|
only the data. After a successful run the confirmation line goes to
|
|
105
127
|
stderr.
|
|
106
128
|
|
|
107
|
-
## Usage
|
|
108
|
-
|
|
109
|
-
Launch with `normalize-tabular-data`. Keys:
|
|
110
|
-
|
|
111
|
-
| Key | Action |
|
|
112
|
-
|-----|------------------------------|
|
|
113
|
-
| `f` | (F)ile — open a file |
|
|
114
|
-
| `o` | (O)peration — choose an op |
|
|
115
|
-
| `p` | (P)lay script — apply `.ntd` |
|
|
116
|
-
| `u` | (U)ndo last applied step |
|
|
117
|
-
| `r` | (R)edo |
|
|
118
|
-
| `s` | (S)ave the data in a format |
|
|
119
|
-
| `q` | (Q)uit |
|
|
120
|
-
|
|
121
|
-
## Operations
|
|
122
|
-
|
|
123
|
-
- **Normalize date(t)imes** — parse a messy date column of *any* input
|
|
124
|
-
format into canonical UTC datetimes at millisecond resolution;
|
|
125
|
-
unparseable values become null. CSV/TSV/JSONLines export serializes
|
|
126
|
-
datetime columns as second-resolution `year-month-dayThh:mm:ss`
|
|
127
|
-
strings; Parquet and Excel keep the real datetime values.
|
|
128
|
-
- **Normalize (d)ates** — the same match-anything parsing, condensed to
|
|
129
|
-
the UTC calendar date: the column becomes date-only ISO-8601
|
|
130
|
-
(`year-month-day`); unparseable values become null.
|
|
131
|
-
- **Trim whitespace** — strip edges and collapse internal whitespace runs,
|
|
132
|
-
per selected columns.
|
|
133
|
-
- Rename a column — click its header in the preview and type the new name.
|
|
134
|
-
- **Combine columns** — concatenate two or more columns with a separator.
|
|
135
|
-
- **Split column** — break one column into `{col}_1..{col}_k`; a blank
|
|
136
|
-
delimiter splits on runs of whitespace.
|
|
137
|
-
- **Remove columns** — drop selected columns entirely.
|
|
138
|
-
- **Deduplicate rows** — on all or selected columns, keeping first or last.
|
|
139
|
-
|
|
140
|
-
## Formats
|
|
141
|
-
|
|
142
|
-
Reads: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`/`.xls` — first sheet).
|
|
143
|
-
Writes: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`).
|
|
144
|
-
|
|
145
|
-
Large files are previewed with a random sample of 250 rows; every operation
|
|
146
|
-
still runs on the full data.
|
|
147
|
-
|
|
148
129
|
## Operation scripts (`.ntd`)
|
|
149
130
|
|
|
150
131
|
Every open file keeps an internal log of the operations performed on it. When
|
|
@@ -1,52 +1,74 @@
|
|
|
1
|
-
# normalize-tabular-data
|
|
1
|
+
# normalize-tabular-data (NTD)
|
|
2
2
|
|
|
3
3
|
A terminal UI (Textual) for interactively normalizing tabular data, backed by
|
|
4
4
|
[polars](https://pola.rs) for speed and
|
|
5
5
|
[gnosis-date-parser](https://pypi.org/project/gnosis-date-parser/) for fuzzy
|
|
6
6
|
date parsing at Rust speed.
|
|
7
7
|
|
|
8
|
+
NTD also supports purely command-line operations for use in scripting, launched
|
|
9
|
+
with `uvx` with no other requirements that are not dynamically downloaded.
|
|
10
|
+
|
|
8
11
|
Load a file, see a preview, build up a pipeline of normalization operations
|
|
9
12
|
(normalize messy dates, trim whitespace, rename a column, deduplicate,
|
|
10
|
-
combine/split columns, drop columns), then save the
|
|
11
|
-
cleaned result.
|
|
13
|
+
combine/split columns, drop columns), then save the cleaned result.
|
|
12
14
|
|
|
13
|
-
|
|
15
|
+
## Formats
|
|
14
16
|
|
|
15
|
-
|
|
17
|
+
Reads: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`/`.xls` — first sheet).
|
|
18
|
+
Writes: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`).
|
|
16
19
|
|
|
17
|
-
|
|
20
|
+
Large files are previewed with a random sample of 250 rows; every operation
|
|
21
|
+
still runs on the full data.
|
|
18
22
|
|
|
19
|
-
|
|
20
|
-
uv tool install normalize-tabular-data
|
|
21
|
-
# upgrade later with:
|
|
22
|
-
uv tool upgrade normalize-tabular-data
|
|
23
|
-
```
|
|
23
|
+
## Running the Text User Interface
|
|
24
24
|
|
|
25
|
-
|
|
25
|
+

|
|
26
26
|
|
|
27
|
-
|
|
27
|
+
Installation and launch options — persistent install, ephemeral `uvx`
|
|
28
|
+
runs, running from a git checkout, the single-file launchers for
|
|
29
|
+
Linux/macOS/Windows, and installing them as desktop icons — are
|
|
30
|
+
described in [docs/running-the-tool.md](docs/running-the-tool.md).
|
|
28
31
|
|
|
29
|
-
|
|
30
|
-
uvx normalize-tabular-data
|
|
31
|
-
# pin a specific version:
|
|
32
|
-
uvx normalize-tabular-data==0.1.1
|
|
33
|
-
```
|
|
32
|
+
## Capabilities in the TUI
|
|
34
33
|
|
|
35
|
-
|
|
34
|
+
Launch with `uvx normalize-tabular-data` (or a launcher). Keys:
|
|
36
35
|
|
|
37
|
-
Within the directory of the cloned repository:
|
|
38
36
|
|
|
39
|
-
|
|
40
|
-
|
|
41
|
-
|
|
37
|
+
| Key | Action |
|
|
38
|
+
|-----|------------------------------|
|
|
39
|
+
| `f` | (F)ile — open a file |
|
|
40
|
+
| `o` | (O)peration — choose an op |
|
|
41
|
+
| `p` | (P)lay script — apply `.ntd` |
|
|
42
|
+
| `u` | (U)ndo last applied step |
|
|
43
|
+
| `r` | (R)edo |
|
|
44
|
+
| `s` | (S)ave the data in a format |
|
|
45
|
+
| `q` | (Q)uit |
|
|
42
46
|
|
|
43
|
-
##
|
|
47
|
+
## Operations
|
|
48
|
+
|
|
49
|
+
- **Normalize date(t)imes** — parse a messy date column of *any* input
|
|
50
|
+
format into canonical UTC datetimes at millisecond resolution;
|
|
51
|
+
unparseable values become null. CSV/TSV/JSONLines export serializes
|
|
52
|
+
datetime columns as second-resolution `year-month-dayThh:mm:ss`
|
|
53
|
+
strings; Parquet and Excel keep the real datetime values.
|
|
54
|
+
- **Normalize (d)ates** — the same match-anything parsing, condensed to
|
|
55
|
+
the UTC calendar date: the column becomes date-only ISO-8601
|
|
56
|
+
(`year-month-day`); unparseable values become null.
|
|
57
|
+
- **Trim whitespace** — strip edges and collapse internal whitespace runs,
|
|
58
|
+
per selected columns.
|
|
59
|
+
- Rename a column — click its header in the preview and type the new name.
|
|
60
|
+
- **Combine columns** — concatenate two or more columns with a separator.
|
|
61
|
+
- **Split column** — break one column into `{col}_1..{col}_k`; a blank
|
|
62
|
+
delimiter splits on runs of whitespace.
|
|
63
|
+
- **Remove columns** — drop selected columns entirely.
|
|
64
|
+
- **Deduplicate rows** — on all or selected columns, keeping first or last.
|
|
65
|
+
|
|
66
|
+
## Command line usage
|
|
44
67
|
|
|
45
68
|
An optional `FILE` argument names a table to open at startup, as if you
|
|
46
69
|
had picked it from the in-app dialog.
|
|
47
70
|
|
|
48
71
|
```bash
|
|
49
|
-
normalize-tabular-data data/members.csv # or with uvx/uv run
|
|
50
72
|
uvx normalize-tabular-data data/members.tsv
|
|
51
73
|
```
|
|
52
74
|
|
|
@@ -87,47 +109,6 @@ to stdout itself and the step lines are suppressed, so stdout carries
|
|
|
87
109
|
only the data. After a successful run the confirmation line goes to
|
|
88
110
|
stderr.
|
|
89
111
|
|
|
90
|
-
## Usage
|
|
91
|
-
|
|
92
|
-
Launch with `normalize-tabular-data`. Keys:
|
|
93
|
-
|
|
94
|
-
| Key | Action |
|
|
95
|
-
|-----|------------------------------|
|
|
96
|
-
| `f` | (F)ile — open a file |
|
|
97
|
-
| `o` | (O)peration — choose an op |
|
|
98
|
-
| `p` | (P)lay script — apply `.ntd` |
|
|
99
|
-
| `u` | (U)ndo last applied step |
|
|
100
|
-
| `r` | (R)edo |
|
|
101
|
-
| `s` | (S)ave the data in a format |
|
|
102
|
-
| `q` | (Q)uit |
|
|
103
|
-
|
|
104
|
-
## Operations
|
|
105
|
-
|
|
106
|
-
- **Normalize date(t)imes** — parse a messy date column of *any* input
|
|
107
|
-
format into canonical UTC datetimes at millisecond resolution;
|
|
108
|
-
unparseable values become null. CSV/TSV/JSONLines export serializes
|
|
109
|
-
datetime columns as second-resolution `year-month-dayThh:mm:ss`
|
|
110
|
-
strings; Parquet and Excel keep the real datetime values.
|
|
111
|
-
- **Normalize (d)ates** — the same match-anything parsing, condensed to
|
|
112
|
-
the UTC calendar date: the column becomes date-only ISO-8601
|
|
113
|
-
(`year-month-day`); unparseable values become null.
|
|
114
|
-
- **Trim whitespace** — strip edges and collapse internal whitespace runs,
|
|
115
|
-
per selected columns.
|
|
116
|
-
- Rename a column — click its header in the preview and type the new name.
|
|
117
|
-
- **Combine columns** — concatenate two or more columns with a separator.
|
|
118
|
-
- **Split column** — break one column into `{col}_1..{col}_k`; a blank
|
|
119
|
-
delimiter splits on runs of whitespace.
|
|
120
|
-
- **Remove columns** — drop selected columns entirely.
|
|
121
|
-
- **Deduplicate rows** — on all or selected columns, keeping first or last.
|
|
122
|
-
|
|
123
|
-
## Formats
|
|
124
|
-
|
|
125
|
-
Reads: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`/`.xls` — first sheet).
|
|
126
|
-
Writes: CSV, TSV, JSON lines, Parquet, Excel (`.xlsx`).
|
|
127
|
-
|
|
128
|
-
Large files are previewed with a random sample of 250 rows; every operation
|
|
129
|
-
still runs on the full data.
|
|
130
|
-
|
|
131
112
|
## Operation scripts (`.ntd`)
|
|
132
113
|
|
|
133
114
|
Every open file keeps an internal log of the operations performed on it. When
|
|
File without changes
|
{normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/__main__.py
RENAMED
|
File without changes
|
{normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/app.py
RENAMED
|
File without changes
|
{normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/io.py
RENAMED
|
File without changes
|
{normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/ops.py
RENAMED
|
File without changes
|
{normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/screens.py
RENAMED
|
File without changes
|
{normalize_tabular_data-0.1.3 → normalize_tabular_data-0.1.4}/src/normalize_tabular_data/widgets.py
RENAMED
|
File without changes
|