nnscope 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- nnscope-0.1.0/LICENSE +21 -0
- nnscope-0.1.0/PKG-INFO +164 -0
- nnscope-0.1.0/README.md +138 -0
- nnscope-0.1.0/pyproject.toml +47 -0
- nnscope-0.1.0/pyproject.toml.orig +40 -0
- nnscope-0.1.0/src/nnscope/__init__.py +12 -0
- nnscope-0.1.0/src/nnscope/adapters.py +233 -0
- nnscope-0.1.0/src/nnscope/export.py +168 -0
- nnscope-0.1.0/src/nnscope/insights.py +102 -0
- nnscope-0.1.0/src/nnscope/py.typed +0 -0
- nnscope-0.1.0/src/nnscope/scope.py +231 -0
- nnscope-0.1.0/src/nnscope/server.py +94 -0
- nnscope-0.1.0/src/nnscope/static/index.html +856 -0
- nnscope-0.1.0/src/nnscope/stats.py +112 -0
nnscope-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
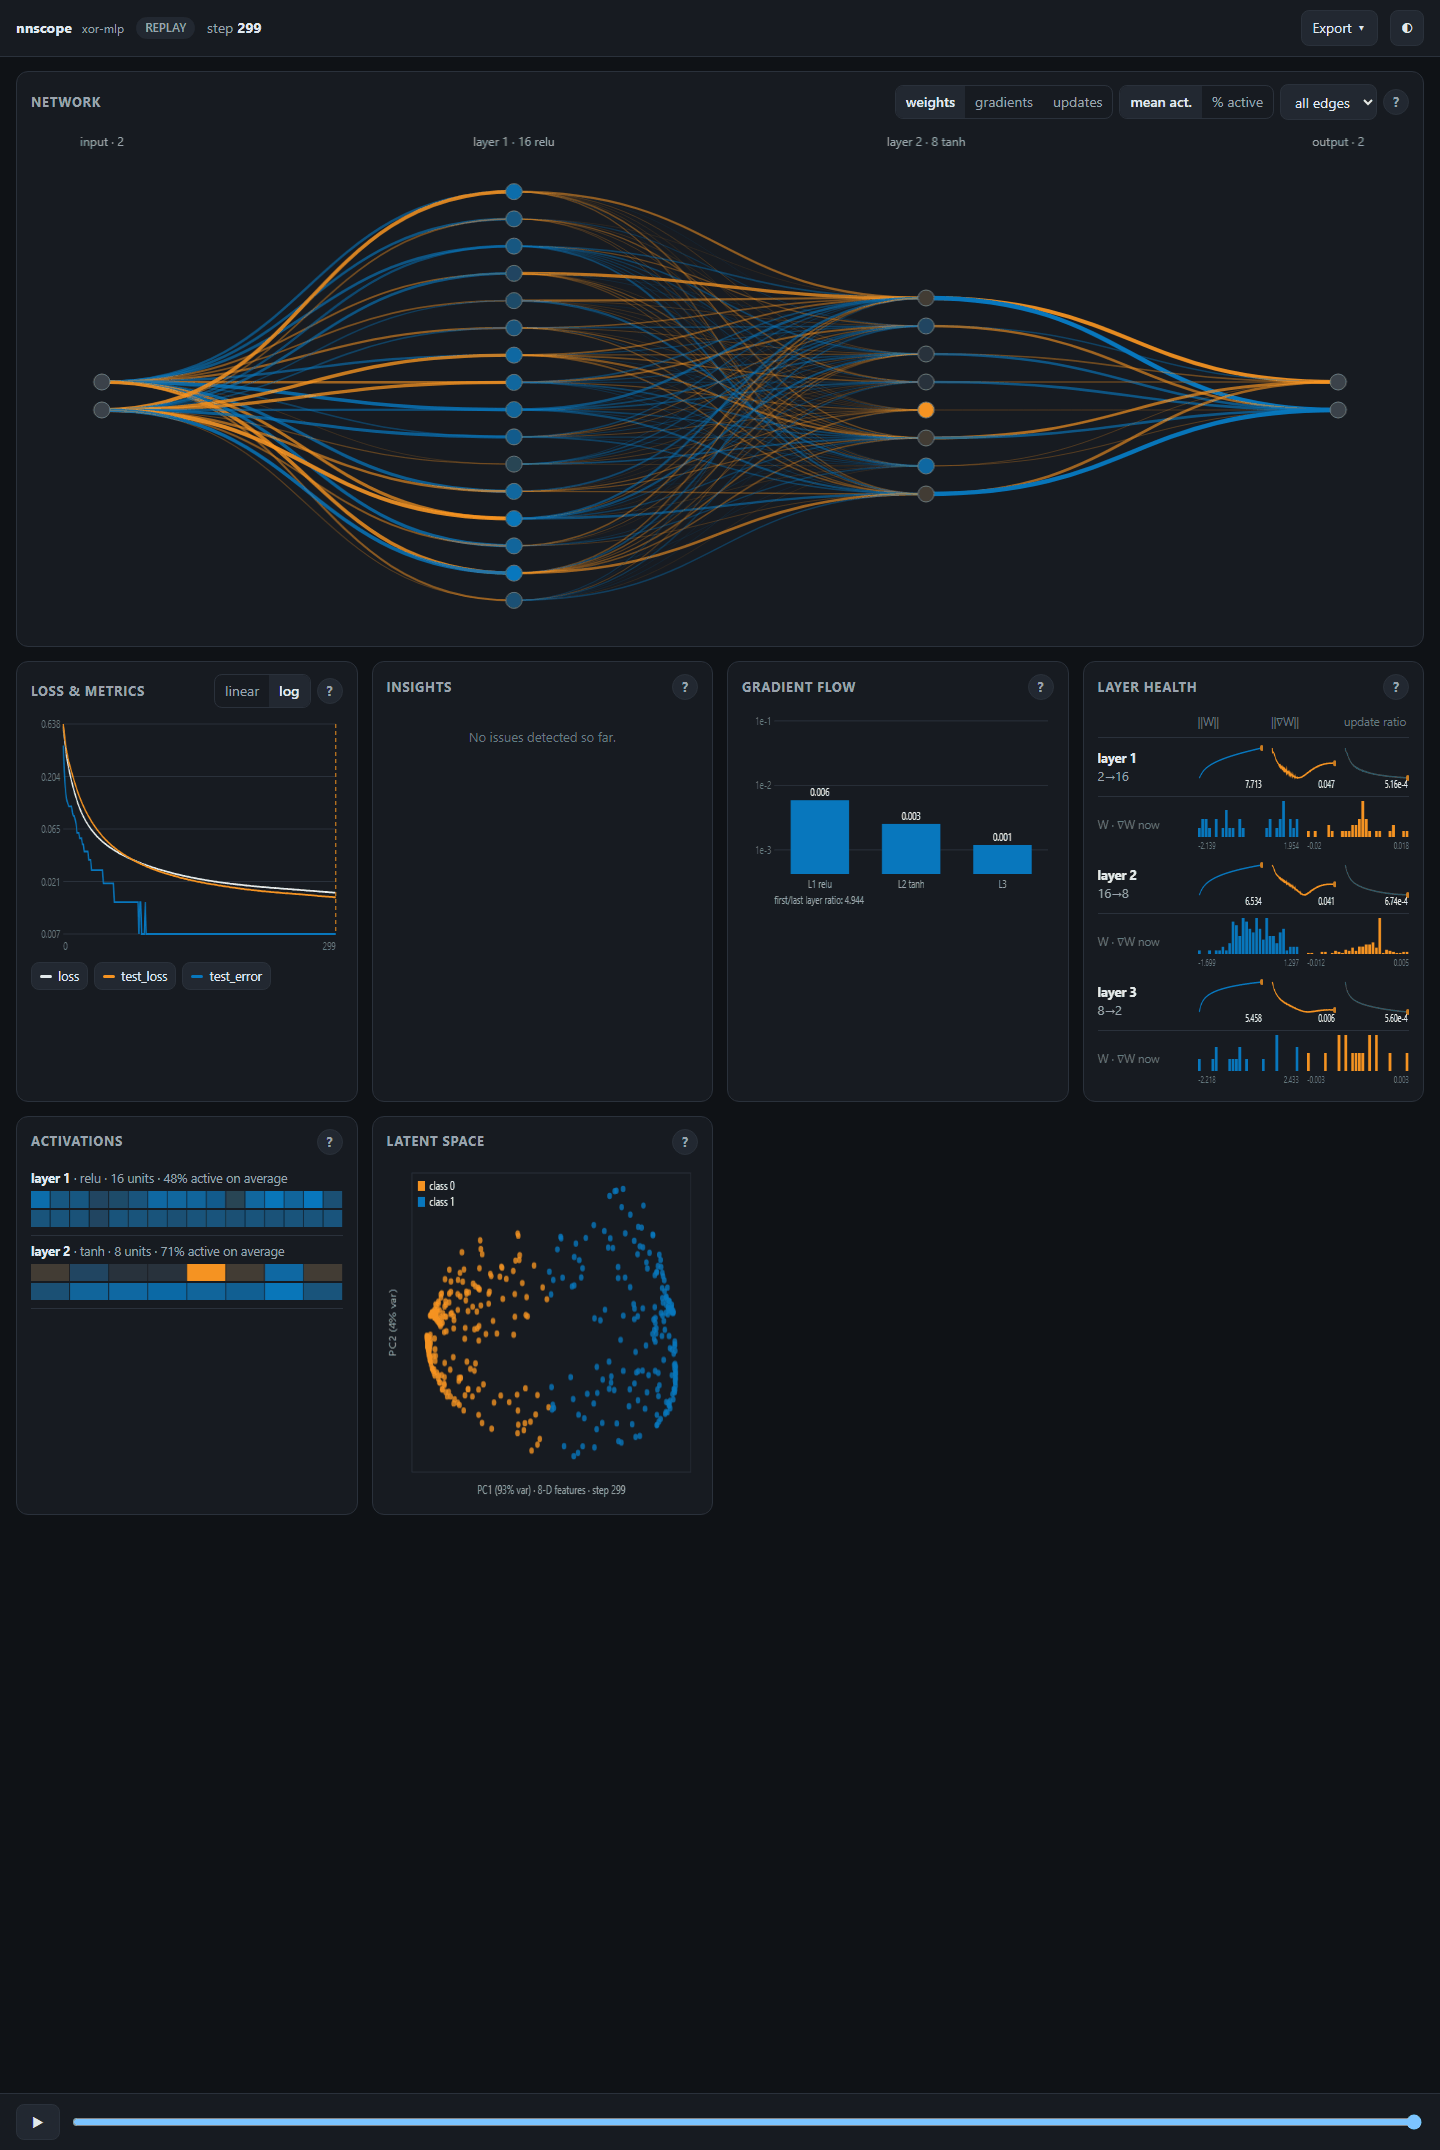
2
|
+
|
|
3
|
+
Copyright (c) 2026 Michael
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
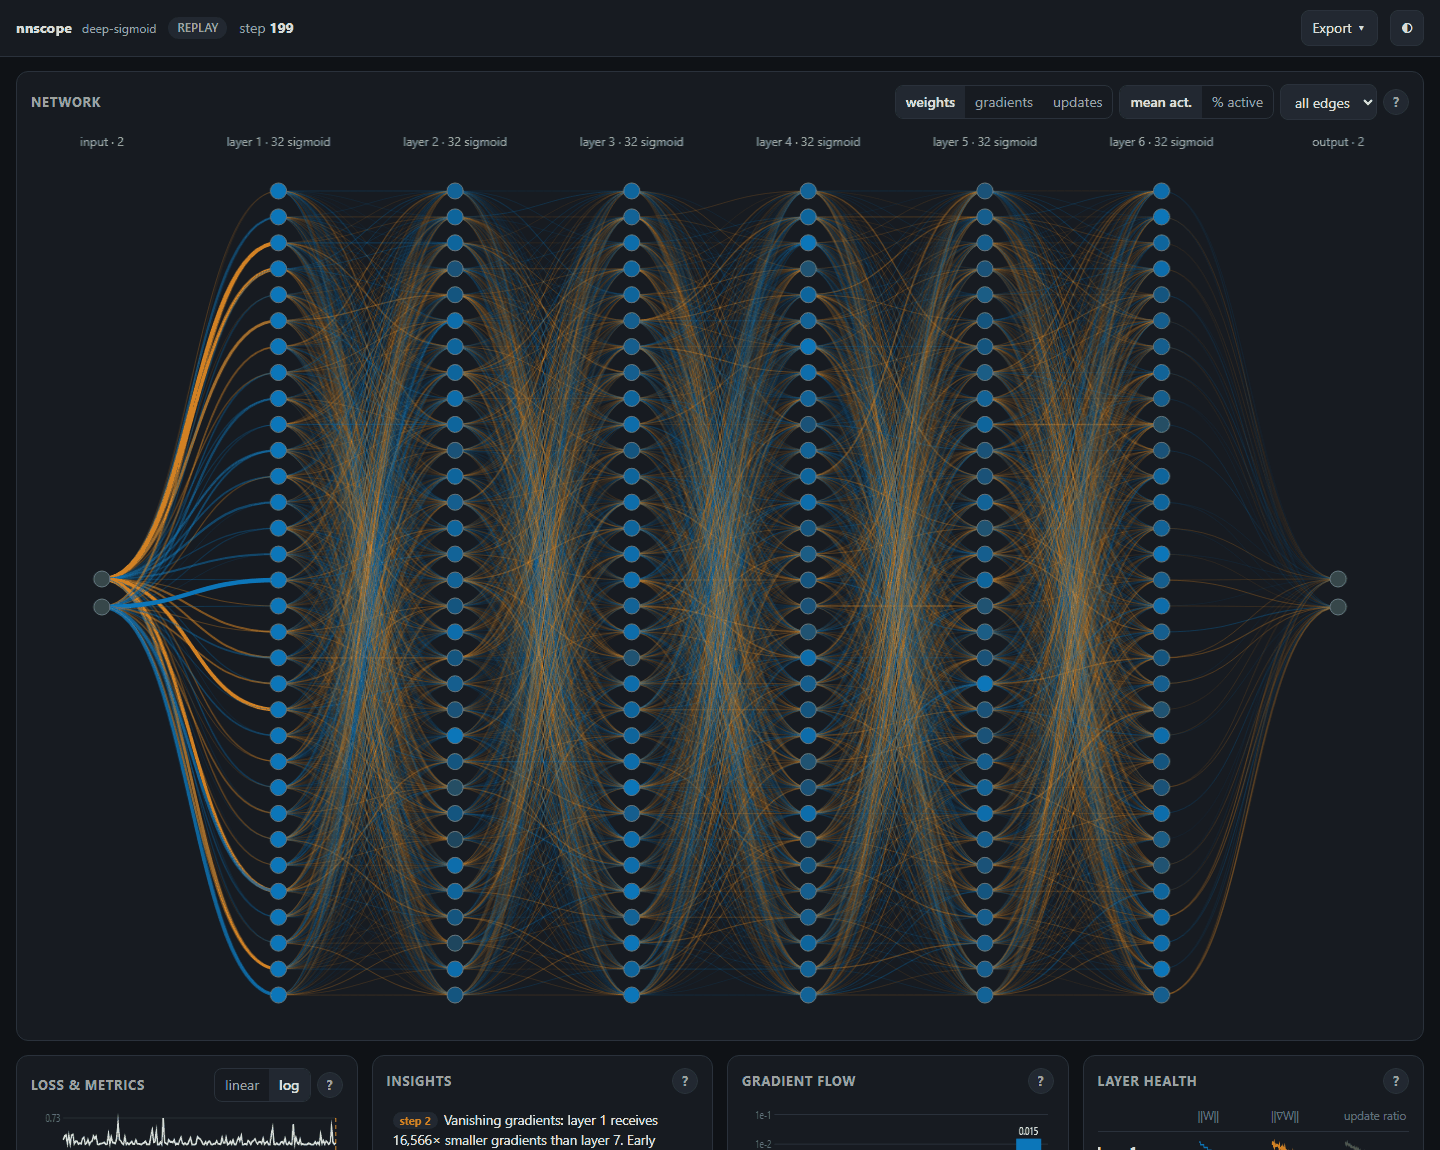
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
nnscope-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,164 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: nnscope
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Watch your NumPy neural network learn: a live, replayable dashboard for weights, gradients, activations and loss.
|
|
5
|
+
Keywords: neural-network,numpy,visualization,backpropagation,education,deep-learning,dashboard
|
|
6
|
+
Author: michaelks
|
|
7
|
+
Author-email: michaelks <michaelks540@gmail.com>
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Classifier: Development Status :: 3 - Alpha
|
|
11
|
+
Classifier: Intended Audience :: Education
|
|
12
|
+
Classifier: Intended Audience :: Science/Research
|
|
13
|
+
Classifier: Operating System :: OS Independent
|
|
14
|
+
Classifier: Programming Language :: Python :: 3
|
|
15
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
16
|
+
Classifier: Topic :: Scientific/Engineering :: Visualization
|
|
17
|
+
Requires-Dist: numpy>=1.21
|
|
18
|
+
Requires-Dist: matplotlib>=3.5 ; extra == 'png'
|
|
19
|
+
Requires-Python: >=3.9
|
|
20
|
+
Project-URL: Homepage, https://github.com/Ashurali/nnscope
|
|
21
|
+
Project-URL: Repository, https://github.com/Ashurali/nnscope
|
|
22
|
+
Project-URL: Issues, https://github.com/Ashurali/nnscope/issues
|
|
23
|
+
Project-URL: Changelog, https://github.com/Ashurali/nnscope/blob/master/CHANGELOG.md
|
|
24
|
+
Provides-Extra: png
|
|
25
|
+
Description-Content-Type: text/markdown
|
|
26
|
+
|
|
27
|
+
# nnscope
|
|
28
|
+
|
|
29
|
+
**Watch your NumPy neural network learn.** Add one line to the training loop of a network you wrote yourself, and nnscope
|
|
30
|
+
shows it live in your browser: every weight, every gradient, every activation, the loss, and plain-language hints about
|
|
31
|
+
what is going on. Afterwards you get a standalone HTML replay you can scrub through, share, or export as images.
|
|
32
|
+
|
|
33
|
+
It was built for students implementing neural networks **from scratch** (forward pass, backprop and SGD in NumPy)
|
|
34
|
+
who want to *see* what their code does: gradients flowing backwards, ReLUs dying, sigmoids saturating, a hidden layer slowly
|
|
35
|
+
learning to separate the classes.
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
|
|
39
|
+
- **Zero setup:** depends only on NumPy. The dashboard is one self-contained HTML file served by Python's standard library.
|
|
40
|
+
- **Works with your code:** auto-detects common NumPy model layouts, or pass plain arrays.
|
|
41
|
+
- **Live and replay:** a live view while training, then `save_html()` for an offline replay with a timeline slider.
|
|
42
|
+
- **Explains itself:** every panel has a (?) with the math behind it, and an insights feed diagnoses common problems.
|
|
43
|
+
- **Responsive:** works on a phone (the network turns vertical), light and dark themes.
|
|
44
|
+
|
|
45
|
+
## Install
|
|
46
|
+
|
|
47
|
+
```bash
|
|
48
|
+
pip install nnscope # NumPy is the only dependency
|
|
49
|
+
pip install "nnscope[png]" # optional: PNG snapshots from Python via matplotlib
|
|
50
|
+
```
|
|
51
|
+
|
|
52
|
+
## Quickstart
|
|
53
|
+
|
|
54
|
+
```python
|
|
55
|
+
import nnscope
|
|
56
|
+
|
|
57
|
+
scope = nnscope.Scope("my-mlp") # opens http://127.0.0.1:8765 in your browser
|
|
58
|
+
for epoch in range(epochs):
|
|
59
|
+
... # your own forward pass, backprop and SGD step
|
|
60
|
+
scope.log(epoch, model=model, loss=train_loss, metrics={"test_loss": test_loss})
|
|
61
|
+
|
|
62
|
+
scope.save_html("run.html") # standalone replay, no server needed
|
|
63
|
+
scope.snapshot("run.svg") # network structure + loss curve as an image
|
|
64
|
+
scope.wait() # keep the live page up until Ctrl+C
|
|
65
|
+
```
|
|
66
|
+
|
|
67
|
+
In a Jupyter notebook, `scope.show()` puts the live dashboard inline. Use `nnscope.Scope(..., live=False)` to only record
|
|
68
|
+
(for `save_html` / `snapshot`).
|
|
69
|
+
|
|
70
|
+
## Connecting your network
|
|
71
|
+
|
|
72
|
+
nnscope never runs your network; it only **reads arrays you already have**.
|
|
73
|
+
|
|
74
|
+
**1. A model object (auto-detected).** Any object with a `.layers` list whose dense layers expose weights and biases,
|
|
75
|
+
optionally with their gradients:
|
|
76
|
+
|
|
77
|
+
| what | attribute names tried |
|
|
78
|
+
|---|---|
|
|
79
|
+
| weights | `W`, `weight`, `weights`, `kernel` |
|
|
80
|
+
| biases | `b`, `bias` |
|
|
81
|
+
| gradients | `dW`, `grad_W`, `W_grad`, `dweight`, … and `db`, `grad_b`, … |
|
|
82
|
+
| cached input (→ activation stats of the previous layer) | `x`, `input`, `inputs`, `a_prev` |
|
|
83
|
+
|
|
84
|
+
Layers without weights are recognised as activations by class name (`ReLU`, `Tanh`, `Sigmoid`, `LeakyReLU`, …), so the graph
|
|
85
|
+
shows `relu`, `tanh`, … on each layer. CS231n-style parameter dicts (`{"W1": …, "b1": …}` plus a matching `grads` dict)
|
|
86
|
+
and lists of `(W, b)` pairs work too.
|
|
87
|
+
|
|
88
|
+
**2. Plain arrays.** No model object needed:
|
|
89
|
+
|
|
90
|
+
```python
|
|
91
|
+
scope.log(step, weights=[W1, W2], biases=[b1, b2], grads=[dW1, dW2], loss=loss)
|
|
92
|
+
```
|
|
93
|
+
|
|
94
|
+
Both `x @ W` (`W` is `(in, out)`) and `W @ x` (`W` is `(out, in)`) conventions are detected from how the shapes chain. Force
|
|
95
|
+
one with `Scope(layout="in_out")` or `layout="out_in"` if a network is ambiguous (e.g. every layer square).
|
|
96
|
+
|
|
97
|
+
**Optional extras for richer views:**
|
|
98
|
+
|
|
99
|
+
```python
|
|
100
|
+
scope.log(step, model=model, loss=loss,
|
|
101
|
+
activations=[a1, a2], # per-layer outputs on a batch → activation statistics
|
|
102
|
+
deltas=[d1, d2, d3], # per-layer ∂L/∂z on a batch → shown in the gradient-flow panel
|
|
103
|
+
latent=z, labels=y) # features of any layer → latent-space scatter
|
|
104
|
+
```
|
|
105
|
+
|
|
106
|
+
## How to read the dashboard
|
|
107
|
+
|
|
108
|
+
| Panel | What it shows | What to look for |
|
|
109
|
+
|---|---|---|
|
|
110
|
+
| **Network** | Neurons (circles) and weights (lines): blue positive, orange negative, thickness ∝ \|w\|. Toggle the lines to **gradients** ∂L/∂w or **updates** Δw, and the node colour to mean activation or % active. | Click a neuron: the **inspector** shows z = Σ wᵢ aᵢ + b with the real numbers from your batch, its strongest inputs, their gradients and how they changed. Dead ReLUs are ringed in red. |
|
|
111
|
+
| **Loss & metrics** | Every scalar you log over time (log or linear scale). | Spikes: learning rate too high. Test loss rising while training loss falls: overfitting. |
|
|
112
|
+
| **Insights** | Plain-language diagnoses, each at the step where it appeared. Click to jump there. | Vanishing/exploding gradients, dead or saturated units, learning rate too high/low, overfitting. |
|
|
113
|
+
| **Gradient flow** | Mean \|∂L/∂W\| per layer, input → output, log scale. | Bars shrinking towards the input = vanishing gradients (e.g. deep sigmoid nets). |
|
|
114
|
+
| **Layer health** | ‖W‖, ‖∇W‖ and the update ratio ‖ΔW‖/‖W‖ per layer over time, plus W and ∇W histograms. | Update ratio ≈ 10⁻³ per SGD step is healthy; ≈ 10⁻¹ is too high. |
|
|
115
|
+
| **Activations** | Per neuron: mean activation and fraction of samples where it is active. | Neurons at 0 % active pass no gradient back and have stopped learning. |
|
|
116
|
+
| **Latent space** | Any layer's features (PCA if wider than 2), coloured by label, along the timeline. | Classes starting mixed and ending linearly separable: the network is building a representation. |
|
|
117
|
+
|
|
118
|
+
Use the **timeline** at the bottom (or ← → and space) to replay training. **Export** saves the network (SVG/PNG), the loss curve,
|
|
119
|
+
the whole dashboard (PNG) or the raw run data (JSON).
|
|
120
|
+
|
|
121
|
+
|
|
122
|
+
|
|
123
|
+
## Examples
|
|
124
|
+
|
|
125
|
+
The [`examples/`](https://github.com/Ashurali/nnscope/tree/master/examples) folder uses a tiny homework-style NumPy MLP ([`_mlp.py`](https://github.com/Ashurali/nnscope/blob/master/examples/_mlp.py)). Run them from that folder;
|
|
126
|
+
add `--no-open` to skip opening a browser tab, or `--headless` to only write `runs/*.html` and `runs/*.svg`.
|
|
127
|
+
|
|
128
|
+
| script | story |
|
|
129
|
+
|---|---|
|
|
130
|
+
| `01_quickstart_xor.py` | the basics: an MLP on XOR-like data, live |
|
|
131
|
+
| `02_plain_arrays.py` | no model object: raw `W1, b1, W2, b2`, hand-written backprop, `deltas=` |
|
|
132
|
+
| `03_latent_bottleneck.py --k 2` | watch a k-unit bottleneck layer separate two classes (try `--k 32`) |
|
|
133
|
+
| `04_vanishing_gradients.py --act sigmoid` | deep sigmoid net: gradients vanish, the insight explains why (compare `--act relu`) |
|
|
134
|
+
| `05_inr_spectral_bias.py [--fourier]` | fit an image f(x, y) → rgb: raw coordinates plateau, Fourier features keep improving |
|
|
135
|
+
|
|
136
|
+
## API
|
|
137
|
+
|
|
138
|
+
```python
|
|
139
|
+
nnscope.Scope(name="run", *, live=True, port=8765, host="127.0.0.1", open_browser=True, max_neurons=32,
|
|
140
|
+
snapshot_every=None, max_snapshots=300, max_records=5000, layout="auto", latent_points=1000, quiet=False)
|
|
141
|
+
```
|
|
142
|
+
|
|
143
|
+
- `log(step=None, *, model=None, loss=None, metrics=None, weights=None, biases=None, grads=None, bias_grads=None, activations=None, deltas=None, latent=None, labels=None, snapshot=None)`
|
|
144
|
+
- `save_html(path)`: standalone replay. `snapshot(path, step=None)`: `.svg` (no dependencies) or `.png` (matplotlib).
|
|
145
|
+
- `show(height=820)`: Jupyter IFrame. `wait()`: serve until Ctrl+C. `close()`; also usable as a context manager.
|
|
146
|
+
- `data()`: everything recorded so far as a JSON-serialisable dict.
|
|
147
|
+
|
|
148
|
+
**Keeping it light.** Scalars are recorded at every `log`; full snapshots (edges, histograms, latent points) are thinned
|
|
149
|
+
adaptively so a run keeps at most `max_snapshots` of them. Layers wider than `max_neurons` draw an evenly spaced subset
|
|
150
|
+
(statistics always use all neurons). The live stream batches updates to about 10 per second.
|
|
151
|
+
|
|
152
|
+
**Limitations.** Dense (fully-connected) layers only for now; convolutional layers are not drawn. The server binds to
|
|
153
|
+
localhost by default.
|
|
154
|
+
|
|
155
|
+
## Development
|
|
156
|
+
|
|
157
|
+
```bash
|
|
158
|
+
uv sync --dev
|
|
159
|
+
uv run --dev pytest
|
|
160
|
+
```
|
|
161
|
+
|
|
162
|
+
## License
|
|
163
|
+
|
|
164
|
+
MIT
|
nnscope-0.1.0/README.md
ADDED
|
@@ -0,0 +1,138 @@
|
|
|
1
|
+
# nnscope
|
|
2
|
+
|
|
3
|
+
**Watch your NumPy neural network learn.** Add one line to the training loop of a network you wrote yourself, and nnscope
|
|
4
|
+
shows it live in your browser: every weight, every gradient, every activation, the loss, and plain-language hints about
|
|
5
|
+
what is going on. Afterwards you get a standalone HTML replay you can scrub through, share, or export as images.
|
|
6
|
+
|
|
7
|
+
It was built for students implementing neural networks **from scratch** (forward pass, backprop and SGD in NumPy)
|
|
8
|
+
who want to *see* what their code does: gradients flowing backwards, ReLUs dying, sigmoids saturating, a hidden layer slowly
|
|
9
|
+
learning to separate the classes.
|
|
10
|
+
|
|
11
|
+

|
|
12
|
+
|
|
13
|
+
- **Zero setup:** depends only on NumPy. The dashboard is one self-contained HTML file served by Python's standard library.
|
|
14
|
+
- **Works with your code:** auto-detects common NumPy model layouts, or pass plain arrays.
|
|
15
|
+
- **Live and replay:** a live view while training, then `save_html()` for an offline replay with a timeline slider.
|
|
16
|
+
- **Explains itself:** every panel has a (?) with the math behind it, and an insights feed diagnoses common problems.
|
|
17
|
+
- **Responsive:** works on a phone (the network turns vertical), light and dark themes.
|
|
18
|
+
|
|
19
|
+
## Install
|
|
20
|
+
|
|
21
|
+
```bash
|
|
22
|
+
pip install nnscope # NumPy is the only dependency
|
|
23
|
+
pip install "nnscope[png]" # optional: PNG snapshots from Python via matplotlib
|
|
24
|
+
```
|
|
25
|
+
|
|
26
|
+
## Quickstart
|
|
27
|
+
|
|
28
|
+
```python
|
|
29
|
+
import nnscope
|
|
30
|
+
|
|
31
|
+
scope = nnscope.Scope("my-mlp") # opens http://127.0.0.1:8765 in your browser
|
|
32
|
+
for epoch in range(epochs):
|
|
33
|
+
... # your own forward pass, backprop and SGD step
|
|
34
|
+
scope.log(epoch, model=model, loss=train_loss, metrics={"test_loss": test_loss})
|
|
35
|
+
|
|
36
|
+
scope.save_html("run.html") # standalone replay, no server needed
|
|
37
|
+
scope.snapshot("run.svg") # network structure + loss curve as an image
|
|
38
|
+
scope.wait() # keep the live page up until Ctrl+C
|
|
39
|
+
```
|
|
40
|
+
|
|
41
|
+
In a Jupyter notebook, `scope.show()` puts the live dashboard inline. Use `nnscope.Scope(..., live=False)` to only record
|
|
42
|
+
(for `save_html` / `snapshot`).
|
|
43
|
+
|
|
44
|
+
## Connecting your network
|
|
45
|
+
|
|
46
|
+
nnscope never runs your network; it only **reads arrays you already have**.
|
|
47
|
+
|
|
48
|
+
**1. A model object (auto-detected).** Any object with a `.layers` list whose dense layers expose weights and biases,
|
|
49
|
+
optionally with their gradients:
|
|
50
|
+
|
|
51
|
+
| what | attribute names tried |
|
|
52
|
+
|---|---|
|
|
53
|
+
| weights | `W`, `weight`, `weights`, `kernel` |
|
|
54
|
+
| biases | `b`, `bias` |
|
|
55
|
+
| gradients | `dW`, `grad_W`, `W_grad`, `dweight`, … and `db`, `grad_b`, … |
|
|
56
|
+
| cached input (→ activation stats of the previous layer) | `x`, `input`, `inputs`, `a_prev` |
|
|
57
|
+
|
|
58
|
+
Layers without weights are recognised as activations by class name (`ReLU`, `Tanh`, `Sigmoid`, `LeakyReLU`, …), so the graph
|
|
59
|
+
shows `relu`, `tanh`, … on each layer. CS231n-style parameter dicts (`{"W1": …, "b1": …}` plus a matching `grads` dict)
|
|
60
|
+
and lists of `(W, b)` pairs work too.
|
|
61
|
+
|
|
62
|
+
**2. Plain arrays.** No model object needed:
|
|
63
|
+
|
|
64
|
+
```python
|
|
65
|
+
scope.log(step, weights=[W1, W2], biases=[b1, b2], grads=[dW1, dW2], loss=loss)
|
|
66
|
+
```
|
|
67
|
+
|
|
68
|
+
Both `x @ W` (`W` is `(in, out)`) and `W @ x` (`W` is `(out, in)`) conventions are detected from how the shapes chain. Force
|
|
69
|
+
one with `Scope(layout="in_out")` or `layout="out_in"` if a network is ambiguous (e.g. every layer square).
|
|
70
|
+
|
|
71
|
+
**Optional extras for richer views:**
|
|
72
|
+
|
|
73
|
+
```python
|
|
74
|
+
scope.log(step, model=model, loss=loss,
|
|
75
|
+
activations=[a1, a2], # per-layer outputs on a batch → activation statistics
|
|
76
|
+
deltas=[d1, d2, d3], # per-layer ∂L/∂z on a batch → shown in the gradient-flow panel
|
|
77
|
+
latent=z, labels=y) # features of any layer → latent-space scatter
|
|
78
|
+
```
|
|
79
|
+
|
|
80
|
+
## How to read the dashboard
|
|
81
|
+
|
|
82
|
+
| Panel | What it shows | What to look for |
|
|
83
|
+
|---|---|---|
|
|
84
|
+
| **Network** | Neurons (circles) and weights (lines): blue positive, orange negative, thickness ∝ \|w\|. Toggle the lines to **gradients** ∂L/∂w or **updates** Δw, and the node colour to mean activation or % active. | Click a neuron: the **inspector** shows z = Σ wᵢ aᵢ + b with the real numbers from your batch, its strongest inputs, their gradients and how they changed. Dead ReLUs are ringed in red. |
|
|
85
|
+
| **Loss & metrics** | Every scalar you log over time (log or linear scale). | Spikes: learning rate too high. Test loss rising while training loss falls: overfitting. |
|
|
86
|
+
| **Insights** | Plain-language diagnoses, each at the step where it appeared. Click to jump there. | Vanishing/exploding gradients, dead or saturated units, learning rate too high/low, overfitting. |
|
|
87
|
+
| **Gradient flow** | Mean \|∂L/∂W\| per layer, input → output, log scale. | Bars shrinking towards the input = vanishing gradients (e.g. deep sigmoid nets). |
|
|
88
|
+
| **Layer health** | ‖W‖, ‖∇W‖ and the update ratio ‖ΔW‖/‖W‖ per layer over time, plus W and ∇W histograms. | Update ratio ≈ 10⁻³ per SGD step is healthy; ≈ 10⁻¹ is too high. |
|
|
89
|
+
| **Activations** | Per neuron: mean activation and fraction of samples where it is active. | Neurons at 0 % active pass no gradient back and have stopped learning. |
|
|
90
|
+
| **Latent space** | Any layer's features (PCA if wider than 2), coloured by label, along the timeline. | Classes starting mixed and ending linearly separable: the network is building a representation. |
|
|
91
|
+
|
|
92
|
+
Use the **timeline** at the bottom (or ← → and space) to replay training. **Export** saves the network (SVG/PNG), the loss curve,
|
|
93
|
+
the whole dashboard (PNG) or the raw run data (JSON).
|
|
94
|
+
|
|
95
|
+

|
|
96
|
+
|
|
97
|
+
## Examples
|
|
98
|
+
|
|
99
|
+
The [`examples/`](https://github.com/Ashurali/nnscope/tree/master/examples) folder uses a tiny homework-style NumPy MLP ([`_mlp.py`](https://github.com/Ashurali/nnscope/blob/master/examples/_mlp.py)). Run them from that folder;
|
|
100
|
+
add `--no-open` to skip opening a browser tab, or `--headless` to only write `runs/*.html` and `runs/*.svg`.
|
|
101
|
+
|
|
102
|
+
| script | story |
|
|
103
|
+
|---|---|
|
|
104
|
+
| `01_quickstart_xor.py` | the basics: an MLP on XOR-like data, live |
|
|
105
|
+
| `02_plain_arrays.py` | no model object: raw `W1, b1, W2, b2`, hand-written backprop, `deltas=` |
|
|
106
|
+
| `03_latent_bottleneck.py --k 2` | watch a k-unit bottleneck layer separate two classes (try `--k 32`) |
|
|
107
|
+
| `04_vanishing_gradients.py --act sigmoid` | deep sigmoid net: gradients vanish, the insight explains why (compare `--act relu`) |
|
|
108
|
+
| `05_inr_spectral_bias.py [--fourier]` | fit an image f(x, y) → rgb: raw coordinates plateau, Fourier features keep improving |
|
|
109
|
+
|
|
110
|
+
## API
|
|
111
|
+
|
|
112
|
+
```python
|
|
113
|
+
nnscope.Scope(name="run", *, live=True, port=8765, host="127.0.0.1", open_browser=True, max_neurons=32,
|
|
114
|
+
snapshot_every=None, max_snapshots=300, max_records=5000, layout="auto", latent_points=1000, quiet=False)
|
|
115
|
+
```
|
|
116
|
+
|
|
117
|
+
- `log(step=None, *, model=None, loss=None, metrics=None, weights=None, biases=None, grads=None, bias_grads=None, activations=None, deltas=None, latent=None, labels=None, snapshot=None)`
|
|
118
|
+
- `save_html(path)`: standalone replay. `snapshot(path, step=None)`: `.svg` (no dependencies) or `.png` (matplotlib).
|
|
119
|
+
- `show(height=820)`: Jupyter IFrame. `wait()`: serve until Ctrl+C. `close()`; also usable as a context manager.
|
|
120
|
+
- `data()`: everything recorded so far as a JSON-serialisable dict.
|
|
121
|
+
|
|
122
|
+
**Keeping it light.** Scalars are recorded at every `log`; full snapshots (edges, histograms, latent points) are thinned
|
|
123
|
+
adaptively so a run keeps at most `max_snapshots` of them. Layers wider than `max_neurons` draw an evenly spaced subset
|
|
124
|
+
(statistics always use all neurons). The live stream batches updates to about 10 per second.
|
|
125
|
+
|
|
126
|
+
**Limitations.** Dense (fully-connected) layers only for now; convolutional layers are not drawn. The server binds to
|
|
127
|
+
localhost by default.
|
|
128
|
+
|
|
129
|
+
## Development
|
|
130
|
+
|
|
131
|
+
```bash
|
|
132
|
+
uv sync --dev
|
|
133
|
+
uv run --dev pytest
|
|
134
|
+
```
|
|
135
|
+
|
|
136
|
+
## License
|
|
137
|
+
|
|
138
|
+
MIT
|
|
@@ -0,0 +1,47 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "nnscope"
|
|
3
|
+
version = "0.1.0"
|
|
4
|
+
description = "Watch your NumPy neural network learn: a live, replayable dashboard for weights, gradients, activations and loss."
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
license-files = ["LICENSE"]
|
|
8
|
+
requires-python = ">=3.9"
|
|
9
|
+
dependencies = ["numpy>=1.21"]
|
|
10
|
+
keywords = [
|
|
11
|
+
"neural-network",
|
|
12
|
+
"numpy",
|
|
13
|
+
"visualization",
|
|
14
|
+
"backpropagation",
|
|
15
|
+
"education",
|
|
16
|
+
"deep-learning",
|
|
17
|
+
"dashboard",
|
|
18
|
+
]
|
|
19
|
+
classifiers = [
|
|
20
|
+
"Development Status :: 3 - Alpha",
|
|
21
|
+
"Intended Audience :: Education",
|
|
22
|
+
"Intended Audience :: Science/Research",
|
|
23
|
+
"Operating System :: OS Independent",
|
|
24
|
+
"Programming Language :: Python :: 3",
|
|
25
|
+
"Topic :: Scientific/Engineering :: Artificial Intelligence",
|
|
26
|
+
"Topic :: Scientific/Engineering :: Visualization",
|
|
27
|
+
]
|
|
28
|
+
|
|
29
|
+
[[project.authors]]
|
|
30
|
+
name = "michaelks"
|
|
31
|
+
email = "michaelks540@gmail.com"
|
|
32
|
+
|
|
33
|
+
[project.optional-dependencies]
|
|
34
|
+
png = ["matplotlib>=3.5"]
|
|
35
|
+
|
|
36
|
+
[project.urls]
|
|
37
|
+
Homepage = "https://github.com/Ashurali/nnscope"
|
|
38
|
+
Repository = "https://github.com/Ashurali/nnscope"
|
|
39
|
+
Issues = "https://github.com/Ashurali/nnscope/issues"
|
|
40
|
+
Changelog = "https://github.com/Ashurali/nnscope/blob/master/CHANGELOG.md"
|
|
41
|
+
|
|
42
|
+
[dependency-groups]
|
|
43
|
+
dev = ["pytest>=7"]
|
|
44
|
+
|
|
45
|
+
[build-system]
|
|
46
|
+
requires = ["uv_build>=0.12.3,<0.13.0"]
|
|
47
|
+
build-backend = "uv_build"
|
|
@@ -0,0 +1,40 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "nnscope"
|
|
3
|
+
version = "0.1.0"
|
|
4
|
+
description = "Watch your NumPy neural network learn: a live, replayable dashboard for weights, gradients, activations and loss."
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
license-files = ["LICENSE"]
|
|
8
|
+
authors = [
|
|
9
|
+
{ name = "michaelks", email = "michaelks540@gmail.com" }
|
|
10
|
+
]
|
|
11
|
+
requires-python = ">=3.9"
|
|
12
|
+
dependencies = [
|
|
13
|
+
"numpy>=1.21",
|
|
14
|
+
]
|
|
15
|
+
keywords = ["neural-network", "numpy", "visualization", "backpropagation", "education", "deep-learning", "dashboard"]
|
|
16
|
+
classifiers = [
|
|
17
|
+
"Development Status :: 3 - Alpha",
|
|
18
|
+
"Intended Audience :: Education",
|
|
19
|
+
"Intended Audience :: Science/Research",
|
|
20
|
+
"Operating System :: OS Independent",
|
|
21
|
+
"Programming Language :: Python :: 3",
|
|
22
|
+
"Topic :: Scientific/Engineering :: Artificial Intelligence",
|
|
23
|
+
"Topic :: Scientific/Engineering :: Visualization",
|
|
24
|
+
]
|
|
25
|
+
|
|
26
|
+
[project.optional-dependencies]
|
|
27
|
+
png = ["matplotlib>=3.5"]
|
|
28
|
+
|
|
29
|
+
[project.urls]
|
|
30
|
+
Homepage = "https://github.com/Ashurali/nnscope"
|
|
31
|
+
Repository = "https://github.com/Ashurali/nnscope"
|
|
32
|
+
Issues = "https://github.com/Ashurali/nnscope/issues"
|
|
33
|
+
Changelog = "https://github.com/Ashurali/nnscope/blob/master/CHANGELOG.md"
|
|
34
|
+
|
|
35
|
+
[dependency-groups]
|
|
36
|
+
dev = ["pytest>=7"]
|
|
37
|
+
|
|
38
|
+
[build-system]
|
|
39
|
+
requires = ["uv_build>=0.12.3,<0.13.0"]
|
|
40
|
+
build-backend = "uv_build"
|
|
@@ -0,0 +1,12 @@
|
|
|
1
|
+
"""nnscope: watch your NumPy neural network learn.
|
|
2
|
+
|
|
3
|
+
import nnscope
|
|
4
|
+
scope = nnscope.Scope("my-mlp")
|
|
5
|
+
scope.log(step, model=model, loss=loss)
|
|
6
|
+
"""
|
|
7
|
+
__version__ = "0.1.0"
|
|
8
|
+
|
|
9
|
+
from .adapters import LayerView, extract_layers # noqa: E402
|
|
10
|
+
from .scope import Scope # noqa: E402
|
|
11
|
+
|
|
12
|
+
__all__ = ["Scope", "extract_layers", "LayerView", "__version__"]
|
|
@@ -0,0 +1,233 @@
|
|
|
1
|
+
"""Turn "whatever the user has" into a uniform list of dense layers.
|
|
2
|
+
|
|
3
|
+
nnscope never runs your network. It only *reads* arrays you already have: weights, biases, their gradients and
|
|
4
|
+
(optionally) activations. This module finds them, either from explicit lists or by duck-typing common NumPy model
|
|
5
|
+
layouts, and normalises every weight matrix to the ``(in_features, out_features)`` orientation used for ``x @ W``.
|
|
6
|
+
"""
|
|
7
|
+
from __future__ import annotations
|
|
8
|
+
|
|
9
|
+
import re
|
|
10
|
+
from dataclasses import dataclass
|
|
11
|
+
from typing import Any, List, Optional, Sequence
|
|
12
|
+
|
|
13
|
+
import numpy as np
|
|
14
|
+
|
|
15
|
+
WEIGHT_ATTRS = ("W", "weight", "weights", "kernel", "w")
|
|
16
|
+
BIAS_ATTRS = ("b", "bias", "biases")
|
|
17
|
+
WEIGHT_GRAD_ATTRS = ("dW", "grad_W", "W_grad", "dweight", "grad_weight", "weight_grad", "dw")
|
|
18
|
+
BIAS_GRAD_ATTRS = ("db", "grad_b", "b_grad", "dbias", "grad_bias", "bias_grad")
|
|
19
|
+
INPUT_CACHE_ATTRS = ("x", "input", "inputs", "a_prev", "x_cache", "cache_x")
|
|
20
|
+
ACTIVATION_NAMES = {
|
|
21
|
+
"relu": "relu", "leakyrelu": "leaky_relu", "tanh": "tanh", "sigmoid": "sigmoid", "logistic": "sigmoid",
|
|
22
|
+
"softmax": "softmax", "elu": "elu", "gelu": "gelu", "softplus": "softplus", "sine": "sine", "sin": "sine",
|
|
23
|
+
"linear": "linear", "identity": "linear", "swish": "swish", "silu": "swish",
|
|
24
|
+
}
|
|
25
|
+
|
|
26
|
+
HELP = """nnscope could not find dense-layer weights. Pass them explicitly, for example
|
|
27
|
+
|
|
28
|
+
scope.log(step, weights=[W1, W2], biases=[b1, b2], grads=[dW1, dW2], loss=loss)
|
|
29
|
+
|
|
30
|
+
or give a model object with a `.layers` list whose layers expose `W`/`b` (and `dW`/`db`),
|
|
31
|
+
a `.params` dict like {"W1": ..., "b1": ...}, or a list of (W, b) pairs."""
|
|
32
|
+
|
|
33
|
+
|
|
34
|
+
@dataclass
|
|
35
|
+
class LayerView:
|
|
36
|
+
"""One dense layer, normalised so that ``W.shape == (in_features, out_features)``."""
|
|
37
|
+
|
|
38
|
+
W: np.ndarray
|
|
39
|
+
b: Optional[np.ndarray] = None
|
|
40
|
+
dW: Optional[np.ndarray] = None
|
|
41
|
+
db: Optional[np.ndarray] = None
|
|
42
|
+
act: Optional[str] = None # activation applied to this layer's output ("relu", "tanh", ...)
|
|
43
|
+
name: str = ""
|
|
44
|
+
source: Any = None # the original layer object, if any (used to find cached inputs)
|
|
45
|
+
|
|
46
|
+
@property
|
|
47
|
+
def in_features(self) -> int:
|
|
48
|
+
return int(self.W.shape[0])
|
|
49
|
+
|
|
50
|
+
@property
|
|
51
|
+
def out_features(self) -> int:
|
|
52
|
+
return int(self.W.shape[1])
|
|
53
|
+
|
|
54
|
+
|
|
55
|
+
def _arr(x: Any) -> Optional[np.ndarray]:
|
|
56
|
+
return np.asarray(x) if isinstance(x, np.ndarray) or (x is not None and hasattr(x, "__array__")) else None
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
def _first_attr(obj: Any, names: Sequence[str], ndim: Optional[int] = None) -> Optional[np.ndarray]:
|
|
60
|
+
for n in names:
|
|
61
|
+
v = getattr(obj, n, None)
|
|
62
|
+
a = _arr(v) if v is not None else None
|
|
63
|
+
if a is not None and a.dtype.kind in "fiu" and (ndim is None or a.ndim == ndim):
|
|
64
|
+
return a
|
|
65
|
+
return None
|
|
66
|
+
|
|
67
|
+
|
|
68
|
+
def activation_name(obj: Any) -> Optional[str]:
|
|
69
|
+
"""Recognise an activation layer by its class name (ReLU, Tanh, Sigmoid, ...)."""
|
|
70
|
+
key = re.sub(r"[^a-z]", "", type(obj).__name__.lower())
|
|
71
|
+
return ACTIVATION_NAMES.get(key)
|
|
72
|
+
|
|
73
|
+
|
|
74
|
+
# ------------------------------------------------------------------ collection from different model layouts
|
|
75
|
+
def _from_layer_objects(layers: Sequence[Any]) -> List[LayerView]:
|
|
76
|
+
views: List[LayerView] = []
|
|
77
|
+
for obj in layers:
|
|
78
|
+
if hasattr(obj, "layers") and not isinstance(obj, (list, tuple)): # nested Sequential
|
|
79
|
+
views.extend(_from_layer_objects(list(obj.layers)))
|
|
80
|
+
continue
|
|
81
|
+
W = _first_attr(obj, WEIGHT_ATTRS, ndim=2)
|
|
82
|
+
if W is not None:
|
|
83
|
+
views.append(LayerView(
|
|
84
|
+
W=W, b=_first_attr(obj, BIAS_ATTRS), dW=_first_attr(obj, WEIGHT_GRAD_ATTRS, ndim=2),
|
|
85
|
+
db=_first_attr(obj, BIAS_GRAD_ATTRS), name=type(obj).__name__, source=obj))
|
|
86
|
+
continue
|
|
87
|
+
act = activation_name(obj)
|
|
88
|
+
if act and views and views[-1].act is None:
|
|
89
|
+
views[-1].act = act
|
|
90
|
+
return views
|
|
91
|
+
|
|
92
|
+
|
|
93
|
+
_KEY = re.compile(r"^(?P<kind>[A-Za-z]+)[_.]?(?P<idx>\d+)$")
|
|
94
|
+
|
|
95
|
+
|
|
96
|
+
def _from_dict(params: dict, grads: Optional[dict] = None) -> List[LayerView]:
|
|
97
|
+
"""CS231n-style dicts: {"W1": ..., "b1": ..., "W2": ...} (+ an optional grads dict with the same keys)."""
|
|
98
|
+
layers: dict = {}
|
|
99
|
+
for key, val in params.items():
|
|
100
|
+
m = _KEY.match(str(key))
|
|
101
|
+
if not m:
|
|
102
|
+
continue
|
|
103
|
+
kind, idx = m.group("kind"), int(m.group("idx"))
|
|
104
|
+
slot = layers.setdefault(idx, {})
|
|
105
|
+
if kind in WEIGHT_ATTRS:
|
|
106
|
+
slot["W"], slot["kW"] = np.asarray(val), key
|
|
107
|
+
elif kind in BIAS_ATTRS:
|
|
108
|
+
slot["b"], slot["kb"] = np.asarray(val), key
|
|
109
|
+
views = []
|
|
110
|
+
for idx in sorted(layers):
|
|
111
|
+
slot = layers[idx]
|
|
112
|
+
if "W" not in slot or slot["W"].ndim != 2:
|
|
113
|
+
continue
|
|
114
|
+
dW = _arr(grads.get(slot["kW"])) if grads else None
|
|
115
|
+
db = _arr(grads.get(slot.get("kb"))) if grads and slot.get("kb") else None
|
|
116
|
+
views.append(LayerView(W=slot["W"], b=slot.get("b"), dW=dW, db=db, name=f"layer {idx}"))
|
|
117
|
+
return views
|
|
118
|
+
|
|
119
|
+
|
|
120
|
+
def _from_sequence(items: Sequence[Any]) -> List[LayerView]:
|
|
121
|
+
"""A list of arrays ([W1, b1, W2, b2] or [W1, W2]), of (W, b) pairs, or of layer objects."""
|
|
122
|
+
if items and not any(isinstance(it, (np.ndarray, tuple, list)) for it in items):
|
|
123
|
+
return _from_layer_objects(items)
|
|
124
|
+
views: List[LayerView] = []
|
|
125
|
+
for it in items:
|
|
126
|
+
if isinstance(it, (tuple, list)):
|
|
127
|
+
W = np.asarray(it[0])
|
|
128
|
+
b = np.asarray(it[1]) if len(it) > 1 and it[1] is not None else None
|
|
129
|
+
views.append(LayerView(W=W, b=b))
|
|
130
|
+
else:
|
|
131
|
+
a = np.asarray(it)
|
|
132
|
+
if a.ndim == 2:
|
|
133
|
+
views.append(LayerView(W=a))
|
|
134
|
+
elif a.ndim == 1 and views and views[-1].b is None:
|
|
135
|
+
views[-1].b = a
|
|
136
|
+
return views
|
|
137
|
+
|
|
138
|
+
|
|
139
|
+
# ------------------------------------------------------------------ orientation
|
|
140
|
+
def _chains(mats: List[np.ndarray], in_out: bool) -> bool:
|
|
141
|
+
if in_out:
|
|
142
|
+
return all(mats[k].shape[1] == mats[k + 1].shape[0] for k in range(len(mats) - 1))
|
|
143
|
+
return all(mats[k].shape[0] == mats[k + 1].shape[1] for k in range(len(mats) - 1))
|
|
144
|
+
|
|
145
|
+
|
|
146
|
+
def detect_layout(views: List[LayerView]) -> str:
|
|
147
|
+
"""Return "in_out" (x @ W, W is (in, out)) or "out_in" (W @ x, W is (out, in))."""
|
|
148
|
+
mats = [v.W for v in views]
|
|
149
|
+
if len(mats) >= 2:
|
|
150
|
+
io, oi = _chains(mats, True), _chains(mats, False)
|
|
151
|
+
if io and not oi:
|
|
152
|
+
return "in_out"
|
|
153
|
+
if oi and not io:
|
|
154
|
+
return "out_in"
|
|
155
|
+
votes = 0 # ambiguous → let the biases decide
|
|
156
|
+
for v in views:
|
|
157
|
+
if v.b is not None and v.W.shape[0] != v.W.shape[1]:
|
|
158
|
+
n = v.b.size
|
|
159
|
+
votes += (n == v.W.shape[1]) - (n == v.W.shape[0])
|
|
160
|
+
return "out_in" if votes < 0 else "in_out"
|
|
161
|
+
|
|
162
|
+
|
|
163
|
+
def normalise(views: List[LayerView], layout: str = "auto") -> List[LayerView]:
|
|
164
|
+
if layout not in ("auto", "in_out", "out_in"):
|
|
165
|
+
raise ValueError('layout must be "auto", "in_out" or "out_in"')
|
|
166
|
+
if layout == "auto":
|
|
167
|
+
layout = detect_layout(views)
|
|
168
|
+
if layout == "out_in":
|
|
169
|
+
for v in views:
|
|
170
|
+
v.W = v.W.T
|
|
171
|
+
if v.dW is not None:
|
|
172
|
+
v.dW = v.dW.T
|
|
173
|
+
for k, v in enumerate(views):
|
|
174
|
+
if not v.name:
|
|
175
|
+
v.name = f"layer {k + 1}"
|
|
176
|
+
for attr in ("b", "db"):
|
|
177
|
+
a = getattr(v, attr)
|
|
178
|
+
if a is not None:
|
|
179
|
+
setattr(v, attr, np.asarray(a).reshape(-1))
|
|
180
|
+
if v.dW is not None and v.dW.shape != v.W.shape:
|
|
181
|
+
v.dW = v.dW.T if v.dW.T.shape == v.W.shape else None
|
|
182
|
+
return views
|
|
183
|
+
|
|
184
|
+
|
|
185
|
+
# ------------------------------------------------------------------ public entry point
|
|
186
|
+
def extract_layers(model: Any = None, *, weights: Optional[Sequence] = None, biases: Optional[Sequence] = None,
|
|
187
|
+
grads: Any = None, bias_grads: Optional[Sequence] = None, layout: str = "auto") -> List[LayerView]:
|
|
188
|
+
"""Collect dense layers from ``model`` or from explicit arrays. Raises ``TypeError`` with usage help if none are found."""
|
|
189
|
+
if weights is not None:
|
|
190
|
+
views = [LayerView(W=np.asarray(W)) for W in weights]
|
|
191
|
+
for k, v in enumerate(views):
|
|
192
|
+
if biases is not None and k < len(biases) and biases[k] is not None:
|
|
193
|
+
v.b = np.asarray(biases[k])
|
|
194
|
+
if isinstance(grads, (list, tuple)) and k < len(grads) and grads[k] is not None:
|
|
195
|
+
v.dW = np.asarray(grads[k])
|
|
196
|
+
if bias_grads is not None and k < len(bias_grads) and bias_grads[k] is not None:
|
|
197
|
+
v.db = np.asarray(bias_grads[k])
|
|
198
|
+
elif model is None:
|
|
199
|
+
raise TypeError(HELP)
|
|
200
|
+
elif hasattr(model, "layers") and not isinstance(model, dict):
|
|
201
|
+
views = _from_layer_objects(list(model.layers))
|
|
202
|
+
elif isinstance(getattr(model, "params", None), dict):
|
|
203
|
+
g = grads if isinstance(grads, dict) else getattr(model, "grads", None)
|
|
204
|
+
views = _from_dict(model.params, g if isinstance(g, dict) else None)
|
|
205
|
+
elif isinstance(model, dict):
|
|
206
|
+
views = _from_dict(model, grads if isinstance(grads, dict) else None)
|
|
207
|
+
elif isinstance(model, (list, tuple)):
|
|
208
|
+
views = _from_sequence(model)
|
|
209
|
+
if isinstance(grads, (list, tuple)):
|
|
210
|
+
for v, g in zip(views, grads):
|
|
211
|
+
v.dW = np.asarray(g) if g is not None else None
|
|
212
|
+
else:
|
|
213
|
+
raise TypeError(HELP)
|
|
214
|
+
views = [v for v in views if v.W.ndim == 2]
|
|
215
|
+
if not views:
|
|
216
|
+
raise TypeError(HELP)
|
|
217
|
+
return normalise(views, layout)
|
|
218
|
+
|
|
219
|
+
|
|
220
|
+
def cached_activations(views: List[LayerView]) -> List[Optional[np.ndarray]]:
|
|
221
|
+
"""Best-effort: the output of hidden layer k is the cached *input* of layer k+1 (e.g. HW-style ``Linear.x``).
|
|
222
|
+
|
|
223
|
+
Returns one entry per layer (the last one, the network output, is usually unknown → None).
|
|
224
|
+
"""
|
|
225
|
+
out: List[Optional[np.ndarray]] = [None] * len(views)
|
|
226
|
+
for k in range(len(views) - 1):
|
|
227
|
+
nxt = views[k + 1].source
|
|
228
|
+
if nxt is None:
|
|
229
|
+
continue
|
|
230
|
+
x = _first_attr(nxt, INPUT_CACHE_ATTRS)
|
|
231
|
+
if x is not None and x.ndim == 2 and x.shape[1] == views[k].out_features:
|
|
232
|
+
out[k] = x
|
|
233
|
+
return out
|