neural-lab 0.5.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- neural_lab-0.5.0/.gitignore +163 -0
- neural_lab-0.5.0/LICENSE +21 -0
- neural_lab-0.5.0/PKG-INFO +283 -0
- neural_lab-0.5.0/README.md +269 -0
- neural_lab-0.5.0/docs/README.md +35 -0
- neural_lab-0.5.0/docs/generate_images.py +173 -0
- neural_lab-0.5.0/docs/pyproject.toml +12 -0
- neural_lab-0.5.0/examples/the_digits_experiment/README.md +14 -0
- neural_lab-0.5.0/examples/the_digits_experiment/main.ipynb +559 -0
- neural_lab-0.5.0/examples/the_digits_experiment/pyproject.toml +12 -0
- neural_lab-0.5.0/examples/the_digits_experiment/visualizations.py +40 -0
- neural_lab-0.5.0/examples/the_nibble_challenge/README.md +14 -0
- neural_lab-0.5.0/examples/the_nibble_challenge/main.ipynb +397 -0
- neural_lab-0.5.0/examples/the_nibble_challenge/pyproject.toml +12 -0
- neural_lab-0.5.0/examples/the_nibble_challenge/visualizations.py +60 -0
- neural_lab-0.5.0/images/digits_confusion_matrix.png +0 -0
- neural_lab-0.5.0/images/digits_predictions.png +0 -0
- neural_lab-0.5.0/images/digits_results.png +0 -0
- neural_lab-0.5.0/images/nibble_multiweight.png +0 -0
- neural_lab-0.5.0/pyproject.toml +29 -0
- neural_lab-0.5.0/src/neural_lab/__about__.py +1 -0
- neural_lab-0.5.0/src/neural_lab/__init__.py +3 -0
- neural_lab-0.5.0/src/neural_lab/layer.py +23 -0
- neural_lab-0.5.0/src/neural_lab/network.py +74 -0
- neural_lab-0.5.0/src/neural_lab/neuron.py +59 -0
- neural_lab-0.5.0/tests/__init__.py +0 -0
- neural_lab-0.5.0/tests/test.py +124 -0
|
@@ -0,0 +1,163 @@
|
|
|
1
|
+
# Byte-compiled / optimized / DLL files
|
|
2
|
+
__pycache__/
|
|
3
|
+
*.py[cod]
|
|
4
|
+
*$py.class
|
|
5
|
+
|
|
6
|
+
# C extensions
|
|
7
|
+
*.so
|
|
8
|
+
|
|
9
|
+
# Distribution / packaging
|
|
10
|
+
.Python
|
|
11
|
+
build/
|
|
12
|
+
develop-eggs/
|
|
13
|
+
dist/
|
|
14
|
+
downloads/
|
|
15
|
+
eggs/
|
|
16
|
+
.eggs/
|
|
17
|
+
lib/
|
|
18
|
+
lib64/
|
|
19
|
+
parts/
|
|
20
|
+
sdist/
|
|
21
|
+
var/
|
|
22
|
+
wheels/
|
|
23
|
+
share/python-wheels/
|
|
24
|
+
*.egg-info/
|
|
25
|
+
.installed.cfg
|
|
26
|
+
*.egg
|
|
27
|
+
MANIFEST
|
|
28
|
+
|
|
29
|
+
# PyInstaller
|
|
30
|
+
# Usually these files are written by a python script from a template
|
|
31
|
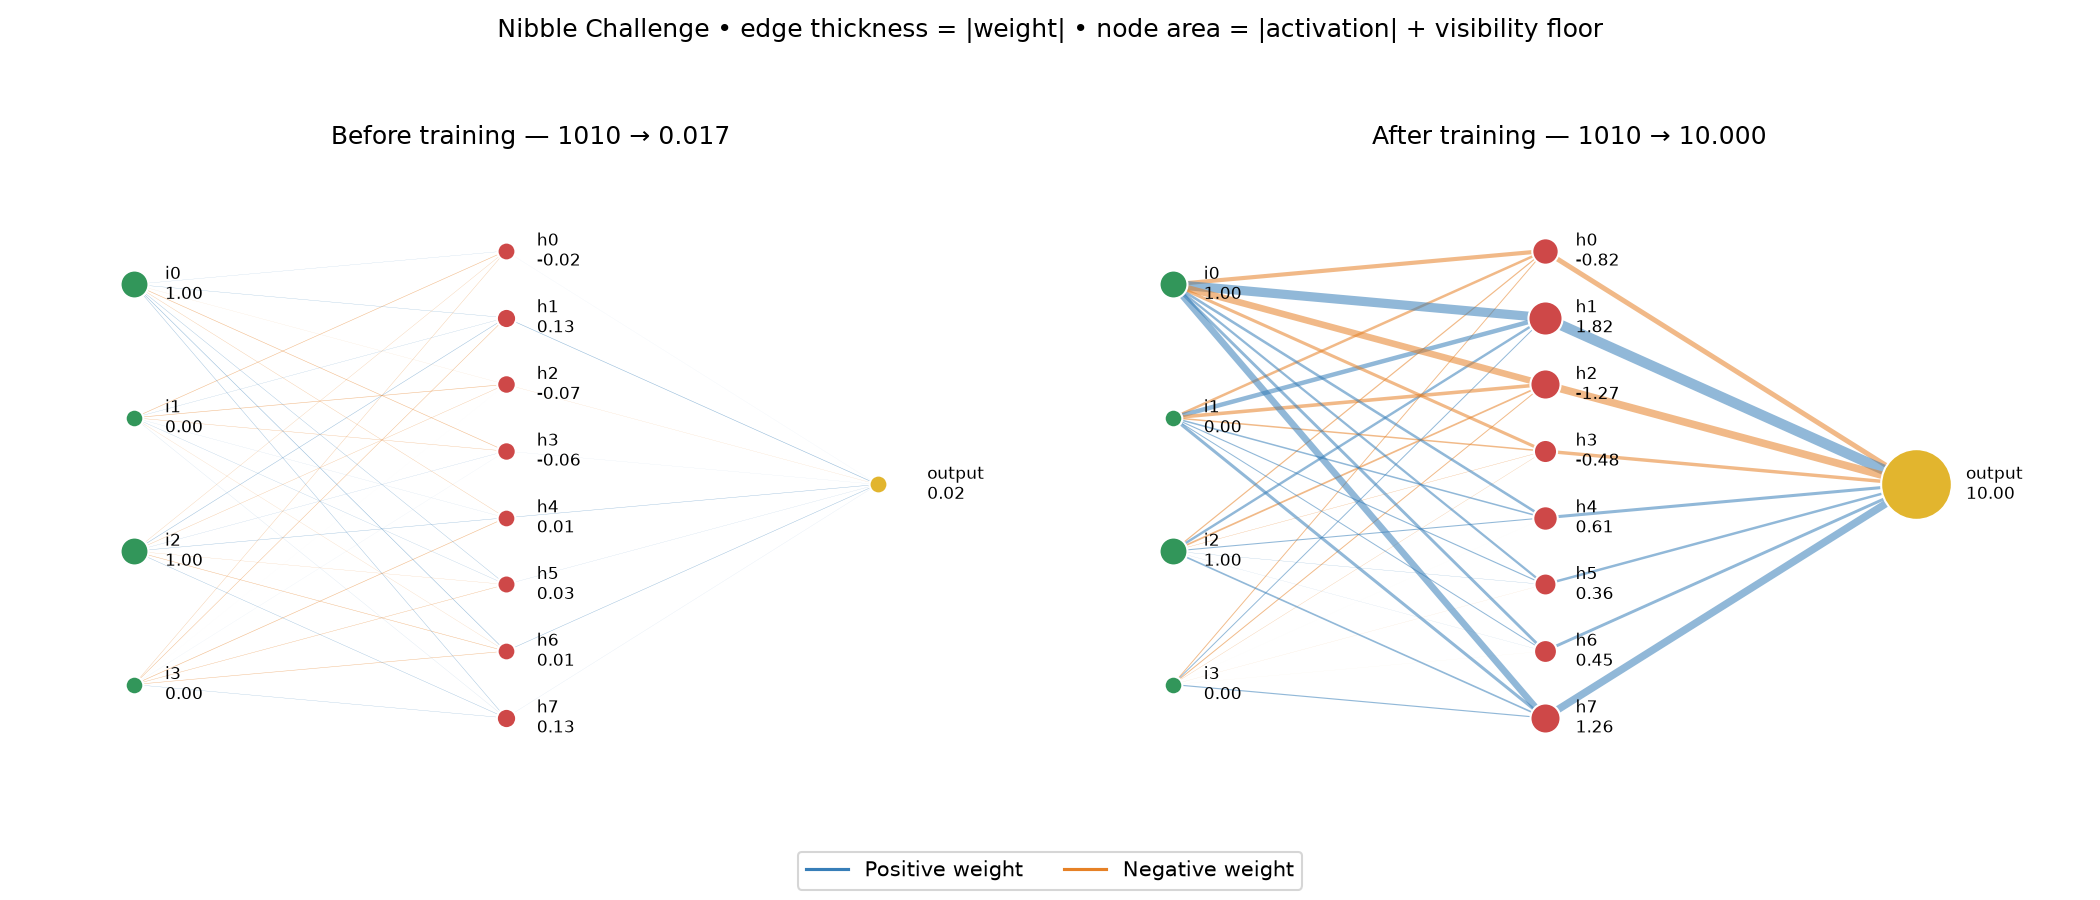
+
# before PyInstaller builds the exe, so as to inject date/other infos into it.
|
|
32
|
+
*.manifest
|
|
33
|
+
*.spec
|
|
34
|
+
|
|
35
|
+
# Installer logs
|
|
36
|
+
pip-log.txt
|
|
37
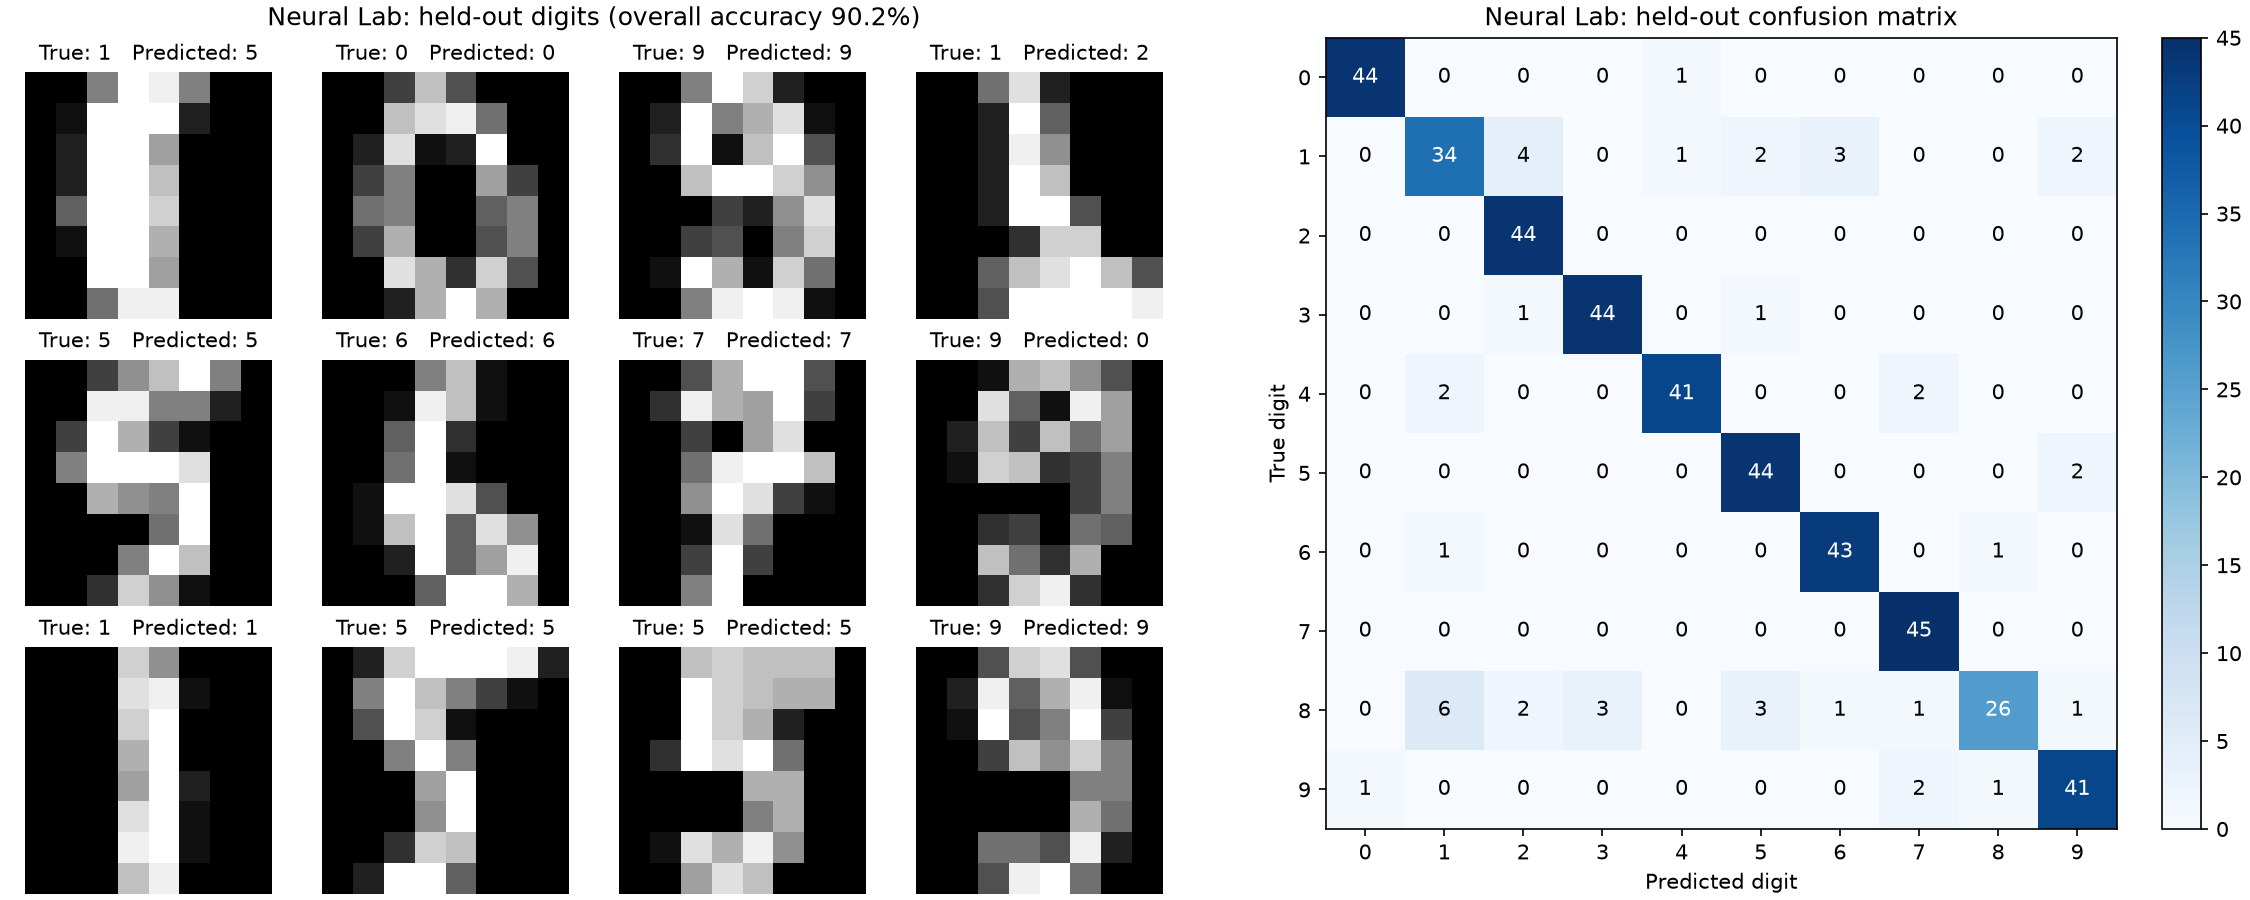
|
+
pip-delete-this-directory.txt
|
|
38
|
+
|
|
39
|
+
# Unit test / coverage reports
|
|
40
|
+
htmlcov/
|
|
41
|
+
.tox/
|
|
42
|
+
.nox/
|
|
43
|
+
.coverage
|
|
44
|
+
.coverage.*
|
|
45
|
+
.cache
|
|
46
|
+
nosetests.xml
|
|
47
|
+
coverage.xml
|
|
48
|
+
*.cover
|
|
49
|
+
*.py,cover
|
|
50
|
+
.hypothesis/
|
|
51
|
+
.pytest_cache/
|
|
52
|
+
cover/
|
|
53
|
+
|
|
54
|
+
# Translations
|
|
55
|
+
*.mo
|
|
56
|
+
*.pot
|
|
57
|
+
|
|
58
|
+
# Django stuff:
|
|
59
|
+
*.log
|
|
60
|
+
local_settings.py
|
|
61
|
+
db.sqlite3
|
|
62
|
+
db.sqlite3-journal
|
|
63
|
+
|
|
64
|
+
# Flask stuff:
|
|
65
|
+
instance/
|
|
66
|
+
.webassets-cache
|
|
67
|
+
|
|
68
|
+
# Scrapy stuff:
|
|
69
|
+
.scrapy
|
|
70
|
+
|
|
71
|
+
# Sphinx documentation
|
|
72
|
+
docs/_build/
|
|
73
|
+
|
|
74
|
+
# PyBuilder
|
|
75
|
+
.pybuilder/
|
|
76
|
+
target/
|
|
77
|
+
|
|
78
|
+
# Jupyter Notebook
|
|
79
|
+
.ipynb_checkpoints
|
|
80
|
+
|
|
81
|
+
# IPython
|
|
82
|
+
profile_default/
|
|
83
|
+
ipython_config.py
|
|
84
|
+
|
|
85
|
+
# pyenv
|
|
86
|
+
# For a library or package, you might want to ignore these files since the code is
|
|
87
|
+
# intended to run in multiple environments; otherwise, check them in:
|
|
88
|
+
# .python-version
|
|
89
|
+
|
|
90
|
+
# pipenv
|
|
91
|
+
# According to pypa/pipenv#598, it is recommended to include Pipfile.lock in version control.
|
|
92
|
+
# However, in case of collaboration, if having platform-specific dependencies or dependencies
|
|
93
|
+
# having no cross-platform support, pipenv may install dependencies that don't work, or not
|
|
94
|
+
# install all needed dependencies.
|
|
95
|
+
#Pipfile.lock
|
|
96
|
+
|
|
97
|
+
# poetry
|
|
98
|
+
# Similar to Pipfile.lock, it is generally recommended to include poetry.lock in version control.
|
|
99
|
+
# This is especially recommended for binary packages to ensure reproducibility, and is more
|
|
100
|
+
# commonly ignored for libraries.
|
|
101
|
+
# https://python-poetry.org/docs/basic-usage/#commit-your-poetrylock-file-to-version-control
|
|
102
|
+
#poetry.lock
|
|
103
|
+
|
|
104
|
+
# pdm
|
|
105
|
+
# Similar to Pipfile.lock, it is generally recommended to include pdm.lock in version control.
|
|
106
|
+
#pdm.lock
|
|
107
|
+
# pdm stores project-wide configurations in .pdm.toml, but it is recommended to not include it
|
|
108
|
+
# in version control.
|
|
109
|
+
# https://pdm.fming.dev/#use-with-ide
|
|
110
|
+
.pdm.toml
|
|
111
|
+
|
|
112
|
+
# PEP 582; used by e.g. github.com/David-OConnor/pyflow and github.com/pdm-project/pdm
|
|
113
|
+
__pypackages__/
|
|
114
|
+
|
|
115
|
+
# Celery stuff
|
|
116
|
+
celerybeat-schedule
|
|
117
|
+
celerybeat.pid
|
|
118
|
+
|
|
119
|
+
# SageMath parsed files
|
|
120
|
+
*.sage.py
|
|
121
|
+
|
|
122
|
+
# Environments
|
|
123
|
+
.env
|
|
124
|
+
.venv
|
|
125
|
+
env/
|
|
126
|
+
venv/
|
|
127
|
+
ENV/
|
|
128
|
+
env.bak/
|
|
129
|
+
venv.bak/
|
|
130
|
+
|
|
131
|
+
# Spyder project settings
|
|
132
|
+
.spyderproject
|
|
133
|
+
.spyproject
|
|
134
|
+
|
|
135
|
+
# Rope project settings
|
|
136
|
+
.ropeproject
|
|
137
|
+
|
|
138
|
+
# mkdocs documentation
|
|
139
|
+
/site
|
|
140
|
+
|
|
141
|
+
# mypy
|
|
142
|
+
.mypy_cache/
|
|
143
|
+
.dmypy.json
|
|
144
|
+
dmypy.json
|
|
145
|
+
|
|
146
|
+
# Pyre type checker
|
|
147
|
+
.pyre/
|
|
148
|
+
|
|
149
|
+
# pytype static type analyzer
|
|
150
|
+
.pytype/
|
|
151
|
+
|
|
152
|
+
# Cython debug symbols
|
|
153
|
+
cython_debug/
|
|
154
|
+
|
|
155
|
+
# PyCharm
|
|
156
|
+
# JetBrains specific template is maintained in a separate JetBrains.gitignore that can
|
|
157
|
+
# be found at https://github.com/github/gitignore/blob/main/Global/JetBrains.gitignore
|
|
158
|
+
# and can be added to the global gitignore or merged into this file. For a more nuclear
|
|
159
|
+
# option (not recommended) you can uncomment the following to ignore the entire idea folder.
|
|
160
|
+
#.idea/
|
|
161
|
+
|
|
162
|
+
*.pkl
|
|
163
|
+
*.html
|
neural_lab-0.5.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2024 FAR Analytics & Research
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,283 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: neural-lab
|
|
3
|
+
Version: 0.5.0
|
|
4
|
+
Summary: A neural network implementation built as an explicit graph of neurons and weighted connections.
|
|
5
|
+
Project-URL: Homepage, https://github.com/adamjpatterson/neural-lab
|
|
6
|
+
Project-URL: Issues, https://github.com/adamjpatterson/neural-lab/issues
|
|
7
|
+
Author-email: FAR Analytics & Research <adpatter2000@gmail.com>
|
|
8
|
+
License-File: LICENSE
|
|
9
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
10
|
+
Classifier: Operating System :: OS Independent
|
|
11
|
+
Classifier: Programming Language :: Python :: 3
|
|
12
|
+
Requires-Python: >=3.11
|
|
13
|
+
Description-Content-Type: text/markdown
|
|
14
|
+
|
|
15
|
+
# Neural Lab
|
|
16
|
+
|
|
17
|
+
[](https://pypi.org/project/neural-lab/) [](https://pypi.org/project/neural-lab/) [](https://github.com/adamjpatterson/neural-lab/blob/main/LICENSE)
|
|
18
|
+
|
|
19
|
+
A neural network implementation built as an explicit graph of neurons and weighted connections.
|
|
20
|
+
|
|
21
|
+
## Introduction
|
|
22
|
+
|
|
23
|
+
**Neural Lab** represents individual neurons and their connections explicitly. Backpropagation is done using explicitly computed gradients. The object-oriented API consists of Network, Layer, and Neuron constructors. The networks can be easily [visualized](#visualizations-of-the-network-before-and-after-training) using a visualization library.
|
|
24
|
+
|
|
25
|
+
## Table of contents
|
|
26
|
+
|
|
27
|
+
- [Installation](#installation)
|
|
28
|
+
- [How it works](#how-it-works)
|
|
29
|
+
- [Examples](#examples)
|
|
30
|
+
- [The nibble challenge](#the-nibble-challenge)
|
|
31
|
+
- [The digits experiment](#the-digits-experiment)
|
|
32
|
+
- [Tests](#tests)
|
|
33
|
+
- [Documentation maintenance](#documentation-maintenance)
|
|
34
|
+
|
|
35
|
+
## Installation
|
|
36
|
+
|
|
37
|
+
To use the published package:
|
|
38
|
+
|
|
39
|
+
```bash
|
|
40
|
+
python -m pip install neural-lab
|
|
41
|
+
```
|
|
42
|
+
|
|
43
|
+
## How it works
|
|
44
|
+
|
|
45
|
+
This implementation demonstrates each component of the API. A 3 layer neural network is constructed that has a 4 neuron input Layer and a 1 neuron output layer. The hidden layer has 8 neurons.
|
|
46
|
+
|
|
47
|
+
### Implement a 3 layer neural network
|
|
48
|
+
|
|
49
|
+
#### Import the Network, Layer, and Neuron classes.
|
|
50
|
+
|
|
51
|
+
```python
|
|
52
|
+
from neural_lab import Network, Layer, Neuron
|
|
53
|
+
```
|
|
54
|
+
|
|
55
|
+
#### Set a step.
|
|
56
|
+
|
|
57
|
+
`step` is the learning rate: it controls the size of weight and bias updates. Each update subtracts `step` times the corresponding gradient. `Layer(step=...)` supplies an initial default only to neurons whose `step` is `None`. Changing `layer.step` later does not change the neurons; update each `neuron.step` directly to change its learning rate.
|
|
58
|
+
|
|
59
|
+
```python
|
|
60
|
+
STEP = 0.01
|
|
61
|
+
```
|
|
62
|
+
|
|
63
|
+
#### Construct a neural network by specifying the Neurons for each Layer and adding the Layers to a Network.
|
|
64
|
+
|
|
65
|
+
```python
|
|
66
|
+
l1 = Layer(neurons=[Neuron() for i in range(0, 4)], step=STEP)
|
|
67
|
+
l2 = Layer(neurons=[Neuron() for i in range(0, 8)], step=STEP)
|
|
68
|
+
l3 = Layer(neurons=[Neuron()], step=STEP)
|
|
69
|
+
n1 = Network([l1, l2, l3], seed=42)
|
|
70
|
+
```
|
|
71
|
+
|
|
72
|
+
#### With the Network defined, you can train the network.
|
|
73
|
+
|
|
74
|
+
Here the network is trained to recognize the nibble 1111 as the decimal number 15.
|
|
75
|
+
|
|
76
|
+
```python
|
|
77
|
+
n1.train([1,1,1,1], [15])
|
|
78
|
+
```
|
|
79
|
+
|
|
80
|
+
You can generate and print a prediction using the `predict` method. Because the network underwent just one iteration of training, the estimate will likely be inaccurate. The accuracy of the prediction can be improved by iteratively training the network. Please see [the nibble challenge](#the-nibble-challenge) for an example of how to iteratively train the network.
|
|
81
|
+
|
|
82
|
+
```python
|
|
83
|
+
prediction = n1.predict([1,1,1,1])
|
|
84
|
+
print(prediction)
|
|
85
|
+
```
|
|
86
|
+
|
|
87
|
+
### How a neuron learns
|
|
88
|
+
|
|
89
|
+
Consider the training call from the example above:
|
|
90
|
+
|
|
91
|
+
```python
|
|
92
|
+
n1.train([1, 1, 1, 1], [15])
|
|
93
|
+
```
|
|
94
|
+
|
|
95
|
+
The four inputs are the bits of `1111`; the target output is `15`. Here is how this one call changes the network. The excerpts below come from `Network` and `Neuron`.
|
|
96
|
+
|
|
97
|
+
#### 1. Calculate a prediction
|
|
98
|
+
|
|
99
|
+
`train` checks that there is one target per output neuron and that every non-input neuron has a finite, positive learning rate (`step`). It then calls:
|
|
100
|
+
|
|
101
|
+
```python
|
|
102
|
+
self.predict(X_train)
|
|
103
|
+
```
|
|
104
|
+
|
|
105
|
+
`predict` checks the inputs and connections, assigns the four input values, and calls `activate` on each hidden neuron, then the output neuron. Inside `Neuron.activate`:
|
|
106
|
+
|
|
107
|
+
```python
|
|
108
|
+
total = self.bias
|
|
109
|
+
for source, weight in self.weights.items():
|
|
110
|
+
total += source.value * weight
|
|
111
|
+
self.value = tanh(total) if self.activation == "tanh" else total
|
|
112
|
+
```
|
|
113
|
+
|
|
114
|
+
Each neuron adds its bias to the weighted inputs and stores its activation in `value`. This example uses linear activation, so `value` is simply `total`. Hidden neurons can also use `tanh`.
|
|
115
|
+
|
|
116
|
+
#### 2. Clear old gradients and calculate the output error
|
|
117
|
+
|
|
118
|
+
Back in `train`, gradients from the previous call are cleared before calculating the output gradients:
|
|
119
|
+
|
|
120
|
+
```python
|
|
121
|
+
for layer in self.layers:
|
|
122
|
+
for neuron in layer.neurons:
|
|
123
|
+
neuron.gradient = 0.0
|
|
124
|
+
neuron.delta = 0.0
|
|
125
|
+
for neuron, target in zip(self.output_layer.neurons, y_train):
|
|
126
|
+
neuron.gradient = neuron.value - target
|
|
127
|
+
```
|
|
128
|
+
|
|
129
|
+
The loss is half the sum of squared output errors. A neuron's `gradient` is the derivative of that loss with respect to its output. For our output neuron, this starts as the prediction minus `15`.
|
|
130
|
+
|
|
131
|
+
#### 3. Propagate gradients backward
|
|
132
|
+
|
|
133
|
+
`train` visits the output layer first, then the hidden layers:
|
|
134
|
+
|
|
135
|
+
```python
|
|
136
|
+
for layer in reversed(self.layers[1:]):
|
|
137
|
+
for neuron in layer.neurons:
|
|
138
|
+
neuron.propagate()
|
|
139
|
+
```
|
|
140
|
+
|
|
141
|
+
Inside `Neuron.propagate`:
|
|
142
|
+
|
|
143
|
+
```python
|
|
144
|
+
derivative = 1 - self.value ** 2 if self.activation == "tanh" else 1.0
|
|
145
|
+
self.delta = self.gradient * derivative
|
|
146
|
+
for source, weight in self.weights.items():
|
|
147
|
+
source.gradient += self.delta * weight
|
|
148
|
+
```
|
|
149
|
+
|
|
150
|
+
`delta` is the derivative of the loss with respect to the weighted sum plus bias, before activation. For linear activation, the derivative is `1`, so `delta` equals `gradient`. Each neuron passes a contribution back through each incoming connection. The `+=` lets a source accumulate contributions from every neuron it feeds. Visiting layers in reverse ensures those contributions arrive before the source propagates its own gradient.
|
|
151
|
+
|
|
152
|
+
#### 4. Update weights and biases
|
|
153
|
+
|
|
154
|
+
Only after the backward pass finishes does `train` change the parameters:
|
|
155
|
+
|
|
156
|
+
```python
|
|
157
|
+
for layer in self.layers[1:]:
|
|
158
|
+
for neuron in layer.neurons:
|
|
159
|
+
for source in neuron.weights:
|
|
160
|
+
neuron.weights[source] -= neuron.step * neuron.delta * source.value
|
|
161
|
+
neuron.bias -= neuron.step * neuron.delta
|
|
162
|
+
```
|
|
163
|
+
|
|
164
|
+
A weight's gradient is `delta * source.value`; the bias gradient is `delta`. Subtracting `step` times each gradient updates the parameters. Waiting until this point means every backward calculation uses the same weights as the forward pass. The next call to `predict` uses the updated weights and biases.
|
|
165
|
+
|
|
166
|
+
Each incoming connection has its own weight in `neuron.weights[source]`. `Neuron(bias=...)` sets the initial bias, and `Network(..., seed=42)` initializes weights reproducibly in [-0.1, 0.1]. Connections added later accept an explicit `weight`; repeated connection calls preserve existing weights.
|
|
167
|
+
|
|
168
|
+
### Explore a trained network
|
|
169
|
+
|
|
170
|
+
After training, remove a connection and compare predictions to see how it affects the network. This experiment is called an ablation.
|
|
171
|
+
|
|
172
|
+
Using your trained network as `n1`:
|
|
173
|
+
|
|
174
|
+
```python
|
|
175
|
+
inputs = [1, 0, 1, 0]
|
|
176
|
+
source = n1.layers[1].neurons[0]
|
|
177
|
+
receiver = n1.output_layer.neurons[0]
|
|
178
|
+
weight = receiver.weights[source]
|
|
179
|
+
before = n1.predict(inputs)
|
|
180
|
+
|
|
181
|
+
source.disconnectRHS(receiver)
|
|
182
|
+
after = n1.predict(inputs)
|
|
183
|
+
print("Original prediction:", before)
|
|
184
|
+
print("Without the connection:", after)
|
|
185
|
+
|
|
186
|
+
source.connectRHS(receiver, weight=weight)
|
|
187
|
+
```
|
|
188
|
+
|
|
189
|
+
Try several inputs: a connection's effect can depend on the input.
|
|
190
|
+
|
|
191
|
+
You can also change an existing weight through `receiver.weights[source]`. Use the connection methods to add or remove edges so incoming weights and outgoing connections stay consistent.
|
|
192
|
+
|
|
193
|
+
## Examples
|
|
194
|
+
|
|
195
|
+
### The nibble challenge
|
|
196
|
+
|
|
197
|
+
#### Setup
|
|
198
|
+
|
|
199
|
+
Change directory into the example project from the repository root.
|
|
200
|
+
|
|
201
|
+
```
|
|
202
|
+
cd examples/the_nibble_challenge
|
|
203
|
+
```
|
|
204
|
+
|
|
205
|
+
Install the example dependencies.
|
|
206
|
+
|
|
207
|
+
```
|
|
208
|
+
pip install .
|
|
209
|
+
```
|
|
210
|
+
|
|
211
|
+
#### Explore the notebook
|
|
212
|
+
|
|
213
|
+
Open [the nibble challenge notebook](https://github.com/adamjpatterson/neural-lab/blob/main/examples/the_nibble_challenge/main.ipynb). It introduces all sixteen four-bit inputs, constructs a 4 → 8 → 1 network, compares initial and trained predictions, and lets you change an input to inspect weights and activations. With seed 42, a step of 0.01, and 10,000 training examples, the displayed R² rounds to 1.000000000.
|
|
214
|
+
|
|
215
|
+
The network learns a simple linear relationship. Training and evaluation both use all sixteen nibbles; hence, the experiment does not provide evidence of generalization. The notebook imports `visualize_network` from [its visualization module](https://github.com/adamjpatterson/neural-lab/blob/main/examples/the_nibble_challenge/visualizations.py).
|
|
216
|
+
|
|
217
|
+
##### Visualizations of the network before and after training
|
|
218
|
+
|
|
219
|
+
|
|
220
|
+
|
|
221
|
+
- Edge thickness is proportional to the absolute connection weight. Blue is positive; orange is negative. Zero-weight edges have zero width.
|
|
222
|
+
- Node area above a small visibility floor is proportional to absolute activation. Green nodes are inputs, red nodes are hidden, and yellow is the output.
|
|
223
|
+
- Both panels use the same input, positions, and scales. Node size represents activity, not importance, and does not encode the activation's sign.
|
|
224
|
+
|
|
225
|
+
This visualization demonstrates that an irregular-looking network can learn a simple mapping almost perfectly: individual connections can reinforce or cancel one another.
|
|
226
|
+
|
|
227
|
+
### The digits experiment
|
|
228
|
+
|
|
229
|
+
#### Setup
|
|
230
|
+
|
|
231
|
+
Change directory into the example project from the repository root.
|
|
232
|
+
|
|
233
|
+
```bash
|
|
234
|
+
cd examples/the_digits_experiment
|
|
235
|
+
```
|
|
236
|
+
|
|
237
|
+
Install the example dependencies.
|
|
238
|
+
|
|
239
|
+
```bash
|
|
240
|
+
pip install .
|
|
241
|
+
```
|
|
242
|
+
|
|
243
|
+
#### Explore the notebook
|
|
244
|
+
|
|
245
|
+
Open [the digits experiment notebook](https://github.com/adamjpatterson/neural-lab/blob/main/examples/the_digits_experiment/main.ipynb). It starts by displaying the [8×8 digits dataset](https://scikit-learn.org/stable/modules/generated/sklearn.datasets.load_digits.html), then normalizes pixels, creates a training/test split, constructs a 64 → 16 → 10 network, trains, and evaluates unseen images. You can inspect an individual prediction and its ten output scores. Scores are not probabilities.
|
|
246
|
+
|
|
247
|
+
The reproducible settings use seed 42, 1,347 training images, 450 test images, 20 epochs, and a step of 0.001. The example achieves **90.22% test accuracy**, compared with **10.22%** for always predicting the most common training digit.
|
|
248
|
+
|
|
249
|
+
The notebook imports `plot_predictions` and `plot_confusion_matrix` from [its visualization module](https://github.com/adamjpatterson/neural-lab/blob/main/examples/the_digits_experiment/visualizations.py).
|
|
250
|
+
|
|
251
|
+
#### Digits predictions and confusion matrix
|
|
252
|
+
|
|
253
|
+
The prediction figure shows the first twelve test images. The confusion matrix includes all 450 test images; rows show the true digit and columns show the predicted digit.
|
|
254
|
+
|
|
255
|
+
|
|
256
|
+
|
|
257
|
+
## Tests
|
|
258
|
+
|
|
259
|
+
The suite in `tests/test.py` checks forward calculations, manual gradients, parameter updates, connection removal and restoration, and input validation.
|
|
260
|
+
|
|
261
|
+
#### Run all tests.
|
|
262
|
+
|
|
263
|
+
```bash
|
|
264
|
+
python -m unittest -v
|
|
265
|
+
```
|
|
266
|
+
|
|
267
|
+
## Documentation maintenance
|
|
268
|
+
|
|
269
|
+
### Regenerating README figures
|
|
270
|
+
|
|
271
|
+
The [documentation-image project](https://github.com/adamjpatterson/neural-lab/blob/main/docs/README.md) has its own dependencies and fixed seed-42 scenarios. From `docs/`, after following its environment setup:
|
|
272
|
+
|
|
273
|
+
```bash
|
|
274
|
+
python generate_images.py
|
|
275
|
+
```
|
|
276
|
+
|
|
277
|
+
It writes the nibble network image and the combined digits predictions and confusion matrix image to `images/`.
|
|
278
|
+
|
|
279
|
+
## Support
|
|
280
|
+
|
|
281
|
+
If you have a feature request or run into any issues, feel free to submit an [issue](https://github.com/adamjpatterson/neural-lab/issues). You’re also welcome to reach out to one of the authors.
|
|
282
|
+
|
|
283
|
+
- [Adam Patterson](https://github.com/adamjpatterson)
|