model2data 1.0.0__tar.gz → 1.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {model2data-1.0.0/model2data.egg-info → model2data-1.1.0}/PKG-INFO +1 -1
- {model2data-1.0.0 → model2data-1.1.0}/README.md +20 -9
- {model2data-1.0.0 → model2data-1.1.0}/model2data/cli.py +64 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/generate/core.py +21 -5
- {model2data-1.0.0 → model2data-1.1.0/model2data.egg-info}/PKG-INFO +1 -1
- {model2data-1.0.0 → model2data-1.1.0}/pyproject.toml +1 -1
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_cli.py +55 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_generation.py +81 -8
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_release_stress.py +8 -8
- {model2data-1.0.0 → model2data-1.1.0}/LICENSE +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/README_PYPI.md +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/__init__.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/dbt/__init__.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/dbt/project.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/dbt/templates/dbt_project.yml.jinja +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/dbt/templates/macros/generate_schema_name.sql +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/dbt/templates/profiles.yml.jinja +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/dbt/tests.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/generate/__init__.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/generate/faker.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/generate/relationships.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/parse/__init__.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/parse/dbml.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data/utils.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data.egg-info/SOURCES.txt +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data.egg-info/dependency_links.txt +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data.egg-info/entry_points.txt +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data.egg-info/requires.txt +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/model2data.egg-info/top_level.txt +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/setup.cfg +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_coverage_gaps.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_dbml_parser.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_dbml_parser_fuzz.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_dbt_integration.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_dbt_naming.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_dbt_project.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_dbt_tests.py +0 -0
- {model2data-1.0.0 → model2data-1.1.0}/tests/test_faker_name_inference.py +0 -0
|
@@ -5,6 +5,8 @@
|
|
|
5
5
|
[](https://codecov.io/gh/JB-Analytica/model2data)
|
|
6
6
|
[](LICENSE)
|
|
7
7
|
|
|
8
|
+
Built and maintained by [JB Analytica](https://www.jbanalytica.com/) — data platform architecture and analytics engineering.
|
|
9
|
+
|
|
8
10
|
**Turn a data model into a running analytics stack in one command.**
|
|
9
11
|
|
|
10
12
|
Give `model2data` a [DBML](https://dbml.dbdiagram.io/docs/) schema — hand-written or exported
|
|
@@ -13,17 +15,17 @@ from an existing database — and it generates realistic, relationship-preservin
|
|
|
13
15
|
DuckDB or Postgres profile. No sample data to hunt down, no dbt boilerplate to hand-write, no
|
|
14
16
|
production data to risk exposing.
|
|
15
17
|
|
|
18
|
+
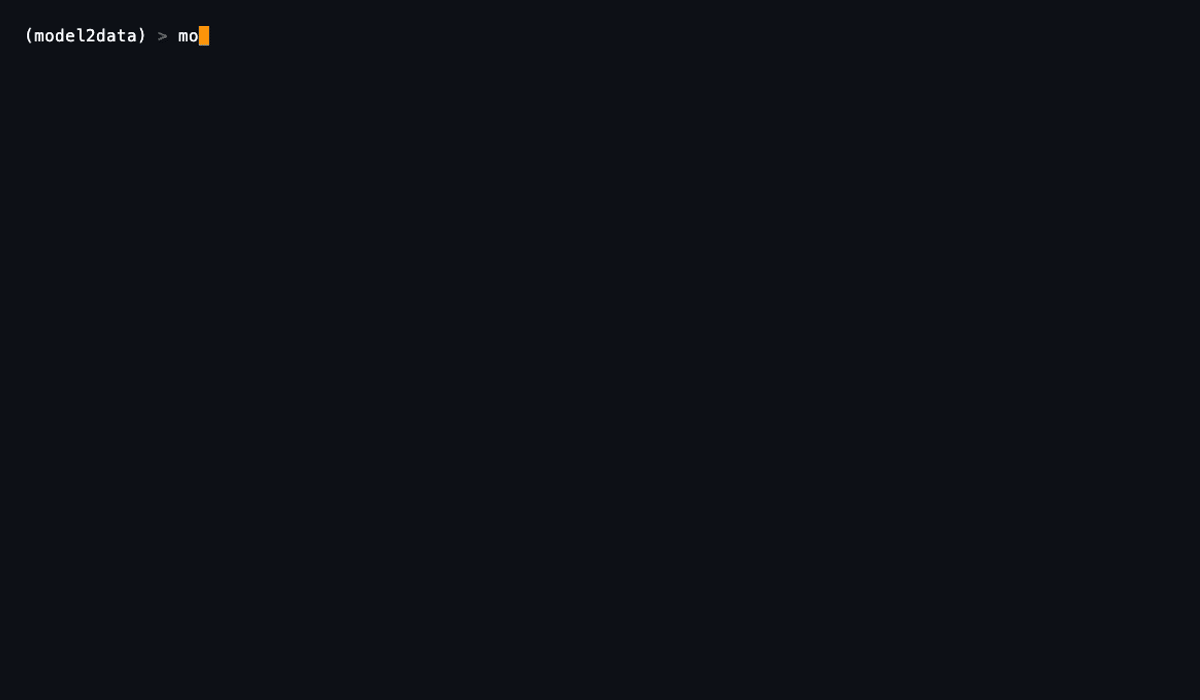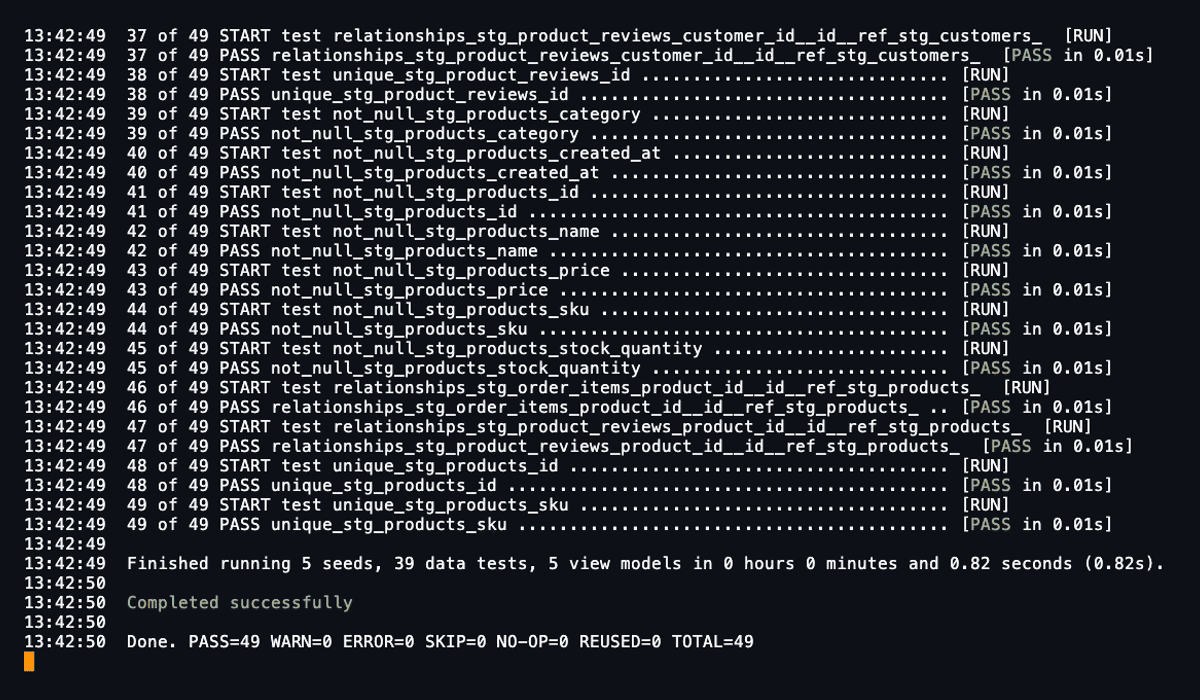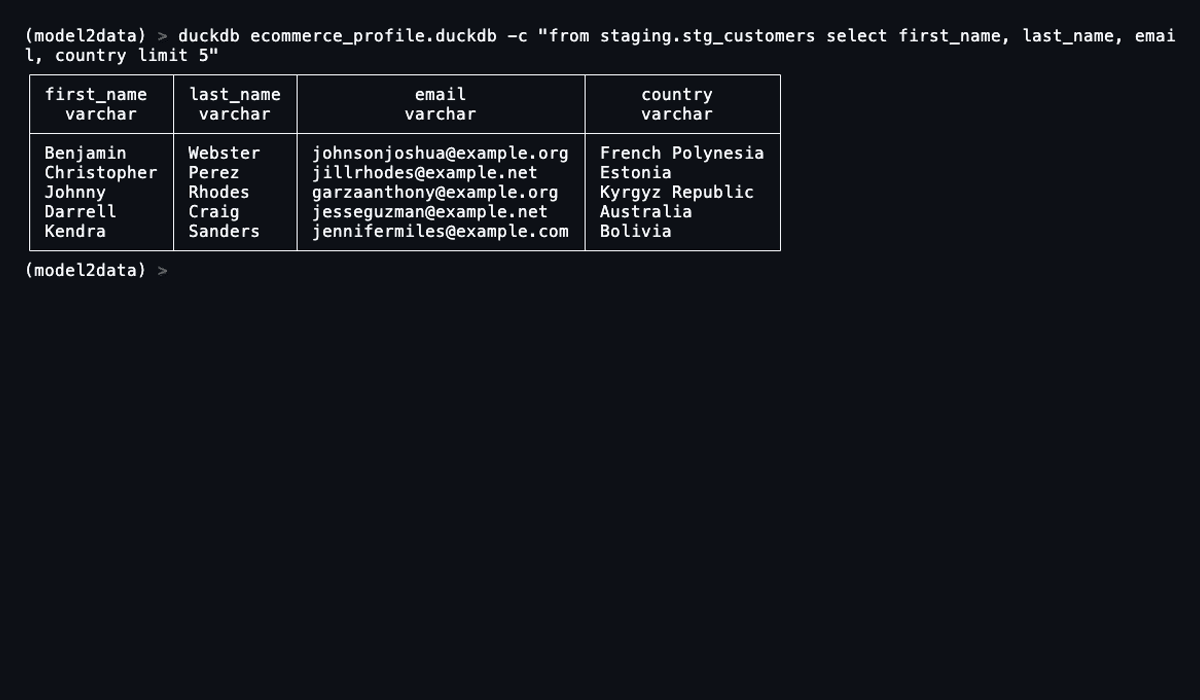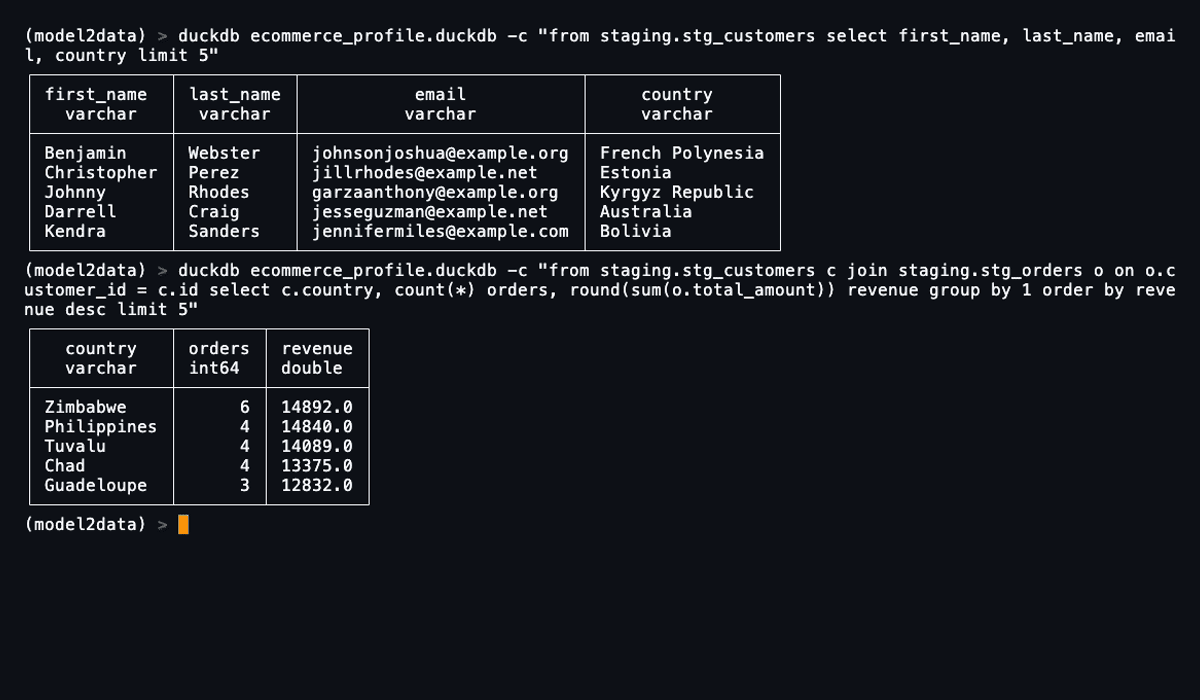
A working analytics stack — real (synthetic) data, tested dbt models, queryable in
|
|
19
|
+
DuckDB — from a schema file, in seconds:
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
|
|
16
23
|
```bash
|
|
17
24
|
pip install model2data
|
|
18
25
|
model2data --file examples/ecommerce.dbml --rows 200 --seed 42
|
|
19
26
|
cd dbt_ecommerce && dbt build
|
|
20
27
|
```
|
|
21
28
|
|
|
22
|
-
That's a working analytics stack — real (synthetic) data, tested dbt models, queryable in
|
|
23
|
-
DuckDB — from a schema file, in seconds:
|
|
24
|
-
|
|
25
|
-

|
|
26
|
-
|
|
27
29
|
---
|
|
28
30
|
|
|
29
31
|
## Why this exists
|
|
@@ -126,6 +128,14 @@ model2data --file examples/ecommerce.dbml --rows 200 --seed 42
|
|
|
126
128
|
|
|
127
129
|
This creates a `dbt_ecommerce/` folder with your data and dbt setup.
|
|
128
130
|
|
|
131
|
+
Real schemas are rarely uniform. `--rows-for` sizes individual tables, so a handful of customers
|
|
132
|
+
can sit behind a large orders table the way they would in the warehouse you're modelling:
|
|
133
|
+
|
|
134
|
+
```bash
|
|
135
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42 \
|
|
136
|
+
--rows-for customers=50 --rows-for order_items=5000
|
|
137
|
+
```
|
|
138
|
+
|
|
129
139
|
Run dbt to load, transform, and test the data:
|
|
130
140
|
|
|
131
141
|
```bash
|
|
@@ -251,10 +261,11 @@ If you're pinned to an older dbt-core, use model2data 0.5.x, which supported dow
|
|
|
251
261
|
|
|
252
262
|
## Project status
|
|
253
263
|
|
|
254
|
-
As of `1.0.0`, model2data is
|
|
255
|
-
DBML schema into realistic synthetic data and a runnable dbt project, reliably.
|
|
256
|
-
|
|
257
|
-
|
|
264
|
+
As of `1.0.0`, model2data is stable and feature-complete for its intended use case: turning a
|
|
265
|
+
DBML schema into realistic synthetic data and a runnable dbt project, reliably. It is actively
|
|
266
|
+
maintained — CI runs a real `dbt build` against both the oldest supported dbt-core and the newest
|
|
267
|
+
release on every push, so compatibility is proven rather than assumed. New capabilities are not
|
|
268
|
+
the focus; correctness, dbt-core compatibility and community contributions are.
|
|
258
269
|
|
|
259
270
|
Ideas that came up during development but were deliberately left out of scope, in case anyone
|
|
260
271
|
wants to pick them up as a contribution:
|
|
@@ -27,6 +27,53 @@ from model2data.utils import normalize_identifier
|
|
|
27
27
|
|
|
28
28
|
SUPPORTED_ADAPTERS = ("duckdb", "postgres")
|
|
29
29
|
|
|
30
|
+
|
|
31
|
+
def _parse_row_overrides(
|
|
32
|
+
raw: Optional[list[str]],
|
|
33
|
+
tables: dict,
|
|
34
|
+
) -> dict[str, int]:
|
|
35
|
+
"""Turn repeated `--rows-for TABLE=N` values into a {table: rows} mapping.
|
|
36
|
+
|
|
37
|
+
Fails loudly rather than silently ignoring a typo: naming a table that
|
|
38
|
+
isn't in the schema almost always means a misspelling, and quietly
|
|
39
|
+
generating the default row count for it would be discovered only by
|
|
40
|
+
counting rows in the output.
|
|
41
|
+
"""
|
|
42
|
+
# `main` is also called directly as a plain function (see tests/), which
|
|
43
|
+
# bypasses Typer and leaves this parameter holding its `OptionInfo` default
|
|
44
|
+
# rather than None. Anything that isn't an actual list means "not supplied".
|
|
45
|
+
if not isinstance(raw, (list, tuple)):
|
|
46
|
+
return {}
|
|
47
|
+
|
|
48
|
+
overrides: dict[str, int] = {}
|
|
49
|
+
for item in raw:
|
|
50
|
+
table_name, separator, count = item.partition("=")
|
|
51
|
+
table_name = table_name.strip()
|
|
52
|
+
if not separator or not table_name:
|
|
53
|
+
raise typer.BadParameter(f"Expected TABLE=N, got {item!r}.", param_hint="--rows-for")
|
|
54
|
+
|
|
55
|
+
try:
|
|
56
|
+
rows = int(count)
|
|
57
|
+
except ValueError:
|
|
58
|
+
raise typer.BadParameter(
|
|
59
|
+
f"Row count for {table_name!r} must be a whole number, got {count!r}.",
|
|
60
|
+
param_hint="--rows-for",
|
|
61
|
+
) from None
|
|
62
|
+
if rows < 1:
|
|
63
|
+
raise typer.BadParameter(
|
|
64
|
+
f"Row count for {table_name!r} must be at least 1, got {rows}.",
|
|
65
|
+
param_hint="--rows-for",
|
|
66
|
+
)
|
|
67
|
+
if table_name not in tables:
|
|
68
|
+
known = ", ".join(sorted(tables)) or "none"
|
|
69
|
+
raise typer.BadParameter(
|
|
70
|
+
f"No table named {table_name!r} in this schema. Tables: {known}.",
|
|
71
|
+
param_hint="--rows-for",
|
|
72
|
+
)
|
|
73
|
+
overrides[table_name] = rows
|
|
74
|
+
return overrides
|
|
75
|
+
|
|
76
|
+
|
|
30
77
|
app = typer.Typer(
|
|
31
78
|
help=(
|
|
32
79
|
"model2data: Generate analytics-ready datasets from DBML models.\n\n"
|
|
@@ -59,6 +106,17 @@ def main(
|
|
|
59
106
|
min=10,
|
|
60
107
|
help="Number of rows to generate per table.",
|
|
61
108
|
),
|
|
109
|
+
# noqa: B008 is only needed here (not on the other options) because a
|
|
110
|
+
# repeatable option must be annotated with a mutable `list` type.
|
|
111
|
+
rows_for: Optional[list[str]] = typer.Option( # noqa: B008
|
|
112
|
+
None,
|
|
113
|
+
"--rows-for",
|
|
114
|
+
metavar="TABLE=N",
|
|
115
|
+
help=(
|
|
116
|
+
"Row count for one table, overriding --rows. Repeatable, e.g.\n"
|
|
117
|
+
"--rows-for customers=200 --rows-for orders=5000."
|
|
118
|
+
),
|
|
119
|
+
),
|
|
62
120
|
seed: Optional[int] = typer.Option(
|
|
63
121
|
None,
|
|
64
122
|
"--seed",
|
|
@@ -124,6 +182,11 @@ def main(
|
|
|
124
182
|
typer.echo("❌ No tables found in the provided DBML file.")
|
|
125
183
|
raise typer.Exit(1)
|
|
126
184
|
|
|
185
|
+
# Validated before anything touches the filesystem: a typo'd table name here
|
|
186
|
+
# should not leave a half-scaffolded project behind for the next run to trip
|
|
187
|
+
# over with a confusing "destination already exists".
|
|
188
|
+
row_overrides = _parse_row_overrides(rows_for, tables)
|
|
189
|
+
|
|
127
190
|
project_name = normalize_identifier(name or file.stem)
|
|
128
191
|
dest = Path.cwd() / f"dbt_{project_name}"
|
|
129
192
|
profile_name = f"{project_name}_profile"
|
|
@@ -150,6 +213,7 @@ def main(
|
|
|
150
213
|
refs=refs,
|
|
151
214
|
base_rows=rows,
|
|
152
215
|
seed=seed,
|
|
216
|
+
row_overrides=row_overrides,
|
|
153
217
|
)
|
|
154
218
|
|
|
155
219
|
# -------------------------
|
|
@@ -2,6 +2,7 @@ from __future__ import annotations
|
|
|
2
2
|
|
|
3
3
|
import random
|
|
4
4
|
from collections import defaultdict, deque
|
|
5
|
+
from collections.abc import Mapping
|
|
5
6
|
from typing import Optional
|
|
6
7
|
|
|
7
8
|
import pandas as pd
|
|
@@ -64,10 +65,19 @@ def generate_data_from_dbml(
|
|
|
64
65
|
refs: list[dict],
|
|
65
66
|
base_rows: int = 100,
|
|
66
67
|
seed: Optional[int] = None,
|
|
68
|
+
row_overrides: Optional[Mapping[str, int]] = None,
|
|
67
69
|
) -> dict[str, pd.DataFrame]:
|
|
68
70
|
"""
|
|
69
71
|
Generate synthetic datasets from parsed DBML definitions.
|
|
70
72
|
|
|
73
|
+
`base_rows` is the row count for every table; `row_overrides` sets it per
|
|
74
|
+
table, keyed by DBML table name. Real schemas are rarely uniform -- a
|
|
75
|
+
handful of dimension rows against a fact table two orders of magnitude
|
|
76
|
+
larger is the normal shape, and generating 100 of each makes joins and
|
|
77
|
+
aggregates behave nothing like the warehouse being modelled. Names not
|
|
78
|
+
present in `row_overrides` fall back to `base_rows`; unknown names are
|
|
79
|
+
ignored.
|
|
80
|
+
|
|
71
81
|
This function is deterministic if a seed is provided.
|
|
72
82
|
It performs no filesystem I/O and returns pandas DataFrames.
|
|
73
83
|
"""
|
|
@@ -93,7 +103,7 @@ def generate_data_from_dbml(
|
|
|
93
103
|
|
|
94
104
|
for table_name in ordered_tables:
|
|
95
105
|
table_def = tables[table_name]
|
|
96
|
-
row_count = _determine_row_count(table_def.name, base_rows)
|
|
106
|
+
row_count = _determine_row_count(table_def.name, base_rows, row_overrides)
|
|
97
107
|
|
|
98
108
|
data: dict[str, list] = {}
|
|
99
109
|
|
|
@@ -341,10 +351,16 @@ def _resolve_self_referencing_fks(
|
|
|
341
351
|
return df
|
|
342
352
|
|
|
343
353
|
|
|
344
|
-
def _determine_row_count(
|
|
345
|
-
|
|
346
|
-
|
|
347
|
-
|
|
354
|
+
def _determine_row_count(
|
|
355
|
+
table_name: str,
|
|
356
|
+
base_rows: int,
|
|
357
|
+
row_overrides: Optional[Mapping[str, int]] = None,
|
|
358
|
+
) -> int:
|
|
359
|
+
"""Return the row count for one table: its override, else `base_rows`."""
|
|
360
|
+
if row_overrides:
|
|
361
|
+
override = row_overrides.get(table_name)
|
|
362
|
+
if override is not None:
|
|
363
|
+
return override
|
|
348
364
|
return base_rows
|
|
349
365
|
|
|
350
366
|
|
|
@@ -777,3 +777,58 @@ def test_cli_summary_is_quiet_when_uniqueness_is_satisfiable(tmp_path):
|
|
|
777
777
|
assert result.exit_code == 0
|
|
778
778
|
assert "duplicate row(s)" not in result.stdout
|
|
779
779
|
assert "duplicate value(s)" not in result.stdout
|
|
780
|
+
|
|
781
|
+
|
|
782
|
+
ROWS_FOR_SCHEMA = """
|
|
783
|
+
Table users {
|
|
784
|
+
id int [pk]
|
|
785
|
+
email email [unique]
|
|
786
|
+
}
|
|
787
|
+
Table orders {
|
|
788
|
+
id int [pk]
|
|
789
|
+
user_id int [not null]
|
|
790
|
+
}
|
|
791
|
+
Ref: orders.user_id > users.id
|
|
792
|
+
"""
|
|
793
|
+
|
|
794
|
+
|
|
795
|
+
def _run_rows_for(tmp_path, *extra_args):
|
|
796
|
+
dbml_file = tmp_path / "shop.dbml"
|
|
797
|
+
dbml_file.write_text(ROWS_FOR_SCHEMA)
|
|
798
|
+
cwd = os.getcwd()
|
|
799
|
+
os.chdir(tmp_path)
|
|
800
|
+
try:
|
|
801
|
+
return runner.invoke(app, ["--file", str(dbml_file), "--rows", "50", *extra_args])
|
|
802
|
+
finally:
|
|
803
|
+
os.chdir(cwd)
|
|
804
|
+
|
|
805
|
+
|
|
806
|
+
def test_cli_rows_for_sets_row_counts_per_table(tmp_path):
|
|
807
|
+
result = _run_rows_for(tmp_path, "--rows-for", "orders=120")
|
|
808
|
+
assert result.exit_code == 0, result.output
|
|
809
|
+
|
|
810
|
+
seeds = tmp_path / "dbt_shop" / "seeds" / "raw"
|
|
811
|
+
assert len(pd.read_csv(seeds / "orders.csv")) == 120
|
|
812
|
+
assert len(pd.read_csv(seeds / "users.csv")) == 50
|
|
813
|
+
|
|
814
|
+
|
|
815
|
+
def test_cli_rows_for_is_repeatable(tmp_path):
|
|
816
|
+
result = _run_rows_for(tmp_path, "--rows-for", "users=10", "--rows-for", "orders=200")
|
|
817
|
+
assert result.exit_code == 0, result.output
|
|
818
|
+
|
|
819
|
+
seeds = tmp_path / "dbt_shop" / "seeds" / "raw"
|
|
820
|
+
assert len(pd.read_csv(seeds / "users.csv")) == 10
|
|
821
|
+
assert len(pd.read_csv(seeds / "orders.csv")) == 200
|
|
822
|
+
|
|
823
|
+
|
|
824
|
+
def test_cli_rows_for_rejects_an_unknown_table(tmp_path):
|
|
825
|
+
"""A typo'd table name would otherwise be discovered by counting rows."""
|
|
826
|
+
result = _run_rows_for(tmp_path, "--rows-for", "userz=10")
|
|
827
|
+
assert result.exit_code != 0
|
|
828
|
+
assert "No table named 'userz'" in result.output
|
|
829
|
+
|
|
830
|
+
|
|
831
|
+
def test_cli_rows_for_rejects_malformed_values(tmp_path):
|
|
832
|
+
assert "Expected TABLE=N" in _run_rows_for(tmp_path, "--rows-for", "users").output
|
|
833
|
+
assert "whole number" in _run_rows_for(tmp_path, "--rows-for", "users=lots").output
|
|
834
|
+
assert "at least 1" in _run_rows_for(tmp_path, "--rows-for", "users=0").output
|
|
@@ -670,7 +670,7 @@ def test_enum_column_whose_name_contains_int_does_not_crash_dtype_coercion():
|
|
|
670
670
|
assert set(df["maintenance_type"]) <= {"oil_change", "repair", "cleaning"}
|
|
671
671
|
|
|
672
672
|
|
|
673
|
-
def test_composite_key_dedup_retry_preserves_fk_validity(
|
|
673
|
+
def test_composite_key_dedup_retry_preserves_fk_validity():
|
|
674
674
|
# Regression test: a join/bridge table's composite key is almost always
|
|
675
675
|
# built from FK columns (posts/tags -> post_tags is the canonical
|
|
676
676
|
# example). When two parent tables are small relative to the bridge
|
|
@@ -679,7 +679,6 @@ def test_composite_key_dedup_retry_preserves_fk_validity(monkeypatch):
|
|
|
679
679
|
# type-based generator instead of resampling from the real parent id
|
|
680
680
|
# pool, silently producing post_id/tag_id values that referenced no
|
|
681
681
|
# real parent row at all.
|
|
682
|
-
import model2data.generate.core as core
|
|
683
682
|
|
|
684
683
|
tables = {
|
|
685
684
|
"posts": TableDef(name="posts", columns=[ColumnDef("id", "int", {"pk"})]),
|
|
@@ -710,12 +709,13 @@ def test_composite_key_dedup_retry_preserves_fk_validity(monkeypatch):
|
|
|
710
709
|
|
|
711
710
|
# Force posts/tags to 5 rows each (25 possible combos) while post_tags
|
|
712
711
|
# gets 200 rows, guaranteeing heavy dedup-retry activity.
|
|
713
|
-
|
|
714
|
-
|
|
715
|
-
|
|
716
|
-
|
|
717
|
-
|
|
718
|
-
|
|
712
|
+
data = generate_data_from_dbml(
|
|
713
|
+
tables,
|
|
714
|
+
refs,
|
|
715
|
+
base_rows=200,
|
|
716
|
+
seed=123,
|
|
717
|
+
row_overrides={"posts": 5, "tags": 5},
|
|
718
|
+
)
|
|
719
719
|
|
|
720
720
|
post_ids = set(data["posts"]["id"].tolist())
|
|
721
721
|
tag_ids = set(data["tags"]["id"].tolist())
|
|
@@ -885,3 +885,76 @@ def test_timestamp_generation_is_reproducible_across_runs():
|
|
|
885
885
|
assert list(first["created_at"]) == list(second["created_at"])
|
|
886
886
|
# No sub-second component at all, so a CSV round-trip stays stable too.
|
|
887
887
|
assert all(ts.endswith(":00") or "." not in ts for ts in map(str, first["created_at"]))
|
|
888
|
+
|
|
889
|
+
|
|
890
|
+
def _users_and_orders() -> tuple[dict, list[dict]]:
|
|
891
|
+
tables = {
|
|
892
|
+
"users": TableDef(
|
|
893
|
+
name="users",
|
|
894
|
+
columns=[ColumnDef("id", "int", {"pk"}), ColumnDef("email", "email", {"unique"})],
|
|
895
|
+
),
|
|
896
|
+
"orders": TableDef(
|
|
897
|
+
name="orders",
|
|
898
|
+
columns=[
|
|
899
|
+
ColumnDef("id", "int", {"pk"}),
|
|
900
|
+
ColumnDef("user_id", "int", {"not null"}),
|
|
901
|
+
ColumnDef("total", "numeric"),
|
|
902
|
+
],
|
|
903
|
+
),
|
|
904
|
+
}
|
|
905
|
+
refs = [
|
|
906
|
+
{
|
|
907
|
+
"source_table": "orders",
|
|
908
|
+
"source_column": "user_id",
|
|
909
|
+
"target_table": "users",
|
|
910
|
+
"target_column": "id",
|
|
911
|
+
}
|
|
912
|
+
]
|
|
913
|
+
return tables, refs
|
|
914
|
+
|
|
915
|
+
|
|
916
|
+
def test_row_overrides_set_row_counts_per_table():
|
|
917
|
+
tables, refs = _users_and_orders()
|
|
918
|
+
|
|
919
|
+
data = generate_data_from_dbml(
|
|
920
|
+
tables, refs, base_rows=50, seed=1, row_overrides={"orders": 300}
|
|
921
|
+
)
|
|
922
|
+
|
|
923
|
+
assert len(data["orders"]) == 300
|
|
924
|
+
assert len(data["users"]) == 50, "tables without an override keep base_rows"
|
|
925
|
+
|
|
926
|
+
|
|
927
|
+
def test_row_overrides_default_to_base_rows_and_ignore_unknown_tables():
|
|
928
|
+
tables, refs = _users_and_orders()
|
|
929
|
+
|
|
930
|
+
data = generate_data_from_dbml(
|
|
931
|
+
tables, refs, base_rows=20, seed=1, row_overrides={"nonexistent": 999}
|
|
932
|
+
)
|
|
933
|
+
|
|
934
|
+
assert {name: len(df) for name, df in data.items()} == {"users": 20, "orders": 20}
|
|
935
|
+
|
|
936
|
+
|
|
937
|
+
def test_foreign_keys_stay_valid_when_the_child_is_much_larger_than_its_parent():
|
|
938
|
+
"""The point of per-table counts: a small dimension against a large fact."""
|
|
939
|
+
tables, refs = _users_and_orders()
|
|
940
|
+
|
|
941
|
+
data = generate_data_from_dbml(
|
|
942
|
+
tables, refs, base_rows=100, seed=42, row_overrides={"users": 5, "orders": 2000}
|
|
943
|
+
)
|
|
944
|
+
|
|
945
|
+
assert len(data["users"]) == 5
|
|
946
|
+
assert len(data["orders"]) == 2000
|
|
947
|
+
assert set(data["orders"]["user_id"]) <= set(data["users"]["id"])
|
|
948
|
+
# A 5-row parent still has to have unique keys for the FK to mean anything.
|
|
949
|
+
assert data["users"]["id"].is_unique
|
|
950
|
+
|
|
951
|
+
|
|
952
|
+
def test_row_overrides_are_deterministic_with_a_seed():
|
|
953
|
+
tables, refs = _users_and_orders()
|
|
954
|
+
overrides = {"users": 25, "orders": 175}
|
|
955
|
+
|
|
956
|
+
first = generate_data_from_dbml(tables, refs, base_rows=50, seed=9, row_overrides=overrides)
|
|
957
|
+
second = generate_data_from_dbml(tables, refs, base_rows=50, seed=9, row_overrides=overrides)
|
|
958
|
+
|
|
959
|
+
assert first["users"].equals(second["users"])
|
|
960
|
+
assert first["orders"].equals(second["orders"])
|
|
@@ -26,7 +26,6 @@ from pathlib import Path
|
|
|
26
26
|
|
|
27
27
|
import pytest
|
|
28
28
|
|
|
29
|
-
import model2data.generate.core as core
|
|
30
29
|
from model2data.generate.core import generate_data_from_dbml
|
|
31
30
|
from model2data.generate.relationships import build_fk_lookup, classify_refs
|
|
32
31
|
from model2data.parse.dbml import ColumnDef, TableDef, parse_dbml
|
|
@@ -187,7 +186,7 @@ def _bridge_schema():
|
|
|
187
186
|
)
|
|
188
187
|
@pytest.mark.parametrize("seed", list(range(1, 16))) # 15 seeds
|
|
189
188
|
def test_composite_key_dedup_extreme_value_space_stress(
|
|
190
|
-
seed, parent_rows, bridge_rows, uniqueness_achievable
|
|
189
|
+
seed, parent_rows, bridge_rows, uniqueness_achievable
|
|
191
190
|
):
|
|
192
191
|
# Extends the original bug-1 regression test
|
|
193
192
|
# (test_composite_key_dedup_retry_preserves_fk_validity in
|
|
@@ -199,12 +198,13 @@ def test_composite_key_dedup_extreme_value_space_stress(
|
|
|
199
198
|
# surface at all.
|
|
200
199
|
tables, refs = _bridge_schema()
|
|
201
200
|
|
|
202
|
-
|
|
203
|
-
|
|
204
|
-
|
|
205
|
-
|
|
206
|
-
|
|
207
|
-
|
|
201
|
+
data = generate_data_from_dbml(
|
|
202
|
+
tables,
|
|
203
|
+
refs,
|
|
204
|
+
base_rows=bridge_rows,
|
|
205
|
+
seed=seed,
|
|
206
|
+
row_overrides={"posts": parent_rows, "tags": parent_rows},
|
|
207
|
+
)
|
|
208
208
|
|
|
209
209
|
post_ids = set(data["posts"]["id"].tolist())
|
|
210
210
|
tag_ids = set(data["tags"]["id"].tolist())
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{model2data-1.0.0 → model2data-1.1.0}/model2data/dbt/templates/macros/generate_schema_name.sql
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|