model2data 0.5.0__tar.gz → 1.0.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- model2data-1.0.0/PKG-INFO +312 -0
- model2data-0.5.0/PKG-INFO → model2data-1.0.0/README.md +84 -73
- model2data-0.5.0/model2data.egg-info/PKG-INFO → model2data-1.0.0/README_PYPI.md +86 -109
- {model2data-0.5.0 → model2data-1.0.0}/model2data/cli.py +27 -5
- {model2data-0.5.0 → model2data-1.0.0}/model2data/dbt/project.py +10 -3
- {model2data-0.5.0 → model2data-1.0.0}/model2data/dbt/templates/dbt_project.yml.jinja +7 -3
- {model2data-0.5.0 → model2data-1.0.0}/model2data/dbt/tests.py +73 -47
- {model2data-0.5.0 → model2data-1.0.0}/model2data/generate/core.py +109 -5
- {model2data-0.5.0 → model2data-1.0.0}/model2data/generate/faker.py +94 -16
- {model2data-0.5.0 → model2data-1.0.0}/model2data/parse/dbml.py +91 -14
- model2data-1.0.0/model2data.egg-info/PKG-INFO +312 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data.egg-info/SOURCES.txt +4 -1
- {model2data-0.5.0 → model2data-1.0.0}/model2data.egg-info/requires.txt +3 -3
- {model2data-0.5.0 → model2data-1.0.0}/pyproject.toml +39 -6
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_cli.py +76 -6
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_dbml_parser.py +290 -1
- model2data-1.0.0/tests/test_dbml_parser_fuzz.py +281 -0
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_dbt_integration.py +51 -10
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_dbt_project.py +7 -3
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_dbt_tests.py +233 -23
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_generation.py +288 -4
- model2data-1.0.0/tests/test_release_stress.py +351 -0
- model2data-0.5.0/README.md +0 -266
- {model2data-0.5.0 → model2data-1.0.0}/LICENSE +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/__init__.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/dbt/__init__.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/dbt/templates/macros/generate_schema_name.sql +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/dbt/templates/profiles.yml.jinja +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/generate/__init__.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/generate/relationships.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/parse/__init__.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data/utils.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data.egg-info/dependency_links.txt +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data.egg-info/entry_points.txt +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/model2data.egg-info/top_level.txt +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/setup.cfg +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_coverage_gaps.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_dbt_naming.py +0 -0
- {model2data-0.5.0 → model2data-1.0.0}/tests/test_faker_name_inference.py +0 -0
|
@@ -0,0 +1,312 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: model2data
|
|
3
|
+
Version: 1.0.0
|
|
4
|
+
Summary: Generate analytics-ready datasets from DBML models
|
|
5
|
+
Author: JB Analytica
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/JB-Analytica/model2data
|
|
8
|
+
Project-URL: Repository, https://github.com/JB-Analytica/model2data
|
|
9
|
+
Project-URL: Issues, https://github.com/JB-Analytica/model2data/issues
|
|
10
|
+
Project-URL: Changelog, https://github.com/JB-Analytica/model2data/blob/main/CHANGELOG.md
|
|
11
|
+
Keywords: dbt,dbml,synthetic-data,test-data,analytics-engineering,data-engineering,duckdb,seed-data
|
|
12
|
+
Classifier: Development Status :: 5 - Production/Stable
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Operating System :: OS Independent
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.14
|
|
21
|
+
Classifier: Topic :: Database
|
|
22
|
+
Classifier: Topic :: Software Development :: Testing
|
|
23
|
+
Classifier: Topic :: Scientific/Engineering :: Information Analysis
|
|
24
|
+
Requires-Python: >=3.10
|
|
25
|
+
Description-Content-Type: text/markdown
|
|
26
|
+
License-File: LICENSE
|
|
27
|
+
Requires-Dist: dbt-core>=1.11
|
|
28
|
+
Requires-Dist: dbt-duckdb>=1.11
|
|
29
|
+
Requires-Dist: faker>=37.12.0
|
|
30
|
+
Requires-Dist: pandas>=2.3.3
|
|
31
|
+
Requires-Dist: pyyaml>=6.0.3
|
|
32
|
+
Requires-Dist: typer>=0.20.0
|
|
33
|
+
Provides-Extra: postgres
|
|
34
|
+
Requires-Dist: dbt-postgres>=1.11; extra == "postgres"
|
|
35
|
+
Provides-Extra: dev
|
|
36
|
+
Requires-Dist: pytest; extra == "dev"
|
|
37
|
+
Requires-Dist: pytest-cov; extra == "dev"
|
|
38
|
+
Requires-Dist: pre-commit; extra == "dev"
|
|
39
|
+
Requires-Dist: ruff>=0.1.0; extra == "dev"
|
|
40
|
+
Requires-Dist: ty>=0.0.4; extra == "dev"
|
|
41
|
+
Requires-Dist: types-pyyaml; extra == "dev"
|
|
42
|
+
Requires-Dist: poethepoet>=0.38.0; extra == "dev"
|
|
43
|
+
Dynamic: license-file
|
|
44
|
+
|
|
45
|
+
# model2data
|
|
46
|
+
|
|
47
|
+
[](https://pypi.org/project/model2data/)
|
|
48
|
+
[](https://github.com/JB-Analytica/model2data/actions/workflows/ci.yml)
|
|
49
|
+
[](https://codecov.io/gh/JB-Analytica/model2data)
|
|
50
|
+
[](https://github.com/JB-Analytica/model2data/blob/main/LICENSE)
|
|
51
|
+
|
|
52
|
+
**Turn a data model into a running analytics stack in one command.**
|
|
53
|
+
|
|
54
|
+
Give `model2data` a [DBML](https://dbml.dbdiagram.io/docs/) schema — hand-written or exported
|
|
55
|
+
from an existing database — and it generates realistic, relationship-preserving synthetic data
|
|
56
|
+
*and* a complete, runnable dbt project around it: seeds, staging models, tests, and a
|
|
57
|
+
DuckDB or Postgres profile. No sample data to hunt down, no dbt boilerplate to hand-write, no
|
|
58
|
+
production data to risk exposing.
|
|
59
|
+
|
|
60
|
+
```bash
|
|
61
|
+
pip install model2data
|
|
62
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42
|
|
63
|
+
cd dbt_ecommerce && dbt build
|
|
64
|
+
```
|
|
65
|
+
|
|
66
|
+
That's a working analytics stack — real (synthetic) data, tested dbt models, queryable in
|
|
67
|
+
DuckDB — from a schema file, in seconds:
|
|
68
|
+
|
|
69
|
+
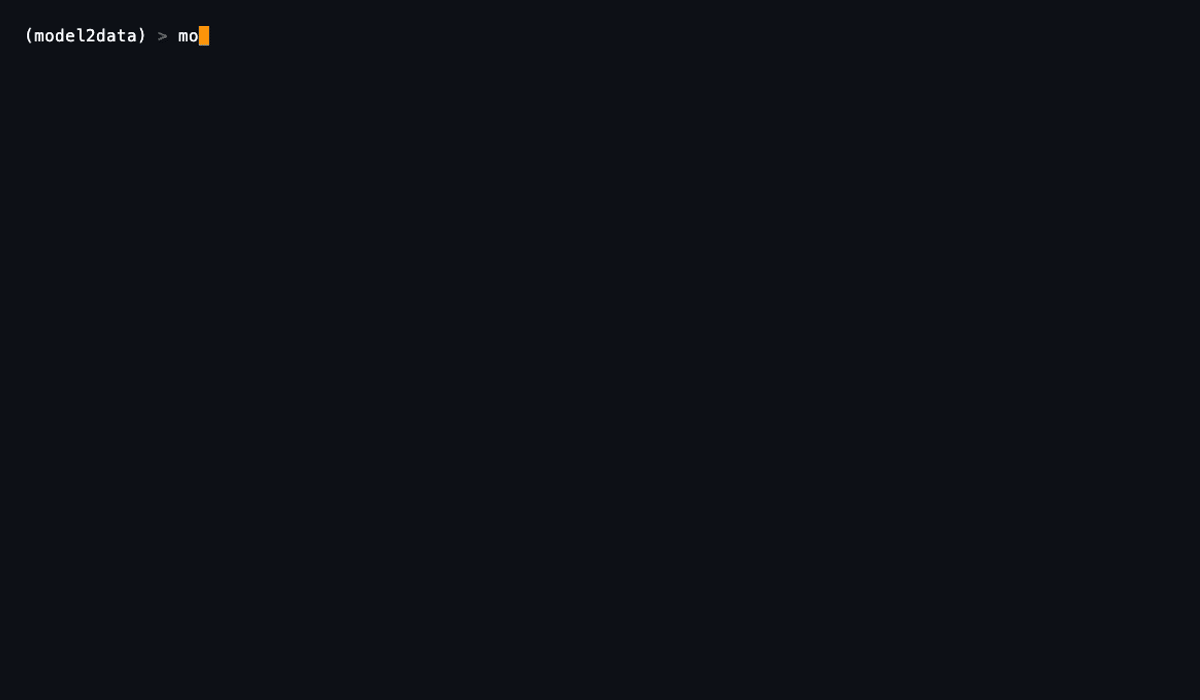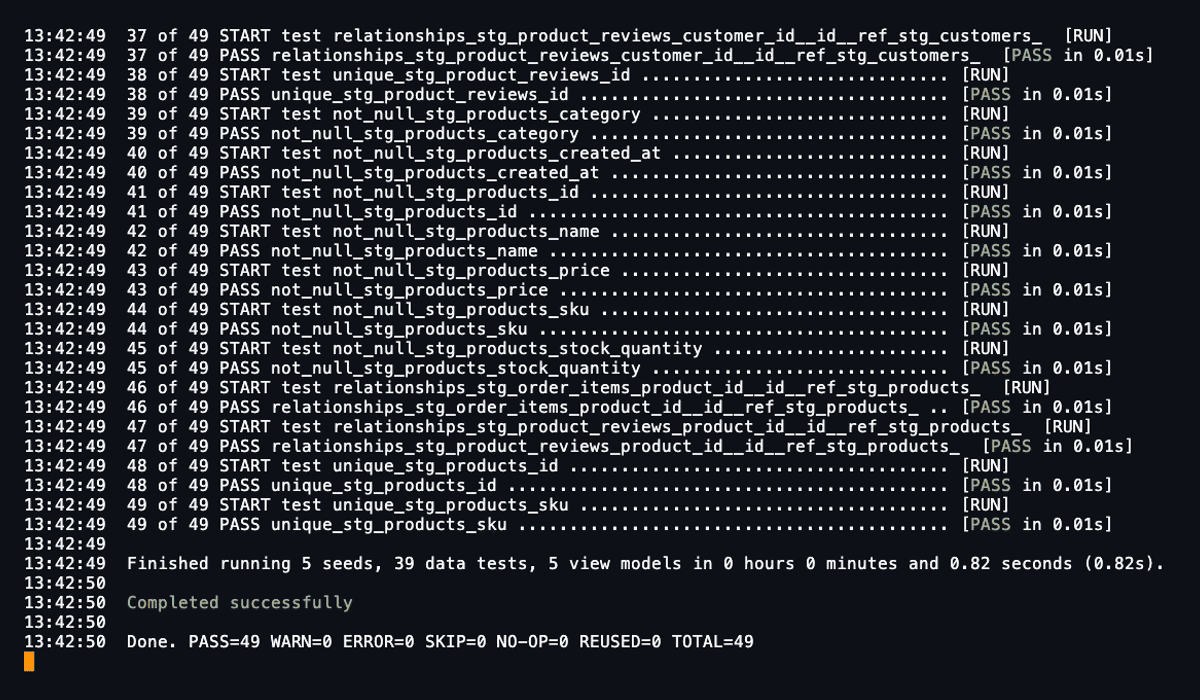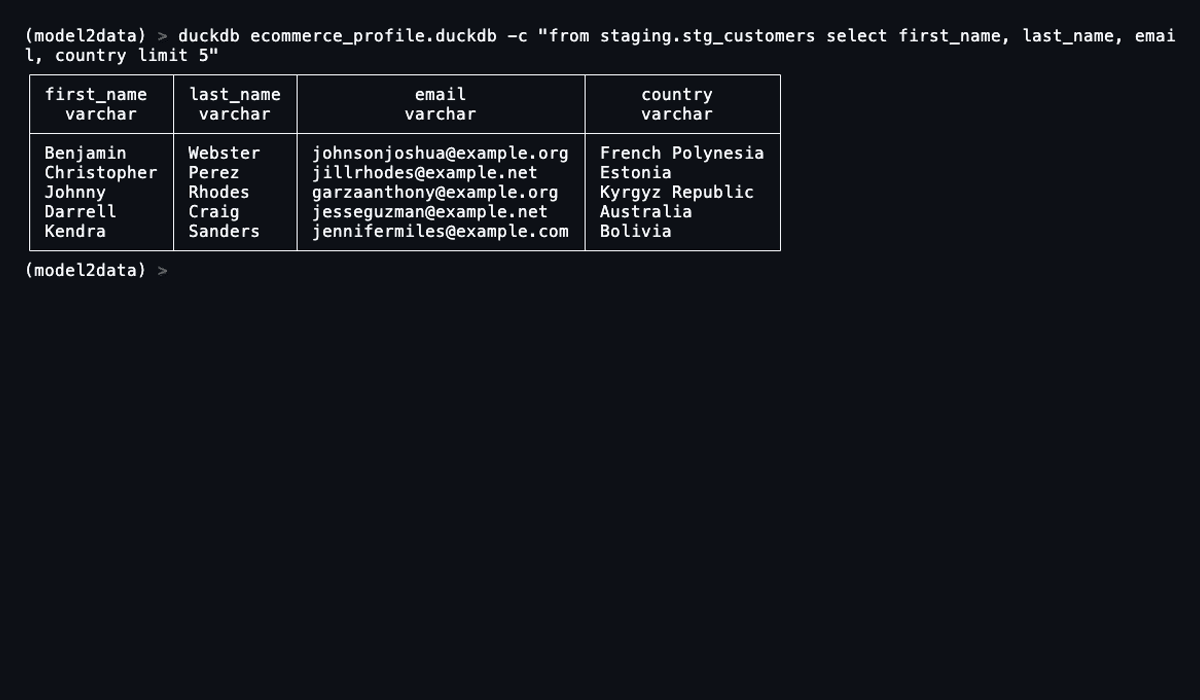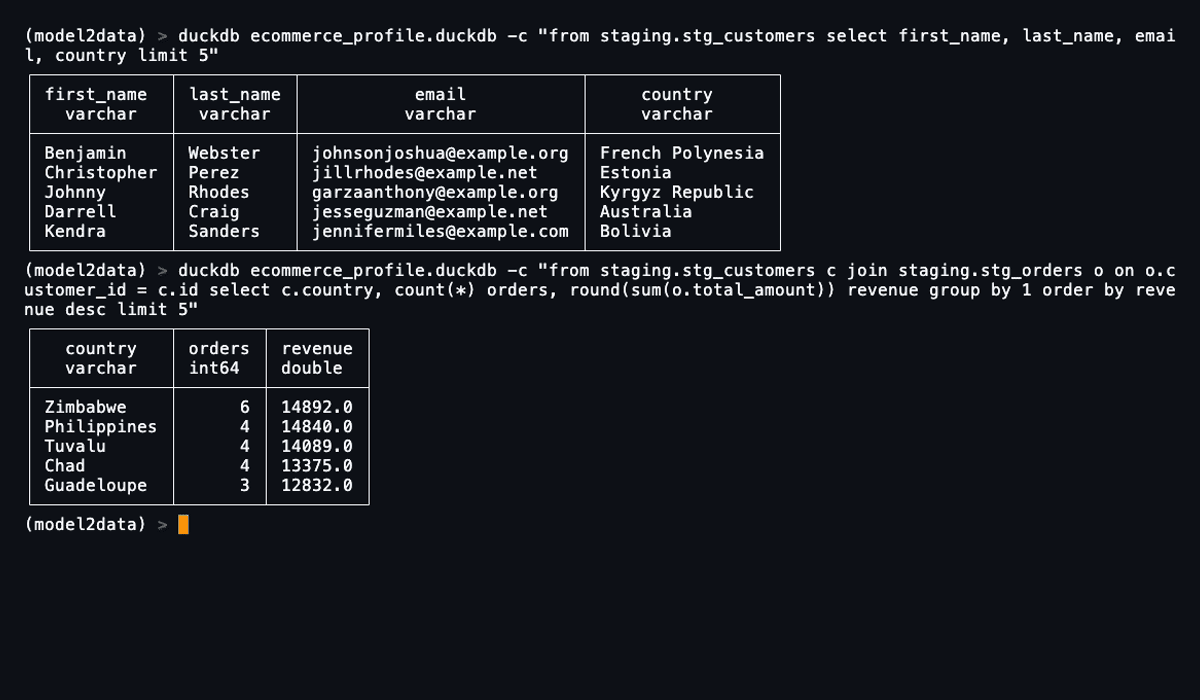
|
|
70
|
+
|
|
71
|
+
---
|
|
72
|
+
|
|
73
|
+
## Why this exists
|
|
74
|
+
|
|
75
|
+
Analytics engineers hit the same wall constantly: you need realistic data to build or test a
|
|
76
|
+
pipeline, but production data is off-limits (privacy, access, scale), and hand-rolling mock CSVs
|
|
77
|
+
is tedious and doesn't scale past two tables. `model2data` closes that gap — from a schema
|
|
78
|
+
definition to a seeded, tested dbt project you can actually run, with no database or production
|
|
79
|
+
access required.
|
|
80
|
+
|
|
81
|
+
- **Privacy-safe.** Nothing but a schema definition goes in; nothing but synthetic data comes out.
|
|
82
|
+
- **Realistic, not random.** Column names are matched against ~35 common patterns — `email`,
|
|
83
|
+
`first_name`, `city`, `phone`, `company`, ... — so a column called `email` gets real-looking
|
|
84
|
+
emails, not `Lorem ipsum` text.
|
|
85
|
+
- **Relationship-preserving.** Foreign keys resolve to real parent rows; tables are generated in
|
|
86
|
+
dependency order.
|
|
87
|
+
- **Deterministic.** Pass `--seed` and the same schema always produces the same data — safe to
|
|
88
|
+
commit fixtures, safe to diff across CI runs.
|
|
89
|
+
- **A real dbt project, not just CSVs.** Seeds, staging models that `ref()` them, schema tests,
|
|
90
|
+
and a ready-to-use profile — the thing you'd otherwise spend an afternoon scaffolding by hand.
|
|
91
|
+
A single `dbt build` loads, transforms, and tests the whole thing.
|
|
92
|
+
|
|
93
|
+
## Who is model2data for?
|
|
94
|
+
|
|
95
|
+
- **Analytics engineers** — generate realistic datasets and a working dbt project without
|
|
96
|
+
waiting on production access.
|
|
97
|
+
- **Data engineers** — produce deterministic test data from an existing schema for pipeline and
|
|
98
|
+
migration testing.
|
|
99
|
+
- **Software & data teams** — prototype integrations and analytics workflows without exposing
|
|
100
|
+
production data.
|
|
101
|
+
- **Consultants & architects** — spin up realistic environments for demos, workshops, and
|
|
102
|
+
architecture validation in minutes, not hours.
|
|
103
|
+
|
|
104
|
+
## How it works
|
|
105
|
+
|
|
106
|
+
1. **Parse.** Reads tables, columns, types, and `Ref` relationships from a DBML file.
|
|
107
|
+
2. **Generate.** Produces synthetic values per column — typed generation for known SQL types
|
|
108
|
+
(int, date, timestamp, ...), name-aware inference for everything else (`email`, `phone`,
|
|
109
|
+
`city`, ...), foreign keys resolved against already-generated parent rows.
|
|
110
|
+
3. **Scaffold.** Writes a complete dbt project around that data: CSV seeds, staging models that
|
|
111
|
+
`ref()` those seeds, `not_null`/`unique`/`relationships` tests, `accepted_values` tests for
|
|
112
|
+
DBML `Enum`-typed columns, singular SQL tests for composite primary/unique keys, table and
|
|
113
|
+
column `description:` fields pulled from DBML notes, and a profile for DuckDB (zero-config,
|
|
114
|
+
file-based) or Postgres.
|
|
115
|
+
|
|
116
|
+
---
|
|
117
|
+
|
|
118
|
+
## Installation
|
|
119
|
+
|
|
120
|
+
```bash
|
|
121
|
+
pip install model2data
|
|
122
|
+
```
|
|
123
|
+
|
|
124
|
+
---
|
|
125
|
+
|
|
126
|
+
## Quick start
|
|
127
|
+
|
|
128
|
+
We bundle several example schemas in `examples/` — this walkthrough uses the e-commerce one
|
|
129
|
+
(`examples/ecommerce.dbml`: customers, products, orders, order items, and reviews).
|
|
130
|
+
|
|
131
|
+
Generate a project with synthetic data:
|
|
132
|
+
|
|
133
|
+
```bash
|
|
134
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42
|
|
135
|
+
```
|
|
136
|
+
|
|
137
|
+
This creates a `dbt_ecommerce/` folder with your data and dbt setup.
|
|
138
|
+
|
|
139
|
+
Run dbt to load, transform, and test the data:
|
|
140
|
+
|
|
141
|
+
```bash
|
|
142
|
+
cd dbt_ecommerce
|
|
143
|
+
dbt build
|
|
144
|
+
```
|
|
145
|
+
|
|
146
|
+
Staging models `ref()` their seeds, so a single `dbt build` loads the seeds, builds the models,
|
|
147
|
+
and runs every generated test in one dependency-ordered pass — no separate `dbt seed`/`dbt run`
|
|
148
|
+
needed, even on a brand-new database. (The individual `dbt deps`, `dbt seed`, and `dbt run`
|
|
149
|
+
commands still work if you'd rather drive the steps yourself; the generated project declares no
|
|
150
|
+
packages, so `dbt deps` is a no-op.)
|
|
151
|
+
|
|
152
|
+
Your analytics-ready dataset is now in DuckDB!
|
|
153
|
+
|
|
154
|
+
To target Postgres instead, install the extra and pass `--adapter postgres`:
|
|
155
|
+
|
|
156
|
+
```bash
|
|
157
|
+
pip install "model2data[postgres]"
|
|
158
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42 --adapter postgres
|
|
159
|
+
```
|
|
160
|
+
|
|
161
|
+
Connection details are read from environment variables (`MODEL2DATA_PG_HOST`, `MODEL2DATA_PG_PORT`, `MODEL2DATA_PG_USER`, `MODEL2DATA_PG_PASSWORD`, `MODEL2DATA_PG_DATABASE`), defaulting to `localhost:5432` with a `postgres`/`postgres` user for local development.
|
|
162
|
+
|
|
163
|
+
After generation, the CLI prints a short summary — tables and rows generated, relationships found in the DBML, and any columns that fell back to generic placeholder text because neither their type nor name could be matched.
|
|
164
|
+
|
|
165
|
+
Pass `--unit-tests` to also generate deterministic dbt unit test fixtures (`models/staging/ut_stg_<table>.yml`) from the actually-generated seed rows:
|
|
166
|
+
|
|
167
|
+
```bash
|
|
168
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42 --unit-tests
|
|
169
|
+
```
|
|
170
|
+
|
|
171
|
+
This targets dbt-core's native unit testing feature, which works out of the box with the base
|
|
172
|
+
install — see [dbt-core versions](#dbt-core-versions) below.
|
|
173
|
+
|
|
174
|
+
---
|
|
175
|
+
|
|
176
|
+
## Generated dbt project structure
|
|
177
|
+
|
|
178
|
+
The generated dbt project includes:
|
|
179
|
+
|
|
180
|
+
```
|
|
181
|
+
dbt_{project_name}/
|
|
182
|
+
├── seeds/
|
|
183
|
+
│ └── raw/
|
|
184
|
+
│ ├── __seed_config.yml # seed descriptions + column-type overrides
|
|
185
|
+
│ ├── table1.csv
|
|
186
|
+
│ └── table2.csv
|
|
187
|
+
├── models/
|
|
188
|
+
│ └── staging/
|
|
189
|
+
│ ├── stg_table1.sql
|
|
190
|
+
│ ├── stg_table1.yml
|
|
191
|
+
│ ├── ut_stg_table1.yml # only with --unit-tests
|
|
192
|
+
│ └── ...
|
|
193
|
+
├── data-tests/
|
|
194
|
+
│ └── unique_combination_stg_table1_col_a_col_b.sql # only for composite pk/unique keys
|
|
195
|
+
├── macros/
|
|
196
|
+
│ └── generate_schema_name.sql
|
|
197
|
+
├── dbt_project.yml
|
|
198
|
+
├── profiles.yml # DuckDB or Postgres config, depending on --adapter
|
|
199
|
+
└── {project_name}_profile.duckdb # DuckDB adapter only
|
|
200
|
+
```
|
|
201
|
+
|
|
202
|
+
- **Seeds**: CSV files with generated synthetic data, plus `__seed_config.yml` — each seed's
|
|
203
|
+
`description:` (from the table's DBML `Note`) and the column-type overrides that keep
|
|
204
|
+
all-digit text columns (barcodes, zero-padded postcodes, ...) from being loaded as integers.
|
|
205
|
+
- **Staging Models**: Basic dbt models that `ref()` their seed. Using `ref()` rather than
|
|
206
|
+
declaring the seeds as dbt `sources` is what gives each model a real DAG edge to the seed
|
|
207
|
+
behind it, so one `dbt build` orders seeds before models on a fresh database.
|
|
208
|
+
- **Tests**: A YAML per staging model with column tests (`not_null`, `unique`, `relationships`,
|
|
209
|
+
and `accepted_values` for DBML `Enum`-typed columns). Column `Note` text from the DBML becomes
|
|
210
|
+
`description:` fields.
|
|
211
|
+
- **Composite key tests**: Composite primary/unique keys declared in an `indexes { }` block get
|
|
212
|
+
a singular SQL test under `data-tests/`, dbt's configured `test-paths`.
|
|
213
|
+
- **Profiles**: Pre-configured for DuckDB (file-based) or Postgres (via env vars), with schema handling.
|
|
214
|
+
- **Unit tests** (opt-in via `--unit-tests`): `models/staging/ut_stg_<table>.yml` fixtures built
|
|
215
|
+
from real generated rows, co-located with each staging model so dbt (which only parses unit
|
|
216
|
+
tests from `model-paths`) picks them up.
|
|
217
|
+
|
|
218
|
+
---
|
|
219
|
+
|
|
220
|
+
## Using model2data with an LLM
|
|
221
|
+
|
|
222
|
+
If you want to go from a plain-English description of a data model straight to a running,
|
|
223
|
+
demo-ready dbt project, [LLMS.md](https://github.com/JB-Analytica/model2data/blob/main/LLMS.md) is written for an LLM/agent to read: it covers the
|
|
224
|
+
full DBML feature set model2data understands (enums, notes, defaults, composite keys, both
|
|
225
|
+
relationship syntaxes, self-references) and the exact command sequence to run. Point an
|
|
226
|
+
LLM-backed coding assistant at it and describe your data model — it can author the DBML and run
|
|
227
|
+
model2data for you.
|
|
228
|
+
|
|
229
|
+
---
|
|
230
|
+
|
|
231
|
+
## dbt-core versions
|
|
232
|
+
|
|
233
|
+
model2data requires **dbt-core >= 1.11**, tracking [dbt's own version support
|
|
234
|
+
policy](https://docs.getdbt.com/docs/dbt-versions): dbt Labs supports each minor release for one
|
|
235
|
+
year, and 1.11 is the oldest that still is. Generated projects build cleanly — no deprecation
|
|
236
|
+
warnings — on every supported dbt-core version, and CI proves it on each push by running a real
|
|
237
|
+
`dbt build` against both the stated floor and the newest release.
|
|
238
|
+
|
|
239
|
+
If you're pinned to an older dbt-core, use model2data 0.5.x, which supported down to 1.8.5.
|
|
240
|
+
|
|
241
|
+
---
|
|
242
|
+
|
|
243
|
+
## Design decisions / non-goals
|
|
244
|
+
|
|
245
|
+
- **DuckDB Default**: Chosen for its zero-config, file-based nature, making it easy to get started without database setup. Postgres is supported via `--adapter postgres`; other adapters can be configured manually.
|
|
246
|
+
- **dbt Integration**: Leverages dbt's transformation capabilities for a familiar workflow in analytics engineering.
|
|
247
|
+
- **Synthetic Data**: Uses deterministic generation for reproducibility; not intended for production use or as a replacement for real data.
|
|
248
|
+
- **Non-goals**: This is not a data migration tool, ETL pipeline, or real-time data generator. It focuses on static, synthetic datasets for testing and prototyping.
|
|
249
|
+
|
|
250
|
+
---
|
|
251
|
+
|
|
252
|
+
## Limitations
|
|
253
|
+
|
|
254
|
+
- Synthetic data generation is heuristic-based (typed generation, name-aware inference, enum/default awareness) and may not perfectly mimic real-world distributions or edge cases.
|
|
255
|
+
- DuckDB and Postgres are supported today; other databases require manual profile adjustments.
|
|
256
|
+
- No support for incremental models or advanced dbt features in generated projects.
|
|
257
|
+
- Composite foreign keys (across a bridge/join table) are generated as independent single-column FKs — each column's values are individually valid, but the *combination* isn't guaranteed to match a real parent composite key unless that key is separately enforced via `indexes { }`.
|
|
258
|
+
- Any DBML the parser can't fully make sense of (a malformed line, a ref pointing at an unknown table, an unrecognized column definition) is reported as a warning in the CLI's summary rather than silently dropped — check that summary after generating from a schema you didn't author yourself.
|
|
259
|
+
|
|
260
|
+
---
|
|
261
|
+
|
|
262
|
+
## Project status
|
|
263
|
+
|
|
264
|
+
As of `1.0.0`, model2data is considered **feature-complete for its intended use case**: turning a
|
|
265
|
+
DBML schema into realistic synthetic data and a runnable dbt project, reliably. There's no active
|
|
266
|
+
roadmap of new capabilities planned — the focus from here is maintenance: bug fixes, keeping pace
|
|
267
|
+
with new dbt-core releases, and reviewing community contributions.
|
|
268
|
+
|
|
269
|
+
Ideas that came up during development but were deliberately left out of scope, in case anyone
|
|
270
|
+
wants to pick them up as a contribution:
|
|
271
|
+
|
|
272
|
+
- Additional database adapters (e.g. Snowflake, BigQuery).
|
|
273
|
+
- A rule-based semantic layer scaffold (`semantic_models.yml`/basic metrics) derived from the
|
|
274
|
+
parsed schema shape.
|
|
275
|
+
- Example mart-layer models on top of staging (the generated `dbt_project.yml` carries a
|
|
276
|
+
ready-to-uncomment `marts` schema/materialization config for this).
|
|
277
|
+
- Locale-aware generation (`--locale`) for non-English/US synthetic data.
|
|
278
|
+
|
|
279
|
+
See [CONTRIBUTING.md](https://github.com/JB-Analytica/model2data/blob/main/CONTRIBUTING.md) if you'd like to work on any of these.
|
|
280
|
+
|
|
281
|
+
---
|
|
282
|
+
|
|
283
|
+
## Contributing
|
|
284
|
+
|
|
285
|
+
We welcome contributions!
|
|
286
|
+
|
|
287
|
+
- Open issues for bugs or feature requests.
|
|
288
|
+
- Submit PRs to add new DBML examples, custom data generators, or improvements.
|
|
289
|
+
- Ensure all new features include tests if possible.
|
|
290
|
+
|
|
291
|
+
See [CONTRIBUTING.md](https://github.com/JB-Analytica/model2data/blob/main/CONTRIBUTING.md) for detailed guidelines, and [DEVELOPMENT.md](https://github.com/JB-Analytica/model2data/blob/main/DEVELOPMENT.md) for the local dev setup and release process.
|
|
292
|
+
|
|
293
|
+
## Code of Conduct
|
|
294
|
+
|
|
295
|
+
Please read our [Code of Conduct](https://github.com/JB-Analytica/model2data/blob/main/CODE_OF_CONDUCT.md) to understand our community standards.
|
|
296
|
+
|
|
297
|
+
---
|
|
298
|
+
|
|
299
|
+
## License
|
|
300
|
+
|
|
301
|
+
MIT License. See LICENSE for details.
|
|
302
|
+
|
|
303
|
+
---
|
|
304
|
+
|
|
305
|
+
<p align="center">
|
|
306
|
+
<a href="https://www.jbanalytica.com">
|
|
307
|
+
<img src="https://raw.githubusercontent.com/JB-Analytica/model2data/main/assets/jba-icon-dark-bg.svg" alt="JB Analytica" height="40">
|
|
308
|
+
</a>
|
|
309
|
+
<br>
|
|
310
|
+
Built and maintained by <a href="https://www.jbanalytica.com"><strong>JB Analytica</strong></a> —
|
|
311
|
+
Data & Analytics Engineering · Data Platform Architecture · Modern BI.
|
|
312
|
+
</p>
|
|
@@ -1,28 +1,3 @@
|
|
|
1
|
-
Metadata-Version: 2.4
|
|
2
|
-
Name: model2data
|
|
3
|
-
Version: 0.5.0
|
|
4
|
-
Summary: Generate analytics-ready datasets from DBML models
|
|
5
|
-
Requires-Python: >=3.10
|
|
6
|
-
Description-Content-Type: text/markdown
|
|
7
|
-
License-File: LICENSE
|
|
8
|
-
Requires-Dist: dbt-core>=1.8.5
|
|
9
|
-
Requires-Dist: dbt-duckdb>=1.8.4
|
|
10
|
-
Requires-Dist: faker>=37.12.0
|
|
11
|
-
Requires-Dist: pandas>=2.3.3
|
|
12
|
-
Requires-Dist: pyyaml>=6.0.3
|
|
13
|
-
Requires-Dist: typer>=0.20.0
|
|
14
|
-
Provides-Extra: postgres
|
|
15
|
-
Requires-Dist: dbt-postgres>=1.8.0; extra == "postgres"
|
|
16
|
-
Provides-Extra: dev
|
|
17
|
-
Requires-Dist: pytest; extra == "dev"
|
|
18
|
-
Requires-Dist: pytest-cov; extra == "dev"
|
|
19
|
-
Requires-Dist: pre-commit; extra == "dev"
|
|
20
|
-
Requires-Dist: ruff>=0.1.0; extra == "dev"
|
|
21
|
-
Requires-Dist: ty>=0.0.4; extra == "dev"
|
|
22
|
-
Requires-Dist: types-pyyaml; extra == "dev"
|
|
23
|
-
Requires-Dist: poethepoet>=0.38.0; extra == "dev"
|
|
24
|
-
Dynamic: license-file
|
|
25
|
-
|
|
26
1
|
# model2data
|
|
27
2
|
|
|
28
3
|
[](https://pypi.org/project/model2data/)
|
|
@@ -34,20 +9,20 @@ Dynamic: license-file
|
|
|
34
9
|
|
|
35
10
|
Give `model2data` a [DBML](https://dbml.dbdiagram.io/docs/) schema — hand-written or exported
|
|
36
11
|
from an existing database — and it generates realistic, relationship-preserving synthetic data
|
|
37
|
-
*and* a complete, runnable dbt project around it: seeds, staging models,
|
|
12
|
+
*and* a complete, runnable dbt project around it: seeds, staging models, tests, and a
|
|
38
13
|
DuckDB or Postgres profile. No sample data to hunt down, no dbt boilerplate to hand-write, no
|
|
39
14
|
production data to risk exposing.
|
|
40
15
|
|
|
41
16
|
```bash
|
|
42
17
|
pip install model2data
|
|
43
|
-
model2data --file examples/
|
|
44
|
-
cd
|
|
18
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42
|
|
19
|
+
cd dbt_ecommerce && dbt build
|
|
45
20
|
```
|
|
46
21
|
|
|
47
22
|
That's a working analytics stack — real (synthetic) data, tested dbt models, queryable in
|
|
48
23
|
DuckDB — from a schema file, in seconds:
|
|
49
24
|
|
|
50
|
-

|
|
25
|
+

|
|
51
26
|
|
|
52
27
|
---
|
|
53
28
|
|
|
@@ -67,8 +42,9 @@ access required.
|
|
|
67
42
|
dependency order.
|
|
68
43
|
- **Deterministic.** Pass `--seed` and the same schema always produces the same data — safe to
|
|
69
44
|
commit fixtures, safe to diff across CI runs.
|
|
70
|
-
- **A real dbt project, not just CSVs.** Seeds, staging models
|
|
71
|
-
ready-to-use profile — the thing you'd otherwise spend an afternoon scaffolding by hand.
|
|
45
|
+
- **A real dbt project, not just CSVs.** Seeds, staging models that `ref()` them, schema tests,
|
|
46
|
+
and a ready-to-use profile — the thing you'd otherwise spend an afternoon scaffolding by hand.
|
|
47
|
+
A single `dbt build` loads, transforms, and tests the whole thing.
|
|
72
48
|
|
|
73
49
|
## Who is model2data for?
|
|
74
50
|
|
|
@@ -106,7 +82,7 @@ flowchart LR
|
|
|
106
82
|
D --> E
|
|
107
83
|
D --> F
|
|
108
84
|
D --> G
|
|
109
|
-
E & F & G --> H["dbt
|
|
85
|
+
E & F & G --> H["dbt build"]
|
|
110
86
|
H --> I[("Analytics-ready\ndataset")]
|
|
111
87
|
|
|
112
88
|
classDef m2dStyle fill:#0A3866,stroke:#2196F0,color:#F6F8FB
|
|
@@ -121,10 +97,10 @@ flowchart LR
|
|
|
121
97
|
2. **Generate.** Produces synthetic values per column — typed generation for known SQL types
|
|
122
98
|
(int, date, timestamp, ...), name-aware inference for everything else (`email`, `phone`,
|
|
123
99
|
`city`, ...), foreign keys resolved against already-generated parent rows.
|
|
124
|
-
3. **Scaffold.** Writes a complete dbt project around that data: CSV seeds, staging models
|
|
125
|
-
`
|
|
126
|
-
`Enum`-typed columns, singular SQL tests for composite primary/unique keys, table and
|
|
127
|
-
`description:` fields pulled from DBML notes, and a profile for DuckDB (zero-config,
|
|
100
|
+
3. **Scaffold.** Writes a complete dbt project around that data: CSV seeds, staging models that
|
|
101
|
+
`ref()` those seeds, `not_null`/`unique`/`relationships` tests, `accepted_values` tests for
|
|
102
|
+
DBML `Enum`-typed columns, singular SQL tests for composite primary/unique keys, table and
|
|
103
|
+
column `description:` fields pulled from DBML notes, and a profile for DuckDB (zero-config,
|
|
128
104
|
file-based) or Postgres.
|
|
129
105
|
|
|
130
106
|
---
|
|
@@ -139,32 +115,37 @@ pip install model2data
|
|
|
139
115
|
|
|
140
116
|
## Quick start
|
|
141
117
|
|
|
142
|
-
We
|
|
118
|
+
We bundle several example schemas in `examples/` — this walkthrough uses the e-commerce one
|
|
119
|
+
(`examples/ecommerce.dbml`: customers, products, orders, order items, and reviews).
|
|
143
120
|
|
|
144
121
|
Generate a project with synthetic data:
|
|
145
122
|
|
|
146
123
|
```bash
|
|
147
|
-
model2data --file examples/
|
|
124
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42
|
|
148
125
|
```
|
|
149
126
|
|
|
150
|
-
This creates a `
|
|
127
|
+
This creates a `dbt_ecommerce/` folder with your data and dbt setup.
|
|
151
128
|
|
|
152
|
-
Run dbt to load and
|
|
129
|
+
Run dbt to load, transform, and test the data:
|
|
153
130
|
|
|
154
131
|
```bash
|
|
155
|
-
cd
|
|
156
|
-
dbt
|
|
157
|
-
dbt seed
|
|
158
|
-
dbt run
|
|
132
|
+
cd dbt_ecommerce
|
|
133
|
+
dbt build
|
|
159
134
|
```
|
|
160
135
|
|
|
136
|
+
Staging models `ref()` their seeds, so a single `dbt build` loads the seeds, builds the models,
|
|
137
|
+
and runs every generated test in one dependency-ordered pass — no separate `dbt seed`/`dbt run`
|
|
138
|
+
needed, even on a brand-new database. (The individual `dbt deps`, `dbt seed`, and `dbt run`
|
|
139
|
+
commands still work if you'd rather drive the steps yourself; the generated project declares no
|
|
140
|
+
packages, so `dbt deps` is a no-op.)
|
|
141
|
+
|
|
161
142
|
Your analytics-ready dataset is now in DuckDB!
|
|
162
143
|
|
|
163
144
|
To target Postgres instead, install the extra and pass `--adapter postgres`:
|
|
164
145
|
|
|
165
146
|
```bash
|
|
166
147
|
pip install "model2data[postgres]"
|
|
167
|
-
model2data --file examples/
|
|
148
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42 --adapter postgres
|
|
168
149
|
```
|
|
169
150
|
|
|
170
151
|
Connection details are read from environment variables (`MODEL2DATA_PG_HOST`, `MODEL2DATA_PG_PORT`, `MODEL2DATA_PG_USER`, `MODEL2DATA_PG_PASSWORD`, `MODEL2DATA_PG_DATABASE`), defaulting to `localhost:5432` with a `postgres`/`postgres` user for local development.
|
|
@@ -174,16 +155,11 @@ After generation, the CLI prints a short summary — tables and rows generated,
|
|
|
174
155
|
Pass `--unit-tests` to also generate deterministic dbt unit test fixtures (`models/staging/ut_stg_<table>.yml`) from the actually-generated seed rows:
|
|
175
156
|
|
|
176
157
|
```bash
|
|
177
|
-
model2data --file examples/
|
|
158
|
+
model2data --file examples/ecommerce.dbml --rows 200 --seed 42 --unit-tests
|
|
178
159
|
```
|
|
179
160
|
|
|
180
|
-
This targets dbt-core's native unit testing feature, which
|
|
181
|
-
|
|
182
|
-
Note: on dbt-core versions in the 1.8.x line specifically, a DBML column named after a SQL
|
|
183
|
-
reserved word (e.g. `by`, as in `examples/hackernews.dbml`) can fail unit test execution with a
|
|
184
|
-
`syntax error` — a dbt-core-internal identifier-quoting limitation in its unit test fixture
|
|
185
|
-
rendering for that release line, not something under model2data's control. It's fixed in later
|
|
186
|
-
dbt-core versions; every other `--unit-tests` path works fine on 1.8.x.
|
|
161
|
+
This targets dbt-core's native unit testing feature, which works out of the box with the base
|
|
162
|
+
install — see [dbt-core versions](#dbt-core-versions) below.
|
|
187
163
|
|
|
188
164
|
---
|
|
189
165
|
|
|
@@ -195,11 +171,11 @@ The generated dbt project includes:
|
|
|
195
171
|
dbt_{project_name}/
|
|
196
172
|
├── seeds/
|
|
197
173
|
│ └── raw/
|
|
174
|
+
│ ├── __seed_config.yml # seed descriptions + column-type overrides
|
|
198
175
|
│ ├── table1.csv
|
|
199
176
|
│ └── table2.csv
|
|
200
177
|
├── models/
|
|
201
178
|
│ └── staging/
|
|
202
|
-
│ ├── __sources.yml
|
|
203
179
|
│ ├── stg_table1.sql
|
|
204
180
|
│ ├── stg_table1.yml
|
|
205
181
|
│ ├── ut_stg_table1.yml # only with --unit-tests
|
|
@@ -213,17 +189,44 @@ dbt_{project_name}/
|
|
|
213
189
|
└── {project_name}_profile.duckdb # DuckDB adapter only
|
|
214
190
|
```
|
|
215
191
|
|
|
216
|
-
- **Seeds**: CSV files with generated synthetic data.
|
|
217
|
-
|
|
218
|
-
-
|
|
219
|
-
|
|
220
|
-
`
|
|
192
|
+
- **Seeds**: CSV files with generated synthetic data, plus `__seed_config.yml` — each seed's
|
|
193
|
+
`description:` (from the table's DBML `Note`) and the column-type overrides that keep
|
|
194
|
+
all-digit text columns (barcodes, zero-padded postcodes, ...) from being loaded as integers.
|
|
195
|
+
- **Staging Models**: Basic dbt models that `ref()` their seed. Using `ref()` rather than
|
|
196
|
+
declaring the seeds as dbt `sources` is what gives each model a real DAG edge to the seed
|
|
197
|
+
behind it, so one `dbt build` orders seeds before models on a fresh database.
|
|
198
|
+
- **Tests**: A YAML per staging model with column tests (`not_null`, `unique`, `relationships`,
|
|
199
|
+
and `accepted_values` for DBML `Enum`-typed columns). Column `Note` text from the DBML becomes
|
|
200
|
+
`description:` fields.
|
|
221
201
|
- **Composite key tests**: Composite primary/unique keys declared in an `indexes { }` block get
|
|
222
202
|
a singular SQL test under `data-tests/`, dbt's configured `test-paths`.
|
|
223
203
|
- **Profiles**: Pre-configured for DuckDB (file-based) or Postgres (via env vars), with schema handling.
|
|
224
204
|
- **Unit tests** (opt-in via `--unit-tests`): `models/staging/ut_stg_<table>.yml` fixtures built
|
|
225
205
|
from real generated rows, co-located with each staging model so dbt (which only parses unit
|
|
226
|
-
tests from `model-paths`) picks them up.
|
|
206
|
+
tests from `model-paths`) picks them up.
|
|
207
|
+
|
|
208
|
+
---
|
|
209
|
+
|
|
210
|
+
## Using model2data with an LLM
|
|
211
|
+
|
|
212
|
+
If you want to go from a plain-English description of a data model straight to a running,
|
|
213
|
+
demo-ready dbt project, [LLMS.md](LLMS.md) is written for an LLM/agent to read: it covers the
|
|
214
|
+
full DBML feature set model2data understands (enums, notes, defaults, composite keys, both
|
|
215
|
+
relationship syntaxes, self-references) and the exact command sequence to run. Point an
|
|
216
|
+
LLM-backed coding assistant at it and describe your data model — it can author the DBML and run
|
|
217
|
+
model2data for you.
|
|
218
|
+
|
|
219
|
+
---
|
|
220
|
+
|
|
221
|
+
## dbt-core versions
|
|
222
|
+
|
|
223
|
+
model2data requires **dbt-core >= 1.11**, tracking [dbt's own version support
|
|
224
|
+
policy](https://docs.getdbt.com/docs/dbt-versions): dbt Labs supports each minor release for one
|
|
225
|
+
year, and 1.11 is the oldest that still is. Generated projects build cleanly — no deprecation
|
|
226
|
+
warnings — on every supported dbt-core version, and CI proves it on each push by running a real
|
|
227
|
+
`dbt build` against both the stated floor and the newest release.
|
|
228
|
+
|
|
229
|
+
If you're pinned to an older dbt-core, use model2data 0.5.x, which supported down to 1.8.5.
|
|
227
230
|
|
|
228
231
|
---
|
|
229
232
|
|
|
@@ -238,24 +241,32 @@ dbt_{project_name}/
|
|
|
238
241
|
|
|
239
242
|
## Limitations
|
|
240
243
|
|
|
241
|
-
-
|
|
242
|
-
- Synthetic data generation is heuristic-based and may not perfectly mimic real-world distributions or edge cases.
|
|
244
|
+
- Synthetic data generation is heuristic-based (typed generation, name-aware inference, enum/default awareness) and may not perfectly mimic real-world distributions or edge cases.
|
|
243
245
|
- DuckDB and Postgres are supported today; other databases require manual profile adjustments.
|
|
244
246
|
- No support for incremental models or advanced dbt features in generated projects.
|
|
247
|
+
- Composite foreign keys (across a bridge/join table) are generated as independent single-column FKs — each column's values are individually valid, but the *combination* isn't guaranteed to match a real parent composite key unless that key is separately enforced via `indexes { }`.
|
|
248
|
+
- Any DBML the parser can't fully make sense of (a malformed line, a ref pointing at an unknown table, an unrecognized column definition) is reported as a warning in the CLI's summary rather than silently dropped — check that summary after generating from a schema you didn't author yourself.
|
|
245
249
|
|
|
246
250
|
---
|
|
247
251
|
|
|
248
|
-
##
|
|
252
|
+
## Project status
|
|
253
|
+
|
|
254
|
+
As of `1.0.0`, model2data is considered **feature-complete for its intended use case**: turning a
|
|
255
|
+
DBML schema into realistic synthetic data and a runnable dbt project, reliably. There's no active
|
|
256
|
+
roadmap of new capabilities planned — the focus from here is maintenance: bug fixes, keeping pace
|
|
257
|
+
with new dbt-core releases, and reviewing community contributions.
|
|
258
|
+
|
|
259
|
+
Ideas that came up during development but were deliberately left out of scope, in case anyone
|
|
260
|
+
wants to pick them up as a contribution:
|
|
261
|
+
|
|
262
|
+
- Additional database adapters (e.g. Snowflake, BigQuery).
|
|
263
|
+
- A rule-based semantic layer scaffold (`semantic_models.yml`/basic metrics) derived from the
|
|
264
|
+
parsed schema shape.
|
|
265
|
+
- Example mart-layer models on top of staging (the generated `dbt_project.yml` carries a
|
|
266
|
+
ready-to-uncomment `marts` schema/materialization config for this).
|
|
267
|
+
- Locale-aware generation (`--locale`) for non-English/US synthetic data.
|
|
249
268
|
|
|
250
|
-
|
|
251
|
-
- [x] Name-aware synthetic data (email, name, address, phone, etc. instead of generic text)
|
|
252
|
-
- [x] Post-run generation summary (tables, rows, relationships, unmapped columns)
|
|
253
|
-
- [x] DBML `Enum` support, real table/column notes as dbt descriptions, composite keys from
|
|
254
|
-
`indexes { }`, `default:` values, and opt-in deterministic dbt unit test scaffolding
|
|
255
|
-
(`--unit-tests`)
|
|
256
|
-
- [ ] Additional database adapters (e.g., Snowflake, BigQuery).
|
|
257
|
-
- [ ] Enhanced data type handling and custom generators.
|
|
258
|
-
- [ ] Improved schema exploration and developer tooling.
|
|
269
|
+
See [CONTRIBUTING.md](CONTRIBUTING.md) if you'd like to work on any of these.
|
|
259
270
|
|
|
260
271
|
---
|
|
261
272
|
|
|
@@ -283,7 +294,7 @@ MIT License. See LICENSE for details.
|
|
|
283
294
|
|
|
284
295
|
<p align="center">
|
|
285
296
|
<a href="https://www.jbanalytica.com">
|
|
286
|
-
<img src="assets/jba-icon-dark-bg.svg" alt="JB Analytica" height="40">
|
|
297
|
+
<img src="https://raw.githubusercontent.com/JB-Analytica/model2data/main/assets/jba-icon-dark-bg.svg" alt="JB Analytica" height="40">
|
|
287
298
|
</a>
|
|
288
299
|
<br>
|
|
289
300
|
Built and maintained by <a href="https://www.jbanalytica.com"><strong>JB Analytica</strong></a> —
|