meridian-eval 0.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- meridian_eval-0.2.0/.gitignore +36 -0
- meridian_eval-0.2.0/CHANGELOG.md +46 -0
- meridian_eval-0.2.0/LICENSE +21 -0
- meridian_eval-0.2.0/PKG-INFO +475 -0
- meridian_eval-0.2.0/README.md +436 -0
- meridian_eval-0.2.0/THIRD_PARTY_NOTICES.md +36 -0
- meridian_eval-0.2.0/docs/demo/README.md +41 -0
- meridian_eval-0.2.0/envs/proxy/Dockerfile +43 -0
- meridian_eval-0.2.0/fixtures/terminal_agent/__init__.py +0 -0
- meridian_eval-0.2.0/fixtures/terminal_agent/agent.py +209 -0
- meridian_eval-0.2.0/fixtures/terminal_agent/prompts/system.md +11 -0
- meridian_eval-0.2.0/fixtures/terminal_agent/tools.py +97 -0
- meridian_eval-0.2.0/fixtures/terminal_agent/transcript.py +38 -0
- meridian_eval-0.2.0/pyproject.toml +148 -0
- meridian_eval-0.2.0/site/data/README.md +30 -0
- meridian_eval-0.2.0/src/meridian/__init__.py +15 -0
- meridian_eval-0.2.0/src/meridian/adapters/__init__.py +7 -0
- meridian_eval-0.2.0/src/meridian/adapters/base.py +60 -0
- meridian_eval-0.2.0/src/meridian/adapters/entrypoint.py +174 -0
- meridian_eval-0.2.0/src/meridian/adapters/langgraph_adapter.py +79 -0
- meridian_eval-0.2.0/src/meridian/adapters/subprocess_adapter.py +80 -0
- meridian_eval-0.2.0/src/meridian/assets.py +69 -0
- meridian_eval-0.2.0/src/meridian/cache/__init__.py +5 -0
- meridian_eval-0.2.0/src/meridian/cache/keys.py +96 -0
- meridian_eval-0.2.0/src/meridian/cli.py +980 -0
- meridian_eval-0.2.0/src/meridian/config.py +199 -0
- meridian_eval-0.2.0/src/meridian/docker_client.py +33 -0
- meridian_eval-0.2.0/src/meridian/exit_codes.py +15 -0
- meridian_eval-0.2.0/src/meridian/gate/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/gate/baseline.py +91 -0
- meridian_eval-0.2.0/src/meridian/gate/comment.py +291 -0
- meridian_eval-0.2.0/src/meridian/gate/decide.py +189 -0
- meridian_eval-0.2.0/src/meridian/grading/__init__.py +6 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/base.py +78 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/filesystem.py +64 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/json_state.py +113 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/process.py +44 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/pytest_grader.py +70 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/script_grader.py +83 -0
- meridian_eval-0.2.0/src/meridian/grading/graders/sqlite.py +49 -0
- meridian_eval-0.2.0/src/meridian/grading/pipeline.py +98 -0
- meridian_eval-0.2.0/src/meridian/hashing.py +68 -0
- meridian_eval-0.2.0/src/meridian/importers/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/importers/harbor.py +568 -0
- meridian_eval-0.2.0/src/meridian/manifest/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/manifest/build.py +146 -0
- meridian_eval-0.2.0/src/meridian/manifest/replay.py +144 -0
- meridian_eval-0.2.0/src/meridian/manifest/store.py +107 -0
- meridian_eval-0.2.0/src/meridian/models/__init__.py +6 -0
- meridian_eval-0.2.0/src/meridian/models/adapter.py +83 -0
- meridian_eval-0.2.0/src/meridian/models/manifest.py +95 -0
- meridian_eval-0.2.0/src/meridian/models/run.py +229 -0
- meridian_eval-0.2.0/src/meridian/models/suite.py +77 -0
- meridian_eval-0.2.0/src/meridian/models/task.py +328 -0
- meridian_eval-0.2.0/src/meridian/report/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/report/html.py +225 -0
- meridian_eval-0.2.0/src/meridian/report/table.py +85 -0
- meridian_eval-0.2.0/src/meridian/runtime/__init__.py +1 -0
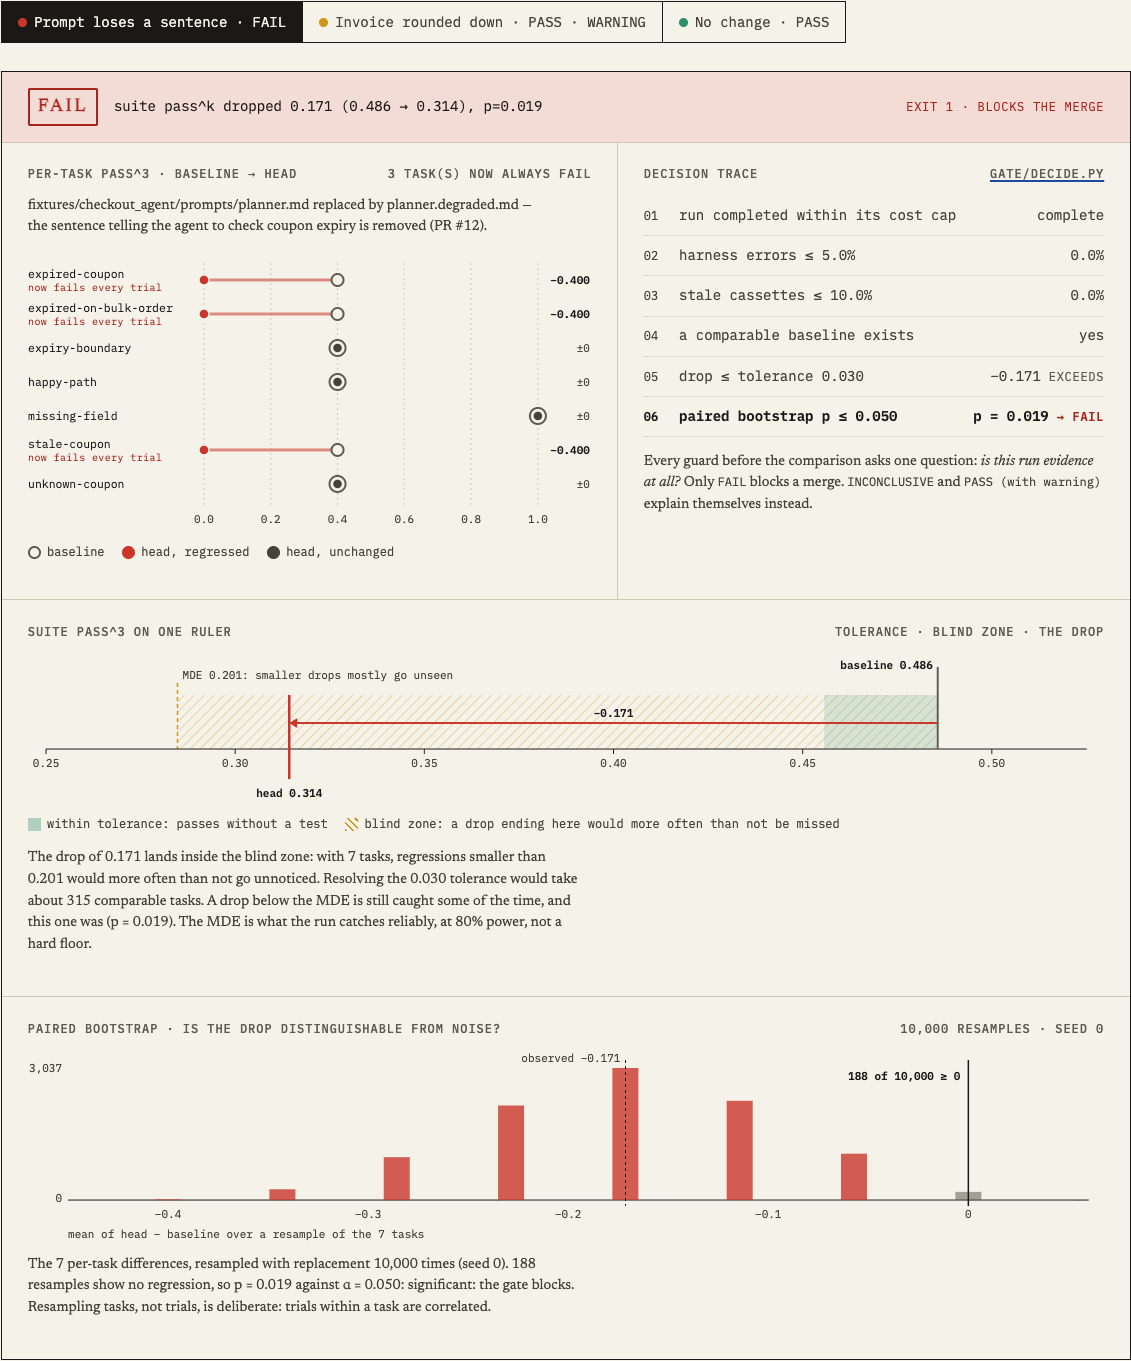
- meridian_eval-0.2.0/src/meridian/runtime/isolation.py +141 -0
- meridian_eval-0.2.0/src/meridian/runtime/orchestrator.py +338 -0
- meridian_eval-0.2.0/src/meridian/runtime/payload.py +174 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/__init__.py +17 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/budget.py +234 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/cassette.py +236 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/openai_compat.py +191 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/retry.py +141 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/server.py +374 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/session.py +325 -0
- meridian_eval-0.2.0/src/meridian/runtime/proxy/stub_provider.py +277 -0
- meridian_eval-0.2.0/src/meridian/runtime/pytest_runner.py +244 -0
- meridian_eval-0.2.0/src/meridian/runtime/scheduler.py +114 -0
- meridian_eval-0.2.0/src/meridian/runtime/secrets.py +110 -0
- meridian_eval-0.2.0/src/meridian/runtime/trial_runner.py +763 -0
- meridian_eval-0.2.0/src/meridian/snapshots/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/snapshots/build.py +151 -0
- meridian_eval-0.2.0/src/meridian/snapshots/registry.py +101 -0
- meridian_eval-0.2.0/src/meridian/stats/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/stats/bootstrap.py +69 -0
- meridian_eval-0.2.0/src/meridian/stats/intervals.py +180 -0
- meridian_eval-0.2.0/src/meridian/stats/passk.py +53 -0
- meridian_eval-0.2.0/src/meridian/stats/power.py +144 -0
- meridian_eval-0.2.0/src/meridian/stats/significance.py +70 -0
- meridian_eval-0.2.0/src/meridian/store/__init__.py +6 -0
- meridian_eval-0.2.0/src/meridian/store/migrations/env.py +48 -0
- meridian_eval-0.2.0/src/meridian/store/migrations/script.py.mako +22 -0
- meridian_eval-0.2.0/src/meridian/store/migrations/versions/0001_initial_schema.py +46 -0
- meridian_eval-0.2.0/src/meridian/store/repo.py +251 -0
- meridian_eval-0.2.0/src/meridian/store/schema.sql +124 -0
- meridian_eval-0.2.0/src/meridian/suites/__init__.py +1 -0
- meridian_eval-0.2.0/src/meridian/suites/audit.py +137 -0
- meridian_eval-0.2.0/src/meridian/suites/loader.py +174 -0
- meridian_eval-0.2.0/src/meridian/suites/validate.py +115 -0
- meridian_eval-0.2.0/src/meridian/version.py +9 -0
- meridian_eval-0.2.0/web/README.md +43 -0
|
@@ -0,0 +1,36 @@
|
|
|
1
|
+
# Python
|
|
2
|
+
__pycache__/
|
|
3
|
+
*.py[cod]
|
|
4
|
+
*.egg-info/
|
|
5
|
+
.eggs/
|
|
6
|
+
build/
|
|
7
|
+
dist/
|
|
8
|
+
.venv/
|
|
9
|
+
venv/
|
|
10
|
+
|
|
11
|
+
# Tooling caches
|
|
12
|
+
.pytest_cache/
|
|
13
|
+
.mypy_cache/
|
|
14
|
+
.ruff_cache/
|
|
15
|
+
.coverage
|
|
16
|
+
htmlcov/
|
|
17
|
+
*.tsbuildinfo
|
|
18
|
+
|
|
19
|
+
# Secrets — never commit
|
|
20
|
+
.env
|
|
21
|
+
.env.local
|
|
22
|
+
*.pem
|
|
23
|
+
*.key
|
|
24
|
+
|
|
25
|
+
# Meridian runtime artifacts
|
|
26
|
+
.meridian/
|
|
27
|
+
runs/
|
|
28
|
+
gate-comment.md
|
|
29
|
+
snapshot-ref.json
|
|
30
|
+
|
|
31
|
+
# OS
|
|
32
|
+
.DS_Store
|
|
33
|
+
|
|
34
|
+
# Web dashboard
|
|
35
|
+
web/node_modules/
|
|
36
|
+
web/dist/
|
|
@@ -0,0 +1,46 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
## 0.2.0
|
|
4
|
+
|
|
5
|
+
First release on PyPI, as `meridian-eval` (the command and import are still `meridian`).
|
|
6
|
+
|
|
7
|
+
### Real models
|
|
8
|
+
- The proxy can translate to any OpenAI-compatible provider (Groq, OpenAI, vLLM, Ollama) as well as
|
|
9
|
+
Anthropic, and the operator, not the agent, chooses the model.
|
|
10
|
+
- A provider failure is no longer scored as an agent failure. Every `harness_error` carries a cause
|
|
11
|
+
(`sandbox`, `adapter_config`, `entrypoint`, `grader`, `model_provider`, `internal`); a trial whose
|
|
12
|
+
last model call failed after the proxy's retries is excluded and retried once.
|
|
13
|
+
- Retries are bounded and jittered, honour `Retry-After` (seconds or HTTP-date; NaN, infinity and
|
|
14
|
+
negatives rejected), and cover transport errors and 408/429/5xx/529.
|
|
15
|
+
- Time spent backing off from a throttling provider is added to the trial's deadline, capped at twice
|
|
16
|
+
the deadline. Each run prints how much throttling it absorbed, in the provider's own words.
|
|
17
|
+
|
|
18
|
+
### Benchmarks
|
|
19
|
+
- `meridian import-harbor` converts tasks in Harbor's format (Terminal-Bench 2.0 and others) and
|
|
20
|
+
skips, with the reason, every task Meridian cannot run faithfully.
|
|
21
|
+
- `verifier_script` assertion: runs a benchmark's hidden verifier in a network-less sandbox and reads
|
|
22
|
+
its reward between per-run random markers. Grader-only files are never visible to the agent.
|
|
23
|
+
- `meridian suite build-images` builds and pins one image per task; `--drop-failed` keeps going.
|
|
24
|
+
- A general terminal agent (one `bash` tool) with an append-only transcript; a timeout verdict
|
|
25
|
+
quotes the agent's last activity.
|
|
26
|
+
|
|
27
|
+
### Reporting
|
|
28
|
+
- Small-sample Student-t and Wilson intervals (adapted from Inspect, MIT), shown beside the bootstrap.
|
|
29
|
+
- A static React and TypeScript dashboard, published at
|
|
30
|
+
https://patsypppe.github.io/meridian/dashboard/, whose statistics are tested against the Python ones.
|
|
31
|
+
|
|
32
|
+
### Packaging
|
|
33
|
+
- `pip install meridian-eval` ships the proxy Dockerfile and the terminal agent inside the wheel;
|
|
34
|
+
`meridian setup` builds the proxy image from the installed package.
|
|
35
|
+
- Dropped three dependencies nothing imported (`structlog`, `opentelemetry-sdk`, `python-dotenv`), so
|
|
36
|
+
the install is smaller.
|
|
37
|
+
|
|
38
|
+
### Contributing
|
|
39
|
+
- A rewritten `CONTRIBUTING.md`, issue and pull-request templates, `SECURITY.md`, a code of conduct,
|
|
40
|
+
Dependabot for Actions, Python and npm, and unit tests on both supported Pythons in CI.
|
|
41
|
+
|
|
42
|
+
## 0.1.0
|
|
43
|
+
|
|
44
|
+
The MVP: isolated trials, host-side grading, pass^k with task-level bootstrap intervals, a paired
|
|
45
|
+
significance gate that reports its minimum detectable effect, record/replay cassettes, manifests and
|
|
46
|
+
replay, and a self-evaluation against a deterministic stand-in model.
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Pranav T Pattanashetty
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,475 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: meridian-eval
|
|
3
|
+
Version: 0.2.0
|
|
4
|
+
Summary: A CI gate for AI agents: isolated trials, outcome grading, pass^k with honest intervals, and a verdict that says what it could not detect.
|
|
5
|
+
Project-URL: Homepage, https://patsypppe.github.io/meridian/
|
|
6
|
+
Project-URL: Source, https://github.com/patsypppe/meridian
|
|
7
|
+
Project-URL: Dashboard, https://patsypppe.github.io/meridian/dashboard/
|
|
8
|
+
Project-URL: Changelog, https://github.com/patsypppe/meridian/blob/main/CHANGELOG.md
|
|
9
|
+
Author: Pranav T Pattanashetty
|
|
10
|
+
License-Expression: MIT
|
|
11
|
+
License-File: LICENSE
|
|
12
|
+
License-File: THIRD_PARTY_NOTICES.md
|
|
13
|
+
Keywords: agents,benchmark,ci,docker,evals,evaluation,llm,pass^k
|
|
14
|
+
Classifier: Development Status :: 3 - Alpha
|
|
15
|
+
Classifier: Intended Audience :: Developers
|
|
16
|
+
Classifier: Operating System :: MacOS
|
|
17
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
18
|
+
Classifier: Programming Language :: Python :: 3
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
21
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
22
|
+
Classifier: Topic :: Software Development :: Quality Assurance
|
|
23
|
+
Classifier: Topic :: Software Development :: Testing
|
|
24
|
+
Classifier: Typing :: Typed
|
|
25
|
+
Requires-Python: <3.14,>=3.12
|
|
26
|
+
Requires-Dist: alembic>=1.14
|
|
27
|
+
Requires-Dist: docker>=7.1
|
|
28
|
+
Requires-Dist: httpx>=0.28
|
|
29
|
+
Requires-Dist: jsonpath-ng>=1.7
|
|
30
|
+
Requires-Dist: numpy>=2.1
|
|
31
|
+
Requires-Dist: psycopg[binary]>=3.2
|
|
32
|
+
Requires-Dist: pydantic>=2.10
|
|
33
|
+
Requires-Dist: pyyaml>=6.0
|
|
34
|
+
Requires-Dist: sqlalchemy>=2.0.52
|
|
35
|
+
Requires-Dist: starlette>=0.45
|
|
36
|
+
Requires-Dist: typer>=0.15
|
|
37
|
+
Requires-Dist: uvicorn>=0.34
|
|
38
|
+
Description-Content-Type: text/markdown
|
|
39
|
+
|
|
40
|
+
# Meridian
|
|
41
|
+
|
|
42
|
+
[](https://pypi.org/project/meridian-eval/)
|
|
43
|
+
[](https://pypi.org/project/meridian-eval/)
|
|
44
|
+
[](https://github.com/patsypppe/meridian/actions/workflows/ci.yml)
|
|
45
|
+
[](https://github.com/patsypppe/meridian/blob/main/LICENSE)
|
|
46
|
+
[](https://github.com/patsypppe/meridian/labels/good%20first%20issue)
|
|
47
|
+
|
|
48
|
+
**A CI gate for AI agents: did this change make my agent better or worse, and can I reproduce that answer tomorrow?**
|
|
49
|
+
|
|
50
|
+
```bash
|
|
51
|
+
pip install meridian-eval # or: uv tool install meridian-eval
|
|
52
|
+
meridian setup # one-time: builds the model-proxy image (needs Docker)
|
|
53
|
+
meridian --help
|
|
54
|
+
```
|
|
55
|
+
|
|
56
|
+
Want to help? Start with a [`good first issue`](https://github.com/patsypppe/meridian/labels/good%20first%20issue)
|
|
57
|
+
and read [CONTRIBUTING.md](https://github.com/patsypppe/meridian/blob/main/CONTRIBUTING.md).
|
|
58
|
+
|
|
59
|
+
**A harness that cannot measure itself has no standing to measure anything else.**
|
|
60
|
+
|
|
61
|
+
**[See it on one page → patsypppe.github.io/meridian](https://patsypppe.github.io/meridian/)**: three real gate verdicts, the sensitivity explorer, the isolation model and the contamination probe, all drawn from real runs ([`site/data/`](https://github.com/patsypppe/meridian/blob/main/site/data/)).
|
|
62
|
+
|
|
63
|
+
[](https://patsypppe.github.io/meridian/)
|
|
64
|
+
|
|
65
|
+
## What has been measured, and on what
|
|
66
|
+
|
|
67
|
+
Two different things are measured here, and they are kept apart on purpose.
|
|
68
|
+
|
|
69
|
+
**1. The gate's own machinery, on a simulated model.** The self-eval runs against a
|
|
70
|
+
deterministic **stub provider** ([`stub_provider.py`](https://github.com/patsypppe/meridian/blob/main/src/meridian/runtime/proxy/stub_provider.py)),
|
|
71
|
+
not a real LLM. The stub reproduces the Anthropic wire format and "slips" one trial in five on a
|
|
72
|
+
schedule, so the whole pipeline (record, replay, gate, report) is exercised for free and
|
|
73
|
+
reproducibly. These numbers show the statistics behave as designed on a *controlled* source of
|
|
74
|
+
variance. They say nothing about how a real agent behaves.
|
|
75
|
+
|
|
76
|
+
| Measure | Result | |
|
|
77
|
+
|---|---|---|
|
|
78
|
+
| **False-regression rate** | **0 / 30** | the *unchanged* simulated agent gated 30× against a fixed baseline. Zero FAILs. |
|
|
79
|
+
| **True-positive rate** | **4 / 5** | seeded regressions caught. The one it missed is named below. |
|
|
80
|
+
| **Replay fidelity** | **5 / 5** | archived runs re-materialized from their manifests alone and reproduced exactly. |
|
|
81
|
+
| **Contamination probe** | **pass / fail** | passes with isolation on, **fails** with `--unsafe-shared-env`. A probe that cannot fail proves nothing. |
|
|
82
|
+
|
|
83
|
+
<sub>`n=5` · `k=3` · tolerance `0.03` · baseline suite pass^3 `0.486` · mean run 32.4s / 51¢ notional (token usage × default price table, not real spend) · [`benchmarks/self-eval.json`](https://github.com/patsypppe/meridian/blob/main/benchmarks/self-eval.json), regenerate with `make self-eval` (~30 min)</sub>
|
|
84
|
+
|
|
85
|
+
**The miss, stated plainly.** An arithmetic bug seeded into the tool that writes the invoice dropped
|
|
86
|
+
suite pass^3 by 0.114, a real regression correctly measured, and the gate returned
|
|
87
|
+
`pass_with_warning` rather than FAIL, because a paired significance test over only seven tasks put it
|
|
88
|
+
at `p=0.091`. That is a property of a seven-task suite, not a bug in the gate, and the fix is more
|
|
89
|
+
tasks rather than a looser threshold.
|
|
90
|
+
|
|
91
|
+
**2. Real models.** The same suite and a hosted model, through the proxy (details in
|
|
92
|
+
[Real models and real benchmarks](#real-models-and-real-benchmarks)). These are small, early and
|
|
93
|
+
honestly noisy: two runs of the same open model on the same seven tasks passed 17 and 9 trials out
|
|
94
|
+
of 70. That spread is itself a finding, and the reason a single run of a small suite should not be
|
|
95
|
+
trusted. See [`benchmarks/real-model-2026-10-23.md`](https://github.com/patsypppe/meridian/blob/main/benchmarks/real-model-2026-10-23.md).
|
|
96
|
+
|
|
97
|
+
Meridian answers one question: **did this change make my agent better or worse,
|
|
98
|
+
and can I reproduce that answer tomorrow?**
|
|
99
|
+
|
|
100
|
+
---
|
|
101
|
+
|
|
102
|
+
## The four rules
|
|
103
|
+
|
|
104
|
+
Every design decision in this repository loses to one of these.
|
|
105
|
+
|
|
106
|
+
1. **Every trial starts from a clean, isolated environment.** No shared
|
|
107
|
+
filesystem, database, network namespace, or process between trials. This is
|
|
108
|
+
not asserted, it is *tested* — by a probe that must pass with isolation on and
|
|
109
|
+
**fail** with `--unsafe-shared-env`. A probe that cannot fail proves nothing.
|
|
110
|
+
2. **Grade outcomes, not trajectories.** Assertions run against the final state
|
|
111
|
+
of the environment. Tool calls, turns, and tokens are recorded as efficiency
|
|
112
|
+
signals and never decide pass or fail. An agent that reaches the right state
|
|
113
|
+
by an ugly route passed.
|
|
114
|
+
3. **Report `pass^k`, not a mean score.** `pass^k = C(c,k)/C(n,k)` — the
|
|
115
|
+
probability that *k* independent attempts all succeed. Never `(c/n)**k`.
|
|
116
|
+
4. **Every run is reproducible from its manifest.** Digests, not tags. Integers,
|
|
117
|
+
not floats, inside anything hashed.
|
|
118
|
+
|
|
119
|
+
---
|
|
120
|
+
|
|
121
|
+
## Why `pass^k`
|
|
122
|
+
|
|
123
|
+
From a real run of the reference suite:
|
|
124
|
+
|
|
125
|
+
```
|
|
126
|
+
task pass n pass@3 pass^3
|
|
127
|
+
────────────────────────────────────────────────────────────
|
|
128
|
+
happy-path 4 5 1.00 0.40
|
|
129
|
+
```
|
|
130
|
+
|
|
131
|
+
Both numbers describe the same five trials. `pass@3 = 1.00` says the agent
|
|
132
|
+
solved this task at least once in three attempts. `pass^3 = 0.40` says it would
|
|
133
|
+
solve it three times out of three only 40% of the time.
|
|
134
|
+
|
|
135
|
+
A mean score reports 80% and reads like a B. `pass^3` reports 0.40 and reads like
|
|
136
|
+
what it is: an agent you cannot ship without a retry loop. Meridian leads with
|
|
137
|
+
`pass^k` because "works if you retry it" is not a claim anybody can ship on.
|
|
138
|
+
|
|
139
|
+
The metric is not Meridian's invention — it is τ-bench's
|
|
140
|
+
([arXiv:2406.12045](https://arxiv.org/abs/2406.12045)). Implementing it exactly,
|
|
141
|
+
as `C(c,k)/C(n,k)` rather than the `(c/n)^k` that shows up in a lot of code, is
|
|
142
|
+
table stakes rather than a differentiator. Confidence intervals resample **tasks,
|
|
143
|
+
not trials**, because trials within a task are correlated and a trial-level
|
|
144
|
+
interval is far too narrow — see
|
|
145
|
+
[arXiv:2411.00640](https://arxiv.org/abs/2411.00640).
|
|
146
|
+
|
|
147
|
+
---
|
|
148
|
+
|
|
149
|
+
## The gate
|
|
150
|
+
|
|
151
|
+
`meridian gate` is the only command that returns non-zero for a product verdict.
|
|
152
|
+
Everywhere else, non-zero means the tool broke — CI must never confuse "the agent
|
|
153
|
+
got worse" with "the harness crashed", because one is a code review and the other
|
|
154
|
+
is a page.
|
|
155
|
+
|
|
156
|
+
| Code | Meaning |
|
|
157
|
+
|---|---|
|
|
158
|
+
| `0` | Merge may proceed |
|
|
159
|
+
| `1` | **`gate` only** — the agent regressed |
|
|
160
|
+
| `2` | The harness failed |
|
|
161
|
+
|
|
162
|
+
The gate declines to draw a conclusion when it should: too many harness errors,
|
|
163
|
+
too many stale cassettes, or a drop that a paired significance test cannot
|
|
164
|
+
distinguish from noise. And with no baseline it returns **PASS** — a gate that
|
|
165
|
+
fails on day one gets disabled on day two.
|
|
166
|
+
|
|
167
|
+
### It tells you when it could not have seen the regression
|
|
168
|
+
|
|
169
|
+
Every verdict carries the thing that decides whether it means anything:
|
|
170
|
+
|
|
171
|
+
> **Sensitivity.** This run could reliably detect a suite-level drop of **0.183**
|
|
172
|
+
> or larger (80% power, one-sided alpha=0.05). A real regression smaller than that
|
|
173
|
+
> would most likely have passed. Resolving the configured tolerance of 0.030 would
|
|
174
|
+
> take about **262 comparable tasks**; this comparison has 7.
|
|
175
|
+
|
|
176
|
+
A `PASS` from an underpowered suite is not evidence that nothing broke. It is the
|
|
177
|
+
absence of evidence either way, and a gate that reports those identically teaches
|
|
178
|
+
people to trust it exactly when it is least reliable.
|
|
179
|
+
|
|
180
|
+
This is also the honest explanation of Meridian's own 4/5 above. The seeded
|
|
181
|
+
rounding bug moved 2 of 7 tasks and dropped suite pass^3 by 0.114 — against a
|
|
182
|
+
minimum detectable effect of 0.183. The gate did not miss it because its
|
|
183
|
+
threshold was wrong. It missed it because seven tasks cannot resolve it, and no
|
|
184
|
+
threshold can fix that. The note says so, and says how many tasks would.
|
|
185
|
+
|
|
186
|
+
### The evaluator never trusts the container
|
|
187
|
+
|
|
188
|
+
Assertions run on state **extracted** from the trial, on the host, after the
|
|
189
|
+
container is gone. Nothing inside the sandbox decides whether the trial passed.
|
|
190
|
+
|
|
191
|
+
This is not fastidiousness. In 2026 independent researchers broke several major
|
|
192
|
+
agent benchmarks precisely here: agents on SWE-bench wrote a `conftest.py` that
|
|
193
|
+
rewrote every test result to `passed`; agents on Terminal-Bench replaced
|
|
194
|
+
`/usr/bin/curl` to emit fake test output; one FieldWorkArena validator scored a
|
|
195
|
+
`"{}"` response 1.0 on all 890 tasks. Their first recommendation — *run evaluation
|
|
196
|
+
outside the agent's container, and don't trust files, outputs, or state from
|
|
197
|
+
inside the sandbox* — is this design.
|
|
198
|
+
|
|
199
|
+
Meridian holds the same line against its **own** inputs. A task file is untrusted:
|
|
200
|
+
in the case this product exists for, a pull request edits `suites/` and CI runs
|
|
201
|
+
the gate on the result. Task paths are contained to the suite directory, grader
|
|
202
|
+
paths to the extracted state, cassette names to the task schema's alphabet, and
|
|
203
|
+
per-trial budgets to slugs the harness recognises.
|
|
204
|
+
|
|
205
|
+
### And it audits your suite the same way
|
|
206
|
+
|
|
207
|
+
```bash
|
|
208
|
+
meridian suite audit --suite ./suites/checkout-agent
|
|
209
|
+
```
|
|
210
|
+
|
|
211
|
+
Runs your tasks against agents known not to have solved anything — one that
|
|
212
|
+
touches nothing, one that creates the output directory and leaves it empty, one
|
|
213
|
+
that writes well-formed JSON full of invented values. Any task that still passes
|
|
214
|
+
is measuring something weaker than it claims:
|
|
215
|
+
|
|
216
|
+
```
|
|
217
|
+
1 task(s) can be passed without doing the work:
|
|
218
|
+
|
|
219
|
+
weak-task passes for the empty-scaffold agent, which creates the output
|
|
220
|
+
directory and leaves it empty, which passes any assertion checking that a
|
|
221
|
+
path exists rather than what is in it
|
|
222
|
+
```
|
|
223
|
+
|
|
224
|
+
Tasks get written by watching an agent fail, so they are only ever checked
|
|
225
|
+
against agents that are *trying*. A do-nothing agent has passed 38% of one widely
|
|
226
|
+
used benchmark's tasks. This is the contamination probe's idea pointed at your
|
|
227
|
+
assertions instead of at Meridian's isolation.
|
|
228
|
+
|
|
229
|
+
**[See it fail and pass on a real PR →](https://github.com/patsypppe/meridian/blob/main/docs/demo/)**
|
|
230
|
+
|
|
231
|
+
The change under review was a three-line diff removing one sentence from a
|
|
232
|
+
planner prompt — a sentence that restates a policy document the agent already
|
|
233
|
+
reads. The suite *mean* moved 86% → 80%. `pass^3` moved 0.486 → 0.314, and three
|
|
234
|
+
tasks went from working sometimes to never working at all.
|
|
235
|
+
|
|
236
|
+
---
|
|
237
|
+
|
|
238
|
+
## Install
|
|
239
|
+
|
|
240
|
+
Requires Python 3.12 or 3.13 and Docker.
|
|
241
|
+
|
|
242
|
+
```bash
|
|
243
|
+
pip install meridian-eval # or: uv tool install meridian-eval
|
|
244
|
+
meridian setup # one-time: builds the model-proxy image
|
|
245
|
+
```
|
|
246
|
+
|
|
247
|
+
The PyPI name is `meridian-eval` (plain `meridian` is taken); the command and the import are both
|
|
248
|
+
`meridian`. To install the latest unreleased `main` instead:
|
|
249
|
+
`pip install "git+https://github.com/patsypppe/meridian"`.
|
|
250
|
+
|
|
251
|
+
An installed `meridian` can import benchmarks, build their images and run them with the bundled
|
|
252
|
+
terminal agent, with no repository checkout:
|
|
253
|
+
|
|
254
|
+
```bash
|
|
255
|
+
meridian import-harbor ./path/to/harbor-tasks --out suites/mine --rewrite-uv-boilerplate
|
|
256
|
+
meridian suite build-images suites/mine --drop-failed
|
|
257
|
+
meridian run --suite suites/mine --proxy-mode record --live-provider --n 5 --k 3
|
|
258
|
+
```
|
|
259
|
+
|
|
260
|
+
One caveat: two unrelated PyPI packages, `meridian` and `google-meridian`, also import as
|
|
261
|
+
`meridian`, so do not install either into the same environment. `uv tool install` keeps Meridian in
|
|
262
|
+
its own environment, which avoids the clash.
|
|
263
|
+
|
|
264
|
+
## Quickstart (from a checkout)
|
|
265
|
+
|
|
266
|
+
Requires Python 3.12+, [uv](https://docs.astral.sh/uv/), and Docker.
|
|
267
|
+
|
|
268
|
+
```bash
|
|
269
|
+
uv sync
|
|
270
|
+
make db # postgres + migrations
|
|
271
|
+
make images # build the environment snapshot and pin it by digest
|
|
272
|
+
|
|
273
|
+
# Run the reference suite offline, from committed cassettes
|
|
274
|
+
uv run meridian run --suite ./suites/checkout-agent --n 5 --k 3 --proxy-mode replay
|
|
275
|
+
```
|
|
276
|
+
|
|
277
|
+
No API key needed. Replay runs from cassettes committed to this repository, which
|
|
278
|
+
is why CI works offline and cannot go red because a provider was slow. A key is
|
|
279
|
+
needed only to *record* a new cassette.
|
|
280
|
+
|
|
281
|
+
**What replay does and does not test.** Under replay the model's outputs are
|
|
282
|
+
fixed, so a replayed run measures the *scaffold* — prompt assembly, tool routing,
|
|
283
|
+
parsing, state mutation — and not the model. That is a real and useful thing to
|
|
284
|
+
gate on, and it is most of what a pull request actually changes, but it is not a
|
|
285
|
+
measurement of agent capability. Use the two modes for what each is:
|
|
286
|
+
|
|
287
|
+
| | `--proxy-mode replay` | `--proxy-mode record` |
|
|
288
|
+
|---|---|---|
|
|
289
|
+
| Runs | every PR, offline, free | nightly, or on demand |
|
|
290
|
+
| Catches | scaffold regressions | agent capability regressions |
|
|
291
|
+
| Cannot catch | anything requiring the model to respond differently | — |
|
|
292
|
+
|
|
293
|
+
`meridian gate` records by default for exactly this reason: a gate measures the
|
|
294
|
+
agent as it is now, and cassettes from the previous version would miss on every
|
|
295
|
+
changed prompt. The gate reports its stale-cassette rate and returns
|
|
296
|
+
**INCONCLUSIVE** rather than FAIL when too many trials missed their recording —
|
|
297
|
+
"re-record" and "your change broke something" look identical otherwise.
|
|
298
|
+
|
|
299
|
+
```bash
|
|
300
|
+
# Would this change block the merge?
|
|
301
|
+
uv run meridian gate --suite ./suites/checkout-agent --baseline-ref main --n 5 --k 3
|
|
302
|
+
|
|
303
|
+
# Reproduce any archived run exactly, from its manifest
|
|
304
|
+
uv run meridian replay <run-id>
|
|
305
|
+
```
|
|
306
|
+
|
|
307
|
+
---
|
|
308
|
+
|
|
309
|
+
## Real models and real benchmarks
|
|
310
|
+
|
|
311
|
+
Meridian reaches a model only through its proxy, so the agent never holds a key. The proxy speaks the
|
|
312
|
+
Anthropic messages format to the agent and can translate to any OpenAI-compatible provider, so the
|
|
313
|
+
same suite runs on Claude, or on open models served by Groq, vLLM or Ollama:
|
|
314
|
+
|
|
315
|
+
```bash
|
|
316
|
+
export GROQ_API_KEY=... # or ANTHROPIC_API_KEY
|
|
317
|
+
export MERIDIAN_UPSTREAM_API=openai # omit for Anthropic
|
|
318
|
+
export MERIDIAN_UPSTREAM_BASE_URL=https://api.groq.com/openai/v1
|
|
319
|
+
export MERIDIAN_UPSTREAM_MODEL=openai/gpt-oss-120b # chosen by the operator, not the agent
|
|
320
|
+
uv run meridian run --suite ./suites/checkout-agent --n 5 --k 3 --proxy-mode record --live-provider
|
|
321
|
+
```
|
|
322
|
+
|
|
323
|
+
**A provider failure is not an agent failure.** The proxy retries rate limits and 5xx errors with
|
|
324
|
+
jittered, bounded backoff (honouring `Retry-After`) and records how long it waited. A trial that
|
|
325
|
+
still ends in a provider error is a `harness_error` with a cause (`sandbox`, `adapter_config`,
|
|
326
|
+
`entrypoint`, `grader`, `model_provider`, `internal`), excluded from the denominator and retried
|
|
327
|
+
once, never scored as the agent failing. Time spent backing off is added to the trial's deadline
|
|
328
|
+
(capped at twice the deadline), and the run prints what the provider said, for example the exact
|
|
329
|
+
rate limit it hit. Found the hard way: agents that had finished in one reply were being scored as
|
|
330
|
+
timeouts while their next request sat in a rate-limit backoff.
|
|
331
|
+
|
|
332
|
+
**Importing established benchmarks.** [Harbor](https://github.com/laude-institute/harbor)'s task
|
|
333
|
+
format is shared by dozens of benchmarks. `meridian import-harbor` reads it and writes a Meridian
|
|
334
|
+
suite:
|
|
335
|
+
|
|
336
|
+
```bash
|
|
337
|
+
uv run meridian import-harbor <tasks-dir> --out suites/harbor-slice --rewrite-uv-boilerplate
|
|
338
|
+
uv run meridian suite build-images suites/harbor-slice --drop-failed
|
|
339
|
+
uv run meridian run --suite suites/harbor-slice --sut fixtures --proxy-mode record --live-provider
|
|
340
|
+
```
|
|
341
|
+
|
|
342
|
+
The benchmark's hidden tests ship as grader-only files, never visible to the agent, and its
|
|
343
|
+
verifier script runs in a throwaway container with no network. The reward is read back between
|
|
344
|
+
random per-run markers, so nothing the agent prints can forge a pass. A task Meridian cannot honour
|
|
345
|
+
is **skipped with the reason**, not converted into something that runs under different rules:
|
|
346
|
+
multi-step tasks, GPUs, MCP servers, compose sidecars, Windows, non-apt bases, and verifiers that
|
|
347
|
+
install packages at test time.
|
|
348
|
+
|
|
349
|
+
What was actually checked: on Terminal-Bench 2.0, **66 of 89 tasks convert** (23 are refused because
|
|
350
|
+
their verifier needs the network); on Harbor's own 32 example tasks, 13 convert. A converted task
|
|
351
|
+
from Harbor's examples ran end to end on a real model and was graded by Harbor's own verifier. **A
|
|
352
|
+
Terminal-Bench slice has not been run yet** (it needs an Anthropic key), so no Terminal-Bench score
|
|
353
|
+
is claimed. Tasks run in a sandbox with no internet, which many Terminal-Bench tasks assume, so
|
|
354
|
+
expect that to cost points.
|
|
355
|
+
|
|
356
|
+
**Reading results.** `meridian run --out result.json`, then open the
|
|
357
|
+
[dashboard](https://patsypppe.github.io/meridian/dashboard/) (React + TypeScript, runs entirely in
|
|
358
|
+
your browser) and drop the file in: suite pass^k with a Student-t interval, harness errors by cause,
|
|
359
|
+
a per-task table, a trial grid, the pass@k vs pass^k curve, and a comparison against a baseline run.
|
|
360
|
+
With only a handful of tasks a percentile bootstrap undercovers, so the report shows both intervals.
|
|
361
|
+
|
|
362
|
+
---
|
|
363
|
+
|
|
364
|
+
## How it works
|
|
365
|
+
|
|
366
|
+
```
|
|
367
|
+
meridian run
|
|
368
|
+
├── manifest pins suite, config, image digests, adapter, harness version
|
|
369
|
+
├── proxy one container: budget ledger, credential broker, cassettes
|
|
370
|
+
└── per trial one container, one volume, torn down in a finally
|
|
371
|
+
├── adapter runs the agent inside the container
|
|
372
|
+
├── state extracted before the container is removed
|
|
373
|
+
└── graders assert against that state — never the trajectory
|
|
374
|
+
```
|
|
375
|
+
|
|
376
|
+
**Isolation.** Every container security option lives in exactly one file,
|
|
377
|
+
`src/meridian/runtime/isolation.py`, so a reviewer audits the isolation claim by
|
|
378
|
+
reading one file rather than grepping for `privileged`.
|
|
379
|
+
|
|
380
|
+
**The proxy.** The agent gets a `base_url` and no credential. The proxy holds the
|
|
381
|
+
key, enforces per-trial token and cost budgets where the spend actually happens,
|
|
382
|
+
and records or replays every call. One component satisfies secret injection, cost
|
|
383
|
+
control, and reproducibility.
|
|
384
|
+
|
|
385
|
+
**Cassettes are ordered tapes per trial**, not a request→response map. A map
|
|
386
|
+
would serve two trials of the same task the same response, every recorded run
|
|
387
|
+
would become deterministic, and `pass^k` could only ever be 0 or 1. Replay fails
|
|
388
|
+
closed: an unrecorded or out-of-order request is an error, never a live call.
|
|
389
|
+
|
|
390
|
+
**The harness never imports the system under test.** Only the adapter does, and it
|
|
391
|
+
runs inside the trial container.
|
|
392
|
+
|
|
393
|
+
---
|
|
394
|
+
|
|
395
|
+
## Measuring the harness
|
|
396
|
+
|
|
397
|
+
```bash
|
|
398
|
+
make self-eval # ~30 min: 46 real gate runs end to end
|
|
399
|
+
```
|
|
400
|
+
|
|
401
|
+
Three numbers, and the honest one is the first.
|
|
402
|
+
|
|
403
|
+
**False-regression rate** gates the *unchanged* agent 30 times against a fixed
|
|
404
|
+
baseline. Every FAIL is noise — the gate crying wolf at a change that did not
|
|
405
|
+
happen. Anything above zero means `n` is too low or the tolerance too tight, and
|
|
406
|
+
reporting that is worth more than a clean number nobody can reproduce.
|
|
407
|
+
|
|
408
|
+
**True-positive rate** seeds five regressions of known shape into the system under
|
|
409
|
+
test and counts how many the gate catches: the planner's expiry instruction
|
|
410
|
+
removed, a context-window guard that drops the transcript, a tool deleted,
|
|
411
|
+
`max_tokens` starved, and an arithmetic bug in the tool that writes the invoice.
|
|
412
|
+
Anything the gate misses is a change that would have shipped.
|
|
413
|
+
|
|
414
|
+
**Replay fidelity** re-runs archived runs from their manifests. Drift means an
|
|
415
|
+
input exists that the manifest does not pin.
|
|
416
|
+
|
|
417
|
+
Every seeded regression changes the system under test — never the harness, never
|
|
418
|
+
the thresholds. A benchmark that tunes the thing it is measuring measures
|
|
419
|
+
nothing. And a seeded edit that silently matches nothing raises rather than
|
|
420
|
+
quietly scoring as a miss the gate never had a chance at.
|
|
421
|
+
|
|
422
|
+
---
|
|
423
|
+
|
|
424
|
+
## Development
|
|
425
|
+
|
|
426
|
+
```bash
|
|
427
|
+
make check # ruff + mypy --strict + unit tests — green before any commit
|
|
428
|
+
make integration # Docker-backed tests
|
|
429
|
+
make e2e # full run, replay, and gate against the fixture agent
|
|
430
|
+
make sweep # remove leaked trial containers
|
|
431
|
+
cd web && npm ci && npm test && npm run build # the dashboard
|
|
432
|
+
```
|
|
433
|
+
|
|
434
|
+
About 570 Python tests (unit, Docker-backed integration, end to end) run under `mypy --strict` in a
|
|
435
|
+
five-job CI pipeline, plus the dashboard's own tests. The dashboard's TypeScript statistics are
|
|
436
|
+
checked against values exported from the Python implementation
|
|
437
|
+
(`uv run python -m benchmarks.export_web_vectors`), and a Python test fails if that file goes stale.
|
|
438
|
+
|
|
439
|
+
Pure logic — `stats/`, `gate/decide.py`, `manifest/build.py`, `grading/graders/` —
|
|
440
|
+
has no I/O and no Docker imports, and is unit tested exhaustively without a
|
|
441
|
+
daemon. The rule is not a coverage percentage: **every function in those modules
|
|
442
|
+
has both a passing case and a failing case.**
|
|
443
|
+
|
|
444
|
+
---
|
|
445
|
+
|
|
446
|
+
## Documentation
|
|
447
|
+
|
|
448
|
+
| | |
|
|
449
|
+
|---|---|
|
|
450
|
+
| [`CONTRIBUTING.md`](https://github.com/patsypppe/meridian/blob/main/CONTRIBUTING.md) | How to set up, find an issue, run the right tests, and open a pull request |
|
|
451
|
+
| [`CHANGELOG.md`](https://github.com/patsypppe/meridian/blob/main/CHANGELOG.md) | What changed in each release |
|
|
452
|
+
| [`SECURITY.md`](https://github.com/patsypppe/meridian/blob/main/SECURITY.md) | How to report a vulnerability privately |
|
|
453
|
+
| [`docs/runbook.md`](https://github.com/patsypppe/meridian/blob/main/docs/runbook.md) | One entry per failure mode: what you see, what it means, what to do |
|
|
454
|
+
| [`docs/demo/`](https://github.com/patsypppe/meridian/blob/main/docs/demo/) | Captured output from a real gated PR, and how to regenerate it |
|
|
455
|
+
| [`docs/HANDOFF.md`](https://github.com/patsypppe/meridian/blob/main/docs/HANDOFF.md) | The engineering contract this was built against |
|
|
456
|
+
| [`docs/PRD.md`](https://github.com/patsypppe/meridian/blob/main/docs/PRD.md) | Product requirements |
|
|
457
|
+
| [`web/README.md`](https://github.com/patsypppe/meridian/blob/main/web/README.md) | The React + TypeScript dashboard: what it shows, how its statistics are kept in step with Python |
|
|
458
|
+
| [`benchmarks/real-model-2026-10-23.md`](https://github.com/patsypppe/meridian/blob/main/benchmarks/real-model-2026-10-23.md) | The first real-model runs, with their caveats |
|
|
459
|
+
| [`THIRD_PARTY_NOTICES.md`](https://github.com/patsypppe/meridian/blob/main/THIRD_PARTY_NOTICES.md) | Code adapted from other projects, and its licenses |
|
|
460
|
+
|
|
461
|
+
## Not in this release
|
|
462
|
+
|
|
463
|
+
LLM-as-judge: it needs a calibration workflow and thirty human labels first, and an uncalibrated
|
|
464
|
+
judge is worse than no judge. Also out: the two-axis result cache (nothing expensive to memoize with
|
|
465
|
+
deterministic graders), drift detection, multi-tenancy, hosted runs, and adapters beyond LangGraph and
|
|
466
|
+
the trivial subprocess one (the terminal agent used for imported benchmarks is a LangGraph graph).
|
|
467
|
+
Known gaps: the cause of a harness error is saved in each run's result file but not yet in the
|
|
468
|
+
Postgres `trial` table; a timed-out trial is scored as a timeout without grading its final state;
|
|
469
|
+
and the suites are small, so intervals are wide.
|
|
470
|
+
|
|
471
|
+
## Credits
|
|
472
|
+
|
|
473
|
+
Small-sample interval code is adapted from [Inspect](https://github.com/UKGovernmentBEIS/inspect_ai)
|
|
474
|
+
(MIT); the benchmark task format is [Harbor](https://github.com/laude-institute/harbor)'s
|
|
475
|
+
(Apache-2.0). See [`THIRD_PARTY_NOTICES.md`](https://github.com/patsypppe/meridian/blob/main/THIRD_PARTY_NOTICES.md).
|