manyhands 1.0.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- manyhands-1.0.0/.gitignore +23 -0
- manyhands-1.0.0/CHANGELOG.md +31 -0
- manyhands-1.0.0/LICENSE +21 -0
- manyhands-1.0.0/PKG-INFO +596 -0
- manyhands-1.0.0/README.md +561 -0
- manyhands-1.0.0/pyproject.toml +75 -0
- manyhands-1.0.0/src/manyhands/__init__.py +7 -0
- manyhands-1.0.0/src/manyhands/__main__.py +5 -0
- manyhands-1.0.0/src/manyhands/align.py +209 -0
- manyhands-1.0.0/src/manyhands/backends.py +621 -0
- manyhands-1.0.0/src/manyhands/cli.py +526 -0
- manyhands-1.0.0/src/manyhands/evaluate.py +446 -0
- manyhands-1.0.0/src/manyhands/glossary.py +95 -0
- manyhands-1.0.0/src/manyhands/layout.py +268 -0
- manyhands-1.0.0/src/manyhands/pipeline.py +440 -0
- manyhands-1.0.0/src/manyhands/report.py +261 -0
- manyhands-1.0.0/src/manyhands/templates/index.html.j2 +51 -0
- manyhands-1.0.0/src/manyhands/templates/report.html.j2 +268 -0
- manyhands-1.0.0/src/manyhands/text.py +120 -0
- manyhands-1.0.0/src/manyhands/vote.py +232 -0
- manyhands-1.0.0/tests/conftest.py +66 -0
- manyhands-1.0.0/tests/data/groundtruth/alto-line.xml +28 -0
- manyhands-1.0.0/tests/data/groundtruth/alto-words.xml +35 -0
- manyhands-1.0.0/tests/data/groundtruth/page.xml +39 -0
- manyhands-1.0.0/tests/data/groundtruth/tei.xml +13 -0
- manyhands-1.0.0/tests/data/pages/.manyhands/transcripts/stub-a/journal-p001.json +10 -0
- manyhands-1.0.0/tests/data/pages/.manyhands/transcripts/stub-a/journal-p002.json +18 -0
- manyhands-1.0.0/tests/data/pages/.manyhands/transcripts/stub-b/journal-p001.json +14 -0
- manyhands-1.0.0/tests/data/pages/.manyhands/transcripts/stub-b/journal-p002.json +19 -0
- manyhands-1.0.0/tests/data/pages/.manyhands/transcripts/stub-c/journal-p001.json +14 -0
- manyhands-1.0.0/tests/data/pages/.manyhands/transcripts/stub-c/journal-p002.json +16 -0
- manyhands-1.0.0/tests/data/pages/SOURCE.md +27 -0
- manyhands-1.0.0/tests/data/pages/journal-p001.jpg +0 -0
- manyhands-1.0.0/tests/data/pages/journal-p002.jpg +0 -0
- manyhands-1.0.0/tests/test_align.py +119 -0
- manyhands-1.0.0/tests/test_backends.py +489 -0
- manyhands-1.0.0/tests/test_cli.py +452 -0
- manyhands-1.0.0/tests/test_evaluate.py +264 -0
- manyhands-1.0.0/tests/test_glossary.py +130 -0
- manyhands-1.0.0/tests/test_layout.py +152 -0
- manyhands-1.0.0/tests/test_pipeline.py +419 -0
- manyhands-1.0.0/tests/test_report.py +257 -0
- manyhands-1.0.0/tests/test_text.py +74 -0
- manyhands-1.0.0/tests/test_vote.py +240 -0
|
@@ -0,0 +1,23 @@
|
|
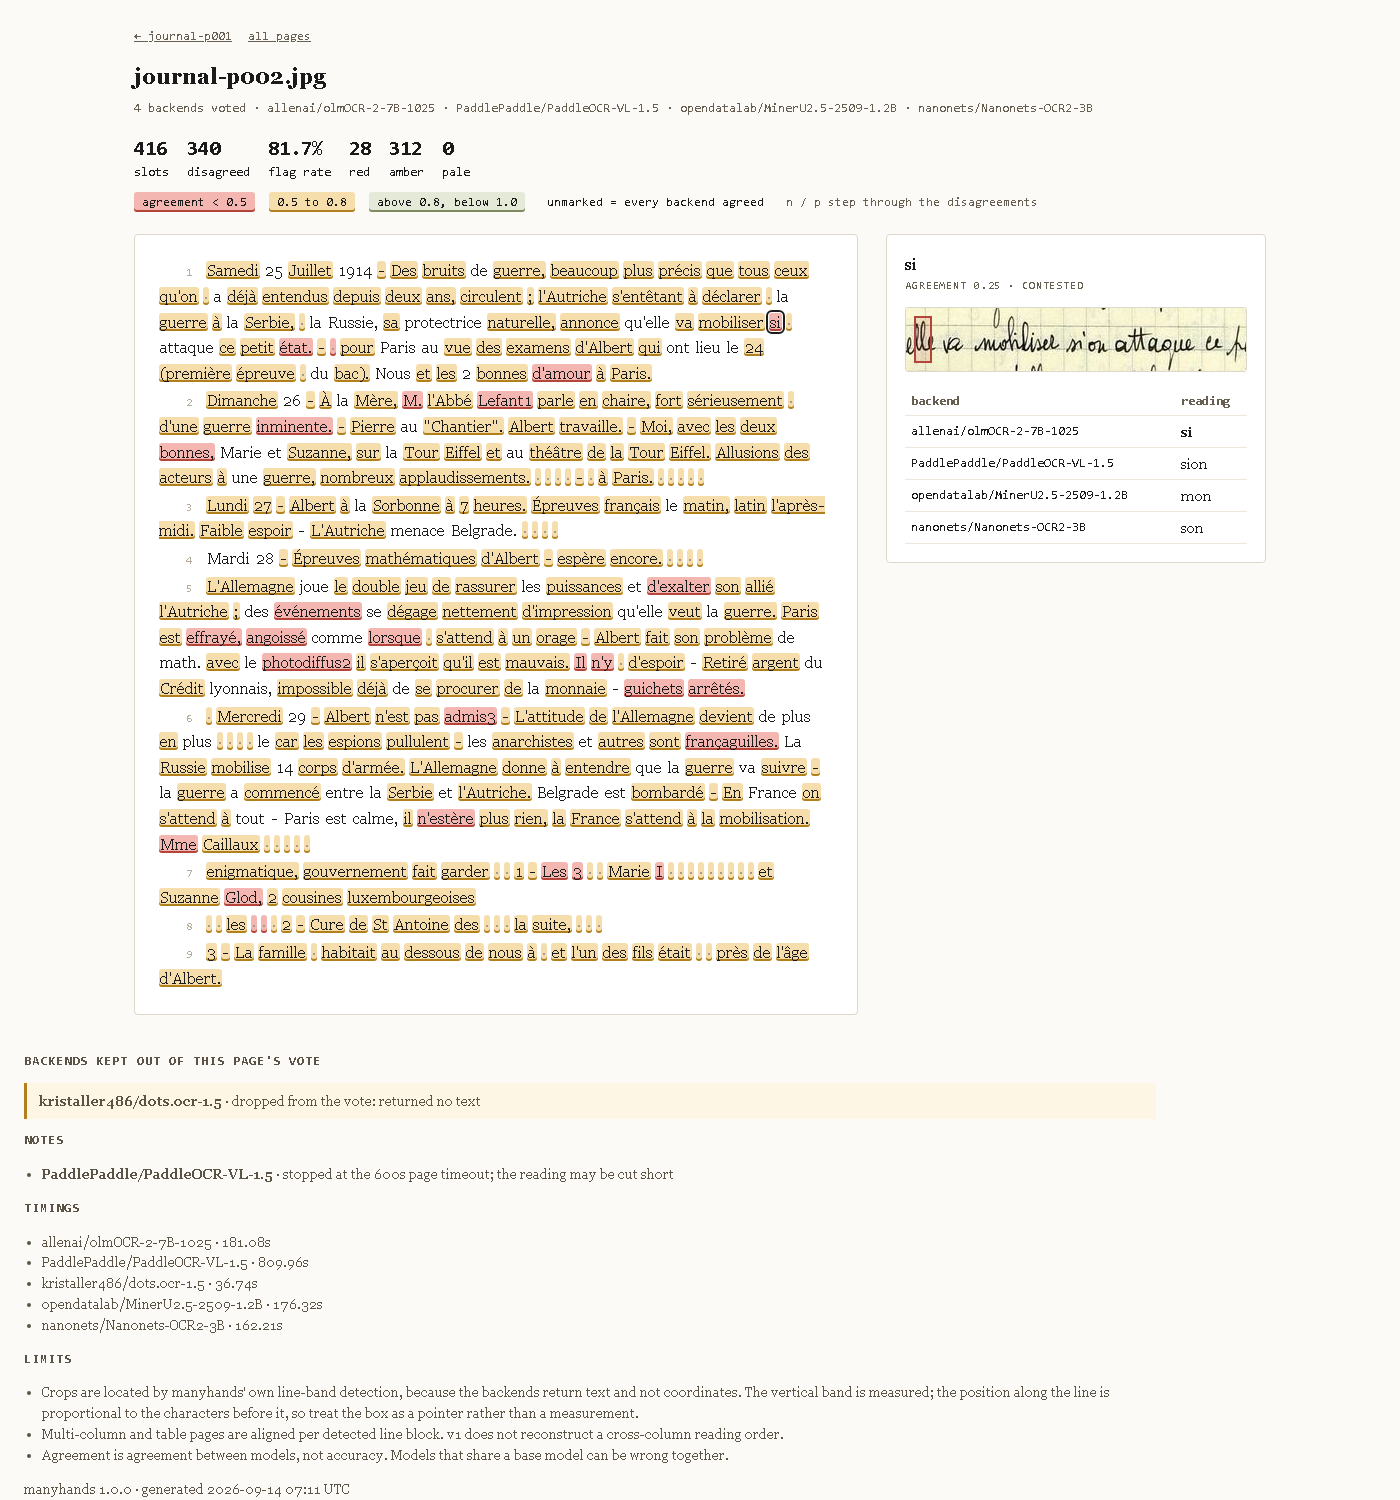
|
1
|
+
__pycache__/
|
|
2
|
+
*.py[cod]
|
|
3
|
+
*.egg-info/
|
|
4
|
+
build/
|
|
5
|
+
dist/
|
|
6
|
+
.venv/
|
|
7
|
+
venv/
|
|
8
|
+
.pytest_cache/
|
|
9
|
+
.ruff_cache/
|
|
10
|
+
.phase0/
|
|
11
|
+
# Generated report folders. tests/data/pages/.manyhands holds committed fixtures,
|
|
12
|
+
# so only the repo-root workspace is ignored.
|
|
13
|
+
/.manyhands/
|
|
14
|
+
manyhands-out/
|
|
15
|
+
# My own full-ensemble caches land next to the fixtures. Only the stubs are committed.
|
|
16
|
+
tests/data/pages/.manyhands/*
|
|
17
|
+
!tests/data/pages/.manyhands/transcripts/
|
|
18
|
+
tests/data/pages/.manyhands/transcripts/*
|
|
19
|
+
!tests/data/pages/.manyhands/transcripts/stub-*
|
|
20
|
+
# Scratch folder for my own full-ensemble runs; the numbers land in the README.
|
|
21
|
+
/runs/
|
|
22
|
+
*.swp
|
|
23
|
+
.DS_Store
|
|
@@ -0,0 +1,31 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
## 1.0.0
|
|
4
|
+
|
|
5
|
+
First release.
|
|
6
|
+
|
|
7
|
+
- `manyhands run <folder>` transcribes a folder of page images or PDFs with several local
|
|
8
|
+
vision-OCR models, aligns the transcripts, and writes `consensus.txt`, `agreement.json`
|
|
9
|
+
and a self-contained `report.html` per page, plus an index across the folder.
|
|
10
|
+
- The report highlights every disagreement in three bands by agreement ratio. Clicking one
|
|
11
|
+
shows the crop of the page beside each model's reading, `n` and `p` step through them, and
|
|
12
|
+
the reports link to each other and to the folder index.
|
|
13
|
+
- `manyhands confirm <page>` records accepted readings into `.manyhands/glossary.json`,
|
|
14
|
+
filed by the competing readings so one decision settles every later page that repeats it.
|
|
15
|
+
- `manyhands eval <dataset-dir>` scores flags against ALTO or PAGE-XML ground truth and
|
|
16
|
+
reports error-capture rate, flag rate and CER against a target set by `--target-capture`
|
|
17
|
+
and `--target-flag`. It scores the consensus text the run would write, character for
|
|
18
|
+
character, and warns when a ground-truth file names a page other than the one its stem
|
|
19
|
+
paired it with.
|
|
20
|
+
- Five permissively-licensed default models, driven through churro-ocr. `stanford-oval/churro-3B`
|
|
21
|
+
is opt-in and prints its licence notice.
|
|
22
|
+
- Anchor-based progressive alignment with null tokens, majority voting with agreement ratios,
|
|
23
|
+
and ties broken by a reading the glossary already confirms, then by backend rank.
|
|
24
|
+
- A model named twice, once by alias and once by id, votes once and the run says so. A model
|
|
25
|
+
cannot corroborate itself.
|
|
26
|
+
- `--json` on `run` writes a folder-level summary, slots and flags per page with the path to
|
|
27
|
+
each page's `agreement.json`, for anyone scripting over the output.
|
|
28
|
+
- Per-page transcript cache, so an interrupted run resumes and a re-report costs no GPU time.
|
|
29
|
+
- Backends that crash, loop, return nothing, or return a wildly different amount of text are
|
|
30
|
+
kept out of the vote and named in the report footer rather than failing the page. One that
|
|
31
|
+
fails to load, or fails three pages in a row, is not tried again for the rest of the run.
|
manyhands-1.0.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Booyaka101
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
manyhands-1.0.0/PKG-INFO
ADDED
|
@@ -0,0 +1,596 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: manyhands
|
|
3
|
+
Version: 1.0.0
|
|
4
|
+
Summary: Run several local OCR models over the same page and show a human exactly which words they disagree on.
|
|
5
|
+
Project-URL: Homepage, https://github.com/Booyaka101/manyhands
|
|
6
|
+
Project-URL: Repository, https://github.com/Booyaka101/manyhands
|
|
7
|
+
Project-URL: Issues, https://github.com/Booyaka101/manyhands/issues
|
|
8
|
+
Project-URL: Changelog, https://github.com/Booyaka101/manyhands/blob/main/CHANGELOG.md
|
|
9
|
+
Author-email: Booyaka101 <cbosch101@gmail.com>
|
|
10
|
+
License: MIT
|
|
11
|
+
License-File: LICENSE
|
|
12
|
+
Keywords: archives,ensemble,handwriting,historical-documents,htr,ocr,rover,transcription,vlm
|
|
13
|
+
Classifier: Development Status :: 4 - Beta
|
|
14
|
+
Classifier: Environment :: Console
|
|
15
|
+
Classifier: Intended Audience :: Science/Research
|
|
16
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
19
|
+
Classifier: Topic :: Scientific/Engineering :: Image Recognition
|
|
20
|
+
Classifier: Topic :: Text Processing :: Linguistic
|
|
21
|
+
Requires-Python: >=3.12
|
|
22
|
+
Requires-Dist: churro-ocr<1,>=0.3.0
|
|
23
|
+
Requires-Dist: jinja2<4,>=3.1
|
|
24
|
+
Requires-Dist: markupsafe<4,>=2.1
|
|
25
|
+
Requires-Dist: numpy<3,>=1.26
|
|
26
|
+
Requires-Dist: pillow<12,>=10.4.0
|
|
27
|
+
Requires-Dist: pypdfium2<6,>=5
|
|
28
|
+
Requires-Dist: typer<1,>=0.12.3
|
|
29
|
+
Provides-Extra: dev
|
|
30
|
+
Requires-Dist: pytest>=8; extra == 'dev'
|
|
31
|
+
Requires-Dist: ruff>=0.6; extra == 'dev'
|
|
32
|
+
Provides-Extra: hf
|
|
33
|
+
Requires-Dist: churro-ocr[hf]<1,>=0.3.0; extra == 'hf'
|
|
34
|
+
Description-Content-Type: text/markdown
|
|
35
|
+
|
|
36
|
+
# manyhands
|
|
37
|
+
|
|
38
|
+
Run several local OCR models over the same handwritten page and show a human exactly which
|
|
39
|
+
words they disagree on.
|
|
40
|
+
|
|
41
|
+
A single vision model transcribing a parish register gives you a wall of confident text.
|
|
42
|
+
Some of it is wrong, and nothing in the output tells you where. manyhands runs the page
|
|
43
|
+
through several different models, aligns what they produced, and highlights every word
|
|
44
|
+
they did not all agree on. You read the highlights instead of proofreading the page.
|
|
45
|
+
|
|
46
|
+
Everything runs locally. No API keys, no uploads, no model weights in this package.
|
|
47
|
+
|
|
48
|
+
|
|
49
|
+
|
|
50
|
+
Page two of the sample diary. `si` is highlighted red because the four models read it as `si`,
|
|
51
|
+
`sion`, `mon` and `son`. The panel shows the line it came from so you can settle it yourself.
|
|
52
|
+
|
|
53
|
+
## What you get per page
|
|
54
|
+
|
|
55
|
+
```
|
|
56
|
+
manyhands-out/
|
|
57
|
+
index.html
|
|
58
|
+
journal-p001/
|
|
59
|
+
consensus.txt the majority reading, one line per aligned line
|
|
60
|
+
agreement.json every slot, its vote counts, its agreement ratio, its bbox
|
|
61
|
+
report.html the consensus with disagreements highlighted, self-contained
|
|
62
|
+
```
|
|
63
|
+
|
|
64
|
+
`report.html` opens in a browser with no server and no network. Click a highlighted word
|
|
65
|
+
and a panel shows the cropped region of the page image alongside one row per model. `n` and
|
|
66
|
+
`p` step through the disagreements without touching the mouse, and each report links to the
|
|
67
|
+
pages either side of it and back to `index.html`.
|
|
68
|
+
|
|
69
|
+
## Install
|
|
70
|
+
|
|
71
|
+
```
|
|
72
|
+
pip install manyhands
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
That gives you the CLI and the alignment, voting and reporting code. It does not pull
|
|
76
|
+
torch, because the right torch build depends on your CUDA version. To actually run models:
|
|
77
|
+
|
|
78
|
+
```
|
|
79
|
+
pip install torch --index-url https://download.pytorch.org/whl/cu128 # or your CUDA build
|
|
80
|
+
pip install 'manyhands[hf]'
|
|
81
|
+
```
|
|
82
|
+
|
|
83
|
+
Model weights download from Hugging Face on first use, into the normal `HF_HOME` cache.
|
|
84
|
+
The five default weight sets are 34 GB together: 16.6, 7.5, 6.1, 2.3 and 1.9. On Windows
|
|
85
|
+
without developer mode the cache keeps two copies of each file, so budget double that.
|
|
86
|
+
|
|
87
|
+
`dots.ocr-1.5` is the exception. churro-ocr fetches it with `snapshot_download(local_dir=...)`
|
|
88
|
+
into `~/.cache/churro-ocr/hf/DotsOCR_1_5/`, so it ignores `HF_HOME` and lands on the system
|
|
89
|
+
drive whatever you set. That was 5.7 GB here.
|
|
90
|
+
|
|
91
|
+
Python 3.12 or newer.
|
|
92
|
+
|
|
93
|
+
## Usage
|
|
94
|
+
|
|
95
|
+
```
|
|
96
|
+
manyhands run <folder> transcribe every page and write the reports
|
|
97
|
+
manyhands confirm <page> record the readings you accept
|
|
98
|
+
manyhands eval <dataset-dir> score the flags against ALTO/PAGE-XML ground truth
|
|
99
|
+
```
|
|
100
|
+
|
|
101
|
+
### run
|
|
102
|
+
|
|
103
|
+
```
|
|
104
|
+
manyhands run scans/parish-register
|
|
105
|
+
```
|
|
106
|
+
|
|
107
|
+
Walks the folder for `.png .jpg .jpeg .tif .tiff .bmp .webp` and PDFs, rasterising PDF
|
|
108
|
+
pages at 300 dpi into `.manyhands/pdf-pages`. Each model is loaded once, run over the whole
|
|
109
|
+
folder, then released, because the default five do not fit in 24 GB together.
|
|
110
|
+
|
|
111
|
+
The two sample pages in this repo, run with the default five:
|
|
112
|
+
|
|
113
|
+
```
|
|
114
|
+
$ manyhands run tests/data/pages
|
|
115
|
+
allenai/olmOCR-2-7B-1025 · journal-p001.jpg: 11 tokens (119.2s)
|
|
116
|
+
allenai/olmOCR-2-7B-1025 · journal-p002.jpg: 365 tokens (181.1s)
|
|
117
|
+
PaddlePaddle/PaddleOCR-VL-1.5 · journal-p001.jpg: 11 tokens (37.0s)
|
|
118
|
+
PaddlePaddle/PaddleOCR-VL-1.5 · journal-p002.jpg: 288 tokens (810.0s)
|
|
119
|
+
kristaller486/dots.ocr-1.5 · journal-p001.jpg: 0 tokens (63.0s)
|
|
120
|
+
kristaller486/dots.ocr-1.5 · journal-p002.jpg: 0 tokens (36.7s)
|
|
121
|
+
opendatalab/MinerU2.5-2509-1.2B · journal-p001.jpg: 11 tokens (47.2s)
|
|
122
|
+
opendatalab/MinerU2.5-2509-1.2B · journal-p002.jpg: 343 tokens (176.3s)
|
|
123
|
+
nanonets/Nanonets-OCR2-3B · journal-p001.jpg: 11 tokens (47.6s)
|
|
124
|
+
nanonets/Nanonets-OCR2-3B · journal-p002.jpg: 365 tokens (162.2s)
|
|
125
|
+
journal-p001.jpg: 0/11 flagged (0%)
|
|
126
|
+
kristaller486/dots.ocr-1.5: dropped from the vote: returned no text
|
|
127
|
+
journal-p002.jpg: 340/416 flagged (82%)
|
|
128
|
+
kristaller486/dots.ocr-1.5: dropped from the vote: returned no text
|
|
129
|
+
|
|
130
|
+
2 pages, 340 of 427 slots flagged (79.6%)
|
|
131
|
+
reports: tests\data\pages\manyhands-out\index.html
|
|
132
|
+
```
|
|
133
|
+
|
|
134
|
+
82% on page two is not a bug, it is the answer. That page is dense 1914 French cursive, and
|
|
135
|
+
two of the four surviving models cannot read it: against `Samedi 25 Juillet 1914` they return
|
|
136
|
+
`Lamedi` and `Jameedi`, against `bruits` they return `briro` and `bulto`. Page one is a sparse
|
|
137
|
+
title page where the survivors agree on all eleven words, so nothing is highlighted. A high
|
|
138
|
+
flag rate means the ensemble is out of its depth on that hand, which is worth knowing before
|
|
139
|
+
you trust any single one of them on it.
|
|
140
|
+
|
|
141
|
+
Useful options:
|
|
142
|
+
|
|
143
|
+
| option | what it does |
|
|
144
|
+
| --- | --- |
|
|
145
|
+
| `--models N` | use the first N of the five defaults. Fewer models is faster, but flags more and reads worse, measured under eval below |
|
|
146
|
+
| `--backends a,b,c` | pick models by Hugging Face id, by alias, or by cached folder name |
|
|
147
|
+
| `--out DIR` | write reports somewhere other than `<folder>/manyhands-out` |
|
|
148
|
+
| `--page-timeout S` | stop a model after S seconds on one page and keep what it read. Default 600 |
|
|
149
|
+
| `--no-cache` | re-transcribe pages that are already in the cache |
|
|
150
|
+
| `--no-glossary` | ignore confirmed readings for this run |
|
|
151
|
+
| `--json FILE` | write a folder-level summary: slots, flags and the report path per page |
|
|
152
|
+
|
|
153
|
+
Every transcript is cached under `<folder>/.manyhands/transcripts/<model>/` as it lands,
|
|
154
|
+
and a page already in the cache is not read again. A run killed on page 80 of 200 picks up
|
|
155
|
+
at page 80. Re-running after a `confirm` costs no GPU time at all.
|
|
156
|
+
|
|
157
|
+
### confirm
|
|
158
|
+
|
|
159
|
+
```
|
|
160
|
+
manyhands confirm scans/parish-register/manyhands-out/journal-p001
|
|
161
|
+
```
|
|
162
|
+
|
|
163
|
+
Walks the flagged slots one at a time and asks which reading is right. You can type a
|
|
164
|
+
number to accept one of the offered readings, type your own, press Enter to skip, or `q`
|
|
165
|
+
to stop. For scripting, `--slot 42 --reading Fenwick` does one slot without prompting.
|
|
166
|
+
|
|
167
|
+
Decisions go into `.manyhands/glossary.json`, filed under the set of competing readings
|
|
168
|
+
rather than under a page and a slot. Confirming `Fenwick` over `Renwick` once settles every
|
|
169
|
+
later page where the same models produce the same argument.
|
|
170
|
+
|
|
171
|
+
`confirm` writes the glossary and nothing else. Run `manyhands run <folder>` again to rebuild
|
|
172
|
+
the reports with the confirmed readings applied and ticked. That second run reads every
|
|
173
|
+
transcript from the cache, so it costs no GPU time.
|
|
174
|
+
|
|
175
|
+
### eval
|
|
176
|
+
|
|
177
|
+
```
|
|
178
|
+
manyhands eval datasets/celestine-doniau-danest/data --per-page
|
|
179
|
+
```
|
|
180
|
+
|
|
181
|
+
Expects each page image next to an ALTO or PAGE-XML file with the same stem, which is how
|
|
182
|
+
[HTR-United](https://htr-united.github.io/) datasets ship. It answers the only question
|
|
183
|
+
that matters for this tool: if a human reads only the highlighted words, how many of the
|
|
184
|
+
real errors do they see, and how much do they have to read to see them.
|
|
185
|
+
|
|
186
|
+
It takes the same `--models`, `--backends`, `--page-timeout` and `--no-cache` options as
|
|
187
|
+
`run`, plus:
|
|
188
|
+
|
|
189
|
+
| option | what it does |
|
|
190
|
+
| --- | --- |
|
|
191
|
+
| `--per-page` | print a row per page as well as the totals |
|
|
192
|
+
| `--limit N` | score only the first N pages |
|
|
193
|
+
| `--out DIR` | also write the page reports and an index there |
|
|
194
|
+
| `--json FILE` | write the scores as JSON |
|
|
195
|
+
| `--target-capture F` | the capture the `[met]` line is judged against, default 0.70 |
|
|
196
|
+
| `--target-flag F` | the flag rate the `[met]` line is judged against, default 0.20 |
|
|
197
|
+
|
|
198
|
+
Two datasets, both published through HTR-United, both scored with the default five models on
|
|
199
|
+
an RTX 4090. Neither is bundled here; clone
|
|
200
|
+
[dataset-celestine-doniau-danest](https://github.com/HTR-United/dataset-celestine-doniau-danest)
|
|
201
|
+
and [tapuscorpus](https://github.com/HTR-United/tapuscorpus) if you want to reproduce these.
|
|
202
|
+
The model loading and per-page progress lines are cut from the blocks, everything else is what
|
|
203
|
+
the command printed.
|
|
204
|
+
|
|
205
|
+
#### 1914 French cursive, four pages
|
|
206
|
+
|
|
207
|
+
```
|
|
208
|
+
$ manyhands eval datasets/celestine-doniau-danest/data --per-page
|
|
209
|
+
10c3fa40-d683-4703-8bc4-94b48936ce85.jpg: capture 88%, flag 91%, CER 15.0%
|
|
210
|
+
7f841dee-0d18-4eef-9966-f13cc9f4589c.jpg: capture 87%, flag 79%, CER 12.3%
|
|
211
|
+
9ee628b4-e868-4236-a2bf-cd563acda597.jpg: capture 81%, flag 76%, CER 12.1%
|
|
212
|
+
e1c22fc0-d84b-4d17-96fb-e3269b4d048d.jpg: capture 0%, flag 40%, CER 8.3%
|
|
213
|
+
|
|
214
|
+
page slots flagged flag% capture% CER%
|
|
215
|
+
----------------------------------------------------------------------------
|
|
216
|
+
10c3fa40-d683-4703-8bc4-94b48936c 690 627 90.9% 87.8% 15.0%
|
|
217
|
+
7f841dee-0d18-4eef-9966-f13cc9f45 402 316 78.6% 86.7% 12.3%
|
|
218
|
+
9ee628b4-e868-4236-a2bf-cd563acda 669 511 76.4% 81.1% 12.1%
|
|
219
|
+
e1c22fc0-d84b-4d17-96fb-e3269b4d0 15 6 40.0% 0.0% 8.3%
|
|
220
|
+
|
|
221
|
+
pages scored 4
|
|
222
|
+
slots 1776
|
|
223
|
+
flagged slots 1460
|
|
224
|
+
|
|
225
|
+
error-capture rate 84.8% (1105 of 1303 wrong characters sit in a flagged word)
|
|
226
|
+
flag rate 82.2% (1460 of 1776 words highlighted for review)
|
|
227
|
+
consensus CER 13.2%
|
|
228
|
+
|
|
229
|
+
target capture >= 70%, flag rate < 20% [not met]
|
|
230
|
+
```
|
|
231
|
+
|
|
232
|
+
#### 20th-century French typescript, four pages
|
|
233
|
+
|
|
234
|
+
Four pages of Franz Toussaint's *Le Jardin des Caresses* out of tapuscorpus, copied into one
|
|
235
|
+
folder. tapuscorpus is much larger. Four pages is what 80 minutes of GPU time buys.
|
|
236
|
+
|
|
237
|
+
```
|
|
238
|
+
$ manyhands eval datasets/tapus-jardin --per-page
|
|
239
|
+
16_7e494_default.jpg: capture 99%, flag 75%, CER 1311.1%
|
|
240
|
+
18_9f102_default.jpg: capture 61%, flag 22%, CER 12.9%
|
|
241
|
+
20_21abf_default.jpg: capture 54%, flag 25%, CER 23.2%
|
|
242
|
+
22_c266f_default.jpg: capture 42%, flag 20%, CER 33.3%
|
|
243
|
+
|
|
244
|
+
page slots flagged flag% capture% CER%
|
|
245
|
+
----------------------------------------------------------------------------
|
|
246
|
+
16_7e494_default.jpg 20 15 75.0% 99.1% 1311.1%
|
|
247
|
+
18_9f102_default.jpg 129 28 21.7% 61.4% 12.9%
|
|
248
|
+
20_21abf_default.jpg 129 32 24.8% 54.4% 23.2%
|
|
249
|
+
22_c266f_default.jpg 177 35 19.8% 41.9% 33.3%
|
|
250
|
+
|
|
251
|
+
pages scored 4
|
|
252
|
+
slots 455
|
|
253
|
+
flagged slots 110
|
|
254
|
+
|
|
255
|
+
error-capture rate 79.3% (1243 of 1568 wrong characters sit in a flagged word)
|
|
256
|
+
flag rate 24.2% (110 of 455 words highlighted for review)
|
|
257
|
+
consensus CER 63.9%
|
|
258
|
+
|
|
259
|
+
target capture >= 70%, flag rate < 20% [not met]
|
|
260
|
+
```
|
|
261
|
+
|
|
262
|
+
#### Read that honestly
|
|
263
|
+
|
|
264
|
+
The bar is catching at least 70% of the wrong characters while highlighting under 20% of the
|
|
265
|
+
words. Neither dataset clears it, and they miss in opposite directions.
|
|
266
|
+
|
|
267
|
+
On the cursive the consensus is wrong about one character in eight, and the models disagree
|
|
268
|
+
about four words in five. Capture is genuinely 85%: re-read only the highlighted words and you
|
|
269
|
+
see five errors in six. But at an 82% flag rate you are re-reading nearly the whole page. On a
|
|
270
|
+
hand this hard manyhands orders your attention, it does not save you the reading. The fourth
|
|
271
|
+
page scoring 0% capture is fifteen words long with six wrong characters in them, which is
|
|
272
|
+
sample size, not signal.
|
|
273
|
+
|
|
274
|
+
The typescript inverts it. Flag rate falls to about a fifth of the words, which is the number
|
|
275
|
+
you want, and capture falls with it. Ignore the title page, discussed next, and the other three
|
|
276
|
+
come to 48.0% capture (292 of 608 wrong characters) at a 21.8% flag rate, over a 24.8% CER.
|
|
277
|
+
Half the errors are in words all five models agreed on, because on clean print the models are
|
|
278
|
+
good enough to make the same mistakes. Agreement is evidence only when the voters are
|
|
279
|
+
independent, and easy material makes them less so.
|
|
280
|
+
|
|
281
|
+
`16_7e494_default.jpg` and its 1311% CER is a ground-truth coverage artefact, not a transcription
|
|
282
|
+
failure. That page is a title page. The ALTO transcribes the seven-line title block and nothing
|
|
283
|
+
else, 72 characters, while the models read the whole page: the margin numbers `85 89 97 164 53`
|
|
284
|
+
and a long decorative rule of dashes. So 1013 consensus characters are scored against 72 of truth
|
|
285
|
+
and almost everything counts as an error. Those 960 characters are 61% of the dataset's error
|
|
286
|
+
total, and since they sit in flagged words they are what lifts the headline capture to 79.3%.
|
|
287
|
+
Quote the per-page rows, not that number.
|
|
288
|
+
|
|
289
|
+
Fewer models is worse on both axes except capture. The same cursive dataset with three backends
|
|
290
|
+
instead of five:
|
|
291
|
+
|
|
292
|
+
```
|
|
293
|
+
$ manyhands eval datasets/celestine-doniau-danest/data --per-page --backends olmocr,paddle,mineru
|
|
294
|
+
10c3fa40-d683-4703-8bc4-94b48936ce85.jpg: capture 92%, flag 91%, CER 17.4%
|
|
295
|
+
7f841dee-0d18-4eef-9966-f13cc9f4589c.jpg: capture 90%, flag 77%, CER 15.6%
|
|
296
|
+
9ee628b4-e868-4236-a2bf-cd563acda597.jpg: capture 90%, flag 96%, CER 16.0%
|
|
297
|
+
e1c22fc0-d84b-4d17-96fb-e3269b4d048d.jpg: capture 0%, flag 40%, CER 8.3%
|
|
298
|
+
|
|
299
|
+
page slots flagged flag% capture% CER%
|
|
300
|
+
----------------------------------------------------------------------------
|
|
301
|
+
10c3fa40-d683-4703-8bc4-94b48936c 684 620 90.6% 92.2% 17.4%
|
|
302
|
+
7f841dee-0d18-4eef-9966-f13cc9f45 387 299 77.3% 89.9% 15.6%
|
|
303
|
+
9ee628b4-e868-4236-a2bf-cd563acda 1835 1765 96.2% 90.0% 16.0%
|
|
304
|
+
e1c22fc0-d84b-4d17-96fb-e3269b4d0 15 6 40.0% 0.0% 8.3%
|
|
305
|
+
|
|
306
|
+
pages scored 4
|
|
307
|
+
slots 2921
|
|
308
|
+
flagged slots 2690
|
|
309
|
+
|
|
310
|
+
error-capture rate 90.5% (1465 of 1618 wrong characters sit in a flagged word)
|
|
311
|
+
flag rate 92.1% (2690 of 2921 words highlighted for review)
|
|
312
|
+
consensus CER 16.4%
|
|
313
|
+
|
|
314
|
+
target capture >= 70%, flag rate < 20% [not met]
|
|
315
|
+
```
|
|
316
|
+
|
|
317
|
+
| backends | capture | flag rate | consensus CER |
|
|
318
|
+
| --- | --- | --- | --- |
|
|
319
|
+
| olmOCR-2, PaddleOCR-VL, MinerU2.5 | 90.5% | 92.1% | 16.4% |
|
|
320
|
+
| the default five | 84.8% | 82.2% | 13.2% |
|
|
321
|
+
|
|
322
|
+
Capture rises because the flags cover nearly everything, which is not a win. The transcript gets
|
|
323
|
+
worse and there is more of the page to re-read. Page `9ee628b4` shows where the extra 1166 slots
|
|
324
|
+
come from: MinerU2.5 returns 1725 tokens for that page against about 600 from every other model,
|
|
325
|
+
and with only three voters that run of repeated text survives into the consensus.
|
|
326
|
+
|
|
327
|
+
So: run it when the material is hard enough that models disagree usefully and your alternative
|
|
328
|
+
is reading every word yourself. On clean print, a single good model plus a spellchecker will
|
|
329
|
+
cost you a lot less.
|
|
330
|
+
|
|
331
|
+
## How it works
|
|
332
|
+
|
|
333
|
+
**Transcribe.** Each backend returns the page as whatever it likes: markdown with tables,
|
|
334
|
+
HTML-ish layout markup, XML line elements, or a bare block of text. `backends.py` flattens
|
|
335
|
+
all of it to display lines so the aligner sees one grammar.
|
|
336
|
+
|
|
337
|
+
**Align.** `align.py` does anchor-based progressive multiple alignment, ROVER style. Tokens
|
|
338
|
+
whose normalised key occurs exactly once in every stream are certain matches, so they become
|
|
339
|
+
single-token columns and cut the page into independent gaps. Each gap is aligned the same
|
|
340
|
+
way recursively, because a key that was ambiguous over a whole page is usually unique inside
|
|
341
|
+
a twenty-token gap. When a gap has no anchors left it falls back to pairwise alignment
|
|
342
|
+
against the longest stream, which is where null tokens appear.
|
|
343
|
+
|
|
344
|
+
**Vote.** `vote.py` groups each column's readings by normalised key, takes the majority, and
|
|
345
|
+
records the agreement ratio. A tie goes to a reading the glossary already confirms, and
|
|
346
|
+
otherwise to the best-ranked backend holding it. The winner is marked `contested` in
|
|
347
|
+
`agreement.json`.
|
|
348
|
+
|
|
349
|
+
**Locate.** The models return text, not coordinates. `layout.py` finds the line bands itself:
|
|
350
|
+
Otsu threshold, a horizontal ink projection, a dense core per line grown out over its
|
|
351
|
+
ascenders and descenders, and the scanner's dark frame trimmed off first so it does not own
|
|
352
|
+
the profile. A document VLM returns a paragraph per entry rather than a line per line, so the
|
|
353
|
+
page is then treated as a ribbon: bands are handed to consensus lines in proportion to their
|
|
354
|
+
character count, and words are laid along the bands their line covers. The vertical band is
|
|
355
|
+
measured. The position along it is an estimate, which is why the report shows the whole line
|
|
356
|
+
crop with the slot boxed rather than a tight crop.
|
|
357
|
+
|
|
358
|
+
### Worked example
|
|
359
|
+
|
|
360
|
+
Five models read a line of a parish register. Four return `Fenwick` and one returns
|
|
361
|
+
`Renwick`:
|
|
362
|
+
|
|
363
|
+
| model | reading |
|
|
364
|
+
| --- | --- |
|
|
365
|
+
| olmOCR-2 | Buried this day John **Fenwick** of the parish |
|
|
366
|
+
| PaddleOCR-VL | Buried this day John **Fenwick** of the parish |
|
|
367
|
+
| dots.ocr | Buried this day John **Fenwick** of the parish |
|
|
368
|
+
| MinerU2.5 | Buried this day John **Fenwick** of the parish |
|
|
369
|
+
| Nanonets-OCR2 | Buried this day John **Renwick** of the parish |
|
|
370
|
+
|
|
371
|
+
The consensus is `Fenwick`, agreement 0.8, drawn amber. Clicking it lists all five readings
|
|
372
|
+
next to the crop of that line.
|
|
373
|
+
|
|
374
|
+
Split the vote two ways and it gets more interesting. Two models read `Fenwick`, two read
|
|
375
|
+
`Fenwich`, one reads `Renwick`: agreement drops to 0.4, the word goes red, and the slot is
|
|
376
|
+
marked `"contested": true` because the plurality reading did not win outright.
|
|
377
|
+
|
|
378
|
+
### Bands
|
|
379
|
+
|
|
380
|
+
| agreement | colour | meaning |
|
|
381
|
+
| --- | --- | --- |
|
|
382
|
+
| 1.0 | none | every model read the same word |
|
|
383
|
+
| above 0.8 | pale | one dissenter in a large ensemble |
|
|
384
|
+
| 0.5 to 0.8 | amber | four of five, or three of four |
|
|
385
|
+
| below 0.5 | red | no reading held a majority |
|
|
386
|
+
|
|
387
|
+
Four models out of five is 0.8 and reads as amber, so the top of the amber band is
|
|
388
|
+
inclusive.
|
|
389
|
+
|
|
390
|
+
## Configuration
|
|
391
|
+
|
|
392
|
+
Default ensemble, in rank order. Rank breaks a tie the glossary does not.
|
|
393
|
+
|
|
394
|
+
| alias | model | params | weights |
|
|
395
|
+
| --- | --- | --- | --- |
|
|
396
|
+
| `olmocr` | `allenai/olmOCR-2-7B-1025` | 7B | 16.6 GB |
|
|
397
|
+
| `paddle` | `PaddlePaddle/PaddleOCR-VL-1.5` | 0.9B | 1.9 GB |
|
|
398
|
+
| `dots` | `kristaller486/dots.ocr-1.5` | 3B | 6.1 GB |
|
|
399
|
+
| `mineru` | `opendatalab/MinerU2.5-2509-1.2B` | 1.2B | 2.3 GB |
|
|
400
|
+
| `nanonets` | `nanonets/Nanonets-OCR2-3B` | 3B | 7.5 GB |
|
|
401
|
+
|
|
402
|
+
`dots.ocr-1.5` contributed nothing to any page reported here, in two different ways. On the two
|
|
403
|
+
sample pages it returns no text: no error, no timeout, zero tokens after 63s and 37s. On all
|
|
404
|
+
eight eval pages, cursive and typescript alike, it dies with `CUDA out of memory. Tried to
|
|
405
|
+
allocate 27.76 GiB` on a 24 GB card. It asks for the whole page at native resolution, so what
|
|
406
|
+
kills it is scan size rather than the hand. It is still in the default five because it is a
|
|
407
|
+
capable model on smaller images and on a bigger card, and because ten pages from two documents
|
|
408
|
+
is thin evidence for editing a default. If it does this to you, the footer will say so and it
|
|
409
|
+
will stop being tried after the third page. Drop it outright with `--backends` if you would
|
|
410
|
+
rather not pay for those three.
|
|
411
|
+
|
|
412
|
+
Other aliases that resolve to models churro-ocr knows: `olmocr-fp8`, `dots-mocr`, `chandra`,
|
|
413
|
+
`deepseek`, `glm`, `infinity`, `lfm`, `churro`. Any Hugging Face id works too.
|
|
414
|
+
|
|
415
|
+
`stanford-oval/churro-3B` is opt-in and prints a notice when you use it. Its weights are
|
|
416
|
+
under the Qwen-research licence, not a permissive open-source licence, so it is not in the
|
|
417
|
+
default five. Check the terms before you use its output.
|
|
418
|
+
|
|
419
|
+
Diversity comes only from using different models. Four of the five default churro-ocr
|
|
420
|
+
profiles resolve to `do_sample: False` and olmOCR-2 to `temperature: 0.1`, so sampling one
|
|
421
|
+
model five times would return one answer five times. There is deliberately no temperature
|
|
422
|
+
path.
|
|
423
|
+
|
|
424
|
+
### Performance
|
|
425
|
+
|
|
426
|
+
Measured on an RTX 4090 (24 GB), CUDA 12.8, weights already in the cache. The two sample
|
|
427
|
+
pages with the default five took 28 minutes end to end, 12:16:08 to 12:44:15:
|
|
428
|
+
|
|
429
|
+
| page | five models | what dominates it |
|
|
430
|
+
| --- | --- | --- |
|
|
431
|
+
| `journal-p001.jpg`, a sparse title page, 11 words | 5m 14s | loading five sets of weights |
|
|
432
|
+
| `journal-p002.jpg`, dense cursive, ~400 words | 22m 46s | PaddleOCR-VL alone, 810s of it |
|
|
433
|
+
|
|
434
|
+
The eight eval pages above ran the same five models. Excluding a nearly blank page that took
|
|
435
|
+
90 seconds, they ranged from 12 to 41 minutes each, median 15.6 minutes.
|
|
436
|
+
|
|
437
|
+
PaddleOCR-VL is usually more than half of that on its own. Over the seven dense eval pages it
|
|
438
|
+
spent 484s, 601s, 618s, 628s, 632s, 668s and 869s, against 42s to 418s for olmOCR-2 on the same
|
|
439
|
+
pages. Dropping it with `--backends` roughly halves the wall clock and costs you one vote.
|
|
440
|
+
|
|
441
|
+
manyhands runs one model over the whole folder, frees its weights, then loads the next, because
|
|
442
|
+
five 3B to 7B models do not fit in 24 GB at once. So a two-page folder pays for five weight
|
|
443
|
+
loads and a two-hundred-page folder also pays for five. Small folders carry a load tax that
|
|
444
|
+
large ones amortise away, which is why the sparse title page above cost five minutes.
|
|
445
|
+
|
|
446
|
+
Budget this for a folder overnight, not for someone waiting at a terminal. Transcripts are
|
|
447
|
+
cached under `.manyhands/transcripts`, so re-running to rebuild the reports after `confirm`
|
|
448
|
+
costs no GPU time. None of these numbers include the 34 GB of first-use weight downloads
|
|
449
|
+
described under Install.
|
|
450
|
+
|
|
451
|
+
## When a model misbehaves
|
|
452
|
+
|
|
453
|
+
The failure modes are not hypothetical, so each one has a defined behaviour.
|
|
454
|
+
|
|
455
|
+
**A model crashes or will not download.** That page records the failure, the rest of the
|
|
456
|
+
ensemble votes without it, and the report footer says which model dropped out and why. A model
|
|
457
|
+
that fails to load is not retried on later pages, and neither is one that fails three pages in
|
|
458
|
+
a row. Running out of VRAM on an archive scan can cost ten minutes before it raises, so a
|
|
459
|
+
backend that cannot handle your pages is not allowed to charge you for every one of them.
|
|
460
|
+
|
|
461
|
+
**A model loops.** Document VLMs fail by latching onto a phrase and emitting it until they
|
|
462
|
+
run out of tokens. A transcript more than half covered by an immediately repeated n-gram is
|
|
463
|
+
dropped from the vote and named in the footer.
|
|
464
|
+
|
|
465
|
+
**A model runs long.** After `--page-timeout` seconds of generation the model is stopped and
|
|
466
|
+
whatever it produced is kept, with a note on the transcript. Default 600 seconds. Not every
|
|
467
|
+
backend honours it. The deadline goes in as a transformers stopping criterion, and some churro
|
|
468
|
+
profiles reach `generate` by a path that never consults one, so the footer says which of the
|
|
469
|
+
two happened rather than claiming a stop that never came.
|
|
470
|
+
|
|
471
|
+
**A model reads a different page.** A transcript over 3x the page's median token count, or
|
|
472
|
+
under a third of it, is dropped from the vote. Overshooting means it invented most of what it
|
|
473
|
+
returned, undershooting means it stopped partway down the page, and either way the rest of its
|
|
474
|
+
"reading" is silence rather than disagreement.
|
|
475
|
+
|
|
476
|
+
**A model reads nothing.** A backend that returns no text at all, on a page the others read
|
|
477
|
+
fine, is dropped exactly like one that crashed. Counting its silence as a dissenting vote
|
|
478
|
+
would flag every word on the page. `dots.ocr-1.5` does this on both sample pages.
|
|
479
|
+
|
|
480
|
+
**Too few models left.** Below three usable voters the outlier rules are suspended, everyone
|
|
481
|
+
is kept, and the notes say so. Dropping a model when only two are left is not a vote.
|
|
482
|
+
|
|
483
|
+
**A blank page.** If every model reads the page as empty, the consensus is empty and the page
|
|
484
|
+
is flagged `blank`. It does not emit whatever one model hallucinated.
|
|
485
|
+
|
|
486
|
+
**Every model failed.** `manyhands run` exits 3 rather than reporting a clean page with zero
|
|
487
|
+
flags.
|
|
488
|
+
|
|
489
|
+
**One model listed twice.** `--backends olmocr,allenai/olmOCR-2-7B-1025` names one model two
|
|
490
|
+
ways. It votes once, and the run says so on stderr. A model cannot corroborate itself, and
|
|
491
|
+
counting it twice would report a lone reading as agreed.
|
|
492
|
+
|
|
493
|
+
## Limitations
|
|
494
|
+
|
|
495
|
+
- **Agreement is agreement, not accuracy.** Models that share a base model can be confidently
|
|
496
|
+
wrong together. An unflagged word is one nobody disagreed about, which is not the same as a
|
|
497
|
+
word that is right. The eval numbers above are the honest measure of this.
|
|
498
|
+
- **Case and edge punctuation are not disagreements.** One model reading `JOURNAL` and
|
|
499
|
+
another `Journal,` are grouped as the same word, because otherwise a page the models agree
|
|
500
|
+
on perfectly lights up red. Letters and diacritics are never folded, since those are exactly
|
|
501
|
+
the differences a palaeographer needs to see. Long s, ligatures and typographic quotes are
|
|
502
|
+
folded.
|
|
503
|
+
- **Bounding boxes are estimates.** The line band is measured from the ink. Which band a word
|
|
504
|
+
lands on, and where along it, is proportional to character counts, so a model that dropped
|
|
505
|
+
half a page drags its neighbours' boxes with it. Treat the box as a pointer at the line, not
|
|
506
|
+
a measurement of the word.
|
|
507
|
+
- **Multi-column and table pages** are aligned per detected line block. v1 does not reconstruct
|
|
508
|
+
a cross-column reading order, so a two-column page produces bands spanning both columns and
|
|
509
|
+
the alignment will fight the reading order.
|
|
510
|
+
- **No training, no cloud, no GUI.** By design. See the non-goals below.
|
|
511
|
+
|
|
512
|
+
## Prior art
|
|
513
|
+
|
|
514
|
+
Cross-model confidence voting in OCR is not new. [Calamari-OCR](https://github.com/Calamari-OCR/calamari)
|
|
515
|
+
has shipped voting across an ensemble of models for years, and it is the reference
|
|
516
|
+
implementation for this idea in the HTR world. If you have segmented line images and can
|
|
517
|
+
train your own models, use Calamari.
|
|
518
|
+
|
|
519
|
+
manyhands differs in three ways.
|
|
520
|
+
|
|
521
|
+
It votes across heterogeneous third-party document VLMs with different output grammars,
|
|
522
|
+
rather than across a cross-fold ensemble of one architecture you trained yourself. Getting
|
|
523
|
+
five different models' markdown, XML and layout markup into one comparable token stream is
|
|
524
|
+
most of the work.
|
|
525
|
+
|
|
526
|
+
It works on whole page scans with no ground truth and no line segmentation, rather than on
|
|
527
|
+
pre-segmented line images.
|
|
528
|
+
|
|
529
|
+
Most of all, it spends the disagreement on the human rather than on the transcript. Calamari
|
|
530
|
+
uses the vote to produce one better line. manyhands shows you the vote, per word, next to
|
|
531
|
+
the image, because on historical material the value of knowing a word is uncertain is higher
|
|
532
|
+
than the value of a marginally better guess at it.
|
|
533
|
+
|
|
534
|
+
## If you run it on your own material
|
|
535
|
+
|
|
536
|
+
The eval numbers above come from eight pages: four of one 1914 French diary and four of one
|
|
537
|
+
20th-century French typescript. Two hands is not a corpus. Whether an ensemble catches errors
|
|
538
|
+
on your hand is an empirical question, and the answer changes with the script, the century and
|
|
539
|
+
the language. If you have an HTR-United dataset, or any folder of pages with ALTO or PAGE-XML
|
|
540
|
+
beside them, `manyhands eval` on it is one command.
|
|
541
|
+
Open an issue with the error-capture and flag rates you got, the hand, and the backends you
|
|
542
|
+
used. Numbers from other people's material are the most useful thing this project can
|
|
543
|
+
receive right now, and the ones that hold up go in this README.
|
|
544
|
+
|
|
545
|
+
## Status
|
|
546
|
+
|
|
547
|
+
1.0.0, and the trove classifier still says Beta, which is the honest pair. Everything documented
|
|
548
|
+
here runs and is covered by tests. What is thin is the evidence: eight scored pages from two
|
|
549
|
+
documents, one hand each, on one GPU. Nothing here has met a hand it was not developed against.
|
|
550
|
+
|
|
551
|
+
Distribution plan, such as it is. PyPI first, because every other step needs an install command
|
|
552
|
+
that works. Then one write-up in r/LocalLLaMA led with the numbers above, the 48.0% capture on
|
|
553
|
+
typescript included, since a post that only quotes 79.3% would be the exact overclaim this tool
|
|
554
|
+
exists to argue against.
|
|
555
|
+
|
|
556
|
+
## Non-goals
|
|
557
|
+
|
|
558
|
+
No model training or fine-tuning. No cloud or API backends. No layout editor. No translation.
|
|
559
|
+
No GUI app. No hosted service. No model weights shipped in this package.
|
|
560
|
+
|
|
561
|
+
## Development
|
|
562
|
+
|
|
563
|
+
```
|
|
564
|
+
git clone https://github.com/Booyaka101/manyhands
|
|
565
|
+
cd manyhands
|
|
566
|
+
python -m venv .venv && .venv/Scripts/activate # or source .venv/bin/activate
|
|
567
|
+
pip install -e '.[dev]'
|
|
568
|
+
pytest
|
|
569
|
+
ruff check .
|
|
570
|
+
```
|
|
571
|
+
|
|
572
|
+
`backends.py` carries one upstream workaround. Four of churro-ocr 0.3.0's preset backends,
|
|
573
|
+
two of them in the default five, combine `@dataclass(slots=True)` with a zero-argument
|
|
574
|
+
`super()`, which raises `TypeError` before any weights load. `repair_preset_super()` patches
|
|
575
|
+
the stale `__class__` cell at load time. It only matters on Python 3.12: 3.13 repoints the cell
|
|
576
|
+
itself when the slotted dataclass is rebuilt, so on 3.13 the function finds nothing to do and
|
|
577
|
+
the presets work unpatched. The draft issue is in
|
|
578
|
+
[docs/churro-issue.md](https://github.com/Booyaka101/manyhands/blob/main/docs/churro-issue.md),
|
|
579
|
+
and the workaround comes out when a churro-ocr release carries the fix.
|
|
580
|
+
|
|
581
|
+
The test suite runs without a GPU and without torch, on Linux and Windows, on 3.12 and 3.13.
|
|
582
|
+
`.github/workflows/ci.yml` runs ruff and pytest over that matrix. The integration tests drive the whole
|
|
583
|
+
pipeline from committed transcript fixtures under `tests/data/pages/.manyhands/transcripts/`,
|
|
584
|
+
which are real output from three of the default models, frozen. Those fixtures are test-only;
|
|
585
|
+
nothing in the shipped package reads them.
|
|
586
|
+
|
|
587
|
+
## Licence
|
|
588
|
+
|
|
589
|
+
MIT. See [LICENSE](LICENSE).
|
|
590
|
+
|
|
591
|
+
The two sample pages under `tests/data/pages/` come from the
|
|
592
|
+
[Célestine Doniau-Danest journal](https://github.com/HTR-United/dataset-celestine-doniau-danest)
|
|
593
|
+
dataset, CC-BY-4.0. The eval numbers above also use
|
|
594
|
+
[tapuscorpus](https://github.com/HTR-United/tapuscorpus), CC-BY-4.0, which is not bundled here.
|
|
595
|
+
Both are published through HTR-United. Model weights are downloaded from Hugging Face and carry
|
|
596
|
+
their own licences.
|