loraport 0.1.3__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- loraport-0.1.3/.github/ISSUE_TEMPLATE/bug.yml +22 -0
- loraport-0.1.3/.github/ISSUE_TEMPLATE/question.yml +11 -0
- loraport-0.1.3/.github/workflows/ci.yml +31 -0
- loraport-0.1.3/.gitignore +41 -0
- loraport-0.1.3/.python-version +1 -0
- loraport-0.1.3/CHANGELOG.md +32 -0
- loraport-0.1.3/LICENSE +21 -0
- loraport-0.1.3/PKG-INFO +258 -0
- loraport-0.1.3/README.en.md +229 -0
- loraport-0.1.3/README.md +231 -0
- loraport-0.1.3/SECURITY.md +7 -0
- loraport-0.1.3/docs/format-notes.md +35 -0
- loraport-0.1.3/docs/images/01-hero.png +0 -0
- loraport-0.1.3/docs/images/02-inspect.png +0 -0
- loraport-0.1.3/docs/images/03-convert.png +0 -0
- loraport-0.1.3/docs/images/04-verify-trap.png +0 -0
- loraport-0.1.3/docs/images/05-reject-dora.png +0 -0
- loraport-0.1.3/pyproject.toml +54 -0
- loraport-0.1.3/src/loraport/__init__.py +30 -0
- loraport-0.1.3/src/loraport/basecfg.py +92 -0
- loraport-0.1.3/src/loraport/cli.py +158 -0
- loraport-0.1.3/src/loraport/convert.py +126 -0
- loraport-0.1.3/src/loraport/delta.py +129 -0
- loraport-0.1.3/src/loraport/detect.py +40 -0
- loraport-0.1.3/src/loraport/errors.py +29 -0
- loraport-0.1.3/src/loraport/formats/__init__.py +1 -0
- loraport-0.1.3/src/loraport/formats/common.py +56 -0
- loraport-0.1.3/src/loraport/formats/mlx.py +117 -0
- loraport-0.1.3/src/loraport/formats/peft.py +125 -0
- loraport-0.1.3/src/loraport/model.py +80 -0
- loraport-0.1.3/src/loraport/render.py +90 -0
- loraport-0.1.3/src/loraport/sample.py +163 -0
- loraport-0.1.3/src/loraport/st_io.py +112 -0
- loraport-0.1.3/tests/conftest.py +38 -0
- loraport-0.1.3/tests/test_cli.py +94 -0
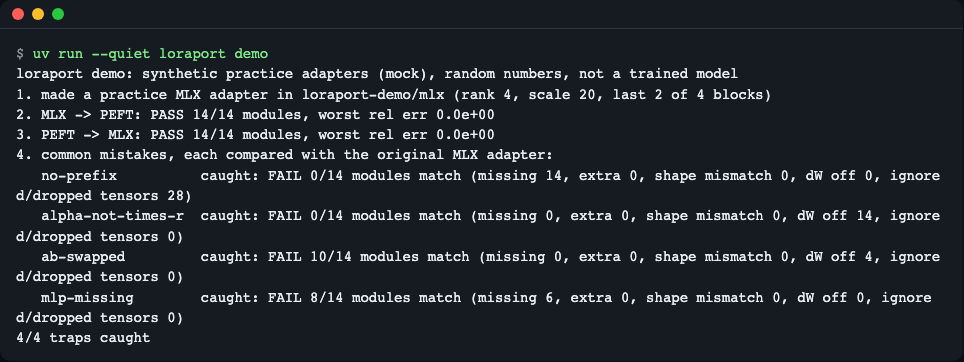
- loraport-0.1.3/tests/test_convert.py +160 -0
- loraport-0.1.3/tests/test_delta.py +62 -0
- loraport-0.1.3/tests/test_formats.py +158 -0
- loraport-0.1.3/tests/test_mlx_integration.py +51 -0
- loraport-0.1.3/tests/test_peft_integration.py +55 -0
- loraport-0.1.3/tests/test_unsupported.py +91 -0
- loraport-0.1.3/tests/test_verify.py +52 -0
- loraport-0.1.3/uv.lock +1490 -0
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
name: 버그 / Bug
|
|
2
|
+
description: README대로 했는데 다르게 동작해요 / Something does not work as the README says
|
|
3
|
+
labels: [bug]
|
|
4
|
+
body:
|
|
5
|
+
- type: textarea
|
|
6
|
+
id: what
|
|
7
|
+
attributes:
|
|
8
|
+
label: 무엇이 일어났나요? / What happened?
|
|
9
|
+
description: 실행한 명령과 나온 메시지를 그대로 붙여 주세요. / Paste the command and the output.
|
|
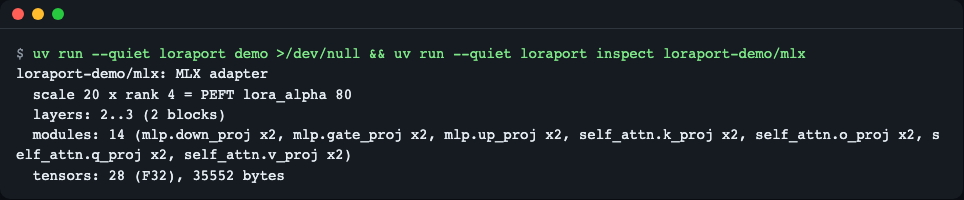
10
|
+
validations:
|
|
11
|
+
required: true
|
|
12
|
+
- type: textarea
|
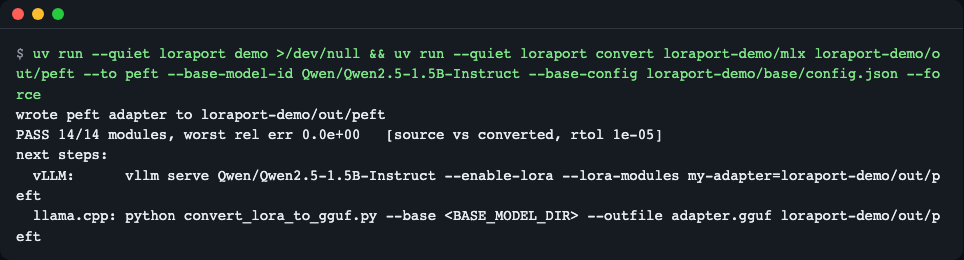
|
13
|
+
id: expected
|
|
14
|
+
attributes:
|
|
15
|
+
label: 기대한 결과 / Expected
|
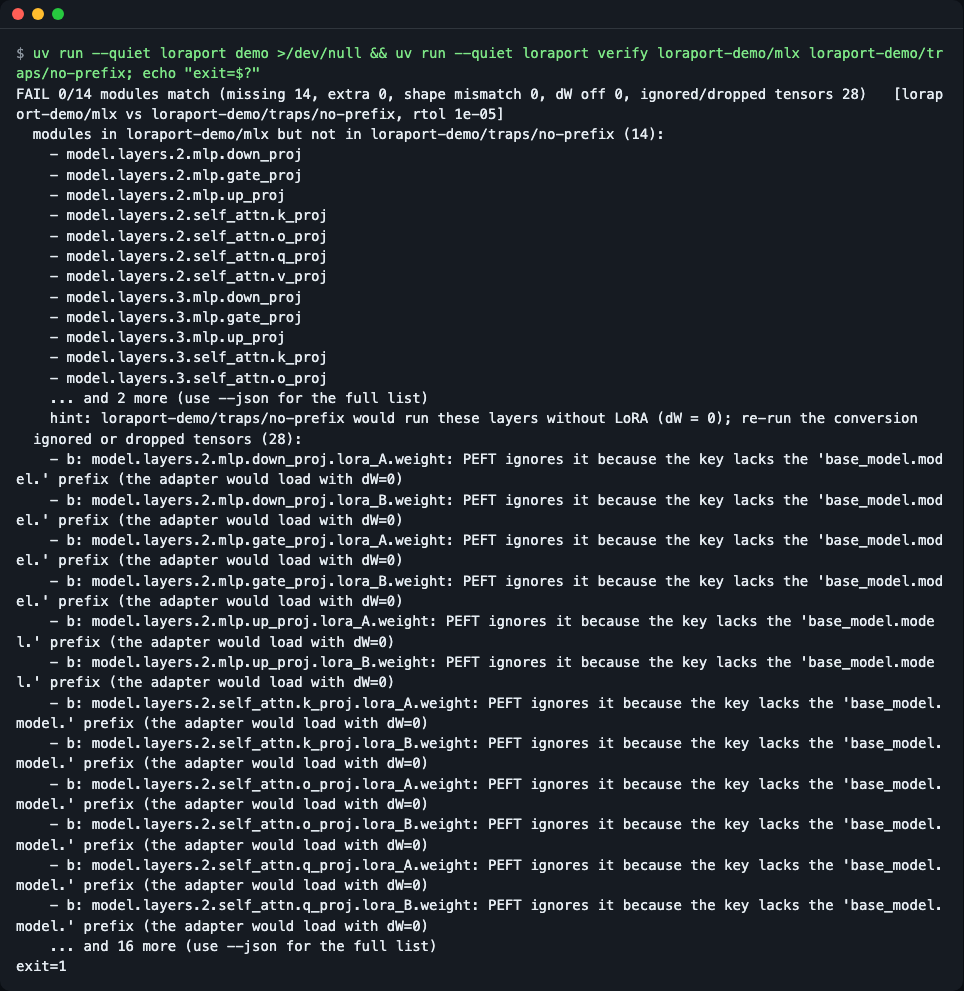
|
16
|
+
- type: input
|
|
17
|
+
id: env
|
|
18
|
+
attributes:
|
|
19
|
+
label: 환경 / Environment
|
|
20
|
+
placeholder: "macOS 15 (M3) · Ubuntu 24.04 · Windows 11 / uv 0.x / mock or real mode"
|
|
21
|
+
validations:
|
|
22
|
+
required: true
|
|
@@ -0,0 +1,11 @@
|
|
|
1
|
+
name: 질문 / Question
|
|
2
|
+
description: 이해가 안 되는 부분이나 더 알고 싶은 점 / Something unclear or worth explaining
|
|
3
|
+
labels: [question]
|
|
4
|
+
body:
|
|
5
|
+
- type: textarea
|
|
6
|
+
id: question
|
|
7
|
+
attributes:
|
|
8
|
+
label: 질문 / Question
|
|
9
|
+
description: README의 어느 부분(절 제목)에 대한 질문인지 알려 주세요. / Which README section is this about?
|
|
10
|
+
validations:
|
|
11
|
+
required: true
|
|
@@ -0,0 +1,31 @@
|
|
|
1
|
+
# Default tests need no network, GPU, torch or mlx: adapters are synthesized at test time.
|
|
2
|
+
name: ci
|
|
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
pull_request:
|
|
6
|
+
schedule:
|
|
7
|
+
- cron: "17 3 * * 1" # weekly: catch breakage from new numpy/safetensors releases
|
|
8
|
+
workflow_dispatch:
|
|
9
|
+
jobs:
|
|
10
|
+
test:
|
|
11
|
+
strategy:
|
|
12
|
+
fail-fast: false
|
|
13
|
+
matrix:
|
|
14
|
+
os: [ubuntu-latest, macos-latest]
|
|
15
|
+
runs-on: ${{ matrix.os }}
|
|
16
|
+
steps:
|
|
17
|
+
- uses: actions/checkout@v4
|
|
18
|
+
- uses: astral-sh/setup-uv@v10.3.3
|
|
19
|
+
- run: uv python install
|
|
20
|
+
- run: uv sync --locked
|
|
21
|
+
- run: uv run pytest -q
|
|
22
|
+
- run: uv run loraport demo --out loraport-demo
|
|
23
|
+
peft:
|
|
24
|
+
# Optional: real PEFT merge check (downloads torch, takes a few minutes)
|
|
25
|
+
runs-on: ubuntu-latest
|
|
26
|
+
steps:
|
|
27
|
+
- uses: actions/checkout@v4
|
|
28
|
+
- uses: astral-sh/setup-uv@v10.3.3
|
|
29
|
+
- run: uv python install
|
|
30
|
+
- run: uv sync --locked --extra peft
|
|
31
|
+
- run: uv run pytest -q -m peft tests/test_peft_integration.py
|
|
@@ -0,0 +1,41 @@
|
|
|
1
|
+
# Python
|
|
2
|
+
__pycache__/
|
|
3
|
+
*.py[cod]
|
|
4
|
+
.venv/
|
|
5
|
+
.pytest_cache/
|
|
6
|
+
.ruff_cache/
|
|
7
|
+
.mypy_cache/
|
|
8
|
+
*.egg-info/
|
|
9
|
+
|
|
10
|
+
# Node
|
|
11
|
+
node_modules/
|
|
12
|
+
dist/
|
|
13
|
+
.next/
|
|
14
|
+
|
|
15
|
+
# 실행 산출물·모델·데이터 캐시
|
|
16
|
+
runs/
|
|
17
|
+
outputs/
|
|
18
|
+
.cache/
|
|
19
|
+
*.safetensors
|
|
20
|
+
*.gguf
|
|
21
|
+
*.bin
|
|
22
|
+
|
|
23
|
+
# 환경·비밀
|
|
24
|
+
.env
|
|
25
|
+
.env.*
|
|
26
|
+
!.env.example
|
|
27
|
+
|
|
28
|
+
# OS·에디터
|
|
29
|
+
.DS_Store
|
|
30
|
+
.vscode/
|
|
31
|
+
.idea/
|
|
32
|
+
|
|
33
|
+
# Flutter·Dart
|
|
34
|
+
.dart_tool/
|
|
35
|
+
build/
|
|
36
|
+
.flutter-plugins
|
|
37
|
+
.flutter-plugins-dependencies
|
|
38
|
+
coverage/
|
|
39
|
+
|
|
40
|
+
# loraport demo output
|
|
41
|
+
loraport-demo/
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
3.12
|
|
@@ -0,0 +1,32 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to this project are documented here.
|
|
4
|
+
The format follows [Keep a Changelog](https://keepachangelog.com/en/1.1.0/) and the project uses [Semantic Versioning](https://semver.org/).
|
|
5
|
+
|
|
6
|
+
## [Unreleased]
|
|
7
|
+
|
|
8
|
+
## [0.1.3] - 2026-11-13
|
|
9
|
+
|
|
10
|
+
### Fixed
|
|
11
|
+
- `convert --to peft` no longer suggests an unpublished tool in its next steps; README example output now matches the real output.
|
|
12
|
+
|
|
13
|
+
## [0.1.2] - 2026-11-13
|
|
14
|
+
|
|
15
|
+
### Fixed
|
|
16
|
+
- A path that does not exist now reports `no such directory (check the path)` instead of the misleading `not a directory (pass the adapter folder, not a file)`. Exit code 2 and the exception type are unchanged.
|
|
17
|
+
|
|
18
|
+
## [0.1.1] - 2026-11-13
|
|
19
|
+
|
|
20
|
+
### Fixed
|
|
21
|
+
- `demo` now creates `loraport-demo/dora` so README section 5 reproduces the DoRA refusal; the section 5 command uses `uv run`.
|
|
22
|
+
|
|
23
|
+
## [0.1.0] - 2026-11-11
|
|
24
|
+
|
|
25
|
+
### Added
|
|
26
|
+
- `loraport inspect`, `convert`, `verify` and `demo` commands.
|
|
27
|
+
- Two-way conversion between mlx-lm and PEFT LoRA adapters (key names, transposes, `lora_alpha = scale x rank`, rslora, `num_layers`, `layers_to_transform`).
|
|
28
|
+
- Per-module dW verification with a low-rank Gram computation (no out x in matrix), missing/extra/shape-mismatch/ignored-key reporting and exit codes 0/1/2.
|
|
29
|
+
- BF16/F16/F32 safetensors reading without torch.
|
|
30
|
+
- Explicit refusal of DoRA, MoE, embedding LoRA, `modules_to_save`, `rank_pattern`/`alpha_pattern` and bias adapters.
|
|
31
|
+
- Optional `--base-config` shape and layer-range check.
|
|
32
|
+
- Python API: `load_adapter`, `convert`, `compare`, `save_peft`, `save_mlx`.
|
loraport-0.1.3/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 LeeGyeongPil
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
loraport-0.1.3/PKG-INFO
ADDED
|
@@ -0,0 +1,258 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: loraport
|
|
3
|
+
Version: 0.1.3
|
|
4
|
+
Summary: Convert LoRA adapters between MLX (mlx-lm) and PEFT formats and prove the weight delta (dW) survived the trip.
|
|
5
|
+
Project-URL: Homepage, https://github.com/LeeGyeongPil/loraport
|
|
6
|
+
Project-URL: Issues, https://github.com/LeeGyeongPil/loraport/issues
|
|
7
|
+
Author: LeeGyeongPil
|
|
8
|
+
License: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: adapter,llama.cpp,lora,mlx,mlx-lm,peft,safetensors,vllm
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
18
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
19
|
+
Requires-Python: >=3.11
|
|
20
|
+
Requires-Dist: numpy>=2.0
|
|
21
|
+
Requires-Dist: safetensors>=0.8.0
|
|
22
|
+
Provides-Extra: peft
|
|
23
|
+
Requires-Dist: peft==0.21.2; extra == 'peft'
|
|
24
|
+
Requires-Dist: torch==2.15.0; extra == 'peft'
|
|
25
|
+
Requires-Dist: transformers==5.22.2; extra == 'peft'
|
|
26
|
+
Description-Content-Type: text/markdown
|
|
27
|
+
|
|
28
|
+
# loraport
|
|
29
|
+
|
|
30
|
+
**한국어** | [English](https://github.com/LeeGyeongPil/loraport/blob/v0.1.3/README.en.md)
|
|
31
|
+
|
|
32
|
+
> **English summary** — loraport converts LoRA adapters between the mlx-lm (Apple Silicon) format and the PEFT format, and proves with numbers that the weight delta (dW) is unchanged after the trip. Use it when you trained on a Mac and want to serve the adapter with PEFT, vLLM or llama.cpp (or the other way round). Try it with `uv run loraport demo` (synthetic practice adapters, no downloads).
|
|
33
|
+
|
|
34
|
+
맥에서 `mlx_lm.lora` 로 학습한 LoRA 어댑터를 PEFT·vLLM·llama.cpp 쪽 형식으로 옮기고(반대 방향도), **옮긴 뒤에도 가중치 변화량(ΔW)이 원본과 같은지 숫자로 확인**하는 명령줄 도구입니다. 키 이름 바꾸기·전치·`alpha = scale × r` 계산을 손으로 짜다가, 에러 없이 ΔW=0 으로 적재되는 조용한 실패를 몇 달 뒤에야 발견하는 일을 줄입니다.
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
*`loraport demo`: 왕복 변환 두 번이 PASS, 흔한 실수 4가지가 모두 FAIL 로 잡힌다(연습용 합성 어댑터).*
|
|
38
|
+
|
|
39
|
+
## 이런 분께
|
|
40
|
+
- 맥(Apple Silicon)에서 mlx-lm 으로 소형 모델을 미세조정하고, 서빙은 리눅스 GPU(vLLM)나 llama.cpp 에서 하려는 분
|
|
41
|
+
- 허브의 PEFT 어댑터를 맥에서 mlx-lm 으로 돌려 보려는 분
|
|
42
|
+
- 변환 스크립트가 바뀔 때마다 "결과가 원본과 같은가"를 CI 에서 자동으로 확인하고 싶은 분
|
|
43
|
+
|
|
44
|
+
## 설치
|
|
45
|
+
```bash
|
|
46
|
+
curl -LsSf https://astral.sh/uv/install.sh | sh # uv 가 없다면
|
|
47
|
+
uv tool install git+https://github.com/LeeGyeongPil/loraport
|
|
48
|
+
```
|
|
49
|
+
저장소를 받아서 바로 써 볼 수도 있습니다(아래 모든 명령은 이 방식으로 실행해 확인했습니다).
|
|
50
|
+
```bash
|
|
51
|
+
git clone https://github.com/LeeGyeongPil/loraport && cd loraport
|
|
52
|
+
uv run loraport --version
|
|
53
|
+
```
|
|
54
|
+
```text
|
|
55
|
+
loraport 0.1.3
|
|
56
|
+
```
|
|
57
|
+
- 필요한 것: Python 3.11 이상(`.python-version` 은 3.12). 의존성은 `numpy`·`safetensors` 뿐이라 torch·mlx 없이 맥·리눅스 어디서나 돕니다.
|
|
58
|
+
- 최소 리눅스 환경에서는 `git`, `curl` 정도만 더 있으면 됩니다.
|
|
59
|
+
|
|
60
|
+
## 빠르게 시작하기
|
|
61
|
+
```bash
|
|
62
|
+
uv run loraport demo
|
|
63
|
+
```
|
|
64
|
+
```text
|
|
65
|
+
loraport demo: synthetic practice adapters (mock), random numbers, not a trained model
|
|
66
|
+
1. made a practice MLX adapter in loraport-demo/mlx (rank 4, scale 20, last 2 of 4 blocks)
|
|
67
|
+
2. MLX -> PEFT: PASS 14/14 modules, worst rel err 0.0e+00
|
|
68
|
+
3. PEFT -> MLX: PASS 14/14 modules, worst rel err 0.0e+00
|
|
69
|
+
4. common mistakes, each compared with the original MLX adapter:
|
|
70
|
+
no-prefix caught: FAIL 0/14 modules match (missing 14, extra 0, shape mismatch 0, dW off 0, ignored/dropped tensors 28)
|
|
71
|
+
alpha-not-times-r caught: FAIL 0/14 modules match (missing 0, extra 0, shape mismatch 0, dW off 14, ignored/dropped tensors 0)
|
|
72
|
+
ab-swapped caught: FAIL 10/14 modules match (missing 0, extra 0, shape mismatch 0, dW off 4, ignored/dropped tensors 0)
|
|
73
|
+
mlp-missing caught: FAIL 8/14 modules match (missing 6, extra 0, shape mismatch 0, dW off 0, ignored/dropped tensors 0)
|
|
74
|
+
4/4 traps caught
|
|
75
|
+
```
|
|
76
|
+
**연습용 목(mock) 모드입니다.** `demo` 는 학습된 모델이 아니라 무작위 숫자로 만든 작은 합성 어댑터(hidden 64, 4층)를 `loraport-demo/` 에 만듭니다. 출력을 꾸며 낸 것은 아니고, 변환 코드와 검증 코드는 실제 어댑터에 쓰는 것과 같은 코드가 그대로 돕니다. 네트워크·GPU·API 키가 필요 없고 1초 안에 끝납니다.
|
|
77
|
+
|
|
78
|
+
읽는 법: 2·3번 줄은 "옮겼다가 돌아와도 모든 모듈의 ΔW 가 같다"는 뜻입니다(`worst rel err` 가 가장 큰 상대 오차). 4번은 일부러 틀리게 만든 어댑터 4종이 모두 FAIL 로 잡혔다는 뜻입니다.
|
|
79
|
+
|
|
80
|
+
## 사용법
|
|
81
|
+
| 명령 | 하는 일 | 예 |
|
|
82
|
+
|---|---|---|
|
|
83
|
+
| `inspect <폴더> [--json]` | 형식·rank·배율·층·모듈 목록·텐서 수 | `loraport inspect adapters` |
|
|
84
|
+
| `convert <원본> <대상> --to peft\|mlx` | 다른 형식으로 변환 후 자동 검증, 다음 단계 명령 안내 | `loraport convert adapters out/peft --to peft` |
|
|
85
|
+
| `verify <A> <B> [--rtol 1e-5] [--json]` | 두 어댑터(형식 무관)의 ΔW 를 모듈별로 비교 | `loraport verify adapters out/peft` |
|
|
86
|
+
| `demo [--out 폴더]` | 연습용 합성 어댑터로 전체 흐름 시연 | `loraport demo` |
|
|
87
|
+
|
|
88
|
+
`convert` 옵션: `--base-config`(기본 모델의 `config.json` 또는 그 폴더 — 모듈 크기·층 범위 대조), `--base-model-id`(PEFT 설정의 `base_model_name_or_path` 에 쓸 허브 이름), `--rtol`(허용 상대 오차, 기본 1e-5), `--no-verify`, `--force`(대상 폴더의 기존 어댑터 파일 덮어쓰기).
|
|
89
|
+
|
|
90
|
+
종료 코드: **0** 통과 / **1** 불일치(검증 실패) / **2** 입력 오류·지원 안 하는 형태·이미 있는 대상.
|
|
91
|
+
|
|
92
|
+
### 1) 어댑터 살펴보기
|
|
93
|
+
```bash
|
|
94
|
+
uv run loraport inspect loraport-demo/mlx
|
|
95
|
+
```
|
|
96
|
+
```text
|
|
97
|
+
loraport-demo/mlx: MLX adapter
|
|
98
|
+
scale 20 x rank 4 = PEFT lora_alpha 80
|
|
99
|
+
layers: 2..3 (2 blocks)
|
|
100
|
+
modules: 14 (mlp.down_proj x2, mlp.gate_proj x2, mlp.up_proj x2, self_attn.k_proj x2, self_attn.o_proj x2, self_attn.q_proj x2, self_attn.v_proj x2)
|
|
101
|
+
tensors: 28 (F32), 35552 bytes
|
|
102
|
+
```
|
|
103
|
+
|
|
104
|
+
*MLX 의 scale 20 이 PEFT 의 `lora_alpha` 80(= 20 × rank 4)으로 환산되는 모습.*
|
|
105
|
+
|
|
106
|
+
`--json` 을 붙이면 같은 정보를 `format`·`rank`·`scale`·`lora_alpha`·`layers`·`modules`·`tensor_count` 등의 키로 가진 JSON 으로 냅니다.
|
|
107
|
+
|
|
108
|
+
### 2) PEFT 형식으로 변환하기
|
|
109
|
+
```bash
|
|
110
|
+
uv run loraport convert loraport-demo/mlx loraport-demo/out/peft --to peft \
|
|
111
|
+
--base-model-id Qwen/Qwen2.5-1.5B-Instruct --base-config loraport-demo/base/config.json
|
|
112
|
+
```
|
|
113
|
+
```text
|
|
114
|
+
wrote peft adapter to loraport-demo/out/peft
|
|
115
|
+
PASS 14/14 modules, worst rel err 0.0e+00 [source vs converted, rtol 1e-05]
|
|
116
|
+
next steps:
|
|
117
|
+
vLLM: vllm serve Qwen/Qwen2.5-1.5B-Instruct --enable-lora --lora-modules my-adapter=loraport-demo/out/peft
|
|
118
|
+
llama.cpp: python convert_lora_to_gguf.py --base <BASE_MODEL_DIR> --outfile adapter.gguf loraport-demo/out/peft
|
|
119
|
+
```
|
|
120
|
+
|
|
121
|
+
*변환이 끝나면 자동 검증 결과와 vLLM·llama.cpp 다음 명령이 나온다.*
|
|
122
|
+
|
|
123
|
+
- 변환 결과는 `adapter_model.safetensors`(메타데이터 `format=pt`)와 `adapter_config.json` 입니다. 설정에는 필요한 필드만 쓰고 학습 인자(데이터 경로 등)는 복사하지 않습니다.
|
|
124
|
+
- 반대 방향은 `--to mlx`. `--base-config` 가 있으면 `num_layers` 를 `전체 층 수 − 가장 앞 층 번호` 로 계산하고, 없으면 `-1`(모든 블록)로 씁니다.
|
|
125
|
+
- `--base-model-id` 를 주지 않으면 `base_model_name_or_path` 는 `null` 입니다.
|
|
126
|
+
- `llama.cpp` 줄의 `<BASE_MODEL_DIR>` 는 직접 채우는 자리표시입니다. llama.cpp·vLLM 명령 자체는 이 도구가 실행하지 않고 안내만 합니다.
|
|
127
|
+
|
|
128
|
+
### 3) 두 어댑터 비교하기(CI)
|
|
129
|
+
```bash
|
|
130
|
+
uv run loraport verify loraport-demo/mlx loraport-demo/out/peft; echo "exit=$?"
|
|
131
|
+
```
|
|
132
|
+
```text
|
|
133
|
+
PASS 14/14 modules, worst rel err 0.0e+00 [loraport-demo/mlx vs loraport-demo/out/peft, rtol 1e-05]
|
|
134
|
+
exit=0
|
|
135
|
+
```
|
|
136
|
+
`--json` 은 `ok`·`missing`·`extra`·`shape_mismatch`·`key_issues`·`worst_rel_err`·`per_module` 을 담은 보고서를 냅니다. CI 에서는 종료 코드 1 이면 빌드를 막으면 됩니다.
|
|
137
|
+
|
|
138
|
+
### 4) 조용한 실패를 잡는 모습
|
|
139
|
+
`demo` 가 만든 `traps/no-prefix` 는 PEFT 키에서 `base_model.model.` 접두사가 빠진 어댑터입니다. 실제 PEFT 는 이 경우 경고만 내고 ΔW=0 으로 적재합니다(에러 없음).
|
|
140
|
+
```bash
|
|
141
|
+
uv run loraport verify loraport-demo/mlx loraport-demo/traps/no-prefix; echo "exit=$?"
|
|
142
|
+
```
|
|
143
|
+
```text
|
|
144
|
+
FAIL 0/14 modules match (missing 14, extra 0, shape mismatch 0, dW off 0, ignored/dropped tensors 28) [loraport-demo/mlx vs loraport-demo/traps/no-prefix, rtol 1e-05]
|
|
145
|
+
modules in loraport-demo/mlx but not in loraport-demo/traps/no-prefix (14):
|
|
146
|
+
- model.layers.2.mlp.down_proj
|
|
147
|
+
...
|
|
148
|
+
hint: loraport-demo/traps/no-prefix would run these layers without LoRA (dW = 0); re-run the conversion
|
|
149
|
+
ignored or dropped tensors (28):
|
|
150
|
+
- b: model.layers.2.mlp.down_proj.lora_A.weight: PEFT ignores it because the key lacks the 'base_model.model.' prefix (the adapter would load with dW=0)
|
|
151
|
+
...
|
|
152
|
+
exit=1
|
|
153
|
+
```
|
|
154
|
+
(중간 줄은 `...` 로 줄였습니다. 전체 목록은 `--json`.)
|
|
155
|
+
|
|
156
|
+
|
|
157
|
+
*접두사 누락 어댑터는 "ΔW=0 으로 적재될 것"이라는 이유와 함께 FAIL(종료 코드 1).*
|
|
158
|
+
|
|
159
|
+
### 5) 지원하지 않는 형태는 거부
|
|
160
|
+
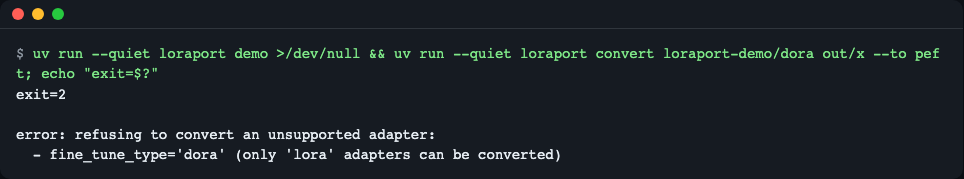
DoRA 어댑터(`fine_tune_type: dora`)는 조용히 망가뜨리지 않고 이유와 함께 거부합니다(아무것도 쓰지 않음). `demo` 가 만든 `loraport-demo/dora` 로 재현합니다.
|
|
161
|
+
```bash
|
|
162
|
+
uv run loraport convert loraport-demo/dora out/x --to peft; echo "exit=$?"
|
|
163
|
+
```
|
|
164
|
+
```text
|
|
165
|
+
error: refusing to convert an unsupported adapter:
|
|
166
|
+
- fine_tune_type='dora' (only 'lora' adapters can be converted)
|
|
167
|
+
exit=2
|
|
168
|
+
```
|
|
169
|
+
|
|
170
|
+
*지원 안 하는 형태는 종료 코드 2 와 이유.*
|
|
171
|
+
|
|
172
|
+
### Python 에서 쓰기
|
|
173
|
+
`adapters` 는 `mlx_lm.lora` 가 학습 결과를 저장하는 기본 폴더입니다(데모로 따라 한다면 `loraport-demo/mlx`). 라이브러리로 쓰려면 프로젝트에 `uv add git+https://github.com/LeeGyeongPil/loraport`(또는 `pip install git+https://github.com/LeeGyeongPil/loraport`)로 설치합니다. `uv tool install` 은 CLI 만 설치합니다.
|
|
174
|
+
```python
|
|
175
|
+
from loraport import load_adapter, convert, compare
|
|
176
|
+
|
|
177
|
+
result = convert("adapters", "out/peft", "peft", base_model_id="Qwen/Qwen2.5-1.5B-Instruct")
|
|
178
|
+
print(result.report.ok, result.report.worst_rel_err) # True 0.0
|
|
179
|
+
|
|
180
|
+
report = compare(load_adapter("adapters"), load_adapter("out/peft"))
|
|
181
|
+
print(report.ok, len(report.per_module)) # True 14 (demo 어댑터 기준)
|
|
182
|
+
```
|
|
183
|
+
공개 API: `load_adapter`, `convert`, `compare`, `save_peft`, `save_mlx`. 예외는 `LoraportError`(하위 `AdapterFormatError`, `UnsupportedAdapterError`).
|
|
184
|
+
|
|
185
|
+
## 설정
|
|
186
|
+
설정 파일·환경변수·API 키는 없습니다. 모든 동작은 명령 옵션으로 정합니다. `--rtol` 기본값은 1e-5 이며, 입력은 F32·F16·BF16 safetensors 를 읽고 출력은 항상 float32 입니다.
|
|
187
|
+
|
|
188
|
+
## 동작 원리
|
|
189
|
+
같은 ΔW 를 두 형식이 다르게 적습니다.
|
|
190
|
+
|
|
191
|
+
| | mlx-lm | PEFT |
|
|
192
|
+
|---|---|---|
|
|
193
|
+
| 가중치 파일 | `adapters.safetensors` | `adapter_model.safetensors` |
|
|
194
|
+
| 키 | `model.layers.{i}.{mod}.lora_a` / `.lora_b` | `base_model.model.model.layers.{i}.{mod}.lora_A.weight` / `.lora_B.weight` |
|
|
195
|
+
| A 모양 | `(in, r)` | `(r, in)` |
|
|
196
|
+
| B 모양 | `(r, out)` | `(out, r)` |
|
|
197
|
+
| 배율 | `scale` | `lora_alpha / r` (rslora 면 `lora_alpha / √r`) |
|
|
198
|
+
| 층 범위 | `num_layers`(뒤에서부터 센 개수, `-1` 은 전부) | `layers_to_transform` 목록 |
|
|
199
|
+
|
|
200
|
+
```mermaid
|
|
201
|
+
flowchart LR
|
|
202
|
+
A["MLX 또는 PEFT 폴더"] --> B["형식 판별·읽기<br/>A(r×in), B(out×r), scale 로 통일"]
|
|
203
|
+
B --> C["변환<br/>키 이름·전치·alpha=scale×r"]
|
|
204
|
+
C --> D["대상 형식으로 쓰기"]
|
|
205
|
+
B --> E["ΔW 비교<br/>저랭크 그람 계산"]
|
|
206
|
+
D --> E
|
|
207
|
+
E --> F["PASS/FAIL + 종료 코드"]
|
|
208
|
+
```
|
|
209
|
+
1. 어느 형식이든 내부에서는 PEFT 배치(`A (r,in)`, `B (out,r)`)와 모듈 이름 `model.layers.{i}.{mod}` 로 통일해 읽습니다.
|
|
210
|
+
2. 변환은 키 이름을 바꾸고, A·B 를 전치하고, `lora_alpha = scale × r`(역방향은 `scale = alpha / r`, rslora 는 `alpha / √r`)로 배율을 환산합니다. 읽기는 관대하고 변환은 엄격해서, A/B 랭크 불일치·지원 안 하는 항목은 쓰기 전에 거부합니다.
|
|
211
|
+
3. 검증은 모듈마다 `‖ΔW₁ − ΔW₂‖ / ‖ΔW₁‖`(프로베니우스 노름)를 잽니다. out×in 행렬을 만들지 않고 `‖UV‖² = trace((UᵀU)(VVᵀ))` 로 float64 로 계산하므로 큰 모듈도 메모리가 작게 듭니다. 제곱을 거치므로 상대 오차 하한은 약 1e-8 입니다.
|
|
212
|
+
4. 모듈이 빠졌는지·더해졌는지·모양이 다른지, 그리고 런타임이 무시할 키(접두사 누락 등)가 없는지도 함께 보고합니다.
|
|
213
|
+
|
|
214
|
+
### 흔한 함정 4가지(demo 가 재현)
|
|
215
|
+
| 이름 | 무슨 실수인가 | 잡히는 방식 |
|
|
216
|
+
|---|---|---|
|
|
217
|
+
| `no-prefix` | PEFT 키에서 `base_model.model.` 접두사 누락 | 모듈 14개 missing + 무시되는 키 28개 |
|
|
218
|
+
| `alpha-not-times-r` | `lora_alpha = scale`(× r 누락) | 14개 모듈 ΔW 불일치 |
|
|
219
|
+
| `ab-swapped` | 정사각 모듈(q/o)에서 A·B 를 바꿔 넣음 | 모양은 통과, ΔW 만 4개 모듈 불일치 |
|
|
220
|
+
| `mlp-missing` | MLP 텐서 누락 | 모듈 6개 missing |
|
|
221
|
+
|
|
222
|
+
자세한 형식 메모와 출처: [docs/format-notes.md](https://github.com/LeeGyeongPil/loraport/blob/v0.1.3/docs/format-notes.md).
|
|
223
|
+
|
|
224
|
+
## 언제 쓰나
|
|
225
|
+
- 이럴 때: mlx-lm 어댑터를 병합하지 않고 그대로 PEFT 계열 도구에 넘기고 싶을 때, 변환 결과가 원본과 같은지 숫자로 남기고 싶을 때.
|
|
226
|
+
- 이럴 땐 다른 도구: 기본 모델에 병합한 전체 모델이 필요하면 [mlx-lm `fuse`](https://github.com/ml-explore/mlx-lm/blob/main/mlx_lm/LORA.md), PEFT 어댑터를 GGUF LoRA 로 바꾸려면 [llama.cpp `convert_lora_to_gguf.py`](https://github.com/ggml-org/llama.cpp).
|
|
227
|
+
|
|
228
|
+
## 지원 안 하는 것과 한계
|
|
229
|
+
- 0.1.3 에서 거부하는 형태: DoRA, MoE(3차원 텐서), embedding LoRA, `modules_to_save`, `rank_pattern`/`alpha_pattern`, bias 어댑터. GGUF 직접 쓰기, 기본 모델 병합, 허브 다운로드(로컬 폴더만)도 범위 밖입니다.
|
|
230
|
+
- **ΔW 동일성만 증명합니다.** 양자화한 기본 모델에 붙이면 출력은 조금 달라질 수 있습니다(출력 동일성은 보장하지 않음).
|
|
231
|
+
- **mlx-lm 쪽은 실제 로드를 확인하지 못했습니다.** 형식은 mlx-lm 0.32.2 설치본 소스와 허브의 실제 mlx-lm 어댑터 헤더로 확인했고, 개발 환경(Metal 장치 없음)에서 `mlx_lm` 의 `load_adapters` 를 직접 돌려 보지는 못했습니다. `--to mlx` 의 `num_layers=-1`·파일에 없는 층이 ΔW=0 으로 남는다는 동작도 소스를 읽은 근거입니다. 맥의 일반 터미널에서는 `uv run --with mlx-lm pytest -m mlx` 로 왕복 테스트를 돌려 볼 수 있는데, 이 명령은 아직 실행해 보지 않았습니다.
|
|
232
|
+
- 어댑터 전체를 float32 로 메모리에 올립니다(스트리밍 아님). 수백 MB 급까지는 가능합니다.
|
|
233
|
+
- 확인한 버전(2026-11-11): numpy 2.5.4, safetensors 0.8.0, 선택 extra `peft` 0.21.2·torch 2.15.0·transformers 5.22.2, mlx-lm 0.32.2(소스 판독).
|
|
234
|
+
|
|
235
|
+
## 자주 겪는 문제
|
|
236
|
+
| 증상 | 원인 | 해결 |
|
|
237
|
+
|---|---|---|
|
|
238
|
+
| `error: ... already contains adapter files; pass --force` (종료 코드 2) | 대상 폴더에 이미 어댑터 파일이 있음 | 다른 폴더를 쓰거나 `--force` |
|
|
239
|
+
| `error: ...: no such directory` (종료 코드 2) | 경로 오타 | 어댑터 폴더 경로를 확인 |
|
|
240
|
+
| `refusing to convert an unsupported adapter` (종료 코드 2) | DoRA·MoE 등 지원 안 하는 형태 | 이유 목록을 확인하고 LoRA 어댑터로 다시 학습·저장 |
|
|
241
|
+
| `verify` 가 `shape mismatch` 로 FAIL | A/B 를 전치하지 않은 어댑터 | `convert` 로 다시 변환 |
|
|
242
|
+
| `verify` 가 `ignored or dropped tensors` 로 FAIL | PEFT 키에 `base_model.model.` 접두사가 없음 | `convert` 로 다시 변환 |
|
|
243
|
+
| `dW differs` 로 FAIL | 배율(`alpha = scale × r`) 또는 A/B 순서 실수 | hint 줄을 따라 변환을 다시 하고, `--rtol` 을 풀어 덮지 않기 |
|
|
244
|
+
| llama.cpp 변환 후 효과가 약함 | `convert_lora_to_gguf.py` 는 `use_rslora` 를 읽지 않음 | loraport 는 항상 `use_rslora=false` + `lora_alpha = scale × r` 로 쓰므로 loraport 출력은 이 문제를 피함 |
|
|
245
|
+
|
|
246
|
+
## 개발·기여
|
|
247
|
+
```bash
|
|
248
|
+
uv run pytest -q
|
|
249
|
+
```
|
|
250
|
+
```text
|
|
251
|
+
72 passed, 2 skipped in 1.70s
|
|
252
|
+
```
|
|
253
|
+
건너뛴 2개는 선택 테스트(실제 PEFT 통합, 맥 전용 mlx 통합)입니다. PEFT 통합은 `uv run --extra peft pytest -q -m peft tests/test_peft_integration.py` 로 돌립니다(torch 설치 때문에 첫 실행은 1분 넘게 걸림. 개발 환경에서 `1 passed`).
|
|
254
|
+
|
|
255
|
+
버그·제안은 이슈로 남겨 주세요. 변경 기록은 [CHANGELOG.md](https://github.com/LeeGyeongPil/loraport/blob/v0.1.3/CHANGELOG.md).
|
|
256
|
+
|
|
257
|
+
## 라이선스
|
|
258
|
+
MIT. 레포에 외부 모델·데이터는 들어 있지 않고 테스트 어댑터는 모두 실행 중에 생성합니다.
|
|
@@ -0,0 +1,229 @@
|
|
|
1
|
+
# loraport
|
|
2
|
+
|
|
3
|
+
[한국어](README.md) | **English**
|
|
4
|
+
|
|
5
|
+
loraport is a command-line tool that converts LoRA adapters trained on a Mac with `mlx_lm.lora` into the PEFT format (so PEFT, vLLM and llama.cpp can use them) and back, and **proves with numbers that the weight delta (dW) is the same after the trip**. It saves you from hand-writing key renames, transposes and the `alpha = scale x r` calculation, and from finding months later that an adapter loaded silently with dW = 0.
|
|
6
|
+
|
|
7
|
+

|
|
8
|
+
*`loraport demo`: two round-trip conversions PASS, and four common mistakes are all caught as FAIL (synthetic practice adapters).*
|
|
9
|
+
|
|
10
|
+
## Who it is for
|
|
11
|
+
- You fine-tune small models with mlx-lm on an Apple Silicon Mac and want to serve on a Linux GPU (vLLM) or with llama.cpp
|
|
12
|
+
- You want to try a PEFT adapter from the hub on a Mac with mlx-lm
|
|
13
|
+
- You want CI to check automatically that a conversion script still produces the same adapter
|
|
14
|
+
|
|
15
|
+
## Install
|
|
16
|
+
```bash
|
|
17
|
+
curl -LsSf https://astral.sh/uv/install.sh | sh # if you do not have uv
|
|
18
|
+
uv tool install git+https://github.com/LeeGyeongPil/loraport
|
|
19
|
+
```
|
|
20
|
+
Or clone and run directly (every command below was run this way).
|
|
21
|
+
```bash
|
|
22
|
+
git clone https://github.com/LeeGyeongPil/loraport && cd loraport
|
|
23
|
+
uv run loraport --version
|
|
24
|
+
```
|
|
25
|
+
```text
|
|
26
|
+
loraport 0.1.3
|
|
27
|
+
```
|
|
28
|
+
- Requires Python 3.11+ (`.python-version` pins 3.12). The only dependencies are `numpy` and `safetensors`, so it runs on macOS and Linux without torch or mlx.
|
|
29
|
+
- On a minimal Linux image you only need `git` and `curl` in addition.
|
|
30
|
+
|
|
31
|
+
## Quick start
|
|
32
|
+
```bash
|
|
33
|
+
uv run loraport demo
|
|
34
|
+
```
|
|
35
|
+
```text
|
|
36
|
+
loraport demo: synthetic practice adapters (mock), random numbers, not a trained model
|
|
37
|
+
1. made a practice MLX adapter in loraport-demo/mlx (rank 4, scale 20, last 2 of 4 blocks)
|
|
38
|
+
2. MLX -> PEFT: PASS 14/14 modules, worst rel err 0.0e+00
|
|
39
|
+
3. PEFT -> MLX: PASS 14/14 modules, worst rel err 0.0e+00
|
|
40
|
+
4. common mistakes, each compared with the original MLX adapter:
|
|
41
|
+
no-prefix caught: FAIL 0/14 modules match (missing 14, extra 0, shape mismatch 0, dW off 0, ignored/dropped tensors 28)
|
|
42
|
+
alpha-not-times-r caught: FAIL 0/14 modules match (missing 0, extra 0, shape mismatch 0, dW off 14, ignored/dropped tensors 0)
|
|
43
|
+
ab-swapped caught: FAIL 10/14 modules match (missing 0, extra 0, shape mismatch 0, dW off 4, ignored/dropped tensors 0)
|
|
44
|
+
mlp-missing caught: FAIL 8/14 modules match (missing 6, extra 0, shape mismatch 0, dW off 0, ignored/dropped tensors 0)
|
|
45
|
+
4/4 traps caught
|
|
46
|
+
```
|
|
47
|
+
**This is a practice (mock) mode.** `demo` builds a small synthetic adapter from random numbers (hidden size 64, 4 layers) in `loraport-demo/`, not a trained model. The output is not faked: the same conversion and verification code that runs on real adapters runs here. No network, GPU or API key is needed, and it finishes in about a second.
|
|
48
|
+
|
|
49
|
+
How to read it: lines 2 and 3 mean the dW of every module is unchanged after converting there and back (`worst rel err` is the largest relative error). Line 4 means all four deliberately broken adapters were caught as FAIL.
|
|
50
|
+
|
|
51
|
+
## Usage
|
|
52
|
+
| Command | What it does | Example |
|
|
53
|
+
|---|---|---|
|
|
54
|
+
| `inspect <dir> [--json]` | format, rank, scale, layers, module list, tensor count | `loraport inspect adapters` |
|
|
55
|
+
| `convert <src> <dst> --to peft\|mlx` | convert to the other format, verify automatically, print next steps | `loraport convert adapters out/peft --to peft` |
|
|
56
|
+
| `verify <A> <B> [--rtol 1e-5] [--json]` | compare dW of two adapters (any format) per module | `loraport verify adapters out/peft` |
|
|
57
|
+
| `demo [--out dir]` | run the whole flow on synthetic practice adapters | `loraport demo` |
|
|
58
|
+
|
|
59
|
+
`convert` options: `--base-config` (the base model's `config.json` or its folder; checks module sizes and layer range), `--base-model-id` (hub name written to `base_model_name_or_path`), `--rtol` (allowed relative error, default 1e-5), `--no-verify`, `--force` (overwrite adapter files already in the destination).
|
|
60
|
+
|
|
61
|
+
Exit codes: **0** pass / **1** mismatch (verification failed) / **2** input error, unsupported adapter type, or destination already exists.
|
|
62
|
+
|
|
63
|
+
### 1) Inspect an adapter
|
|
64
|
+
```bash
|
|
65
|
+
uv run loraport inspect loraport-demo/mlx
|
|
66
|
+
```
|
|
67
|
+
```text
|
|
68
|
+
loraport-demo/mlx: MLX adapter
|
|
69
|
+
scale 20 x rank 4 = PEFT lora_alpha 80
|
|
70
|
+
layers: 2..3 (2 blocks)
|
|
71
|
+
modules: 14 (mlp.down_proj x2, mlp.gate_proj x2, mlp.up_proj x2, self_attn.k_proj x2, self_attn.o_proj x2, self_attn.q_proj x2, self_attn.v_proj x2)
|
|
72
|
+
tensors: 28 (F32), 35552 bytes
|
|
73
|
+
```
|
|
74
|
+

|
|
75
|
+
*MLX scale 20 maps to PEFT `lora_alpha` 80 (= 20 x rank 4).*
|
|
76
|
+
|
|
77
|
+
With `--json` the same information comes out as JSON with keys such as `format`, `rank`, `scale`, `lora_alpha`, `layers`, `modules` and `tensor_count`.
|
|
78
|
+
|
|
79
|
+
### 2) Convert to PEFT
|
|
80
|
+
```bash
|
|
81
|
+
uv run loraport convert loraport-demo/mlx loraport-demo/out/peft --to peft \
|
|
82
|
+
--base-model-id Qwen/Qwen2.5-1.5B-Instruct --base-config loraport-demo/base/config.json
|
|
83
|
+
```
|
|
84
|
+
```text
|
|
85
|
+
wrote peft adapter to loraport-demo/out/peft
|
|
86
|
+
PASS 14/14 modules, worst rel err 0.0e+00 [source vs converted, rtol 1e-05]
|
|
87
|
+
next steps:
|
|
88
|
+
vLLM: vllm serve Qwen/Qwen2.5-1.5B-Instruct --enable-lora --lora-modules my-adapter=loraport-demo/out/peft
|
|
89
|
+
llama.cpp: python convert_lora_to_gguf.py --base <BASE_MODEL_DIR> --outfile adapter.gguf loraport-demo/out/peft
|
|
90
|
+
```
|
|
91
|
+

|
|
92
|
+
*After converting, the automatic verification result and the next vLLM / llama.cpp commands are shown.*
|
|
93
|
+
|
|
94
|
+
- The result is `adapter_model.safetensors` (metadata `format=pt`) plus `adapter_config.json`. Only the needed fields are written to the config; training arguments such as data paths are not copied.
|
|
95
|
+
- The other direction is `--to mlx`. With `--base-config`, `num_layers` is computed as `total layers - first adapted layer index`; without it, `-1` (all blocks) is written.
|
|
96
|
+
- Without `--base-model-id`, `base_model_name_or_path` is `null`.
|
|
97
|
+
- `<BASE_MODEL_DIR>` in the llama.cpp line is a placeholder you fill in. The tool only prints the vLLM and llama.cpp commands; it does not run them.
|
|
98
|
+
|
|
99
|
+
### 3) Compare two adapters (CI)
|
|
100
|
+
```bash
|
|
101
|
+
uv run loraport verify loraport-demo/mlx loraport-demo/out/peft; echo "exit=$?"
|
|
102
|
+
```
|
|
103
|
+
```text
|
|
104
|
+
PASS 14/14 modules, worst rel err 0.0e+00 [loraport-demo/mlx vs loraport-demo/out/peft, rtol 1e-05]
|
|
105
|
+
exit=0
|
|
106
|
+
```
|
|
107
|
+
`--json` prints a report with `ok`, `missing`, `extra`, `shape_mismatch`, `key_issues`, `worst_rel_err` and `per_module`. In CI, block the build on exit code 1.
|
|
108
|
+
|
|
109
|
+
### 4) Catching a silent failure
|
|
110
|
+
`traps/no-prefix`, created by `demo`, is an adapter whose PEFT keys lack the `base_model.model.` prefix. Real PEFT only warns and loads it with dW = 0 (no error).
|
|
111
|
+
```bash
|
|
112
|
+
uv run loraport verify loraport-demo/mlx loraport-demo/traps/no-prefix; echo "exit=$?"
|
|
113
|
+
```
|
|
114
|
+
```text
|
|
115
|
+
FAIL 0/14 modules match (missing 14, extra 0, shape mismatch 0, dW off 0, ignored/dropped tensors 28) [loraport-demo/mlx vs loraport-demo/traps/no-prefix, rtol 1e-05]
|
|
116
|
+
modules in loraport-demo/mlx but not in loraport-demo/traps/no-prefix (14):
|
|
117
|
+
- model.layers.2.mlp.down_proj
|
|
118
|
+
...
|
|
119
|
+
hint: loraport-demo/traps/no-prefix would run these layers without LoRA (dW = 0); re-run the conversion
|
|
120
|
+
ignored or dropped tensors (28):
|
|
121
|
+
- b: model.layers.2.mlp.down_proj.lora_A.weight: PEFT ignores it because the key lacks the 'base_model.model.' prefix (the adapter would load with dW=0)
|
|
122
|
+
...
|
|
123
|
+
exit=1
|
|
124
|
+
```
|
|
125
|
+
(Middle lines are shortened to `...`; use `--json` for the full lists.)
|
|
126
|
+
|
|
127
|
+

|
|
128
|
+
*The adapter with missing prefixes fails (exit code 1) with the reason "would load with dW = 0".*
|
|
129
|
+
|
|
130
|
+
### 5) Unsupported adapter types are refused
|
|
131
|
+
A DoRA adapter (`fine_tune_type: dora`) is refused with a reason instead of being converted wrongly; nothing is written. Reproduce it with the `loraport-demo/dora` folder that `demo` creates.
|
|
132
|
+
```bash
|
|
133
|
+
uv run loraport convert loraport-demo/dora out/x --to peft; echo "exit=$?"
|
|
134
|
+
```
|
|
135
|
+
```text
|
|
136
|
+
error: refusing to convert an unsupported adapter:
|
|
137
|
+
- fine_tune_type='dora' (only 'lora' adapters can be converted)
|
|
138
|
+
exit=2
|
|
139
|
+
```
|
|
140
|
+

|
|
141
|
+
*Unsupported types give exit code 2 and a reason.*
|
|
142
|
+
|
|
143
|
+
### Using it from Python
|
|
144
|
+
`adapters` is the default output folder of `mlx_lm.lora` (if you follow the demo, use `loraport-demo/mlx`). To import it as a library, run `uv add git+https://github.com/LeeGyeongPil/loraport` (or `pip install git+https://github.com/LeeGyeongPil/loraport`) in your project; `uv tool install` installs the CLI only.
|
|
145
|
+
```python
|
|
146
|
+
from loraport import load_adapter, convert, compare
|
|
147
|
+
|
|
148
|
+
result = convert("adapters", "out/peft", "peft", base_model_id="Qwen/Qwen2.5-1.5B-Instruct")
|
|
149
|
+
print(result.report.ok, result.report.worst_rel_err) # True 0.0
|
|
150
|
+
|
|
151
|
+
report = compare(load_adapter("adapters"), load_adapter("out/peft"))
|
|
152
|
+
print(report.ok, len(report.per_module)) # True 14 (for the demo adapter)
|
|
153
|
+
```
|
|
154
|
+
Public API: `load_adapter`, `convert`, `compare`, `save_peft`, `save_mlx`. Exceptions: `LoraportError` (subclasses `AdapterFormatError`, `UnsupportedAdapterError`).
|
|
155
|
+
|
|
156
|
+
## Configuration
|
|
157
|
+
There are no config files, environment variables or API keys. Everything is set with command options. `--rtol` defaults to 1e-5. Input may be F32, F16 or BF16 safetensors; output is always float32.
|
|
158
|
+
|
|
159
|
+
## How it works
|
|
160
|
+
The two formats write the same dW differently.
|
|
161
|
+
|
|
162
|
+
| | mlx-lm | PEFT |
|
|
163
|
+
|---|---|---|
|
|
164
|
+
| weights file | `adapters.safetensors` | `adapter_model.safetensors` |
|
|
165
|
+
| key | `model.layers.{i}.{mod}.lora_a` / `.lora_b` | `base_model.model.model.layers.{i}.{mod}.lora_A.weight` / `.lora_B.weight` |
|
|
166
|
+
| A shape | `(in, r)` | `(r, in)` |
|
|
167
|
+
| B shape | `(r, out)` | `(out, r)` |
|
|
168
|
+
| scale | `scale` | `lora_alpha / r` (`lora_alpha / sqrt(r)` with rslora) |
|
|
169
|
+
| layer range | `num_layers` (count from the last block, `-1` = all) | `layers_to_transform` list |
|
|
170
|
+
|
|
171
|
+
```mermaid
|
|
172
|
+
flowchart LR
|
|
173
|
+
A["MLX or PEFT folder"] --> B["Detect and read<br/>unify as A(r x in), B(out x r), scale"]
|
|
174
|
+
B --> C["Convert<br/>key names, transpose, alpha = scale x r"]
|
|
175
|
+
C --> D["Write target format"]
|
|
176
|
+
B --> E["Compare dW<br/>low-rank Gram computation"]
|
|
177
|
+
D --> E
|
|
178
|
+
E --> F["PASS/FAIL + exit code"]
|
|
179
|
+
```
|
|
180
|
+
1. Whatever the format, adapters are read into the PEFT layout (`A (r,in)`, `B (out,r)`) with module names `model.layers.{i}.{mod}`.
|
|
181
|
+
2. Conversion renames keys, transposes A and B, and converts the scale with `lora_alpha = scale x r` (reverse: `scale = alpha / r`, rslora: `alpha / sqrt(r)`). Reading is lenient and converting is strict: mismatched A/B ranks and unsupported items are refused before anything is written.
|
|
182
|
+
3. Verification measures `||dW1 - dW2|| / ||dW1||` (Frobenius norm) per module. It never builds the out x in matrix: it uses `||UV||^2 = trace((U^T U)(V V^T))` in float64, so even large modules need little memory. Because of the squaring, the relative error floor is about 1e-8.
|
|
183
|
+
4. It also reports modules that are missing, extra or differently shaped, and keys a runtime would ignore (such as a missing prefix).
|
|
184
|
+
|
|
185
|
+
### Four common pitfalls (reproduced by demo)
|
|
186
|
+
| Name | The mistake | How it is caught |
|
|
187
|
+
|---|---|---|
|
|
188
|
+
| `no-prefix` | PEFT keys lack the `base_model.model.` prefix | 14 modules missing + 28 ignored keys |
|
|
189
|
+
| `alpha-not-times-r` | `lora_alpha = scale` (x r forgotten) | dW mismatch in 14 modules |
|
|
190
|
+
| `ab-swapped` | A and B swapped on square modules (q/o) | shapes pass, dW mismatch in 4 modules |
|
|
191
|
+
| `mlp-missing` | MLP tensors dropped | 6 modules missing |
|
|
192
|
+
|
|
193
|
+
Format notes and sources: [docs/format-notes.md](docs/format-notes.md).
|
|
194
|
+
|
|
195
|
+
## When to use it
|
|
196
|
+
- Good fit: you want to hand an mlx-lm adapter to PEFT-based tools without merging it, and keep a numeric record that the conversion matches the original.
|
|
197
|
+
- Other tools: for a merged full model use [mlx-lm `fuse`](https://github.com/ml-explore/mlx-lm/blob/main/mlx_lm/LORA.md); to turn a PEFT adapter into a GGUF LoRA use [llama.cpp `convert_lora_to_gguf.py`](https://github.com/ggml-org/llama.cpp).
|
|
198
|
+
|
|
199
|
+
## Unsupported and limits
|
|
200
|
+
- Refused in 0.1.3: DoRA, MoE (3-D tensors), embedding LoRA, `modules_to_save`, `rank_pattern`/`alpha_pattern`, bias adapters. Writing GGUF directly, merging into the base model and downloading from the hub (local folders only) are out of scope.
|
|
201
|
+
- **Only dW equality is proven.** Attached to a quantized base model, outputs may differ slightly (output equality is not guaranteed).
|
|
202
|
+
- **Loading in mlx-lm itself was not verified.** The format was checked against the installed mlx-lm 0.32.2 source and the header of a real mlx-lm adapter on the hub, but `load_adapters` from `mlx_lm` could not be run in the development environment (no Metal device). The behavior of `num_layers=-1` and of layers missing from the file staying at dW = 0 for `--to mlx` also rests on reading the source. On a normal Mac terminal you can run the round-trip test with `uv run --with mlx-lm pytest -m mlx`; that command has not been run yet.
|
|
203
|
+
- The whole adapter is loaded into memory as float32 (no streaming). Adapters up to a few hundred MB are fine.
|
|
204
|
+
- Versions checked (2026-11-11): numpy 2.5.4, safetensors 0.8.0, optional extra `peft` 0.21.2 / torch 2.15.0 / transformers 5.22.2, mlx-lm 0.32.2 (read from source).
|
|
205
|
+
|
|
206
|
+
## Troubleshooting
|
|
207
|
+
| Symptom | Cause | Fix |
|
|
208
|
+
|---|---|---|
|
|
209
|
+
| `error: ... already contains adapter files; pass --force` (exit 2) | the destination already has adapter files | use another folder or `--force` |
|
|
210
|
+
| `error: ...: no such directory` (exit 2) | a typo in the path | check the adapter folder path |
|
|
211
|
+
| `refusing to convert an unsupported adapter` (exit 2) | DoRA, MoE or another unsupported type | read the reasons; retrain and save as a plain LoRA adapter |
|
|
212
|
+
| `verify` FAILs with `shape mismatch` | A/B were not transposed | convert again with `convert` |
|
|
213
|
+
| `verify` FAILs with `ignored or dropped tensors` | PEFT keys lack the `base_model.model.` prefix | convert again with `convert` |
|
|
214
|
+
| FAIL with `dW differs` | scale (`alpha = scale x r`) or A/B order mistake | follow the hint line and re-convert; do not loosen `--rtol` to hide it |
|
|
215
|
+
| Weak effect after llama.cpp conversion | `convert_lora_to_gguf.py` does not read `use_rslora` | loraport always writes `use_rslora=false` with `lora_alpha = scale x r`, so its output avoids this |
|
|
216
|
+
|
|
217
|
+
## Development
|
|
218
|
+
```bash
|
|
219
|
+
uv run pytest -q
|
|
220
|
+
```
|
|
221
|
+
```text
|
|
222
|
+
72 passed, 2 skipped in 1.70s
|
|
223
|
+
```
|
|
224
|
+
The two skipped tests are optional (real PEFT integration, Mac-only mlx integration). Run the PEFT one with `uv run --extra peft pytest -q -m peft tests/test_peft_integration.py` (the first run takes over a minute because of torch; `1 passed` in the development environment).
|
|
225
|
+
|
|
226
|
+
Report bugs and ideas as issues. Changes are listed in [CHANGELOG.md](CHANGELOG.md).
|
|
227
|
+
|
|
228
|
+
## License
|
|
229
|
+
MIT. The repo ships no external models or data; test adapters are generated at run time.
|