localdesk 0.3.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- localdesk-0.3.0/.dockerignore +10 -0
- localdesk-0.3.0/.gitattributes +4 -0
- localdesk-0.3.0/.github/workflows/ci.yml +33 -0
- localdesk-0.3.0/.github/workflows/release.yml +80 -0
- localdesk-0.3.0/.gitignore +22 -0
- localdesk-0.3.0/CHANGELOG.md +50 -0
- localdesk-0.3.0/Dockerfile +10 -0
- localdesk-0.3.0/LICENSE +21 -0
- localdesk-0.3.0/NOTICE.md +43 -0
- localdesk-0.3.0/PKG-INFO +314 -0
- localdesk-0.3.0/README.md +274 -0
- localdesk-0.3.0/compose.yaml +18 -0
- localdesk-0.3.0/data/README.md +55 -0
- localdesk-0.3.0/docs/ARCHITECTURE.md +107 -0
- localdesk-0.3.0/docs/BENCHMARK.md +154 -0
- localdesk-0.3.0/docs/DATASETS.md +77 -0
- localdesk-0.3.0/docs/GPU_HTTP.md +89 -0
- localdesk-0.3.0/docs/RELEASING.md +29 -0
- localdesk-0.3.0/docs/RUNBOOK.md +92 -0
- localdesk-0.3.0/docs/TRAINING.md +111 -0
- localdesk-0.3.0/docs/TRAINING_PLAN.md +39 -0
- localdesk-0.3.0/docs/VALIDATION.md +109 -0
- localdesk-0.3.0/docs/demo.png +0 -0
- localdesk-0.3.0/docs/risk-coverage.svg +46 -0
- localdesk-0.3.0/docs/service-demo.png +0 -0
- localdesk-0.3.0/experiments/banking77.json +31 -0
- localdesk-0.3.0/experiments/clinc150.json +31 -0
- localdesk-0.3.0/experiments/it-support.json +34 -0
- localdesk-0.3.0/experiments/sms-filter.json +27 -0
- localdesk-0.3.0/notebooks/benchmark_qwen.ipynb +191 -0
- localdesk-0.3.0/notebooks/train_qwen.ipynb +215 -0
- localdesk-0.3.0/notebooks/train_qwen_drive.ipynb +272 -0
- localdesk-0.3.0/pyproject.toml +71 -0
- localdesk-0.3.0/reports/baseline.json +162 -0
- localdesk-0.3.0/reports/comparison-colab-it.json +1980 -0
- localdesk-0.3.0/reports/comparison-colab-it.md +27 -0
- localdesk-0.3.0/reports/comparison-it.json +1333 -0
- localdesk-0.3.0/reports/comparison-it.md +24 -0
- localdesk-0.3.0/reports/comparison-sms.json +751 -0
- localdesk-0.3.0/reports/comparison-sms.md +24 -0
- localdesk-0.3.0/reports/cpu-suite.json +1070 -0
- localdesk-0.3.0/reports/cpu-suite.md +32 -0
- localdesk-0.3.0/reports/data_manifest.json +3417 -0
- localdesk-0.3.0/reports/demo.json +309 -0
- localdesk-0.3.0/reports/gpu-http-it.json +383 -0
- localdesk-0.3.0/reports/observed-colab-it.json +30 -0
- localdesk-0.3.0/reports/qwen-serving-training.json +213 -0
- localdesk-0.3.0/reports/service-reuse.json +260 -0
- localdesk-0.3.0/requirements-gpu.txt +8 -0
- localdesk-0.3.0/scripts/build_benchmark_notebook.py +131 -0
- localdesk-0.3.0/scripts/build_drive_notebook.py +203 -0
- localdesk-0.3.0/scripts/fixtures/verify_gpu_http_20261012.py.txt +276 -0
- localdesk-0.3.0/scripts/prepare_banking77.py +76 -0
- localdesk-0.3.0/scripts/prepare_clinc150.py +51 -0
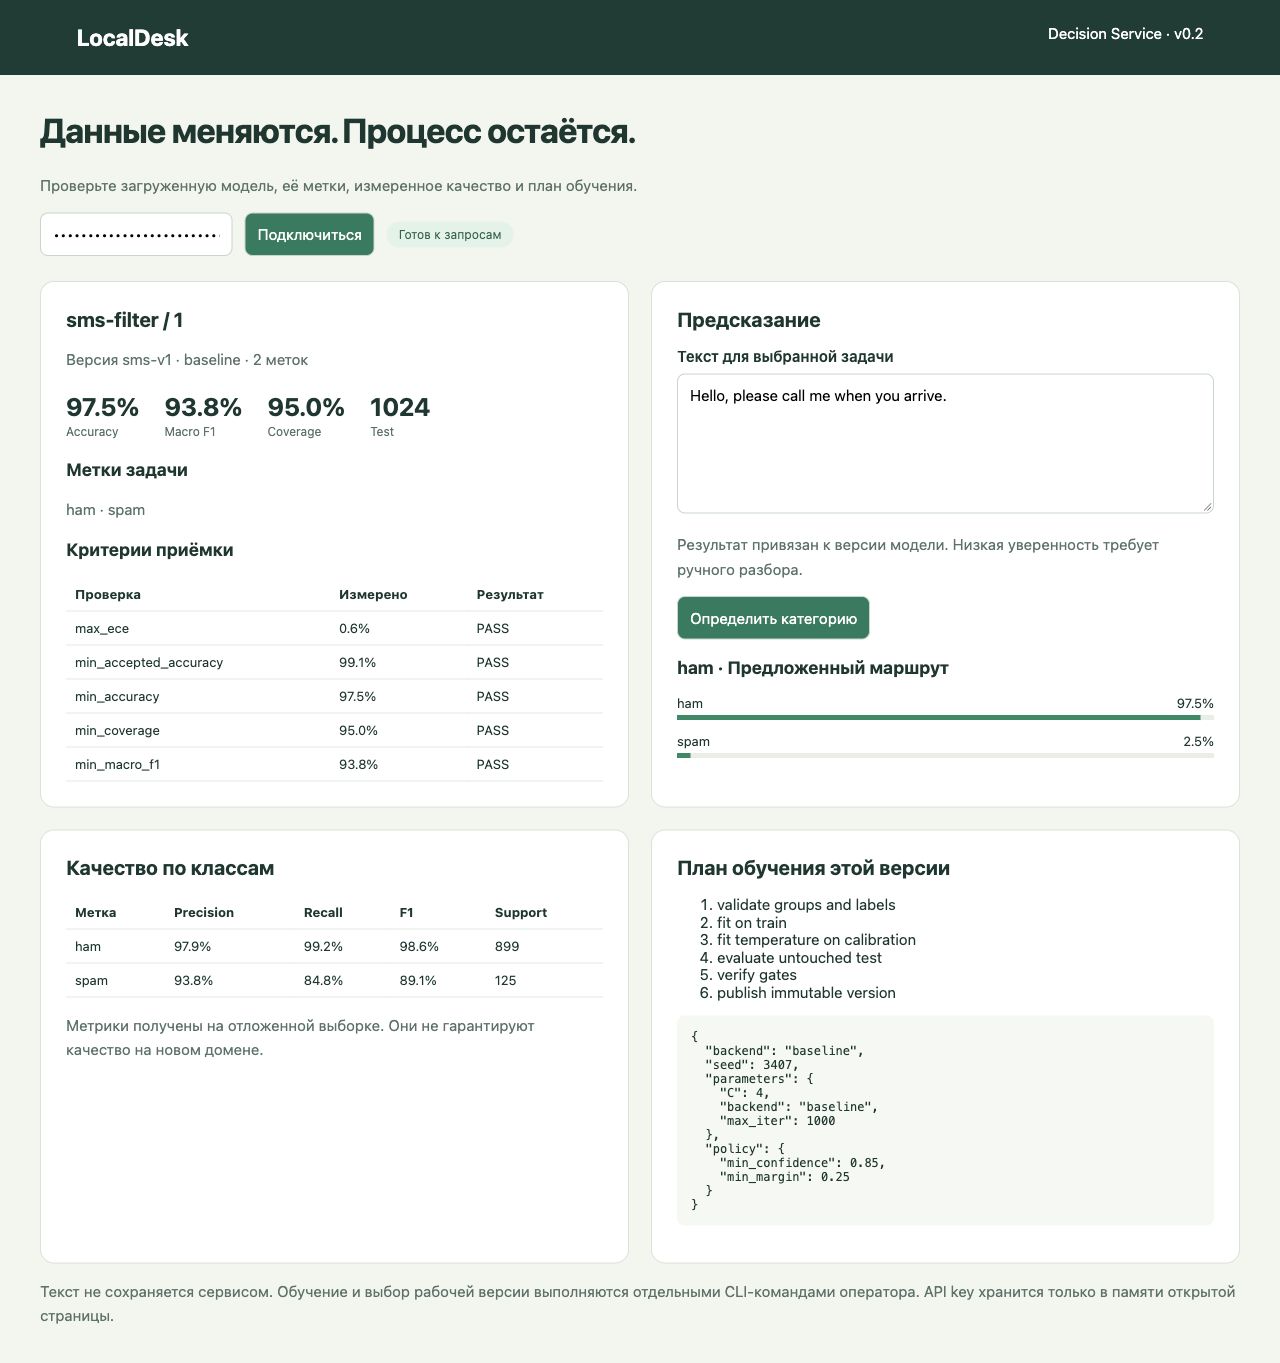
- localdesk-0.3.0/scripts/prepare_data.py +47 -0
- localdesk-0.3.0/scripts/prepare_sms.py +42 -0
- localdesk-0.3.0/scripts/publish_benchmark_report.py +92 -0
- localdesk-0.3.0/scripts/publish_cpu_suite.py +241 -0
- localdesk-0.3.0/scripts/train_baseline.py +141 -0
- localdesk-0.3.0/scripts/train_demo.py +77 -0
- localdesk-0.3.0/scripts/verify_it_qwen_http.py +11 -0
- localdesk-0.3.0/scripts/verify_service_reuse.py +89 -0
- localdesk-0.3.0/src/localdesk/__init__.py +3 -0
- localdesk-0.3.0/src/localdesk/analysis.py +86 -0
- localdesk-0.3.0/src/localdesk/api.py +375 -0
- localdesk-0.3.0/src/localdesk/assets/baseline.json.gz +0 -0
- localdesk-0.3.0/src/localdesk/assets/demo.json.gz +0 -0
- localdesk-0.3.0/src/localdesk/assets/index.html +50 -0
- localdesk-0.3.0/src/localdesk/assets/service.html +7 -0
- localdesk-0.3.0/src/localdesk/baseline.py +84 -0
- localdesk-0.3.0/src/localdesk/benchmark.py +618 -0
- localdesk-0.3.0/src/localdesk/benchmark_qwen.py +206 -0
- localdesk-0.3.0/src/localdesk/cli.py +151 -0
- localdesk-0.3.0/src/localdesk/config.py +284 -0
- localdesk-0.3.0/src/localdesk/core.py +80 -0
- localdesk-0.3.0/src/localdesk/data.py +207 -0
- localdesk-0.3.0/src/localdesk/dataset.py +251 -0
- localdesk-0.3.0/src/localdesk/metrics.py +107 -0
- localdesk-0.3.0/src/localdesk/model.py +103 -0
- localdesk-0.3.0/src/localdesk/pipeline.py +196 -0
- localdesk-0.3.0/src/localdesk/registry.py +229 -0
- localdesk-0.3.0/src/localdesk/schema.py +31 -0
- localdesk-0.3.0/src/localdesk/server.py +104 -0
- localdesk-0.3.0/src/localdesk/sources.py +96 -0
- localdesk-0.3.0/src/localdesk/tfidf.py +225 -0
- localdesk-0.3.0/src/localdesk/training.py +255 -0
- localdesk-0.3.0/tasks/banking77.json +86 -0
- localdesk-0.3.0/tasks/clinc150.json +159 -0
- localdesk-0.3.0/tasks/it-support.json +15 -0
- localdesk-0.3.0/tasks/sms-filter.json +11 -0
- localdesk-0.3.0/tests/test_api.py +201 -0
- localdesk-0.3.0/tests/test_baseline.py +63 -0
- localdesk-0.3.0/tests/test_benchmark.py +236 -0
- localdesk-0.3.0/tests/test_benchmark_qwen.py +116 -0
- localdesk-0.3.0/tests/test_configurable.py +233 -0
- localdesk-0.3.0/tests/test_core.py +99 -0
- localdesk-0.3.0/tests/test_data_metrics.py +157 -0
- localdesk-0.3.0/tests/test_demo.py +44 -0
- localdesk-0.3.0/tests/test_model.py +129 -0
- localdesk-0.3.0/tests/test_pipeline.py +246 -0
- localdesk-0.3.0/tests/test_server.py +62 -0
- localdesk-0.3.0/tests/test_tfidf.py +167 -0
- localdesk-0.3.0/tests/test_training.py +59 -0
- localdesk-0.3.0/uv.lock +629 -0
|
@@ -0,0 +1,33 @@
|
|
|
1
|
+
name: CI
|
|
2
|
+
|
|
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
pull_request:
|
|
6
|
+
|
|
7
|
+
permissions:
|
|
8
|
+
contents: read
|
|
9
|
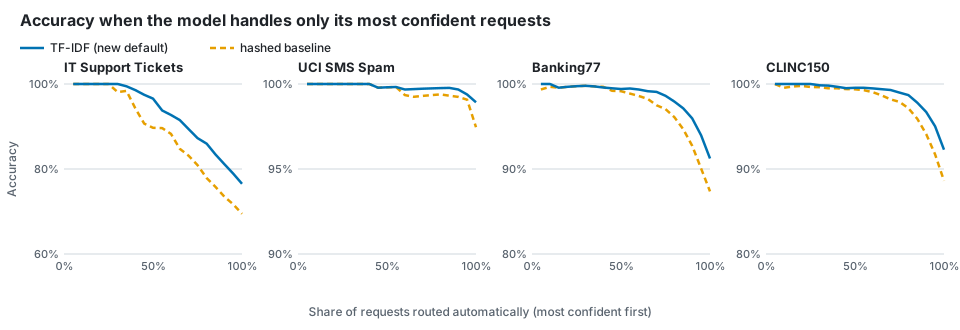
+
|
|
10
|
+
jobs:
|
|
11
|
+
checks:
|
|
12
|
+
strategy:
|
|
13
|
+
matrix:
|
|
14
|
+
os: [ubuntu-latest, windows-latest, macos-latest]
|
|
15
|
+
python: ['3.11', '3.12', '3.13']
|
|
16
|
+
runs-on: ${{ matrix.os }}
|
|
17
|
+
steps:
|
|
18
|
+
- uses: actions/checkout@v4
|
|
19
|
+
- uses: actions/setup-python@v5
|
|
20
|
+
with:
|
|
21
|
+
python-version: ${{ matrix.python }}
|
|
22
|
+
- name: Install project and development tools
|
|
23
|
+
run: python -m pip install '.[dev,baseline,service]'
|
|
24
|
+
- name: Lint
|
|
25
|
+
run: ruff check .
|
|
26
|
+
- name: Format
|
|
27
|
+
run: ruff format --check .
|
|
28
|
+
- name: Test core, packaged model, notebook syntax and HTTP boundary
|
|
29
|
+
run: pytest -q
|
|
30
|
+
- name: Build wheel and sdist
|
|
31
|
+
run: python -m build
|
|
32
|
+
- name: CLI smoke
|
|
33
|
+
run: localdesk predict 'File share access request'
|
|
@@ -0,0 +1,80 @@
|
|
|
1
|
+
name: Release
|
|
2
|
+
|
|
3
|
+
# Publishes with PyPI Trusted Publishing (OIDC): no API tokens are stored in GitHub.
|
|
4
|
+
# A `v*` tag publishes to PyPI; a manual run publishes to TestPyPI for a dry run.
|
|
5
|
+
on:
|
|
6
|
+
push:
|
|
7
|
+
tags: ['v*']
|
|
8
|
+
workflow_dispatch:
|
|
9
|
+
|
|
10
|
+
permissions:
|
|
11
|
+
contents: read
|
|
12
|
+
|
|
13
|
+
jobs:
|
|
14
|
+
build:
|
|
15
|
+
runs-on: ubuntu-latest
|
|
16
|
+
steps:
|
|
17
|
+
- uses: actions/checkout@v4
|
|
18
|
+
- uses: actions/setup-python@v5
|
|
19
|
+
with:
|
|
20
|
+
python-version: '3.13'
|
|
21
|
+
- name: Install build tools
|
|
22
|
+
run: python -m pip install build==1.3.0 twine==7.0.0
|
|
23
|
+
- name: Tag must match the package version
|
|
24
|
+
if: startsWith(github.ref, 'refs/tags/v')
|
|
25
|
+
run: |
|
|
26
|
+
python - <<'EOF'
|
|
27
|
+
import os, tomllib
|
|
28
|
+
version = tomllib.load(open("pyproject.toml", "rb"))["project"]["version"]
|
|
29
|
+
tag = os.environ["GITHUB_REF_NAME"].removeprefix("v")
|
|
30
|
+
if tag != version:
|
|
31
|
+
raise SystemExit(f"tag v{tag} does not match pyproject version {version}")
|
|
32
|
+
EOF
|
|
33
|
+
- name: Build wheel and sdist
|
|
34
|
+
run: python -m build
|
|
35
|
+
- name: Check package metadata and README rendering
|
|
36
|
+
run: twine check --strict dist/*
|
|
37
|
+
- name: Smoke test the wheel without optional dependencies
|
|
38
|
+
run: |
|
|
39
|
+
python -m venv /tmp/smoke
|
|
40
|
+
/tmp/smoke/bin/pip install dist/*.whl
|
|
41
|
+
/tmp/smoke/bin/localdesk predict 'File share access request'
|
|
42
|
+
- uses: actions/upload-artifact@v7
|
|
43
|
+
with:
|
|
44
|
+
name: dist
|
|
45
|
+
path: dist/
|
|
46
|
+
if-no-files-found: error
|
|
47
|
+
|
|
48
|
+
testpypi:
|
|
49
|
+
if: github.event_name == 'workflow_dispatch'
|
|
50
|
+
needs: build
|
|
51
|
+
runs-on: ubuntu-latest
|
|
52
|
+
environment:
|
|
53
|
+
name: testpypi
|
|
54
|
+
url: https://test.pypi.org/p/localdesk
|
|
55
|
+
permissions:
|
|
56
|
+
id-token: write
|
|
57
|
+
steps:
|
|
58
|
+
- uses: actions/download-artifact@v8
|
|
59
|
+
with:
|
|
60
|
+
name: dist
|
|
61
|
+
path: dist/
|
|
62
|
+
- uses: pypa/gh-action-pypi-publish@v1.14.2
|
|
63
|
+
with:
|
|
64
|
+
repository-url: https://test.pypi.org/legacy/
|
|
65
|
+
|
|
66
|
+
pypi:
|
|
67
|
+
if: startsWith(github.ref, 'refs/tags/v')
|
|
68
|
+
needs: build
|
|
69
|
+
runs-on: ubuntu-latest
|
|
70
|
+
environment:
|
|
71
|
+
name: pypi
|
|
72
|
+
url: https://pypi.org/p/localdesk
|
|
73
|
+
permissions:
|
|
74
|
+
id-token: write
|
|
75
|
+
steps:
|
|
76
|
+
- uses: actions/download-artifact@v8
|
|
77
|
+
with:
|
|
78
|
+
name: dist
|
|
79
|
+
path: dist/
|
|
80
|
+
- uses: pypa/gh-action-pypi-publish@v1.14.2
|
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
.venv/
|
|
2
|
+
__pycache__/
|
|
3
|
+
*.py[cod]
|
|
4
|
+
.pytest_cache/
|
|
5
|
+
.ruff_cache/
|
|
6
|
+
*.egg-info/
|
|
7
|
+
dist/
|
|
8
|
+
build/
|
|
9
|
+
data/raw/
|
|
10
|
+
data/zenodo/
|
|
11
|
+
data/sms/
|
|
12
|
+
artifacts/
|
|
13
|
+
*.safetensors
|
|
14
|
+
*.pt
|
|
15
|
+
*.pth
|
|
16
|
+
*.pickle
|
|
17
|
+
*.h5
|
|
18
|
+
.env
|
|
19
|
+
.env.*
|
|
20
|
+
.DS_Store
|
|
21
|
+
data/banking77/
|
|
22
|
+
data/clinc150/
|
|
@@ -0,0 +1,50 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to this project are documented here. The format follows
|
|
4
|
+
[Keep a Changelog](https://keepachangelog.com/en/1.1.0/) and the project uses
|
|
5
|
+
[Semantic Versioning](https://semver.org/).
|
|
6
|
+
|
|
7
|
+
## [0.3.0] - 2026-10-12
|
|
8
|
+
|
|
9
|
+
First release on PyPI. The distribution is now named `localdesk`
|
|
10
|
+
(previously `localdesk-decisions`, never published).
|
|
11
|
+
|
|
12
|
+
### Added
|
|
13
|
+
- `tfidf` CPU backend: hashed word 1–2 grams and character 3–5 grams with
|
|
14
|
+
sublinear TF-IDF and balanced logistic regression. Inference needs only the
|
|
15
|
+
standard library; artifacts store hash buckets, not a training vocabulary.
|
|
16
|
+
Shipped experiments use it.
|
|
17
|
+
- Packaged TF-IDF demo model, now the default for `localdesk predict`, `serve`
|
|
18
|
+
and `evaluate` without `--model` (76.5% vs 69.5% accuracy on the IT holdout).
|
|
19
|
+
`--backend baseline` keeps the previous model.
|
|
20
|
+
- Risk-coverage curves in every training report (coverage at 90/95/99%
|
|
21
|
+
accuracy, AURC) and out-of-scope analysis (review share, AUROC).
|
|
22
|
+
- Banking77 and CLINC150 adapters with pinned sources and checksums, and
|
|
23
|
+
`scripts/publish_cpu_suite.py` for the four-dataset comparison.
|
|
24
|
+
- Release workflow using PyPI Trusted Publishing; Python 3.12 in CI.
|
|
25
|
+
|
|
26
|
+
### Changed
|
|
27
|
+
- Concurrent API requests wait in a bounded queue (32 requests, 30 s) instead
|
|
28
|
+
of failing immediately with `MODEL_BUSY`.
|
|
29
|
+
- A failed training run moves its record to `.failed-<id>-…` and frees the
|
|
30
|
+
run ID for a retry.
|
|
31
|
+
- Optional dependencies use version ranges instead of exact pins; exact
|
|
32
|
+
tested versions stay in `uv.lock`. Tested at both ends of each range.
|
|
33
|
+
- README rewritten around a quick start and measured results.
|
|
34
|
+
|
|
35
|
+
### Fixed
|
|
36
|
+
- A version that fails post-publish verification is withdrawn instead of
|
|
37
|
+
remaining under a completed run ID.
|
|
38
|
+
- `localdesk runs` lists damaged registry entries as invalid instead of
|
|
39
|
+
aborting.
|
|
40
|
+
- Dataset downloads read until EOF and retry truncated bodies.
|
|
41
|
+
- `/metrics` declares a type for every counter; JSONL errors name the line.
|
|
42
|
+
|
|
43
|
+
## [0.2.0] - 2026-10-11
|
|
44
|
+
|
|
45
|
+
Configurable service: task/experiment JSON, immutable registry with quality
|
|
46
|
+
gates, FastAPI inference API, operator dashboard, Qwen/Unsloth recipe and the
|
|
47
|
+
comparative benchmark. Not published to PyPI.
|
|
48
|
+
|
|
49
|
+
[0.3.0]: https://github.com/denis-samatov/localdesk/compare/52a3f7c...v0.3.0
|
|
50
|
+
[0.2.0]: https://github.com/denis-samatov/localdesk/commit/52a3f7c
|
|
@@ -0,0 +1,10 @@
|
|
|
1
|
+
FROM python:3.13-slim
|
|
2
|
+
ENV PYTHONDONTWRITEBYTECODE=1 PYTHONUNBUFFERED=1 LOCALDESK_REGISTRY=/models
|
|
3
|
+
WORKDIR /app
|
|
4
|
+
COPY pyproject.toml README.md LICENSE NOTICE.md ./
|
|
5
|
+
COPY src ./src
|
|
6
|
+
RUN python -m pip install --no-cache-dir '.[service]' && useradd --uid 10001 --create-home app
|
|
7
|
+
USER 10001
|
|
8
|
+
EXPOSE 8765
|
|
9
|
+
HEALTHCHECK --interval=30s --timeout=5s --start-period=20s --retries=3 CMD python -c "import urllib.request; urllib.request.urlopen('http://127.0.0.1:8765/health/ready', timeout=3)"
|
|
10
|
+
CMD ["uvicorn", "localdesk.api:application", "--factory", "--host", "0.0.0.0", "--port", "8765", "--no-access-log"]
|
localdesk-0.3.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Denis Samatov
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,43 @@
|
|
|
1
|
+
The project code and original notebook are MIT licensed.
|
|
2
|
+
|
|
3
|
+
The training data are **Classification of IT Support Tickets**, Leonardo
|
|
4
|
+
Santiago Benitez Pereira, Federal Institute of Santa Catarina, 2022, v2.
|
|
5
|
+
Source: https://doi.org/10.5281/zenodo.7648117
|
|
6
|
+
License: https://creativecommons.org/licenses/by/4.0/
|
|
7
|
+
|
|
8
|
+
Changes made by this project: ID-based CSV joining; normalization for duplicate
|
|
9
|
+
detection (NFKC, case folding, whitespace collapse); conservative grouping by
|
|
10
|
+
PII-tag-stripped, tokenized and hashed baseline input features; duplicate and conflicting
|
|
11
|
+
label removal; a calibration split from source training data; source EOL templates
|
|
12
|
+
reserved as an unsupported-category challenge; conversion to Unsloth choice rows.
|
|
13
|
+
The published linear baseline was trained on this adapted data. Keep this attribution
|
|
14
|
+
with the baseline. Ticket texts are downloaded on demand and excluded from this Git repository.
|
|
15
|
+
|
|
16
|
+
The second configured domain uses **SMS Spam Collection**, Tiago Almeida and
|
|
17
|
+
Jos Hidalgo, UCI Machine Learning Repository, 2011.
|
|
18
|
+
Source: https://doi.org/10.24432/C5CC84 — CC BY 4.0.
|
|
19
|
+
Changes: verified archive extraction and conversion to id/text/label CSV;
|
|
20
|
+
conservative equivalent-input deduplication and deterministic grouped splits.
|
|
21
|
+
Original labels are retained. Raw SMS content is excluded from Git and serving logs.
|
|
22
|
+
|
|
23
|
+
The third and fourth domains are downloaded on demand and excluded from Git:
|
|
24
|
+
|
|
25
|
+
**Banking77**, Iñigo Casanueva, Tadas Temčinas, Daniela Gerz, Matthew Henderson
|
|
26
|
+
and Ivan Vulić, "Efficient Intent Detection with Dual Sentence Encoders", 2020.
|
|
27
|
+
Source: https://github.com/PolyAI-LDN/task-specific-datasets — CC BY 4.0.
|
|
28
|
+
|
|
29
|
+
**CLINC150**, Stefan Larson, Anish Mahendran, Joseph J. Peper, Christopher Clarke,
|
|
30
|
+
Andrew Lee, Parker Hill, Jonathan K. Kummerfeld, Kevin Leach, Michael A. Laurenzano,
|
|
31
|
+
Lingjia Tang and Jason Mars, "An Evaluation Dataset for Intent Classification and
|
|
32
|
+
Out-of-Scope Prediction", EMNLP 2019. Source: https://github.com/clinc/oos-eval —
|
|
33
|
+
CC BY 3.0 (https://creativecommons.org/licenses/by/3.0/).
|
|
34
|
+
|
|
35
|
+
Changes to both: verified extraction to id/text/label JSONL; collapsing of
|
|
36
|
+
model-equivalent duplicates so no group crosses splits; dropping of conflicting
|
|
37
|
+
labels; a deterministic calibration split from Banking77 training data; CLINC150
|
|
38
|
+
out-of-scope test queries kept in a separate file. Original labels are retained.
|
|
39
|
+
|
|
40
|
+
Optional Unsloth / Unsloth Zoo dependencies and the Qwen model retain their own
|
|
41
|
+
licenses. No Unsloth implementation code or notebook content is copied into this
|
|
42
|
+
repository. API integration does not relicense the upstream software. Consult the
|
|
43
|
+
upstream licenses before redistribution or service deployment.
|
localdesk-0.3.0/PKG-INFO
ADDED
|
@@ -0,0 +1,314 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: localdesk
|
|
3
|
+
Version: 0.3.0
|
|
4
|
+
Summary: Calibrated text classification service that abstains when unsure: quality gates, immutable model registry, CPU TF-IDF and optional Qwen/Unsloth fine-tuning
|
|
5
|
+
Project-URL: Homepage, https://github.com/denis-samatov/localdesk
|
|
6
|
+
Project-URL: Documentation, https://github.com/denis-samatov/localdesk/tree/main/docs
|
|
7
|
+
Project-URL: Changelog, https://github.com/denis-samatov/localdesk/blob/main/CHANGELOG.md
|
|
8
|
+
Project-URL: Issues, https://github.com/denis-samatov/localdesk/issues
|
|
9
|
+
Author: Denis Samatov
|
|
10
|
+
License-Expression: MIT
|
|
11
|
+
License-File: LICENSE
|
|
12
|
+
License-File: NOTICE.md
|
|
13
|
+
Keywords: abstention,calibration,fastapi,intent-detection,mlops,model-registry,selective-classification,text-classification,ticket-routing,unsloth
|
|
14
|
+
Classifier: Development Status :: 4 - Beta
|
|
15
|
+
Classifier: Framework :: FastAPI
|
|
16
|
+
Classifier: Intended Audience :: Developers
|
|
17
|
+
Classifier: Intended Audience :: Science/Research
|
|
18
|
+
Classifier: Operating System :: OS Independent
|
|
19
|
+
Classifier: Programming Language :: Python :: 3
|
|
20
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
22
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
23
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
24
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
25
|
+
Classifier: Topic :: Text Processing :: Linguistic
|
|
26
|
+
Requires-Python: >=3.11
|
|
27
|
+
Provides-Extra: baseline
|
|
28
|
+
Requires-Dist: numpy<3,>=1.26; extra == 'baseline'
|
|
29
|
+
Requires-Dist: scikit-learn<2,>=1.6; extra == 'baseline'
|
|
30
|
+
Requires-Dist: scipy<2,>=1.13; extra == 'baseline'
|
|
31
|
+
Provides-Extra: dev
|
|
32
|
+
Requires-Dist: build==1.3.0; extra == 'dev'
|
|
33
|
+
Requires-Dist: httpx2==2.13.1; extra == 'dev'
|
|
34
|
+
Requires-Dist: pytest==8.4.2; extra == 'dev'
|
|
35
|
+
Requires-Dist: ruff==0.13.3; extra == 'dev'
|
|
36
|
+
Provides-Extra: service
|
|
37
|
+
Requires-Dist: fastapi<1,>=0.115; extra == 'service'
|
|
38
|
+
Requires-Dist: uvicorn<1,>=0.30; extra == 'service'
|
|
39
|
+
Description-Content-Type: text/markdown
|
|
40
|
+
|
|
41
|
+
# LocalDesk
|
|
42
|
+
|
|
43
|
+
**Train a text classifier that knows when it isn't sure, and ship it with receipts.**
|
|
44
|
+
|
|
45
|
+
[](https://github.com/denis-samatov/localdesk/actions/workflows/ci.yml)
|
|
46
|
+
[](https://pypi.org/project/localdesk/)
|
|
47
|
+
|
|
48
|
+
[](https://github.com/denis-samatov/localdesk/blob/main/LICENSE)
|
|
49
|
+
[](https://colab.research.google.com/github/denis-samatov/localdesk/blob/main/notebooks/benchmark_qwen.ipynb)
|
|
50
|
+
|
|
51
|
+
LocalDesk turns a CSV or JSONL file and a JSON list of labels into a versioned,
|
|
52
|
+
calibrated classification service that runs locally. It is built for routing:
|
|
53
|
+
support tickets, intents, spam, triage queues. In those settings a confident
|
|
54
|
+
wrong answer costs more than asking a human.
|
|
55
|
+
|
|
56
|
+
- **Abstains instead of guessing.** Every prediction is either `route` or `review`,
|
|
57
|
+
based on calibrated confidence and the margin between the top two labels.
|
|
58
|
+
- **Quality gates before deploy.** A version that misses your accuracy, macro-F1,
|
|
59
|
+
calibration or coverage thresholds cannot be promoted or served.
|
|
60
|
+
- **Every version is reproducible and tamper-evident.** Each version is immutable
|
|
61
|
+
and pins the task, the data fingerprints, the report and the training plan with
|
|
62
|
+
SHA-256 checksums.
|
|
63
|
+
- **CPU first, LLM when it pays off.** The default TF-IDF model trains in seconds,
|
|
64
|
+
reaches **91–99% accuracy on three of four public benchmarks**, and needs only the
|
|
65
|
+
Python standard library for inference. An optional Qwen + Unsloth LoRA recipe
|
|
66
|
+
gave a further **+5.7 pp accuracy** on the hardest one, real IT tickets.
|
|
67
|
+
|
|
68
|
+
|
|
69
|
+
|
|
70
|
+
## Try it in 10 seconds
|
|
71
|
+
|
|
72
|
+
The package ships with the TF-IDF demo model trained on real IT tickets
|
|
73
|
+
(76.5% accuracy on the 524-ticket holdout, [report](https://github.com/denis-samatov/localdesk/blob/main/reports/demo.json)).
|
|
74
|
+
Running a prediction has no runtime dependencies:
|
|
75
|
+
|
|
76
|
+
```bash
|
|
77
|
+
pip install localdesk
|
|
78
|
+
localdesk predict "File share access request"
|
|
79
|
+
localdesk predict "I can't open the shared finance folder"
|
|
80
|
+
```
|
|
81
|
+
|
|
82
|
+
A clear request is routed. An ambiguous one goes to a human with the reason
|
|
83
|
+
attached (output abbreviated):
|
|
84
|
+
|
|
85
|
+
```jsonc
|
|
86
|
+
{"category": "Fileservice", "action": "route", "probabilities": {"Fileservice": 0.999, ...}, "review_reasons": []}
|
|
87
|
+
{"category": "Fileservice", "action": "review", "probabilities": {"Fileservice": 0.43, "Support general": 0.24, ...},
|
|
88
|
+
"review_reasons": ["low_confidence", "small_margin"]}
|
|
89
|
+
```
|
|
90
|
+
|
|
91
|
+
Run `localdesk serve` to open the same model in a local web page at `http://127.0.0.1:8765`.
|
|
92
|
+
|
|
93
|
+
## Train on your own data (5 minutes)
|
|
94
|
+
|
|
95
|
+
**1. Describe the task.** The labels are yours; nothing in the core is IT-specific.
|
|
96
|
+
|
|
97
|
+
```json
|
|
98
|
+
{
|
|
99
|
+
"id": "my-intents",
|
|
100
|
+
"version": "1",
|
|
101
|
+
"instructions": "Choose the intent of the message.",
|
|
102
|
+
"labels": {
|
|
103
|
+
"returns": "Requests to return a purchased item.",
|
|
104
|
+
"delivery": "Questions or problems with delivery.",
|
|
105
|
+
"other": "Other supported customer requests."
|
|
106
|
+
},
|
|
107
|
+
"min_confidence": 0.8,
|
|
108
|
+
"min_margin": 0.2
|
|
109
|
+
}
|
|
110
|
+
```
|
|
111
|
+
|
|
112
|
+
**2. Point an experiment at your file and set the bar a model must clear.**
|
|
113
|
+
|
|
114
|
+
```json
|
|
115
|
+
{
|
|
116
|
+
"task": "my-task.json",
|
|
117
|
+
"dataset": {
|
|
118
|
+
"path": "my-records.csv",
|
|
119
|
+
"format": "csv",
|
|
120
|
+
"text_column": "message",
|
|
121
|
+
"label_column": "intent",
|
|
122
|
+
"id_column": "id"
|
|
123
|
+
},
|
|
124
|
+
"registry": "my-registry",
|
|
125
|
+
"training": {"backend": "tfidf"},
|
|
126
|
+
"gates": {"min_accuracy": 0.7, "min_macro_f1": 0.6, "max_ece": 0.1}
|
|
127
|
+
}
|
|
128
|
+
```
|
|
129
|
+
|
|
130
|
+
**3. Validate, train, promote, serve.**
|
|
131
|
+
|
|
132
|
+
```bash
|
|
133
|
+
pip install 'localdesk[baseline,service]' # training + HTTP API
|
|
134
|
+
|
|
135
|
+
localdesk validate my-experiment.json # checks labels, leakage, class support
|
|
136
|
+
localdesk train my-experiment.json --run-id v1 # fit, calibrate, evaluate, gate
|
|
137
|
+
localdesk runs --registry my-registry # list versions and gate results
|
|
138
|
+
localdesk promote v1 --registry my-registry # refuses versions that failed gates
|
|
139
|
+
localdesk api --registry my-registry --anonymous-local
|
|
140
|
+
```
|
|
141
|
+
|
|
142
|
+
Paths are relative to the experiment file. JSONL supports dotted fields such as
|
|
143
|
+
`gold.category`, and you can supply explicit train/calibration/test files.
|
|
144
|
+
Unknown labels, conflicting duplicates, groups that cross splits and typos in the
|
|
145
|
+
configuration fail early with a clear message.
|
|
146
|
+
|
|
147
|
+
## Results on real public data
|
|
148
|
+
|
|
149
|
+
The same pipeline and commands on four public datasets. Only the configuration changes.
|
|
150
|
+
Default `tfidf` backend, test sets never used for fitting or calibration:
|
|
151
|
+
|
|
152
|
+
| Dataset | Labels | Test rows | Accuracy | Macro F1 | Auto-routed | Accuracy when routed |
|
|
153
|
+
| --- | ---: | ---: | ---: | ---: | ---: | ---: |
|
|
154
|
+
| [IT Support Tickets](https://zenodo.org/records/7648117) | 6 | 524 | 76.5% | 72.9% | 60.5% | **92.4%** |
|
|
155
|
+
| [UCI SMS Spam](https://archive.ics.uci.edu/dataset/228/sms+spam+collection) | 2 | 1,024 | 98.9% | 97.4% | 97.7% | **99.3%** |
|
|
156
|
+
| [Banking77](https://github.com/PolyAI-LDN/task-specific-datasets) | 77 | 3,071 | 91.2% | 91.3% | 86.9% | **96.8%** |
|
|
157
|
+
| [CLINC150](https://github.com/clinc/oos-eval) | 150 | 4,486 | 92.3% | 92.2% | 88.9% | **97.0%** |
|
|
158
|
+
|
|
159
|
+
"Auto-routed" is the share of requests the model handled without a human under
|
|
160
|
+
the task's fixed review policy, and "Accuracy when routed" is measured on those
|
|
161
|
+
requests only. Compared with the legacy hashed baseline, TF-IDF adds 1.5–7.1 pp
|
|
162
|
+
accuracy on every dataset and routes 2.6–16.4 pp more requests automatically
|
|
163
|
+
([full comparison](https://github.com/denis-samatov/localdesk/blob/main/reports/cpu-suite.md)). Training takes 1–40 seconds on a laptop CPU.
|
|
164
|
+
|
|
165
|
+
|
|
166
|
+
|
|
167
|
+
The fewer requests the model takes, the more accurate it gets. On Banking77,
|
|
168
|
+
TF-IDF keeps 95% accuracy on its most confident 93% of queries; the old baseline
|
|
169
|
+
holds that accuracy on only 84%. These curves are read off the test sets: use them
|
|
170
|
+
to choose a policy, then confirm it on your own data.
|
|
171
|
+
|
|
172
|
+
**Queries outside every label.** CLINC150 includes 1,000 test queries that match
|
|
173
|
+
none of its 150 intents and are never seen in training. Under the default policy,
|
|
174
|
+
**85% of them go to human review** instead of receiving a wrong intent.
|
|
175
|
+
|
|
176
|
+
To reproduce from a clone of this repository (the scripts download and checksum
|
|
177
|
+
the public data):
|
|
178
|
+
|
|
179
|
+
```bash
|
|
180
|
+
pip install -e '.[baseline]'
|
|
181
|
+
python scripts/prepare_data.py && python scripts/prepare_sms.py
|
|
182
|
+
python scripts/prepare_banking77.py && python scripts/prepare_clinc150.py
|
|
183
|
+
python scripts/publish_cpu_suite.py # both CPU backends on all four datasets
|
|
184
|
+
```
|
|
185
|
+
|
|
186
|
+
**Fine-tuned Qwen vs classic baselines** (same 524 IT test rows, free Colab T4):
|
|
187
|
+
|
|
188
|
+
| Method | Accuracy | Macro F1 | p50 latency |
|
|
189
|
+
| --- | ---: | ---: | ---: |
|
|
190
|
+
| Qwen 3.5 4B + LoRA (LocalDesk recipe) | **82.8%** | **80.6%** | 389 ms |
|
|
191
|
+
| TF-IDF + SVM (tuned) | 77.1% | 73.5% | 1.8 ms |
|
|
192
|
+
| TF-IDF + logistic regression | 77.7% | 74.0% | 2.1 ms |
|
|
193
|
+
| Qwen 3.5 4B zero-shot | 55.3% | 54.1% | 251 ms |
|
|
194
|
+
|
|
195
|
+
The accuracy gain over the SVM is +5.73 pp, with a paired-bootstrap 95% CI of
|
|
196
|
+
[+2.48, +9.16] pp. Macro-F1 gain is +7.06 pp, with a 95% CI of [+3.31, +11.10] pp.
|
|
197
|
+
Full protocol: [docs/BENCHMARK.md](https://github.com/denis-samatov/localdesk/blob/main/docs/BENCHMARK.md) · report:
|
|
198
|
+
[reports/comparison-colab-it.md](https://github.com/denis-samatov/localdesk/blob/main/reports/comparison-colab-it.md) ·
|
|
199
|
+
run it yourself: [Colab notebook](https://colab.research.google.com/github/denis-samatov/localdesk/blob/main/notebooks/benchmark_qwen.ipynb).
|
|
200
|
+
|
|
201
|
+
These are reused public holdouts, not a field trial. Measure on your own data
|
|
202
|
+
before relying on the numbers. [docs/VALIDATION.md](https://github.com/denis-samatov/localdesk/blob/main/docs/VALIDATION.md) lists
|
|
203
|
+
exactly what was and wasn't verified.
|
|
204
|
+
|
|
205
|
+
## How it works
|
|
206
|
+
|
|
207
|
+
```mermaid
|
|
208
|
+
flowchart LR
|
|
209
|
+
C[Task + experiment JSON] --> D[CSV / JSONL intake]
|
|
210
|
+
D --> V[Validate labels, group duplicates, isolate splits]
|
|
211
|
+
V --> T[Train: CPU TF-IDF or Qwen LoRA]
|
|
212
|
+
T --> K[Calibrate on a separate split]
|
|
213
|
+
K --> E[Evaluate on untouched test]
|
|
214
|
+
E --> G{Quality gates}
|
|
215
|
+
G -->|pass| R[Immutable version in registry]
|
|
216
|
+
G -->|fail| X[Kept for inspection, never served]
|
|
217
|
+
R --> P[promote / rollback]
|
|
218
|
+
P --> A[HTTP API + dashboard]
|
|
219
|
+
```
|
|
220
|
+
|
|
221
|
+
- **No leakage by construction.** Records that share a conversation or produce
|
|
222
|
+
identical model features are grouped together, and a group never spans
|
|
223
|
+
train/calibration/test.
|
|
224
|
+
- **Training and serving are separate processes.** The HTTP API cannot upload
|
|
225
|
+
data, train or promote; it only answers predictions. Operators use the CLI.
|
|
226
|
+
- **Promotion is an atomic pointer swap.** Rollback is `localdesk promote <older-run>`.
|
|
227
|
+
Workers verify every checksum on startup.
|
|
228
|
+
|
|
229
|
+
More detail: [architecture and contracts](https://github.com/denis-samatov/localdesk/blob/main/docs/ARCHITECTURE.md) ·
|
|
230
|
+
[training plan](https://github.com/denis-samatov/localdesk/blob/main/docs/TRAINING_PLAN.md).
|
|
231
|
+
|
|
232
|
+
## HTTP API
|
|
233
|
+
|
|
234
|
+
```bash
|
|
235
|
+
export LOCALDESK_API_KEY=change-me
|
|
236
|
+
localdesk api --registry my-registry # or: docker compose up --build -d
|
|
237
|
+
|
|
238
|
+
curl http://127.0.0.1:8765/v1/predictions \
|
|
239
|
+
-H "X-API-Key: $LOCALDESK_API_KEY" -H 'Content-Type: application/json' \
|
|
240
|
+
-d '{"text": "Where is my parcel?"}'
|
|
241
|
+
```
|
|
242
|
+
|
|
243
|
+
| Endpoint | Purpose |
|
|
244
|
+
| --- | --- |
|
|
245
|
+
| `POST /v1/predictions`, `POST /v1/predictions/batch` | Decision, probabilities, model version and task hash |
|
|
246
|
+
| `GET /v1/model`, `/v1/model/report`, `/v1/model/plan` | Active labels, measured quality, gates and training plan |
|
|
247
|
+
| `GET /health/live`, `/health/ready` | Liveness; readiness only when a qualified model is loaded |
|
|
248
|
+
| `GET /metrics` | Prometheus counters (no request bodies are logged) |
|
|
249
|
+
|
|
250
|
+
Inference requests are queued and run one at a time, so a single process can
|
|
251
|
+
safely hold a GPU model. The API key is compared in constant time, bodies are
|
|
252
|
+
size- and time-limited, and anonymous mode accepts only loopback hosts and
|
|
253
|
+
origins. The Docker setup runs as a non-root user with a read-only filesystem
|
|
254
|
+
and models mounted read-only. See the [runbook](https://github.com/denis-samatov/localdesk/blob/main/docs/RUNBOOK.md).
|
|
255
|
+
|
|
256
|
+
## Fine-tune Qwen with Unsloth (optional, CUDA)
|
|
257
|
+
|
|
258
|
+
Swap the `training` block and keep the rest of the pipeline:
|
|
259
|
+
|
|
260
|
+
```json
|
|
261
|
+
"training": {"backend": "unsloth", "epochs": 2, "rank": 16, "batch_size": 2,
|
|
262
|
+
"gradient_accumulation": 4, "learning_rate": 0.0002}
|
|
263
|
+
```
|
|
264
|
+
|
|
265
|
+
The classification head is built from your label descriptions. Upstream
|
|
266
|
+
revisions are pinned in `requirements-gpu.txt`. Training stops on skipped or
|
|
267
|
+
truncated examples instead of silently degrading. Setup: [docs/TRAINING.md](https://github.com/denis-samatov/localdesk/blob/main/docs/TRAINING.md).
|
|
268
|
+
GPU serving details: [docs/GPU_HTTP.md](https://github.com/denis-samatov/localdesk/blob/main/docs/GPU_HTTP.md).
|
|
269
|
+
|
|
270
|
+
## Status
|
|
271
|
+
|
|
272
|
+
LocalDesk is **v0.2, early but tested**. CI runs lint, formatting, the test suite,
|
|
273
|
+
package build and a CLI smoke test on Linux, macOS and Windows with Python 3.11,
|
|
274
|
+
3.12 and 3.13.
|
|
275
|
+
|
|
276
|
+
Current scope is single-label text classification on a single node. Not included
|
|
277
|
+
yet: multi-label targets, a hosted Qwen checkpoint you can download, multi-tenant
|
|
278
|
+
isolation, and hot-swapping models without a restart.
|
|
279
|
+
|
|
280
|
+
## Development
|
|
281
|
+
|
|
282
|
+
```bash
|
|
283
|
+
git clone https://github.com/denis-samatov/localdesk.git && cd localdesk
|
|
284
|
+
uv sync --frozen --extra dev --extra baseline --extra service
|
|
285
|
+
uv run pytest -q
|
|
286
|
+
uv run ruff check . && uv run ruff format --check .
|
|
287
|
+
```
|
|
288
|
+
|
|
289
|
+
Issues and pull requests are welcome. Please include a test for any change in behaviour.
|
|
290
|
+
|
|
291
|
+
## Documentation
|
|
292
|
+
|
|
293
|
+
[Architecture](https://github.com/denis-samatov/localdesk/blob/main/docs/ARCHITECTURE.md) · [Runbook & API](https://github.com/denis-samatov/localdesk/blob/main/docs/RUNBOOK.md) ·
|
|
294
|
+
[Datasets & provenance](https://github.com/denis-samatov/localdesk/blob/main/docs/DATASETS.md) · [Training](https://github.com/denis-samatov/localdesk/blob/main/docs/TRAINING.md) ·
|
|
295
|
+
[Benchmark protocol](https://github.com/denis-samatov/localdesk/blob/main/docs/BENCHMARK.md) · [GPU HTTP check](https://github.com/denis-samatov/localdesk/blob/main/docs/GPU_HTTP.md) ·
|
|
296
|
+
[Validation evidence](https://github.com/denis-samatov/localdesk/blob/main/docs/VALIDATION.md)
|
|
297
|
+
|
|
298
|
+
## По-русски
|
|
299
|
+
|
|
300
|
+
LocalDesk превращает CSV/JSONL и список меток в калиброванный сервис классификации
|
|
301
|
+
текста с версиями и порогами качества. Модель отвечает «маршрутизировать» или
|
|
302
|
+
«на ручной разбор», если не уверена. Ядро не привязано к домену: меняются только
|
|
303
|
+
JSON-описание задачи и датасет. Обучение на CPU занимает секунды. Дообучение
|
|
304
|
+
Qwen через Unsloth дало +5,7 п.п. точности к сильному TF-IDF baseline на реальных
|
|
305
|
+
IT-заявках. На четырёх публичных датасетах (IT-заявки, SMS, Banking77, CLINC150)
|
|
306
|
+
CPU-модель по умолчанию даёт от 76,5% до 98,9% точности, а 85% запросов вне всех
|
|
307
|
+
категорий отправляет на ручной разбор. Качество на других языках и в других организациях нужно измерять
|
|
308
|
+
отдельно.
|
|
309
|
+
|
|
310
|
+
## License
|
|
311
|
+
|
|
312
|
+
Code and notebooks: [MIT](https://github.com/denis-samatov/localdesk/blob/main/LICENSE). The bundled demo model and benchmarks use
|
|
313
|
+
public datasets under CC BY 4.0; attribution is in [NOTICE.md](https://github.com/denis-samatov/localdesk/blob/main/NOTICE.md).
|
|
314
|
+
Optional dependencies and model weights keep their own licenses.
|