llmperfscope 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- llmperfscope-0.1.0/CHANGELOG.md +14 -0
- llmperfscope-0.1.0/CITATION.cff +17 -0
- llmperfscope-0.1.0/CONTRIBUTING.md +33 -0
- llmperfscope-0.1.0/LICENSE +190 -0
- llmperfscope-0.1.0/MANIFEST.in +10 -0
- llmperfscope-0.1.0/PKG-INFO +207 -0
- llmperfscope-0.1.0/README.md +175 -0
- llmperfscope-0.1.0/docs/adapters.md +92 -0
- llmperfscope-0.1.0/docs/comparing.md +95 -0
- llmperfscope-0.1.0/docs/deep-dives.md +62 -0
- llmperfscope-0.1.0/docs/engines.md +171 -0
- llmperfscope-0.1.0/docs/figures.md +156 -0
- llmperfscope-0.1.0/docs/quickstart.md +102 -0
- llmperfscope-0.1.0/docs/reading-reports.md +125 -0
- llmperfscope-0.1.0/docs/run-json.md +122 -0
- llmperfscope-0.1.0/docs/validation.md +58 -0
- llmperfscope-0.1.0/examples/cases-llama-bench.json +13 -0
- llmperfscope-0.1.0/examples/transformers_generate.py +29 -0
- llmperfscope-0.1.0/examples/vllm_offline.py +21 -0
- llmperfscope-0.1.0/pyproject.toml +52 -0
- llmperfscope-0.1.0/setup.cfg +4 -0
- llmperfscope-0.1.0/src/llmperfscope/__init__.py +6 -0
- llmperfscope-0.1.0/src/llmperfscope/__main__.py +5 -0
- llmperfscope-0.1.0/src/llmperfscope/adapters.py +396 -0
- llmperfscope-0.1.0/src/llmperfscope/analyze.py +598 -0
- llmperfscope-0.1.0/src/llmperfscope/api.py +202 -0
- llmperfscope-0.1.0/src/llmperfscope/capabilities.py +83 -0
- llmperfscope-0.1.0/src/llmperfscope/cli.py +502 -0
- llmperfscope-0.1.0/src/llmperfscope/compare.py +232 -0
- llmperfscope-0.1.0/src/llmperfscope/container.py +79 -0
- llmperfscope-0.1.0/src/llmperfscope/cpuprof.py +238 -0
- llmperfscope-0.1.0/src/llmperfscope/diagnose.py +525 -0
- llmperfscope-0.1.0/src/llmperfscope/driver.py +361 -0
- llmperfscope-0.1.0/src/llmperfscope/figures.py +1096 -0
- llmperfscope-0.1.0/src/llmperfscope/gpu.py +277 -0
- llmperfscope-0.1.0/src/llmperfscope/html.py +320 -0
- llmperfscope-0.1.0/src/llmperfscope/machine.py +313 -0
- llmperfscope-0.1.0/src/llmperfscope/markers.py +107 -0
- llmperfscope-0.1.0/src/llmperfscope/native/cpuprof.c +274 -0
- llmperfscope-0.1.0/src/llmperfscope/nsys.py +287 -0
- llmperfscope-0.1.0/src/llmperfscope/procfs.py +165 -0
- llmperfscope-0.1.0/src/llmperfscope/report.py +264 -0
- llmperfscope-0.1.0/src/llmperfscope/runner.py +567 -0
- llmperfscope-0.1.0/src/llmperfscope/sampler.py +237 -0
- llmperfscope-0.1.0/src/llmperfscope/share.py +67 -0
- llmperfscope-0.1.0/src/llmperfscope/system.py +223 -0
- llmperfscope-0.1.0/src/llmperfscope.egg-info/PKG-INFO +207 -0
- llmperfscope-0.1.0/src/llmperfscope.egg-info/SOURCES.txt +58 -0
- llmperfscope-0.1.0/src/llmperfscope.egg-info/dependency_links.txt +1 -0
- llmperfscope-0.1.0/src/llmperfscope.egg-info/entry_points.txt +2 -0
- llmperfscope-0.1.0/src/llmperfscope.egg-info/requires.txt +3 -0
- llmperfscope-0.1.0/src/llmperfscope.egg-info/top_level.txt +1 -0
- llmperfscope-0.1.0/tests/fake_engine.py +104 -0
- llmperfscope-0.1.0/tests/fake_openai_server.py +73 -0
- llmperfscope-0.1.0/tests/helpers.py +66 -0
- llmperfscope-0.1.0/tests/test_figures.py +283 -0
- llmperfscope-0.1.0/tests/test_html.py +61 -0
- llmperfscope-0.1.0/tests/test_parsers.py +663 -0
- llmperfscope-0.1.0/tests/test_runs.py +350 -0
- llmperfscope-0.1.0/tests/test_samples.py +107 -0
|
@@ -0,0 +1,14 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
## 0.1.0
|
|
4
|
+
|
|
5
|
+
First public release.
|
|
6
|
+
|
|
7
|
+
- `run`, `serve` and `attach`: profile any command, server, container or running process over its whole life, with no code changes.
|
|
8
|
+
- Per-phase verdicts on what limits it, findings on memory and on data moving between disk, RAM and GPU, and on how serving scales.
|
|
9
|
+
- Support for llama.cpp, vLLM, SGLang, Text Generation Inference, Ollama, transformers and any OpenAI-compatible server, plus phase markers for anything else.
|
|
10
|
+
- `--nsys` for GPU kernels, collectives and copies, `--cpu-profile` for host hot spots without `perf`, `--cold-start` for a first load.
|
|
11
|
+
- `diff`, `matrix` and `noise`: comparisons that judge speed, memory, load time and energy together.
|
|
12
|
+
- `figure`: paper figures as PDF, SVG and PNG, with their data as CSV and suggested captions.
|
|
13
|
+
- `anonymize`: a copy of a run that can be published.
|
|
14
|
+
- `report.html`: every counter on one time axis.
|
|
@@ -0,0 +1,17 @@
|
|
|
1
|
+
cff-version: 1.2.0
|
|
2
|
+
message: "If you use this software, please cite it as below."
|
|
3
|
+
title: "llmperfscope: a whole-lifecycle profiler for LLM inference engines"
|
|
4
|
+
type: software
|
|
5
|
+
authors:
|
|
6
|
+
- family-names: Kwon
|
|
7
|
+
given-names: Yonghye
|
|
8
|
+
repository-code: "https://github.com/developer0hye/llmperfscope"
|
|
9
|
+
license: Apache-2.0
|
|
10
|
+
version: 0.1.0
|
|
11
|
+
date-released: "2026-11-01"
|
|
12
|
+
keywords:
|
|
13
|
+
- llm
|
|
14
|
+
- profiling
|
|
15
|
+
- inference
|
|
16
|
+
- performance
|
|
17
|
+
- gpu
|
|
@@ -0,0 +1,33 @@
|
|
|
1
|
+
# Contributing
|
|
2
|
+
|
|
3
|
+
Issues and pull requests are welcome. Reports of a wrong number or a misleading verdict are especially useful: please attach the run, copied with `llmperfscope anonymize RUN --out DIR`.
|
|
4
|
+
|
|
5
|
+
## Setting up
|
|
6
|
+
|
|
7
|
+
```sh
|
|
8
|
+
git clone https://github.com/developer0hye/llmperfscope && cd llmperfscope
|
|
9
|
+
pip install -e ".[figures]"
|
|
10
|
+
cd tests && python3 -m unittest
|
|
11
|
+
```
|
|
12
|
+
|
|
13
|
+
The tests need Linux but no GPU: real processes with known behaviour stand in for an engine, and scripted GPUs for hardware. On other systems `test_samples` and `test_docs` still run.
|
|
14
|
+
|
|
15
|
+
## What a change should do
|
|
16
|
+
|
|
17
|
+
- **An instrument has to be right.** A new number needs a test where the true answer is known, because the process was made to behave that way. Then the report has to say what happened.
|
|
18
|
+
- **Keep the measuring side free of dependencies.** `pip install llmperfscope` installs nothing else. Only `figures` needs matplotlib, and it loads only when drawing.
|
|
19
|
+
- **Do not disturb the engine.** Anything slow goes on its own thread and at a low rate. If a change could cost the engine speed, show it does not: alternate fresh processes with and without it, on a real engine. See [docs/validation.md](docs/validation.md).
|
|
20
|
+
- **State the evidence.** A finding carries the numbers it rests on, and says so when it cannot tell. It stays silent on short runs and shared machines unless the evidence survives them.
|
|
21
|
+
- **Keep the docs in step.** A new option or finding goes in `docs/`. `tests/test_docs.py` checks that every option and relative link in the docs exists.
|
|
22
|
+
|
|
23
|
+
## Adding an engine
|
|
24
|
+
|
|
25
|
+
See [docs/adapters.md](docs/adapters.md). Often a preset is enough. Please add a real sample of the engine's output to `tests/test_parsers.py`.
|
|
26
|
+
|
|
27
|
+
## Figures
|
|
28
|
+
|
|
29
|
+
The series colors are validated for color vision deficiency in their fixed order, so assign them in sequence and never cycle them. Render at `--width single` and `--width double` and look at the result, since tests cannot see an overlap. Regenerate the gallery with `docs/gallery/make.sh`.
|
|
30
|
+
|
|
31
|
+
## Sample runs
|
|
32
|
+
|
|
33
|
+
`examples/sample-runs` holds real runs, copied with `llmperfscope anonymize`. Check a new one for names before adding it.
|
|
@@ -0,0 +1,190 @@
|
|
|
1
|
+
Apache License
|
|
2
|
+
Version 2.0, January 2004
|
|
3
|
+
http://www.apache.org/licenses/
|
|
4
|
+
|
|
5
|
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
|
6
|
+
|
|
7
|
+
1. Definitions.
|
|
8
|
+
|
|
9
|
+
"License" shall mean the terms and conditions for use, reproduction,
|
|
10
|
+
and distribution as defined by Sections 1 through 9 of this document.
|
|
11
|
+
|
|
12
|
+
"Licensor" shall mean the copyright owner or entity authorized by
|
|
13
|
+
the copyright owner that is granting the License.
|
|
14
|
+
|
|
15
|
+
"Legal Entity" shall mean the union of the acting entity and all
|
|
16
|
+
other entities that control, are controlled by, or are under common
|
|
17
|
+
control with that entity. For the purposes of this definition,
|
|
18
|
+
"control" means (i) the power, direct or indirect, to cause the
|
|
19
|
+
direction or management of such entity, whether by contract or
|
|
20
|
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
|
21
|
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
|
22
|
+
|
|
23
|
+
"You" (or "Your") shall mean an individual or Legal Entity
|
|
24
|
+
exercising permissions granted by this License.
|
|
25
|
+
|
|
26
|
+
"Source" form shall mean the preferred form for making modifications,
|
|
27
|
+
including but not limited to software source code, documentation
|
|
28
|
+
source, and configuration files.
|
|
29
|
+
|
|
30
|
+
"Object" form shall mean any form resulting from mechanical
|
|
31
|
+
transformation or translation of a Source form, including but
|
|
32
|
+
not limited to compiled object code, generated documentation,
|
|
33
|
+
and conversions to other media types.
|
|
34
|
+
|
|
35
|
+
"Work" shall mean the work of authorship, whether in Source or
|
|
36
|
+
Object form, made available under the License, as indicated by a
|
|
37
|
+
copyright notice that is included in or attached to the work
|
|
38
|
+
(an example is provided in the Appendix below).
|
|
39
|
+
|
|
40
|
+
"Derivative Works" shall mean any work, whether in Source or Object
|
|
41
|
+
form, that is based on (or derived from) the Work and for which the
|
|
42
|
+
editorial revisions, annotations, elaborations, or other modifications
|
|
43
|
+
represent, as a whole, an original work of authorship. For the purposes
|
|
44
|
+
of this License, Derivative Works shall not include works that remain
|
|
45
|
+
separable from, or merely link (or bind by name) to the interfaces of,
|
|
46
|
+
the Work and Derivative Works thereof.
|
|
47
|
+
|
|
48
|
+
"Contribution" shall mean any work of authorship, including
|
|
49
|
+
the original version of the Work and any modifications or additions
|
|
50
|
+
to that Work or Derivative Works thereof, that is intentionally
|
|
51
|
+
submitted to the Licensor for inclusion in the Work by the copyright owner
|
|
52
|
+
or by an individual or Legal Entity authorized to submit on behalf of
|
|
53
|
+
the copyright owner. For the purposes of this definition, "submitted"
|
|
54
|
+
means any form of electronic, verbal, or written communication sent
|
|
55
|
+
to the Licensor or its representatives, including but not limited to
|
|
56
|
+
communication on electronic mailing lists, source code control systems,
|
|
57
|
+
and issue tracking systems that are managed by, or on behalf of, the
|
|
58
|
+
Licensor for the purpose of discussing and improving the Work, but
|
|
59
|
+
excluding communication that is conspicuously marked or otherwise
|
|
60
|
+
designated in writing by the copyright owner as "Not a Contribution."
|
|
61
|
+
|
|
62
|
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
|
63
|
+
on behalf of whom a Contribution has been received by the Licensor and
|
|
64
|
+
subsequently incorporated within the Work.
|
|
65
|
+
|
|
66
|
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
|
67
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
68
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
69
|
+
copyright license to reproduce, prepare Derivative Works of,
|
|
70
|
+
publicly display, publicly perform, sublicense, and distribute the
|
|
71
|
+
Work and such Derivative Works in Source or Object form.
|
|
72
|
+
|
|
73
|
+
3. Grant of Patent License. Subject to the terms and conditions of
|
|
74
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
75
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
76
|
+
(except as stated in this section) patent license to make, have made,
|
|
77
|
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
|
78
|
+
where such license applies only to those patent claims licensable
|
|
79
|
+
by such Contributor that are necessarily infringed by their
|
|
80
|
+
Contribution(s) alone or by combination of their Contribution(s)
|
|
81
|
+
with the Work to which such Contribution(s) was submitted. If You
|
|
82
|
+
institute patent litigation against any entity (including a
|
|
83
|
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
|
84
|
+
or a Contribution incorporated within the Work constitutes direct
|
|
85
|
+
or contributory patent infringement, then any patent licenses
|
|
86
|
+
granted to You under this License for that Work shall terminate
|
|
87
|
+
as of the date such litigation is filed.
|
|
88
|
+
|
|
89
|
+
4. Redistribution. You may reproduce and distribute copies of the
|
|
90
|
+
Work or Derivative Works thereof in any medium, with or without
|
|
91
|
+
modifications, and in Source or Object form, provided that You
|
|
92
|
+
meet the following conditions:
|
|
93
|
+
|
|
94
|
+
(a) You must give any other recipients of the Work or
|
|
95
|
+
Derivative Works a copy of this License; and
|
|
96
|
+
|
|
97
|
+
(b) You must cause any modified files to carry prominent notices
|
|
98
|
+
stating that You changed the files; and
|
|
99
|
+
|
|
100
|
+
(c) You must retain, in the Source form of any Derivative Works
|
|
101
|
+
that You distribute, all copyright, patent, trademark, and
|
|
102
|
+
attribution notices from the Source form of the Work,
|
|
103
|
+
excluding those notices that do not pertain to any part of
|
|
104
|
+
the Derivative Works; and
|
|
105
|
+
|
|
106
|
+
(d) If the Work includes a "NOTICE" text file as part of its
|
|
107
|
+
distribution, then any Derivative Works that You distribute must
|
|
108
|
+
include a readable copy of the attribution notices contained
|
|
109
|
+
within such NOTICE file, excluding any notices that do not
|
|
110
|
+
pertain to any part of the Derivative Works, in at least one
|
|
111
|
+
of the following places: within a NOTICE text file distributed
|
|
112
|
+
as part of the Derivative Works; within the Source form or
|
|
113
|
+
documentation, if provided along with the Derivative Works; or,
|
|
114
|
+
within a display generated by the Derivative Works, if and
|
|
115
|
+
wherever such third-party notices normally appear. The contents
|
|
116
|
+
of the NOTICE file are for informational purposes only and
|
|
117
|
+
do not modify the License. You may add Your own attribution
|
|
118
|
+
notices within Derivative Works that You distribute, alongside
|
|
119
|
+
or as an addendum to the NOTICE text from the Work, provided
|
|
120
|
+
that such additional attribution notices cannot be construed
|
|
121
|
+
as modifying the License.
|
|
122
|
+
|
|
123
|
+
You may add Your own copyright statement to Your modifications and
|
|
124
|
+
may provide additional or different license terms and conditions
|
|
125
|
+
for use, reproduction, or distribution of Your modifications, or
|
|
126
|
+
for any such Derivative Works as a whole, provided Your use,
|
|
127
|
+
reproduction, and distribution of the Work otherwise complies with
|
|
128
|
+
the conditions stated in this License.
|
|
129
|
+
|
|
130
|
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
|
131
|
+
any Contribution intentionally submitted for inclusion in the Work
|
|
132
|
+
by You to the Licensor shall be under the terms and conditions of
|
|
133
|
+
this License, without any additional terms or conditions.
|
|
134
|
+
Notwithstanding the above, nothing herein shall supersede or modify
|
|
135
|
+
the terms of any separate license agreement you may have executed
|
|
136
|
+
with Licensor regarding such Contributions.
|
|
137
|
+
|
|
138
|
+
6. Trademarks. This License does not grant permission to use the trade
|
|
139
|
+
names, trademarks, service marks, or product names of the Licensor,
|
|
140
|
+
except as required for reasonable and customary use in describing the
|
|
141
|
+
origin of the Work and reproducing the content of the NOTICE file.
|
|
142
|
+
|
|
143
|
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
|
144
|
+
agreed to in writing, Licensor provides the Work (and each
|
|
145
|
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
|
146
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
|
147
|
+
implied, including, without limitation, any warranties or conditions
|
|
148
|
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
|
149
|
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
|
150
|
+
appropriateness of using or redistributing the Work and assume any
|
|
151
|
+
risks associated with Your exercise of permissions under this License.
|
|
152
|
+
|
|
153
|
+
8. Limitation of Liability. In no event and under no legal theory,
|
|
154
|
+
whether in tort (including negligence), contract, or otherwise,
|
|
155
|
+
unless required by applicable law (such as deliberate and grossly
|
|
156
|
+
negligent acts) or agreed to in writing, shall any Contributor be
|
|
157
|
+
liable to You for damages, including any direct, indirect, special,
|
|
158
|
+
incidental, or consequential damages of any character arising as a
|
|
159
|
+
result of this License or out of the use or inability to use the
|
|
160
|
+
Work (including but not limited to damages for loss of goodwill,
|
|
161
|
+
work stoppage, computer failure or malfunction, or any and all
|
|
162
|
+
other commercial damages or losses), even if such Contributor
|
|
163
|
+
has been advised of the possibility of such damages.
|
|
164
|
+
|
|
165
|
+
9. Accepting Warranty or Additional Liability. While redistributing
|
|
166
|
+
the Work or Derivative Works thereof, You may choose to offer,
|
|
167
|
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
|
168
|
+
or other liability obligations and/or rights consistent with this
|
|
169
|
+
License. However, in accepting such obligations, You may act only
|
|
170
|
+
on Your own behalf and on Your sole responsibility, not on behalf
|
|
171
|
+
of any other Contributor, and only if You agree to indemnify,
|
|
172
|
+
defend, and hold each Contributor harmless for any liability
|
|
173
|
+
incurred by, or claims asserted against, such Contributor by reason
|
|
174
|
+
of your accepting any such warranty or additional liability.
|
|
175
|
+
|
|
176
|
+
END OF TERMS AND CONDITIONS
|
|
177
|
+
|
|
178
|
+
Copyright 2026 Yonghye Kwon
|
|
179
|
+
|
|
180
|
+
Licensed under the Apache License, Version 2.0 (the "License");
|
|
181
|
+
you may not use this file except in compliance with the License.
|
|
182
|
+
You may obtain a copy of the License at
|
|
183
|
+
|
|
184
|
+
http://www.apache.org/licenses/LICENSE-2.0
|
|
185
|
+
|
|
186
|
+
Unless required by applicable law or agreed to in writing, software
|
|
187
|
+
distributed under the License is distributed on an "AS IS" BASIS,
|
|
188
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
|
189
|
+
See the License for the specific language governing permissions and
|
|
190
|
+
limitations under the License.
|
|
@@ -0,0 +1,10 @@
|
|
|
1
|
+
include CHANGELOG.md CITATION.cff CONTRIBUTING.md LICENSE README.md
|
|
2
|
+
recursive-include src/llmperfscope/native *.c
|
|
3
|
+
recursive-include tests *.py
|
|
4
|
+
recursive-include docs *.md
|
|
5
|
+
include examples/*.py examples/*.json
|
|
6
|
+
global-exclude *.pyc *.so
|
|
7
|
+
prune examples/sample-runs
|
|
8
|
+
prune docs/gallery
|
|
9
|
+
# It checks links into what the two lines above leave out.
|
|
10
|
+
exclude tests/test_docs.py
|
|
@@ -0,0 +1,207 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: llmperfscope
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Whole-lifecycle profiler for LLM inference engines: load, warmup, prefill, decode, serving and teardown; speed, memory and energy. Works with any engine, needs no code changes.
|
|
5
|
+
Author: Yonghye Kwon
|
|
6
|
+
License-Expression: Apache-2.0
|
|
7
|
+
Project-URL: Homepage, https://github.com/developer0hye/llmperfscope
|
|
8
|
+
Project-URL: Documentation, https://github.com/developer0hye/llmperfscope/tree/main/docs
|
|
9
|
+
Project-URL: Issues, https://github.com/developer0hye/llmperfscope/issues
|
|
10
|
+
Project-URL: Changelog, https://github.com/developer0hye/llmperfscope/blob/main/CHANGELOG.md
|
|
11
|
+
Keywords: llm,profiler,inference,performance,gpu,llama.cpp,vllm,sglang,benchmark,bottleneck
|
|
12
|
+
Classifier: Development Status :: 4 - Beta
|
|
13
|
+
Classifier: Environment :: Console
|
|
14
|
+
Classifier: Intended Audience :: Developers
|
|
15
|
+
Classifier: Intended Audience :: Science/Research
|
|
16
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
17
|
+
Classifier: Programming Language :: Python :: 3
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.9
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
22
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
23
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
24
|
+
Classifier: Topic :: Software Development :: Testing
|
|
25
|
+
Classifier: Topic :: System :: Benchmark
|
|
26
|
+
Requires-Python: >=3.9
|
|
27
|
+
Description-Content-Type: text/markdown
|
|
28
|
+
License-File: LICENSE
|
|
29
|
+
Provides-Extra: figures
|
|
30
|
+
Requires-Dist: matplotlib>=3.7; extra == "figures"
|
|
31
|
+
Dynamic: license-file
|
|
32
|
+
|
|
33
|
+
# llmperfscope
|
|
34
|
+
|
|
35
|
+
[](https://pypi.org/project/llmperfscope/)
|
|
36
|
+
[](https://github.com/developer0hye/llmperfscope/actions/workflows/tests.yml)
|
|
37
|
+
[](https://github.com/developer0hye/llmperfscope/blob/main/LICENSE)
|
|
38
|
+
|
|
39
|
+
Tells you what limits an LLM engine, where its memory goes, and how its data moves between disk, RAM, CPU and GPU, over its whole life: load, warmup, prefill, decode, serving and shutdown.
|
|
40
|
+
|
|
41
|
+
It works with any engine and needs no code changes. Put it in front of the command you already run:
|
|
42
|
+
|
|
43
|
+
```sh
|
|
44
|
+
pip install llmperfscope
|
|
45
|
+
llmperfscope run -- llama-bench -m model.gguf -ngl 0 -lm mmap
|
|
46
|
+
```
|
|
47
|
+
|
|
48
|
+
Here is a 0.6 GiB model on the CPU with 450 MiB of RAM, from [a real run](https://github.com/developer0hye/llmperfscope/tree/main/examples/sample-runs/cpu-ram-limited):
|
|
49
|
+
|
|
50
|
+
```
|
|
51
|
+
## What limits each phase
|
|
52
|
+
|
|
53
|
+
| phase | limit | confidence | why |
|
|
54
|
+
|--------|-------|------------|-----------------------------------------------------------------------------------------------------------|
|
|
55
|
+
| decode | ram | high | Host RAM is short: 333 MiB/s of file pages dropped and read again, tasks stalled on memory 13% of the time. |
|
|
56
|
+
|
|
57
|
+
## Data movement findings
|
|
58
|
+
|
|
59
|
+
- **warning**: 18.79 GiB read from disk and 49,217 major page faults during decode. The weights or cache are not staying in RAM:
|
|
60
|
+
evicted pages, mmap of tensors used on the CPU, or an engine offloading to disk.
|
|
61
|
+
- Load read 0.64 GiB from sda (hdd) at 878 MiB/s; 0% of the model was cached before the run.
|
|
62
|
+
```
|
|
63
|
+
|
|
64
|
+
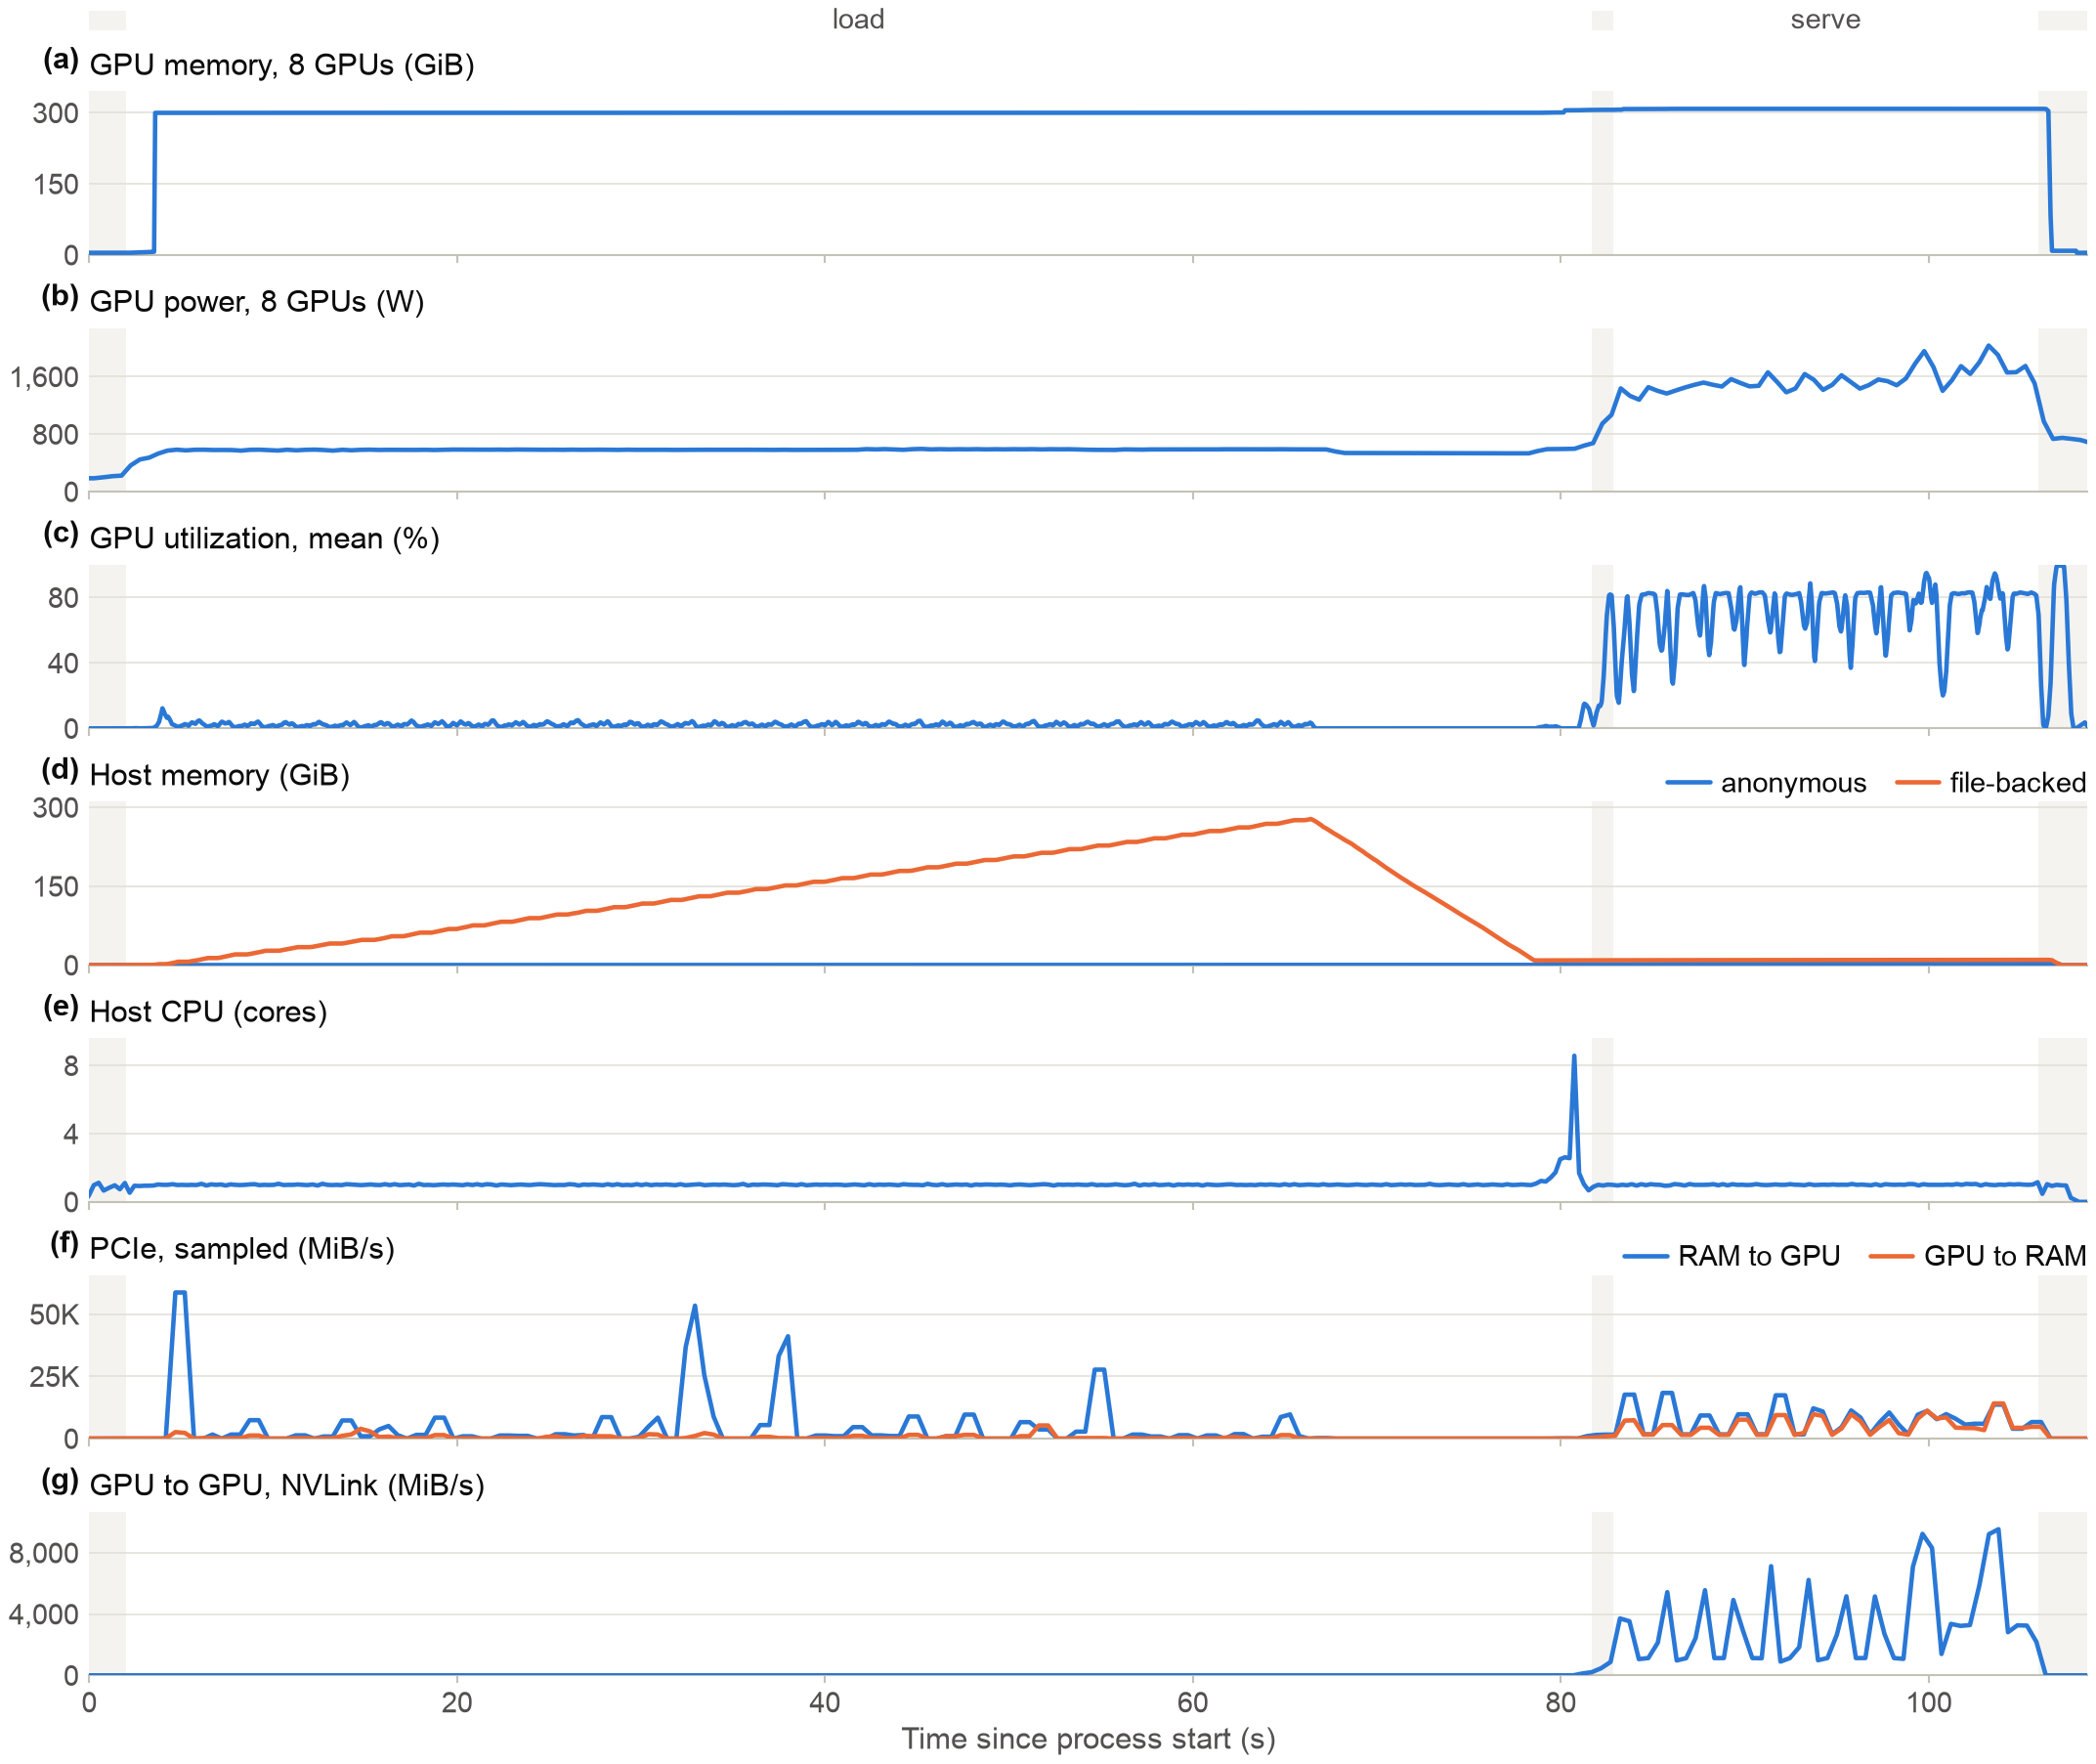
Each run also writes `report.html` with every counter on one time axis, `run.json` with all the numbers, and, on request, figures ready for a paper:
|
|
65
|
+
|
|
66
|
+
|
|
67
|
+
|
|
68
|
+
## Install
|
|
69
|
+
|
|
70
|
+
```sh
|
|
71
|
+
pip install llmperfscope # no dependencies
|
|
72
|
+
pip install "llmperfscope[figures]" # adds matplotlib, for paper figures
|
|
73
|
+
llmperfscope check # what can be measured on this machine
|
|
74
|
+
```
|
|
75
|
+
|
|
76
|
+
Measuring needs Linux and Python 3.9 or newer. GPU telemetry needs an NVIDIA driver; without one you still get phases, host memory, CPU and disk. A C compiler is needed only for `--cpu-profile`.
|
|
77
|
+
|
|
78
|
+
## Use it with your engine
|
|
79
|
+
|
|
80
|
+
Servers are started, loaded, stopped and measured in one command. llmperfscope finds the port, waits until the server is ready, sends streaming requests and reads its metrics.
|
|
81
|
+
|
|
82
|
+
```sh
|
|
83
|
+
llmperfscope serve -- llama-server -m model.gguf -ngl 99
|
|
84
|
+
llmperfscope serve -- vllm serve Qwen/Qwen3-0.6B
|
|
85
|
+
llmperfscope serve -- python -m sglang.launch_server --model-path Qwen/Qwen3-0.6B
|
|
86
|
+
llmperfscope serve -- text-generation-launcher --model-id Qwen/Qwen3-0.6B
|
|
87
|
+
llmperfscope serve --model qwen2.5:0.5b --pull -- ollama serve
|
|
88
|
+
|
|
89
|
+
# Containers work the same way. llmperfscope follows the engine inside, not the docker client.
|
|
90
|
+
llmperfscope serve -- docker run --gpus all -p 8000:8000 vllm/vllm-openai --model Qwen/Qwen3-0.6B
|
|
91
|
+
```
|
|
92
|
+
|
|
93
|
+
Choose the load with `--prompts file.jsonl`, `--concurrency 1,4,8` and `--max-tokens 64`. Any other OpenAI-compatible server works with `--preset openai --url http://host:port`, and something already running with `llmperfscope attach`.
|
|
94
|
+
|
|
95
|
+
An engine used as a library takes a wrapper and, optionally, a few markers. They do nothing when no profiler is running:
|
|
96
|
+
|
|
97
|
+
```python
|
|
98
|
+
import llmperfscope
|
|
99
|
+
|
|
100
|
+
with llmperfscope.phase("load"):
|
|
101
|
+
model = AutoModelForCausalLM.from_pretrained(name, device_map="auto")
|
|
102
|
+
|
|
103
|
+
timer = llmperfscope.TokenTimer()
|
|
104
|
+
with llmperfscope.phase("decode", tokens=128):
|
|
105
|
+
model.generate(**inputs, max_new_tokens=128, streamer=timer)
|
|
106
|
+
print(timer.summary())
|
|
107
|
+
```
|
|
108
|
+
|
|
109
|
+
```sh
|
|
110
|
+
llmperfscope run -- python script.py
|
|
111
|
+
```
|
|
112
|
+
|
|
113
|
+
Any other program can mark phases from any language, with no dependency:
|
|
114
|
+
|
|
115
|
+
```sh
|
|
116
|
+
llmperfscope run --mark 'Model loaded=decode' -- my-engine # a line in its output starts a phase
|
|
117
|
+
echo decode >> "$LLMPERFSCOPE_MARKERS" # or append to this file
|
|
118
|
+
```
|
|
119
|
+
|
|
120
|
+
Tested end to end with llama.cpp (`llama-bench`, `llama-server`), vLLM 0.32.0 (server and library), SGLang 0.5.22, Text Generation Inference 3.3.7, Ollama 0.40.9 and transformers. See [the engine notes](https://github.com/developer0hye/llmperfscope/blob/main/docs/engines.md).
|
|
121
|
+
|
|
122
|
+
## What it answers
|
|
123
|
+
|
|
124
|
+
**What limits this phase?** Each phase gets one verdict with the numbers behind it: `gpu`, `gpu (throttled)`, `gpu imbalance`, `gpu + host wait`, `cpu (one thread)`, `cpu (many threads)`, `cpu contention`, `disk (nvme|ssd|hdd)`, `ram`. It rests on the kernel's pressure stall counters, GPU utilization history, per-thread CPU time and disk activity. A phase too short for these counters is reported as too short.
|
|
125
|
+
|
|
126
|
+
**Is memory being overused?** llmperfscope reports GPU memory per device and per process, host memory split into anonymous and file-backed, swap, and the engine's own breakdown where it gives one. It flags:
|
|
127
|
+
|
|
128
|
+
- a GPU or the host running out of headroom
|
|
129
|
+
- a transient peak that decides what fits
|
|
130
|
+
- host memory that keeps growing, as a leak would
|
|
131
|
+
- weights held in RAM next to their GPU copy
|
|
132
|
+
- PyTorch reserving far more than its tensors use, and cache pools that are mostly unused
|
|
133
|
+
- GPUs filled unevenly
|
|
134
|
+
|
|
135
|
+
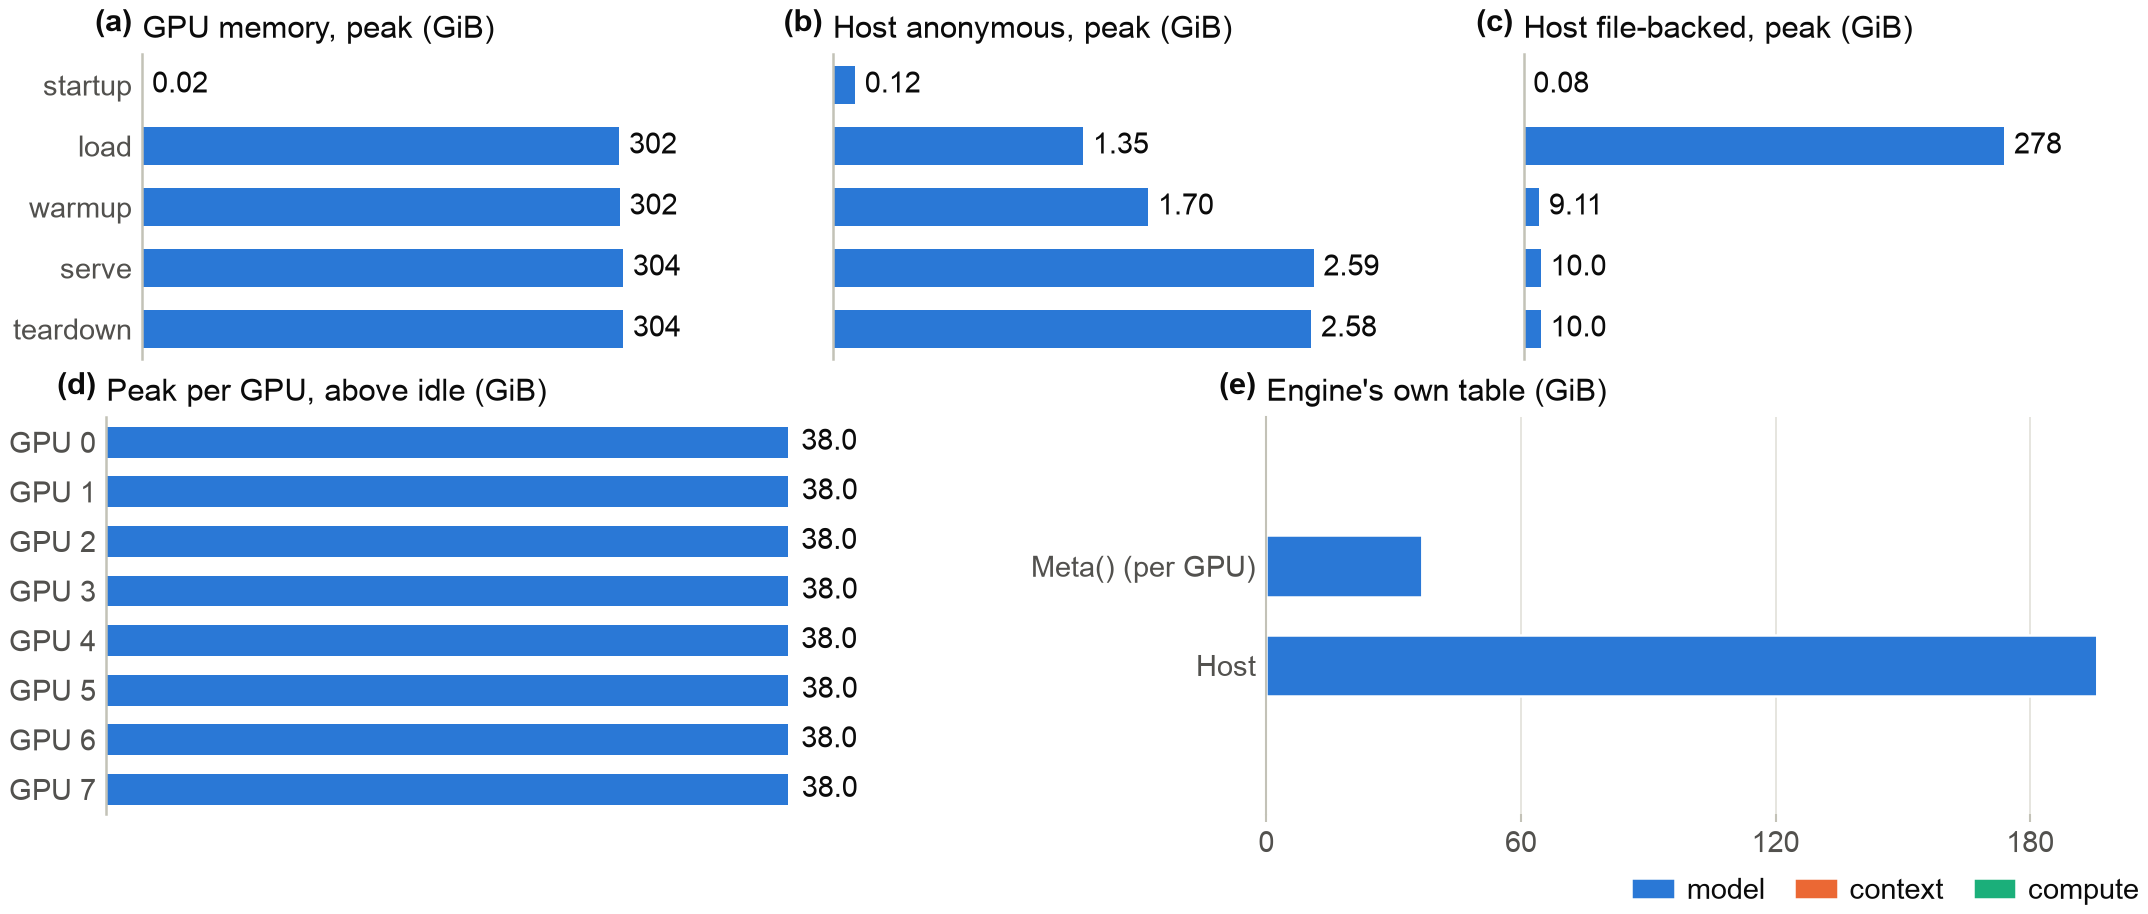
**Where does data travel?** Per phase: bytes read and written per disk, with NVMe, SSD and HDD told apart; swap in and out; page cache changes and refaults; major page faults; RAM to GPU and back over PCIe; GPU to GPU over NVLink. Reads from disk during inference are flagged, because they mean the weights are not staying in RAM. `--cold-start` drops the model from the page cache first, without root, so a load can be measured as a user's first run would see it.
|
|
136
|
+
|
|
137
|
+
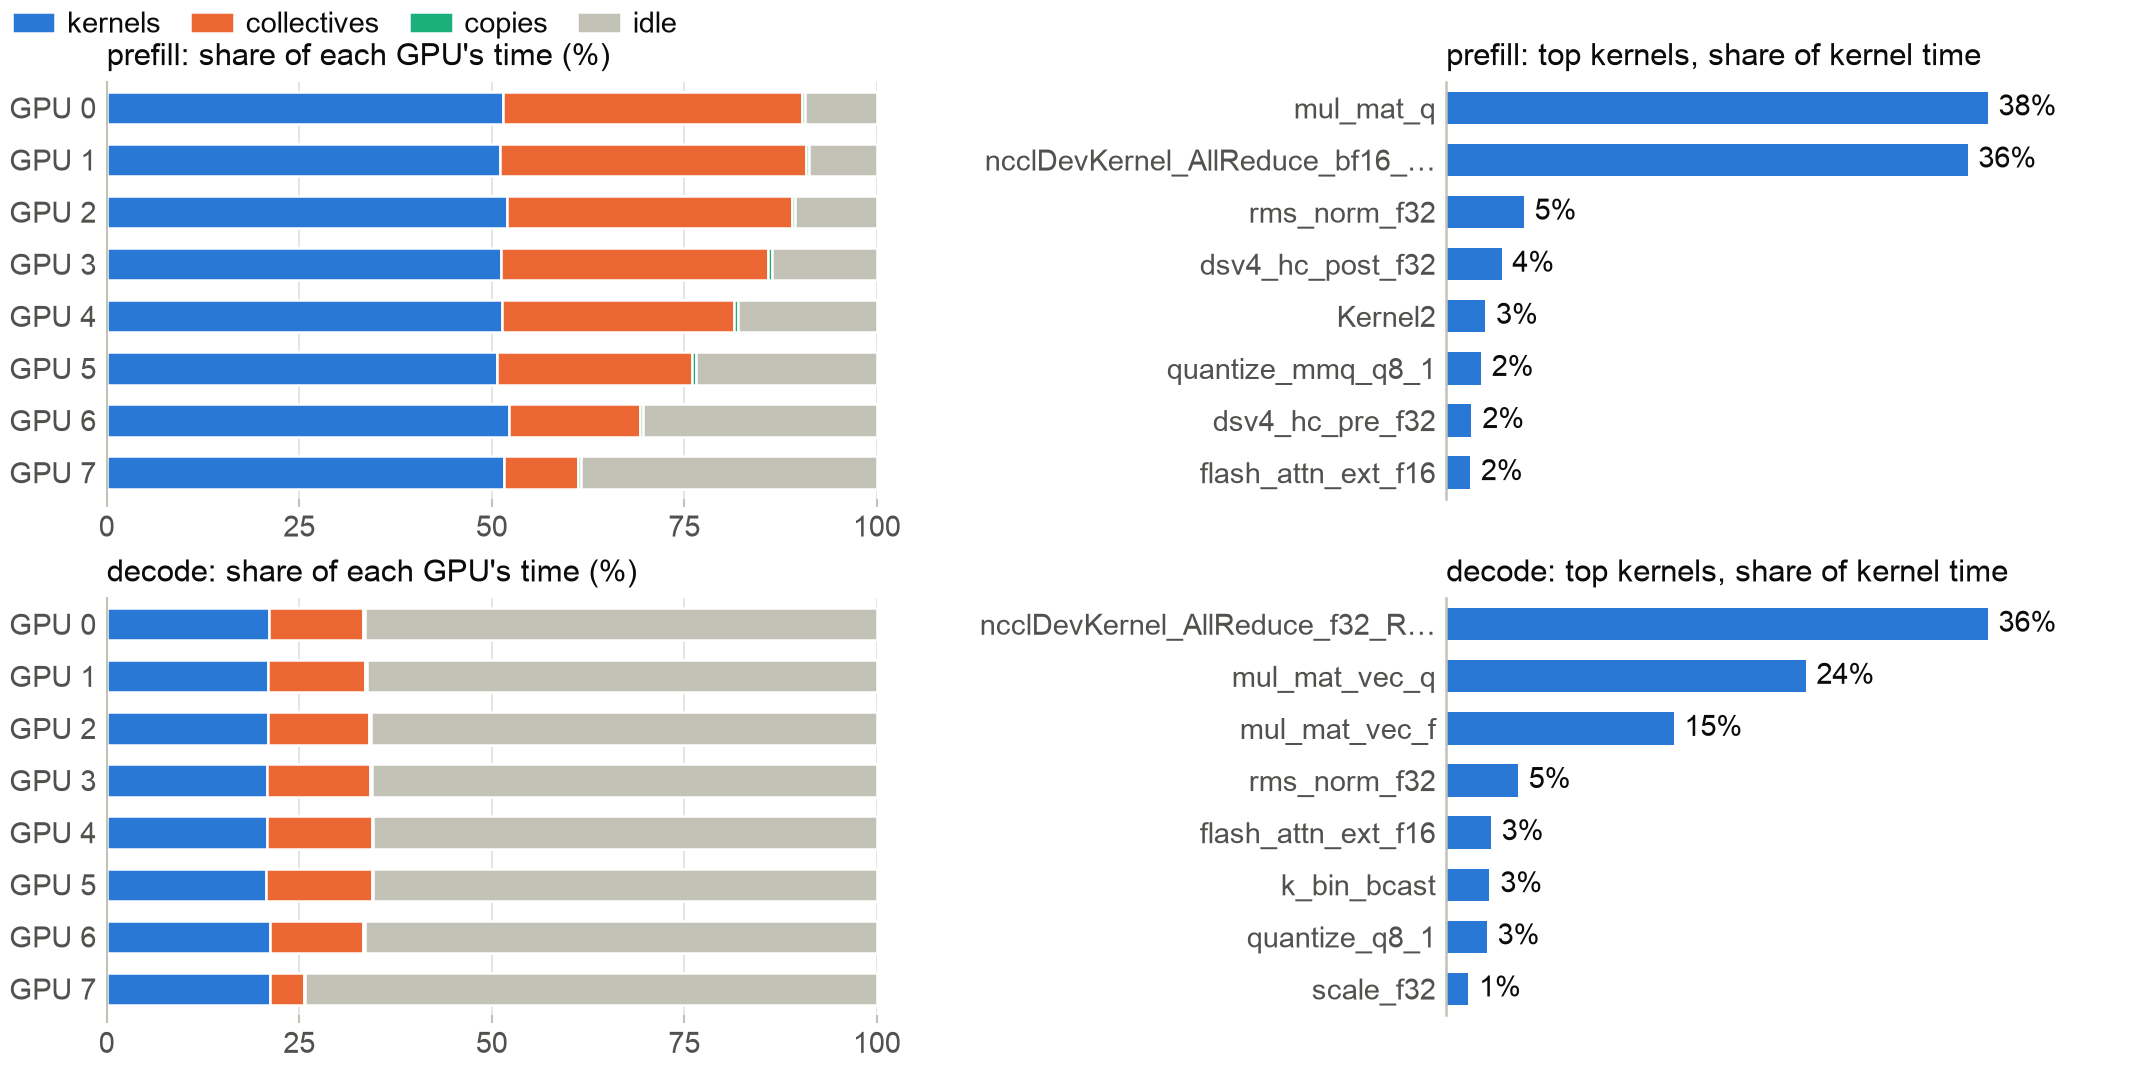
**Where does the GPU's time go?** Add `--nsys` for kernels, collectives, copies and idle gaps per phase and per token, the host's time in CUDA calls, and exact bytes copied. Add `--cpu-profile` for the hot functions of the host threads. It samples from inside the process, so it works where `perf` is not allowed. Both slow the engine down, so those runs are marked and never counted as speed results.
|
|
138
|
+
|
|
139
|
+
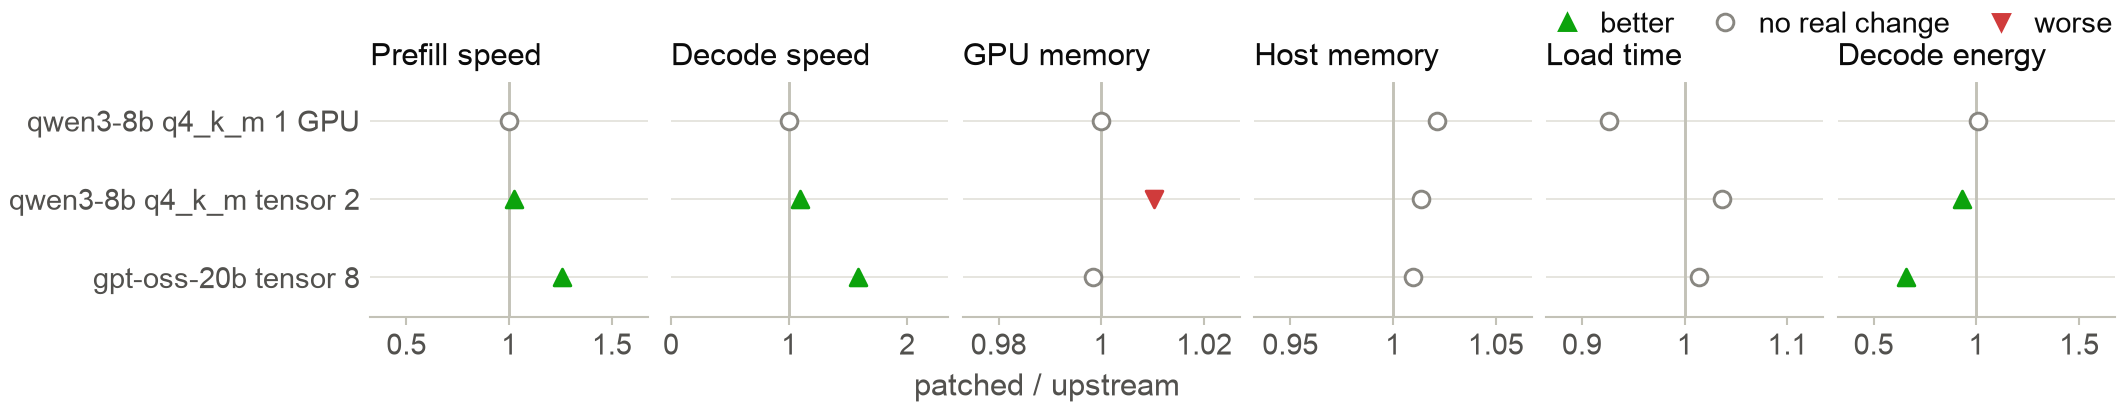
**What did a change cost?** `llmperfscope matrix` runs two builds in alternating order across many cases, in fresh processes, re-checking the machine before each arm. It judges speed, memory, load time and energy together, so a speed win that costs memory shows up as a regression. A difference counts only if the arms do not overlap and it exceeds the noise floor. Measure that floor with the same binary on both sides.
|
|
140
|
+
|
|
141
|
+
```sh
|
|
142
|
+
llmperfscope matrix --cases cases.json --a old=build-old/bin --b new=build-new/bin --out res
|
|
143
|
+
```
|
|
144
|
+
|
|
145
|
+
## Figures for papers
|
|
146
|
+
|
|
147
|
+
```sh
|
|
148
|
+
llmperfscope figure RUN_DIR --width single --print-safe --out figures
|
|
149
|
+
```
|
|
150
|
+
|
|
151
|
+
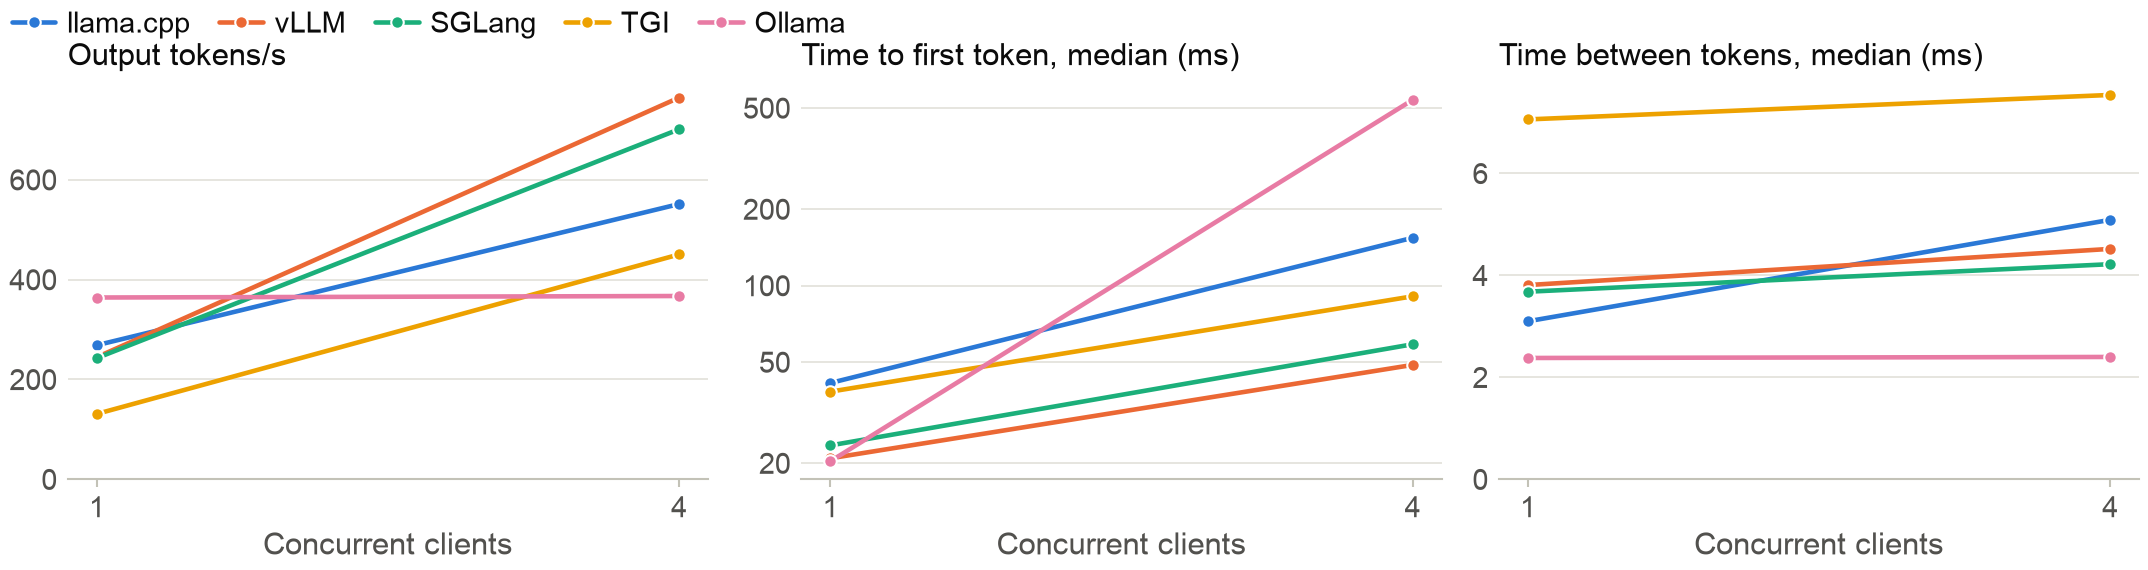
You get vector PDF with embedded TrueType fonts, editable SVG, 300 dpi PNG, the data behind each figure as CSV, and a suggested caption with the numbers filled in. Widths match common paper layouts, colors stay distinct under color vision deficiency, and the same run gives byte-identical PDF and SVG. `llmperfscope anonymize` makes a copy of a run with no host names or paths, to publish with the paper.
|
|
152
|
+
|
|
153
|
+
| | |
|
|
154
|
+
|---|---|
|
|
155
|
+
|  |  |
|
|
156
|
+
|  |  |
|
|
157
|
+
|
|
158
|
+
See [every figure and how to fit it to your venue](https://github.com/developer0hye/llmperfscope/blob/main/docs/figures.md). The runs behind these are [in the repository](https://github.com/developer0hye/llmperfscope/tree/main/examples/sample-runs), so you can try it with no GPU.
|
|
159
|
+
|
|
160
|
+
## Trusting the numbers
|
|
161
|
+
|
|
162
|
+
- **The tool's own cost is measured.** Sampling happens in another process, pinned away from the engine's CPUs when it can be. Speed with llmperfscope against without it, alternating fresh processes, 4 arms each of 10 repetitions, on 8 RTX A6000 (the same binary against itself varies by about 1% at 8 GPUs):
|
|
163
|
+
|
|
164
|
+
| Case | Prefill | Decode |
|
|
165
|
+
|---|---:|---:|
|
|
166
|
+
| Qwen3-30B-A3B Q8_0, 1 GPU | 1.00 | 1.00 |
|
|
167
|
+
| Qwen3-30B-A3B Q8_0, 8 GPUs, tensor split | 0.998 | 1.000 |
|
|
168
|
+
| DeepSeek-V4.1-Flash, 8 GPUs, tensor split | 1.001 | 1.001 |
|
|
169
|
+
|
|
170
|
+
- **Every run checks itself.** Phase times are compared with the engine's own timers where it has them; it was 1.000 to 1.001 in the runs above. Power from the energy counter is compared with the power gauge, because the counter was caught under-reporting by half when read too often; llmperfscope reads it about twice a second, and a large disagreement is called out in the report.
|
|
171
|
+
- **Known answers.** The RAM-limited run above took decode from 73.9 to 2.5 tokens/s, and the report named `ram`. GPU memory from NVML matched llama.cpp's own table to within driver overhead. GPU kernel times matched a separately written analysis of the same trace.
|
|
172
|
+
- **Every run stores its context.** That means foreign CPU and GPU load, the page cache state of the model, the storage it lives on, binary hashes, the git commit and relevant environment variables. Runs on a busy machine are flagged, and `--precheck wait` waits for it to go quiet.
|
|
173
|
+
- **Hung runs stop.** A collective that spins forever looks busy to every utilization counter, so progress means output or resource changes. A stalled run is killed with a report of what its threads were doing.
|
|
174
|
+
- **Credentials stay out.** Tokens and keys in the command line and environment are never written to the report.
|
|
175
|
+
|
|
176
|
+
The test suite runs real processes with known behaviour and checks that the report says what happened: `cd tests && python3 -m unittest`. See [how it was validated](https://github.com/developer0hye/llmperfscope/blob/main/docs/validation.md), including the mistakes it has already made.
|
|
177
|
+
|
|
178
|
+
## Limits
|
|
179
|
+
|
|
180
|
+
- Linux only for measuring. GPU telemetry is NVIDIA only for now ([other vendors can plug in](https://github.com/developer0hye/llmperfscope/blob/main/docs/adapters.md)); without it you still get host metrics and phases.
|
|
181
|
+
- GPU hardware counters such as cache hit rates need admin rights (`RmProfilingAdminOnly=0`). llmperfscope does not read them yet.
|
|
182
|
+
- Memory bandwidth on the host is not visible without privileges.
|
|
183
|
+
- PCIe traffic is a sample, not a count. Use `--nsys` for exact copy bytes.
|
|
184
|
+
- System-wide counters (disks, swap, pressure) include other processes. On a shared machine, trust the per-process columns.
|
|
185
|
+
- NVML's GPU utilization needs about a second to mean anything, which is why short phases are not judged.
|
|
186
|
+
|
|
187
|
+
## Documentation
|
|
188
|
+
|
|
189
|
+
| | |
|
|
190
|
+
|---|---|
|
|
191
|
+
| [Quickstart](https://github.com/developer0hye/llmperfscope/blob/main/docs/quickstart.md) | install, first run, which command to use |
|
|
192
|
+
| [Engines](https://github.com/developer0hye/llmperfscope/blob/main/docs/engines.md) | llama.cpp, vLLM, SGLang, TGI, Ollama, transformers, containers, any other program |
|
|
193
|
+
| [Reading a report](https://github.com/developer0hye/llmperfscope/blob/main/docs/reading-reports.md) | every verdict and finding, and what to do about it |
|
|
194
|
+
| [Figures](https://github.com/developer0hye/llmperfscope/blob/main/docs/figures.md) | paper figures, sizes, fonts, captions, checklist |
|
|
195
|
+
| [Comparing](https://github.com/developer0hye/llmperfscope/blob/main/docs/comparing.md) | A/B runs, noise floors, what counts as a real difference |
|
|
196
|
+
| [Going deeper](https://github.com/developer0hye/llmperfscope/blob/main/docs/deep-dives.md) | `--nsys`, `--cpu-profile`, `--cold-start` |
|
|
197
|
+
| [Run data](https://github.com/developer0hye/llmperfscope/blob/main/docs/run-json.md) | `run.json`, samples and requests, for your own analysis |
|
|
198
|
+
| [Adding an engine](https://github.com/developer0hye/llmperfscope/blob/main/docs/adapters.md) | presets, adapters, GPU backends |
|
|
199
|
+
| [Validation](https://github.com/developer0hye/llmperfscope/blob/main/docs/validation.md) | overhead, known answers, limits |
|
|
200
|
+
|
|
201
|
+
## Citing
|
|
202
|
+
|
|
203
|
+
If llmperfscope helps your work, please cite it. GitHub's "Cite this repository" button gives BibTeX from [CITATION.cff](https://github.com/developer0hye/llmperfscope/blob/main/CITATION.cff).
|
|
204
|
+
|
|
205
|
+
## License
|
|
206
|
+
|
|
207
|
+
Apache-2.0
|