lifekeeper 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- lifekeeper-0.1.0/LICENSE +21 -0
- lifekeeper-0.1.0/PKG-INFO +44 -0
- lifekeeper-0.1.0/README.md +113 -0
- lifekeeper-0.1.0/docs/pypi.md +18 -0
- lifekeeper-0.1.0/lifekeeper.egg-info/PKG-INFO +44 -0
- lifekeeper-0.1.0/lifekeeper.egg-info/SOURCES.txt +24 -0
- lifekeeper-0.1.0/lifekeeper.egg-info/dependency_links.txt +1 -0
- lifekeeper-0.1.0/lifekeeper.egg-info/entry_points.txt +7 -0
- lifekeeper-0.1.0/lifekeeper.egg-info/requires.txt +11 -0
- lifekeeper-0.1.0/lifekeeper.egg-info/top_level.txt +1 -0
- lifekeeper-0.1.0/pyproject.toml +44 -0
- lifekeeper-0.1.0/setup.cfg +4 -0
- lifekeeper-0.1.0/tests/test_ask.py +199 -0
- lifekeeper-0.1.0/tests/test_faces.py +75 -0
- lifekeeper-0.1.0/tests/test_little_data.py +95 -0
- lifekeeper-0.1.0/tests/test_page.py +342 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/__init__.py +3 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/app.py +342 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/ask.py +410 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/cities.tsv.gz +0 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/faces.py +287 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/icon.ico +0 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/icon_data.py +80 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/lifekeeper.py +1243 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/places.py +179 -0
- lifekeeper-0.1.0/toolkit/lifekeeper/webui.py +234 -0
lifekeeper-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Claudia Kitova
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,44 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: lifekeeper
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Reclaim your data: one page of your life from your photos, chats and posts, and answers from your own records.
|
|
5
|
+
Author: Claudia Kitova
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/claudiakitova/lifekeeper
|
|
8
|
+
Project-URL: Source, https://github.com/claudiakitova/lifekeeper
|
|
9
|
+
Keywords: life archive,personal data,data export,timeline,google takeout,local-first,digital twin
|
|
10
|
+
Classifier: Programming Language :: Python :: 3
|
|
11
|
+
Classifier: Operating System :: OS Independent
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Topic :: Utilities
|
|
14
|
+
Requires-Python: >=3.10
|
|
15
|
+
Description-Content-Type: text/markdown
|
|
16
|
+
License-File: LICENSE
|
|
17
|
+
Provides-Extra: photos
|
|
18
|
+
Requires-Dist: pillow>=10; extra == "photos"
|
|
19
|
+
Provides-Extra: app
|
|
20
|
+
Requires-Dist: pywebview>=5; extra == "app"
|
|
21
|
+
Provides-Extra: faces
|
|
22
|
+
Requires-Dist: opencv-python-headless>=4.8; extra == "faces"
|
|
23
|
+
Requires-Dist: numpy>=1.24; extra == "faces"
|
|
24
|
+
Requires-Dist: pillow>=10; extra == "faces"
|
|
25
|
+
Dynamic: license-file
|
|
26
|
+
|
|
27
|
+
<img src="https://raw.githubusercontent.com/claudiakitova/lifekeeper/main/docs/images/lockup.svg" alt="Lifekeeper" width="320">
|
|
28
|
+
|
|
29
|
+
Reclaim your data and start your digital self: everything about you in one place, on your own computer
|
|
30
|
+
|
|
31
|
+
Lifekeeper reads the exports you already have (phone photos, Telegram, WhatsApp, Instagram, Facebook, X, Google Takeout, Spotify, Netflix, Goodreads, LinkedIn, calendars, mood diaries and more) and writes one page of your life, year by year and month by month. Then you can ask questions about your life and get answers from your own records, with the records shown.
|
|
32
|
+
|
|
33
|
+
```
|
|
34
|
+
pipx install "lifekeeper[photos,app,faces]"
|
|
35
|
+
lifekeeper path/to/your/exports --out my-life.html
|
|
36
|
+
lifekeeper-ask path/to/your/exports "When did I meet Leo?"
|
|
37
|
+
lifekeeper-app
|
|
38
|
+
```
|
|
39
|
+
|
|
40
|
+
Making the page sends nothing anywhere. Answers use no AI by default; you can choose a model on your own computer (Ollama) or Google Gemini with your own key.
|
|
41
|
+
|
|
42
|
+
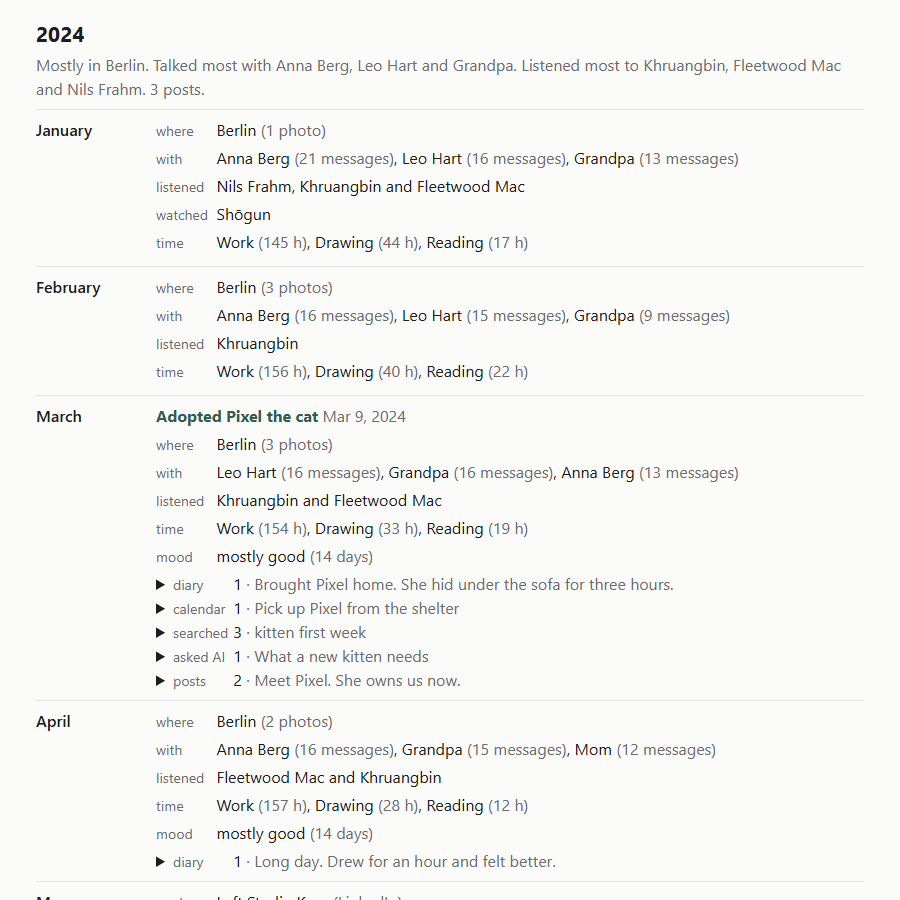
|
|
43
|
+
|
|
44
|
+
The method, the download guides for each service, and the double-click apps for Windows and Mac: https://github.com/claudiakitova/lifekeeper
|
|
@@ -0,0 +1,113 @@
|
|
|
1
|
+
<p align="center">
|
|
2
|
+
<picture>
|
|
3
|
+
<source media="(prefers-color-scheme: dark)" srcset="docs/images/lockup-dark.svg">
|
|
4
|
+
<img src="docs/images/lockup.svg" alt="Lifekeeper" width="380">
|
|
5
|
+
</picture>
|
|
6
|
+
</p>
|
|
7
|
+
|
|
8
|
+
<h3 align="center">Reclaim your data and start your digital self: everything about you in one place, on your own computer</h3>
|
|
9
|
+
|
|
10
|
+
<p align="center">
|
|
11
|
+
<a href="https://github.com/claudiakitova/lifekeeper/actions/workflows/tests.yml"><img src="https://github.com/claudiakitova/lifekeeper/actions/workflows/tests.yml/badge.svg" alt="Tests"></a>
|
|
12
|
+
<a href="https://github.com/claudiakitova/lifekeeper/releases/latest"><img src="https://img.shields.io/github/v/release/claudiakitova/lifekeeper?label=release" alt="Latest release"></a>
|
|
13
|
+
<a href="LICENSE"><img src="https://img.shields.io/github/license/claudiakitova/lifekeeper" alt="MIT license"></a>
|
|
14
|
+
</p>
|
|
15
|
+
|
|
16
|
+
Your photos, chats and posts are held by a dozen companies, and you only see them through their apps. Lifekeeper is how you take them back and put them together into one archive that you own and can read, search and correct.
|
|
17
|
+
|
|
18
|
+

|
|
19
|
+
|
|
20
|
+
## Make your page
|
|
21
|
+
|
|
22
|
+
Lifekeeper reads a folder of exports and writes one HTML page: your life by year and month, with where you were, who you talked to, and what you posted, listened to, read and watched. This part works offline and sends nothing anywhere.
|
|
23
|
+
|
|
24
|
+
It reads photos, Telegram, WhatsApp, Messenger and Instagram chats, Android texts, sent Gmail, Google location history, Facebook, Instagram and X posts, Instagram stories, your comments, calendars, Google Keep, LinkedIn, Spotify, YouTube, Netflix, Goodreads, Google searches, ChatGPT chats, time trackers, mood diaries, Flo, and notes you write yourself. Zips can stay zipped. [Details](toolkit/lifekeeper/).
|
|
25
|
+
|
|
26
|
+
### The app (Windows, Mac)
|
|
27
|
+
|
|
28
|
+
1. Download it from [Releases](https://github.com/claudiakitova/lifekeeper/releases) and unzip.
|
|
29
|
+
2. Double-click it, choose the folder with your exports, and press "Make my page".
|
|
30
|
+
3. The page opens in your browser.
|
|
31
|
+
4. To ask a question about your life, type it in the same window.
|
|
32
|
+
|
|
33
|
+
The app isn't signed, so the first time your computer asks before running it:
|
|
34
|
+
- Windows: "Windows protected your PC" → **More info** → **Run anyway**.
|
|
35
|
+
- Mac: right-click the app → **Open** → **Open**.
|
|
36
|
+
|
|
37
|
+
### The script
|
|
38
|
+
|
|
39
|
+
Install it with [pipx](https://pipx.pypa.io) (Python 3.10 or newer):
|
|
40
|
+
|
|
41
|
+
```
|
|
42
|
+
pipx install "lifekeeper[photos,app,faces]"
|
|
43
|
+
lifekeeper path/to/your/exports --out my-life.html
|
|
44
|
+
lifekeeper-ask path/to/your/exports "When did I meet Leo?"
|
|
45
|
+
lifekeeper-app # the window
|
|
46
|
+
lifekeeper-faces scan path/to/your/exports # find the people in your photos
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
Or run it from a copy of this repository. It needs Python 3.10 or newer. Pillow is optional (`pip install pillow`); with it, Lifekeeper reads the dates and places stored inside photos.
|
|
50
|
+
|
|
51
|
+
Try it on the made-up [demo](demo/) data:
|
|
52
|
+
|
|
53
|
+
```
|
|
54
|
+
python toolkit/lifekeeper/lifekeeper.py demo/exports --out demo/life.html
|
|
55
|
+
```
|
|
56
|
+
|
|
57
|
+
Then on your own exports:
|
|
58
|
+
|
|
59
|
+
```
|
|
60
|
+
python toolkit/lifekeeper/lifekeeper.py path/to/your/exports --out my-life.html
|
|
61
|
+
```
|
|
62
|
+
|
|
63
|
+
## People in your photos
|
|
64
|
+
|
|
65
|
+
Lifekeeper can find the faces in your photos, group the same person across photos, and let you name each group once. After that, your page shows who is in your photos each month, and you can ask about them. It runs on your computer with OpenCV's face models; no photo leaves it. In the app, press **Find faces** after making your page. [Details](toolkit/lifekeeper/#people-in-your-photos).
|
|
66
|
+
|
|
67
|
+
## Places and trips
|
|
68
|
+
|
|
69
|
+
Photos with a location, and Google location history, are named by town, using [GeoNames](https://www.geonames.org/). Lifekeeper works out where home was each month and lists the trips away from it, with the places, days and photos. If it gets home wrong, write where you lived in `my_homes.csv`. [Details](toolkit/lifekeeper/#places-and-trips).
|
|
70
|
+
|
|
71
|
+
## Ask a question
|
|
72
|
+
|
|
73
|
+
Ask a question about your life and get an answer from your own records, with the records it used. In the app, type it under "Ask a question". With the script:
|
|
74
|
+
|
|
75
|
+
```
|
|
76
|
+
python toolkit/lifekeeper/ask.py path/to/your/exports "When did I meet Leo?"
|
|
77
|
+
```
|
|
78
|
+
|
|
79
|
+
With no AI, it shows the records that match, and nothing leaves your computer. For a written answer, add a model you choose: one on your own computer (`--ollama gemma3`) or Google Gemini with your own key (`--gemini`). Every sentence of an answer has to cite a record, and a sentence with a date or number that isn't in its records is left out. [Details](toolkit/lifekeeper/#ask-a-question).
|
|
80
|
+
|
|
81
|
+
## Getting your data
|
|
82
|
+
|
|
83
|
+
- [How to download it](docs/download-your-data/), step by step.
|
|
84
|
+
- [Every source I know of](docs/sources.md), and which ones Lifekeeper reads.
|
|
85
|
+
- [How much to collect](docs/collecting.md). An afternoon is enough to start.
|
|
86
|
+
|
|
87
|
+
## The method
|
|
88
|
+
|
|
89
|
+
- [The approach](docs/approach.md): ten steps, and what went wrong while I built a 20-year archive.
|
|
90
|
+
- [Start small](docs/start-small.md): a first week.
|
|
91
|
+
- [Privacy](docs/privacy.md) and [encrypted backup](docs/backup.md).
|
|
92
|
+
- [Readable on a hard day](docs/readable-on-a-hard-day.md): how I write pages so they're easy to read when I'm tired or unwell.
|
|
93
|
+
- [What it's useful for](docs/uses.md), including [memory loss](docs/memory-loss.md) (with sources).
|
|
94
|
+
- [Why not just give an AI access to my accounts?](docs/why-not-just-connect-ai.md)
|
|
95
|
+
- [Similar projects](docs/alternatives.md).
|
|
96
|
+
- [Claude Code skills](skills/) that build and review an archive with you.
|
|
97
|
+
|
|
98
|
+
## Rules I follow
|
|
99
|
+
|
|
100
|
+
1. Original files are never changed. Everything else is made from them and can be rebuilt.
|
|
101
|
+
2. What I say about my own life beats what a program worked out. My corrections survive every re-import.
|
|
102
|
+
3. Every fact links to the record it came from.
|
|
103
|
+
4. Pages use plain words and real dates. Nothing technical.
|
|
104
|
+
5. Data stays on my computer unless I decide to send it somewhere.
|
|
105
|
+
6. Open formats, encrypted backups in more than one place, and a restore I've tested.
|
|
106
|
+
|
|
107
|
+
## Status
|
|
108
|
+
|
|
109
|
+
This is the method and a small tool. The full app runs on my own archive (search across everything, reading photos and scans, a life map) and isn't public yet.
|
|
110
|
+
|
|
111
|
+
## About
|
|
112
|
+
|
|
113
|
+
Made by [Claudia Kitova](https://github.com/claudiakitova). [MIT License](LICENSE). To contribute, see [CONTRIBUTING](CONTRIBUTING.md).
|
|
@@ -0,0 +1,18 @@
|
|
|
1
|
+
<img src="https://raw.githubusercontent.com/claudiakitova/lifekeeper/main/docs/images/lockup.svg" alt="Lifekeeper" width="320">
|
|
2
|
+
|
|
3
|
+
Reclaim your data and start your digital self: everything about you in one place, on your own computer
|
|
4
|
+
|
|
5
|
+
Lifekeeper reads the exports you already have (phone photos, Telegram, WhatsApp, Instagram, Facebook, X, Google Takeout, Spotify, Netflix, Goodreads, LinkedIn, calendars, mood diaries and more) and writes one page of your life, year by year and month by month. Then you can ask questions about your life and get answers from your own records, with the records shown.
|
|
6
|
+
|
|
7
|
+
```
|
|
8
|
+
pipx install "lifekeeper[photos,app,faces]"
|
|
9
|
+
lifekeeper path/to/your/exports --out my-life.html
|
|
10
|
+
lifekeeper-ask path/to/your/exports "When did I meet Leo?"
|
|
11
|
+
lifekeeper-app
|
|
12
|
+
```
|
|
13
|
+
|
|
14
|
+
Making the page sends nothing anywhere. Answers use no AI by default; you can choose a model on your own computer (Ollama) or Google Gemini with your own key.
|
|
15
|
+
|
|
16
|
+

|
|
17
|
+
|
|
18
|
+
The method, the download guides for each service, and the double-click apps for Windows and Mac: https://github.com/claudiakitova/lifekeeper
|
|
@@ -0,0 +1,44 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: lifekeeper
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Reclaim your data: one page of your life from your photos, chats and posts, and answers from your own records.
|
|
5
|
+
Author: Claudia Kitova
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/claudiakitova/lifekeeper
|
|
8
|
+
Project-URL: Source, https://github.com/claudiakitova/lifekeeper
|
|
9
|
+
Keywords: life archive,personal data,data export,timeline,google takeout,local-first,digital twin
|
|
10
|
+
Classifier: Programming Language :: Python :: 3
|
|
11
|
+
Classifier: Operating System :: OS Independent
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Topic :: Utilities
|
|
14
|
+
Requires-Python: >=3.10
|
|
15
|
+
Description-Content-Type: text/markdown
|
|
16
|
+
License-File: LICENSE
|
|
17
|
+
Provides-Extra: photos
|
|
18
|
+
Requires-Dist: pillow>=10; extra == "photos"
|
|
19
|
+
Provides-Extra: app
|
|
20
|
+
Requires-Dist: pywebview>=5; extra == "app"
|
|
21
|
+
Provides-Extra: faces
|
|
22
|
+
Requires-Dist: opencv-python-headless>=4.8; extra == "faces"
|
|
23
|
+
Requires-Dist: numpy>=1.24; extra == "faces"
|
|
24
|
+
Requires-Dist: pillow>=10; extra == "faces"
|
|
25
|
+
Dynamic: license-file
|
|
26
|
+
|
|
27
|
+
<img src="https://raw.githubusercontent.com/claudiakitova/lifekeeper/main/docs/images/lockup.svg" alt="Lifekeeper" width="320">
|
|
28
|
+
|
|
29
|
+
Reclaim your data and start your digital self: everything about you in one place, on your own computer
|
|
30
|
+
|
|
31
|
+
Lifekeeper reads the exports you already have (phone photos, Telegram, WhatsApp, Instagram, Facebook, X, Google Takeout, Spotify, Netflix, Goodreads, LinkedIn, calendars, mood diaries and more) and writes one page of your life, year by year and month by month. Then you can ask questions about your life and get answers from your own records, with the records shown.
|
|
32
|
+
|
|
33
|
+
```
|
|
34
|
+
pipx install "lifekeeper[photos,app,faces]"
|
|
35
|
+
lifekeeper path/to/your/exports --out my-life.html
|
|
36
|
+
lifekeeper-ask path/to/your/exports "When did I meet Leo?"
|
|
37
|
+
lifekeeper-app
|
|
38
|
+
```
|
|
39
|
+
|
|
40
|
+
Making the page sends nothing anywhere. Answers use no AI by default; you can choose a model on your own computer (Ollama) or Google Gemini with your own key.
|
|
41
|
+
|
|
42
|
+

|
|
43
|
+
|
|
44
|
+
The method, the download guides for each service, and the double-click apps for Windows and Mac: https://github.com/claudiakitova/lifekeeper
|
|
@@ -0,0 +1,24 @@
|
|
|
1
|
+
LICENSE
|
|
2
|
+
README.md
|
|
3
|
+
pyproject.toml
|
|
4
|
+
docs/pypi.md
|
|
5
|
+
lifekeeper.egg-info/PKG-INFO
|
|
6
|
+
lifekeeper.egg-info/SOURCES.txt
|
|
7
|
+
lifekeeper.egg-info/dependency_links.txt
|
|
8
|
+
lifekeeper.egg-info/entry_points.txt
|
|
9
|
+
lifekeeper.egg-info/requires.txt
|
|
10
|
+
lifekeeper.egg-info/top_level.txt
|
|
11
|
+
tests/test_ask.py
|
|
12
|
+
tests/test_faces.py
|
|
13
|
+
tests/test_little_data.py
|
|
14
|
+
tests/test_page.py
|
|
15
|
+
toolkit/lifekeeper/__init__.py
|
|
16
|
+
toolkit/lifekeeper/app.py
|
|
17
|
+
toolkit/lifekeeper/ask.py
|
|
18
|
+
toolkit/lifekeeper/cities.tsv.gz
|
|
19
|
+
toolkit/lifekeeper/faces.py
|
|
20
|
+
toolkit/lifekeeper/icon.ico
|
|
21
|
+
toolkit/lifekeeper/icon_data.py
|
|
22
|
+
toolkit/lifekeeper/lifekeeper.py
|
|
23
|
+
toolkit/lifekeeper/places.py
|
|
24
|
+
toolkit/lifekeeper/webui.py
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
lifekeeper
|
|
@@ -0,0 +1,44 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["setuptools>=68"]
|
|
3
|
+
build-backend = "setuptools.build_meta"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "lifekeeper"
|
|
7
|
+
version = "0.1.0"
|
|
8
|
+
description = "Reclaim your data: one page of your life from your photos, chats and posts, and answers from your own records."
|
|
9
|
+
readme = "docs/pypi.md"
|
|
10
|
+
requires-python = ">=3.10"
|
|
11
|
+
license = "MIT"
|
|
12
|
+
license-files = ["LICENSE"]
|
|
13
|
+
authors = [{ name = "Claudia Kitova" }]
|
|
14
|
+
keywords = ["life archive", "personal data", "data export", "timeline", "google takeout", "local-first", "digital twin"]
|
|
15
|
+
classifiers = [
|
|
16
|
+
"Programming Language :: Python :: 3",
|
|
17
|
+
"Operating System :: OS Independent",
|
|
18
|
+
"Environment :: Console",
|
|
19
|
+
"Topic :: Utilities",
|
|
20
|
+
]
|
|
21
|
+
|
|
22
|
+
[project.optional-dependencies]
|
|
23
|
+
photos = ["pillow>=10"]
|
|
24
|
+
app = ["pywebview>=5"]
|
|
25
|
+
faces = ["opencv-python-headless>=4.8", "numpy>=1.24", "pillow>=10"]
|
|
26
|
+
|
|
27
|
+
[project.scripts]
|
|
28
|
+
lifekeeper = "lifekeeper.lifekeeper:main"
|
|
29
|
+
lifekeeper-ask = "lifekeeper.ask:main"
|
|
30
|
+
lifekeeper-faces = "lifekeeper.faces:main"
|
|
31
|
+
|
|
32
|
+
[project.gui-scripts]
|
|
33
|
+
lifekeeper-app = "lifekeeper.app:main"
|
|
34
|
+
|
|
35
|
+
[project.urls]
|
|
36
|
+
Homepage = "https://github.com/claudiakitova/lifekeeper"
|
|
37
|
+
Source = "https://github.com/claudiakitova/lifekeeper"
|
|
38
|
+
|
|
39
|
+
[tool.setuptools]
|
|
40
|
+
package-dir = { "lifekeeper" = "toolkit/lifekeeper" }
|
|
41
|
+
packages = ["lifekeeper"]
|
|
42
|
+
|
|
43
|
+
[tool.setuptools.package-data]
|
|
44
|
+
lifekeeper = ["icon.ico", "cities.tsv.gz"]
|
|
@@ -0,0 +1,199 @@
|
|
|
1
|
+
"""Ask finds the right records and shows only answers it can check. No model and no network are used here.
|
|
2
|
+
|
|
3
|
+
python -m unittest discover -s tests
|
|
4
|
+
"""
|
|
5
|
+
import json
|
|
6
|
+
import sys
|
|
7
|
+
import tempfile
|
|
8
|
+
import unittest
|
|
9
|
+
from pathlib import Path
|
|
10
|
+
|
|
11
|
+
ROOT = Path(__file__).resolve().parent.parent
|
|
12
|
+
sys.path.insert(0, str(ROOT / "toolkit" / "lifekeeper"))
|
|
13
|
+
sys.path.insert(0, str(ROOT / "toolkit" / "lifekeeper"))
|
|
14
|
+
import ask # noqa: E402
|
|
15
|
+
import lifekeeper # noqa: E402
|
|
16
|
+
|
|
17
|
+
|
|
18
|
+
def meta(text):
|
|
19
|
+
return text.encode("utf-8").decode("latin-1")
|
|
20
|
+
|
|
21
|
+
|
|
22
|
+
class Ask(unittest.TestCase):
|
|
23
|
+
@classmethod
|
|
24
|
+
def setUpClass(cls):
|
|
25
|
+
cls.folder = tempfile.TemporaryDirectory()
|
|
26
|
+
root = Path(cls.folder.name)
|
|
27
|
+
(root / "my_events.csv").write_text(
|
|
28
|
+
"date,title,note\n"
|
|
29
|
+
"2019-09-02,Started an evening design course,Twice a week after work.\n"
|
|
30
|
+
"2021-03-14,Met Leo,At Anna's birthday party.\n"
|
|
31
|
+
"2022-04,Moved to Lisbon,\n"
|
|
32
|
+
"2023-06-18,Дедушке исполнилось 90,Собралась вся семья.\n", encoding="utf-8")
|
|
33
|
+
posts = root / "facebook" / "your_activity_across_facebook" / "posts"
|
|
34
|
+
posts.mkdir(parents=True)
|
|
35
|
+
(posts / "your_posts__check_ins__photos_and_videos_1.json").write_text(json.dumps([
|
|
36
|
+
{"timestamp": 1629115200, "data": [{"post": meta("Lisbon, you have my heart.")}]},
|
|
37
|
+
{"timestamp": 1567425600, "data": [{"post": meta("First day of the course. Nervous.")}]}]), encoding="utf-8")
|
|
38
|
+
(root / "goodreads_library_export.csv").write_text(
|
|
39
|
+
"Title,Author,Date Read\nKlara and the Sun,Kazuo Ishiguro,2021/04/11\n", encoding="utf-8")
|
|
40
|
+
(root / "result.json").write_text(json.dumps({
|
|
41
|
+
"personal_information": {"user_id": 1, "first_name": "Mira", "last_name": "Novak"},
|
|
42
|
+
"chats": {"list": [{"name": "Leo Hart", "type": "personal_chat", "messages": [
|
|
43
|
+
{"id": 1, "type": "message", "date": "2021-03-15T10:00:00", "from": "Leo Hart", "from_id": "user2", "text": "hi"},
|
|
44
|
+
{"id": 2, "type": "message", "date": "2021-03-15T10:01:00", "from": "Mira Novak", "from_id": "user1", "text": "hi"}]}]}}),
|
|
45
|
+
encoding="utf-8")
|
|
46
|
+
cls.found = ask.records(lifekeeper.build(str(root), []))
|
|
47
|
+
|
|
48
|
+
@classmethod
|
|
49
|
+
def tearDownClass(cls):
|
|
50
|
+
cls.folder.cleanup()
|
|
51
|
+
|
|
52
|
+
def test_records_cover_what_lite_reads(self):
|
|
53
|
+
kinds = {record["kind"] for record in self.found}
|
|
54
|
+
self.assertLessEqual({"my note", "Facebook post", "book read", "person", "messages"}, kinds)
|
|
55
|
+
self.assertIn("Mar 14, 2021 · my note · Met Leo: At Anna's birthday party.", [ask.line(record) for record in self.found])
|
|
56
|
+
|
|
57
|
+
def test_search_finds_by_words(self):
|
|
58
|
+
first = ask.search(self.found, "When did I meet Leo?", limit=1)[0]
|
|
59
|
+
self.assertEqual((first["kind"], first["day"]), ("my note", "2021-03-14")) # "meet" finds "Met"
|
|
60
|
+
moved = ask.search(self.found, "When did I move?", limit=1)[0]
|
|
61
|
+
self.assertIn("Moved to Lisbon", moved["text"]) # "move" finds "Moved"
|
|
62
|
+
|
|
63
|
+
def test_search_finds_by_year_and_month(self):
|
|
64
|
+
in_2021 = ask.search(self.found, "What happened in 2021?")
|
|
65
|
+
self.assertTrue(in_2021)
|
|
66
|
+
self.assertEqual({record["day"][:4] for record in in_2021}, {"2021"})
|
|
67
|
+
in_march = ask.search(self.found, "What did I do in March 2021?", limit=3)
|
|
68
|
+
self.assertEqual({record["day"][:7] for record in in_march}, {"2021-03"})
|
|
69
|
+
|
|
70
|
+
def test_search_in_russian(self):
|
|
71
|
+
first = ask.search(self.found, "Когда дедушке исполнилось 90?", limit=1)[0]
|
|
72
|
+
self.assertEqual(first["day"], "2023-06-18")
|
|
73
|
+
|
|
74
|
+
def test_newer_sources_become_records(self):
|
|
75
|
+
with tempfile.TemporaryDirectory() as folder:
|
|
76
|
+
root = Path(folder)
|
|
77
|
+
(root / "conversations.json").write_text(json.dumps([{"title": "Packing list for Lisbon", "create_time": 1628500000, "mapping": {}}]), encoding="utf-8")
|
|
78
|
+
(root / "MyActivity.json").write_text(json.dumps([{"header": "Search", "title": "Searched for flights to lisbon", "time": "2021-08-01T10:00:00.000Z"}]), encoding="utf-8")
|
|
79
|
+
(root / "timelogger.csv").write_text("Activity type,Duration,From,To,Comment,Tags\nWork,08:30,2021-08-03 09:00,2021-08-03 17:30,,\n", encoding="utf-8")
|
|
80
|
+
(root / "daylio_export.csv").write_text("full_date,date,weekday,time,mood,activities,note_title,note\n2021-08-14,14 August,Saturday,21:00,rad,travel,,First evening in Lisbon.\n", encoding="utf-8")
|
|
81
|
+
lines = [ask.line(record) for record in ask.records(lifekeeper.build(str(root), []))]
|
|
82
|
+
self.assertIn("Aug 9, 2021 · AI chat · Packing list for Lisbon", lines)
|
|
83
|
+
self.assertIn("Aug 2021 · searches · Searched for flights to lisbon", lines)
|
|
84
|
+
self.assertIn("Aug 2021 · time · Time spent: Work (8 h)", lines)
|
|
85
|
+
self.assertIn("Aug 14, 2021 · diary · First evening in Lisbon.", lines)
|
|
86
|
+
self.assertIn("Aug 2021 · mood · Mood mostly rad (1 day)", lines)
|
|
87
|
+
|
|
88
|
+
def test_feelings_find_moods_and_diaries(self):
|
|
89
|
+
with tempfile.TemporaryDirectory() as folder:
|
|
90
|
+
root = Path(folder)
|
|
91
|
+
(root / "daylio_export.csv").write_text("full_date,date,weekday,time,mood,activities,note_title,note\n"
|
|
92
|
+
"2024-06-03,3 June,Monday,21:00,rad,work,,First day at Lumen. Everyone was kind.\n",
|
|
93
|
+
encoding="utf-8")
|
|
94
|
+
found = ask.records(lifekeeper.build(str(root), []))
|
|
95
|
+
kinds = {record["kind"] for record in ask.search(found, "How did I feel when I started at Lumen?")}
|
|
96
|
+
self.assertEqual(kinds, {"diary", "mood"})
|
|
97
|
+
|
|
98
|
+
def test_gemini_retries_when_busy(self):
|
|
99
|
+
import io
|
|
100
|
+
import urllib.error
|
|
101
|
+
calls = []
|
|
102
|
+
|
|
103
|
+
def busy_then_fine(request, timeout):
|
|
104
|
+
calls.append(1)
|
|
105
|
+
if len(calls) < 3:
|
|
106
|
+
raise urllib.error.HTTPError(request.full_url, 503, "busy", {}, io.BytesIO(b'{"error": {"status": "UNAVAILABLE"}}'))
|
|
107
|
+
return io.BytesIO(json.dumps({"candidates": [{"content": {"parts": [{"text": "ok"}]}}]}).encode())
|
|
108
|
+
|
|
109
|
+
real = ask.urllib.request.urlopen
|
|
110
|
+
ask.urllib.request.urlopen = busy_then_fine
|
|
111
|
+
try:
|
|
112
|
+
self.assertEqual(ask.gemini("s", "p", "key", waits=(0, 0)), "ok")
|
|
113
|
+
calls.clear()
|
|
114
|
+
ask.urllib.request.urlopen = lambda request, timeout: (_ for _ in ()).throw(
|
|
115
|
+
urllib.error.HTTPError(request.full_url, 503, "busy", {}, io.BytesIO(b"{}")))
|
|
116
|
+
with self.assertRaisesRegex(RuntimeError, "busy right now"):
|
|
117
|
+
ask.gemini("s", "p", "key", waits=(0, 0))
|
|
118
|
+
finally:
|
|
119
|
+
ask.urllib.request.urlopen = real
|
|
120
|
+
|
|
121
|
+
def test_nothing_matches(self):
|
|
122
|
+
self.assertEqual(ask.search(self.found, "Did I ever go to Mars?"), [])
|
|
123
|
+
self.assertEqual(ask.answer(self.found, "Did I ever go to Mars?"), "Nothing in your records matches that question.")
|
|
124
|
+
|
|
125
|
+
def test_without_a_model_the_records_are_shown(self):
|
|
126
|
+
shown = ask.answer(self.found, "When did I meet Leo?")
|
|
127
|
+
self.assertTrue(shown.startswith("Records that match (no AI was used):"))
|
|
128
|
+
self.assertIn("Met Leo: At Anna's birthday party.", shown)
|
|
129
|
+
|
|
130
|
+
def chosen(self):
|
|
131
|
+
return ask.search(self.found, "When did I meet Leo?")
|
|
132
|
+
|
|
133
|
+
def number_of(self, text):
|
|
134
|
+
return next(number for number, record in enumerate(self.chosen(), 1) if text in record["text"])
|
|
135
|
+
|
|
136
|
+
def test_a_cited_sentence_is_kept_and_renumbered(self):
|
|
137
|
+
note = self.number_of("Met Leo")
|
|
138
|
+
text, sources = ask.checked(f"You met Leo on Mar 14, 2021, at Anna's birthday party [{note}].", self.chosen())
|
|
139
|
+
self.assertEqual(text, "You met Leo on Mar 14, 2021, at Anna's birthday party [1].")
|
|
140
|
+
self.assertEqual([record["text"] for record in sources], ["Met Leo: At Anna's birthday party."])
|
|
141
|
+
|
|
142
|
+
def test_a_sentence_without_a_record_is_left_out(self):
|
|
143
|
+
note = self.number_of("Met Leo")
|
|
144
|
+
text, sources = ask.checked(f"You met Leo on Mar 14, 2021 [{note}]. It was love at first sight.", self.chosen())
|
|
145
|
+
self.assertEqual(text, "You met Leo on Mar 14, 2021 [1].")
|
|
146
|
+
self.assertEqual(len(sources), 1)
|
|
147
|
+
|
|
148
|
+
def test_a_date_the_records_do_not_have_is_left_out(self):
|
|
149
|
+
note = self.number_of("Met Leo")
|
|
150
|
+
text, sources = ask.checked(f"You met Leo in 2019 [{note}].", self.chosen())
|
|
151
|
+
self.assertEqual((text, sources), ("", []))
|
|
152
|
+
|
|
153
|
+
def test_a_record_number_that_does_not_exist_is_left_out(self):
|
|
154
|
+
text, _ = ask.checked("You met Leo at a party [99].", self.chosen())
|
|
155
|
+
self.assertEqual(text, "")
|
|
156
|
+
|
|
157
|
+
def test_citation_after_the_period_and_short_words(self):
|
|
158
|
+
note = self.number_of("Met Leo")
|
|
159
|
+
text, _ = ask.checked(f"You met Leo on Mar. 14, 2021. [{note}]", self.chosen())
|
|
160
|
+
self.assertEqual(text, "You met Leo on Mar. 14, 2021 [1].")
|
|
161
|
+
|
|
162
|
+
def test_answer_with_a_model(self):
|
|
163
|
+
note = self.number_of("Met Leo")
|
|
164
|
+
seen = {}
|
|
165
|
+
|
|
166
|
+
def model(system, prompt):
|
|
167
|
+
seen["system"], seen["prompt"] = system, prompt
|
|
168
|
+
return f"You met Leo on Mar 14, 2021 [{note}]. You have been inseparable ever since."
|
|
169
|
+
|
|
170
|
+
told = []
|
|
171
|
+
shown = ask.answer(self.found, "When did I meet Leo?", model, note=told.append)
|
|
172
|
+
self.assertEqual(shown, "You met Leo on Mar 14, 2021 [1].\n\nFrom your records:\n"
|
|
173
|
+
"[1] Mar 14, 2021 · my note · Met Leo: At Anna's birthday party.")
|
|
174
|
+
self.assertIn("Question: When did I meet Leo?", seen["prompt"])
|
|
175
|
+
self.assertIn(f"[{note}] Mar 14, 2021 · my note · Met Leo", seen["prompt"])
|
|
176
|
+
self.assertEqual(told, [len(self.chosen())]) # the person is told how many records are sent
|
|
177
|
+
|
|
178
|
+
def test_an_answer_that_cannot_be_checked_is_not_shown(self):
|
|
179
|
+
shown = ask.answer(self.found, "When did I meet Leo?", lambda system, prompt: "You met Leo in Paris in 2015.")
|
|
180
|
+
self.assertTrue(shown.startswith("The model's answer couldn't be checked against your records, so it isn't shown."))
|
|
181
|
+
self.assertNotIn("Paris", shown)
|
|
182
|
+
|
|
183
|
+
def test_the_model_says_the_records_do_not_say(self):
|
|
184
|
+
shown = ask.answer(self.found, "When did I meet Leo?", lambda system, prompt: "The records don't say.")
|
|
185
|
+
self.assertTrue(shown.startswith("Your records don't say. The closest ones:"))
|
|
186
|
+
|
|
187
|
+
def test_gemini_request_keeps_the_key_out_of_the_text(self):
|
|
188
|
+
request = ask.gemini_request("system text", "prompt text", "SECRET-KEY", "some-model")
|
|
189
|
+
self.assertIn("/models/some-model:generateContent", request.full_url)
|
|
190
|
+
self.assertNotIn("SECRET-KEY", request.full_url)
|
|
191
|
+
self.assertNotIn(b"SECRET-KEY", request.data)
|
|
192
|
+
self.assertEqual(request.get_header("X-goog-api-key"), "SECRET-KEY")
|
|
193
|
+
body = json.loads(request.data)
|
|
194
|
+
self.assertEqual(body["contents"][0]["parts"][0]["text"], "prompt text")
|
|
195
|
+
self.assertEqual(body["generationConfig"]["temperature"], 0)
|
|
196
|
+
|
|
197
|
+
|
|
198
|
+
if __name__ == "__main__":
|
|
199
|
+
unittest.main()
|
|
@@ -0,0 +1,75 @@
|
|
|
1
|
+
"""The faces add-on groups and names faces right. The faces here are made-up vectors, so no photos and no models are needed.
|
|
2
|
+
|
|
3
|
+
python -m unittest discover -s tests
|
|
4
|
+
"""
|
|
5
|
+
import sys
|
|
6
|
+
import tempfile
|
|
7
|
+
from contextlib import closing
|
|
8
|
+
import unittest
|
|
9
|
+
from pathlib import Path
|
|
10
|
+
|
|
11
|
+
sys.path.insert(0, str(Path(__file__).resolve().parent.parent / "toolkit" / "lifekeeper"))
|
|
12
|
+
import faces # noqa: E402
|
|
13
|
+
|
|
14
|
+
try:
|
|
15
|
+
import numpy
|
|
16
|
+
except ImportError: # the faces add-on isn't installed: these tests wait for it
|
|
17
|
+
numpy = None
|
|
18
|
+
|
|
19
|
+
|
|
20
|
+
@unittest.skipIf(numpy is None, "the faces add-on (NumPy) isn't installed")
|
|
21
|
+
class Faces(unittest.TestCase):
|
|
22
|
+
def setUp(self):
|
|
23
|
+
self.folder = tempfile.TemporaryDirectory()
|
|
24
|
+
self.root = Path(self.folder.name) / "exports"
|
|
25
|
+
self.root.mkdir()
|
|
26
|
+
|
|
27
|
+
def tearDown(self):
|
|
28
|
+
self.folder.cleanup()
|
|
29
|
+
|
|
30
|
+
def add(self, connection, photo, vector, score=0.9):
|
|
31
|
+
vector = numpy.asarray(vector, dtype="float32")
|
|
32
|
+
vector /= numpy.linalg.norm(vector)
|
|
33
|
+
connection.execute("INSERT INTO faces(photo,x,y,w,h,score,embedding,crop) VALUES (?,0,0,100,100,?,?,?)",
|
|
34
|
+
(photo, score, vector.tobytes(), b"jpeg"))
|
|
35
|
+
|
|
36
|
+
def test_group_name_hide(self):
|
|
37
|
+
rng = numpy.random.default_rng(1)
|
|
38
|
+
anna, leo, stranger = (rng.normal(size=128) for _ in range(3))
|
|
39
|
+
with closing(faces.connect(self.root)) as connection:
|
|
40
|
+
for n in range(4):
|
|
41
|
+
self.add(connection, f"a{n}.jpg", anna + rng.normal(scale=0.15, size=128))
|
|
42
|
+
for n in range(3):
|
|
43
|
+
self.add(connection, f"l{n}.jpg", leo + rng.normal(scale=0.15, size=128))
|
|
44
|
+
self.add(connection, "s.jpg", stranger) # seen once: too few to show
|
|
45
|
+
connection.commit()
|
|
46
|
+
self.assertEqual(faces.group(self.root), 3)
|
|
47
|
+
groups = faces.people(self.root)
|
|
48
|
+
self.assertEqual([group["photos"] for group in groups], [4, 3])
|
|
49
|
+
anna_group, leo_group = groups[0]["person"], groups[1]["person"]
|
|
50
|
+
self.assertEqual(faces.name(self.root, anna_group, "Anna"), 4)
|
|
51
|
+
faces.group(self.root) # regrouping keeps the name: names belong to faces
|
|
52
|
+
self.assertEqual([(group["name"], group["photos"]) for group in faces.people(self.root)][0], ("Anna", 4))
|
|
53
|
+
self.assertEqual(faces.hide(self.root, leo_group), 3)
|
|
54
|
+
self.assertEqual([group["name"] for group in faces.people(self.root)], ["Anna"])
|
|
55
|
+
self.assertIn("Anna", faces.people_page(self.root))
|
|
56
|
+
|
|
57
|
+
def test_one_person_in_two_groups_shows_once(self):
|
|
58
|
+
rng = numpy.random.default_rng(2)
|
|
59
|
+
young, older = rng.normal(size=128), rng.normal(size=128) # far apart: two groups
|
|
60
|
+
with closing(faces.connect(self.root)) as connection:
|
|
61
|
+
for n in range(3):
|
|
62
|
+
self.add(connection, f"y{n}.jpg", young + rng.normal(scale=0.1, size=128))
|
|
63
|
+
self.add(connection, f"o{n}.jpg", older + rng.normal(scale=0.1, size=128))
|
|
64
|
+
connection.commit()
|
|
65
|
+
faces.group(self.root)
|
|
66
|
+
first, second = faces.people(self.root)
|
|
67
|
+
faces.name(self.root, first["person"], "Mom")
|
|
68
|
+
faces.name(self.root, second["person"], "mom")
|
|
69
|
+
merged = faces.people(self.root)
|
|
70
|
+
self.assertEqual(len(merged), 1)
|
|
71
|
+
self.assertEqual((merged[0]["photos"], len(merged[0]["persons"])), (6, 2))
|
|
72
|
+
|
|
73
|
+
|
|
74
|
+
if __name__ == "__main__":
|
|
75
|
+
unittest.main()
|