kpnn2 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- kpnn2-0.1.0/LICENSE +22 -0
- kpnn2-0.1.0/PKG-INFO +281 -0
- kpnn2-0.1.0/README.md +226 -0
- kpnn2-0.1.0/pyproject.toml +121 -0
- kpnn2-0.1.0/setup.cfg +4 -0
- kpnn2-0.1.0/src/kpnn2/__init__.py +45 -0
- kpnn2-0.1.0/src/kpnn2/_adjacency_spec.py +387 -0
- kpnn2-0.1.0/src/kpnn2/_align.py +215 -0
- kpnn2-0.1.0/src/kpnn2/_attributions.py +377 -0
- kpnn2-0.1.0/src/kpnn2/_errors.py +29 -0
- kpnn2-0.1.0/src/kpnn2/_gather.py +158 -0
- kpnn2-0.1.0/src/kpnn2/_layout.py +315 -0
- kpnn2-0.1.0/src/kpnn2/_mask_tensor.py +23 -0
- kpnn2-0.1.0/src/kpnn2/_masked_linear.py +457 -0
- kpnn2-0.1.0/src/kpnn2/_packed_linear.py +472 -0
- kpnn2-0.1.0/src/kpnn2/_parse.py +640 -0
- kpnn2-0.1.0/src/kpnn2/_parse_adjacency.py +187 -0
- kpnn2-0.1.0/src/kpnn2/_serialize.py +359 -0
- kpnn2-0.1.0/src/kpnn2/_spec.py +473 -0
- kpnn2-0.1.0/src/kpnn2.egg-info/PKG-INFO +281 -0
- kpnn2-0.1.0/src/kpnn2.egg-info/SOURCES.txt +22 -0
- kpnn2-0.1.0/src/kpnn2.egg-info/dependency_links.txt +1 -0
- kpnn2-0.1.0/src/kpnn2.egg-info/requires.txt +36 -0
- kpnn2-0.1.0/src/kpnn2.egg-info/top_level.txt +1 -0
kpnn2-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Thomas Rauter
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
22
|
+
|
kpnn2-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,281 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: kpnn2
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Turn a named edgelist into sparsely connected PyTorch layers you assemble yourself.
|
|
5
|
+
Author: Thomas Rauter
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://thomas-rauter.github.io/kpnn2/
|
|
8
|
+
Project-URL: Documentation, https://thomas-rauter.github.io/kpnn2/
|
|
9
|
+
Project-URL: Repository, https://github.com/Thomas-Rauter/kpnn2
|
|
10
|
+
Project-URL: Issues, https://github.com/Thomas-Rauter/kpnn2/issues
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Intended Audience :: Science/Research
|
|
13
|
+
Classifier: Programming Language :: Python :: 3
|
|
14
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
15
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.14
|
|
19
|
+
Classifier: Topic :: Scientific/Engineering
|
|
20
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
21
|
+
Requires-Python: >=3.10
|
|
22
|
+
Description-Content-Type: text/markdown
|
|
23
|
+
License-File: LICENSE
|
|
24
|
+
Requires-Dist: torch<3,>=2.1
|
|
25
|
+
Requires-Dist: pandas<3,>=2.2
|
|
26
|
+
Requires-Dist: numpy<3,>=1.24
|
|
27
|
+
Requires-Dist: xarray<2025.7,>=2024.11; python_version < "3.11"
|
|
28
|
+
Requires-Dist: xarray<2026.8,>=2026.4; python_version >= "3.11"
|
|
29
|
+
Provides-Extra: dev
|
|
30
|
+
Requires-Dist: pytest; extra == "dev"
|
|
31
|
+
Requires-Dist: pytest-cov; extra == "dev"
|
|
32
|
+
Requires-Dist: ruff==0.16.4; extra == "dev"
|
|
33
|
+
Requires-Dist: mypy; extra == "dev"
|
|
34
|
+
Requires-Dist: pandas-stubs<2.4,>=2.3.3; extra == "dev"
|
|
35
|
+
Requires-Dist: build; extra == "dev"
|
|
36
|
+
Requires-Dist: scikit-learn; extra == "dev"
|
|
37
|
+
Requires-Dist: captum; extra == "dev"
|
|
38
|
+
Provides-Extra: docs
|
|
39
|
+
Requires-Dist: mkdocs; extra == "docs"
|
|
40
|
+
Requires-Dist: mkdocs-material; extra == "docs"
|
|
41
|
+
Requires-Dist: mkdocstrings[python]; extra == "docs"
|
|
42
|
+
Requires-Dist: mkdocs-jupyter; extra == "docs"
|
|
43
|
+
Requires-Dist: mkdocs-include-markdown-plugin; extra == "docs"
|
|
44
|
+
Requires-Dist: pymdown-extensions; extra == "docs"
|
|
45
|
+
Requires-Dist: nbconvert; extra == "docs"
|
|
46
|
+
Requires-Dist: ipykernel; extra == "docs"
|
|
47
|
+
Requires-Dist: ipywidgets; extra == "docs"
|
|
48
|
+
Requires-Dist: graphviz; extra == "docs"
|
|
49
|
+
Requires-Dist: IPython; extra == "docs"
|
|
50
|
+
Requires-Dist: seaborn; extra == "docs"
|
|
51
|
+
Requires-Dist: captum; extra == "docs"
|
|
52
|
+
Requires-Dist: black; extra == "docs"
|
|
53
|
+
Requires-Dist: mike<3,>=2; extra == "docs"
|
|
54
|
+
Dynamic: license-file
|
|
55
|
+
|
|
56
|
+
# kpnn2
|
|
57
|
+
|
|
58
|
+
[](https://github.com/Thomas-Rauter/kpnn2/actions/workflows/ci.yml)
|
|
59
|
+
[](https://app.codecov.io/gh/Thomas-Rauter/kpnn2)
|
|
60
|
+
[](https://pypi.org/project/kpnn2/)
|
|
61
|
+
[](https://pypi.org/project/kpnn2/)
|
|
62
|
+
[](https://pypi.org/project/kpnn2/)
|
|
63
|
+
[](https://pypi.org/project/kpnn2/)
|
|
64
|
+
[](https://pypi.org/project/kpnn2/)
|
|
65
|
+
|
|
66
|
+
Turn a named edgelist into sparsely connected PyTorch layers
|
|
67
|
+
you assemble yourself.
|
|
68
|
+
|
|
69
|
+
## Overview
|
|
70
|
+
|
|
71
|
+
A fully connected neural network (NN), in which every node in one
|
|
72
|
+
layer connects to every node in the next, is easy to implement in
|
|
73
|
+
PyTorch.
|
|
74
|
+
|
|
75
|
+
A sparsely connected NN with skip edges is not. Only some pairs of
|
|
76
|
+
nodes are linked, and some edges skip layers. That is the gap
|
|
77
|
+
`kpnn2` (**K**nowledge **P**rimed **N**eural **N**etworks) fills: the same
|
|
78
|
+
PyTorch workflow, with that connectivity.
|
|
79
|
+
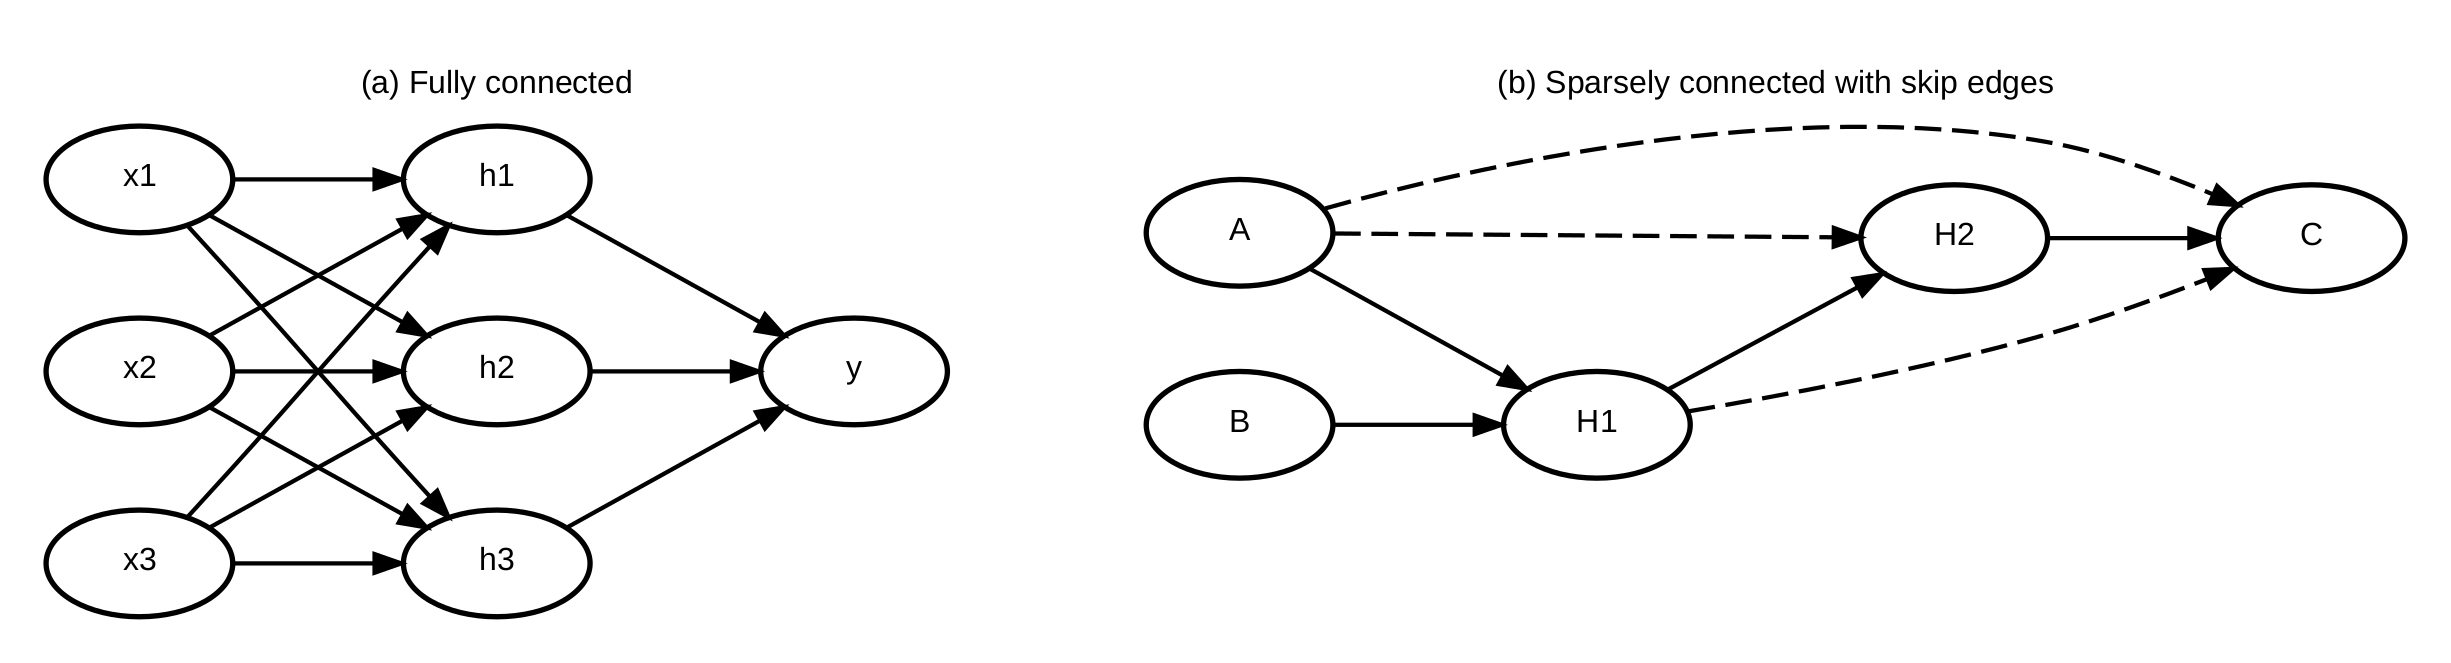
Figure 1 shows a dense NN next to a sparse NN with skip edges.
|
|
80
|
+
|
|
81
|
+
|
|
82
|
+
|
|
83
|
+
**Figure 1.** (a) Dense adjacent layers, the usual PyTorch case.
|
|
84
|
+
(b) A sparsely connected DAG with skip edges (dashed), the same graph as on
|
|
85
|
+
the [Skip edges](docs/skip-edges.ipynb) page. `kpnn2` turns (b)
|
|
86
|
+
into ordinary `MaskedLinear` hops, one per layer, with the skip
|
|
87
|
+
edges inside those masks.
|
|
88
|
+
|
|
89
|
+
An **edgelist** is a table of directed connections: each row links
|
|
90
|
+
a `source` node to a `target` node. For example:
|
|
91
|
+
|
|
92
|
+
| source | target |
|
|
93
|
+
|--------|--------|
|
|
94
|
+
| A | H |
|
|
95
|
+
| B | H |
|
|
96
|
+
| H | C |
|
|
97
|
+
|
|
98
|
+
`parse_layered()` layers that table into a `LayeredSpec`. You write
|
|
99
|
+
a normal `torch.nn.Module`, train with standard PyTorch, and can
|
|
100
|
+
map attributions back onto the named nodes. That parser needs a
|
|
101
|
+
DAG; a graph with feedback loops goes through `parse_adjacency()`
|
|
102
|
+
instead, which puts every node into one state vector with packed
|
|
103
|
+
edge indices (see the
|
|
104
|
+
[Recurrent example](docs/recurrent-example.ipynb)).
|
|
105
|
+
|
|
106
|
+
Sparse connectivity is often used for speed or memory, without
|
|
107
|
+
needing control over which nodes are linked. A newer line of work
|
|
108
|
+
instead builds the NN so its wiring is a real network, for example
|
|
109
|
+
a biological or chemical graph. Attributions on the NN nodes then
|
|
110
|
+
map onto the nodes of that network, which gives the model a direct
|
|
111
|
+
form of interpretability.
|
|
112
|
+
|
|
113
|
+
In biology this is an active research area, including pathway-based models
|
|
114
|
+
([Fortelny and Bock, 2020](https://doi.org/10.1186/s13059-020-02100-5))
|
|
115
|
+
and ontology-based models
|
|
116
|
+
([Elmarakeby et al., 2021](https://doi.org/10.1038/s41586-021-03922-4)).
|
|
117
|
+
The [Getting started](docs/getting-started.ipynb) notebook walks
|
|
118
|
+
through a biological example.
|
|
119
|
+
|
|
120
|
+
`kpnn2` is a set of (domain-agnostic) primitives, not a graph compiler. There
|
|
121
|
+
is no ready-made model object. Training loops, losses, optimizers,
|
|
122
|
+
activations, and heads stay yours.
|
|
123
|
+
|
|
124
|
+
As a further note, "graph" here means the architecture specification, not a
|
|
125
|
+
graph neural network, which cannot be implemented using `kpnn2` in PyTorch.
|
|
126
|
+
|
|
127
|
+
## Core workflow
|
|
128
|
+
|
|
129
|
+
1. Define a model architecture as an edgelist with named `source`
|
|
130
|
+
and `target` nodes.
|
|
131
|
+
2. Parse it with `parse_layered()` to a `LayeredSpec`. For a graph
|
|
132
|
+
with feedback loops, use `parse_adjacency()` and an
|
|
133
|
+
`AdjacencySpec` instead.
|
|
134
|
+
3. Write an `nn.Module` with one `MaskedLinear` per
|
|
135
|
+
`spec.hops`, feeding each one
|
|
136
|
+
`gather_hop_inputs(saved, hop)`. Skip edges are already
|
|
137
|
+
inside those masks, so there is nothing extra to call.
|
|
138
|
+
4. Align named input tables with `align_inputs()`.
|
|
139
|
+
5. Train with ordinary PyTorch.
|
|
140
|
+
6. Optionally run Captum (or another method) yourself, then label a
|
|
141
|
+
layer tensor with `map_node_attributions()` (returns xarray).
|
|
142
|
+
7. A checkpoint is `spec.to_dict()` plus `state_dict`, not
|
|
143
|
+
weights alone.
|
|
144
|
+
|
|
145
|
+
The snippet below is a minimal run of steps 1–4, using the
|
|
146
|
+
edgelist from the table above. Column order in the input table
|
|
147
|
+
does not matter: `align_inputs()` matches names. Skip edges are
|
|
148
|
+
omitted here; see [**Skip edges**](docs/skip-edges.ipynb). A full
|
|
149
|
+
walkthrough, including training and attribution, is in
|
|
150
|
+
[**Getting started**](docs/getting-started.ipynb).
|
|
151
|
+
|
|
152
|
+
```python
|
|
153
|
+
import pandas as pd
|
|
154
|
+
import torch.nn.functional as F
|
|
155
|
+
from torch import nn
|
|
156
|
+
|
|
157
|
+
import kpnn2
|
|
158
|
+
|
|
159
|
+
edgelist = pd.DataFrame(
|
|
160
|
+
{
|
|
161
|
+
"source": ["A", "B", "H"],
|
|
162
|
+
"target": ["H", "H", "C"],
|
|
163
|
+
}
|
|
164
|
+
)
|
|
165
|
+
spec = kpnn2.parse_layered(edgelist)
|
|
166
|
+
|
|
167
|
+
|
|
168
|
+
class Net(nn.Module):
|
|
169
|
+
def __init__(self, spec: kpnn2.LayeredSpec):
|
|
170
|
+
super().__init__()
|
|
171
|
+
self.lin0 = kpnn2.MaskedLinear(spec.hops[0].mask)
|
|
172
|
+
self.lin1 = kpnn2.MaskedLinear(spec.hops[1].mask)
|
|
173
|
+
|
|
174
|
+
def forward(self, x):
|
|
175
|
+
h = F.relu(self.lin0(x))
|
|
176
|
+
return self.lin1(h)
|
|
177
|
+
|
|
178
|
+
|
|
179
|
+
model = Net(spec)
|
|
180
|
+
x = kpnn2.align_inputs(
|
|
181
|
+
pd.DataFrame({"B": [0.2, 0.4], "A": [0.1, 0.3]}),
|
|
182
|
+
spec,
|
|
183
|
+
)
|
|
184
|
+
y = model(x)
|
|
185
|
+
# Continue training with ordinary PyTorch.
|
|
186
|
+
```
|
|
187
|
+
|
|
188
|
+
## API
|
|
189
|
+
|
|
190
|
+
The documented public names are:
|
|
191
|
+
|
|
192
|
+
- `parse_layered()`
|
|
193
|
+
- `parse_adjacency()`
|
|
194
|
+
- `LayeredSpec`
|
|
195
|
+
- `Hop`
|
|
196
|
+
- `Skip`
|
|
197
|
+
- `AdjacencySpec`
|
|
198
|
+
- `MaskedLinear`
|
|
199
|
+
- `PackedLinear`
|
|
200
|
+
- `gather_hop_inputs()`
|
|
201
|
+
- `align_inputs()`
|
|
202
|
+
- `map_node_attributions()`
|
|
203
|
+
|
|
204
|
+
`LayeredSpec.hops` holds one `Hop` per layer after the first, and
|
|
205
|
+
a hop's mask carries every edge entering that layer, skip edges
|
|
206
|
+
included. `LayeredSpec.skips` lists which edges span layers, as
|
|
207
|
+
metadata. An `AdjacencySpec` has no layers and no skips: it carries
|
|
208
|
+
packed `source_index` / `target_index` over all `nodes`, plus
|
|
209
|
+
`input_index` and `output_index` into that state vector.
|
|
210
|
+
`to_mask()` densifies for `MaskedLinear` on small graphs.
|
|
211
|
+
|
|
212
|
+
See the [**API reference**](docs/api.md) for details, and
|
|
213
|
+
[**Skip edges**](docs/skip-edges.ipynb) for a worked example.
|
|
214
|
+
|
|
215
|
+
## Package philosophy
|
|
216
|
+
|
|
217
|
+
`kpnn2` is intentionally minimally opinionated.
|
|
218
|
+
|
|
219
|
+
It owns edgelist parsing, mask tensors, hop input assembly, named
|
|
220
|
+
input alignment, and attribution column names. It does not impose
|
|
221
|
+
broader modeling choices such as:
|
|
222
|
+
|
|
223
|
+
- activation functions
|
|
224
|
+
- output heads
|
|
225
|
+
- dropout
|
|
226
|
+
- loss functions
|
|
227
|
+
- optimizers
|
|
228
|
+
- training loops
|
|
229
|
+
|
|
230
|
+
Those remain part of the normal PyTorch workflow:
|
|
231
|
+
|
|
232
|
+
- `kpnn2` turns the edgelist into structure you can execute
|
|
233
|
+
- PyTorch handles `forward()`, training, and customization
|
|
234
|
+
- you map trained tensors back to named nodes when you want
|
|
235
|
+
interpretation
|
|
236
|
+
|
|
237
|
+
## Installation
|
|
238
|
+
|
|
239
|
+
Requires Python 3.10 or later.
|
|
240
|
+
|
|
241
|
+
```bash
|
|
242
|
+
pip install kpnn2
|
|
243
|
+
```
|
|
244
|
+
|
|
245
|
+
## Start here
|
|
246
|
+
|
|
247
|
+
If you are new to the package, start with a tutorial:
|
|
248
|
+
|
|
249
|
+
- [**Installation**](docs/installation.md) for package setup
|
|
250
|
+
- [**Getting started**](docs/getting-started.ipynb) for a full
|
|
251
|
+
end-to-end feedforward example
|
|
252
|
+
- [**Recurrent example**](docs/recurrent-example.ipynb) for
|
|
253
|
+
`parse_adjacency()` and a shared `MaskedLinear` over one state
|
|
254
|
+
vector when the graph has feedback loops (`parse_layered` still
|
|
255
|
+
requires a DAG)
|
|
256
|
+
|
|
257
|
+
The other pages explain a design choice; they are not second
|
|
258
|
+
examples:
|
|
259
|
+
|
|
260
|
+
- [**Layered vs. Adjacency**](docs/layered_vs_adjacency.md) for
|
|
261
|
+
how the two parsers differ and when to pick one
|
|
262
|
+
- [**Skip edges**](docs/skip-edges.ipynb) for edges that jump a
|
|
263
|
+
layer, and why they need no separate mechanism
|
|
264
|
+
- [**Mapping attributions**](docs/map-node-attributions.ipynb) for
|
|
265
|
+
labeling layer tensors with node names
|
|
266
|
+
- [**PackedLinear**](docs/packed_linear.md) when `n` is large on
|
|
267
|
+
an `AdjacencySpec`
|
|
268
|
+
- [**API reference**](docs/api.md) for function- and object-level
|
|
269
|
+
documentation
|
|
270
|
+
|
|
271
|
+
## Citation
|
|
272
|
+
|
|
273
|
+
If you use `kpnn2` in research, please cite the software.
|
|
274
|
+
Citation metadata is available in
|
|
275
|
+
[`CITATION.cff`](https://github.com/Thomas-Rauter/kpnn2/blob/main/CITATION.cff).
|
|
276
|
+
|
|
277
|
+
## License
|
|
278
|
+
|
|
279
|
+
This project is licensed under the MIT License. See the
|
|
280
|
+
[LICENSE file on GitHub](https://github.com/Thomas-Rauter/kpnn2/blob/main/LICENSE)
|
|
281
|
+
for details.
|
kpnn2-0.1.0/README.md
ADDED
|
@@ -0,0 +1,226 @@
|
|
|
1
|
+
# kpnn2
|
|
2
|
+
|
|
3
|
+
[](https://github.com/Thomas-Rauter/kpnn2/actions/workflows/ci.yml)
|
|
4
|
+
[](https://app.codecov.io/gh/Thomas-Rauter/kpnn2)
|
|
5
|
+
[](https://pypi.org/project/kpnn2/)
|
|
6
|
+
[](https://pypi.org/project/kpnn2/)
|
|
7
|
+
[](https://pypi.org/project/kpnn2/)
|
|
8
|
+
[](https://pypi.org/project/kpnn2/)
|
|
9
|
+
[](https://pypi.org/project/kpnn2/)
|
|
10
|
+
|
|
11
|
+
Turn a named edgelist into sparsely connected PyTorch layers
|
|
12
|
+
you assemble yourself.
|
|
13
|
+
|
|
14
|
+
## Overview
|
|
15
|
+
|
|
16
|
+
A fully connected neural network (NN), in which every node in one
|
|
17
|
+
layer connects to every node in the next, is easy to implement in
|
|
18
|
+
PyTorch.
|
|
19
|
+
|
|
20
|
+
A sparsely connected NN with skip edges is not. Only some pairs of
|
|
21
|
+
nodes are linked, and some edges skip layers. That is the gap
|
|
22
|
+
`kpnn2` (**K**nowledge **P**rimed **N**eural **N**etworks) fills: the same
|
|
23
|
+
PyTorch workflow, with that connectivity.
|
|
24
|
+
Figure 1 shows a dense NN next to a sparse NN with skip edges.
|
|
25
|
+
|
|
26
|
+

|
|
27
|
+
|
|
28
|
+
**Figure 1.** (a) Dense adjacent layers, the usual PyTorch case.
|
|
29
|
+
(b) A sparsely connected DAG with skip edges (dashed), the same graph as on
|
|
30
|
+
the [Skip edges](docs/skip-edges.ipynb) page. `kpnn2` turns (b)
|
|
31
|
+
into ordinary `MaskedLinear` hops, one per layer, with the skip
|
|
32
|
+
edges inside those masks.
|
|
33
|
+
|
|
34
|
+
An **edgelist** is a table of directed connections: each row links
|
|
35
|
+
a `source` node to a `target` node. For example:
|
|
36
|
+
|
|
37
|
+
| source | target |
|
|
38
|
+
|--------|--------|
|
|
39
|
+
| A | H |
|
|
40
|
+
| B | H |
|
|
41
|
+
| H | C |
|
|
42
|
+
|
|
43
|
+
`parse_layered()` layers that table into a `LayeredSpec`. You write
|
|
44
|
+
a normal `torch.nn.Module`, train with standard PyTorch, and can
|
|
45
|
+
map attributions back onto the named nodes. That parser needs a
|
|
46
|
+
DAG; a graph with feedback loops goes through `parse_adjacency()`
|
|
47
|
+
instead, which puts every node into one state vector with packed
|
|
48
|
+
edge indices (see the
|
|
49
|
+
[Recurrent example](docs/recurrent-example.ipynb)).
|
|
50
|
+
|
|
51
|
+
Sparse connectivity is often used for speed or memory, without
|
|
52
|
+
needing control over which nodes are linked. A newer line of work
|
|
53
|
+
instead builds the NN so its wiring is a real network, for example
|
|
54
|
+
a biological or chemical graph. Attributions on the NN nodes then
|
|
55
|
+
map onto the nodes of that network, which gives the model a direct
|
|
56
|
+
form of interpretability.
|
|
57
|
+
|
|
58
|
+
In biology this is an active research area, including pathway-based models
|
|
59
|
+
([Fortelny and Bock, 2020](https://doi.org/10.1186/s13059-020-02100-5))
|
|
60
|
+
and ontology-based models
|
|
61
|
+
([Elmarakeby et al., 2021](https://doi.org/10.1038/s41586-021-03922-4)).
|
|
62
|
+
The [Getting started](docs/getting-started.ipynb) notebook walks
|
|
63
|
+
through a biological example.
|
|
64
|
+
|
|
65
|
+
`kpnn2` is a set of (domain-agnostic) primitives, not a graph compiler. There
|
|
66
|
+
is no ready-made model object. Training loops, losses, optimizers,
|
|
67
|
+
activations, and heads stay yours.
|
|
68
|
+
|
|
69
|
+
As a further note, "graph" here means the architecture specification, not a
|
|
70
|
+
graph neural network, which cannot be implemented using `kpnn2` in PyTorch.
|
|
71
|
+
|
|
72
|
+
## Core workflow
|
|
73
|
+
|
|
74
|
+
1. Define a model architecture as an edgelist with named `source`
|
|
75
|
+
and `target` nodes.
|
|
76
|
+
2. Parse it with `parse_layered()` to a `LayeredSpec`. For a graph
|
|
77
|
+
with feedback loops, use `parse_adjacency()` and an
|
|
78
|
+
`AdjacencySpec` instead.
|
|
79
|
+
3. Write an `nn.Module` with one `MaskedLinear` per
|
|
80
|
+
`spec.hops`, feeding each one
|
|
81
|
+
`gather_hop_inputs(saved, hop)`. Skip edges are already
|
|
82
|
+
inside those masks, so there is nothing extra to call.
|
|
83
|
+
4. Align named input tables with `align_inputs()`.
|
|
84
|
+
5. Train with ordinary PyTorch.
|
|
85
|
+
6. Optionally run Captum (or another method) yourself, then label a
|
|
86
|
+
layer tensor with `map_node_attributions()` (returns xarray).
|
|
87
|
+
7. A checkpoint is `spec.to_dict()` plus `state_dict`, not
|
|
88
|
+
weights alone.
|
|
89
|
+
|
|
90
|
+
The snippet below is a minimal run of steps 1–4, using the
|
|
91
|
+
edgelist from the table above. Column order in the input table
|
|
92
|
+
does not matter: `align_inputs()` matches names. Skip edges are
|
|
93
|
+
omitted here; see [**Skip edges**](docs/skip-edges.ipynb). A full
|
|
94
|
+
walkthrough, including training and attribution, is in
|
|
95
|
+
[**Getting started**](docs/getting-started.ipynb).
|
|
96
|
+
|
|
97
|
+
```python
|
|
98
|
+
import pandas as pd
|
|
99
|
+
import torch.nn.functional as F
|
|
100
|
+
from torch import nn
|
|
101
|
+
|
|
102
|
+
import kpnn2
|
|
103
|
+
|
|
104
|
+
edgelist = pd.DataFrame(
|
|
105
|
+
{
|
|
106
|
+
"source": ["A", "B", "H"],
|
|
107
|
+
"target": ["H", "H", "C"],
|
|
108
|
+
}
|
|
109
|
+
)
|
|
110
|
+
spec = kpnn2.parse_layered(edgelist)
|
|
111
|
+
|
|
112
|
+
|
|
113
|
+
class Net(nn.Module):
|
|
114
|
+
def __init__(self, spec: kpnn2.LayeredSpec):
|
|
115
|
+
super().__init__()
|
|
116
|
+
self.lin0 = kpnn2.MaskedLinear(spec.hops[0].mask)
|
|
117
|
+
self.lin1 = kpnn2.MaskedLinear(spec.hops[1].mask)
|
|
118
|
+
|
|
119
|
+
def forward(self, x):
|
|
120
|
+
h = F.relu(self.lin0(x))
|
|
121
|
+
return self.lin1(h)
|
|
122
|
+
|
|
123
|
+
|
|
124
|
+
model = Net(spec)
|
|
125
|
+
x = kpnn2.align_inputs(
|
|
126
|
+
pd.DataFrame({"B": [0.2, 0.4], "A": [0.1, 0.3]}),
|
|
127
|
+
spec,
|
|
128
|
+
)
|
|
129
|
+
y = model(x)
|
|
130
|
+
# Continue training with ordinary PyTorch.
|
|
131
|
+
```
|
|
132
|
+
|
|
133
|
+
## API
|
|
134
|
+
|
|
135
|
+
The documented public names are:
|
|
136
|
+
|
|
137
|
+
- `parse_layered()`
|
|
138
|
+
- `parse_adjacency()`
|
|
139
|
+
- `LayeredSpec`
|
|
140
|
+
- `Hop`
|
|
141
|
+
- `Skip`
|
|
142
|
+
- `AdjacencySpec`
|
|
143
|
+
- `MaskedLinear`
|
|
144
|
+
- `PackedLinear`
|
|
145
|
+
- `gather_hop_inputs()`
|
|
146
|
+
- `align_inputs()`
|
|
147
|
+
- `map_node_attributions()`
|
|
148
|
+
|
|
149
|
+
`LayeredSpec.hops` holds one `Hop` per layer after the first, and
|
|
150
|
+
a hop's mask carries every edge entering that layer, skip edges
|
|
151
|
+
included. `LayeredSpec.skips` lists which edges span layers, as
|
|
152
|
+
metadata. An `AdjacencySpec` has no layers and no skips: it carries
|
|
153
|
+
packed `source_index` / `target_index` over all `nodes`, plus
|
|
154
|
+
`input_index` and `output_index` into that state vector.
|
|
155
|
+
`to_mask()` densifies for `MaskedLinear` on small graphs.
|
|
156
|
+
|
|
157
|
+
See the [**API reference**](docs/api.md) for details, and
|
|
158
|
+
[**Skip edges**](docs/skip-edges.ipynb) for a worked example.
|
|
159
|
+
|
|
160
|
+
## Package philosophy
|
|
161
|
+
|
|
162
|
+
`kpnn2` is intentionally minimally opinionated.
|
|
163
|
+
|
|
164
|
+
It owns edgelist parsing, mask tensors, hop input assembly, named
|
|
165
|
+
input alignment, and attribution column names. It does not impose
|
|
166
|
+
broader modeling choices such as:
|
|
167
|
+
|
|
168
|
+
- activation functions
|
|
169
|
+
- output heads
|
|
170
|
+
- dropout
|
|
171
|
+
- loss functions
|
|
172
|
+
- optimizers
|
|
173
|
+
- training loops
|
|
174
|
+
|
|
175
|
+
Those remain part of the normal PyTorch workflow:
|
|
176
|
+
|
|
177
|
+
- `kpnn2` turns the edgelist into structure you can execute
|
|
178
|
+
- PyTorch handles `forward()`, training, and customization
|
|
179
|
+
- you map trained tensors back to named nodes when you want
|
|
180
|
+
interpretation
|
|
181
|
+
|
|
182
|
+
## Installation
|
|
183
|
+
|
|
184
|
+
Requires Python 3.10 or later.
|
|
185
|
+
|
|
186
|
+
```bash
|
|
187
|
+
pip install kpnn2
|
|
188
|
+
```
|
|
189
|
+
|
|
190
|
+
## Start here
|
|
191
|
+
|
|
192
|
+
If you are new to the package, start with a tutorial:
|
|
193
|
+
|
|
194
|
+
- [**Installation**](docs/installation.md) for package setup
|
|
195
|
+
- [**Getting started**](docs/getting-started.ipynb) for a full
|
|
196
|
+
end-to-end feedforward example
|
|
197
|
+
- [**Recurrent example**](docs/recurrent-example.ipynb) for
|
|
198
|
+
`parse_adjacency()` and a shared `MaskedLinear` over one state
|
|
199
|
+
vector when the graph has feedback loops (`parse_layered` still
|
|
200
|
+
requires a DAG)
|
|
201
|
+
|
|
202
|
+
The other pages explain a design choice; they are not second
|
|
203
|
+
examples:
|
|
204
|
+
|
|
205
|
+
- [**Layered vs. Adjacency**](docs/layered_vs_adjacency.md) for
|
|
206
|
+
how the two parsers differ and when to pick one
|
|
207
|
+
- [**Skip edges**](docs/skip-edges.ipynb) for edges that jump a
|
|
208
|
+
layer, and why they need no separate mechanism
|
|
209
|
+
- [**Mapping attributions**](docs/map-node-attributions.ipynb) for
|
|
210
|
+
labeling layer tensors with node names
|
|
211
|
+
- [**PackedLinear**](docs/packed_linear.md) when `n` is large on
|
|
212
|
+
an `AdjacencySpec`
|
|
213
|
+
- [**API reference**](docs/api.md) for function- and object-level
|
|
214
|
+
documentation
|
|
215
|
+
|
|
216
|
+
## Citation
|
|
217
|
+
|
|
218
|
+
If you use `kpnn2` in research, please cite the software.
|
|
219
|
+
Citation metadata is available in
|
|
220
|
+
[`CITATION.cff`](https://github.com/Thomas-Rauter/kpnn2/blob/main/CITATION.cff).
|
|
221
|
+
|
|
222
|
+
## License
|
|
223
|
+
|
|
224
|
+
This project is licensed under the MIT License. See the
|
|
225
|
+
[LICENSE file on GitHub](https://github.com/Thomas-Rauter/kpnn2/blob/main/LICENSE)
|
|
226
|
+
for details.
|