kaggle-dataset-lint 0.3.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- kaggle_dataset_lint-0.3.0/LICENSE +21 -0
- kaggle_dataset_lint-0.3.0/PKG-INFO +182 -0
- kaggle_dataset_lint-0.3.0/README.md +149 -0
- kaggle_dataset_lint-0.3.0/pyproject.toml +48 -0
- kaggle_dataset_lint-0.3.0/setup.cfg +4 -0
- kaggle_dataset_lint-0.3.0/src/kaggle_dataset_lint.egg-info/PKG-INFO +182 -0
- kaggle_dataset_lint-0.3.0/src/kaggle_dataset_lint.egg-info/SOURCES.txt +14 -0
- kaggle_dataset_lint-0.3.0/src/kaggle_dataset_lint.egg-info/dependency_links.txt +1 -0
- kaggle_dataset_lint-0.3.0/src/kaggle_dataset_lint.egg-info/entry_points.txt +2 -0
- kaggle_dataset_lint-0.3.0/src/kaggle_dataset_lint.egg-info/requires.txt +21 -0
- kaggle_dataset_lint-0.3.0/src/kaggle_dataset_lint.egg-info/top_level.txt +1 -0
- kaggle_dataset_lint-0.3.0/src/kaggle_dataset_lint.py +400 -0
- kaggle_dataset_lint-0.3.0/tests/test_builds.py +49 -0
- kaggle_dataset_lint-0.3.0/tests/test_lint.py +227 -0
- kaggle_dataset_lint-0.3.0/tests/test_push_cover.py +38 -0
- kaggle_dataset_lint-0.3.0/tests/test_smoke.py +81 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 tb91117
|
|
4
|
+
|
|
5
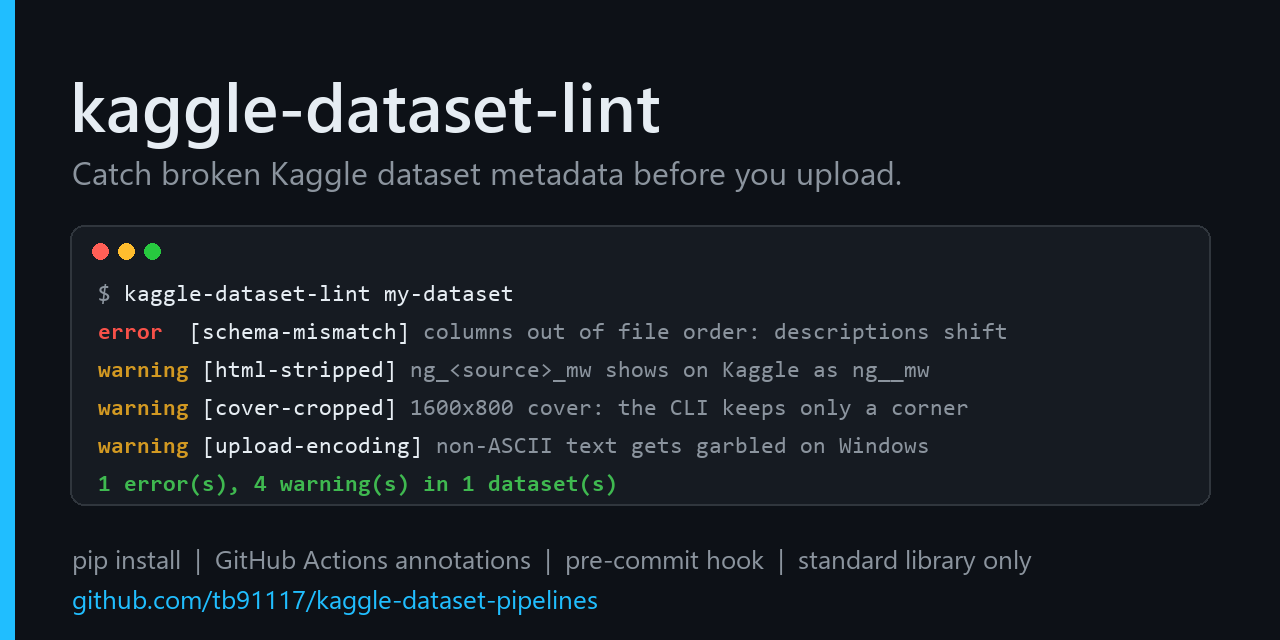
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,182 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: kaggle-dataset-lint
|
|
3
|
+
Version: 0.3.0
|
|
4
|
+
Summary: Lint Kaggle dataset metadata (dataset-metadata.json) before you upload
|
|
5
|
+
License-Expression: MIT
|
|
6
|
+
Project-URL: Homepage, https://github.com/tb91117/kaggle-dataset-pipelines
|
|
7
|
+
Project-URL: Issues, https://github.com/tb91117/kaggle-dataset-pipelines/issues
|
|
8
|
+
Keywords: kaggle,datasets,lint,metadata,open-data,data-pipeline
|
|
9
|
+
Classifier: Programming Language :: Python :: 3
|
|
10
|
+
Classifier: Environment :: Console
|
|
11
|
+
Classifier: Topic :: Scientific/Engineering
|
|
12
|
+
Classifier: Topic :: Software Development :: Quality Assurance
|
|
13
|
+
Requires-Python: >=3.10
|
|
14
|
+
Description-Content-Type: text/markdown
|
|
15
|
+
License-File: LICENSE
|
|
16
|
+
Provides-Extra: parquet
|
|
17
|
+
Requires-Dist: pyarrow>=14; extra == "parquet"
|
|
18
|
+
Provides-Extra: pipelines
|
|
19
|
+
Requires-Dist: pandas>=2.0; extra == "pipelines"
|
|
20
|
+
Requires-Dist: numpy>=1.24; extra == "pipelines"
|
|
21
|
+
Requires-Dist: pyarrow>=14; extra == "pipelines"
|
|
22
|
+
Requires-Dist: matplotlib>=3.7; extra == "pipelines"
|
|
23
|
+
Requires-Dist: pillow>=10; extra == "pipelines"
|
|
24
|
+
Requires-Dist: openpyxl>=3.1; extra == "pipelines"
|
|
25
|
+
Provides-Extra: publish
|
|
26
|
+
Requires-Dist: kaggle>=2.2.5; extra == "publish"
|
|
27
|
+
Provides-Extra: notebooks
|
|
28
|
+
Requires-Dist: nbformat>=5.9; extra == "notebooks"
|
|
29
|
+
Provides-Extra: dev
|
|
30
|
+
Requires-Dist: ruff>=0.6; extra == "dev"
|
|
31
|
+
Requires-Dist: pytest>=8; extra == "dev"
|
|
32
|
+
Dynamic: license-file
|
|
33
|
+
|
|
34
|
+
# kaggle-dataset-pipelines
|
|
35
|
+
|
|
36
|
+
[](https://github.com/tb91117/kaggle-dataset-pipelines/actions/workflows/ci.yml)
|
|
37
|
+
[](https://github.com/tb91117/kaggle-dataset-pipelines/blob/main/LICENSE)
|
|
38
|
+
|
|
39
|
+
**Lint your Kaggle dataset before you upload it**, plus the build scripts behind
|
|
40
|
+
[six public Kaggle datasets](#datasets-built-with-this-repo).
|
|
41
|
+
|
|
42
|
+
|
|
43
|
+
|
|
44
|
+
## kaggle-dataset-lint
|
|
45
|
+
|
|
46
|
+
Kaggle accepts a `dataset-metadata.json` that is subtly wrong and then shows a broken dataset page. Four examples;
|
|
47
|
+
all but the cover crop were found in published datasets:
|
|
48
|
+
|
|
49
|
+
- **Column descriptions on the wrong columns.** Kaggle matches schema fields to columns *by position*, so two swapped
|
|
50
|
+
fields shift the descriptions without any error.
|
|
51
|
+
- **Text that disappears.** Kaggle's renderer drops unknown HTML tags, so `ng_<source>_mw` in a description shows as
|
|
52
|
+
`ng__mw`.
|
|
53
|
+
- **A cover that shows only its corner.** The Kaggle CLI always crops the top-left 560x280 pixels, whatever the image
|
|
54
|
+
size.
|
|
55
|
+
- **Garbled text from Windows.** The CLI reads `dataset-metadata.json` with the system encoding, so on most Windows
|
|
56
|
+
machines a `×` in a UTF-8 description reaches Kaggle as two other characters. Set `PYTHONUTF8=1` before uploading.
|
|
57
|
+
|
|
58
|
+
```bash
|
|
59
|
+
pip install kaggle-dataset-lint
|
|
60
|
+
kaggle-dataset-lint path/to/my-dataset # the folder you pass to `kaggle datasets create -p`
|
|
61
|
+
```
|
|
62
|
+
|
|
63
|
+
No dependencies: it is a single standard-library file, so you can also just download
|
|
64
|
+
[`src/kaggle_dataset_lint.py`](https://github.com/tb91117/kaggle-dataset-pipelines/blob/main/src/kaggle_dataset_lint.py) and run `python kaggle_dataset_lint.py my-dataset`.
|
|
65
|
+
Install `pyarrow` too if you want Parquet columns checked.
|
|
66
|
+
|
|
67
|
+
```text
|
|
68
|
+
my-dataset/dataset-metadata.json: error: [title-length] title is 51 characters; Kaggle allows 6-50
|
|
69
|
+
my-dataset/dataset-metadata.json: warning: [html-stripped] description contains <unit>: Kaggle's renderer drops unknown HTML tags, so the text disappears (`ng_<source>_mw` shows as `ng__mw`). Write {unit} or <unit>
|
|
70
|
+
my-dataset/dataset-metadata.json: warning: [cover-cropped] dataset-cover-image.png is 1600x800, but the Kaggle CLI always crops the top-left 560x280 pixels for the header and a 280x280 square at x=140 for the thumbnail. Resize it to 560x280, or set the cover in the web UI
|
|
71
|
+
my-dataset/dataset-metadata.json: error: [schema-mismatch] readings.csv: schema fields must list every column in file order, or Kaggle attaches the descriptions to the wrong columns (first difference at position 1: schema has 'station', file has 'time')
|
|
72
|
+
my-dataset/dataset-metadata.json: warning: [file-undeclared] no resource entry (so no file or column descriptions) for: notes.txt
|
|
73
|
+
my-dataset/dataset-metadata.json: warning: [subfolder-skipped] raw/ is skipped by `kaggle datasets create/version` unless you pass --dir-mode zip or tar
|
|
74
|
+
2 error(s), 4 warning(s) in 1 dataset(s)
|
|
75
|
+
```
|
|
76
|
+
|
|
77
|
+
### What it checks
|
|
78
|
+
|
|
79
|
+
| Level | Checks |
|
|
80
|
+
|---|---|
|
|
81
|
+
| **Error**: Kaggle rejects it, or the page comes out wrong | title 6-50 characters, subtitle 20-80, exactly one license, `id` is `owner/slug` (no `INSERT_..._HERE` placeholders), valid `expectedUpdateFrequency`, every declared file exists and is declared once, schema fields list every column in file order (CSV, TSV, Parquet), cover is .png/.jpg/.jpeg/.webp and at least 560x280 |
|
|
82
|
+
| **Warning**: silent problems and incomplete pages | `<word>` placeholders Kaggle strips, covers the CLI crops to a corner, subfolders `kaggle datasets create/version` skips, non-ASCII text the CLI would garble because it reads the file with the system encoding (cp1252 on most Windows machines), files and columns without descriptions, missing subtitle, description, tags, sources, update frequency or cover image, slugs `kaggle datasets create` rejects |
|
|
83
|
+
| **Note**: worth a look, never fails | license names that aren't in Kaggle's documented ids, column types outside Kaggle's best-effort list |
|
|
84
|
+
|
|
85
|
+
The rules come from the Kaggle CLI source and its
|
|
86
|
+
[dataset metadata docs](https://github.com/Kaggle/kaggle-cli/blob/main/docs/datasets_metadata.md). It also reads the
|
|
87
|
+
`{"info": ...}` layout that `kaggle datasets metadata` downloads.
|
|
88
|
+
|
|
89
|
+
### Options
|
|
90
|
+
|
|
91
|
+
- `--strict`: exit 1 on warnings as well as errors.
|
|
92
|
+
- `--no-files`: check only the metadata, not data files or the cover.
|
|
93
|
+
- `--ignore cover-missing,keywords-missing`: skip findings by code.
|
|
94
|
+
- `--format github`: print GitHub Actions annotations.
|
|
95
|
+
|
|
96
|
+
### In CI or pre-commit
|
|
97
|
+
|
|
98
|
+
```yaml
|
|
99
|
+
# GitHub Actions
|
|
100
|
+
- run: pip install kaggle-dataset-lint==0.3.0
|
|
101
|
+
- run: kaggle-dataset-lint --format github data/my-dataset
|
|
102
|
+
```
|
|
103
|
+
|
|
104
|
+
```yaml
|
|
105
|
+
# .pre-commit-config.yaml
|
|
106
|
+
repos:
|
|
107
|
+
- repo: https://github.com/tb91117/kaggle-dataset-pipelines
|
|
108
|
+
rev: v0.3.0
|
|
109
|
+
hooks:
|
|
110
|
+
- id: kaggle-dataset-lint
|
|
111
|
+
```
|
|
112
|
+
|
|
113
|
+
## Open-data pipelines
|
|
114
|
+
|
|
115
|
+
Each pipeline downloads an official public source, builds tidy Parquet/CSV files with typed columns, writes a full
|
|
116
|
+
`dataset-metadata.json` (title, subtitle, description, per-column descriptions, license, keywords) and renders a cover
|
|
117
|
+
image. Re-running a pipeline refreshes the dataset, so the Kaggle version stays current with the source. Every build is
|
|
118
|
+
tested on small real-data samples and must pass the linter.
|
|
119
|
+
|
|
120
|
+
### Datasets built with this repo
|
|
121
|
+
|
|
122
|
+
| Dataset on Kaggle | Source | Pipeline |
|
|
123
|
+
|---|---|---|
|
|
124
|
+
| [US Flight Delays & On-Time Performance 2022–2026](https://www.kaggle.com/datasets/teddybrown414/us-flight-delays-and-on-time-performance-2022-2026) | BTS *Reporting Carrier On-Time Performance* | `fetch_bts.py` → `build_bts.py` |
|
|
125
|
+
| [US Electric Grid Hourly Data (EIA-930)](https://www.kaggle.com/datasets/teddybrown414/us-electric-grid-hourly-eia-930) | EIA Hourly Electric Grid Monitor, six-month BALANCE files | `fetch_eia930.py` → `build_eia930.py` |
|
|
126
|
+
| [World Development Indicators 1960–2025](https://www.kaggle.com/datasets/teddybrown414/world-bank-world-development-indicators) | World Bank WDI bulk CSV | `fetch_wdi.py` → `build_wdi.py` |
|
|
127
|
+
| [San Francisco Street Tree Inventory](https://www.kaggle.com/datasets/teddybrown414/san-francisco-trees) | DataSF `tkzw-k3nq` (SODA API) | `fetch_sf_trees.py` → `build_v2.py trees` |
|
|
128
|
+
| [BTC/USDT 15-min Candles + Indicators 2017–2025](https://www.kaggle.com/datasets/teddybrown414/binance-ohlc-with-indicators) | Binance public market-data API (spot BTCUSDT, 15-minute klines) | `build_v2.py binance` |
|
|
129
|
+
| [Query Intent Routing for AI Assistants](https://www.kaggle.com/datasets/teddybrown414/data-for-classifying-intent-of-query) | Written by the dataset author for an assistant tool-routing prototype | `build_v2.py intent` |
|
|
130
|
+
|
|
131
|
+
The last two are rebuilt from the author's own source files, so they have no fetch step.
|
|
132
|
+
|
|
133
|
+
### Quick start
|
|
134
|
+
|
|
135
|
+
```bash
|
|
136
|
+
pip install -e ".[pipelines]"
|
|
137
|
+
python -I tools/fetch_eia930.py # downloads into datasets/eia930-hourly-grid/source/ (resumable)
|
|
138
|
+
python -I tools/build_eia930.py # writes datasets/eia930-hourly-grid/v1/ (data + metadata + cover)
|
|
139
|
+
```
|
|
140
|
+
|
|
141
|
+
Nothing is uploaded by the build scripts. Publishing is a separate, explicit step:
|
|
142
|
+
|
|
143
|
+
```bash
|
|
144
|
+
kaggle datasets version -p datasets/eia930-hourly-grid/v1 -m "Refresh"
|
|
145
|
+
python -I tools/push_cover.py datasets/eia930-hourly-grid/v1 <owner>/<slug> # cover with a correct crop
|
|
146
|
+
```
|
|
147
|
+
|
|
148
|
+
### Run on Kaggle instead of locally
|
|
149
|
+
|
|
150
|
+
Some sources are large (the BTS files are several GB). `make_kaggle_pipeline.py` assembles fetch + build + cover
|
|
151
|
+
into one self-contained Kaggle script kernel, so the download happens on Kaggle's servers:
|
|
152
|
+
|
|
153
|
+
```bash
|
|
154
|
+
python -I tools/make_kaggle_pipeline.py wdi none # bts | eia930 | wdi | trees; none = build only
|
|
155
|
+
kaggle kernels push -p pipelines/world-bank-wdi-dataset-pipeline
|
|
156
|
+
```
|
|
157
|
+
|
|
158
|
+
The kernel's output folder is the finished dataset: create or update the Kaggle dataset from it
|
|
159
|
+
(dataset page → New version → Notebook output). For `eia930`, `wdi` and `trees` the repo's scripts are embedded
|
|
160
|
+
verbatim and run as files with `KDP_DATA_ROOT` pointing at Kaggle's scratch disk, so a kernel run and a local run
|
|
161
|
+
produce the same files.
|
|
162
|
+
|
|
163
|
+
With `private` or `public`, the kernel reads a Kaggle Secret named `KAGGLE_API_TOKEN` (Notebook → Add-ons → Secrets).
|
|
164
|
+
|
|
165
|
+
### Tools
|
|
166
|
+
|
|
167
|
+
| Script | What it does |
|
|
168
|
+
|---|---|
|
|
169
|
+
| `src/kaggle_dataset_lint.py` | The linter above (`kaggle-dataset-lint`). |
|
|
170
|
+
| `fetch_*.py` | Resumable downloaders with retries; complete files are skipped on re-run. |
|
|
171
|
+
| `KDP_DATA_ROOT` | Environment variable: where sources are downloaded and datasets are built (default `./datasets`). |
|
|
172
|
+
| `build_*.py` | Clean, type and document a source into a Kaggle-ready folder. |
|
|
173
|
+
| `make_covers.py` | One distinct 2:1 cover design per dataset (no title text; Kaggle shows the title). |
|
|
174
|
+
| `push_cover.py` | Uploads metadata + cover with a crop that covers the whole image (the kaggle CLI crops the top-left corner). |
|
|
175
|
+
| `make_kaggle_pipeline.py` | Turns a fetch + build pair into a single Kaggle script kernel. |
|
|
176
|
+
| `make_notebooks.py` | Generates the example notebooks that accompany each dataset. |
|
|
177
|
+
| `profile_csv.py` | Prints a compact column profile of every CSV under a dataset folder. |
|
|
178
|
+
|
|
179
|
+
## Licenses
|
|
180
|
+
|
|
181
|
+
The code in this repo is MIT-licensed. The data keeps its source license: BTS and EIA data are US government works
|
|
182
|
+
(public domain), World Bank WDI is CC BY 4.0, and DataSF publishes under ODC-PDDL. Check each source before reuse.
|
|
@@ -0,0 +1,149 @@
|
|
|
1
|
+
# kaggle-dataset-pipelines
|
|
2
|
+
|
|
3
|
+
[](https://github.com/tb91117/kaggle-dataset-pipelines/actions/workflows/ci.yml)
|
|
4
|
+
[](https://github.com/tb91117/kaggle-dataset-pipelines/blob/main/LICENSE)
|
|
5
|
+
|
|
6
|
+
**Lint your Kaggle dataset before you upload it**, plus the build scripts behind
|
|
7
|
+
[six public Kaggle datasets](#datasets-built-with-this-repo).
|
|
8
|
+
|
|
9
|
+

|
|
10
|
+
|
|
11
|
+
## kaggle-dataset-lint
|
|
12
|
+
|
|
13
|
+
Kaggle accepts a `dataset-metadata.json` that is subtly wrong and then shows a broken dataset page. Four examples;
|
|
14
|
+
all but the cover crop were found in published datasets:
|
|
15
|
+
|
|
16
|
+
- **Column descriptions on the wrong columns.** Kaggle matches schema fields to columns *by position*, so two swapped
|
|
17
|
+
fields shift the descriptions without any error.
|
|
18
|
+
- **Text that disappears.** Kaggle's renderer drops unknown HTML tags, so `ng_<source>_mw` in a description shows as
|
|
19
|
+
`ng__mw`.
|
|
20
|
+
- **A cover that shows only its corner.** The Kaggle CLI always crops the top-left 560x280 pixels, whatever the image
|
|
21
|
+
size.
|
|
22
|
+
- **Garbled text from Windows.** The CLI reads `dataset-metadata.json` with the system encoding, so on most Windows
|
|
23
|
+
machines a `×` in a UTF-8 description reaches Kaggle as two other characters. Set `PYTHONUTF8=1` before uploading.
|
|
24
|
+
|
|
25
|
+
```bash
|
|
26
|
+
pip install kaggle-dataset-lint
|
|
27
|
+
kaggle-dataset-lint path/to/my-dataset # the folder you pass to `kaggle datasets create -p`
|
|
28
|
+
```
|
|
29
|
+
|
|
30
|
+
No dependencies: it is a single standard-library file, so you can also just download
|
|
31
|
+
[`src/kaggle_dataset_lint.py`](https://github.com/tb91117/kaggle-dataset-pipelines/blob/main/src/kaggle_dataset_lint.py) and run `python kaggle_dataset_lint.py my-dataset`.
|
|
32
|
+
Install `pyarrow` too if you want Parquet columns checked.
|
|
33
|
+
|
|
34
|
+
```text
|
|
35
|
+
my-dataset/dataset-metadata.json: error: [title-length] title is 51 characters; Kaggle allows 6-50
|
|
36
|
+
my-dataset/dataset-metadata.json: warning: [html-stripped] description contains <unit>: Kaggle's renderer drops unknown HTML tags, so the text disappears (`ng_<source>_mw` shows as `ng__mw`). Write {unit} or <unit>
|
|
37
|
+
my-dataset/dataset-metadata.json: warning: [cover-cropped] dataset-cover-image.png is 1600x800, but the Kaggle CLI always crops the top-left 560x280 pixels for the header and a 280x280 square at x=140 for the thumbnail. Resize it to 560x280, or set the cover in the web UI
|
|
38
|
+
my-dataset/dataset-metadata.json: error: [schema-mismatch] readings.csv: schema fields must list every column in file order, or Kaggle attaches the descriptions to the wrong columns (first difference at position 1: schema has 'station', file has 'time')
|
|
39
|
+
my-dataset/dataset-metadata.json: warning: [file-undeclared] no resource entry (so no file or column descriptions) for: notes.txt
|
|
40
|
+
my-dataset/dataset-metadata.json: warning: [subfolder-skipped] raw/ is skipped by `kaggle datasets create/version` unless you pass --dir-mode zip or tar
|
|
41
|
+
2 error(s), 4 warning(s) in 1 dataset(s)
|
|
42
|
+
```
|
|
43
|
+
|
|
44
|
+
### What it checks
|
|
45
|
+
|
|
46
|
+
| Level | Checks |
|
|
47
|
+
|---|---|
|
|
48
|
+
| **Error**: Kaggle rejects it, or the page comes out wrong | title 6-50 characters, subtitle 20-80, exactly one license, `id` is `owner/slug` (no `INSERT_..._HERE` placeholders), valid `expectedUpdateFrequency`, every declared file exists and is declared once, schema fields list every column in file order (CSV, TSV, Parquet), cover is .png/.jpg/.jpeg/.webp and at least 560x280 |
|
|
49
|
+
| **Warning**: silent problems and incomplete pages | `<word>` placeholders Kaggle strips, covers the CLI crops to a corner, subfolders `kaggle datasets create/version` skips, non-ASCII text the CLI would garble because it reads the file with the system encoding (cp1252 on most Windows machines), files and columns without descriptions, missing subtitle, description, tags, sources, update frequency or cover image, slugs `kaggle datasets create` rejects |
|
|
50
|
+
| **Note**: worth a look, never fails | license names that aren't in Kaggle's documented ids, column types outside Kaggle's best-effort list |
|
|
51
|
+
|
|
52
|
+
The rules come from the Kaggle CLI source and its
|
|
53
|
+
[dataset metadata docs](https://github.com/Kaggle/kaggle-cli/blob/main/docs/datasets_metadata.md). It also reads the
|
|
54
|
+
`{"info": ...}` layout that `kaggle datasets metadata` downloads.
|
|
55
|
+
|
|
56
|
+
### Options
|
|
57
|
+
|
|
58
|
+
- `--strict`: exit 1 on warnings as well as errors.
|
|
59
|
+
- `--no-files`: check only the metadata, not data files or the cover.
|
|
60
|
+
- `--ignore cover-missing,keywords-missing`: skip findings by code.
|
|
61
|
+
- `--format github`: print GitHub Actions annotations.
|
|
62
|
+
|
|
63
|
+
### In CI or pre-commit
|
|
64
|
+
|
|
65
|
+
```yaml
|
|
66
|
+
# GitHub Actions
|
|
67
|
+
- run: pip install kaggle-dataset-lint==0.3.0
|
|
68
|
+
- run: kaggle-dataset-lint --format github data/my-dataset
|
|
69
|
+
```
|
|
70
|
+
|
|
71
|
+
```yaml
|
|
72
|
+
# .pre-commit-config.yaml
|
|
73
|
+
repos:
|
|
74
|
+
- repo: https://github.com/tb91117/kaggle-dataset-pipelines
|
|
75
|
+
rev: v0.3.0
|
|
76
|
+
hooks:
|
|
77
|
+
- id: kaggle-dataset-lint
|
|
78
|
+
```
|
|
79
|
+
|
|
80
|
+
## Open-data pipelines
|
|
81
|
+
|
|
82
|
+
Each pipeline downloads an official public source, builds tidy Parquet/CSV files with typed columns, writes a full
|
|
83
|
+
`dataset-metadata.json` (title, subtitle, description, per-column descriptions, license, keywords) and renders a cover
|
|
84
|
+
image. Re-running a pipeline refreshes the dataset, so the Kaggle version stays current with the source. Every build is
|
|
85
|
+
tested on small real-data samples and must pass the linter.
|
|
86
|
+
|
|
87
|
+
### Datasets built with this repo
|
|
88
|
+
|
|
89
|
+
| Dataset on Kaggle | Source | Pipeline |
|
|
90
|
+
|---|---|---|
|
|
91
|
+
| [US Flight Delays & On-Time Performance 2022–2026](https://www.kaggle.com/datasets/teddybrown414/us-flight-delays-and-on-time-performance-2022-2026) | BTS *Reporting Carrier On-Time Performance* | `fetch_bts.py` → `build_bts.py` |
|
|
92
|
+
| [US Electric Grid Hourly Data (EIA-930)](https://www.kaggle.com/datasets/teddybrown414/us-electric-grid-hourly-eia-930) | EIA Hourly Electric Grid Monitor, six-month BALANCE files | `fetch_eia930.py` → `build_eia930.py` |
|
|
93
|
+
| [World Development Indicators 1960–2025](https://www.kaggle.com/datasets/teddybrown414/world-bank-world-development-indicators) | World Bank WDI bulk CSV | `fetch_wdi.py` → `build_wdi.py` |
|
|
94
|
+
| [San Francisco Street Tree Inventory](https://www.kaggle.com/datasets/teddybrown414/san-francisco-trees) | DataSF `tkzw-k3nq` (SODA API) | `fetch_sf_trees.py` → `build_v2.py trees` |
|
|
95
|
+
| [BTC/USDT 15-min Candles + Indicators 2017–2025](https://www.kaggle.com/datasets/teddybrown414/binance-ohlc-with-indicators) | Binance public market-data API (spot BTCUSDT, 15-minute klines) | `build_v2.py binance` |
|
|
96
|
+
| [Query Intent Routing for AI Assistants](https://www.kaggle.com/datasets/teddybrown414/data-for-classifying-intent-of-query) | Written by the dataset author for an assistant tool-routing prototype | `build_v2.py intent` |
|
|
97
|
+
|
|
98
|
+
The last two are rebuilt from the author's own source files, so they have no fetch step.
|
|
99
|
+
|
|
100
|
+
### Quick start
|
|
101
|
+
|
|
102
|
+
```bash
|
|
103
|
+
pip install -e ".[pipelines]"
|
|
104
|
+
python -I tools/fetch_eia930.py # downloads into datasets/eia930-hourly-grid/source/ (resumable)
|
|
105
|
+
python -I tools/build_eia930.py # writes datasets/eia930-hourly-grid/v1/ (data + metadata + cover)
|
|
106
|
+
```
|
|
107
|
+
|
|
108
|
+
Nothing is uploaded by the build scripts. Publishing is a separate, explicit step:
|
|
109
|
+
|
|
110
|
+
```bash
|
|
111
|
+
kaggle datasets version -p datasets/eia930-hourly-grid/v1 -m "Refresh"
|
|
112
|
+
python -I tools/push_cover.py datasets/eia930-hourly-grid/v1 <owner>/<slug> # cover with a correct crop
|
|
113
|
+
```
|
|
114
|
+
|
|
115
|
+
### Run on Kaggle instead of locally
|
|
116
|
+
|
|
117
|
+
Some sources are large (the BTS files are several GB). `make_kaggle_pipeline.py` assembles fetch + build + cover
|
|
118
|
+
into one self-contained Kaggle script kernel, so the download happens on Kaggle's servers:
|
|
119
|
+
|
|
120
|
+
```bash
|
|
121
|
+
python -I tools/make_kaggle_pipeline.py wdi none # bts | eia930 | wdi | trees; none = build only
|
|
122
|
+
kaggle kernels push -p pipelines/world-bank-wdi-dataset-pipeline
|
|
123
|
+
```
|
|
124
|
+
|
|
125
|
+
The kernel's output folder is the finished dataset: create or update the Kaggle dataset from it
|
|
126
|
+
(dataset page → New version → Notebook output). For `eia930`, `wdi` and `trees` the repo's scripts are embedded
|
|
127
|
+
verbatim and run as files with `KDP_DATA_ROOT` pointing at Kaggle's scratch disk, so a kernel run and a local run
|
|
128
|
+
produce the same files.
|
|
129
|
+
|
|
130
|
+
With `private` or `public`, the kernel reads a Kaggle Secret named `KAGGLE_API_TOKEN` (Notebook → Add-ons → Secrets).
|
|
131
|
+
|
|
132
|
+
### Tools
|
|
133
|
+
|
|
134
|
+
| Script | What it does |
|
|
135
|
+
|---|---|
|
|
136
|
+
| `src/kaggle_dataset_lint.py` | The linter above (`kaggle-dataset-lint`). |
|
|
137
|
+
| `fetch_*.py` | Resumable downloaders with retries; complete files are skipped on re-run. |
|
|
138
|
+
| `KDP_DATA_ROOT` | Environment variable: where sources are downloaded and datasets are built (default `./datasets`). |
|
|
139
|
+
| `build_*.py` | Clean, type and document a source into a Kaggle-ready folder. |
|
|
140
|
+
| `make_covers.py` | One distinct 2:1 cover design per dataset (no title text; Kaggle shows the title). |
|
|
141
|
+
| `push_cover.py` | Uploads metadata + cover with a crop that covers the whole image (the kaggle CLI crops the top-left corner). |
|
|
142
|
+
| `make_kaggle_pipeline.py` | Turns a fetch + build pair into a single Kaggle script kernel. |
|
|
143
|
+
| `make_notebooks.py` | Generates the example notebooks that accompany each dataset. |
|
|
144
|
+
| `profile_csv.py` | Prints a compact column profile of every CSV under a dataset folder. |
|
|
145
|
+
|
|
146
|
+
## Licenses
|
|
147
|
+
|
|
148
|
+
The code in this repo is MIT-licensed. The data keeps its source license: BTS and EIA data are US government works
|
|
149
|
+
(public domain), World Bank WDI is CC BY 4.0, and DataSF publishes under ODC-PDDL. Check each source before reuse.
|
|
@@ -0,0 +1,48 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "kaggle-dataset-lint"
|
|
3
|
+
version = "0.3.0"
|
|
4
|
+
description = "Lint Kaggle dataset metadata (dataset-metadata.json) before you upload"
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
requires-python = ">=3.10"
|
|
8
|
+
keywords = ["kaggle", "datasets", "lint", "metadata", "open-data", "data-pipeline"]
|
|
9
|
+
classifiers = [
|
|
10
|
+
"Programming Language :: Python :: 3",
|
|
11
|
+
"Environment :: Console",
|
|
12
|
+
"Topic :: Scientific/Engineering",
|
|
13
|
+
"Topic :: Software Development :: Quality Assurance",
|
|
14
|
+
]
|
|
15
|
+
dependencies = [] # the linter is standard library only
|
|
16
|
+
|
|
17
|
+
[project.optional-dependencies]
|
|
18
|
+
parquet = ["pyarrow>=14"] # lets the linter check Parquet columns
|
|
19
|
+
pipelines = [
|
|
20
|
+
"pandas>=2.0",
|
|
21
|
+
"numpy>=1.24",
|
|
22
|
+
"pyarrow>=14",
|
|
23
|
+
"matplotlib>=3.7",
|
|
24
|
+
"pillow>=10",
|
|
25
|
+
"openpyxl>=3.1",
|
|
26
|
+
]
|
|
27
|
+
publish = ["kaggle>=2.2.5"]
|
|
28
|
+
notebooks = ["nbformat>=5.9"]
|
|
29
|
+
dev = ["ruff>=0.6", "pytest>=8"]
|
|
30
|
+
|
|
31
|
+
[project.scripts]
|
|
32
|
+
kaggle-dataset-lint = "kaggle_dataset_lint:main"
|
|
33
|
+
|
|
34
|
+
[project.urls]
|
|
35
|
+
Homepage = "https://github.com/tb91117/kaggle-dataset-pipelines"
|
|
36
|
+
Issues = "https://github.com/tb91117/kaggle-dataset-pipelines/issues"
|
|
37
|
+
|
|
38
|
+
[tool.ruff]
|
|
39
|
+
line-length = 130
|
|
40
|
+
target-version = "py310"
|
|
41
|
+
|
|
42
|
+
[build-system]
|
|
43
|
+
requires = ["setuptools>=77"]
|
|
44
|
+
build-backend = "setuptools.build_meta"
|
|
45
|
+
|
|
46
|
+
[tool.setuptools]
|
|
47
|
+
package-dir = { "" = "src" }
|
|
48
|
+
py-modules = ["kaggle_dataset_lint"] # the pipelines in tools/ are scripts, not part of the package
|
|
@@ -0,0 +1,182 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: kaggle-dataset-lint
|
|
3
|
+
Version: 0.3.0
|
|
4
|
+
Summary: Lint Kaggle dataset metadata (dataset-metadata.json) before you upload
|
|
5
|
+
License-Expression: MIT
|
|
6
|
+
Project-URL: Homepage, https://github.com/tb91117/kaggle-dataset-pipelines
|
|
7
|
+
Project-URL: Issues, https://github.com/tb91117/kaggle-dataset-pipelines/issues
|
|
8
|
+
Keywords: kaggle,datasets,lint,metadata,open-data,data-pipeline
|
|
9
|
+
Classifier: Programming Language :: Python :: 3
|
|
10
|
+
Classifier: Environment :: Console
|
|
11
|
+
Classifier: Topic :: Scientific/Engineering
|
|
12
|
+
Classifier: Topic :: Software Development :: Quality Assurance
|
|
13
|
+
Requires-Python: >=3.10
|
|
14
|
+
Description-Content-Type: text/markdown
|
|
15
|
+
License-File: LICENSE
|
|
16
|
+
Provides-Extra: parquet
|
|
17
|
+
Requires-Dist: pyarrow>=14; extra == "parquet"
|
|
18
|
+
Provides-Extra: pipelines
|
|
19
|
+
Requires-Dist: pandas>=2.0; extra == "pipelines"
|
|
20
|
+
Requires-Dist: numpy>=1.24; extra == "pipelines"
|
|
21
|
+
Requires-Dist: pyarrow>=14; extra == "pipelines"
|
|
22
|
+
Requires-Dist: matplotlib>=3.7; extra == "pipelines"
|
|
23
|
+
Requires-Dist: pillow>=10; extra == "pipelines"
|
|
24
|
+
Requires-Dist: openpyxl>=3.1; extra == "pipelines"
|
|
25
|
+
Provides-Extra: publish
|
|
26
|
+
Requires-Dist: kaggle>=2.2.5; extra == "publish"
|
|
27
|
+
Provides-Extra: notebooks
|
|
28
|
+
Requires-Dist: nbformat>=5.9; extra == "notebooks"
|
|
29
|
+
Provides-Extra: dev
|
|
30
|
+
Requires-Dist: ruff>=0.6; extra == "dev"
|
|
31
|
+
Requires-Dist: pytest>=8; extra == "dev"
|
|
32
|
+
Dynamic: license-file
|
|
33
|
+
|
|
34
|
+
# kaggle-dataset-pipelines
|
|
35
|
+
|
|
36
|
+
[](https://github.com/tb91117/kaggle-dataset-pipelines/actions/workflows/ci.yml)
|
|
37
|
+
[](https://github.com/tb91117/kaggle-dataset-pipelines/blob/main/LICENSE)
|
|
38
|
+
|
|
39
|
+
**Lint your Kaggle dataset before you upload it**, plus the build scripts behind
|
|
40
|
+
[six public Kaggle datasets](#datasets-built-with-this-repo).
|
|
41
|
+
|
|
42
|
+

|
|
43
|
+
|
|
44
|
+
## kaggle-dataset-lint
|
|
45
|
+
|
|
46
|
+
Kaggle accepts a `dataset-metadata.json` that is subtly wrong and then shows a broken dataset page. Four examples;
|
|
47
|
+
all but the cover crop were found in published datasets:
|
|
48
|
+
|
|
49
|
+
- **Column descriptions on the wrong columns.** Kaggle matches schema fields to columns *by position*, so two swapped
|
|
50
|
+
fields shift the descriptions without any error.
|
|
51
|
+
- **Text that disappears.** Kaggle's renderer drops unknown HTML tags, so `ng_<source>_mw` in a description shows as
|
|
52
|
+
`ng__mw`.
|
|
53
|
+
- **A cover that shows only its corner.** The Kaggle CLI always crops the top-left 560x280 pixels, whatever the image
|
|
54
|
+
size.
|
|
55
|
+
- **Garbled text from Windows.** The CLI reads `dataset-metadata.json` with the system encoding, so on most Windows
|
|
56
|
+
machines a `×` in a UTF-8 description reaches Kaggle as two other characters. Set `PYTHONUTF8=1` before uploading.
|
|
57
|
+
|
|
58
|
+
```bash
|
|
59
|
+
pip install kaggle-dataset-lint
|
|
60
|
+
kaggle-dataset-lint path/to/my-dataset # the folder you pass to `kaggle datasets create -p`
|
|
61
|
+
```
|
|
62
|
+
|
|
63
|
+
No dependencies: it is a single standard-library file, so you can also just download
|
|
64
|
+
[`src/kaggle_dataset_lint.py`](https://github.com/tb91117/kaggle-dataset-pipelines/blob/main/src/kaggle_dataset_lint.py) and run `python kaggle_dataset_lint.py my-dataset`.
|
|
65
|
+
Install `pyarrow` too if you want Parquet columns checked.
|
|
66
|
+
|
|
67
|
+
```text
|
|
68
|
+
my-dataset/dataset-metadata.json: error: [title-length] title is 51 characters; Kaggle allows 6-50
|
|
69
|
+
my-dataset/dataset-metadata.json: warning: [html-stripped] description contains <unit>: Kaggle's renderer drops unknown HTML tags, so the text disappears (`ng_<source>_mw` shows as `ng__mw`). Write {unit} or <unit>
|
|
70
|
+
my-dataset/dataset-metadata.json: warning: [cover-cropped] dataset-cover-image.png is 1600x800, but the Kaggle CLI always crops the top-left 560x280 pixels for the header and a 280x280 square at x=140 for the thumbnail. Resize it to 560x280, or set the cover in the web UI
|
|
71
|
+
my-dataset/dataset-metadata.json: error: [schema-mismatch] readings.csv: schema fields must list every column in file order, or Kaggle attaches the descriptions to the wrong columns (first difference at position 1: schema has 'station', file has 'time')
|
|
72
|
+
my-dataset/dataset-metadata.json: warning: [file-undeclared] no resource entry (so no file or column descriptions) for: notes.txt
|
|
73
|
+
my-dataset/dataset-metadata.json: warning: [subfolder-skipped] raw/ is skipped by `kaggle datasets create/version` unless you pass --dir-mode zip or tar
|
|
74
|
+
2 error(s), 4 warning(s) in 1 dataset(s)
|
|
75
|
+
```
|
|
76
|
+
|
|
77
|
+
### What it checks
|
|
78
|
+
|
|
79
|
+
| Level | Checks |
|
|
80
|
+
|---|---|
|
|
81
|
+
| **Error**: Kaggle rejects it, or the page comes out wrong | title 6-50 characters, subtitle 20-80, exactly one license, `id` is `owner/slug` (no `INSERT_..._HERE` placeholders), valid `expectedUpdateFrequency`, every declared file exists and is declared once, schema fields list every column in file order (CSV, TSV, Parquet), cover is .png/.jpg/.jpeg/.webp and at least 560x280 |
|
|
82
|
+
| **Warning**: silent problems and incomplete pages | `<word>` placeholders Kaggle strips, covers the CLI crops to a corner, subfolders `kaggle datasets create/version` skips, non-ASCII text the CLI would garble because it reads the file with the system encoding (cp1252 on most Windows machines), files and columns without descriptions, missing subtitle, description, tags, sources, update frequency or cover image, slugs `kaggle datasets create` rejects |
|
|
83
|
+
| **Note**: worth a look, never fails | license names that aren't in Kaggle's documented ids, column types outside Kaggle's best-effort list |
|
|
84
|
+
|
|
85
|
+
The rules come from the Kaggle CLI source and its
|
|
86
|
+
[dataset metadata docs](https://github.com/Kaggle/kaggle-cli/blob/main/docs/datasets_metadata.md). It also reads the
|
|
87
|
+
`{"info": ...}` layout that `kaggle datasets metadata` downloads.
|
|
88
|
+
|
|
89
|
+
### Options
|
|
90
|
+
|
|
91
|
+
- `--strict`: exit 1 on warnings as well as errors.
|
|
92
|
+
- `--no-files`: check only the metadata, not data files or the cover.
|
|
93
|
+
- `--ignore cover-missing,keywords-missing`: skip findings by code.
|
|
94
|
+
- `--format github`: print GitHub Actions annotations.
|
|
95
|
+
|
|
96
|
+
### In CI or pre-commit
|
|
97
|
+
|
|
98
|
+
```yaml
|
|
99
|
+
# GitHub Actions
|
|
100
|
+
- run: pip install kaggle-dataset-lint==0.3.0
|
|
101
|
+
- run: kaggle-dataset-lint --format github data/my-dataset
|
|
102
|
+
```
|
|
103
|
+
|
|
104
|
+
```yaml
|
|
105
|
+
# .pre-commit-config.yaml
|
|
106
|
+
repos:
|
|
107
|
+
- repo: https://github.com/tb91117/kaggle-dataset-pipelines
|
|
108
|
+
rev: v0.3.0
|
|
109
|
+
hooks:
|
|
110
|
+
- id: kaggle-dataset-lint
|
|
111
|
+
```
|
|
112
|
+
|
|
113
|
+
## Open-data pipelines
|
|
114
|
+
|
|
115
|
+
Each pipeline downloads an official public source, builds tidy Parquet/CSV files with typed columns, writes a full
|
|
116
|
+
`dataset-metadata.json` (title, subtitle, description, per-column descriptions, license, keywords) and renders a cover
|
|
117
|
+
image. Re-running a pipeline refreshes the dataset, so the Kaggle version stays current with the source. Every build is
|
|
118
|
+
tested on small real-data samples and must pass the linter.
|
|
119
|
+
|
|
120
|
+
### Datasets built with this repo
|
|
121
|
+
|
|
122
|
+
| Dataset on Kaggle | Source | Pipeline |
|
|
123
|
+
|---|---|---|
|
|
124
|
+
| [US Flight Delays & On-Time Performance 2022–2026](https://www.kaggle.com/datasets/teddybrown414/us-flight-delays-and-on-time-performance-2022-2026) | BTS *Reporting Carrier On-Time Performance* | `fetch_bts.py` → `build_bts.py` |
|
|
125
|
+
| [US Electric Grid Hourly Data (EIA-930)](https://www.kaggle.com/datasets/teddybrown414/us-electric-grid-hourly-eia-930) | EIA Hourly Electric Grid Monitor, six-month BALANCE files | `fetch_eia930.py` → `build_eia930.py` |
|
|
126
|
+
| [World Development Indicators 1960–2025](https://www.kaggle.com/datasets/teddybrown414/world-bank-world-development-indicators) | World Bank WDI bulk CSV | `fetch_wdi.py` → `build_wdi.py` |
|
|
127
|
+
| [San Francisco Street Tree Inventory](https://www.kaggle.com/datasets/teddybrown414/san-francisco-trees) | DataSF `tkzw-k3nq` (SODA API) | `fetch_sf_trees.py` → `build_v2.py trees` |
|
|
128
|
+
| [BTC/USDT 15-min Candles + Indicators 2017–2025](https://www.kaggle.com/datasets/teddybrown414/binance-ohlc-with-indicators) | Binance public market-data API (spot BTCUSDT, 15-minute klines) | `build_v2.py binance` |
|
|
129
|
+
| [Query Intent Routing for AI Assistants](https://www.kaggle.com/datasets/teddybrown414/data-for-classifying-intent-of-query) | Written by the dataset author for an assistant tool-routing prototype | `build_v2.py intent` |
|
|
130
|
+
|
|
131
|
+
The last two are rebuilt from the author's own source files, so they have no fetch step.
|
|
132
|
+
|
|
133
|
+
### Quick start
|
|
134
|
+
|
|
135
|
+
```bash
|
|
136
|
+
pip install -e ".[pipelines]"
|
|
137
|
+
python -I tools/fetch_eia930.py # downloads into datasets/eia930-hourly-grid/source/ (resumable)
|
|
138
|
+
python -I tools/build_eia930.py # writes datasets/eia930-hourly-grid/v1/ (data + metadata + cover)
|
|
139
|
+
```
|
|
140
|
+
|
|
141
|
+
Nothing is uploaded by the build scripts. Publishing is a separate, explicit step:
|
|
142
|
+
|
|
143
|
+
```bash
|
|
144
|
+
kaggle datasets version -p datasets/eia930-hourly-grid/v1 -m "Refresh"
|
|
145
|
+
python -I tools/push_cover.py datasets/eia930-hourly-grid/v1 <owner>/<slug> # cover with a correct crop
|
|
146
|
+
```
|
|
147
|
+
|
|
148
|
+
### Run on Kaggle instead of locally
|
|
149
|
+
|
|
150
|
+
Some sources are large (the BTS files are several GB). `make_kaggle_pipeline.py` assembles fetch + build + cover
|
|
151
|
+
into one self-contained Kaggle script kernel, so the download happens on Kaggle's servers:
|
|
152
|
+
|
|
153
|
+
```bash
|
|
154
|
+
python -I tools/make_kaggle_pipeline.py wdi none # bts | eia930 | wdi | trees; none = build only
|
|
155
|
+
kaggle kernels push -p pipelines/world-bank-wdi-dataset-pipeline
|
|
156
|
+
```
|
|
157
|
+
|
|
158
|
+
The kernel's output folder is the finished dataset: create or update the Kaggle dataset from it
|
|
159
|
+
(dataset page → New version → Notebook output). For `eia930`, `wdi` and `trees` the repo's scripts are embedded
|
|
160
|
+
verbatim and run as files with `KDP_DATA_ROOT` pointing at Kaggle's scratch disk, so a kernel run and a local run
|
|
161
|
+
produce the same files.
|
|
162
|
+
|
|
163
|
+
With `private` or `public`, the kernel reads a Kaggle Secret named `KAGGLE_API_TOKEN` (Notebook → Add-ons → Secrets).
|
|
164
|
+
|
|
165
|
+
### Tools
|
|
166
|
+
|
|
167
|
+
| Script | What it does |
|
|
168
|
+
|---|---|
|
|
169
|
+
| `src/kaggle_dataset_lint.py` | The linter above (`kaggle-dataset-lint`). |
|
|
170
|
+
| `fetch_*.py` | Resumable downloaders with retries; complete files are skipped on re-run. |
|
|
171
|
+
| `KDP_DATA_ROOT` | Environment variable: where sources are downloaded and datasets are built (default `./datasets`). |
|
|
172
|
+
| `build_*.py` | Clean, type and document a source into a Kaggle-ready folder. |
|
|
173
|
+
| `make_covers.py` | One distinct 2:1 cover design per dataset (no title text; Kaggle shows the title). |
|
|
174
|
+
| `push_cover.py` | Uploads metadata + cover with a crop that covers the whole image (the kaggle CLI crops the top-left corner). |
|
|
175
|
+
| `make_kaggle_pipeline.py` | Turns a fetch + build pair into a single Kaggle script kernel. |
|
|
176
|
+
| `make_notebooks.py` | Generates the example notebooks that accompany each dataset. |
|
|
177
|
+
| `profile_csv.py` | Prints a compact column profile of every CSV under a dataset folder. |
|
|
178
|
+
|
|
179
|
+
## Licenses
|
|
180
|
+
|
|
181
|
+
The code in this repo is MIT-licensed. The data keeps its source license: BTS and EIA data are US government works
|
|
182
|
+
(public domain), World Bank WDI is CC BY 4.0, and DataSF publishes under ODC-PDDL. Check each source before reuse.
|
|
@@ -0,0 +1,14 @@
|
|
|
1
|
+
LICENSE
|
|
2
|
+
README.md
|
|
3
|
+
pyproject.toml
|
|
4
|
+
src/kaggle_dataset_lint.py
|
|
5
|
+
src/kaggle_dataset_lint.egg-info/PKG-INFO
|
|
6
|
+
src/kaggle_dataset_lint.egg-info/SOURCES.txt
|
|
7
|
+
src/kaggle_dataset_lint.egg-info/dependency_links.txt
|
|
8
|
+
src/kaggle_dataset_lint.egg-info/entry_points.txt
|
|
9
|
+
src/kaggle_dataset_lint.egg-info/requires.txt
|
|
10
|
+
src/kaggle_dataset_lint.egg-info/top_level.txt
|
|
11
|
+
tests/test_builds.py
|
|
12
|
+
tests/test_lint.py
|
|
13
|
+
tests/test_push_cover.py
|
|
14
|
+
tests/test_smoke.py
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
kaggle_dataset_lint
|