judgekit 0.2.1__tar.gz → 0.2.2__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {judgekit-0.2.1/src/judgekit.egg-info → judgekit-0.2.2}/PKG-INFO +32 -24
- {judgekit-0.2.1 → judgekit-0.2.2}/README.md +31 -23
- {judgekit-0.2.1 → judgekit-0.2.2}/pyproject.toml +1 -1
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/__init__.py +1 -1
- {judgekit-0.2.1 → judgekit-0.2.2/src/judgekit.egg-info}/PKG-INFO +32 -24
- {judgekit-0.2.1 → judgekit-0.2.2}/LICENSE +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/setup.cfg +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/agreement.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/audit.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/bias.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/bootstrap.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/calibration.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/cli.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/consistency.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/demo.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/io.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/py.typed +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/report.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/result.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/schema.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit/synthetic.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit.egg-info/SOURCES.txt +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit.egg-info/dependency_links.txt +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit.egg-info/entry_points.txt +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit.egg-info/requires.txt +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/src/judgekit.egg-info/top_level.txt +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_agreement.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_bias.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_calibration_bootstrap.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_cli.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_consistency.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_report.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_schema_io.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_skips.py +0 -0
- {judgekit-0.2.1 → judgekit-0.2.2}/tests/test_synthetic_recovery.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: judgekit
|
|
3
|
-
Version: 0.2.
|
|
3
|
+
Version: 0.2.2
|
|
4
4
|
Summary: Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.
|
|
5
5
|
Author: Hadi Mohammadi
|
|
6
6
|
License: MIT
|
|
@@ -30,13 +30,19 @@ Requires-Dist: krippendorff>=0.6; extra == "dev"
|
|
|
30
30
|
Requires-Dist: statsmodels>=0.14; extra == "dev"
|
|
31
31
|
Dynamic: license-file
|
|
32
32
|
|
|
33
|
-
|
|
33
|
+
<div align="center">
|
|
34
34
|
|
|
35
|
-
|
|
35
|
+
# judgekit
|
|
36
36
|
|
|
37
37
|
[](https://github.com/mohammadi-hadi/judgekit/actions/workflows/ci.yml)
|
|
38
|
+
[](https://pypi.org/project/judgekit/)
|
|
38
39
|
[](https://doi.org/10.5281/zenodo.21802868)
|
|
39
|
-
[![
|
|
40
|
+
[](https://www.python.org/downloads/)
|
|
41
|
+
[](https://github.com/mohammadi-hadi/judgekit/blob/main/LICENSE)
|
|
42
|
+
|
|
43
|
+
*Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.*
|
|
44
|
+
|
|
45
|
+
</div>
|
|
40
46
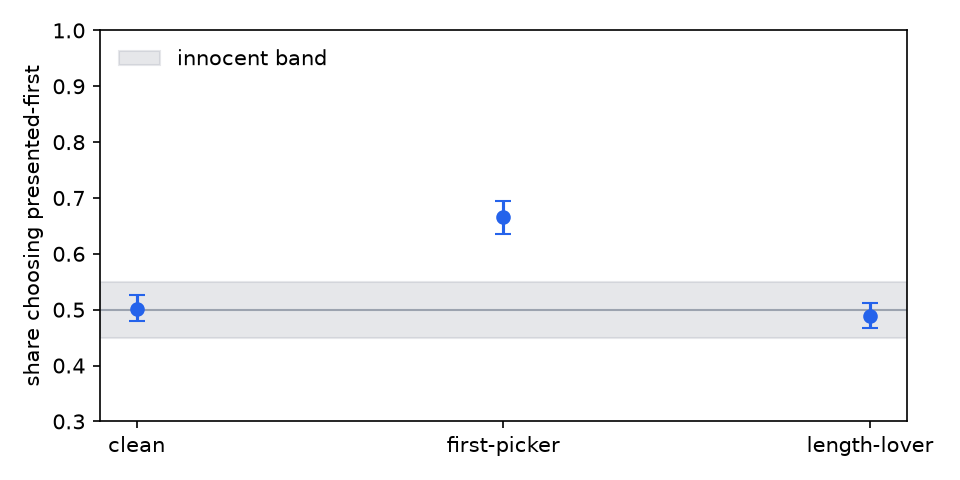
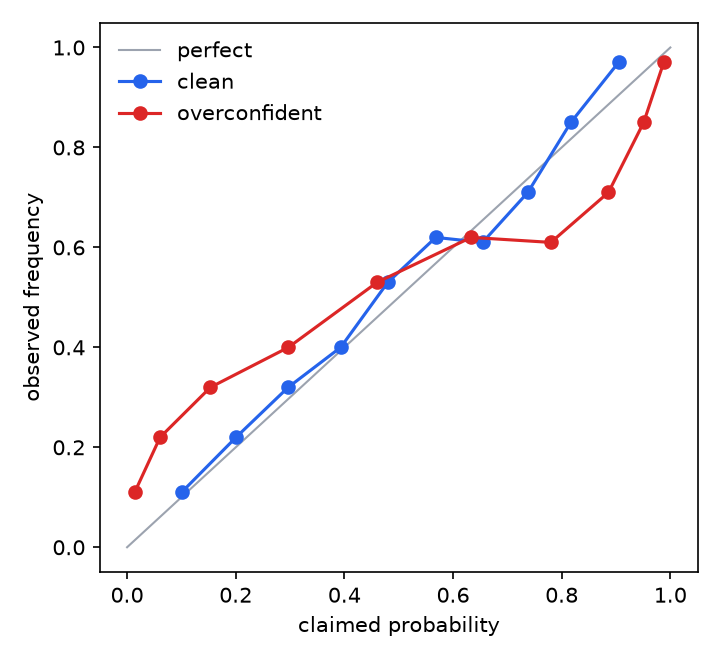
|
|
|
41
47
|
An LLM judge is a model too. It can prefer whichever answer came first, reward
|
|
42
48
|
padding, favor its own outputs, hug the middle of the scale, and say "90%
|
|
@@ -65,22 +71,22 @@ The row to sit with is `length-lover`: quadratic-weighted kappa with humans of
|
|
|
65
71
|
0.80 — a number most eval writeups would celebrate — while carrying a verbosity
|
|
66
72
|
bias of +0.82. Agreement is not an audit.
|
|
67
73
|
|
|
68
|
-
`make demo` regenerates this table, the [full report](results/report.md) and
|
|
74
|
+
`make demo` regenerates this table, the [full report](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) and
|
|
69
75
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
70
76
|
fails if a committed number differs from what the code produces.
|
|
71
77
|
|
|
72
|
-

|
|
78
|
+
|
|
73
79
|
|
|
74
|
-

|
|
80
|
+
|
|
75
81
|
|
|
76
82
|
## Two real judges, audited
|
|
77
83
|
|
|
78
|
-
[`examples/audit_ollama.py`](examples/audit_ollama.py) builds a small
|
|
84
|
+
[`examples/audit_ollama.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/examples/audit_ollama.py) builds a small
|
|
79
85
|
adversarial arithmetic benchmark — one answer provably correct by
|
|
80
86
|
construction, and half the time the wrong answer is the long, worked-through
|
|
81
87
|
one — then asks a local Ollama model to judge every pair in both presentation
|
|
82
88
|
orders. Verdicts and full reports are committed under
|
|
83
|
-
[examples/results](examples/results/).
|
|
89
|
+
[examples/results](https://github.com/mohammadi-hadi/judgekit/tree/main/examples/results/).
|
|
84
90
|
|
|
85
91
|
| judge (temperature 0) | truth agreement | position preference | verbosity excess | flips under swap | decisive on identical pairs |
|
|
86
92
|
|---|---|---|---|---|---|
|
|
@@ -92,10 +98,13 @@ Same task, different failure modes at different severities. Two judges follow
|
|
|
92
98
|
slot order — aya picks whatever is presented first 91.0% of the time and flips
|
|
93
99
|
81.9% of pairs when the order is swapped; qwen sits at 76.8% and 56.8%. The
|
|
94
100
|
llama judge grades effort instead, picking the longer answer 48 points more
|
|
95
|
-
often than correctness warrants and
|
|
96
|
-
|
|
97
|
-
|
|
98
|
-
|
|
101
|
+
often than correctness warrants and scoring 0.443 against ground truth. Two of
|
|
102
|
+
the three never once declare a tie between identical answers, which is also
|
|
103
|
+
why that 0.443 is softer than it looks: those 15 pairs are unwinnable for a
|
|
104
|
+
judge that never ties, and on the 90 adversarial pairs alone the llama judge
|
|
105
|
+
reaches 0.517 — level with chance rather than below it. n=105 pairs,
|
|
106
|
+
adversarial by construction — an illustration of what the probes see, not a
|
|
107
|
+
model leaderboard.
|
|
99
108
|
|
|
100
109
|
## Install
|
|
101
110
|
|
|
@@ -177,7 +186,7 @@ judge.
|
|
|
177
186
|
silent on the clean judge, including a world where longer answers genuinely
|
|
178
187
|
are better and the raw length correlation would convict an honest judge.
|
|
179
188
|
- **Drift-checked results.** Every number above and in
|
|
180
|
-
[results/report.md](results/report.md) is regenerated by CI from pinned
|
|
189
|
+
[results/report.md](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) is regenerated by CI from pinned
|
|
181
190
|
dependencies and diffed against the committed copy.
|
|
182
191
|
|
|
183
192
|
## Design notes
|
|
@@ -187,7 +196,7 @@ judge.
|
|
|
187
196
|
defect-free judge could plausibly occupy — position 0.45–0.55, correlations
|
|
188
197
|
±0.10, self-preference ±0.20 scale points, spread 0.90–1.10, ECE ≤ 0.05 —
|
|
189
198
|
and flags only when the whole 95% interval leaves it. The bands are opinions,
|
|
190
|
-
stated in one place ([`bias.py`](src/judgekit/bias.py)) and easy to disagree
|
|
199
|
+
stated in one place ([`bias.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/src/judgekit/bias.py)) and easy to disagree
|
|
191
200
|
with.
|
|
192
201
|
- **Item-level bootstrap.** Re-judgments and swapped presentations of an item
|
|
193
202
|
are resampled together; treating correlated rows as independent evidence
|
|
@@ -230,25 +239,24 @@ the LLM-as-a-judge survey ([Gu et al., 2024](https://arxiv.org/abs/2411.15594)).
|
|
|
230
239
|
judgekit's contribution is packaging the checks as one auditable tool with
|
|
231
240
|
uncertainty on every number and validation by implantation.
|
|
232
241
|
|
|
233
|
-
|
|
234
|
-
|
|
235
|
-
[
|
|
236
|
-
|
|
237
|
-
|
|
238
|
-
leaderboard a judge's verdicts add up to.
|
|
242
|
+
## Part of evalstack
|
|
243
|
+
|
|
244
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
245
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
246
|
+
and the two chains that run end to end.
|
|
239
247
|
|
|
240
248
|
## Citation
|
|
241
249
|
|
|
242
250
|
If judgekit is useful in your research, please cite it (see
|
|
243
|
-
[CITATION.cff](CITATION.cff)):
|
|
251
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/judgekit/blob/main/CITATION.cff)):
|
|
244
252
|
|
|
245
253
|
```bibtex
|
|
246
254
|
@software{mohammadi_judgekit,
|
|
247
255
|
author = {Mohammadi, Hadi},
|
|
248
256
|
title = {judgekit: audit an LLM judge before you trust it},
|
|
249
257
|
url = {https://github.com/mohammadi-hadi/judgekit},
|
|
250
|
-
doi = {10.5281/zenodo.
|
|
251
|
-
version = {0.2.
|
|
258
|
+
doi = {10.5281/zenodo.21802868},
|
|
259
|
+
version = {0.2.2},
|
|
252
260
|
year = {2026}
|
|
253
261
|
}
|
|
254
262
|
```
|
|
@@ -1,10 +1,16 @@
|
|
|
1
|
-
|
|
1
|
+
<div align="center">
|
|
2
2
|
|
|
3
|
-
|
|
3
|
+
# judgekit
|
|
4
4
|
|
|
5
5
|
[](https://github.com/mohammadi-hadi/judgekit/actions/workflows/ci.yml)
|
|
6
|
+
[](https://pypi.org/project/judgekit/)
|
|
6
7
|
[](https://doi.org/10.5281/zenodo.21802868)
|
|
7
|
-
[![
|
|
8
|
+
[](https://www.python.org/downloads/)
|
|
9
|
+
[](https://github.com/mohammadi-hadi/judgekit/blob/main/LICENSE)
|
|
10
|
+
|
|
11
|
+
*Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.*
|
|
12
|
+
|
|
13
|
+
</div>
|
|
8
14
|
|
|
9
15
|
An LLM judge is a model too. It can prefer whichever answer came first, reward
|
|
10
16
|
padding, favor its own outputs, hug the middle of the scale, and say "90%
|
|
@@ -33,22 +39,22 @@ The row to sit with is `length-lover`: quadratic-weighted kappa with humans of
|
|
|
33
39
|
0.80 — a number most eval writeups would celebrate — while carrying a verbosity
|
|
34
40
|
bias of +0.82. Agreement is not an audit.
|
|
35
41
|
|
|
36
|
-
`make demo` regenerates this table, the [full report](results/report.md) and
|
|
42
|
+
`make demo` regenerates this table, the [full report](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) and
|
|
37
43
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
38
44
|
fails if a committed number differs from what the code produces.
|
|
39
45
|
|
|
40
|
-

|
|
46
|
+

|
|
41
47
|
|
|
42
|
-

|
|
48
|
+

|
|
43
49
|
|
|
44
50
|
## Two real judges, audited
|
|
45
51
|
|
|
46
|
-
[`examples/audit_ollama.py`](examples/audit_ollama.py) builds a small
|
|
52
|
+
[`examples/audit_ollama.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/examples/audit_ollama.py) builds a small
|
|
47
53
|
adversarial arithmetic benchmark — one answer provably correct by
|
|
48
54
|
construction, and half the time the wrong answer is the long, worked-through
|
|
49
55
|
one — then asks a local Ollama model to judge every pair in both presentation
|
|
50
56
|
orders. Verdicts and full reports are committed under
|
|
51
|
-
[examples/results](examples/results/).
|
|
57
|
+
[examples/results](https://github.com/mohammadi-hadi/judgekit/tree/main/examples/results/).
|
|
52
58
|
|
|
53
59
|
| judge (temperature 0) | truth agreement | position preference | verbosity excess | flips under swap | decisive on identical pairs |
|
|
54
60
|
|---|---|---|---|---|---|
|
|
@@ -60,10 +66,13 @@ Same task, different failure modes at different severities. Two judges follow
|
|
|
60
66
|
slot order — aya picks whatever is presented first 91.0% of the time and flips
|
|
61
67
|
81.9% of pairs when the order is swapped; qwen sits at 76.8% and 56.8%. The
|
|
62
68
|
llama judge grades effort instead, picking the longer answer 48 points more
|
|
63
|
-
often than correctness warrants and
|
|
64
|
-
|
|
65
|
-
|
|
66
|
-
|
|
69
|
+
often than correctness warrants and scoring 0.443 against ground truth. Two of
|
|
70
|
+
the three never once declare a tie between identical answers, which is also
|
|
71
|
+
why that 0.443 is softer than it looks: those 15 pairs are unwinnable for a
|
|
72
|
+
judge that never ties, and on the 90 adversarial pairs alone the llama judge
|
|
73
|
+
reaches 0.517 — level with chance rather than below it. n=105 pairs,
|
|
74
|
+
adversarial by construction — an illustration of what the probes see, not a
|
|
75
|
+
model leaderboard.
|
|
67
76
|
|
|
68
77
|
## Install
|
|
69
78
|
|
|
@@ -145,7 +154,7 @@ judge.
|
|
|
145
154
|
silent on the clean judge, including a world where longer answers genuinely
|
|
146
155
|
are better and the raw length correlation would convict an honest judge.
|
|
147
156
|
- **Drift-checked results.** Every number above and in
|
|
148
|
-
[results/report.md](results/report.md) is regenerated by CI from pinned
|
|
157
|
+
[results/report.md](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) is regenerated by CI from pinned
|
|
149
158
|
dependencies and diffed against the committed copy.
|
|
150
159
|
|
|
151
160
|
## Design notes
|
|
@@ -155,7 +164,7 @@ judge.
|
|
|
155
164
|
defect-free judge could plausibly occupy — position 0.45–0.55, correlations
|
|
156
165
|
±0.10, self-preference ±0.20 scale points, spread 0.90–1.10, ECE ≤ 0.05 —
|
|
157
166
|
and flags only when the whole 95% interval leaves it. The bands are opinions,
|
|
158
|
-
stated in one place ([`bias.py`](src/judgekit/bias.py)) and easy to disagree
|
|
167
|
+
stated in one place ([`bias.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/src/judgekit/bias.py)) and easy to disagree
|
|
159
168
|
with.
|
|
160
169
|
- **Item-level bootstrap.** Re-judgments and swapped presentations of an item
|
|
161
170
|
are resampled together; treating correlated rows as independent evidence
|
|
@@ -198,25 +207,24 @@ the LLM-as-a-judge survey ([Gu et al., 2024](https://arxiv.org/abs/2411.15594)).
|
|
|
198
207
|
judgekit's contribution is packaging the checks as one auditable tool with
|
|
199
208
|
uncertainty on every number and validation by implantation.
|
|
200
209
|
|
|
201
|
-
|
|
202
|
-
|
|
203
|
-
[
|
|
204
|
-
|
|
205
|
-
|
|
206
|
-
leaderboard a judge's verdicts add up to.
|
|
210
|
+
## Part of evalstack
|
|
211
|
+
|
|
212
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
213
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
214
|
+
and the two chains that run end to end.
|
|
207
215
|
|
|
208
216
|
## Citation
|
|
209
217
|
|
|
210
218
|
If judgekit is useful in your research, please cite it (see
|
|
211
|
-
[CITATION.cff](CITATION.cff)):
|
|
219
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/judgekit/blob/main/CITATION.cff)):
|
|
212
220
|
|
|
213
221
|
```bibtex
|
|
214
222
|
@software{mohammadi_judgekit,
|
|
215
223
|
author = {Mohammadi, Hadi},
|
|
216
224
|
title = {judgekit: audit an LLM judge before you trust it},
|
|
217
225
|
url = {https://github.com/mohammadi-hadi/judgekit},
|
|
218
|
-
doi = {10.5281/zenodo.
|
|
219
|
-
version = {0.2.
|
|
226
|
+
doi = {10.5281/zenodo.21802868},
|
|
227
|
+
version = {0.2.2},
|
|
220
228
|
year = {2026}
|
|
221
229
|
}
|
|
222
230
|
```
|
|
@@ -4,7 +4,7 @@ build-backend = "setuptools.build_meta"
|
|
|
4
4
|
|
|
5
5
|
[project]
|
|
6
6
|
name = "judgekit"
|
|
7
|
-
version = "0.2.
|
|
7
|
+
version = "0.2.2"
|
|
8
8
|
description = "Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability."
|
|
9
9
|
readme = "README.md"
|
|
10
10
|
license = { text = "MIT" }
|
|
@@ -5,7 +5,7 @@ from judgekit.io import dump_verdicts, load_verdicts
|
|
|
5
5
|
from judgekit.result import ProbeResult, SkippedProbe
|
|
6
6
|
from judgekit.schema import BinaryVerdict, GradedVerdict, PairwiseVerdict
|
|
7
7
|
|
|
8
|
-
__version__ = "0.2.
|
|
8
|
+
__version__ = "0.2.2"
|
|
9
9
|
|
|
10
10
|
__all__ = [
|
|
11
11
|
"AuditReport",
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: judgekit
|
|
3
|
-
Version: 0.2.
|
|
3
|
+
Version: 0.2.2
|
|
4
4
|
Summary: Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.
|
|
5
5
|
Author: Hadi Mohammadi
|
|
6
6
|
License: MIT
|
|
@@ -30,13 +30,19 @@ Requires-Dist: krippendorff>=0.6; extra == "dev"
|
|
|
30
30
|
Requires-Dist: statsmodels>=0.14; extra == "dev"
|
|
31
31
|
Dynamic: license-file
|
|
32
32
|
|
|
33
|
-
|
|
33
|
+
<div align="center">
|
|
34
34
|
|
|
35
|
-
|
|
35
|
+
# judgekit
|
|
36
36
|
|
|
37
37
|
[](https://github.com/mohammadi-hadi/judgekit/actions/workflows/ci.yml)
|
|
38
|
+
[](https://pypi.org/project/judgekit/)
|
|
38
39
|
[](https://doi.org/10.5281/zenodo.21802868)
|
|
39
|
-
[![
|
|
40
|
+
[](https://www.python.org/downloads/)
|
|
41
|
+
[](https://github.com/mohammadi-hadi/judgekit/blob/main/LICENSE)
|
|
42
|
+
|
|
43
|
+
*Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.*
|
|
44
|
+
|
|
45
|
+
</div>
|
|
40
46
|
|
|
41
47
|
An LLM judge is a model too. It can prefer whichever answer came first, reward
|
|
42
48
|
padding, favor its own outputs, hug the middle of the scale, and say "90%
|
|
@@ -65,22 +71,22 @@ The row to sit with is `length-lover`: quadratic-weighted kappa with humans of
|
|
|
65
71
|
0.80 — a number most eval writeups would celebrate — while carrying a verbosity
|
|
66
72
|
bias of +0.82. Agreement is not an audit.
|
|
67
73
|
|
|
68
|
-
`make demo` regenerates this table, the [full report](results/report.md) and
|
|
74
|
+
`make demo` regenerates this table, the [full report](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) and
|
|
69
75
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
70
76
|
fails if a committed number differs from what the code produces.
|
|
71
77
|
|
|
72
|
-

|
|
78
|
+

|
|
73
79
|
|
|
74
|
-

|
|
80
|
+

|
|
75
81
|
|
|
76
82
|
## Two real judges, audited
|
|
77
83
|
|
|
78
|
-
[`examples/audit_ollama.py`](examples/audit_ollama.py) builds a small
|
|
84
|
+
[`examples/audit_ollama.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/examples/audit_ollama.py) builds a small
|
|
79
85
|
adversarial arithmetic benchmark — one answer provably correct by
|
|
80
86
|
construction, and half the time the wrong answer is the long, worked-through
|
|
81
87
|
one — then asks a local Ollama model to judge every pair in both presentation
|
|
82
88
|
orders. Verdicts and full reports are committed under
|
|
83
|
-
[examples/results](examples/results/).
|
|
89
|
+
[examples/results](https://github.com/mohammadi-hadi/judgekit/tree/main/examples/results/).
|
|
84
90
|
|
|
85
91
|
| judge (temperature 0) | truth agreement | position preference | verbosity excess | flips under swap | decisive on identical pairs |
|
|
86
92
|
|---|---|---|---|---|---|
|
|
@@ -92,10 +98,13 @@ Same task, different failure modes at different severities. Two judges follow
|
|
|
92
98
|
slot order — aya picks whatever is presented first 91.0% of the time and flips
|
|
93
99
|
81.9% of pairs when the order is swapped; qwen sits at 76.8% and 56.8%. The
|
|
94
100
|
llama judge grades effort instead, picking the longer answer 48 points more
|
|
95
|
-
often than correctness warrants and
|
|
96
|
-
|
|
97
|
-
|
|
98
|
-
|
|
101
|
+
often than correctness warrants and scoring 0.443 against ground truth. Two of
|
|
102
|
+
the three never once declare a tie between identical answers, which is also
|
|
103
|
+
why that 0.443 is softer than it looks: those 15 pairs are unwinnable for a
|
|
104
|
+
judge that never ties, and on the 90 adversarial pairs alone the llama judge
|
|
105
|
+
reaches 0.517 — level with chance rather than below it. n=105 pairs,
|
|
106
|
+
adversarial by construction — an illustration of what the probes see, not a
|
|
107
|
+
model leaderboard.
|
|
99
108
|
|
|
100
109
|
## Install
|
|
101
110
|
|
|
@@ -177,7 +186,7 @@ judge.
|
|
|
177
186
|
silent on the clean judge, including a world where longer answers genuinely
|
|
178
187
|
are better and the raw length correlation would convict an honest judge.
|
|
179
188
|
- **Drift-checked results.** Every number above and in
|
|
180
|
-
[results/report.md](results/report.md) is regenerated by CI from pinned
|
|
189
|
+
[results/report.md](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) is regenerated by CI from pinned
|
|
181
190
|
dependencies and diffed against the committed copy.
|
|
182
191
|
|
|
183
192
|
## Design notes
|
|
@@ -187,7 +196,7 @@ judge.
|
|
|
187
196
|
defect-free judge could plausibly occupy — position 0.45–0.55, correlations
|
|
188
197
|
±0.10, self-preference ±0.20 scale points, spread 0.90–1.10, ECE ≤ 0.05 —
|
|
189
198
|
and flags only when the whole 95% interval leaves it. The bands are opinions,
|
|
190
|
-
stated in one place ([`bias.py`](src/judgekit/bias.py)) and easy to disagree
|
|
199
|
+
stated in one place ([`bias.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/src/judgekit/bias.py)) and easy to disagree
|
|
191
200
|
with.
|
|
192
201
|
- **Item-level bootstrap.** Re-judgments and swapped presentations of an item
|
|
193
202
|
are resampled together; treating correlated rows as independent evidence
|
|
@@ -230,25 +239,24 @@ the LLM-as-a-judge survey ([Gu et al., 2024](https://arxiv.org/abs/2411.15594)).
|
|
|
230
239
|
judgekit's contribution is packaging the checks as one auditable tool with
|
|
231
240
|
uncertainty on every number and validation by implantation.
|
|
232
241
|
|
|
233
|
-
|
|
234
|
-
|
|
235
|
-
[
|
|
236
|
-
|
|
237
|
-
|
|
238
|
-
leaderboard a judge's verdicts add up to.
|
|
242
|
+
## Part of evalstack
|
|
243
|
+
|
|
244
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
245
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
246
|
+
and the two chains that run end to end.
|
|
239
247
|
|
|
240
248
|
## Citation
|
|
241
249
|
|
|
242
250
|
If judgekit is useful in your research, please cite it (see
|
|
243
|
-
[CITATION.cff](CITATION.cff)):
|
|
251
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/judgekit/blob/main/CITATION.cff)):
|
|
244
252
|
|
|
245
253
|
```bibtex
|
|
246
254
|
@software{mohammadi_judgekit,
|
|
247
255
|
author = {Mohammadi, Hadi},
|
|
248
256
|
title = {judgekit: audit an LLM judge before you trust it},
|
|
249
257
|
url = {https://github.com/mohammadi-hadi/judgekit},
|
|
250
|
-
doi = {10.5281/zenodo.
|
|
251
|
-
version = {0.2.
|
|
258
|
+
doi = {10.5281/zenodo.21802868},
|
|
259
|
+
version = {0.2.2},
|
|
252
260
|
year = {2026}
|
|
253
261
|
}
|
|
254
262
|
```
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|