judgekit 0.2.0__tar.gz → 0.2.2__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {judgekit-0.2.0/src/judgekit.egg-info → judgekit-0.2.2}/PKG-INFO +55 -29
- {judgekit-0.2.0 → judgekit-0.2.2}/README.md +53 -27
- {judgekit-0.2.0 → judgekit-0.2.2}/pyproject.toml +2 -2
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/__init__.py +2 -2
- {judgekit-0.2.0 → judgekit-0.2.2/src/judgekit.egg-info}/PKG-INFO +55 -29
- {judgekit-0.2.0 → judgekit-0.2.2}/LICENSE +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/setup.cfg +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/agreement.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/audit.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/bias.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/bootstrap.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/calibration.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/cli.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/consistency.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/demo.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/io.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/py.typed +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/report.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/result.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/schema.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit/synthetic.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit.egg-info/SOURCES.txt +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit.egg-info/dependency_links.txt +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit.egg-info/entry_points.txt +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit.egg-info/requires.txt +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/src/judgekit.egg-info/top_level.txt +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_agreement.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_bias.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_calibration_bootstrap.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_cli.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_consistency.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_report.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_schema_io.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_skips.py +0 -0
- {judgekit-0.2.0 → judgekit-0.2.2}/tests/test_synthetic_recovery.py +0 -0
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: judgekit
|
|
3
|
-
Version: 0.2.
|
|
4
|
-
Summary:
|
|
3
|
+
Version: 0.2.2
|
|
4
|
+
Summary: Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.
|
|
5
5
|
Author: Hadi Mohammadi
|
|
6
6
|
License: MIT
|
|
7
7
|
Project-URL: Homepage, https://github.com/mohammadi-hadi/judgekit
|
|
@@ -30,11 +30,19 @@ Requires-Dist: krippendorff>=0.6; extra == "dev"
|
|
|
30
30
|
Requires-Dist: statsmodels>=0.14; extra == "dev"
|
|
31
31
|
Dynamic: license-file
|
|
32
32
|
|
|
33
|
-
|
|
33
|
+
<div align="center">
|
|
34
34
|
|
|
35
|
-
|
|
35
|
+
# judgekit
|
|
36
36
|
|
|
37
37
|
[](https://github.com/mohammadi-hadi/judgekit/actions/workflows/ci.yml)
|
|
38
|
+
[](https://pypi.org/project/judgekit/)
|
|
39
|
+
[](https://doi.org/10.5281/zenodo.21802868)
|
|
40
|
+
[](https://www.python.org/downloads/)
|
|
41
|
+
[](https://github.com/mohammadi-hadi/judgekit/blob/main/LICENSE)
|
|
42
|
+
|
|
43
|
+
*Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.*
|
|
44
|
+
|
|
45
|
+
</div>
|
|
38
46
|
|
|
39
47
|
An LLM judge is a model too. It can prefer whichever answer came first, reward
|
|
40
48
|
padding, favor its own outputs, hug the middle of the scale, and say "90%
|
|
@@ -63,35 +71,40 @@ The row to sit with is `length-lover`: quadratic-weighted kappa with humans of
|
|
|
63
71
|
0.80 — a number most eval writeups would celebrate — while carrying a verbosity
|
|
64
72
|
bias of +0.82. Agreement is not an audit.
|
|
65
73
|
|
|
66
|
-
`make demo` regenerates this table, the [full report](results/report.md) and
|
|
74
|
+
`make demo` regenerates this table, the [full report](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) and
|
|
67
75
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
68
76
|
fails if a committed number differs from what the code produces.
|
|
69
77
|
|
|
70
|
-

|
|
78
|
+
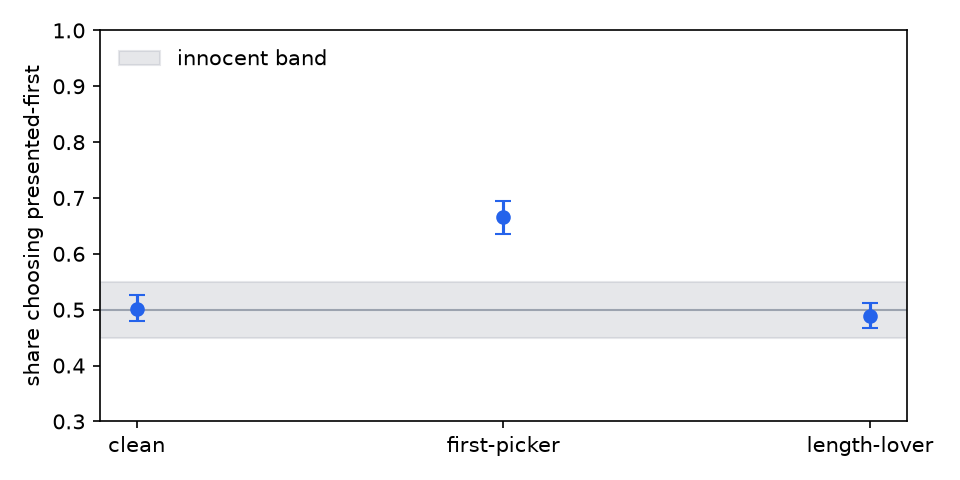
|
|
71
79
|
|
|
72
|
-

|
|
80
|
+
|
|
73
81
|
|
|
74
82
|
## Two real judges, audited
|
|
75
83
|
|
|
76
|
-
[`examples/audit_ollama.py`](examples/audit_ollama.py) builds a small
|
|
84
|
+
[`examples/audit_ollama.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/examples/audit_ollama.py) builds a small
|
|
77
85
|
adversarial arithmetic benchmark — one answer provably correct by
|
|
78
86
|
construction, and half the time the wrong answer is the long, worked-through
|
|
79
87
|
one — then asks a local Ollama model to judge every pair in both presentation
|
|
80
88
|
orders. Verdicts and full reports are committed under
|
|
81
|
-
[examples/results](examples/results/).
|
|
89
|
+
[examples/results](https://github.com/mohammadi-hadi/judgekit/tree/main/examples/results/).
|
|
82
90
|
|
|
83
91
|
| judge (temperature 0) | truth agreement | position preference | verbosity excess | flips under swap | decisive on identical pairs |
|
|
84
92
|
|---|---|---|---|---|---|
|
|
93
|
+
| aya-expanse:8b | 0.433 | **0.910** (flag) | +0.106 | 0.819 | 1.000 |
|
|
85
94
|
| qwen2.5:14b | 0.667 | **0.768** (flag) | +0.131 | 0.568 | 0.200 |
|
|
86
95
|
| llama3.1:8b | 0.443 | 0.576 | **+0.483** (flag) | 0.171 | 1.000 |
|
|
87
96
|
|
|
88
|
-
Same task,
|
|
89
|
-
presented
|
|
90
|
-
|
|
91
|
-
|
|
92
|
-
|
|
93
|
-
|
|
94
|
-
|
|
97
|
+
Same task, different failure modes at different severities. Two judges follow
|
|
98
|
+
slot order — aya picks whatever is presented first 91.0% of the time and flips
|
|
99
|
+
81.9% of pairs when the order is swapped; qwen sits at 76.8% and 56.8%. The
|
|
100
|
+
llama judge grades effort instead, picking the longer answer 48 points more
|
|
101
|
+
often than correctness warrants and scoring 0.443 against ground truth. Two of
|
|
102
|
+
the three never once declare a tie between identical answers, which is also
|
|
103
|
+
why that 0.443 is softer than it looks: those 15 pairs are unwinnable for a
|
|
104
|
+
judge that never ties, and on the 90 adversarial pairs alone the llama judge
|
|
105
|
+
reaches 0.517 — level with chance rather than below it. n=105 pairs,
|
|
106
|
+
adversarial by construction — an illustration of what the probes see, not a
|
|
107
|
+
model leaderboard.
|
|
95
108
|
|
|
96
109
|
## Install
|
|
97
110
|
|
|
@@ -99,13 +112,9 @@ of what the probes see, not a model leaderboard.
|
|
|
99
112
|
pip install judgekit
|
|
100
113
|
```
|
|
101
114
|
|
|
102
|
-
|
|
103
|
-
|
|
104
|
-
|
|
105
|
-
pip install git+https://github.com/mohammadi-hadi/judgekit
|
|
106
|
-
```
|
|
107
|
-
|
|
108
|
-
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib.
|
|
115
|
+
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib. The
|
|
116
|
+
development version installs with
|
|
117
|
+
`pip install git+https://github.com/mohammadi-hadi/judgekit`.
|
|
109
118
|
|
|
110
119
|
## Quickstart
|
|
111
120
|
|
|
@@ -177,7 +186,7 @@ judge.
|
|
|
177
186
|
silent on the clean judge, including a world where longer answers genuinely
|
|
178
187
|
are better and the raw length correlation would convict an honest judge.
|
|
179
188
|
- **Drift-checked results.** Every number above and in
|
|
180
|
-
[results/report.md](results/report.md) is regenerated by CI from pinned
|
|
189
|
+
[results/report.md](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) is regenerated by CI from pinned
|
|
181
190
|
dependencies and diffed against the committed copy.
|
|
182
191
|
|
|
183
192
|
## Design notes
|
|
@@ -187,7 +196,7 @@ judge.
|
|
|
187
196
|
defect-free judge could plausibly occupy — position 0.45–0.55, correlations
|
|
188
197
|
±0.10, self-preference ±0.20 scale points, spread 0.90–1.10, ECE ≤ 0.05 —
|
|
189
198
|
and flags only when the whole 95% interval leaves it. The bands are opinions,
|
|
190
|
-
stated in one place ([`bias.py`](src/judgekit/bias.py)) and easy to disagree
|
|
199
|
+
stated in one place ([`bias.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/src/judgekit/bias.py)) and easy to disagree
|
|
191
200
|
with.
|
|
192
201
|
- **Item-level bootstrap.** Re-judgments and swapped presentations of an item
|
|
193
202
|
are resampled together; treating correlated rows as independent evidence
|
|
@@ -230,10 +239,27 @@ the LLM-as-a-judge survey ([Gu et al., 2024](https://arxiv.org/abs/2411.15594)).
|
|
|
230
239
|
judgekit's contribution is packaging the checks as one auditable tool with
|
|
231
240
|
uncertainty on every number and validation by implantation.
|
|
232
241
|
|
|
233
|
-
|
|
234
|
-
|
|
235
|
-
[
|
|
236
|
-
|
|
242
|
+
## Part of evalstack
|
|
243
|
+
|
|
244
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
245
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
246
|
+
and the two chains that run end to end.
|
|
247
|
+
|
|
248
|
+
## Citation
|
|
249
|
+
|
|
250
|
+
If judgekit is useful in your research, please cite it (see
|
|
251
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/judgekit/blob/main/CITATION.cff)):
|
|
252
|
+
|
|
253
|
+
```bibtex
|
|
254
|
+
@software{mohammadi_judgekit,
|
|
255
|
+
author = {Mohammadi, Hadi},
|
|
256
|
+
title = {judgekit: audit an LLM judge before you trust it},
|
|
257
|
+
url = {https://github.com/mohammadi-hadi/judgekit},
|
|
258
|
+
doi = {10.5281/zenodo.21802868},
|
|
259
|
+
version = {0.2.2},
|
|
260
|
+
year = {2026}
|
|
261
|
+
}
|
|
262
|
+
```
|
|
237
263
|
|
|
238
264
|
## License
|
|
239
265
|
|
|
@@ -1,8 +1,16 @@
|
|
|
1
|
-
|
|
1
|
+
<div align="center">
|
|
2
2
|
|
|
3
|
-
|
|
3
|
+
# judgekit
|
|
4
4
|
|
|
5
5
|
[](https://github.com/mohammadi-hadi/judgekit/actions/workflows/ci.yml)
|
|
6
|
+
[](https://pypi.org/project/judgekit/)
|
|
7
|
+
[](https://doi.org/10.5281/zenodo.21802868)
|
|
8
|
+
[](https://www.python.org/downloads/)
|
|
9
|
+
[](https://github.com/mohammadi-hadi/judgekit/blob/main/LICENSE)
|
|
10
|
+
|
|
11
|
+
*Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.*
|
|
12
|
+
|
|
13
|
+
</div>
|
|
6
14
|
|
|
7
15
|
An LLM judge is a model too. It can prefer whichever answer came first, reward
|
|
8
16
|
padding, favor its own outputs, hug the middle of the scale, and say "90%
|
|
@@ -31,35 +39,40 @@ The row to sit with is `length-lover`: quadratic-weighted kappa with humans of
|
|
|
31
39
|
0.80 — a number most eval writeups would celebrate — while carrying a verbosity
|
|
32
40
|
bias of +0.82. Agreement is not an audit.
|
|
33
41
|
|
|
34
|
-
`make demo` regenerates this table, the [full report](results/report.md) and
|
|
42
|
+
`make demo` regenerates this table, the [full report](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) and
|
|
35
43
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
36
44
|
fails if a committed number differs from what the code produces.
|
|
37
45
|
|
|
38
|
-

|
|
46
|
+

|
|
39
47
|
|
|
40
|
-

|
|
48
|
+

|
|
41
49
|
|
|
42
50
|
## Two real judges, audited
|
|
43
51
|
|
|
44
|
-
[`examples/audit_ollama.py`](examples/audit_ollama.py) builds a small
|
|
52
|
+
[`examples/audit_ollama.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/examples/audit_ollama.py) builds a small
|
|
45
53
|
adversarial arithmetic benchmark — one answer provably correct by
|
|
46
54
|
construction, and half the time the wrong answer is the long, worked-through
|
|
47
55
|
one — then asks a local Ollama model to judge every pair in both presentation
|
|
48
56
|
orders. Verdicts and full reports are committed under
|
|
49
|
-
[examples/results](examples/results/).
|
|
57
|
+
[examples/results](https://github.com/mohammadi-hadi/judgekit/tree/main/examples/results/).
|
|
50
58
|
|
|
51
59
|
| judge (temperature 0) | truth agreement | position preference | verbosity excess | flips under swap | decisive on identical pairs |
|
|
52
60
|
|---|---|---|---|---|---|
|
|
61
|
+
| aya-expanse:8b | 0.433 | **0.910** (flag) | +0.106 | 0.819 | 1.000 |
|
|
53
62
|
| qwen2.5:14b | 0.667 | **0.768** (flag) | +0.131 | 0.568 | 0.200 |
|
|
54
63
|
| llama3.1:8b | 0.443 | 0.576 | **+0.483** (flag) | 0.171 | 1.000 |
|
|
55
64
|
|
|
56
|
-
Same task,
|
|
57
|
-
presented
|
|
58
|
-
|
|
59
|
-
|
|
60
|
-
|
|
61
|
-
|
|
62
|
-
|
|
65
|
+
Same task, different failure modes at different severities. Two judges follow
|
|
66
|
+
slot order — aya picks whatever is presented first 91.0% of the time and flips
|
|
67
|
+
81.9% of pairs when the order is swapped; qwen sits at 76.8% and 56.8%. The
|
|
68
|
+
llama judge grades effort instead, picking the longer answer 48 points more
|
|
69
|
+
often than correctness warrants and scoring 0.443 against ground truth. Two of
|
|
70
|
+
the three never once declare a tie between identical answers, which is also
|
|
71
|
+
why that 0.443 is softer than it looks: those 15 pairs are unwinnable for a
|
|
72
|
+
judge that never ties, and on the 90 adversarial pairs alone the llama judge
|
|
73
|
+
reaches 0.517 — level with chance rather than below it. n=105 pairs,
|
|
74
|
+
adversarial by construction — an illustration of what the probes see, not a
|
|
75
|
+
model leaderboard.
|
|
63
76
|
|
|
64
77
|
## Install
|
|
65
78
|
|
|
@@ -67,13 +80,9 @@ of what the probes see, not a model leaderboard.
|
|
|
67
80
|
pip install judgekit
|
|
68
81
|
```
|
|
69
82
|
|
|
70
|
-
|
|
71
|
-
|
|
72
|
-
|
|
73
|
-
pip install git+https://github.com/mohammadi-hadi/judgekit
|
|
74
|
-
```
|
|
75
|
-
|
|
76
|
-
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib.
|
|
83
|
+
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib. The
|
|
84
|
+
development version installs with
|
|
85
|
+
`pip install git+https://github.com/mohammadi-hadi/judgekit`.
|
|
77
86
|
|
|
78
87
|
## Quickstart
|
|
79
88
|
|
|
@@ -145,7 +154,7 @@ judge.
|
|
|
145
154
|
silent on the clean judge, including a world where longer answers genuinely
|
|
146
155
|
are better and the raw length correlation would convict an honest judge.
|
|
147
156
|
- **Drift-checked results.** Every number above and in
|
|
148
|
-
[results/report.md](results/report.md) is regenerated by CI from pinned
|
|
157
|
+
[results/report.md](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) is regenerated by CI from pinned
|
|
149
158
|
dependencies and diffed against the committed copy.
|
|
150
159
|
|
|
151
160
|
## Design notes
|
|
@@ -155,7 +164,7 @@ judge.
|
|
|
155
164
|
defect-free judge could plausibly occupy — position 0.45–0.55, correlations
|
|
156
165
|
±0.10, self-preference ±0.20 scale points, spread 0.90–1.10, ECE ≤ 0.05 —
|
|
157
166
|
and flags only when the whole 95% interval leaves it. The bands are opinions,
|
|
158
|
-
stated in one place ([`bias.py`](src/judgekit/bias.py)) and easy to disagree
|
|
167
|
+
stated in one place ([`bias.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/src/judgekit/bias.py)) and easy to disagree
|
|
159
168
|
with.
|
|
160
169
|
- **Item-level bootstrap.** Re-judgments and swapped presentations of an item
|
|
161
170
|
are resampled together; treating correlated rows as independent evidence
|
|
@@ -198,10 +207,27 @@ the LLM-as-a-judge survey ([Gu et al., 2024](https://arxiv.org/abs/2411.15594)).
|
|
|
198
207
|
judgekit's contribution is packaging the checks as one auditable tool with
|
|
199
208
|
uncertainty on every number and validation by implantation.
|
|
200
209
|
|
|
201
|
-
|
|
202
|
-
|
|
203
|
-
[
|
|
204
|
-
|
|
210
|
+
## Part of evalstack
|
|
211
|
+
|
|
212
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
213
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
214
|
+
and the two chains that run end to end.
|
|
215
|
+
|
|
216
|
+
## Citation
|
|
217
|
+
|
|
218
|
+
If judgekit is useful in your research, please cite it (see
|
|
219
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/judgekit/blob/main/CITATION.cff)):
|
|
220
|
+
|
|
221
|
+
```bibtex
|
|
222
|
+
@software{mohammadi_judgekit,
|
|
223
|
+
author = {Mohammadi, Hadi},
|
|
224
|
+
title = {judgekit: audit an LLM judge before you trust it},
|
|
225
|
+
url = {https://github.com/mohammadi-hadi/judgekit},
|
|
226
|
+
doi = {10.5281/zenodo.21802868},
|
|
227
|
+
version = {0.2.2},
|
|
228
|
+
year = {2026}
|
|
229
|
+
}
|
|
230
|
+
```
|
|
205
231
|
|
|
206
232
|
## License
|
|
207
233
|
|
|
@@ -4,8 +4,8 @@ build-backend = "setuptools.build_meta"
|
|
|
4
4
|
|
|
5
5
|
[project]
|
|
6
6
|
name = "judgekit"
|
|
7
|
-
version = "0.2.
|
|
8
|
-
description = "
|
|
7
|
+
version = "0.2.2"
|
|
8
|
+
description = "Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability."
|
|
9
9
|
readme = "README.md"
|
|
10
10
|
license = { text = "MIT" }
|
|
11
11
|
authors = [{ name = "Hadi Mohammadi" }]
|
|
@@ -1,11 +1,11 @@
|
|
|
1
|
-
"""judgekit:
|
|
1
|
+
"""judgekit: bias probes for LLM judges, each with a bootstrap confidence interval."""
|
|
2
2
|
|
|
3
3
|
from judgekit.audit import AuditReport, run_audit
|
|
4
4
|
from judgekit.io import dump_verdicts, load_verdicts
|
|
5
5
|
from judgekit.result import ProbeResult, SkippedProbe
|
|
6
6
|
from judgekit.schema import BinaryVerdict, GradedVerdict, PairwiseVerdict
|
|
7
7
|
|
|
8
|
-
__version__ = "0.2.
|
|
8
|
+
__version__ = "0.2.2"
|
|
9
9
|
|
|
10
10
|
__all__ = [
|
|
11
11
|
"AuditReport",
|
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: judgekit
|
|
3
|
-
Version: 0.2.
|
|
4
|
-
Summary:
|
|
3
|
+
Version: 0.2.2
|
|
4
|
+
Summary: Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.
|
|
5
5
|
Author: Hadi Mohammadi
|
|
6
6
|
License: MIT
|
|
7
7
|
Project-URL: Homepage, https://github.com/mohammadi-hadi/judgekit
|
|
@@ -30,11 +30,19 @@ Requires-Dist: krippendorff>=0.6; extra == "dev"
|
|
|
30
30
|
Requires-Dist: statsmodels>=0.14; extra == "dev"
|
|
31
31
|
Dynamic: license-file
|
|
32
32
|
|
|
33
|
-
|
|
33
|
+
<div align="center">
|
|
34
34
|
|
|
35
|
-
|
|
35
|
+
# judgekit
|
|
36
36
|
|
|
37
37
|
[](https://github.com/mohammadi-hadi/judgekit/actions/workflows/ci.yml)
|
|
38
|
+
[](https://pypi.org/project/judgekit/)
|
|
39
|
+
[](https://doi.org/10.5281/zenodo.21802868)
|
|
40
|
+
[](https://www.python.org/downloads/)
|
|
41
|
+
[](https://github.com/mohammadi-hadi/judgekit/blob/main/LICENSE)
|
|
42
|
+
|
|
43
|
+
*Bias probes for LLM judges, each with a bootstrap confidence interval: position, verbosity, self-preference, calibration and stability.*
|
|
44
|
+
|
|
45
|
+
</div>
|
|
38
46
|
|
|
39
47
|
An LLM judge is a model too. It can prefer whichever answer came first, reward
|
|
40
48
|
padding, favor its own outputs, hug the middle of the scale, and say "90%
|
|
@@ -63,35 +71,40 @@ The row to sit with is `length-lover`: quadratic-weighted kappa with humans of
|
|
|
63
71
|
0.80 — a number most eval writeups would celebrate — while carrying a verbosity
|
|
64
72
|
bias of +0.82. Agreement is not an audit.
|
|
65
73
|
|
|
66
|
-
`make demo` regenerates this table, the [full report](results/report.md) and
|
|
74
|
+
`make demo` regenerates this table, the [full report](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) and
|
|
67
75
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
68
76
|
fails if a committed number differs from what the code produces.
|
|
69
77
|
|
|
70
|
-

|
|
78
|
+

|
|
71
79
|
|
|
72
|
-

|
|
80
|
+

|
|
73
81
|
|
|
74
82
|
## Two real judges, audited
|
|
75
83
|
|
|
76
|
-
[`examples/audit_ollama.py`](examples/audit_ollama.py) builds a small
|
|
84
|
+
[`examples/audit_ollama.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/examples/audit_ollama.py) builds a small
|
|
77
85
|
adversarial arithmetic benchmark — one answer provably correct by
|
|
78
86
|
construction, and half the time the wrong answer is the long, worked-through
|
|
79
87
|
one — then asks a local Ollama model to judge every pair in both presentation
|
|
80
88
|
orders. Verdicts and full reports are committed under
|
|
81
|
-
[examples/results](examples/results/).
|
|
89
|
+
[examples/results](https://github.com/mohammadi-hadi/judgekit/tree/main/examples/results/).
|
|
82
90
|
|
|
83
91
|
| judge (temperature 0) | truth agreement | position preference | verbosity excess | flips under swap | decisive on identical pairs |
|
|
84
92
|
|---|---|---|---|---|---|
|
|
93
|
+
| aya-expanse:8b | 0.433 | **0.910** (flag) | +0.106 | 0.819 | 1.000 |
|
|
85
94
|
| qwen2.5:14b | 0.667 | **0.768** (flag) | +0.131 | 0.568 | 0.200 |
|
|
86
95
|
| llama3.1:8b | 0.443 | 0.576 | **+0.483** (flag) | 0.171 | 1.000 |
|
|
87
96
|
|
|
88
|
-
Same task,
|
|
89
|
-
presented
|
|
90
|
-
|
|
91
|
-
|
|
92
|
-
|
|
93
|
-
|
|
94
|
-
|
|
97
|
+
Same task, different failure modes at different severities. Two judges follow
|
|
98
|
+
slot order — aya picks whatever is presented first 91.0% of the time and flips
|
|
99
|
+
81.9% of pairs when the order is swapped; qwen sits at 76.8% and 56.8%. The
|
|
100
|
+
llama judge grades effort instead, picking the longer answer 48 points more
|
|
101
|
+
often than correctness warrants and scoring 0.443 against ground truth. Two of
|
|
102
|
+
the three never once declare a tie between identical answers, which is also
|
|
103
|
+
why that 0.443 is softer than it looks: those 15 pairs are unwinnable for a
|
|
104
|
+
judge that never ties, and on the 90 adversarial pairs alone the llama judge
|
|
105
|
+
reaches 0.517 — level with chance rather than below it. n=105 pairs,
|
|
106
|
+
adversarial by construction — an illustration of what the probes see, not a
|
|
107
|
+
model leaderboard.
|
|
95
108
|
|
|
96
109
|
## Install
|
|
97
110
|
|
|
@@ -99,13 +112,9 @@ of what the probes see, not a model leaderboard.
|
|
|
99
112
|
pip install judgekit
|
|
100
113
|
```
|
|
101
114
|
|
|
102
|
-
|
|
103
|
-
|
|
104
|
-
|
|
105
|
-
pip install git+https://github.com/mohammadi-hadi/judgekit
|
|
106
|
-
```
|
|
107
|
-
|
|
108
|
-
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib.
|
|
115
|
+
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib. The
|
|
116
|
+
development version installs with
|
|
117
|
+
`pip install git+https://github.com/mohammadi-hadi/judgekit`.
|
|
109
118
|
|
|
110
119
|
## Quickstart
|
|
111
120
|
|
|
@@ -177,7 +186,7 @@ judge.
|
|
|
177
186
|
silent on the clean judge, including a world where longer answers genuinely
|
|
178
187
|
are better and the raw length correlation would convict an honest judge.
|
|
179
188
|
- **Drift-checked results.** Every number above and in
|
|
180
|
-
[results/report.md](results/report.md) is regenerated by CI from pinned
|
|
189
|
+
[results/report.md](https://github.com/mohammadi-hadi/judgekit/blob/main/results/report.md) is regenerated by CI from pinned
|
|
181
190
|
dependencies and diffed against the committed copy.
|
|
182
191
|
|
|
183
192
|
## Design notes
|
|
@@ -187,7 +196,7 @@ judge.
|
|
|
187
196
|
defect-free judge could plausibly occupy — position 0.45–0.55, correlations
|
|
188
197
|
±0.10, self-preference ±0.20 scale points, spread 0.90–1.10, ECE ≤ 0.05 —
|
|
189
198
|
and flags only when the whole 95% interval leaves it. The bands are opinions,
|
|
190
|
-
stated in one place ([`bias.py`](src/judgekit/bias.py)) and easy to disagree
|
|
199
|
+
stated in one place ([`bias.py`](https://github.com/mohammadi-hadi/judgekit/blob/main/src/judgekit/bias.py)) and easy to disagree
|
|
191
200
|
with.
|
|
192
201
|
- **Item-level bootstrap.** Re-judgments and swapped presentations of an item
|
|
193
202
|
are resampled together; treating correlated rows as independent evidence
|
|
@@ -230,10 +239,27 @@ the LLM-as-a-judge survey ([Gu et al., 2024](https://arxiv.org/abs/2411.15594)).
|
|
|
230
239
|
judgekit's contribution is packaging the checks as one auditable tool with
|
|
231
240
|
uncertainty on every number and validation by implantation.
|
|
232
241
|
|
|
233
|
-
|
|
234
|
-
|
|
235
|
-
[
|
|
236
|
-
|
|
242
|
+
## Part of evalstack
|
|
243
|
+
|
|
244
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
245
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
246
|
+
and the two chains that run end to end.
|
|
247
|
+
|
|
248
|
+
## Citation
|
|
249
|
+
|
|
250
|
+
If judgekit is useful in your research, please cite it (see
|
|
251
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/judgekit/blob/main/CITATION.cff)):
|
|
252
|
+
|
|
253
|
+
```bibtex
|
|
254
|
+
@software{mohammadi_judgekit,
|
|
255
|
+
author = {Mohammadi, Hadi},
|
|
256
|
+
title = {judgekit: audit an LLM judge before you trust it},
|
|
257
|
+
url = {https://github.com/mohammadi-hadi/judgekit},
|
|
258
|
+
doi = {10.5281/zenodo.21802868},
|
|
259
|
+
version = {0.2.2},
|
|
260
|
+
year = {2026}
|
|
261
|
+
}
|
|
262
|
+
```
|
|
237
263
|
|
|
238
264
|
## License
|
|
239
265
|
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|