jev2semopt 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- jev2semopt-0.1.0/.gitignore +8 -0
- jev2semopt-0.1.0/CONTRIBUTING.md +32 -0
- jev2semopt-0.1.0/LICENSE +21 -0
- jev2semopt-0.1.0/NOTICE +20 -0
- jev2semopt-0.1.0/PKG-INFO +267 -0
- jev2semopt-0.1.0/README.md +242 -0
- jev2semopt-0.1.0/benchmarks/README.md +169 -0
- jev2semopt-0.1.0/benchmarks/download_scifact.py +37 -0
- jev2semopt-0.1.0/benchmarks/environment.txt +81 -0
- jev2semopt-0.1.0/benchmarks/official_jev.py +106 -0
- jev2semopt-0.1.0/benchmarks/plot_results.py +93 -0
- jev2semopt-0.1.0/benchmarks/report_small_sample.py +72 -0
- jev2semopt-0.1.0/benchmarks/results/scifact-qwen25-05b.json +23147 -0
- jev2semopt-0.1.0/benchmarks/results/scifact-small-gpt4omini.json +5043 -0
- jev2semopt-0.1.0/benchmarks/scifact.py +239 -0
- jev2semopt-0.1.0/benchmarks/scifact_data.py +74 -0
- jev2semopt-0.1.0/benchmarks/small_sample.py +222 -0
- jev2semopt-0.1.0/docs/api.md +76 -0
- jev2semopt-0.1.0/docs/architecture.md +48 -0
- jev2semopt-0.1.0/docs/assets/scifact-local.png +0 -0
- jev2semopt-0.1.0/docs/assets/scifact-local.svg +3073 -0
- jev2semopt-0.1.0/docs/assets/scifact-small-sample.png +0 -0
- jev2semopt-0.1.0/docs/assets/scifact-small-sample.svg +2261 -0
- jev2semopt-0.1.0/docs/evaluation.md +28 -0
- jev2semopt-0.1.0/docs/implementation-plan.md +40 -0
- jev2semopt-0.1.0/docs/licenses/LOTUS-Apache-2.0.txt +201 -0
- jev2semopt-0.1.0/docs/licenses.md +23 -0
- jev2semopt-0.1.0/docs/official-jev.md +88 -0
- jev2semopt-0.1.0/docs/privacy.md +16 -0
- jev2semopt-0.1.0/docs/releasing.md +23 -0
- jev2semopt-0.1.0/docs/verification.md +28 -0
- jev2semopt-0.1.0/examples/decorated_decision.py +28 -0
- jev2semopt-0.1.0/examples/official_jev.py +24 -0
- jev2semopt-0.1.0/examples/refund_pipeline.py +40 -0
- jev2semopt-0.1.0/pyproject.toml +46 -0
- jev2semopt-0.1.0/src/jev2semopt/__init__.py +14 -0
- jev2semopt-0.1.0/src/jev2semopt/adapters/__init__.py +1 -0
- jev2semopt-0.1.0/src/jev2semopt/adapters/jev.py +123 -0
- jev2semopt-0.1.0/src/jev2semopt/adapters/llm2jev.py +31 -0
- jev2semopt-0.1.0/src/jev2semopt/contracts.py +20 -0
- jev2semopt-0.1.0/src/jev2semopt/decorators.py +27 -0
- jev2semopt-0.1.0/src/jev2semopt/engine.py +152 -0
- jev2semopt-0.1.0/src/jev2semopt/execution.py +102 -0
- jev2semopt-0.1.0/src/jev2semopt/pandas.py +36 -0
- jev2semopt-0.1.0/src/jev2semopt/py.typed +0 -0
- jev2semopt-0.1.0/src/jev2semopt/table.py +40 -0
- jev2semopt-0.1.0/tests/test_adapter.py +58 -0
- jev2semopt-0.1.0/tests/test_architecture.py +70 -0
- jev2semopt-0.1.0/tests/test_benchmark_metrics.py +40 -0
- jev2semopt-0.1.0/tests/test_jev.py +182 -0
- jev2semopt-0.1.0/tests/test_operators.py +315 -0
- jev2semopt-0.1.0/uv.lock +4271 -0
|
@@ -0,0 +1,32 @@
|
|
|
1
|
+
# Development
|
|
2
|
+
|
|
3
|
+
Python 3.8 is the minimum. Use `typing` generics and Optional/Union, and evaluate
|
|
4
|
+
annotations on the minimum interpreter. Keep module responsibility docstrings and
|
|
5
|
+
contract comments immediately before named functions, including decorators.
|
|
6
|
+
|
|
7
|
+
```bash
|
|
8
|
+
uv sync --group dev
|
|
9
|
+
uv run python -m unittest discover -s tests -v
|
|
10
|
+
uv run python -m compileall -q src tests examples benchmarks
|
|
11
|
+
uv run mypy src/jev2semopt
|
|
12
|
+
uv run python examples/refund_pipeline.py
|
|
13
|
+
uv run python examples/decorated_decision.py
|
|
14
|
+
uv build
|
|
15
|
+
uv run twine check dist/*
|
|
16
|
+
```
|
|
17
|
+
|
|
18
|
+
Use `UV_PROJECT_ENVIRONMENT=.venv38 uv sync --python 3.8 --group dev` and the same
|
|
19
|
+
environment setting with `uv run --python 3.8 ...` for minimum-version checks.
|
|
20
|
+
Tests must not fetch models or require network access after dependencies are installed.
|
|
21
|
+
The fixed Git development source in pyproject.toml is deliberately separate from
|
|
22
|
+
wheel dependency metadata; see [releasing](docs/releasing.md) for production checks.
|
|
23
|
+
|
|
24
|
+
Keep ownership boundaries in [architecture](docs/architecture.md). Do not copy
|
|
25
|
+
provider code, private upstream helpers, or probability validation into operators.
|
|
26
|
+
Preserve source attribution. Use deterministic backend/runtime doubles for tests;
|
|
27
|
+
validate both successful behavior and rejected input before adding public options.
|
|
28
|
+
|
|
29
|
+
PR descriptions should state the concrete behavioral result, verification evidence,
|
|
30
|
+
relevant issues, and changed assumptions. Update docs/implementation-plan.md when
|
|
31
|
+
scope or architecture changes. Agent commits use author and committer
|
|
32
|
+
`Silan.Hu <silan.hu@u.nus.edu>`. No history rewriting or edited provenance dates.
|
jev2semopt-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Silan.Hu and Jev2SemOpt contributors
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
jev2semopt-0.1.0/NOTICE
ADDED
|
@@ -0,0 +1,20 @@
|
|
|
1
|
+
Jev2SemOpt
|
|
2
|
+
Copyright (c) 2026 Silan.Hu and Jev2SemOpt contributors
|
|
3
|
+
|
|
4
|
+
The semantic-operator model and operator vocabulary are inspired by LOTUS:
|
|
5
|
+
https://github.com/lotus-data/lotus
|
|
6
|
+
https://arxiv.org/abs/2407.11418
|
|
7
|
+
LOTUS is Apache-2.0 licensed. Its operator implementation is an external
|
|
8
|
+
benchmark dependency, not part of the Jev2SemOpt runtime. The reranking benchmark
|
|
9
|
+
objective/prompt is adapted from its llm-eval experiment; see
|
|
10
|
+
docs/licenses/LOTUS-Apache-2.0.txt for the upstream license.
|
|
11
|
+
|
|
12
|
+
Jev state/questions and Choice, Score, Noul interface concepts originate with TypeSafe:
|
|
13
|
+
https://typesafe.ai/blog/introducing-system-one-models-and-jev
|
|
14
|
+
This project is independent. Its HTTP adapter targets the documented TypeSafe
|
|
15
|
+
API; hosted model behavior and accuracy have not been verified.
|
|
16
|
+
|
|
17
|
+
LLM2Jev provides public decision types and execution as an external dependency:
|
|
18
|
+
https://github.com/Qingbolan/llm2jev-releases
|
|
19
|
+
Its architectural separation and documentation structure informed this project.
|
|
20
|
+
LLM2Jev is MIT licensed, copyright (c) 2026 LLM2Jev contributors.
|
|
@@ -0,0 +1,267 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: jev2semopt
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Bounded semantic dataframe operators powered by Jev-style decisions
|
|
5
|
+
Project-URL: Repository, https://github.com/Qingbolan/Jev2SemOpt
|
|
6
|
+
Project-URL: Documentation, https://github.com/Qingbolan/Jev2SemOpt/tree/main/docs
|
|
7
|
+
Author-email: "Silan.Hu" <silan.hu@u.nus.edu>
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
License-File: NOTICE
|
|
11
|
+
Keywords: dataframe,jev,llm,semantic-operators
|
|
12
|
+
Classifier: Development Status :: 3 - Alpha
|
|
13
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
14
|
+
Classifier: Typing :: Typed
|
|
15
|
+
Requires-Python: >=3.8
|
|
16
|
+
Requires-Dist: llm2jev<0.3,>=0.2.1
|
|
17
|
+
Requires-Dist: pandas<3,>=1.5
|
|
18
|
+
Provides-Extra: jev
|
|
19
|
+
Requires-Dist: httpx<1,>=0.27; extra == 'jev'
|
|
20
|
+
Provides-Extra: ollama
|
|
21
|
+
Requires-Dist: llm2jev[ollama]<0.3,>=0.2.1; extra == 'ollama'
|
|
22
|
+
Provides-Extra: transformers
|
|
23
|
+
Requires-Dist: llm2jev[transformers]<0.3,>=0.2.1; extra == 'transformers'
|
|
24
|
+
Description-Content-Type: text/markdown
|
|
25
|
+
|
|
26
|
+
# Jev2SemOpt — Typed decisions over tables
|
|
27
|
+
|
|
28
|
+
**Filter tickets. Assign queues. Rank records. Match pairs.**
|
|
29
|
+
|
|
30
|
+
A support pipeline needs to keep refund requests, assign a fixed queue, and count
|
|
31
|
+
the resulting tickets. Jev2SemOpt makes those dataset operations explicit: select
|
|
32
|
+
the fields the model may see, bind a typed question once, evaluate each record,
|
|
33
|
+
and apply the result with ordinary Pandas operations.
|
|
34
|
+
|
|
35
|
+
Jev2SemOpt is an independent, early-stage Python library inspired by
|
|
36
|
+
[LOTUS semantic operators](https://github.com/lotus-data/lotus), using
|
|
37
|
+
[LLM2Jev](https://github.com/Qingbolan/llm2jev-releases) for Jev-style decisions.
|
|
38
|
+
The Jev interface concepts and `Choice`, `Score`, `Noul` vocabulary originate with
|
|
39
|
+
[TypeSafe](https://typesafe.ai/blog/introducing-system-one-models-and-jev).
|
|
40
|
+
Use a local LLM2Jev runtime or the official TypeSafe HTTP API through `JevBackend`.
|
|
41
|
+
The HTTP adapter is contract-tested; hosted Jev accuracy has not been measured.
|
|
42
|
+
|
|
43
|
+
## Install and run
|
|
44
|
+
|
|
45
|
+
Python **3.8+**. The core requires Pandas and LLM2Jev; model providers are opt-in.
|
|
46
|
+
|
|
47
|
+
```bash
|
|
48
|
+
pip install jev2semopt
|
|
49
|
+
# Official hosted Jev (requires a TypeSafe API key):
|
|
50
|
+
pip install 'jev2semopt[jev]'
|
|
51
|
+
# Local providers:
|
|
52
|
+
pip install 'jev2semopt[transformers]'
|
|
53
|
+
# or: pip install 'jev2semopt[ollama]'
|
|
54
|
+
```
|
|
55
|
+
|
|
56
|
+
For a model-free example or development:
|
|
57
|
+
|
|
58
|
+
```bash
|
|
59
|
+
git clone https://github.com/Qingbolan/Jev2SemOpt.git
|
|
60
|
+
cd Jev2SemOpt
|
|
61
|
+
uv sync --group dev
|
|
62
|
+
uv run python examples/refund_pipeline.py
|
|
63
|
+
uv run python examples/decorated_decision.py
|
|
64
|
+
```
|
|
65
|
+
|
|
66
|
+
These examples use synthetic scores and require no model or API key. Production
|
|
67
|
+
and development dependencies resolve from PyPI. See [release verification](docs/releasing.md).
|
|
68
|
+
|
|
69
|
+
## A refund pipeline
|
|
70
|
+
|
|
71
|
+
Configure execution explicitly. The application owns the runtime and closes it;
|
|
72
|
+
Jev2SemOpt only borrows it. The following requires compatible local model weights
|
|
73
|
+
and a model-appropriate LLM2Jev encoder/label configuration; it is an API example,
|
|
74
|
+
not a validated inference configuration.
|
|
75
|
+
|
|
76
|
+
```python
|
|
77
|
+
import pandas as pd
|
|
78
|
+
from llm2jev import LLM2Jev, TransformersRuntime
|
|
79
|
+
from jev2semopt import LLM2JevBackend, SemEngine, Choice
|
|
80
|
+
|
|
81
|
+
tickets = pd.DataFrame({
|
|
82
|
+
"id": [101, 102],
|
|
83
|
+
"text": ["Please refund my order.", "Where is my parcel?"],
|
|
84
|
+
})
|
|
85
|
+
|
|
86
|
+
with TransformersRuntime("/path/to/local/model", device="cpu") as runtime:
|
|
87
|
+
engine = SemEngine(LLM2JevBackend(
|
|
88
|
+
LLM2Jev(runtime=runtime, model_identity=runtime.identity),
|
|
89
|
+
model=runtime.identity.name,
|
|
90
|
+
))
|
|
91
|
+
refunds = engine.sem_filter(
|
|
92
|
+
tickets, "Does text explicitly request a refund?",
|
|
93
|
+
columns=["text"], threshold=0.7, probability_column="refund_support",
|
|
94
|
+
)
|
|
95
|
+
routed = engine.sem_map(
|
|
96
|
+
refunds,
|
|
97
|
+
Choice(instructions="Which team should handle text?", criteria={
|
|
98
|
+
"billing": "Payments, invoices, or refunds",
|
|
99
|
+
"delivery": "Shipping, tracking, or missing parcels",
|
|
100
|
+
"other": "Requests outside billing and delivery",
|
|
101
|
+
}),
|
|
102
|
+
columns=["text"], output="queue",
|
|
103
|
+
)
|
|
104
|
+
counts = routed.groupby("queue").size()
|
|
105
|
+
```
|
|
106
|
+
|
|
107
|
+
Only `text` enters the decision state. IDs remain available in the output. Column
|
|
108
|
+
names in instructions refer to keys in that state; there is **no `{column}` string
|
|
109
|
+
interpolation**. Thresholds require validation on your own labeled workload.
|
|
110
|
+
|
|
111
|
+
## Operators and boundaries
|
|
112
|
+
|
|
113
|
+
Official hosted Jev is also supported through `JevBackend`, using a caller-owned
|
|
114
|
+
HTTP client and TypeSafe API key. See the [official API integration](docs/official-jev.md)
|
|
115
|
+
for setup and verification limits. An OpenRouter key does not authenticate TypeSafe.
|
|
116
|
+
|
|
117
|
+
| Operator | Jev decision | Output and scope |
|
|
118
|
+
| --- | --- | --- |
|
|
119
|
+
| `sem_filter(frame, instructions, ...)` | `Noul` | Rows with support **≥ threshold**, original order and index |
|
|
120
|
+
| `sem_map(frame, Choice(...), output=...)` | `Choice` | All rows plus a chosen label from supplied alternatives |
|
|
121
|
+
| `sem_score(frame, Score(...), ...)` | `Score` | All rows plus expected ordinal rubric level |
|
|
122
|
+
| `sem_topk(frame, Score(...), k=...)` | `Score` | Largest expected levels; stable source-order ties |
|
|
123
|
+
| `sem_join(left, right, instructions, ...)` | `Noul` | Inner join over candidate pairs; namespaced source fields and positions |
|
|
124
|
+
|
|
125
|
+
LOTUS provides a broader semantic operator model, including generated projections,
|
|
126
|
+
extraction, aggregation, and comparator-based ranking. Jev2SemOpt deliberately
|
|
127
|
+
restricts mappings to finite alternatives and ranks by an explicit ordinal rubric.
|
|
128
|
+
It is not a drop-in LOTUS replacement. Free-text extraction, summaries, vector
|
|
129
|
+
search, learned cascades, SQL planning, asynchronous execution, and distributed
|
|
130
|
+
execution are not implemented. Count/group/sum the typed outputs with Pandas;
|
|
131
|
+
there is no misleading `sem_agg` alias for a generative summary.
|
|
132
|
+
|
|
133
|
+
```python
|
|
134
|
+
from jev2semopt import Score
|
|
135
|
+
|
|
136
|
+
ranked = engine.sem_topk(
|
|
137
|
+
tickets,
|
|
138
|
+
Score(instructions="How urgent is text?", criteria=[
|
|
139
|
+
"Routine request", "Time-sensitive issue", "Immediate safety or service emergency",
|
|
140
|
+
]),
|
|
141
|
+
columns=["text"], k=10, output="urgency",
|
|
142
|
+
)
|
|
143
|
+
|
|
144
|
+
matches = engine.sem_join(
|
|
145
|
+
tickets, policies,
|
|
146
|
+
"Does left.text describe a case covered by right.policy?",
|
|
147
|
+
left_columns=["text"], right_columns=["policy"],
|
|
148
|
+
candidates=[(0, 1), (1, 0)], # row POSITIONS, not index labels
|
|
149
|
+
threshold=0.8,
|
|
150
|
+
)
|
|
151
|
+
```
|
|
152
|
+
|
|
153
|
+
The join output includes `left.<column>`, `right.<column>`, `_left_position`,
|
|
154
|
+
`_right_position`, and `_probability`. Without candidates it evaluates every pair,
|
|
155
|
+
subject to a default 100,000-pair limit. A shortlist can reduce work but can also
|
|
156
|
+
exclude true matches; the caller owns its recall. See [API contracts](docs/api.md).
|
|
157
|
+
|
|
158
|
+
## Python-native integration
|
|
159
|
+
|
|
160
|
+
The Pandas accessor is opt-in and uses Pandas' registration decorator. It forwards
|
|
161
|
+
to the same engine implementation and does not install global model settings:
|
|
162
|
+
|
|
163
|
+
```python
|
|
164
|
+
import jev2semopt.pandas
|
|
165
|
+
|
|
166
|
+
refunds = tickets.jev.sem_filter(
|
|
167
|
+
engine, "Does text request a refund?", columns=["text"], threshold=0.7,
|
|
168
|
+
)
|
|
169
|
+
```
|
|
170
|
+
|
|
171
|
+
Use `@decision` when application code already builds the state for one decision:
|
|
172
|
+
|
|
173
|
+
```python
|
|
174
|
+
from jev2semopt import Noul, decision
|
|
175
|
+
|
|
176
|
+
@decision(engine, question=Noul(instructions="Does text explicitly request a refund?"))
|
|
177
|
+
def refund_requested(text):
|
|
178
|
+
return {"text": text}
|
|
179
|
+
|
|
180
|
+
answer = refund_requested("Please refund my order.")
|
|
181
|
+
print(answer.noul)
|
|
182
|
+
```
|
|
183
|
+
|
|
184
|
+
The decorator binds once, preserves function metadata with `functools.wraps`, and
|
|
185
|
+
evaluates new state on each call. It does not cache results across calls. Decorated
|
|
186
|
+
functions must be synchronous JSON-state builders and now return typed answers.
|
|
187
|
+
|
|
188
|
+
## Measured results
|
|
189
|
+
|
|
190
|
+
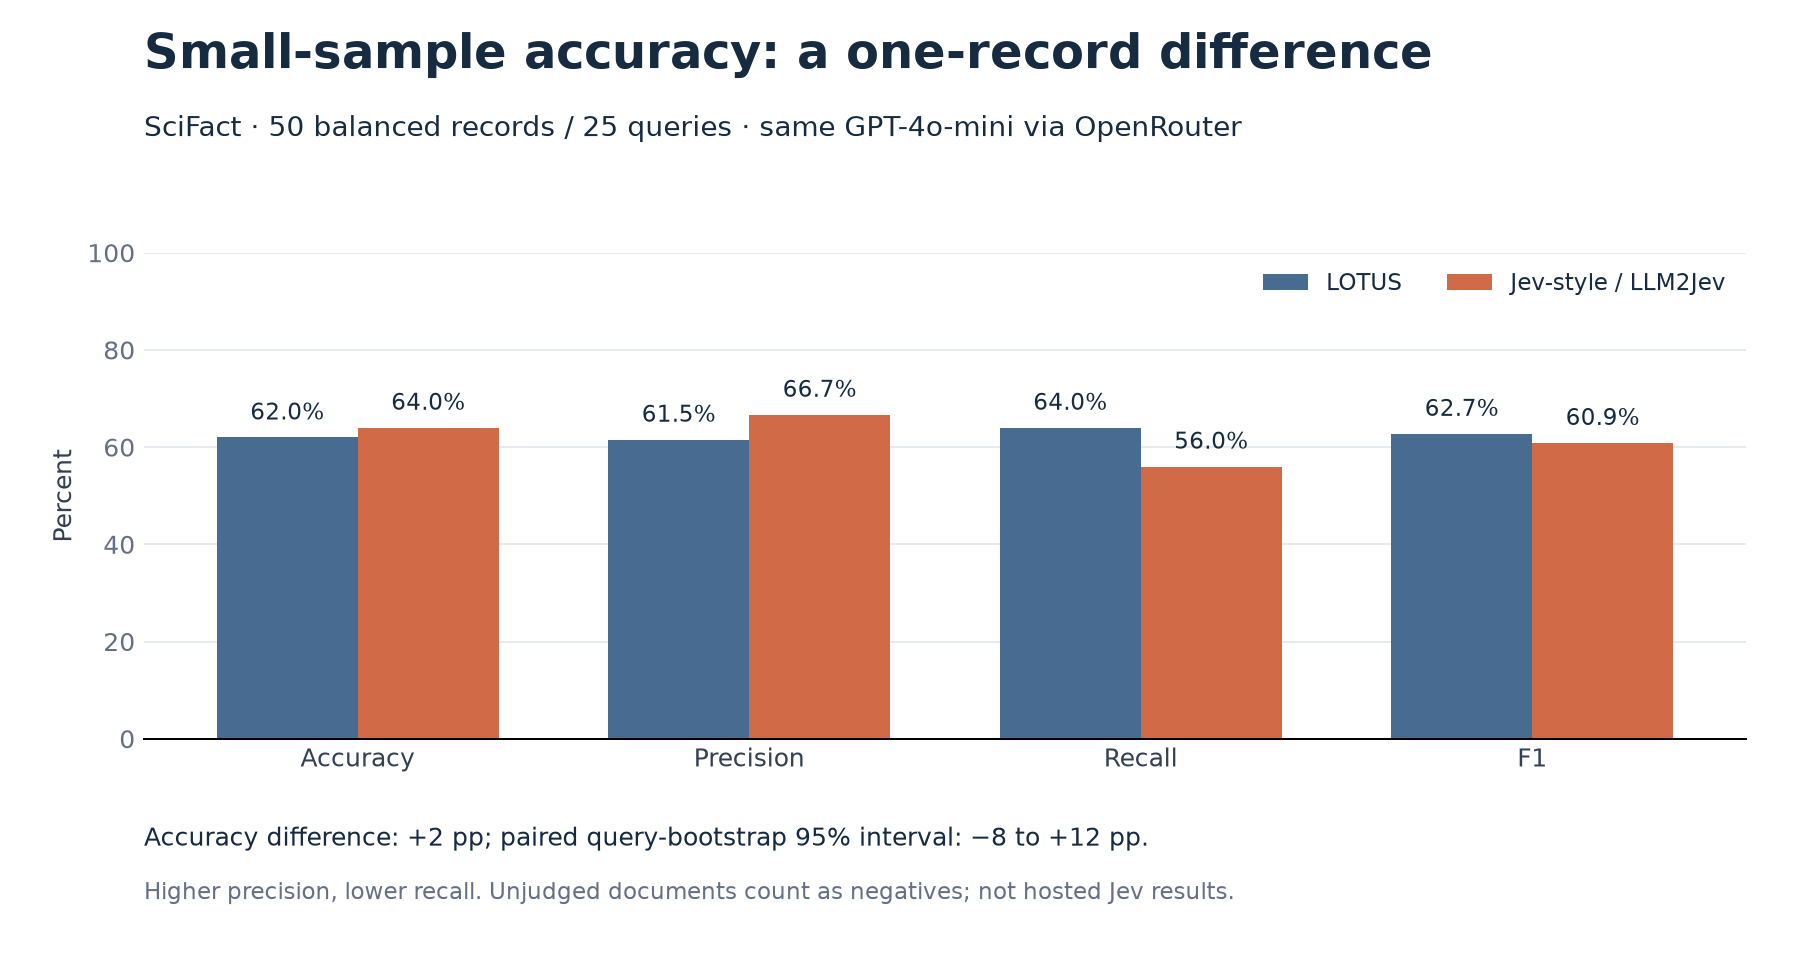
On **50 balanced SciFact records**, the same GPT-4o-mini scored **31/50 with LOTUS**
|
|
191
|
+
and **32/50 with Jev-style / LLM2Jev**. The one-record difference does not establish
|
|
192
|
+
an accuracy improvement: the paired 95% interval spans −8 to +12 percentage points.
|
|
193
|
+
Jev-style improves precision but lowers recall and F1 in this run.
|
|
194
|
+
|
|
195
|
+
|
|
196
|
+
|
|
197
|
+
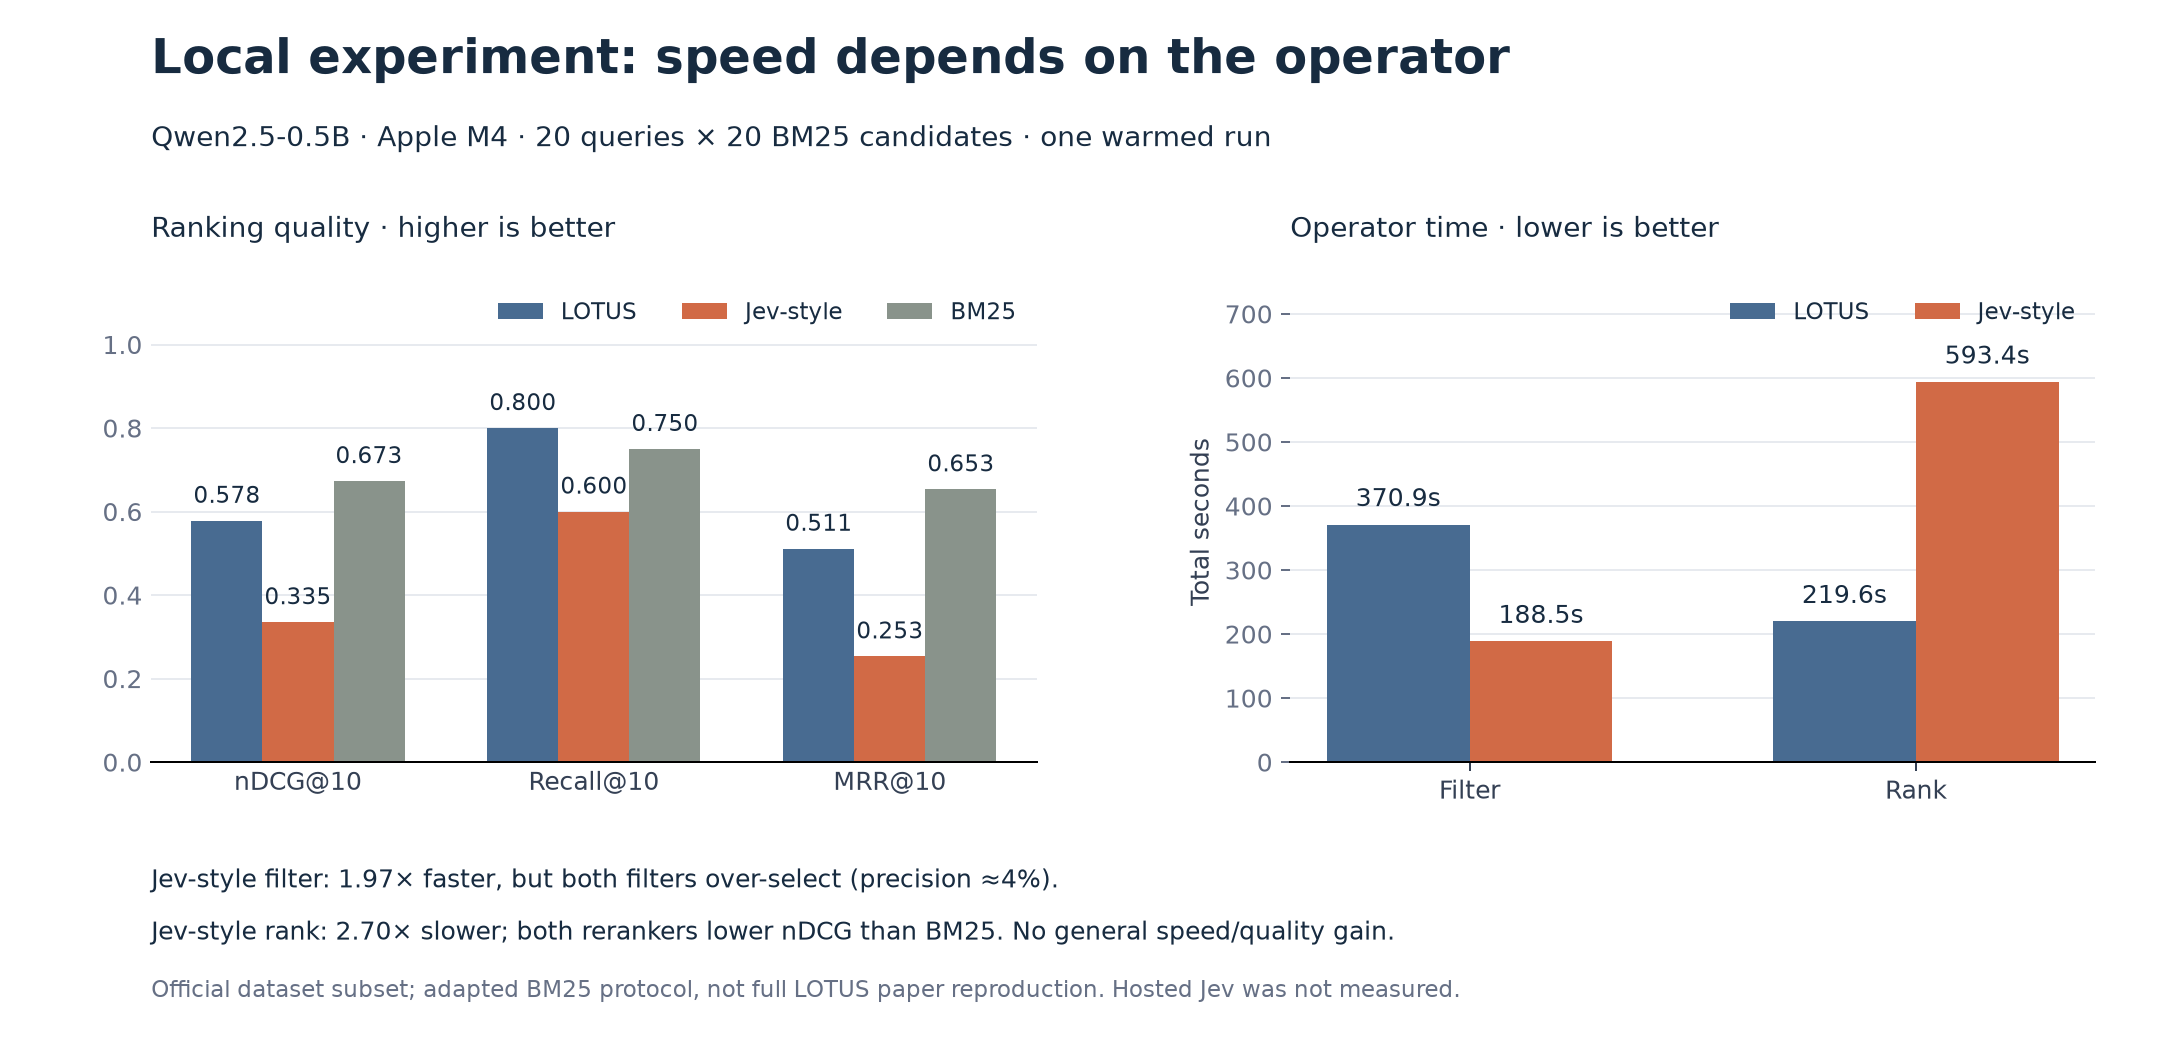
On **400 local Qwen2.5-0.5B candidate pairs**, Jev-style filtering was 1.97× faster,
|
|
198
|
+
but both filters had roughly 4% precision. Three-level Jev-style scoring was 2.70×
|
|
199
|
+
slower than LOTUS scoring and reduced ranking quality. BM25 had the highest nDCG.
|
|
200
|
+
|
|
201
|
+
|
|
202
|
+
|
|
203
|
+
These are **official SciFact dataset subsets with adapted protocols**, not full
|
|
204
|
+
LOTUS paper reproduction or measurements of TypeSafe's hosted Jev model. Unjudged
|
|
205
|
+
documents count as negatives under the qrel convention. Prompts differ between
|
|
206
|
+
operators; these experiments do not isolate probability assembly as the cause.
|
|
207
|
+
[Sampling, confusion matrices, costs, raw observations, and reproduction](https://github.com/Qingbolan/Jev2SemOpt/blob/v0.1.0/benchmarks/README.md).
|
|
208
|
+
|
|
209
|
+
## Execution cost and score meaning
|
|
210
|
+
|
|
211
|
+
`SemEngine(backend, deduplicate=True)` reuses identical selected JSON state **within
|
|
212
|
+
one operation**. This is opt-in and assumes the backend is deterministic and has no
|
|
213
|
+
per-call side effects. There is no global cache and no stale reuse across operations.
|
|
214
|
+
Question binding avoids recompilation; it is not a KV cache or a batched model call.
|
|
215
|
+
|
|
216
|
+
For `N` rows, filtering requires `N` one-candidate evaluations; mapping with `C`
|
|
217
|
+
choices requires `N × C` binary candidates; scoring with `R` rubric levels requires
|
|
218
|
+
`N × R`. An exhaustive join needs `L × R` pair evaluations. Duplicate reuse reduces
|
|
219
|
+
these counts to unique selected states. Calls are sequential. Join candidates and
|
|
220
|
+
results are materialized in memory; this version targets bounded in-memory tables.
|
|
221
|
+
|
|
222
|
+
No end-to-end speedup, calibrated correctness, or equivalence to LOTUS quality is
|
|
223
|
+
claimed. `Noul` is label-conditioned support; `Score` is an expected equally spaced
|
|
224
|
+
rubric index. These are decision signals, not probabilities that the answer is right.
|
|
225
|
+
LLM2Jev's Transformers adapter reads next-token logits; its Ollama adapter requests
|
|
226
|
+
one token to obtain exact binary logprobs. Jev2SemOpt never parses generated prose.
|
|
227
|
+
See [evaluation protocol](docs/evaluation.md).
|
|
228
|
+
|
|
229
|
+
## Architecture and development
|
|
230
|
+
|
|
231
|
+
```text
|
|
232
|
+
DataFrame API / @decision
|
|
233
|
+
↓
|
|
234
|
+
SemEngine — positional relational semantics
|
|
235
|
+
↓
|
|
236
|
+
EvaluationSession — one rule, detached state, operation-local reuse
|
|
237
|
+
↓
|
|
238
|
+
DecisionBackend.bind → BoundDecision.evaluate → typed Answer
|
|
239
|
+
↓
|
|
240
|
+
├─ LLM2JevBackend → public LLM2Jev API → caller-owned runtime
|
|
241
|
+
└─ JevBackend → TypeSafe HTTP API → caller-owned HTTP client
|
|
242
|
+
```
|
|
243
|
+
|
|
244
|
+
The engine depends on a backend protocol, not Ollama or Transformers. Models,
|
|
245
|
+
prompts, device configuration, binary labels, and runtime lifecycle stay in
|
|
246
|
+
LLM2Jev for local execution; hosted execution uses the supplied HTTP client. There is no new resource lifecycle to duplicate in the table layer.
|
|
247
|
+
|
|
248
|
+
```text
|
|
249
|
+
src/jev2semopt/
|
|
250
|
+
├── contracts.py Backend and bound-decision protocols
|
|
251
|
+
├── execution.py State isolation, answer checks, safe failure boundary
|
|
252
|
+
├── engine.py Filter/map/score/top-k/join semantics
|
|
253
|
+
├── table.py Dataframe schema and state projection
|
|
254
|
+
├── decorators.py Function-to-decision binding
|
|
255
|
+
├── pandas.py Opt-in accessor registration
|
|
256
|
+
└── adapters/ LLM2Jev service and official Jev HTTP integration
|
|
257
|
+
```
|
|
258
|
+
|
|
259
|
+
Run the checks in [CONTRIBUTING.md](CONTRIBUTING.md). Architectural decisions,
|
|
260
|
+
privacy constraints, and delivery status are documented in
|
|
261
|
+
[architecture](docs/architecture.md), [privacy](docs/privacy.md), and
|
|
262
|
+
[implementation plan](docs/implementation-plan.md). Attribution is recorded in
|
|
263
|
+
[NOTICE](NOTICE). Licensed under [MIT](LICENSE); [dependency and benchmark attribution](docs/licenses.md).
|
|
264
|
+
|
|
265
|
+
[Local verification record](docs/verification.md): 50 deterministic tests passed
|
|
266
|
+
on Python 3.8, 3.12, and 3.14. Real-model observations are recorded separately in
|
|
267
|
+
the [benchmark report](benchmarks/README.md).
|
|
@@ -0,0 +1,242 @@
|
|
|
1
|
+
# Jev2SemOpt — Typed decisions over tables
|
|
2
|
+
|
|
3
|
+
**Filter tickets. Assign queues. Rank records. Match pairs.**
|
|
4
|
+
|
|
5
|
+
A support pipeline needs to keep refund requests, assign a fixed queue, and count
|
|
6
|
+
the resulting tickets. Jev2SemOpt makes those dataset operations explicit: select
|
|
7
|
+
the fields the model may see, bind a typed question once, evaluate each record,
|
|
8
|
+
and apply the result with ordinary Pandas operations.
|
|
9
|
+
|
|
10
|
+
Jev2SemOpt is an independent, early-stage Python library inspired by
|
|
11
|
+
[LOTUS semantic operators](https://github.com/lotus-data/lotus), using
|
|
12
|
+
[LLM2Jev](https://github.com/Qingbolan/llm2jev-releases) for Jev-style decisions.
|
|
13
|
+
The Jev interface concepts and `Choice`, `Score`, `Noul` vocabulary originate with
|
|
14
|
+
[TypeSafe](https://typesafe.ai/blog/introducing-system-one-models-and-jev).
|
|
15
|
+
Use a local LLM2Jev runtime or the official TypeSafe HTTP API through `JevBackend`.
|
|
16
|
+
The HTTP adapter is contract-tested; hosted Jev accuracy has not been measured.
|
|
17
|
+
|
|
18
|
+
## Install and run
|
|
19
|
+
|
|
20
|
+
Python **3.8+**. The core requires Pandas and LLM2Jev; model providers are opt-in.
|
|
21
|
+
|
|
22
|
+
```bash
|
|
23
|
+
pip install jev2semopt
|
|
24
|
+
# Official hosted Jev (requires a TypeSafe API key):
|
|
25
|
+
pip install 'jev2semopt[jev]'
|
|
26
|
+
# Local providers:
|
|
27
|
+
pip install 'jev2semopt[transformers]'
|
|
28
|
+
# or: pip install 'jev2semopt[ollama]'
|
|
29
|
+
```
|
|
30
|
+
|
|
31
|
+
For a model-free example or development:
|
|
32
|
+
|
|
33
|
+
```bash
|
|
34
|
+
git clone https://github.com/Qingbolan/Jev2SemOpt.git
|
|
35
|
+
cd Jev2SemOpt
|
|
36
|
+
uv sync --group dev
|
|
37
|
+
uv run python examples/refund_pipeline.py
|
|
38
|
+
uv run python examples/decorated_decision.py
|
|
39
|
+
```
|
|
40
|
+
|
|
41
|
+
These examples use synthetic scores and require no model or API key. Production
|
|
42
|
+
and development dependencies resolve from PyPI. See [release verification](docs/releasing.md).
|
|
43
|
+
|
|
44
|
+
## A refund pipeline
|
|
45
|
+
|
|
46
|
+
Configure execution explicitly. The application owns the runtime and closes it;
|
|
47
|
+
Jev2SemOpt only borrows it. The following requires compatible local model weights
|
|
48
|
+
and a model-appropriate LLM2Jev encoder/label configuration; it is an API example,
|
|
49
|
+
not a validated inference configuration.
|
|
50
|
+
|
|
51
|
+
```python
|
|
52
|
+
import pandas as pd
|
|
53
|
+
from llm2jev import LLM2Jev, TransformersRuntime
|
|
54
|
+
from jev2semopt import LLM2JevBackend, SemEngine, Choice
|
|
55
|
+
|
|
56
|
+
tickets = pd.DataFrame({
|
|
57
|
+
"id": [101, 102],
|
|
58
|
+
"text": ["Please refund my order.", "Where is my parcel?"],
|
|
59
|
+
})
|
|
60
|
+
|
|
61
|
+
with TransformersRuntime("/path/to/local/model", device="cpu") as runtime:
|
|
62
|
+
engine = SemEngine(LLM2JevBackend(
|
|
63
|
+
LLM2Jev(runtime=runtime, model_identity=runtime.identity),
|
|
64
|
+
model=runtime.identity.name,
|
|
65
|
+
))
|
|
66
|
+
refunds = engine.sem_filter(
|
|
67
|
+
tickets, "Does text explicitly request a refund?",
|
|
68
|
+
columns=["text"], threshold=0.7, probability_column="refund_support",
|
|
69
|
+
)
|
|
70
|
+
routed = engine.sem_map(
|
|
71
|
+
refunds,
|
|
72
|
+
Choice(instructions="Which team should handle text?", criteria={
|
|
73
|
+
"billing": "Payments, invoices, or refunds",
|
|
74
|
+
"delivery": "Shipping, tracking, or missing parcels",
|
|
75
|
+
"other": "Requests outside billing and delivery",
|
|
76
|
+
}),
|
|
77
|
+
columns=["text"], output="queue",
|
|
78
|
+
)
|
|
79
|
+
counts = routed.groupby("queue").size()
|
|
80
|
+
```
|
|
81
|
+
|
|
82
|
+
Only `text` enters the decision state. IDs remain available in the output. Column
|
|
83
|
+
names in instructions refer to keys in that state; there is **no `{column}` string
|
|
84
|
+
interpolation**. Thresholds require validation on your own labeled workload.
|
|
85
|
+
|
|
86
|
+
## Operators and boundaries
|
|
87
|
+
|
|
88
|
+
Official hosted Jev is also supported through `JevBackend`, using a caller-owned
|
|
89
|
+
HTTP client and TypeSafe API key. See the [official API integration](docs/official-jev.md)
|
|
90
|
+
for setup and verification limits. An OpenRouter key does not authenticate TypeSafe.
|
|
91
|
+
|
|
92
|
+
| Operator | Jev decision | Output and scope |
|
|
93
|
+
| --- | --- | --- |
|
|
94
|
+
| `sem_filter(frame, instructions, ...)` | `Noul` | Rows with support **≥ threshold**, original order and index |
|
|
95
|
+
| `sem_map(frame, Choice(...), output=...)` | `Choice` | All rows plus a chosen label from supplied alternatives |
|
|
96
|
+
| `sem_score(frame, Score(...), ...)` | `Score` | All rows plus expected ordinal rubric level |
|
|
97
|
+
| `sem_topk(frame, Score(...), k=...)` | `Score` | Largest expected levels; stable source-order ties |
|
|
98
|
+
| `sem_join(left, right, instructions, ...)` | `Noul` | Inner join over candidate pairs; namespaced source fields and positions |
|
|
99
|
+
|
|
100
|
+
LOTUS provides a broader semantic operator model, including generated projections,
|
|
101
|
+
extraction, aggregation, and comparator-based ranking. Jev2SemOpt deliberately
|
|
102
|
+
restricts mappings to finite alternatives and ranks by an explicit ordinal rubric.
|
|
103
|
+
It is not a drop-in LOTUS replacement. Free-text extraction, summaries, vector
|
|
104
|
+
search, learned cascades, SQL planning, asynchronous execution, and distributed
|
|
105
|
+
execution are not implemented. Count/group/sum the typed outputs with Pandas;
|
|
106
|
+
there is no misleading `sem_agg` alias for a generative summary.
|
|
107
|
+
|
|
108
|
+
```python
|
|
109
|
+
from jev2semopt import Score
|
|
110
|
+
|
|
111
|
+
ranked = engine.sem_topk(
|
|
112
|
+
tickets,
|
|
113
|
+
Score(instructions="How urgent is text?", criteria=[
|
|
114
|
+
"Routine request", "Time-sensitive issue", "Immediate safety or service emergency",
|
|
115
|
+
]),
|
|
116
|
+
columns=["text"], k=10, output="urgency",
|
|
117
|
+
)
|
|
118
|
+
|
|
119
|
+
matches = engine.sem_join(
|
|
120
|
+
tickets, policies,
|
|
121
|
+
"Does left.text describe a case covered by right.policy?",
|
|
122
|
+
left_columns=["text"], right_columns=["policy"],
|
|
123
|
+
candidates=[(0, 1), (1, 0)], # row POSITIONS, not index labels
|
|
124
|
+
threshold=0.8,
|
|
125
|
+
)
|
|
126
|
+
```
|
|
127
|
+
|
|
128
|
+
The join output includes `left.<column>`, `right.<column>`, `_left_position`,
|
|
129
|
+
`_right_position`, and `_probability`. Without candidates it evaluates every pair,
|
|
130
|
+
subject to a default 100,000-pair limit. A shortlist can reduce work but can also
|
|
131
|
+
exclude true matches; the caller owns its recall. See [API contracts](docs/api.md).
|
|
132
|
+
|
|
133
|
+
## Python-native integration
|
|
134
|
+
|
|
135
|
+
The Pandas accessor is opt-in and uses Pandas' registration decorator. It forwards
|
|
136
|
+
to the same engine implementation and does not install global model settings:
|
|
137
|
+
|
|
138
|
+
```python
|
|
139
|
+
import jev2semopt.pandas
|
|
140
|
+
|
|
141
|
+
refunds = tickets.jev.sem_filter(
|
|
142
|
+
engine, "Does text request a refund?", columns=["text"], threshold=0.7,
|
|
143
|
+
)
|
|
144
|
+
```
|
|
145
|
+
|
|
146
|
+
Use `@decision` when application code already builds the state for one decision:
|
|
147
|
+
|
|
148
|
+
```python
|
|
149
|
+
from jev2semopt import Noul, decision
|
|
150
|
+
|
|
151
|
+
@decision(engine, question=Noul(instructions="Does text explicitly request a refund?"))
|
|
152
|
+
def refund_requested(text):
|
|
153
|
+
return {"text": text}
|
|
154
|
+
|
|
155
|
+
answer = refund_requested("Please refund my order.")
|
|
156
|
+
print(answer.noul)
|
|
157
|
+
```
|
|
158
|
+
|
|
159
|
+
The decorator binds once, preserves function metadata with `functools.wraps`, and
|
|
160
|
+
evaluates new state on each call. It does not cache results across calls. Decorated
|
|
161
|
+
functions must be synchronous JSON-state builders and now return typed answers.
|
|
162
|
+
|
|
163
|
+
## Measured results
|
|
164
|
+
|
|
165
|
+
On **50 balanced SciFact records**, the same GPT-4o-mini scored **31/50 with LOTUS**
|
|
166
|
+
and **32/50 with Jev-style / LLM2Jev**. The one-record difference does not establish
|
|
167
|
+
an accuracy improvement: the paired 95% interval spans −8 to +12 percentage points.
|
|
168
|
+
Jev-style improves precision but lowers recall and F1 in this run.
|
|
169
|
+
|
|
170
|
+

|
|
171
|
+
|
|
172
|
+
On **400 local Qwen2.5-0.5B candidate pairs**, Jev-style filtering was 1.97× faster,
|
|
173
|
+
but both filters had roughly 4% precision. Three-level Jev-style scoring was 2.70×
|
|
174
|
+
slower than LOTUS scoring and reduced ranking quality. BM25 had the highest nDCG.
|
|
175
|
+
|
|
176
|
+

|
|
177
|
+
|
|
178
|
+
These are **official SciFact dataset subsets with adapted protocols**, not full
|
|
179
|
+
LOTUS paper reproduction or measurements of TypeSafe's hosted Jev model. Unjudged
|
|
180
|
+
documents count as negatives under the qrel convention. Prompts differ between
|
|
181
|
+
operators; these experiments do not isolate probability assembly as the cause.
|
|
182
|
+
[Sampling, confusion matrices, costs, raw observations, and reproduction](https://github.com/Qingbolan/Jev2SemOpt/blob/v0.1.0/benchmarks/README.md).
|
|
183
|
+
|
|
184
|
+
## Execution cost and score meaning
|
|
185
|
+
|
|
186
|
+
`SemEngine(backend, deduplicate=True)` reuses identical selected JSON state **within
|
|
187
|
+
one operation**. This is opt-in and assumes the backend is deterministic and has no
|
|
188
|
+
per-call side effects. There is no global cache and no stale reuse across operations.
|
|
189
|
+
Question binding avoids recompilation; it is not a KV cache or a batched model call.
|
|
190
|
+
|
|
191
|
+
For `N` rows, filtering requires `N` one-candidate evaluations; mapping with `C`
|
|
192
|
+
choices requires `N × C` binary candidates; scoring with `R` rubric levels requires
|
|
193
|
+
`N × R`. An exhaustive join needs `L × R` pair evaluations. Duplicate reuse reduces
|
|
194
|
+
these counts to unique selected states. Calls are sequential. Join candidates and
|
|
195
|
+
results are materialized in memory; this version targets bounded in-memory tables.
|
|
196
|
+
|
|
197
|
+
No end-to-end speedup, calibrated correctness, or equivalence to LOTUS quality is
|
|
198
|
+
claimed. `Noul` is label-conditioned support; `Score` is an expected equally spaced
|
|
199
|
+
rubric index. These are decision signals, not probabilities that the answer is right.
|
|
200
|
+
LLM2Jev's Transformers adapter reads next-token logits; its Ollama adapter requests
|
|
201
|
+
one token to obtain exact binary logprobs. Jev2SemOpt never parses generated prose.
|
|
202
|
+
See [evaluation protocol](docs/evaluation.md).
|
|
203
|
+
|
|
204
|
+
## Architecture and development
|
|
205
|
+
|
|
206
|
+
```text
|
|
207
|
+
DataFrame API / @decision
|
|
208
|
+
↓
|
|
209
|
+
SemEngine — positional relational semantics
|
|
210
|
+
↓
|
|
211
|
+
EvaluationSession — one rule, detached state, operation-local reuse
|
|
212
|
+
↓
|
|
213
|
+
DecisionBackend.bind → BoundDecision.evaluate → typed Answer
|
|
214
|
+
↓
|
|
215
|
+
├─ LLM2JevBackend → public LLM2Jev API → caller-owned runtime
|
|
216
|
+
└─ JevBackend → TypeSafe HTTP API → caller-owned HTTP client
|
|
217
|
+
```
|
|
218
|
+
|
|
219
|
+
The engine depends on a backend protocol, not Ollama or Transformers. Models,
|
|
220
|
+
prompts, device configuration, binary labels, and runtime lifecycle stay in
|
|
221
|
+
LLM2Jev for local execution; hosted execution uses the supplied HTTP client. There is no new resource lifecycle to duplicate in the table layer.
|
|
222
|
+
|
|
223
|
+
```text
|
|
224
|
+
src/jev2semopt/
|
|
225
|
+
├── contracts.py Backend and bound-decision protocols
|
|
226
|
+
├── execution.py State isolation, answer checks, safe failure boundary
|
|
227
|
+
├── engine.py Filter/map/score/top-k/join semantics
|
|
228
|
+
├── table.py Dataframe schema and state projection
|
|
229
|
+
├── decorators.py Function-to-decision binding
|
|
230
|
+
├── pandas.py Opt-in accessor registration
|
|
231
|
+
└── adapters/ LLM2Jev service and official Jev HTTP integration
|
|
232
|
+
```
|
|
233
|
+
|
|
234
|
+
Run the checks in [CONTRIBUTING.md](CONTRIBUTING.md). Architectural decisions,
|
|
235
|
+
privacy constraints, and delivery status are documented in
|
|
236
|
+
[architecture](docs/architecture.md), [privacy](docs/privacy.md), and
|
|
237
|
+
[implementation plan](docs/implementation-plan.md). Attribution is recorded in
|
|
238
|
+
[NOTICE](NOTICE). Licensed under [MIT](LICENSE); [dependency and benchmark attribution](docs/licenses.md).
|
|
239
|
+
|
|
240
|
+
[Local verification record](docs/verification.md): 50 deterministic tests passed
|
|
241
|
+
on Python 3.8, 3.12, and 3.14. Real-model observations are recorded separately in
|
|
242
|
+
the [benchmark report](benchmarks/README.md).
|