iobrx 0.3.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- iobrx-0.3.0/LICENSE +21 -0
- iobrx-0.3.0/PKG-INFO +621 -0
- iobrx-0.3.0/README.md +577 -0
- iobrx-0.3.0/pyproject.toml +81 -0
- iobrx-0.3.0/rust/Cargo.lock +382 -0
- iobrx-0.3.0/rust/Cargo.toml +24 -0
- iobrx-0.3.0/rust/argsort_wrapper.cpp +20 -0
- iobrx-0.3.0/rust/build.rs +25 -0
- iobrx-0.3.0/rust/src/lib.rs +4847 -0
- iobrx-0.3.0/rust/vendor/LICENSE.libsvm +30 -0
- iobrx-0.3.0/rust/vendor/LICENSE.scikit-learn +29 -0
- iobrx-0.3.0/rust/vendor/LICENSE.x86-simd-sort +202 -0
- iobrx-0.3.0/rust/vendor/THIRD_PARTY_NOTICES.md +32 -0
- iobrx-0.3.0/rust/vendor/sklearn/svm/src/libsvm/_svm_cython_blas_helpers.h +9 -0
- iobrx-0.3.0/rust/vendor/sklearn/svm/src/newrand/newrand.h +59 -0
- iobrx-0.3.0/rust/vendor/svm.cpp +3187 -0
- iobrx-0.3.0/rust/vendor/svm.h +176 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx2-32bit-half.hpp +556 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx2-32bit-qsort.hpp +647 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx2-64bit-qsort.hpp +667 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx2-emu-funcs.hpp +421 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx512-16bit-common.h +202 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx512-16bit-qsort.hpp +632 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx512-32bit-qsort.hpp +734 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx512-64bit-argsort.hpp +13 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx512-64bit-common.h +1322 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx512-64bit-qsort.hpp +12 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/avx512fp16-16bit-qsort.hpp +203 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/x86simdsort-static-incl.h +190 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-common-argsort.h +671 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-common-comparators.hpp +127 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-common-includes.h +115 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-common-keyvaluesort.hpp +725 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-common-qsort.h +722 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-custom-float.h +90 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-network-keyvaluesort.hpp +661 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-network-qsort.hpp +235 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-optimal-networks.hpp +328 -0
- iobrx-0.3.0/rust/vendor/x86-simd-sort/src/xss-pivot-selection.hpp +240 -0
- iobrx-0.3.0/rust/wrapper.cpp +137 -0
- iobrx-0.3.0/src/iobrx/__init__.py +2675 -0
- iobrx-0.3.0/src/iobrx/_backend.py +45 -0
- iobrx-0.3.0/src/iobrx/_fast/__init__.py +11 -0
- iobrx-0.3.0/src/iobrx/_fast/anno_eset_fast.py +312 -0
- iobrx-0.3.0/src/iobrx/_fast/batch_salmon_fast.py +414 -0
- iobrx-0.3.0/src/iobrx/_fast/batch_star_count_fast.py +294 -0
- iobrx-0.3.0/src/iobrx/_fast/bayesprism_fast.py +1611 -0
- iobrx-0.3.0/src/iobrx/_fast/bayesprism_gibbs_rust.py +283 -0
- iobrx-0.3.0/src/iobrx/_fast/cibersort_fast.py +191 -0
- iobrx-0.3.0/src/iobrx/_fast/count2tpm_fast.py +510 -0
- iobrx-0.3.0/src/iobrx/_fast/epic_fast.py +370 -0
- iobrx-0.3.0/src/iobrx/_fast/estimate_fast.py +152 -0
- iobrx-0.3.0/src/iobrx/_fast/fastq_qc_fast.py +317 -0
- iobrx-0.3.0/src/iobrx/_fast/hla_typing_fast.py +968 -0
- iobrx-0.3.0/src/iobrx/_fast/ips_fast.py +248 -0
- iobrx-0.3.0/src/iobrx/_fast/log2_eset_fast.py +260 -0
- iobrx-0.3.0/src/iobrx/_fast/lr_cal_fast.py +351 -0
- iobrx-0.3.0/src/iobrx/_fast/mcpcounter_fast.py +135 -0
- iobrx-0.3.0/src/iobrx/_fast/merge_salmon_fast.py +519 -0
- iobrx-0.3.0/src/iobrx/_fast/merge_star_count_fast.py +437 -0
- iobrx-0.3.0/src/iobrx/_fast/mouse2human_fast.py +368 -0
- iobrx-0.3.0/src/iobrx/_fast/nmf_fast.py +544 -0
- iobrx-0.3.0/src/iobrx/_fast/prepare_salmon_fast.py +209 -0
- iobrx-0.3.0/src/iobrx/_fast/quantiseq_fast.py +232 -0
- iobrx-0.3.0/src/iobrx/_fast/runall_fast.py +1478 -0
- iobrx-0.3.0/src/iobrx/_fast/sig_score_fast.py +583 -0
- iobrx-0.3.0/src/iobrx/_fast/sig_scores_fast.py +219 -0
- iobrx-0.3.0/src/iobrx/_fast/sig_ssgsea_fast.py +73 -0
- iobrx-0.3.0/src/iobrx/_fast/spechla_fast.py +1388 -0
- iobrx-0.3.0/src/iobrx/_fast/ssgsea_fast.py +240 -0
- iobrx-0.3.0/src/iobrx/_fast/tme_cluster_fast.py +233 -0
- iobrx-0.3.0/src/iobrx/_fast/tme_profile_fast.py +688 -0
- iobrx-0.3.0/src/iobrx/_fast/trust4_fast.py +1169 -0
- iobrx-0.3.0/src/iobrx/_run_state.py +90 -0
- iobrx-0.3.0/src/iobrx/_sites.py +72 -0
- iobrx-0.3.0/src/iobrx/_sorting.py +26 -0
- iobrx-0.3.0/src/iobrx/_testdata.py +127 -0
- iobrx-0.3.0/src/iobrx/_threads.py +55 -0
iobrx-0.3.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 iobrx contributors
|
|
4
|
+
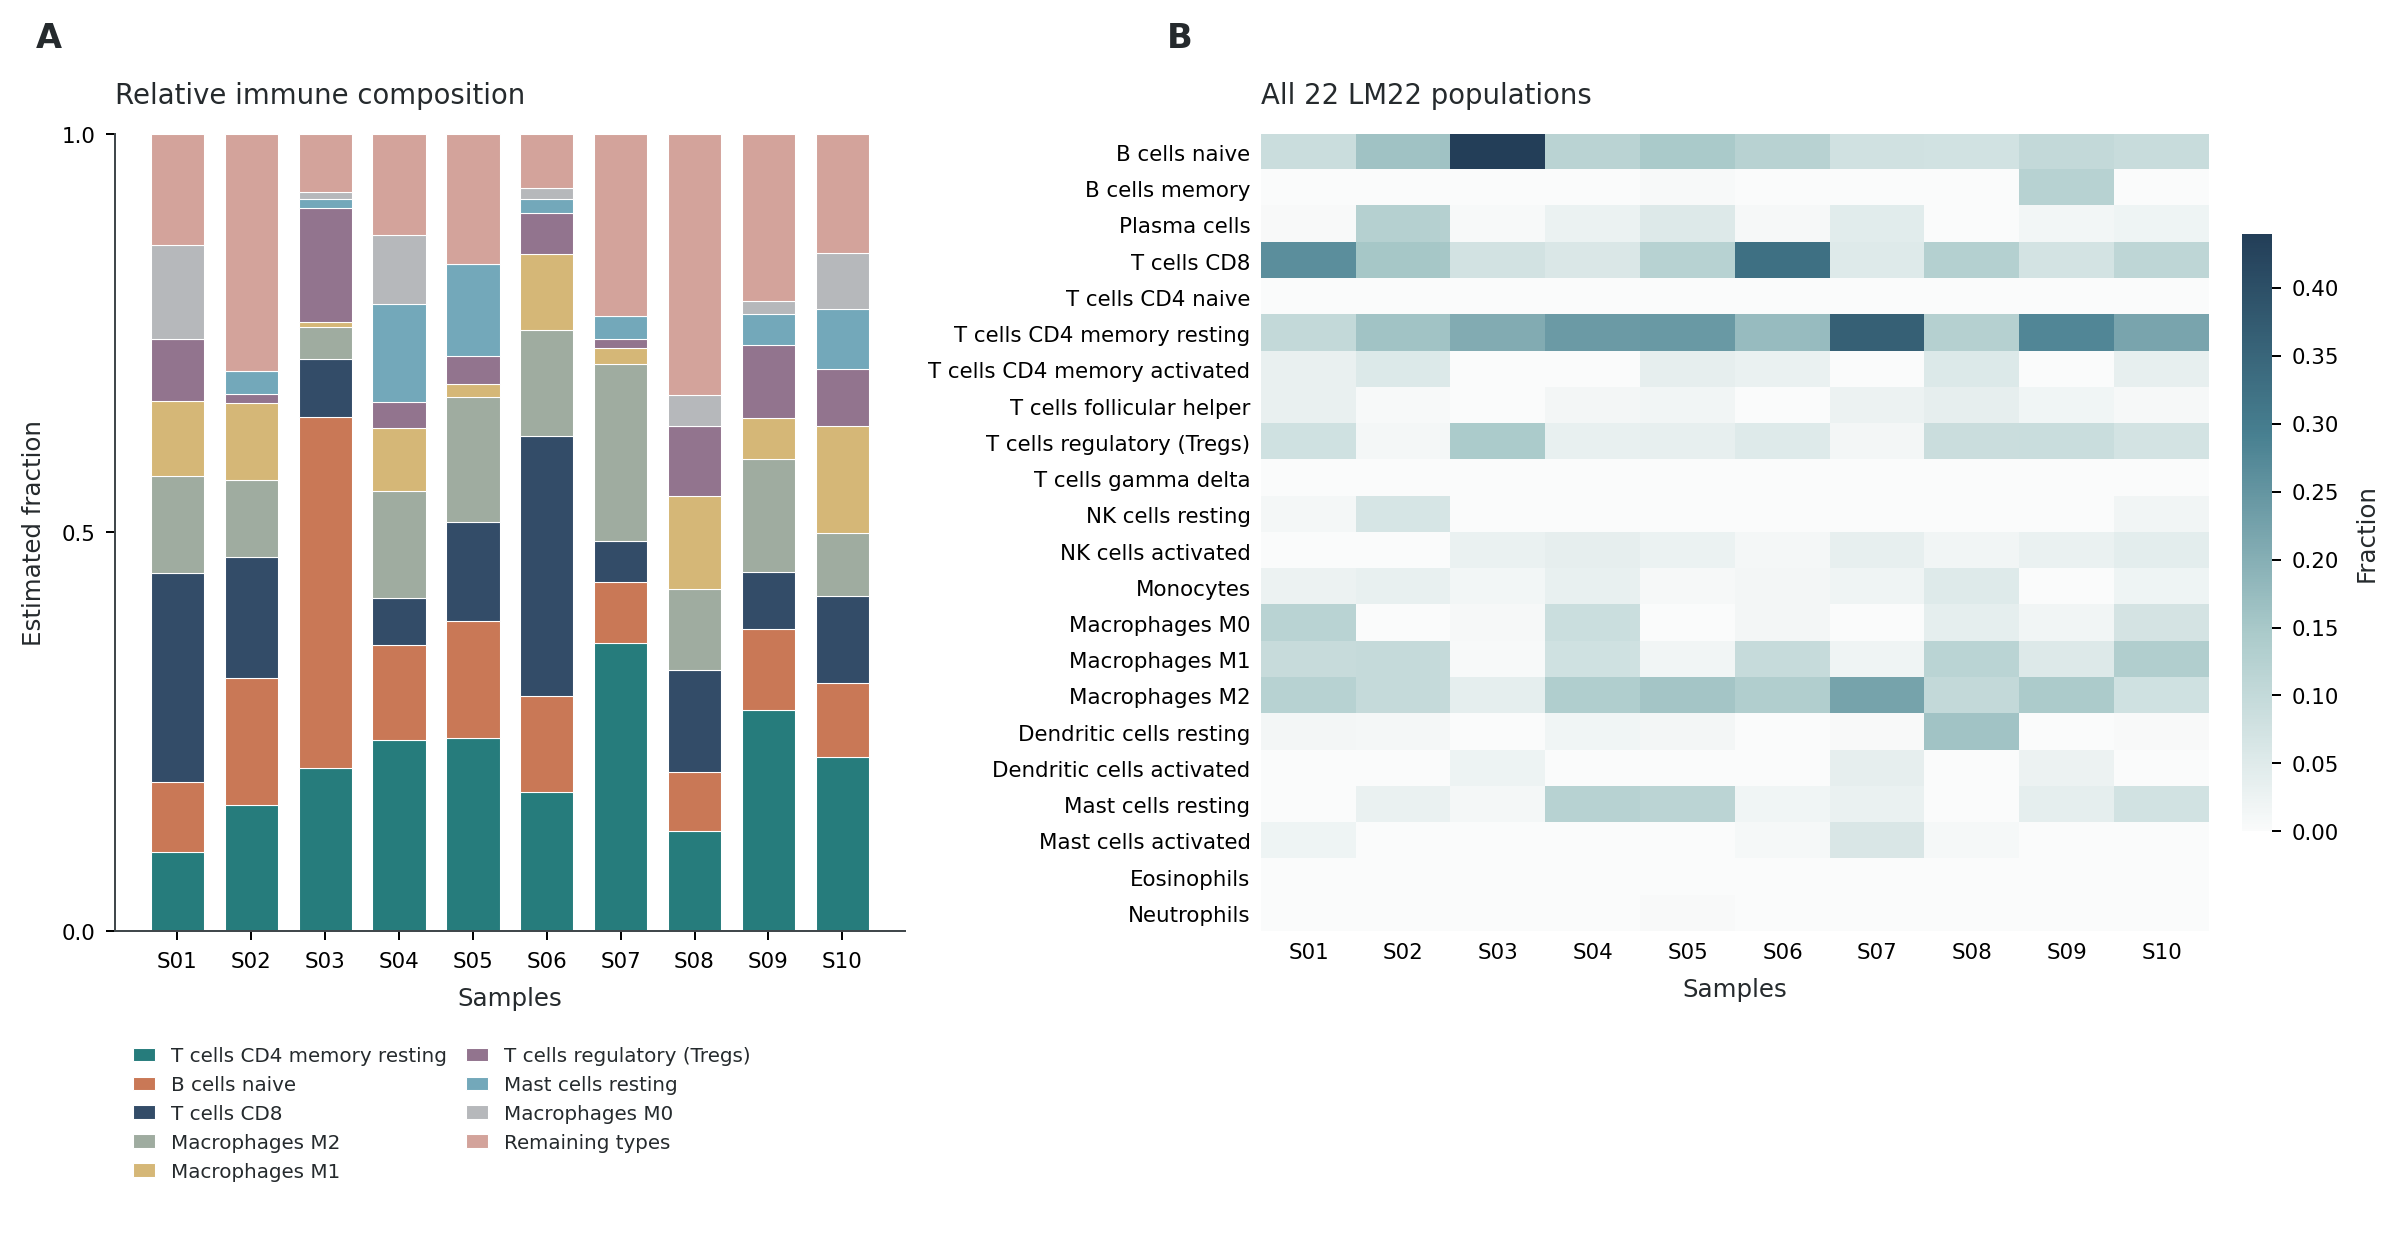
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
iobrx-0.3.0/PKG-INFO
ADDED
|
@@ -0,0 +1,621 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: iobrx
|
|
3
|
+
Version: 0.3.0
|
|
4
|
+
Classifier: Development Status :: 3 - Alpha
|
|
5
|
+
Classifier: Intended Audience :: Science/Research
|
|
6
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
7
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
8
|
+
Classifier: Programming Language :: Rust
|
|
9
|
+
Classifier: Topic :: Scientific/Engineering :: Bio-Informatics
|
|
10
|
+
Requires-Dist: iobrpy==0.2.1
|
|
11
|
+
Requires-Dist: numpy==2.2.6
|
|
12
|
+
Requires-Dist: pandas>=2.3,<3
|
|
13
|
+
Requires-Dist: scipy==1.16.3
|
|
14
|
+
Requires-Dist: scikit-learn==1.7.2
|
|
15
|
+
Requires-Dist: gseapy==1.3.1
|
|
16
|
+
Requires-Dist: joblib>=1.3
|
|
17
|
+
Requires-Dist: pyarrow>=20,<21
|
|
18
|
+
Requires-Dist: pyreadr>=0.5.6,<0.6
|
|
19
|
+
Requires-Dist: pytest>=7.0 ; extra == 'test'
|
|
20
|
+
Requires-Dist: matplotlib>=3.7 ; extra == 'tutorials'
|
|
21
|
+
Requires-Dist: nbformat>=5.9 ; extra == 'tutorials'
|
|
22
|
+
Requires-Dist: nbclient>=0.10 ; extra == 'tutorials'
|
|
23
|
+
Requires-Dist: ipykernel>=6 ; extra == 'tutorials'
|
|
24
|
+
Requires-Dist: jupyterlab>=4 ; extra == 'tutorials'
|
|
25
|
+
Provides-Extra: test
|
|
26
|
+
Provides-Extra: tutorials
|
|
27
|
+
License-File: LICENSE
|
|
28
|
+
License-File: rust/vendor/THIRD_PARTY_NOTICES.md
|
|
29
|
+
License-File: rust/vendor/LICENSE.libsvm
|
|
30
|
+
License-File: rust/vendor/LICENSE.scikit-learn
|
|
31
|
+
License-File: rust/vendor/LICENSE.x86-simd-sort
|
|
32
|
+
Summary: Accelerated IOBRpy workflows with a pandas API, Rust kernels and scoped numerical parity validation
|
|
33
|
+
Keywords: bioinformatics,deconvolution,cibersort,ssgsea,iobr,tumor-microenvironment
|
|
34
|
+
Author: iobrx contributors
|
|
35
|
+
License: MIT
|
|
36
|
+
Requires-Python: >=3.11
|
|
37
|
+
Description-Content-Type: text/markdown; charset=UTF-8; variant=GFM
|
|
38
|
+
Project-URL: Benchmarks, https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md
|
|
39
|
+
Project-URL: Changelog, https://github.com/LCGaoZzz/iobrx/blob/main/CHANGELOG.md
|
|
40
|
+
Project-URL: Homepage, https://github.com/LCGaoZzz/iobrx
|
|
41
|
+
Project-URL: Issues, https://github.com/LCGaoZzz/iobrx/issues
|
|
42
|
+
Project-URL: Repository, https://github.com/LCGaoZzz/iobrx
|
|
43
|
+
|
|
44
|
+
# iobrx
|
|
45
|
+
|
|
46
|
+
**Fast, faithful tumor microenvironment analysis with a pandas API.**
|
|
47
|
+
|
|
48
|
+
[](https://github.com/LCGaoZzz/iobrx/actions/workflows/ci.yml)
|
|
49
|
+
[](https://github.com/LCGaoZzz/iobrx/blob/main/CHANGELOG.md)
|
|
50
|
+
[](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/README.md)
|
|
51
|
+
[](https://github.com/LCGaoZzz/iobrx/blob/main/LICENSE)
|
|
52
|
+
|
|
53
|
+
English · [中文说明](https://github.com/LCGaoZzz/iobrx/blob/main/README.zh-CN.md) · [Tutorial gallery](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/README.md) · [CPU compatibility](https://github.com/LCGaoZzz/iobrx/blob/main/docs/PORTABILITY.md) · [Benchmarks](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)
|
|
54
|
+
|
|
55
|
+
**iobrx is an independently maintained acceleration and integration layer built
|
|
56
|
+
on the original [IOBRpy](https://github.com/IOBR/IOBRpy) toolkit.** It depends on
|
|
57
|
+
IOBRpy and reuses its reference resources, gene signatures and analysis semantics.
|
|
58
|
+
iobrx adds Rust kernels, parallel/vectorized execution, a pandas API, tested
|
|
59
|
+
tutorials and Omicos agent interfaces. Inputs and outputs are ordinary
|
|
60
|
+
DataFrames and files. Numerical parity is tested per method and fixture;
|
|
61
|
+
it is not a universal bit-exact guarantee for every new workflow, parameter or
|
|
62
|
+
input. See the explicit exceptions and [validation scope](docs/VALIDATION_0.3.md).
|
|
63
|
+
|
|
64
|
+
[Original IOBRpy repository](https://github.com/IOBR/IOBRpy) · [Official IOBRpy documentation](https://iobr.github.io/IOBRpy/)
|
|
65
|
+
|
|
66
|
+
**29 public APIs** — 27 workflow functions (plus the `deconvolute_quantiseq`
|
|
67
|
+
alias and the `load_official` data helper) covering the following IOBRpy workflow families:
|
|
68
|
+
immune deconvolution (CIBERSORT, BayesPrism, EPIC, quanTIseq, MCP-counter,
|
|
69
|
+
ESTIMATE), signature scoring (PCA / z-score / ssGSEA / integration), TPM
|
|
70
|
+
conversion and annotation, Immunophenoscore, ligand–receptor pairing, NMF and
|
|
71
|
+
TME clustering, the full `tme_profile` chain, RNA-seq file merging, and the
|
|
72
|
+
FASTQ→TME orchestration stages (fastp / salmon / STAR / TRUST4 / SpecHLA).
|
|
73
|
+
|
|
74
|
+
**Omicos:** the harness now exposes 27 typed analysis identifiers (the four signature modes are separate identifiers), including 16 new adapters. HLA and custom-reference BayesPrism remain direct-API capabilities. [Input contracts and limits](agent-harness/omicos/skills/iobrx/references/extended-workflows.md).
|
|
75
|
+
|
|
76
|
+
**Evidence scope:** R3–R6 timings below are imported campaign measurements. Some raw campaign scripts/logs are not archived here, so these numbers are not independently reproducible from this PR alone. New local validation separates numerical tests, stub-tool contracts and actual tutorial timings.
|
|
77
|
+
|
|
78
|
+
**New real-data evidence:** [FASTQ/BAM/HLA recipe, repeated timings and logs](benchmarks/real_tools/README.md)
|
|
79
|
+
and tutorials 24–28 use public sequencing reads and actual tools. Four-thread
|
|
80
|
+
Salmon varies between repeated original runs as well as across wrappers;
|
|
81
|
+
HLA extraction was slower in this small fixture. These results do not support
|
|
82
|
+
a claim that every workflow is faster or universally byte-identical.
|
|
83
|
+
|
|
84
|
+
### What's new in 0.3.0
|
|
85
|
+
|
|
86
|
+
- **18 additional workflow APIs** (campaign rounds R3–R6): `nmf`,
|
|
87
|
+
`merge_salmon`, `merge_star_count`, `prepare_salmon`, `log2_eset`, `ips`,
|
|
88
|
+
`mouse2human`, `lr_cal`, `tme_cluster`, `bayesprism`, `tme_profile`,
|
|
89
|
+
`fastq_qc`, `batch_salmon`, `batch_star_count`, `trust4`, `runall`,
|
|
90
|
+
`spechla`, `hla_typing`, plus a 30.3× glue optimization inside
|
|
91
|
+
`calculate_sig_score`.
|
|
92
|
+
- **Standalone HLA read extraction**: `extract_hla_read` extracts reads from
|
|
93
|
+
one BAM/CRAM using prepared tools, with dependency auto-installation off by default.
|
|
94
|
+
- **4 new Rust kernels**: `lr_gene_valid_mask` (LR_cal gene filter),
|
|
95
|
+
`tme_kmeans` (k-means + KL index), `merge_salmon_parse` (quant.sf reader),
|
|
96
|
+
`bp_gibbs` (BayesPrism Gibbs sampler reproducing numpy's full RNG chain
|
|
97
|
+
bit-for-bit).
|
|
98
|
+
- **`tme_profile` end-to-end 10.59×** vs the original CLI on the frozen STAD
|
|
99
|
+
fixture — the endpoint of a measured bottleneck-shift chain
|
|
100
|
+
1.12× → 8.44× → 10.59× ([BENCHMARKS.md Part II](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)).
|
|
101
|
+
- **Campaign-reported benchmark (R6)**: 14 core candidates re-measured under one
|
|
102
|
+
unified cold-start protocol against the unmodified original CLI; every
|
|
103
|
+
parity contract reported PASS. The original submission recorded 188 default tests; current checks and limitations are tracked in [validation](docs/VALIDATION_0.3.md).
|
|
104
|
+
|
|
105
|
+
|
|
106
|
+
|
|
107
|
+
## Additional executed tutorials
|
|
108
|
+
|
|
109
|
+
Eleven new notebooks cover IPS, LR scores, NMF, TME clustering, conditional
|
|
110
|
+
log transforms, mouse mapping, Salmon/STAR merging, Salmon preparation,
|
|
111
|
+
`tme_profile` and BayesPrism. Each includes actual outputs and an embedded
|
|
112
|
+
figure with two reviewed revisions. The table reports one final notebook API
|
|
113
|
+
call on the local WSL/Omicos interpreter, two requested threads, excluding
|
|
114
|
+
input preparation. These are small tutorial observations, not speedup claims.
|
|
115
|
+
NMF's BLAS parallelism is not governed solely by the requested thread count.
|
|
116
|
+
The BayesPrism example uses a short demo chain; file-merging examples are synthetic.
|
|
117
|
+
|
|
118
|
+
| Tutorial | Input shape | API call time |
|
|
119
|
+
| --- | --- | --- |
|
|
120
|
+
| [13_ips](tutorials/13_ips.ipynb) | 48058 × 4 | 0.016 s |
|
|
121
|
+
| [14_lr_cal](tutorials/14_lr_cal.ipynb) | 48058 × 4 | 0.143 s |
|
|
122
|
+
| [15_nmf](tutorials/15_nmf.ipynb) | 10 × 22 | 0.465 s |
|
|
123
|
+
| [16_tme_cluster](tutorials/16_tme_cluster.ipynb) | 10 × 22 | 0.044 s |
|
|
124
|
+
| [17_log2_eset](tutorials/17_log2_eset.ipynb) | 48058 × 4 | 0.235 s |
|
|
125
|
+
| [18_mouse2human](tutorials/18_mouse2human.ipynb) | 4 × 3 | 0.020 s |
|
|
126
|
+
| [19_merge_salmon](tutorials/19_merge_salmon.ipynb) | 3 × 3 | 0.076 s |
|
|
127
|
+
| [20_prepare_salmon](tutorials/20_prepare_salmon.ipynb) | 3 × 4 | 0.014 s |
|
|
128
|
+
| [21_merge_star_count](tutorials/21_merge_star_count.ipynb) | 3 × 3 | 0.073 s |
|
|
129
|
+
| [22_tme_profile](tutorials/22_tme_profile.ipynb) | 48058 × 2 | 4.828 s |
|
|
130
|
+
| [23_bayesprism](tutorials/23_bayesprism.ipynb) | 128 × 3 | 0.351 s |
|
|
131
|
+
|
|
132
|
+
## Install
|
|
133
|
+
|
|
134
|
+
Validated target: **Python 3.11, Linux x86-64 / WSL2**. Use an isolated
|
|
135
|
+
environment. Versioned wheels, source archives, checksums and the container
|
|
136
|
+
digest are delivered through the [v0.3.0 release](https://github.com/LCGaoZzz/iobrx/releases/tag/v0.3.0).
|
|
137
|
+
After downloading its CPython 3.11 wheel:
|
|
138
|
+
|
|
139
|
+
```bash
|
|
140
|
+
python3.11 -m venv .venv
|
|
141
|
+
source .venv/bin/activate
|
|
142
|
+
python -m pip install --only-binary=:all: ./iobrx-0.3.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
|
|
143
|
+
python -c "import iobrx; print(iobrx.backend_info())"
|
|
144
|
+
```
|
|
145
|
+
|
|
146
|
+
This wheel path does not require Cargo or a C++ compiler. When **0.3.0 appears
|
|
147
|
+
on [PyPI](https://pypi.org/project/iobrx/)**, the index-based equivalent is:
|
|
148
|
+
|
|
149
|
+
```bash
|
|
150
|
+
python -m pip install --only-binary=:all: iobrx==0.3.0
|
|
151
|
+
# Tsinghua mirrors PyPI asynchronously; wait until the same version is listed.
|
|
152
|
+
python -m pip install --only-binary=:all: -i https://pypi.tuna.tsinghua.edu.cn/simple iobrx==0.3.0
|
|
153
|
+
```
|
|
154
|
+
|
|
155
|
+
PyPI publication and mirror synchronization are independent of GitHub assets.
|
|
156
|
+
If an index has not synchronized, install the release wheel directly.
|
|
157
|
+
|
|
158
|
+
For source development, install Cargo and a C++17 compiler:
|
|
159
|
+
|
|
160
|
+
```bash
|
|
161
|
+
git clone https://github.com/LCGaoZzz/iobrx.git
|
|
162
|
+
cd iobrx
|
|
163
|
+
python -m pip install -c tests/constraints-validated.txt ".[tutorials,test]"
|
|
164
|
+
python -c "import iobrx; print(iobrx.backend_info())"
|
|
165
|
+
python -m jupyterlab tutorials
|
|
166
|
+
```
|
|
167
|
+
|
|
168
|
+
Use the same interpreter as the Jupyter kernel. In an existing Omicos
|
|
169
|
+
environment, first check dependency compatibility; use an isolated environment
|
|
170
|
+
when the required numerical versions conflict. `pip install` from this source
|
|
171
|
+
builds the extension; it is not an installation without compilation.
|
|
172
|
+
|
|
173
|
+
The core-analysis container uses `ghcr.io/lcgaozzz/iobrx:0.3.0`; for immutable
|
|
174
|
+
execution use the digest in the release's `container-digest.txt`.
|
|
175
|
+
Alignment and HLA binaries require the separate external-tool environment.
|
|
176
|
+
See [release notes](docs/releases/0.3.0.md).
|
|
177
|
+
|
|
178
|
+
**Why the dependency pins** (details and measurements in
|
|
179
|
+
[BENCHMARKS.md §I.7](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)):
|
|
180
|
+
|
|
181
|
+
| Pin | Reason |
|
|
182
|
+
| --- | --- |
|
|
183
|
+
| `iobrpy==0.2.1` | Supplies reference resources and the original-workflow fallback. Current package and parity tests use this exact PyPI version; the earlier campaign also compared with 0.2.0. |
|
|
184
|
+
| `numpy==2.2.6` | Uses the validated reduction and sorting implementation. The campaign observed different rounding and CIBERSORT support sets with newer NumPy; broader version ranges are not promised. |
|
|
185
|
+
| `scikit-learn==1.7.2` | Matches the vendored `svm.cpp` and the tested reference solver. Newer sklearn versions require separate numerical validation. |
|
|
186
|
+
| `scipy==1.16.3`, `gseapy==1.3.1` | Keeps optimization and enrichment calculations on the validated implementations. |
|
|
187
|
+
|
|
188
|
+
These are the exact requirements in [package metadata](pyproject.toml), not
|
|
189
|
+
minimum versions. Remaining dependency bounds and the complete test environment
|
|
190
|
+
are recorded in [the validation constraints](tests/constraints-validated.txt).
|
|
191
|
+
|
|
192
|
+
**CPU compatibility and operating-system packaging are separate.** Upstream
|
|
193
|
+
IOBRpy's binary distribution limits straightforward installation on other
|
|
194
|
+
Python/platform combinations. Windows users can use WSL2; macOS, ARM and
|
|
195
|
+
native Windows are not claimed as validated full-stack targets. See the
|
|
196
|
+
[compatibility notes](https://github.com/LCGaoZzz/iobrx/blob/main/docs/PORTABILITY.md) for fallback behavior and limits.
|
|
197
|
+
|
|
198
|
+
## Quick start
|
|
199
|
+
|
|
200
|
+
```python
|
|
201
|
+
import numpy as np
|
|
202
|
+
import pandas as pd
|
|
203
|
+
import iobrx
|
|
204
|
+
|
|
205
|
+
iobrx.set_threads(8)
|
|
206
|
+
counts = pd.read_parquet("tutorials/data/eset_stad.parquet") # genes × samples
|
|
207
|
+
tpm = iobrx.count2tpm(counts, check_data=True, remove_version=True)
|
|
208
|
+
log_expression = np.log2(tpm + 1)
|
|
209
|
+
|
|
210
|
+
# Deconvolution and scores (linear TPM for the RNA-seq deconvolution examples)
|
|
211
|
+
cib = iobrx.cibersort(tpm, perm=100, QN=False) # Rust NuSVR core
|
|
212
|
+
epic = iobrx.epic(tpm)["cellFractions"]
|
|
213
|
+
qnt = iobrx.quantiseq(tpm, tumor=True, rmgenes="default")
|
|
214
|
+
scores = iobrx.calculate_sig_score(
|
|
215
|
+
log_expression, "signature_collection", method="integration"
|
|
216
|
+
)
|
|
217
|
+
|
|
218
|
+
# 0.3.0 ports
|
|
219
|
+
lr = iobrx.lr_cal(eset="tpm_symbol.csv", output_file="lr.csv",
|
|
220
|
+
data_type="tpm", id_type="symbol", cancer_type="pancan")
|
|
221
|
+
ips = iobrx.ips(eset="tpm_symbol.csv", output_file="ips.csv")
|
|
222
|
+
clusters = iobrx.tme_cluster(df=pd.read_csv("tme_transposed.csv"), id="sample")
|
|
223
|
+
iobrx.bayesprism(bulk="bulk_counts.csv", out_dir="bp_out", n_threads=8)
|
|
224
|
+
# add backend="rust" for the bit-exact Rust Gibbs kernel
|
|
225
|
+
|
|
226
|
+
# The whole TME profiling chain in one process (10.59× vs the original CLI)
|
|
227
|
+
iobrx.tme_profile(input="TPM.csv", output="tme_out", threads=16)
|
|
228
|
+
|
|
229
|
+
# FASTQ → TME orchestration (external tools must be on PATH — see below)
|
|
230
|
+
iobrx.runall(mode="salmon", outdir="run_out", fastq="raw_fastq_dir",
|
|
231
|
+
threads=16, resume=True,
|
|
232
|
+
unknown=["--index", "references/salmon"])
|
|
233
|
+
```
|
|
234
|
+
|
|
235
|
+
`runall(resume=True)` reuses a table only after its producing step succeeded
|
|
236
|
+
and its recorded output hash matches. A failed or interrupted table write is
|
|
237
|
+
retried; successful upstream steps can still be reused. State schema 2 adds
|
|
238
|
+
these per-step records: pre-schema-2 run directories require a new `outdir`.
|
|
239
|
+
Existing schema 2 records remain compatible. Changed inputs, parameters,
|
|
240
|
+
references or recorded calculation products require a new directory; unrelated
|
|
241
|
+
notes and figures can be added, edited or removed without blocking resume.
|
|
242
|
+
An uncatchable kill can leave unverified calculation products, which are not
|
|
243
|
+
treated as completed work.
|
|
244
|
+
|
|
245
|
+
Open [the complete workflow notebook](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/12_complete_workflow.ipynb)
|
|
246
|
+
for input checks, interpretation, plots, and per-stage timers on the public
|
|
247
|
+
example data (no download needed after installation). The four standalone
|
|
248
|
+
signature tutorials use the public IMvigor210 demonstration panel:
|
|
249
|
+
872 features × 348 samples.
|
|
250
|
+
|
|
251
|
+
## The 29 APIs at a glance
|
|
252
|
+
|
|
253
|
+
| API | One-liner |
|
|
254
|
+
| --- | --- |
|
|
255
|
+
| `cibersort` | CIBERSORT LM22 immune deconvolution (NuSVR) — Rust core, seeded permutations |
|
|
256
|
+
| `calculate_sig_score` | Per-sample signature scores: `pca` / `zscore` / `ssgsea` / `integration` |
|
|
257
|
+
| `count2tpm` | Raw count matrix → TPM (vectorized, bit-identical) |
|
|
258
|
+
| `quantiseq` | quanTIseq TIL10 deconvolution with a memoized HGNC alias map |
|
|
259
|
+
| `deconvolute_quantiseq` | Alias kept for the original function name |
|
|
260
|
+
| `epic` | EPIC cell fractions and mRNA proportions |
|
|
261
|
+
| `mcpcounter` | MCP-counter population abundance scores |
|
|
262
|
+
| `estimate_score` | ESTIMATE stromal / immune scores and tumor purity |
|
|
263
|
+
| `anno_eset` | Aggregate probes / Ensembl ids to gene symbols |
|
|
264
|
+
| `bayesprism` | BayesPrism deconvolution — python-fast default, opt-in Rust Gibbs, determinism-fixed |
|
|
265
|
+
| `tme_profile` | The whole TME profiling chain (sig scores + 6 deconvolutions + LR_cal) in one process |
|
|
266
|
+
| `nmf` | NMF clustering with silhouette-based k selection |
|
|
267
|
+
| `tme_cluster` | TME k-means clustering with KL-index best-k selection (Rust core) |
|
|
268
|
+
| `lr_cal` | Ligand–receptor pair expression matrix, min of log2 TPM (Rust gene-filter core) |
|
|
269
|
+
| `ips` | Immunophenoscore (Charoentong 2017 four-block design) |
|
|
270
|
+
| `merge_salmon` | Merge Salmon `quant.sf` dirs → TPM / count matrices (Rust parse engine) |
|
|
271
|
+
| `merge_star_count` | Merge STAR `ReadsPerGene.out.tab` files → one count matrix |
|
|
272
|
+
| `prepare_salmon` | Salmon TPM → deduplicated symbol / ENSG / ENST matrix |
|
|
273
|
+
| `log2_eset` | `log2(x+1)` on a genes × samples matrix |
|
|
274
|
+
| `mouse2human` | Mouse → human gene-symbol conversion |
|
|
275
|
+
| `fastq_qc` | FASTQ QC with fastp + MultiQC (external-tool stage) |
|
|
276
|
+
| `batch_salmon` | Batch Salmon quantification over paired-end FASTQs |
|
|
277
|
+
| `batch_star_count` | Batch STAR two-pass alignment + GeneCounts |
|
|
278
|
+
| `trust4` | TRUST4 TCR/BCR reconstruction + accelerated immune post-processing |
|
|
279
|
+
| `spechla` | SpecHLA full-resolution HLA typing for one sample |
|
|
280
|
+
| `extract_hla_read` | Extract HLA-related FASTQs from one BAM/CRAM without running typing |
|
|
281
|
+
| `hla_typing` | Batch HLA typing from a directory of BAM files |
|
|
282
|
+
| `runall` | End-to-end FASTQ → TME orchestrator (salmon / star chains) |
|
|
283
|
+
| `load_official` | Resolve / download the public IOBR example data |
|
|
284
|
+
|
|
285
|
+
## Three routes, one choice — how every API is accelerated
|
|
286
|
+
|
|
287
|
+
Each ported module was evaluated along three routes: keep calling the
|
|
288
|
+
**original iobrpy CLI**, write a **pure-Python fast path**, or build a
|
|
289
|
+
**Rust kernel**. The final choice is whatever passed the bit-exact contract
|
|
290
|
+
at the best measured wall time. Speedups for the 19 ported APIs are the
|
|
291
|
+
**R6 formal blind benchmark** (unified cold-start protocol, fresh subprocess
|
|
292
|
+
per run, interleaved arms, medians — `research/bench_r6/results.json`,
|
|
293
|
+
[BENCHMARKS.md §II.6](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)); orchestration-stage ratios are the
|
|
294
|
+
R5 real-data runs ([§II.8](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)); pre-port modules carry their
|
|
295
|
+
official-gate numbers ([Part I](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)).
|
|
296
|
+
|
|
297
|
+
| Module | Original route | Pure-Python route | Rust route | Final choice | Speedup | Parity contract |
|
|
298
|
+
| --- | --- | --- | --- | --- | --- | --- |
|
|
299
|
+
| cibersort | iobrpy CLI | python fallback | Rust NuSVR core (vendored sklearn-1.7.2 libsvm) | **rust (auto)** | official gates: 34.1× e2e, up to **53.6×** held-out — see BENCHMARKS Part I | bit-exact except the unseeded P-value column |
|
|
300
|
+
| calculate_sig_score | iobrpy CLI | python | Rust ssGSEA/PCA cores + glue optimization | **rust (auto)** | glue step **30.3×** (R5); stage gates 6.6–11.5× (Part I) | bit-exact |
|
|
301
|
+
| count2tpm / epic / estimate / mcpcounter / quantiseq / anno_eset | iobrpy CLI | python | rust / vectorized | **rust-vectorized (auto)** | see BENCHMARKS Part I (count2tpm up to 48.8×, quantiseq up to 16.9×, mcpcounter 4.2–5.0×, anno_eset 3.5–3.8×, estimate 2.5–3.4×, epic 1.6–1.8×) | bit-exact |
|
|
302
|
+
| nmf | iobrpy CLI | **python (chosen)** | no Rust core (both arms share sklearn's NMF) | **python** | **1.21×** (R6) | bit-exact: 3-file sha256 (clusters / top_features / pca_plot.png) |
|
|
303
|
+
| merge_salmon | iobrpy CLI | python sequential parse (1.86× R6) | Rust read/parse engine | **rust (auto)** | **2.41×** (R6) | column-aligned token-exact (upstream `as_completed` column order is nondeterministic; port order is deterministic) |
|
|
304
|
+
| merge_star_count | iobrpy CLI | **python (chosen)** | none | **python** | **1.75×** (R6) | column-aligned token-exact + stat-row **bug-compat** (upstream's leading-4-stat-rows defect preserved) |
|
|
305
|
+
| prepare_salmon | iobrpy CLI | **python (chosen)** | none | **python** | **2.37×** (R6) | bit-exact (sha256) |
|
|
306
|
+
| log2_eset | iobrpy CLI | **python (chosen)** | none | **python** | **2.29×** (R6) | bit-exact (sha256) |
|
|
307
|
+
| ips | iobrpy CLI | **python (chosen)** | none | **python** | **3.25×** (R6) | bit-exact (sha256) |
|
|
308
|
+
| mouse2human | iobrpy CLI | **python (chosen)** | none | **python** | **3.76×** (R6) | bit-exact (sha256) |
|
|
309
|
+
| lr_cal | iobrpy CLI | python fallback | Rust gene-filter core | **rust (auto)** | **8.48×** (R6) | bit-exact (sha256) |
|
|
310
|
+
| tme_cluster | iobrpy CLI | python RNG / k-means loop | Rust k-means core | **rust (auto)** | **7.17×** (R6) | bit-exact (sha256) |
|
|
311
|
+
| bayesprism | iobrpy CLI | **python-fast (auto default)** | Rust Gibbs core (opt-in) | **python auto; `backend="rust"` optional** | python **2.62×** / rust **3.74×** (R6) | bit-exact: hs0 3-file sha256; the Rust kernel reproduces numpy's full RNG chain bit-for-bit |
|
|
312
|
+
| tme_profile | iobrpy CLI (9 serial sub-steps) | — | reuse_fast v3 (sig glue + Rust LR_cal) | **reuse_fast (`cibersort_backend="original"`)** | **10.59×** (R6) | 9 outputs: 7 raw-byte identical + 2 identical after stripping the unseeded cibersort P-value column |
|
|
313
|
+
| fastq_qc | iobrpy CLI | **python (chosen)** | none (the tool itself does the work) | **python** | ≈1.0× real data (R5; launch layer 14.9× lighter) | bit-exact except fastp-internal HTML jitter |
|
|
314
|
+
| batch_salmon | iobrpy CLI | **python (chosen)** | none | **python** | ≈1.0× per-sample real data (R5; launch layer 14.8× lighter) | bit-exact except run-metadata timestamps |
|
|
315
|
+
| batch_star_count | iobrpy CLI | **python (chosen)** | none | **python** | ≈1× real data (R5, under the declared 16-vs-32-thread deviation; launch layer 10.6× lighter) | BAM record stream + count tables bit-exact; header @PG/@CO carry the declared thread count |
|
|
316
|
+
| trust4 | iobrpy CLI | **python (chosen, accelerated post-processing)** | none | **python** | ≈1.0× real data (R5; stub launch 3.3× lighter) | bit-exact: 12/12 files byte-identical incl. post-processing outputs |
|
|
317
|
+
| runall | iobrpy CLI | **python (chosen)** | none | **python** | **1.02×** real data (R5) | bit-exact except documented tool jitter classes |
|
|
318
|
+
| spechla | iobrpy CLI | **python (chosen)** | none | **python** | **1.01×** real data (R5) | bit-exact except samtools @PG random-ID jitter |
|
|
319
|
+
| hla_typing | iobrpy CLI | **python (chosen)** | none | **python** | **1.05×** real data (R5) | bit-exact except samtools @PG random-ID jitter |
|
|
320
|
+
| extract_hla_read | iobrpy CLI | existing extraction helpers | none | **python** | Not benchmarked | command/output contracts tested with stub scripts |
|
|
321
|
+
|
|
322
|
+
## Why the speedups differ: one floor model
|
|
323
|
+
|
|
324
|
+
Every number in the table above obeys **speedup ≈ min(1/(1−p), floor)** —
|
|
325
|
+
`p` is the share of the original wall time that is a compressible hotspot,
|
|
326
|
+
and each module class has its own incompressible floor. This was the
|
|
327
|
+
campaign's measured conclusion across rounds R1–R6
|
|
328
|
+
([BENCHMARKS.md Part II](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)), not a post-hoc story:
|
|
329
|
+
|
|
330
|
+
1. **A Rust kernel pays off (≥5×) only when p ≥ 0.6.** `lr_cal`'s per-gene
|
|
331
|
+
pandas filter passes were p=0.81 of the original wall → **8.48×**;
|
|
332
|
+
`tme_cluster`'s pure-Python k-means dominates → **7.17×**. BayesPrism's
|
|
333
|
+
Gibbs sampler is only p≈0.24 → the Rust kernel lands at **3.74×** (1.56×
|
|
334
|
+
over the python lane), below 5× despite being bit-exact by construction.
|
|
335
|
+
2. **Bottleneck shift (multi-stage Amdahl).** `tme_profile`:
|
|
336
|
+
**1.12×** (one process, original code — the un-optimized sig-score glue
|
|
337
|
+
was ~84% of the wall) → **8.44×** (the 30.3× glue fix moves the floor to
|
|
338
|
+
cibersort + LR_cal ≈76%) → **10.59×** (LR_cal→Rust, sub-step
|
|
339
|
+
4.10 s → 0.22 s ≈18.6×; the floor is now the contract-bound original
|
|
340
|
+
CIBERSORT solver at 58.6% + the sig Rust chain at 31%). The next floor is
|
|
341
|
+
~9.3 s (~16.6×) — **≥12× is unreachable without breaking the cibersort
|
|
342
|
+
bit-exact contract.**
|
|
343
|
+
3. **Write-out ceiling (~2.4×) for the io-merge modules.** `merge_salmon`'s
|
|
344
|
+
Rust parser is **10.32×** faster in isolation, but the byte-level output
|
|
345
|
+
contract (pandas `to_csv` serialization + gzip) caps end-to-end at ~2.5×:
|
|
346
|
+
measured 2.41–2.48× ≈ 96% of the same-window theoretical ceiling. Rust
|
|
347
|
+
cannot buy its way past the write floor.
|
|
348
|
+
4. **Import + pandas-IO floor (~2–3.8×) for the small modules.** Every
|
|
349
|
+
original CLI call pays a ~1.3–1.4 s `iobrpy.main` import on 1.3–1.9 s
|
|
350
|
+
total walls. Removing it exposes pandas `read_csv`/`to_csv` as the new
|
|
351
|
+
floor: pure-IO modules land at 2.29–2.37× (`log2_eset`,
|
|
352
|
+
`prepare_salmon`), modules with real net compute at 3.25–3.76× (`ips`,
|
|
353
|
+
`mouse2human`), and `nmf` converges to 1.21× because both arms run the
|
|
354
|
+
same sklearn solver (shared-kernel floor).
|
|
355
|
+
5. **Orchestration ceiling (speedup ≈ 1).** For `fastq_qc` / `batch_salmon`
|
|
356
|
+
/ `batch_star_count` / `trust4` / `runall` / `spechla` / `hla_typing` the
|
|
357
|
+
external binaries *are* the wall. Real-data ratios: 0.99–1.25× (the 1.25×
|
|
358
|
+
STAR residual is fully attributable to a declared 32→16 thread deviation,
|
|
359
|
+
visible in STAR's own mapping-speed log). The ported value is API
|
|
360
|
+
consistency, in-process composition (no console-script/PATH requirement),
|
|
361
|
+
resume/parallel scheduling and byte-identical products — plus a Python
|
|
362
|
+
launch layer **3.3–14.9× lighter**, measurable when the tools are
|
|
363
|
+
stubbed.
|
|
364
|
+
|
|
365
|
+
## Bit-exact contracts and known nondeterminism
|
|
366
|
+
|
|
367
|
+
**Bit-exact** means: identical index/columns/dtypes/NaN mask with
|
|
368
|
+
`max_abs_diff == 0.0` on every numeric cell, or sha256-equal output files,
|
|
369
|
+
versus the ORIGINAL iobrpy 0.2.0 executed in the same environment. The
|
|
370
|
+
contracts are enforced by `tests/test_parity_*.py` (188 tests pass by
|
|
371
|
+
default; the official-data gates run in CI with the frozen fixtures).
|
|
372
|
+
|
|
373
|
+
Every known nondeterministic item is an **upstream** property, proven by
|
|
374
|
+
original-vs-original controls, and handled by an explicit contract clause:
|
|
375
|
+
|
|
376
|
+
- **CIBERSORT P-value column** — the original seeds its permutations from OS
|
|
377
|
+
entropy (`SeedSequence()` unseeded), so *the original itself* is not
|
|
378
|
+
reproducible run-to-run on that column. iobrx seeds them: stable across
|
|
379
|
+
runs and thread counts, identical formula and `1/perm` granularity. The
|
|
380
|
+
column is excluded from every byte contract that contains it (cibersort
|
|
381
|
+
output; tme_profile's `cibersort_results.csv` / `deconvo_merged.csv`).
|
|
382
|
+
- **BayesPrism state order** — the original's cell-state iteration order
|
|
383
|
+
follows the per-process `PYTHONHASHSEED` and can flip discrete Gibbs draws.
|
|
384
|
+
iobrx's default `state_order="sorted"` removes the dependency (theta /
|
|
385
|
+
theta_cv 100% bit-exact vs a `PYTHONHASHSEED=0` original; Z_tumor ULP-only,
|
|
386
|
+
max abs 1.42e-14, zero discrete flips); `state_order="legacy"` with
|
|
387
|
+
`PYTHONHASHSEED=0` reproduces the frozen gold shas exactly (the R6 parity
|
|
388
|
+
configuration).
|
|
389
|
+
- **`as_completed` column order** — the original `merge_salmon` /
|
|
390
|
+
`merge_star_count` column order varies run-to-run (three different orders
|
|
391
|
+
observed in three R6 reps). iobrx emits a deterministic sorted order; the
|
|
392
|
+
parity contract aligns by column name and compares token-for-token and
|
|
393
|
+
frame-bit-for-bit.
|
|
394
|
+
- **samtools @PG / @RG header IDs** — spechla / hla_typing
|
|
395
|
+
`<sample>.realign.sort.bam` inherit random `samtools merge` header ids
|
|
396
|
+
(e.g. `bwa-7A10F178`); an original-vs-original rerun shows the same
|
|
397
|
+
jitter. Alignment record streams and every other product are byte-compared.
|
|
398
|
+
- **fastp HTML jitter** — the duplication rate's 7th significant digit in
|
|
399
|
+
`fastp.html` varies per run *inside the fastp binary* (an original CLI
|
|
400
|
+
rerun reproduced the port's digit and differed from its own frozen
|
|
401
|
+
baseline); cleaned FASTQs are byte-identical.
|
|
402
|
+
- **Run metadata** — log timestamps (salmon/STAR/TRUST4 logs, multiqc
|
|
403
|
+
uuid/creation dates) are declared run-metadata; **every data artifact is
|
|
404
|
+
sha256-compared without normalization**.
|
|
405
|
+
- **Bug-compat preserved** — upstream defects that are visible in output
|
|
406
|
+
bytes are kept deliberately, e.g. `merge_star_count`'s leading four global
|
|
407
|
+
stat rows that the original never purges, and `lr_cal`'s count-branch
|
|
408
|
+
behavior.
|
|
409
|
+
|
|
410
|
+
Exact parity is an **observed result on specified inputs and pinned
|
|
411
|
+
dependency versions** (numpy<2.3, scikit-learn<1.8 — see Install), not a
|
|
412
|
+
cross-platform floating-point guarantee ([details](https://github.com/LCGaoZzz/iobrx/blob/main/docs/PORTABILITY.md)).
|
|
413
|
+
|
|
414
|
+
## External tools (bring your own)
|
|
415
|
+
|
|
416
|
+
iobrx orchestrates the heavy binaries but does not bundle them. Install them
|
|
417
|
+
yourself and put them on `PATH` (or pass the per-stage `*_bin` overrides);
|
|
418
|
+
iobrx preserves the upstream command parameters. Equality still depends on
|
|
419
|
+
the tool's determinism and the declared comparison target; see the measured
|
|
420
|
+
Salmon variability and scoped FASTQ/BAM/HLA comparisons in the new recipe.
|
|
421
|
+
|
|
422
|
+
| Stage | External tools |
|
|
423
|
+
| --- | --- |
|
|
424
|
+
| `fastq_qc` | fastp, MultiQC |
|
|
425
|
+
| `batch_salmon` | salmon |
|
|
426
|
+
| `batch_star_count` | STAR (+ samtools) |
|
|
427
|
+
| `trust4` | TRUST4 (`run-trust4`) |
|
|
428
|
+
| `spechla` / `hla_typing` | SpecHLA toolchain: samtools, bwa/bowtie2, bcftools, freebayes, vcflib, blastn, bamUtil (`bam`) |
|
|
429
|
+
| `extract_hla_read` | SpecHLA extraction assets, samtools and bamUtil (`bam`); sorted/indexed BAM or CRAM |
|
|
430
|
+
| `runall` | everything in the chosen salmon/star chain |
|
|
431
|
+
|
|
432
|
+
All pure-compute APIs (deconvolution, signature scores, TPM, annotation,
|
|
433
|
+
IPS, LR_cal, NMF/TME clustering, merges) need **no external tools** — only
|
|
434
|
+
iobrpy (references + fallback) and the pinned scientific stack.
|
|
435
|
+
|
|
436
|
+
For extraction without typing, use the prepared environment:
|
|
437
|
+
|
|
438
|
+
```python
|
|
439
|
+
iobrx.extract_hla_read("sample1", "sample1.bam", "hg38", "hla_reads")
|
|
440
|
+
```
|
|
441
|
+
|
|
442
|
+
This new API defaults to `auto_install=False` for both backends; explicitly
|
|
443
|
+
enable `auto_install=True` only when installing tools is part of the task.
|
|
444
|
+
It is currently a direct Python API, not a typed harness adapter.
|
|
445
|
+
|
|
446
|
+
## Omicos and agent workflows
|
|
447
|
+
|
|
448
|
+
The [agent harness](https://github.com/LCGaoZzz/iobrx/tree/main/agent-harness) adds a JSON CLI, an optional
|
|
449
|
+
stdio MCP server and a portable Omicos Agent/Skill pair for 27 analysis identifiers.
|
|
450
|
+
It validates matrix orientation, declared scale and gene IDs, then records
|
|
451
|
+
parameters, input/output metadata, versions, backend and elapsed time in a result
|
|
452
|
+
manifest. Analyses use the existing iobrx API and preserve its result layouts.
|
|
453
|
+
Known requests can run directly; discovery and diagnostics are optional.
|
|
454
|
+
Agents can also use the public Python API for custom work. Full SHA-256
|
|
455
|
+
auditing is opt-in; default result inspection checks file availability.
|
|
456
|
+
|
|
457
|
+
After installing iobrx, from this checkout:
|
|
458
|
+
|
|
459
|
+
```bash
|
|
460
|
+
python -m pip install ./agent-harness
|
|
461
|
+
iobrx-agent run --request agent-harness/examples/signature_pca.json
|
|
462
|
+
```
|
|
463
|
+
|
|
464
|
+
See [Omicos setup](https://github.com/LCGaoZzz/iobrx/blob/main/agent-harness/omicos/README.md) for workspace/catalog
|
|
465
|
+
installation and MCP configuration, and [harness validation](https://github.com/LCGaoZzz/iobrx/blob/main/agent-harness/VALIDATION.md)
|
|
466
|
+
for the actual test record. The companion harness is installed from this
|
|
467
|
+
repository; it is not yet a separately published PyPI package.
|
|
468
|
+
|
|
469
|
+
## How long does each analysis take?
|
|
470
|
+
|
|
471
|
+
Measured on **Intel Core i9-13900KF, WSL2 Ubuntu, Python 3.11, 8 requested
|
|
472
|
+
threads, no AVX-512**, using the existing Omicos environment. Each row runs
|
|
473
|
+
in a fresh Python process: first call, followed by three repeat calls.
|
|
474
|
+
The main time is the **median of those three repeats**. Data loading, input
|
|
475
|
+
preparation and plotting are excluded; the complete workflow includes its
|
|
476
|
+
own normalization and analysis stages. OS file caches may already be warm.
|
|
477
|
+
|
|
478
|
+
<!-- BENCHMARK_TABLE_START -->
|
|
479
|
+
| Analysis / notebook | Input: features × samples | Median | First call | Parity vs IOBRpy |
|
|
480
|
+
| --- | --- | ---: | ---: | --- |
|
|
481
|
+
| [Gene annotation and duplicate resolution](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/01_gene_annotation.ipynb) | 60,483 × 10 | **16.7 ms** | 36.0 ms | bit-identical |
|
|
482
|
+
| [Count-to-TPM normalization](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/02_counts_to_tpm.ipynb) | 60,483 × 10 | **67.5 ms** | 111.6 ms | bit-identical |
|
|
483
|
+
| [PCA signature scoring](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/03_signature_pca.ipynb) | 872 × 348 | **244.1 ms** | 600.4 ms | bit-identical |
|
|
484
|
+
| [Mean-based signature scoring](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/04_signature_zscore.ipynb) | 872 × 348 | **78.6 ms** | 487.8 ms | bit-identical |
|
|
485
|
+
| [ssGSEA signature enrichment](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/05_signature_ssgsea.ipynb) | 872 × 348 | **86.7 ms** | 495.9 ms | bit-identical |
|
|
486
|
+
| [Integrated signature scoring](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/06_signature_integration.ipynb) | 872 × 348 | **336.0 ms** | 817.9 ms | bit-identical |
|
|
487
|
+
| [CIBERSORT immune composition](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/07_cibersort.ipynb) | 48,058 × 10 | **26.37 s** | 26.99 s | bit-identical, P-value excepted |
|
|
488
|
+
| [EPIC cell fractions and mRNA proportions](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/08_epic.ipynb) | 48,058 × 10 | **6.8 ms** | 301.9 ms | bit-identical |
|
|
489
|
+
| [quanTIseq immune deconvolution](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/09_quantiseq.ipynb) | 48,058 × 10 | **40.9 ms** | 475.2 ms | bit-identical |
|
|
490
|
+
| [MCP-counter population scores](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/10_mcpcounter.ipynb) | 48,058 × 10 | **1.1 ms** | 10.0 ms | bit-identical |
|
|
491
|
+
| [ESTIMATE stromal and immune scores](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/11_estimate.ipynb) | 48,058 × 10 | **15.8 ms** | 31.0 ms | bit-identical |
|
|
492
|
+
| [A complete, inspectable TME workflow](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/12_complete_workflow.ipynb) | 60,483 × 10 | **28.29 s** | 29.59 s | per stage, as rows above |
|
|
493
|
+
<!-- BENCHMARK_TABLE_END -->
|
|
494
|
+
|
|
495
|
+
These are local wall-clock measurements, not a promise for other hardware or
|
|
496
|
+
cohorts. CIBERSORT uses **100 permutations and `QN=False`** on the full STAD
|
|
497
|
+
TPM matrix. The restricted IMvigor210 signature panel is a different
|
|
498
|
+
workload. The complete workflow runs integration scoring on the full STAD
|
|
499
|
+
expression matrix, so its total is not the sum of the standalone rows.
|
|
500
|
+
|
|
501
|
+
The **Parity** column is not a timing: it states what the official gates
|
|
502
|
+
([`tests/test_parity_official.py`](https://github.com/LCGaoZzz/iobrx/blob/main/tests/test_parity_official.py)) assert for
|
|
503
|
+
that analysis on the same fixtures — equal index, labels and column names, and
|
|
504
|
+
exact equality of every numeric cell (`max_abs_diff == 0.0`) against the
|
|
505
|
+
ORIGINAL `iobrpy` implementations executed in the same environment
|
|
506
|
+
([validation record](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/results/validation.json)). The single
|
|
507
|
+
exception is CIBERSORT's P-value: the original seeds its permutations from OS
|
|
508
|
+
entropy and is not reproducible run-to-run even by itself, whereas iobrx's
|
|
509
|
+
P-values are seeded — stable across runs and thread counts, with the
|
|
510
|
+
identical formula and `1/perm` granularity. All 11 gates are re-run by CI on
|
|
511
|
+
every push and pull request under the
|
|
512
|
+
[validated constraints](https://github.com/LCGaoZzz/iobrx/blob/main/tests/constraints-validated.txt), and the same
|
|
513
|
+
contract held on the historical 224-thread Xeon campaign
|
|
514
|
+
([BENCHMARKS.md](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)). Exact parity is an observed result on those
|
|
515
|
+
environments, not a cross-platform floating-point guarantee
|
|
516
|
+
([details](https://github.com/LCGaoZzz/iobrx/blob/main/docs/PORTABILITY.md)).
|
|
517
|
+
|
|
518
|
+
[Raw repeats, ranges and environment](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/results/benchmark.json) ·
|
|
519
|
+
[Benchmark method and reproduction](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/BENCHMARKS.md) ·
|
|
520
|
+
[Historical Xeon performance campaign](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)
|
|
521
|
+
[Full performance record: acceleration stack + port campaign](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)
|
|
522
|
+
|
|
523
|
+
The historical 224-thread Xeon speedups (Part I) and the R6 blind port
|
|
524
|
+
benchmark (Part II) are retained as separate experiments; they are not used
|
|
525
|
+
to advertise desktop performance.
|
|
526
|
+
|
|
527
|
+
## Choose the right output
|
|
528
|
+
|
|
529
|
+
| Analysis | Input used in the tutorials | Output and interpretation |
|
|
530
|
+
| --- | --- | --- |
|
|
531
|
+
| `anno_eset` | Ensembl expression + annotation | Gene-symbol matrix; duplicate candidates are ranked and one row retained |
|
|
532
|
+
| `count2tpm` | Raw nonnegative counts | TPM matrix; filtering/deduplication can leave sums below one million |
|
|
533
|
+
| `calculate_sig_score` | Suitable preprocessed expression | `pca`, `zscore`, `ssgsea`, or `integration`; method-specific signature scores |
|
|
534
|
+
| `cibersort` | Linear TPM, `QN=False` | Relative LM22 immune fractions + fit statistics |
|
|
535
|
+
| `epic` | Linear TPM | Cell fractions, mRNA proportions, fit diagnostics |
|
|
536
|
+
| `quantiseq` | Linear TPM, tumor settings explicit | TIL10 fractions and an uncharacterized remainder |
|
|
537
|
+
| `mcpcounter` | `log2(TPM + 1)` | Population abundance scores, not percentages |
|
|
538
|
+
| `estimate_score` | `log2(TPM + 1)`, `platform="rnaseq"` | Stromal, immune and combined enrichment scores |
|
|
539
|
+
| `bayesprism` | Pseudo-bulk counts + scRNA reference | Cell-type/state deconvolution with credible intervals |
|
|
540
|
+
| `lr_cal` | TPM (symbol or Ensembl) | Ligand–receptor pair matrix (min of the two log2 TPMs) |
|
|
541
|
+
| `ips` | TPM/FPKM expression set | Immunophenoscore 0–1 across four blocks (Charoentong 2017) |
|
|
542
|
+
|
|
543
|
+
The upstream method named **`zscore`** averages preprocessed signature
|
|
544
|
+
expression; it does not guarantee standardized output. `integration`
|
|
545
|
+
concatenates three methods rather than averaging them. Only the exact
|
|
546
|
+
`platform="affymetrix"` string requests IOBRpy's calibrated ESTIMATE purity
|
|
547
|
+
transformation; the historical `"affy"` default does not. These RNA-seq
|
|
548
|
+
tutorials therefore show scores without that purity transformation.
|
|
549
|
+
|
|
550
|
+
## Compatibility and numerical fidelity
|
|
551
|
+
|
|
552
|
+
```python
|
|
553
|
+
iobrx.backend_info() # native availability, sorting dispatch, bundled BLAS
|
|
554
|
+
|
|
555
|
+
# Optional: explicitly use the original IOBRpy workflow.
|
|
556
|
+
cib = iobrx.cibersort(tpm, perm=100, QN=False, backend="python")
|
|
557
|
+
# backend="rust" requires native support and reports an error if unavailable.
|
|
558
|
+
```
|
|
559
|
+
|
|
560
|
+
`backend="auto"` is the default wherever an accelerated lane exists (see the
|
|
561
|
+
route table for which lane each module ships). Set `IOBRX_DISABLE_RUST=1`
|
|
562
|
+
**before importing** to disable native acceleration process-wide. Missing
|
|
563
|
+
native support does not prevent using the public analysis API when IOBRpy
|
|
564
|
+
and its dependencies are installed. Missing compatible OpenBLAS triggers
|
|
565
|
+
fallback for CIBERSORT/PCA.
|
|
566
|
+
|
|
567
|
+
All parity gates run in CI on every push and pull request under the
|
|
568
|
+
[validated constraints](https://github.com/LCGaoZzz/iobrx/blob/main/tests/constraints-validated.txt); their assertion is
|
|
569
|
+
exact equality — labels and every numeric cell, or file sha256 — against the
|
|
570
|
+
ORIGINAL executed on the same fixtures, with the documented nondeterminism
|
|
571
|
+
clauses above. Exact parity is an **observed result on specified inputs and
|
|
572
|
+
dependency versions**, not a cross-platform floating-point guarantee. Native
|
|
573
|
+
CIBERSORT uses seeded permutations; the original Python implementation uses
|
|
574
|
+
unseeded permutations, so its P-value column is excluded from
|
|
575
|
+
exact-equality assertions. See
|
|
576
|
+
[precision and fallback details](https://github.com/LCGaoZzz/iobrx/blob/main/docs/PORTABILITY.md).
|
|
577
|
+
|
|
578
|
+
## Reproduce, test, contribute
|
|
579
|
+
|
|
580
|
+
```bash
|
|
581
|
+
python -m pytest -q # 188 smoke + parity + portability tests
|
|
582
|
+
IOBRX_TESTDATA=tutorials/data python -m pytest -q -m full # official-data gates
|
|
583
|
+
python scripts/execute_tutorials.py # all 12, fresh kernels, embedded plots
|
|
584
|
+
python scripts/benchmark_tutorials.py # first call + 3 repeats per analysis
|
|
585
|
+
python scripts/validate_tutorials.py # outputs, exports and data checksums
|
|
586
|
+
```
|
|
587
|
+
|
|
588
|
+
Tutorials can be read directly on GitHub. To run them interactively:
|
|
589
|
+
`python -m jupyterlab tutorials`. Plotting helpers are in
|
|
590
|
+
[`tutorials/_common.py`](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/_common.py); every analysis call remains
|
|
591
|
+
visible in its notebook. [The figure-review record](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/FIGURE_REVIEW.md)
|
|
592
|
+
documents both refinements, with draft and final overview images.
|
|
593
|
+
|
|
594
|
+
Contributions should preserve the parity gates and add a focused regression
|
|
595
|
+
test for changed numerical behavior. Files in `bench/` are frozen historical
|
|
596
|
+
artifacts. Report package versions, backend information, input shape and
|
|
597
|
+
expression scale when reporting a problem.
|
|
598
|
+
|
|
599
|
+
## Upstream credit, citation and license
|
|
600
|
+
|
|
601
|
+
We thank the [IOBRpy developers](https://github.com/IOBR/IOBRpy), the
|
|
602
|
+
[IOBR team](https://github.com/IOBR/IOBR), and the original method authors for
|
|
603
|
+
the workflows and reference resources on which this package builds.
|
|
604
|
+
|
|
605
|
+
When publishing results, cite IOBR/IOBRpy and the original methods actually
|
|
606
|
+
used — including CIBERSORT (Newman et al.), BayesPrism, quanTIseq, EPIC,
|
|
607
|
+
MCP-counter, ESTIMATE, IPS (Charoentong et al. 2017), TRUST4, SpecHLA, and
|
|
608
|
+
the tool papers for fastp/salmon/STAR when you run the orchestration stages.
|
|
609
|
+
See the [IOBRpy preprint](https://doi.org/10.64898/2026.07.17.739055) and the
|
|
610
|
+
[upstream citation guide](https://iobr.github.io/IOBRpy/Citation.html). The
|
|
611
|
+
preprint reports CIBERSORT *thread scaling* inside the original
|
|
612
|
+
implementation — a different measurement axis from the port speedups here
|
|
613
|
+
(see [BENCHMARKS.md §II.9](https://github.com/LCGaoZzz/iobrx/blob/main/BENCHMARKS.md)).
|
|
614
|
+
|
|
615
|
+
iobrx provides acceleration and tutorials; it does not replace those methods
|
|
616
|
+
or validate clinical conclusions from an unlabeled example dataset.
|
|
617
|
+
|
|
618
|
+
iobrx code: [MIT](https://github.com/LCGaoZzz/iobrx/blob/main/LICENSE). Vendored sources retain their
|
|
619
|
+
[third-party notices](https://github.com/LCGaoZzz/iobrx/blob/main/rust/vendor/THIRD_PARTY_NOTICES.md). Public example data
|
|
620
|
+
retains its [upstream attribution and GPL-3 terms](https://github.com/LCGaoZzz/iobrx/blob/main/tutorials/data/README.md).
|
|
621
|
+
|