interaction-harness 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- interaction_harness-0.1.0/.env.example +71 -0
- interaction_harness-0.1.0/.github/ISSUE_TEMPLATE/bug-report.yml +34 -0
- interaction_harness-0.1.0/.github/ISSUE_TEMPLATE/config.yml +1 -0
- interaction_harness-0.1.0/.github/ISSUE_TEMPLATE/server-report.yml +61 -0
- interaction_harness-0.1.0/.github/workflows/ci.yml +46 -0
- interaction_harness-0.1.0/.github/workflows/publish.yml +29 -0
- interaction_harness-0.1.0/.gitignore +25 -0
- interaction_harness-0.1.0/CONTRIBUTING.md +49 -0
- interaction_harness-0.1.0/LICENSE +21 -0
- interaction_harness-0.1.0/PKG-INFO +269 -0
- interaction_harness-0.1.0/README.md +224 -0
- interaction_harness-0.1.0/demos/barge-in.png +0 -0
- interaction_harness-0.1.0/demos/dashboard.png +0 -0
- interaction_harness-0.1.0/demos/session.gif +0 -0
- interaction_harness-0.1.0/docs/backends.md +73 -0
- interaction_harness-0.1.0/docs/endpoints.md +77 -0
- interaction_harness-0.1.0/docs/interaction-models.md +146 -0
- interaction_harness-0.1.0/docs/protocol.md +83 -0
- interaction_harness-0.1.0/docs/tools.md +75 -0
- interaction_harness-0.1.0/examples/my_tools.py +25 -0
- interaction_harness-0.1.0/pyproject.toml +103 -0
- interaction_harness-0.1.0/src/interaction_harness/__init__.py +1 -0
- interaction_harness-0.1.0/src/interaction_harness/__main__.py +3 -0
- interaction_harness-0.1.0/src/interaction_harness/cli.py +140 -0
- interaction_harness-0.1.0/src/interaction_harness/config.py +210 -0
- interaction_harness-0.1.0/src/interaction_harness/doctor.py +171 -0
- interaction_harness-0.1.0/src/interaction_harness/llm.py +174 -0
- interaction_harness-0.1.0/src/interaction_harness/prompts.py +29 -0
- interaction_harness-0.1.0/src/interaction_harness/selftest.py +289 -0
- interaction_harness-0.1.0/src/interaction_harness/server.py +106 -0
- interaction_harness-0.1.0/src/interaction_harness/session.py +848 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/__init__.py +93 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/assets/SILERO_VAD_LICENSE +21 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/assets/silero_vad.onnx +0 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/base.py +142 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/endpoint.py +112 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/mlx.py +143 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/onnx.py +88 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/silero.py +53 -0
- interaction_harness-0.1.0/src/interaction_harness/speech/text.py +75 -0
- interaction_harness-0.1.0/src/interaction_harness/static/app.js +277 -0
- interaction_harness-0.1.0/src/interaction_harness/static/index.html +97 -0
- interaction_harness-0.1.0/src/interaction_harness/static/mic-worklet.js +37 -0
- interaction_harness-0.1.0/src/interaction_harness/static/style.css +151 -0
- interaction_harness-0.1.0/src/interaction_harness/tools/__init__.py +5 -0
- interaction_harness-0.1.0/src/interaction_harness/tools/builtin.py +161 -0
- interaction_harness-0.1.0/src/interaction_harness/tools/registry.py +155 -0
- interaction_harness-0.1.0/src/interaction_harness/tools/web.py +359 -0
- interaction_harness-0.1.0/tests/conftest.py +136 -0
- interaction_harness-0.1.0/tests/data/vad_clip.npy +0 -0
- interaction_harness-0.1.0/tests/data/vad_ref.npy +0 -0
- interaction_harness-0.1.0/tests/test_config.py +88 -0
- interaction_harness-0.1.0/tests/test_llm_and_web.py +49 -0
- interaction_harness-0.1.0/tests/test_session.py +138 -0
- interaction_harness-0.1.0/tests/test_speech.py +167 -0
- interaction_harness-0.1.0/tests/test_tools.py +89 -0
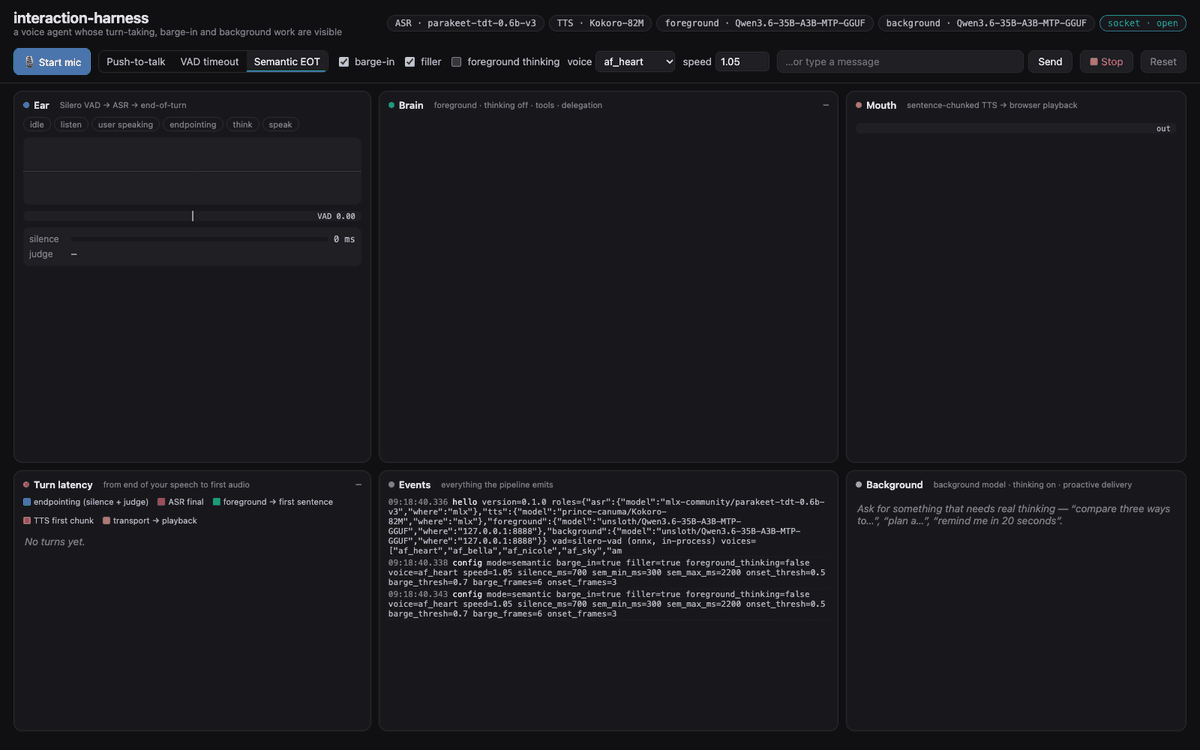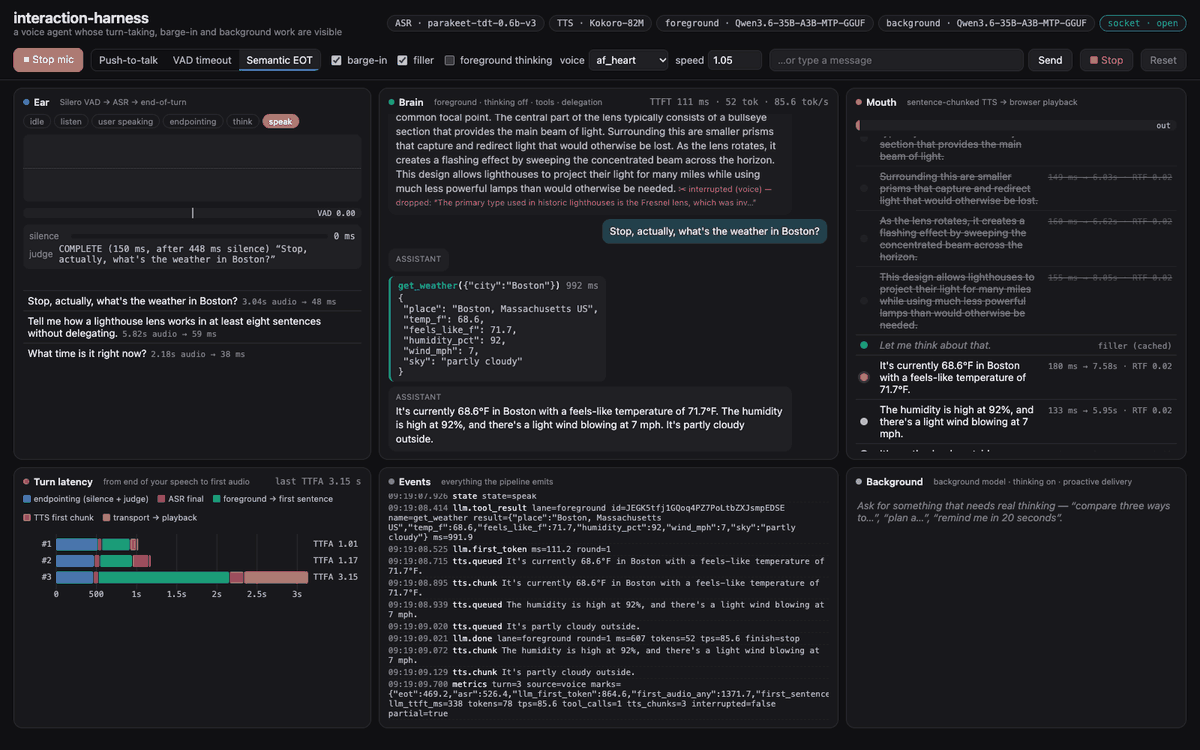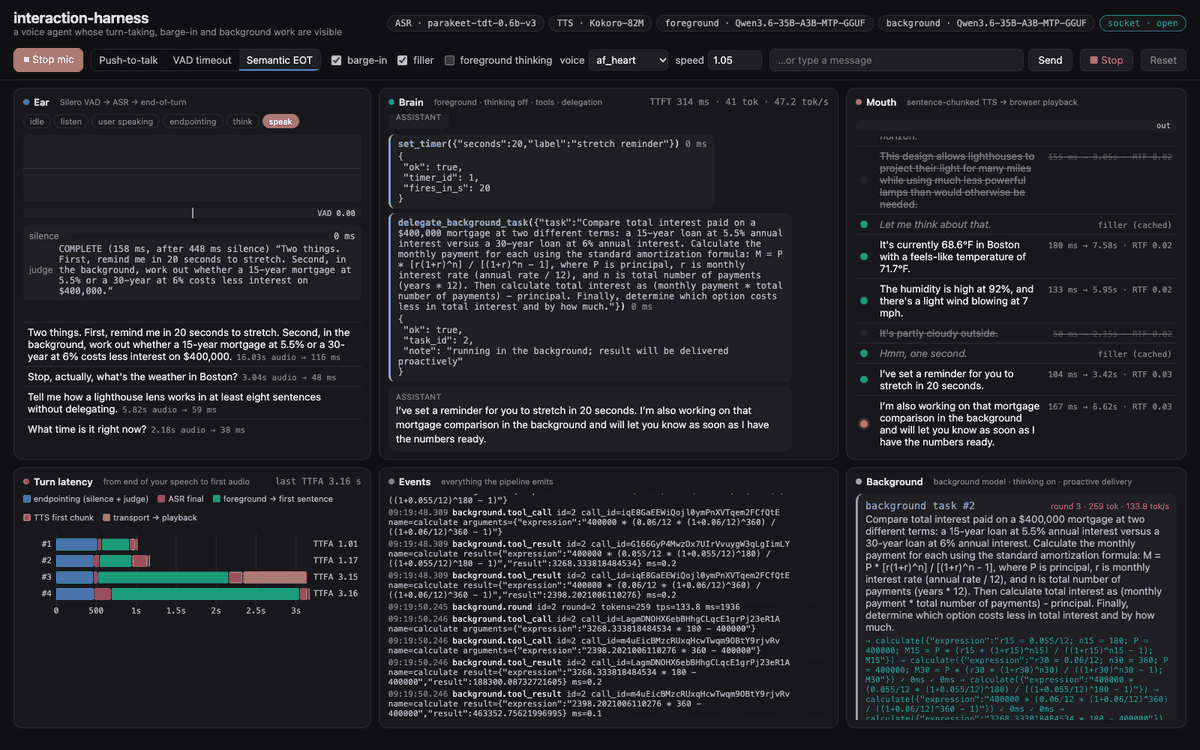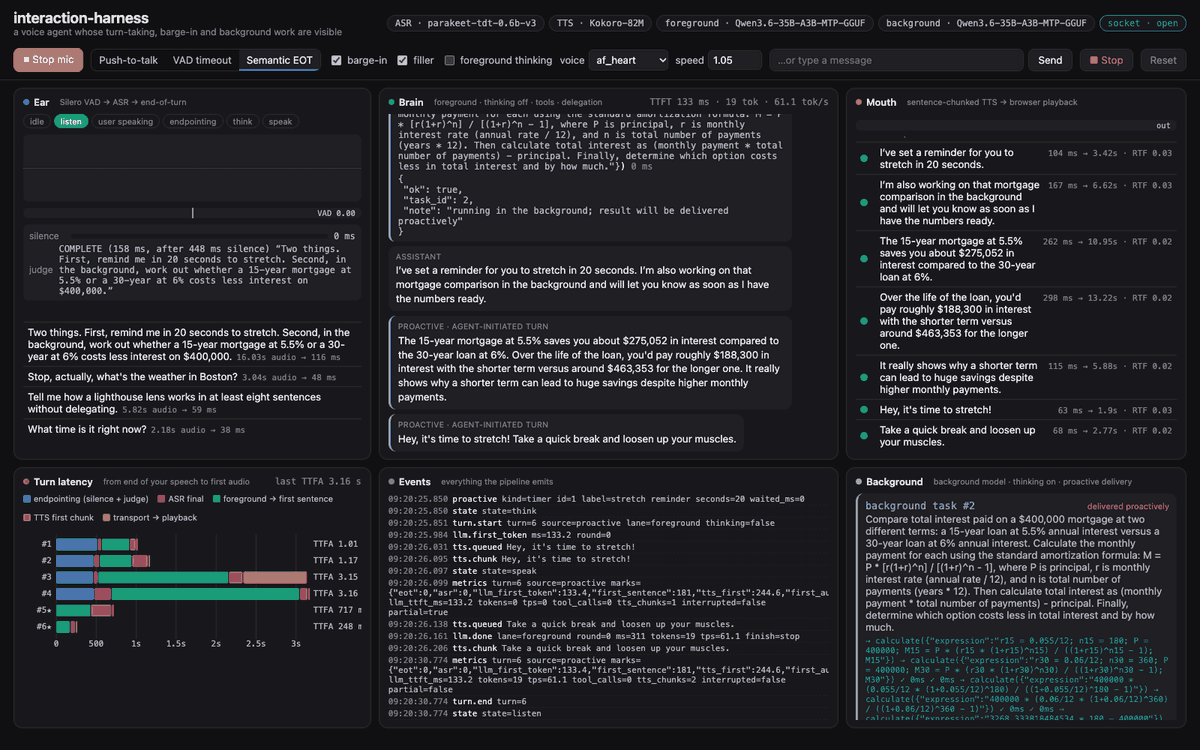
- interaction_harness-0.1.0/uv.lock +2472 -0
|
@@ -0,0 +1,71 @@
|
|
|
1
|
+
# interaction-harness settings. Copy to .env (or export the variables) and fill in what you use.
|
|
2
|
+
# Every model role is any OpenAI-compatible endpoint: <ROLE>_BASE_URL, <ROLE>_API_KEY, <ROLE>_MODEL.
|
|
3
|
+
# A key is only ever sent to the host it was set for.
|
|
4
|
+
|
|
5
|
+
# --- FOREGROUND: holds the conversation, calls quick tools, hands off hard work, judges end-of-turn --------
|
|
6
|
+
# Required. Falls back to OPENAI_BASE_URL / OPENAI_API_KEY when these are unset.
|
|
7
|
+
FOREGROUND_BASE_URL=http://127.0.0.1:8080/v1
|
|
8
|
+
FOREGROUND_API_KEY=
|
|
9
|
+
# Blank: the first model the server lists.
|
|
10
|
+
FOREGROUND_MODEL=
|
|
11
|
+
# How this server switches thinking: chat_template_kwargs (vLLM, llama.cpp, SGLang) | reasoning_effort | off
|
|
12
|
+
FOREGROUND_THINKING=chat_template_kwargs
|
|
13
|
+
|
|
14
|
+
# --- BACKGROUND: works on handed-off tasks with thinking on, browses, reports back on its own ---------------
|
|
15
|
+
# Blank: the foreground's server and model (field by field).
|
|
16
|
+
BACKGROUND_BASE_URL=
|
|
17
|
+
BACKGROUND_API_KEY=
|
|
18
|
+
BACKGROUND_MODEL=
|
|
19
|
+
BACKGROUND_THINKING=
|
|
20
|
+
BACKGROUND_TEMPERATURE=0.7
|
|
21
|
+
# Model calls per background task
|
|
22
|
+
BACKGROUND_ROUNDS=10
|
|
23
|
+
|
|
24
|
+
# --- ASR: speech -> text (POST /audio/transcriptions) ------------------------------------------------------
|
|
25
|
+
# Blank or "local": Parakeet TDT 0.6B v3 in-process (MLX on Apple Silicon, ONNX elsewhere).
|
|
26
|
+
ASR_BASE_URL=
|
|
27
|
+
ASR_API_KEY=
|
|
28
|
+
# Endpoint: the server's transcription model. In-process: override the Parakeet model id.
|
|
29
|
+
ASR_MODEL=
|
|
30
|
+
ASR_LANGUAGE=
|
|
31
|
+
# Partial transcripts every N ms while you talk; 0 = only when the end-of-turn judge needs one.
|
|
32
|
+
# On an endpoint each partial is one request.
|
|
33
|
+
ASR_PARTIAL_MS=640
|
|
34
|
+
|
|
35
|
+
# --- TTS: text -> speech (POST /audio/speech) --------------------------------------------------------------
|
|
36
|
+
# Blank or "local": Kokoro-82M in-process (MLX on Apple Silicon, ONNX elsewhere).
|
|
37
|
+
TTS_BASE_URL=
|
|
38
|
+
TTS_API_KEY=
|
|
39
|
+
TTS_MODEL=
|
|
40
|
+
# Blank: af_heart in-process, else the first voice the server lists (required if the server lists none).
|
|
41
|
+
TTS_VOICE=
|
|
42
|
+
# Comma-separated voices for the dashboard's picker, if the server does not list them.
|
|
43
|
+
TTS_VOICES=
|
|
44
|
+
# Endpoint audio: wav (default) or pcm; with pcm, the server's sample rate.
|
|
45
|
+
TTS_FORMAT=wav
|
|
46
|
+
TTS_SAMPLE_RATE=24000
|
|
47
|
+
TTS_SPEED=1.05
|
|
48
|
+
|
|
49
|
+
# --- in-process speech --------------------------------------------------------------------------------------
|
|
50
|
+
# auto (mlx on Apple Silicon, onnx elsewhere) | mlx | onnx
|
|
51
|
+
BACKEND=auto
|
|
52
|
+
# onnx backend: cpu | cuda (needs the onnx-gpu extra)
|
|
53
|
+
DEVICE=cpu
|
|
54
|
+
# onnx model variants: PARAKEET fp32|int8, KOKORO fp32|fp16|int8
|
|
55
|
+
PARAKEET_ONNX_VARIANT=int8
|
|
56
|
+
KOKORO_ONNX_VARIANT=int8
|
|
57
|
+
|
|
58
|
+
# --- everything else ----------------------------------------------------------------------------------------
|
|
59
|
+
# Comma-separated Python files of @tool functions
|
|
60
|
+
TOOLS=
|
|
61
|
+
# A directory to keep a WAV of every user turn the ASR heard (debugging)
|
|
62
|
+
SAVE_UTTERANCES=
|
|
63
|
+
HOST=127.0.0.1
|
|
64
|
+
PORT=8765
|
|
65
|
+
# HTTPS, so a browser on another machine may use the microphone
|
|
66
|
+
SSL_CERTFILE=
|
|
67
|
+
SSL_KEYFILE=
|
|
68
|
+
# Prompt overrides (easier in interaction-harness.toml under [prompts])
|
|
69
|
+
# FOREGROUND_PROMPT=
|
|
70
|
+
# BACKGROUND_PROMPT=
|
|
71
|
+
# END_OF_TURN_PROMPT=
|
|
@@ -0,0 +1,34 @@
|
|
|
1
|
+
name: Bug report
|
|
2
|
+
description: Something doesn't work the way the README says it should.
|
|
3
|
+
labels: [bug]
|
|
4
|
+
body:
|
|
5
|
+
- type: textarea
|
|
6
|
+
id: what
|
|
7
|
+
attributes:
|
|
8
|
+
label: What happened
|
|
9
|
+
description: What you did, what you expected, and what happened instead.
|
|
10
|
+
validations:
|
|
11
|
+
required: true
|
|
12
|
+
- type: textarea
|
|
13
|
+
id: events
|
|
14
|
+
attributes:
|
|
15
|
+
label: Events or logs
|
|
16
|
+
description: |
|
|
17
|
+
The relevant lines from the dashboard's Events panel or the server's terminal. If it's about speech
|
|
18
|
+
or turn-taking, setting `SAVE_UTTERANCES=DIR` keeps a WAV of each turn the ASR heard.
|
|
19
|
+
render: text
|
|
20
|
+
- type: input
|
|
21
|
+
id: version
|
|
22
|
+
attributes:
|
|
23
|
+
label: Version
|
|
24
|
+
description: The output of `interaction-harness --version`.
|
|
25
|
+
validations:
|
|
26
|
+
required: true
|
|
27
|
+
- type: input
|
|
28
|
+
id: setup
|
|
29
|
+
attributes:
|
|
30
|
+
label: Setup
|
|
31
|
+
description: OS and hardware, which roles are in-process or on an endpoint, and which servers and models.
|
|
32
|
+
placeholder: e.g. macOS 26, M4 Pro; speech in-process (MLX); foreground llama.cpp with Qwen3-8B
|
|
33
|
+
validations:
|
|
34
|
+
required: true
|
|
@@ -0,0 +1 @@
|
|
|
1
|
+
blank_issues_enabled: true
|
|
@@ -0,0 +1,61 @@
|
|
|
1
|
+
name: Server report
|
|
2
|
+
description: You ran the harness against a model server. Tell us whether it worked.
|
|
3
|
+
title: "Server report: "
|
|
4
|
+
labels: [server report]
|
|
5
|
+
body:
|
|
6
|
+
- type: markdown
|
|
7
|
+
attributes:
|
|
8
|
+
value: |
|
|
9
|
+
Reports like this fill in the README's "Tested with" table. Run `interaction-harness doctor` with your
|
|
10
|
+
settings first; it checks each role on its own and prints what to paste below.
|
|
11
|
+
- type: dropdown
|
|
12
|
+
id: roles
|
|
13
|
+
attributes:
|
|
14
|
+
label: Roles
|
|
15
|
+
description: Which roles did this server play?
|
|
16
|
+
multiple: true
|
|
17
|
+
options: [ASR, TTS, foreground, background]
|
|
18
|
+
validations:
|
|
19
|
+
required: true
|
|
20
|
+
- type: input
|
|
21
|
+
id: server
|
|
22
|
+
attributes:
|
|
23
|
+
label: Server and version
|
|
24
|
+
placeholder: e.g. vLLM 0.13.1, Speaches 0.9, OpenAI API
|
|
25
|
+
validations:
|
|
26
|
+
required: true
|
|
27
|
+
- type: input
|
|
28
|
+
id: model
|
|
29
|
+
attributes:
|
|
30
|
+
label: Model
|
|
31
|
+
placeholder: e.g. Qwen/Qwen3-8B
|
|
32
|
+
validations:
|
|
33
|
+
required: true
|
|
34
|
+
- type: input
|
|
35
|
+
id: hardware
|
|
36
|
+
attributes:
|
|
37
|
+
label: Hardware and OS
|
|
38
|
+
placeholder: e.g. RTX 4090, Ubuntu 24.04
|
|
39
|
+
- type: dropdown
|
|
40
|
+
id: result
|
|
41
|
+
attributes:
|
|
42
|
+
label: Did it work?
|
|
43
|
+
options:
|
|
44
|
+
- "Yes: doctor passes and conversation works"
|
|
45
|
+
- "Partly: some checks warn or fail"
|
|
46
|
+
- "No"
|
|
47
|
+
validations:
|
|
48
|
+
required: true
|
|
49
|
+
- type: textarea
|
|
50
|
+
id: doctor
|
|
51
|
+
attributes:
|
|
52
|
+
label: doctor output
|
|
53
|
+
description: The output of `interaction-harness doctor`. Remove any keys or private hostnames.
|
|
54
|
+
render: text
|
|
55
|
+
validations:
|
|
56
|
+
required: true
|
|
57
|
+
- type: textarea
|
|
58
|
+
id: notes
|
|
59
|
+
attributes:
|
|
60
|
+
label: Notes
|
|
61
|
+
description: Settings you needed (thinking switch, server flags), and anything else worth knowing.
|
|
@@ -0,0 +1,46 @@
|
|
|
1
|
+
name: ci
|
|
2
|
+
|
|
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
branches: [main]
|
|
6
|
+
pull_request:
|
|
7
|
+
|
|
8
|
+
jobs:
|
|
9
|
+
test:
|
|
10
|
+
strategy:
|
|
11
|
+
fail-fast: false
|
|
12
|
+
matrix:
|
|
13
|
+
os: [ubuntu-latest, macos-latest]
|
|
14
|
+
runs-on: ${{ matrix.os }}
|
|
15
|
+
steps:
|
|
16
|
+
- uses: actions/checkout@v7
|
|
17
|
+
- uses: astral-sh/setup-uv@v10.3.3
|
|
18
|
+
with:
|
|
19
|
+
enable-cache: true
|
|
20
|
+
- name: Install
|
|
21
|
+
run: uv sync --locked
|
|
22
|
+
- name: Lint
|
|
23
|
+
run: uv run ruff check src tests examples
|
|
24
|
+
- name: Unit tests (fakes and stubs; no models, no network)
|
|
25
|
+
run: uv run pytest -q
|
|
26
|
+
- name: CLI loads
|
|
27
|
+
run: |
|
|
28
|
+
uv run interaction-harness --version
|
|
29
|
+
uv run interaction-harness serve --help > /dev/null
|
|
30
|
+
|
|
31
|
+
speech-onnx-linux:
|
|
32
|
+
# the in-process ONNX speech stack on Linux, for real: download, TTS -> ASR round trip, partials, VAD
|
|
33
|
+
runs-on: ubuntu-latest
|
|
34
|
+
steps:
|
|
35
|
+
- uses: actions/checkout@v7
|
|
36
|
+
- uses: astral-sh/setup-uv@v10.3.3
|
|
37
|
+
with:
|
|
38
|
+
enable-cache: true
|
|
39
|
+
- name: Install
|
|
40
|
+
run: uv sync --locked
|
|
41
|
+
- uses: actions/cache@v6
|
|
42
|
+
with:
|
|
43
|
+
path: ~/.cache/interaction-harness
|
|
44
|
+
key: onnx-models-v1-int8
|
|
45
|
+
- name: Speech round trip
|
|
46
|
+
run: uv run interaction-harness warmup --backend onnx
|
|
@@ -0,0 +1,29 @@
|
|
|
1
|
+
name: publish
|
|
2
|
+
|
|
3
|
+
# Publishing a GitHub release uploads that version to PyPI. PyPI trusts this workflow directly (a
|
|
4
|
+
# "trusted publisher"), so no token is stored anywhere.
|
|
5
|
+
on:
|
|
6
|
+
release:
|
|
7
|
+
types: [published]
|
|
8
|
+
workflow_dispatch:
|
|
9
|
+
|
|
10
|
+
jobs:
|
|
11
|
+
pypi:
|
|
12
|
+
runs-on: ubuntu-latest
|
|
13
|
+
environment: pypi
|
|
14
|
+
permissions:
|
|
15
|
+
id-token: write
|
|
16
|
+
steps:
|
|
17
|
+
- uses: actions/checkout@v7
|
|
18
|
+
- uses: astral-sh/setup-uv@v10.3.3
|
|
19
|
+
- name: The tag matches the package version
|
|
20
|
+
if: github.event_name == 'release'
|
|
21
|
+
run: |
|
|
22
|
+
version=$(uv version --short)
|
|
23
|
+
test "${GITHUB_REF_NAME}" = "v${version}" || { echo "tag ${GITHUB_REF_NAME} != v${version}"; exit 1; }
|
|
24
|
+
- name: Build
|
|
25
|
+
run: uv build
|
|
26
|
+
- name: Check the PyPI page renders
|
|
27
|
+
run: uvx twine check dist/*
|
|
28
|
+
- name: Publish
|
|
29
|
+
run: uv publish --trusted-publishing always
|
|
@@ -0,0 +1,25 @@
|
|
|
1
|
+
# secrets and local settings
|
|
2
|
+
.env
|
|
3
|
+
.env.*
|
|
4
|
+
!.env.example
|
|
5
|
+
interaction-harness.toml
|
|
6
|
+
|
|
7
|
+
# python
|
|
8
|
+
__pycache__/
|
|
9
|
+
*.py[cod]
|
|
10
|
+
.venv/
|
|
11
|
+
build/
|
|
12
|
+
dist/
|
|
13
|
+
*.egg-info/
|
|
14
|
+
.pytest_cache/
|
|
15
|
+
.ruff_cache/
|
|
16
|
+
|
|
17
|
+
# runtime output
|
|
18
|
+
utterances/
|
|
19
|
+
*.log
|
|
20
|
+
*.pid
|
|
21
|
+
|
|
22
|
+
# editors and OS
|
|
23
|
+
.DS_Store
|
|
24
|
+
.idea/
|
|
25
|
+
.vscode/
|
|
@@ -0,0 +1,49 @@
|
|
|
1
|
+
# Contributing
|
|
2
|
+
|
|
3
|
+
Issues and pull requests are welcome. The most useful contributions are:
|
|
4
|
+
|
|
5
|
+
- **Server reports.** Run `interaction-harness doctor` against a server not yet in the README's "Tested
|
|
6
|
+
with" table (OpenAI, Speaches, Kokoro-FastAPI, …) and file a
|
|
7
|
+
[server report](https://github.com/IMJONEZZ/interaction-harness/issues/new?template=server-report.yml)
|
|
8
|
+
with the output.
|
|
9
|
+
- **Backends.** In-process speech on other hardware or with other models. See
|
|
10
|
+
[docs/backends.md](docs/backends.md).
|
|
11
|
+
- **Interaction-model experiments.** New end-of-turn policies, backchannel handling, or better barge-in
|
|
12
|
+
rules. `session.py` is the one place the policy lives.
|
|
13
|
+
|
|
14
|
+
## Setup
|
|
15
|
+
|
|
16
|
+
```bash
|
|
17
|
+
git clone https://github.com/IMJONEZZ/interaction-harness && cd interaction-harness
|
|
18
|
+
uv sync # Python 3.11-3.13
|
|
19
|
+
uv run pytest # unit tests: fakes and stubs, no models, no network
|
|
20
|
+
uv run ruff check src tests examples
|
|
21
|
+
```
|
|
22
|
+
|
|
23
|
+
With a model server, check your change end to end:
|
|
24
|
+
|
|
25
|
+
```bash
|
|
26
|
+
uv run interaction-harness doctor --foreground-base-url http://127.0.0.1:8080/v1
|
|
27
|
+
uv run interaction-harness selftest --foreground-base-url http://127.0.0.1:8080/v1
|
|
28
|
+
```
|
|
29
|
+
|
|
30
|
+
`selftest` talks to the agent with synthesized speech, checking endpointing, tools, barge-in, background
|
|
31
|
+
delivery, timers, push-to-talk and typed turns. Some checks depend on the model's choices, such as which
|
|
32
|
+
tool it picks; those are warnings, not failures.
|
|
33
|
+
|
|
34
|
+
## Where things are
|
|
35
|
+
|
|
36
|
+
| Path | What it holds |
|
|
37
|
+
|---|---|
|
|
38
|
+
| `src/interaction_harness/session.py` | the interaction model: state machine, endpointing, barge-in, both models, proactive delivery |
|
|
39
|
+
| `src/interaction_harness/config.py` | settings and the four roles |
|
|
40
|
+
| `src/interaction_harness/llm.py` | the chat roles, the thinking switch, the end-of-turn judge |
|
|
41
|
+
| `src/interaction_harness/speech/` | VAD, and ASR and TTS on MLX, ONNX or an endpoint |
|
|
42
|
+
| `src/interaction_harness/tools/` | the tool registry, built-in tools, web search and fetch |
|
|
43
|
+
| `src/interaction_harness/static/` | the dashboard: vanilla JS, no build step |
|
|
44
|
+
| `tests/` | unit tests; `conftest.py` has fakes for every model role |
|
|
45
|
+
|
|
46
|
+
## Style
|
|
47
|
+
|
|
48
|
+
Keep the dashboard dependency-free, and keep the state machine readable. If a change affects latency,
|
|
49
|
+
say how you measured it; the waterfall and `doctor` are there for that.
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Chris Brousseau
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,269 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: interaction-harness
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: A voice agent whose interaction model (turn-taking, barge-in, background work) is visible and swappable
|
|
5
|
+
Project-URL: Homepage, https://github.com/IMJONEZZ/interaction-harness
|
|
6
|
+
Project-URL: Source, https://github.com/IMJONEZZ/interaction-harness
|
|
7
|
+
Project-URL: Issues, https://github.com/IMJONEZZ/interaction-harness/issues
|
|
8
|
+
Author: Chris Brousseau
|
|
9
|
+
License-Expression: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
License-File: src/interaction_harness/speech/assets/SILERO_VAD_LICENSE
|
|
12
|
+
Keywords: barge-in,end-of-turn,llm,openai-compatible,speech,turn-taking,voice agent
|
|
13
|
+
Classifier: Development Status :: 3 - Alpha
|
|
14
|
+
Classifier: Environment :: Web Environment
|
|
15
|
+
Classifier: Intended Audience :: Developers
|
|
16
|
+
Classifier: Intended Audience :: Science/Research
|
|
17
|
+
Classifier: Operating System :: MacOS
|
|
18
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
19
|
+
Classifier: Programming Language :: Python :: 3
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
22
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
23
|
+
Classifier: Topic :: Multimedia :: Sound/Audio :: Speech
|
|
24
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
25
|
+
Requires-Python: <3.14,>=3.11
|
|
26
|
+
Requires-Dist: ddgs>=9
|
|
27
|
+
Requires-Dist: fastapi>=0.110
|
|
28
|
+
Requires-Dist: httpx>=0.27
|
|
29
|
+
Requires-Dist: kokoro-onnx>=0.4
|
|
30
|
+
Requires-Dist: misaki[en]>=0.9; sys_platform == 'darwin' and platform_machine == 'arm64'
|
|
31
|
+
Requires-Dist: mlx-audio>=0.5; sys_platform == 'darwin' and platform_machine == 'arm64'
|
|
32
|
+
Requires-Dist: numpy>=1.26
|
|
33
|
+
Requires-Dist: onnx-asr[hub]>=0.10
|
|
34
|
+
Requires-Dist: onnxruntime>=1.18
|
|
35
|
+
Requires-Dist: openai>=1.66
|
|
36
|
+
Requires-Dist: parakeet-mlx>=0.5; sys_platform == 'darwin' and platform_machine == 'arm64'
|
|
37
|
+
Requires-Dist: pypdf>=5
|
|
38
|
+
Requires-Dist: python-dotenv>=1.0
|
|
39
|
+
Requires-Dist: soundfile>=0.12
|
|
40
|
+
Requires-Dist: uvicorn[standard]>=0.29
|
|
41
|
+
Requires-Dist: websockets>=13
|
|
42
|
+
Provides-Extra: onnx-gpu
|
|
43
|
+
Requires-Dist: onnxruntime-gpu>=1.18; extra == 'onnx-gpu'
|
|
44
|
+
Description-Content-Type: text/markdown
|
|
45
|
+
|
|
46
|
+
# interaction-harness
|
|
47
|
+
|
|
48
|
+
A voice agent whose **interaction model** is visible and swappable: when it decides you've finished
|
|
49
|
+
talking, how it lets you cut in, and how it keeps the conversation going while a second model works on
|
|
50
|
+
something hard and then brings the answer up on its own.
|
|
51
|
+
|
|
52
|
+
Every model it uses is an **OpenAI-compatible endpoint you choose**: speech-to-text, text-to-speech,
|
|
53
|
+
the foreground model that holds the conversation, and the background model it hands work to. Speech can
|
|
54
|
+
also run in-process, on Apple Silicon (MLX) or anywhere else (ONNX).
|
|
55
|
+
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
<sub>A real session on one Mac, every model live: Parakeet and Kokoro in-process, Qwen3.6-35B-A3B on
|
|
59
|
+
llama.cpp as both foreground and background. The user's lines are spoken by Kokoro through Chrome's fake
|
|
60
|
+
microphone. Real time, no cuts.</sub>
|
|
61
|
+
|
|
62
|
+
## What it shows
|
|
63
|
+
|
|
64
|
+
- **Turn-taking you can switch mid-conversation.** Push-to-talk, a VAD silence timeout, or *semantic
|
|
65
|
+
end-of-turn*: after 300 ms of silence the foreground model reads the transcript and answers COMPLETE or
|
|
66
|
+
INCOMPLETE, so "I was wondering whether…" keeps the floor with you.
|
|
67
|
+
- **Barge-in that keeps the history honest.** About 190 ms of confident speech over the agent stops the
|
|
68
|
+
model, the TTS queue and playback. The history keeps only what you actually heard, so the model never
|
|
69
|
+
quotes a reply it didn't finish.
|
|
70
|
+
- **A foreground and a background model.** The foreground answers in a sentence or two and hands real
|
|
71
|
+
work (analysis, planning, research with web search) to the background model, then keeps chatting. When
|
|
72
|
+
the background result is ready and you go quiet, the agent takes its own turn to tell you. Timers work
|
|
73
|
+
the same way.
|
|
74
|
+
- **Every step on screen.** VAD probability, partial and final transcripts, the judge's verdicts, streamed
|
|
75
|
+
tokens and reasoning, tool calls, the TTS queue (struck through when you interrupt), background tasks,
|
|
76
|
+
and a per-turn latency waterfall from the end of your speech to the first audio.
|
|
77
|
+
|
|
78
|
+
## Four model roles, four endpoints
|
|
79
|
+
|
|
80
|
+
| Role | What it does | OpenAI-compatible API | If left blank |
|
|
81
|
+
|---|---|---|---|
|
|
82
|
+
| `ASR` | speech → text | `POST /v1/audio/transcriptions` | Parakeet TDT 0.6B v3, in-process |
|
|
83
|
+
| `TTS` | text → speech | `POST /v1/audio/speech` | Kokoro-82M, in-process |
|
|
84
|
+
| `FOREGROUND` | holds the conversation, calls quick tools, hands off; also judges end-of-turn | `POST /v1/chat/completions` | required |
|
|
85
|
+
| `BACKGROUND` | works on handed-off tasks with thinking on; can browse | `POST /v1/chat/completions` | the foreground's server and model |
|
|
86
|
+
|
|
87
|
+
Each role takes `<ROLE>_BASE_URL`, `<ROLE>_API_KEY` and `<ROLE>_MODEL`, so you can mix them freely. For
|
|
88
|
+
example, run ASR on a GPU box, TTS on your laptop, the foreground on a small fast local model, and the
|
|
89
|
+
background on a large model in the cloud. A key is only ever sent to the host it was set for.
|
|
90
|
+
|
|
91
|
+
Voice activity detection is the one model that is not a role. It runs on every 32 ms of microphone audio,
|
|
92
|
+
so a network round trip would break endpointing, and there is no OpenAI API for it. Silero VAD runs
|
|
93
|
+
in-process on onnxruntime, on every platform, with no torch.
|
|
94
|
+
|
|
95
|
+
## Quickstart
|
|
96
|
+
|
|
97
|
+
You need:
|
|
98
|
+
|
|
99
|
+
- Python 3.11–3.13 and [uv](https://docs.astral.sh/uv/)
|
|
100
|
+
- Chrome or Safari
|
|
101
|
+
- an OpenAI-compatible chat server that streams and supports tool calls, such as llama.cpp's
|
|
102
|
+
`llama-server --jinja`, vLLM, LM Studio, Ollama, or a hosted API
|
|
103
|
+
|
|
104
|
+
Headphones make barge-in reliable.
|
|
105
|
+
|
|
106
|
+
**All speech local (Mac or Linux).** In-process speech is MLX on Apple Silicon and ONNX everywhere else,
|
|
107
|
+
picked automatically. Models download on first use.
|
|
108
|
+
|
|
109
|
+
```bash
|
|
110
|
+
uv tool install git+https://github.com/IMJONEZZ/interaction-harness
|
|
111
|
+
interaction-harness doctor --foreground-base-url http://127.0.0.1:8080/v1 # checks every role
|
|
112
|
+
interaction-harness serve --foreground-base-url http://127.0.0.1:8080/v1 --open
|
|
113
|
+
```
|
|
114
|
+
|
|
115
|
+
**On a remote GPU box.** Browsers only allow the microphone on `localhost` or HTTPS. Either tunnel the
|
|
116
|
+
port (`ssh -L 8765:localhost:8765 gpu-box`) and open http://localhost:8765, or pass
|
|
117
|
+
`--ssl-certfile/--ssl-keyfile`.
|
|
118
|
+
|
|
119
|
+
**Every role on an endpoint.**
|
|
120
|
+
|
|
121
|
+
```bash
|
|
122
|
+
export FOREGROUND_BASE_URL=http://127.0.0.1:8080/v1 # fast model, thinking off
|
|
123
|
+
export BACKGROUND_BASE_URL=http://gpu-box:8000/v1 BACKGROUND_MODEL=your/reasoning-model
|
|
124
|
+
export ASR_BASE_URL=http://speech-box:8000/v1 ASR_MODEL=your/transcription-model
|
|
125
|
+
export TTS_BASE_URL=http://speech-box:8000/v1 TTS_MODEL=your/speech-model TTS_VOICE=af_heart
|
|
126
|
+
interaction-harness serve --open
|
|
127
|
+
```
|
|
128
|
+
|
|
129
|
+
Settings come from flags, then the environment, then `.env` in the working directory, then
|
|
130
|
+
`interaction-harness.toml`. [`.env.example`](https://github.com/IMJONEZZ/interaction-harness/blob/main/.env.example) lists every setting, and
|
|
131
|
+
[`examples/interaction-harness.toml`](https://github.com/IMJONEZZ/interaction-harness/blob/main/examples/interaction-harness.toml) shows a config file.
|
|
132
|
+
|
|
133
|
+
### Try this
|
|
134
|
+
|
|
135
|
+
1. Start the mic and say *"What time is it?"* Watch the VAD bar, the partial transcript, the judge's
|
|
136
|
+
`COMPLETE`, the `get_time` tool card, the first TTS chunk, and the waterfall row.
|
|
137
|
+
2. Say *"I was wondering whether…"* and pause. The judge answers `INCOMPLETE` and the floor stays with you.
|
|
138
|
+
3. Ask for a long story, then talk over it. The reply stops, the sentences you didn't hear are struck
|
|
139
|
+
through, and the Brain panel marks the message ✂.
|
|
140
|
+
4. Say *"In the background, compare a 15-year and a 30-year mortgage on 400k and tell me which costs less
|
|
141
|
+
in interest. Also remind me in 20 seconds to stretch."* Keep chatting. The Background panel streams the
|
|
142
|
+
background model's reasoning, and when it's done and you go quiet, the agent brings it up on its own.
|
|
143
|
+
5. Switch to **VAD timeout** and repeat step 1, then compare the endpointing segment in the waterfall.
|
|
144
|
+
|
|
145
|
+
## Commands
|
|
146
|
+
|
|
147
|
+
| Command | What it does |
|
|
148
|
+
|---|---|
|
|
149
|
+
| `interaction-harness serve` | the dashboard and voice server (default http://localhost:8765) |
|
|
150
|
+
| `interaction-harness doctor` | checks each role on its own: streaming, tool calls, the end-of-turn judge, a TTS → ASR round trip, VAD; reports latency |
|
|
151
|
+
| `interaction-harness selftest` | talks to the agent with synthesized speech and checks endpointing, tools, barge-in, background delivery, timers, push-to-talk and typed turns |
|
|
152
|
+
| `interaction-harness warmup` | downloads and loads the in-process speech models, then exits |
|
|
153
|
+
|
|
154
|
+
They all take the same settings flags (`--foreground-base-url`, `--asr-model`, `--backend onnx`, …).
|
|
155
|
+
`interaction-harness serve --help` lists them.
|
|
156
|
+
|
|
157
|
+
## Your own tools
|
|
158
|
+
|
|
159
|
+
```python
|
|
160
|
+
# my_tools.py, loaded with: interaction-harness serve --tools my_tools.py
|
|
161
|
+
from typing import Annotated
|
|
162
|
+
from interaction_harness.tools import tool
|
|
163
|
+
|
|
164
|
+
@tool
|
|
165
|
+
def stock_level(sku: Annotated[str, "the product code"]) -> dict:
|
|
166
|
+
"""How many of a product are in stock."""
|
|
167
|
+
return {"sku": sku, "in_stock": 12}
|
|
168
|
+
|
|
169
|
+
@tool(lanes=["background"]) # only the background model may call this one
|
|
170
|
+
async def search_tickets(query: str, limit: int = 5) -> list[dict]:
|
|
171
|
+
"""Search the support ticket system."""
|
|
172
|
+
...
|
|
173
|
+
```
|
|
174
|
+
|
|
175
|
+
The JSON schema comes from the signature and the description from the docstring. See
|
|
176
|
+
[docs/tools.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/tools.md).
|
|
177
|
+
|
|
178
|
+
## Measured latency
|
|
179
|
+
|
|
180
|
+
Latency here is the time from the end of your speech to the first audio, as the waterfall measures it.
|
|
181
|
+
That includes 300 ms of silence before the judge is asked, then the judge, ASR, the foreground model's
|
|
182
|
+
first sentence, and the first TTS chunk.
|
|
183
|
+
|
|
184
|
+
The numbers below are the median of 10 short spoken turns with no tools, in semantic mode. They were
|
|
185
|
+
measured on an M5 Max MacBook Pro, plugged in and otherwise idle, with Qwen3.6-35B-A3B (UD-Q8_K_XL,
|
|
186
|
+
llama.cpp via Unsloth Studio) as the foreground model.
|
|
187
|
+
|
|
188
|
+
| Speech | Median | Range |
|
|
189
|
+
|---|---|---|
|
|
190
|
+
| In-process MLX | 908 ms | 741–1,780 ms |
|
|
191
|
+
| In-process ONNX on CPU (int8) | 909 ms | 795–1,571 ms |
|
|
192
|
+
| ASR + TTS on an endpoint (mlx-audio server, same machine) | 787 ms | 734–1,060 ms |
|
|
193
|
+
|
|
194
|
+
On a machine this fast the three are within noise of each other. About 500 ms of a typical turn is deciding
|
|
195
|
+
that you've finished: the 300 ms of silence, then the judge. That is the place to tune first. Turns that
|
|
196
|
+
call a tool add a model round trip; the waterfall shows each segment.
|
|
197
|
+
|
|
198
|
+
## Tested with
|
|
199
|
+
|
|
200
|
+
| Role | Server or backend | Status |
|
|
201
|
+
|---|---|---|
|
|
202
|
+
| foreground, background | llama.cpp (Unsloth Studio), Qwen3.6-35B-A3B | tested: `doctor`, `selftest` |
|
|
203
|
+
| background | vLLM, GLM-5.3-Flash (FP4) on a DGX Spark | tested: `doctor`, `selftest` |
|
|
204
|
+
| ASR, TTS | mlx-audio 0.6.4 server (Parakeet, Kokoro) | tested: `doctor`, `selftest` |
|
|
205
|
+
| in-process speech | MLX on Apple Silicon (macOS) | tested: `doctor`, `selftest` |
|
|
206
|
+
| in-process speech | ONNX on CPU, macOS arm64 | tested: `doctor`, `selftest` |
|
|
207
|
+
| in-process speech | ONNX on CPU, Linux x86_64 | tested in CI: `warmup` round trip |
|
|
208
|
+
| in-process speech | ONNX on CPU, Linux arm64 (DGX Spark) | not yet tested |
|
|
209
|
+
| foreground, background | Ollama, LM Studio | built on llama.cpp, the engine tested above |
|
|
210
|
+
| any role | OpenAI, Speaches, Kokoro-FastAPI, other servers | untested; should work if they implement the endpoint. Run `doctor`, and please [report what you find](https://github.com/IMJONEZZ/interaction-harness/issues/new?template=server-report.yml) |
|
|
211
|
+
|
|
212
|
+
How a server switches thinking on and off varies. Set `FOREGROUND_THINKING` / `BACKGROUND_THINKING` to
|
|
213
|
+
`chat_template_kwargs` (vLLM, llama.cpp, SGLang with Qwen- or GLM-style templates), `reasoning_effort`, or
|
|
214
|
+
`off`. See [docs/endpoints.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/endpoints.md).
|
|
215
|
+
|
|
216
|
+
## Where this fits
|
|
217
|
+
|
|
218
|
+
[Pipecat](https://github.com/pipecat-ai/pipecat) and [LiveKit Agents](https://github.com/livekit/agents)
|
|
219
|
+
are production frameworks for shipping voice agents. This is a harness for *studying and tuning* the
|
|
220
|
+
interaction model:
|
|
221
|
+
|
|
222
|
+
- the whole turn-taking policy is one readable state machine
|
|
223
|
+
([`session.py`](https://github.com/IMJONEZZ/interaction-harness/blob/main/src/interaction_harness/session.py))
|
|
224
|
+
- every decision streams to the dashboard
|
|
225
|
+
- every model is swappable through the same OpenAI API you already run
|
|
226
|
+
|
|
227
|
+
Use it to choose an end-of-turn policy, measure what barge-in or a background model costs, or try a new
|
|
228
|
+
model in a real conversation before you build it into something bigger.
|
|
229
|
+
|
|
230
|
+
[docs/interaction-models.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/interaction-models.md) covers the background: what "interaction model"
|
|
231
|
+
means, the turn-taking regimes in use today, and the latency budgets people cite.
|
|
232
|
+
|
|
233
|
+
### Where it stops short
|
|
234
|
+
|
|
235
|
+
This is a cascade, and a cascade has limits that a native full-duplex model doesn't:
|
|
236
|
+
|
|
237
|
+
- no backchannel while you talk
|
|
238
|
+
- no overlapping speech
|
|
239
|
+
- no reaction to *how* you said something, because ASR drops prosody
|
|
240
|
+
- the end-of-turn judge only sees text
|
|
241
|
+
|
|
242
|
+
In exchange you get a swappable brain, tools, auditability, and a latency budget you can see.
|
|
243
|
+
|
|
244
|
+
## Docs
|
|
245
|
+
|
|
246
|
+
- [docs/endpoints.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/endpoints.md): the four roles, keys, thinking switches, and server notes
|
|
247
|
+
- [docs/backends.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/backends.md): in-process speech on MLX and ONNX, model variants, GPUs
|
|
248
|
+
- [docs/protocol.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/protocol.md): the WebSocket protocol, if you want your own front end
|
|
249
|
+
- [docs/tools.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/tools.md): writing tools, and how the background hand-off and timers work
|
|
250
|
+
- [docs/interaction-models.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/docs/interaction-models.md): background reading
|
|
251
|
+
- [CONTRIBUTING.md](https://github.com/IMJONEZZ/interaction-harness/blob/main/CONTRIBUTING.md)
|
|
252
|
+
|
|
253
|
+
## Credits
|
|
254
|
+
|
|
255
|
+
| Component | By | License |
|
|
256
|
+
|---|---|---|
|
|
257
|
+
| [Parakeet TDT 0.6B v3](https://huggingface.co/nvidia/parakeet-tdt-0.6b-v3) | NVIDIA | CC-BY-4.0 |
|
|
258
|
+
| [Kokoro-82M](https://huggingface.co/hexgrad/Kokoro-82M) | hexgrad | Apache-2.0 |
|
|
259
|
+
| [Silero VAD](https://github.com/snakers4/silero-vad) (its ONNX model ships in this package) | Silero Team | MIT |
|
|
260
|
+
| [parakeet-mlx](https://github.com/senstella/parakeet-mlx) | senstella | Apache-2.0 |
|
|
261
|
+
| [mlx-audio](https://github.com/Blaizzy/mlx-audio) | Blaizzy | MIT |
|
|
262
|
+
| [onnx-asr](https://github.com/istupakov/onnx-asr) | istupakov | MIT |
|
|
263
|
+
| [kokoro-onnx](https://github.com/thewh1teagle/kokoro-onnx) | thewh1teagle | MIT |
|
|
264
|
+
|
|
265
|
+
The web tools follow the design of Unsloth Studio's, re-implemented from scratch.
|
|
266
|
+
|
|
267
|
+
## License
|
|
268
|
+
|
|
269
|
+
MIT. See [LICENSE](https://github.com/IMJONEZZ/interaction-harness/blob/main/LICENSE).
|