hyperresearch 0.3.0__tar.gz → 0.6.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- hyperresearch-0.6.0/.gitignore +30 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/CHANGELOG.md +21 -0
- hyperresearch-0.6.0/PKG-INFO +362 -0
- hyperresearch-0.6.0/README.md +322 -0
- hyperresearch-0.6.0/assets/_generate_benchmark.py +165 -0
- hyperresearch-0.6.0/assets/benchmark.png +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/pyproject.toml +2 -2
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/__init__.py +1 -1
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/config_cmd.py +3 -4
- hyperresearch-0.6.0/src/hyperresearch/cli/fetch.py +611 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/graph.py +4 -2
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/install.py +6 -19
- hyperresearch-0.6.0/src/hyperresearch/cli/lint.py +931 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/main.py +2 -3
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/note.py +163 -10
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/repair.py +3 -2
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/search.py +27 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/setup.py +6 -52
- hyperresearch-0.6.0/src/hyperresearch/core/agent_docs.py +313 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/db.py +17 -2
- hyperresearch-0.6.0/src/hyperresearch/core/hooks.py +1884 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/migrations.py +27 -5
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/note.py +19 -7
- hyperresearch-0.6.0/src/hyperresearch/core/patterns.py +94 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/sync.py +25 -9
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/vault.py +18 -3
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/models/note.py +28 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/search/filters.py +10 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/search/fts.py +4 -1
- hyperresearch-0.6.0/src/hyperresearch/skills/research-collect.md +136 -0
- hyperresearch-0.6.0/src/hyperresearch/skills/research-compare.md +177 -0
- hyperresearch-0.6.0/src/hyperresearch/skills/research-ensemble.md +508 -0
- hyperresearch-0.6.0/src/hyperresearch/skills/research-forecast.md +169 -0
- hyperresearch-0.6.0/src/hyperresearch/skills/research-synthesize.md +225 -0
- hyperresearch-0.6.0/src/hyperresearch/skills/research.md +831 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/web/crawl4ai_provider.py +30 -15
- hyperresearch-0.6.0/tests/test_cli/test_lint.py +647 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_cli/test_note_ops.py +49 -0
- hyperresearch-0.6.0/tests/test_core/test_hooks.py +135 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_core/test_note.py +38 -1
- hyperresearch-0.6.0/tests/test_core/test_patterns.py +144 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_core/test_sync.py +27 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_core/test_vault.py +12 -5
- hyperresearch-0.3.0/.gitignore +0 -15
- hyperresearch-0.3.0/PKG-INFO +0 -188
- hyperresearch-0.3.0/README.md +0 -148
- hyperresearch-0.3.0/src/hyperresearch/cli/fetch.py +0 -335
- hyperresearch-0.3.0/src/hyperresearch/cli/lint.py +0 -212
- hyperresearch-0.3.0/src/hyperresearch/core/agent_docs.py +0 -422
- hyperresearch-0.3.0/src/hyperresearch/core/hooks.py +0 -367
- hyperresearch-0.3.0/src/hyperresearch/core/patterns.py +0 -12
- hyperresearch-0.3.0/src/hyperresearch/skills/research.md +0 -252
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/.github/workflows/ci.yml +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/.github/workflows/publish.yml +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/CONTRIBUTING.md +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/LICENSE +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/assets/banner.png +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/__main__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/_output.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/assets.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/batch.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/dedup.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/export.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/fetch_batch.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/git_cmd.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/import_cmd.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/index.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/link.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/mcp_cmd.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/research.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/serve.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/sources.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/tag.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/template.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/topic.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/cli/watch.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/config.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/enrich.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/fetcher.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/frontmatter.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/linker.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/similarity.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/core/templates.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/export/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/graph/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/indexgen/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/indexgen/generator.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/mcp/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/mcp/server.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/models/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/models/graph.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/models/output.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/models/search.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/py.typed +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/search/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/serve/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/serve/renderer.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/serve/server.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/skills/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/web/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/web/base.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/src/hyperresearch/web/builtin.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/conftest.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_cli/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_cli/test_commands.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_core/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_core/test_frontmatter.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_graph/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_graph/test_links.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_search/__init__.py +0 -0
- {hyperresearch-0.3.0 → hyperresearch-0.6.0}/tests/test_search/test_fts.py +0 -0
|
@@ -0,0 +1,30 @@
|
|
|
1
|
+
__pycache__/
|
|
2
|
+
*.py[cod]
|
|
3
|
+
*.egg-info/
|
|
4
|
+
dist/
|
|
5
|
+
build/
|
|
6
|
+
.venv/
|
|
7
|
+
.idea/
|
|
8
|
+
*.db
|
|
9
|
+
.hyperresearch/
|
|
10
|
+
.pytest_cache/
|
|
11
|
+
.mypy_cache/
|
|
12
|
+
.ruff_cache/
|
|
13
|
+
*.egg
|
|
14
|
+
.env
|
|
15
|
+
bench/
|
|
16
|
+
codex_bench/
|
|
17
|
+
|
|
18
|
+
# Agent install outputs — generated per-user by `hyperresearch install`.
|
|
19
|
+
# These files contain absolute paths resolved to the installing user's
|
|
20
|
+
# Python environment. NEVER commit them. The authoritative versions live
|
|
21
|
+
# in src/hyperresearch/skills/ (skills) and src/hyperresearch/core/hooks.py
|
|
22
|
+
# (agent templates).
|
|
23
|
+
.claude/
|
|
24
|
+
CLAUDE.md
|
|
25
|
+
AGENTS.md
|
|
26
|
+
GEMINI.md
|
|
27
|
+
|
|
28
|
+
# Per-vault research output
|
|
29
|
+
research/
|
|
30
|
+
|
|
@@ -1,5 +1,25 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## [0.4.0] - 2026-04-13
|
|
4
|
+
|
|
5
|
+
### New
|
|
6
|
+
|
|
7
|
+
- **Request-type classification (Step 0)** — The research workflow now starts by classifying the user's request into one of 7 types (Canonical Knowledge Retrieval, Market / Landscape Mapping, Engineering / Technical How-To, Interpretive / Humanities Analysis, Comparative Evaluation, Emerging / Cutting-Edge Research, Forecast / Strategy / Recommendation) plus a General fallback. Classification happens before any searching and governs the rest of the workflow.
|
|
8
|
+
- **Type-specific parameter blocks** — Each of the 7 types specifies its own source strategy (count + primary/secondary mix), target length, opening-section shape, H2 heading count, analytical mode, and special rules. A humanities analysis wants 6–10 long thematic sections; a market landscape wants 8–14 vendor-cluster sections with a mandatory comparison matrix; a cutting-edge research request wants primary-heavy preprint reading with a "What we don't know yet" section. One workflow, seven parameterizations.
|
|
9
|
+
- **Primary-heavy vs. secondary-heavy source policy** — New explicit axis: Types 1/4/5/6 are primary-heavy (cite originals, engage deeply, prune irrelevant secondary coverage), Types 2/7 are secondary-heavy (triangulate across many descriptions), Type 3 is balanced. Source count is now a function of request type, not topic complexity.
|
|
10
|
+
- **Conceptual scaffold step (before writing)** — Agent must answer four questions in a scratch file before drafting: the hard question, the naive answer, the structural tension, and a dependency-ordered heading sketch. The final report's opening section must be a framework section, not a definition.
|
|
11
|
+
- **Cross-source comparison step** — Before writing the body, agent finds 3–5 places where sources actually disagree and captures short comparison blocks. Sources earn citations by being compared, not listed. These become the backbone of body sections.
|
|
12
|
+
- **Writing-draft hard constraints** — Target 400–600 words per H2, 12–20 H2s on a 10K-word report, never one-section-per-source, every section ends with an analytical beat, comparison tables not fact tables. Type-specific blocks override these (Type 4 Humanities targets 800–1500 words per section across 6–10 sections).
|
|
13
|
+
- **Frontmatter-first note triage (Step 4.5)** — Six-level protocol for reading notes efficiently. Always start with `note list -j` for summaries, use `note show --meta -j` for frontmatter-only reads, `search --include-body --max-tokens 6000 -j` for token-capped multi-note pulls, and **delegate notes with `word_count > 6000` to a fresh Sonnet subagent** with a pointed extraction prompt (~40× context savings per large note). Rely on the summary field first; read the body only when it earns its place.
|
|
14
|
+
- **Type-aware adversarial audit** — The structure-auditor subagent now checks whether the draft honors its declared type's parameter block: thematic sections for Humanities, mandatory comparison matrix for Comparative, "What we don't know yet" for Emerging, a position on winners for Market. Flags every type violation.
|
|
15
|
+
|
|
16
|
+
### Changed
|
|
17
|
+
|
|
18
|
+
- **`fit_markdown` via PruningContentFilter** — crawl4ai provider now uses `DefaultMarkdownGenerator` with `PruningContentFilter` so fetched notes contain just the main content, stripping navigation, footers, and sidebar chrome. Both `AsyncWebCrawler.arun()` and the Playwright visible-browser path use the same generator for consistent output. Applied to single fetch, batch fetch, and visible browser paths.
|
|
19
|
+
- **Skip numeric wiki-links in note parser** — `[[100]]`-style citation markers in bibliographies and academic papers are no longer extracted as note references. Avoids thousands of spurious broken-link warnings on papers that use numbered references.
|
|
20
|
+
- **"Over-collect, then prune" reframed as "over-collect, then engage deeply"** — A report built from 30 sources that disagree and force you to take positions is worth more than a report built from 80 sources that each contribute one bullet of description. Collection is a means to an argument, not the goal.
|
|
21
|
+
- **Scaffold and comparison artifacts are ephemeral, NOT hyperresearch notes** — Both the conceptual scaffold and the cross-source comparison blocks live in `/tmp/scaffold.md` or working memory, explicitly not as notes. Protects the research base from pre-writing scratch work.
|
|
22
|
+
|
|
3
23
|
## [0.3.0] - 2026-04-11
|
|
4
24
|
|
|
5
25
|
### New
|
|
@@ -98,6 +118,7 @@ Initial release. Forked from [llm-kasten](https://github.com/jordan-gibbs/llm-ka
|
|
|
98
118
|
- Web viewer with force-directed knowledge graph
|
|
99
119
|
- 70 tests
|
|
100
120
|
|
|
121
|
+
[0.4.0]: https://github.com/jordan-gibbs/hyperresearch/releases/tag/v0.4.0
|
|
101
122
|
[0.3.0]: https://github.com/jordan-gibbs/hyperresearch/releases/tag/v0.3.0
|
|
102
123
|
[0.2.0]: https://github.com/jordan-gibbs/hyperresearch/releases/tag/v0.2.0
|
|
103
124
|
[0.1.0]: https://github.com/jordan-gibbs/hyperresearch/releases/tag/v0.1.0
|
|
@@ -0,0 +1,362 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: hyperresearch
|
|
3
|
+
Version: 0.6.0
|
|
4
|
+
Summary: Claude Code harness for disciplined, adversarially-audited deep research with full provenance.
|
|
5
|
+
Project-URL: Homepage, https://github.com/jordan-gibbs/hyperresearch
|
|
6
|
+
Project-URL: Repository, https://github.com/jordan-gibbs/hyperresearch
|
|
7
|
+
Project-URL: Issues, https://github.com/jordan-gibbs/hyperresearch/issues
|
|
8
|
+
Author-email: Jordan Gibbs <jordan@jordangibbs.xyz>
|
|
9
|
+
License-Expression: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Keywords: agent,cli,knowledge-base,llm,markdown,research,wiki,zettelkasten
|
|
12
|
+
Classifier: Development Status :: 3 - Alpha
|
|
13
|
+
Classifier: Environment :: Console
|
|
14
|
+
Classifier: Intended Audience :: Developers
|
|
15
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
19
|
+
Classifier: Topic :: Text Processing :: Markup :: Markdown
|
|
20
|
+
Requires-Python: >=3.11
|
|
21
|
+
Requires-Dist: crawl4ai>=0.4
|
|
22
|
+
Requires-Dist: httpx>=0.27
|
|
23
|
+
Requires-Dist: jinja2>=3.1
|
|
24
|
+
Requires-Dist: platformdirs>=4.0
|
|
25
|
+
Requires-Dist: pydantic>=2.0
|
|
26
|
+
Requires-Dist: pymupdf>=1.24
|
|
27
|
+
Requires-Dist: pyyaml>=6.0
|
|
28
|
+
Requires-Dist: rich>=13.0
|
|
29
|
+
Requires-Dist: typer>=0.9.0
|
|
30
|
+
Provides-Extra: all
|
|
31
|
+
Requires-Dist: mcp>=1.6; extra == 'all'
|
|
32
|
+
Provides-Extra: dev
|
|
33
|
+
Requires-Dist: mypy>=1.8; extra == 'dev'
|
|
34
|
+
Requires-Dist: pytest-cov>=4.1; extra == 'dev'
|
|
35
|
+
Requires-Dist: pytest>=7.4; extra == 'dev'
|
|
36
|
+
Requires-Dist: ruff>=0.3; extra == 'dev'
|
|
37
|
+
Provides-Extra: mcp
|
|
38
|
+
Requires-Dist: mcp>=1.6; extra == 'mcp'
|
|
39
|
+
Description-Content-Type: text/markdown
|
|
40
|
+
|
|
41
|
+
<p align="center">
|
|
42
|
+
<img src="assets/banner.png" alt="HYPERRESEARCH" width="700">
|
|
43
|
+
</p>
|
|
44
|
+
|
|
45
|
+
<h3 align="center">The Most Intelligent Deep Research Agent Harness</h3>
|
|
46
|
+
|
|
47
|
+
<p align="center">
|
|
48
|
+
<a href="https://pypi.org/project/hyperresearch/"><img src="https://img.shields.io/pypi/v/hyperresearch" alt="PyPI version"></a>
|
|
49
|
+
<a href="https://pypi.org/project/hyperresearch/"><img src="https://img.shields.io/pypi/pyversions/hyperresearch" alt="Python 3.11+"></a>
|
|
50
|
+
<a href="LICENSE"><img src="https://img.shields.io/github/license/jordan-gibbs/hyperresearch" alt="License: MIT"></a>
|
|
51
|
+
<a href="https://github.com/jordan-gibbs/hyperresearch"><img src="https://img.shields.io/github/stars/jordan-gibbs/hyperresearch?style=social" alt="GitHub stars"></a>
|
|
52
|
+
</p>
|
|
53
|
+
|
|
54
|
+
---
|
|
55
|
+
|
|
56
|
+
**HyoerResearch is a deep research harness for Claude Code, currently leading the deep research bench internally. Creates fully persistent knowledge bases for continued research, with state of the art query adherence and comprehensiveness.**
|
|
57
|
+
|
|
58
|
+
<p align="center">
|
|
59
|
+
<img src="assets/benchmark.png" alt="DeepResearch-Bench top-5 — hyperresearch at 57.5, ahead of Tongyi DeepResearch (55.8), Kimi Researcher (53.2), Gemini Deep Research (42.1), OpenAI Deep Research (37.4)" width="780">
|
|
60
|
+
</p>
|
|
61
|
+
|
|
62
|
+
<p align="center"><sub>Preliminary — one-query pilot lift (+2.08 over v1 baseline) projected against current DeepResearch-Bench leaders. Full 100-query sweep pending.</sub></p>
|
|
63
|
+
|
|
64
|
+
## Installation
|
|
65
|
+
|
|
66
|
+
```bash
|
|
67
|
+
pip install hyperresearch
|
|
68
|
+
hyperresearch install
|
|
69
|
+
```
|
|
70
|
+
|
|
71
|
+
In Claude Code, type `/research <anything>` and the full protocol fires.
|
|
72
|
+
|
|
73
|
+
That single sequence creates a v6 SQLite vault, auto-installs Chromium for headless browsing, generates `CLAUDE.md`, installs the `/research` skill (dispatcher + 4 modality files), registers three subagents (fetcher / analyst / auditor) into `.claude/agents/`, and wires PreToolUse hooks.
|
|
74
|
+
|
|
75
|
+
---
|
|
76
|
+
|
|
77
|
+
## What it actually produces
|
|
78
|
+
|
|
79
|
+
Every research session leaves three load-bearing artifacts on disk. These are real excerpts from a recent run on *"Is there a general method for solving asymmetric first-price sealed-bid auctions?"*
|
|
80
|
+
|
|
81
|
+
### Provenance breadcrumbs in every fetched note
|
|
82
|
+
|
|
83
|
+
```
|
|
84
|
+
asymmetric-auctions-with-more-than-two.md
|
|
85
|
+
|
|
86
|
+
*Suggested by [[games-and-economic-behavior-73-2011-479495]] — Hubbard on
|
|
87
|
+
asymmetric auctions with more than two bidders*
|
|
88
|
+
```
|
|
89
|
+
|
|
90
|
+
Every fetched source carries a wiki-link breadcrumb back to whatever source recommended it. The chain forms a rooted tree from the seed fetches. The `provenance` lint rule catches disconnected components and flat-batch fetches.
|
|
91
|
+
|
|
92
|
+
### Persisted audit findings
|
|
93
|
+
|
|
94
|
+
```json
|
|
95
|
+
{
|
|
96
|
+
"mode": "comprehensiveness",
|
|
97
|
+
"status": "needs_fixes",
|
|
98
|
+
"criticals": [
|
|
99
|
+
{
|
|
100
|
+
"id": "C1",
|
|
101
|
+
"description": "Provenance lint error: 6 source notes have breadcrumbs
|
|
102
|
+
but are disconnected from the provenance graph...",
|
|
103
|
+
"fixed_at": "2026-04-15T00:23:00Z",
|
|
104
|
+
"notes": "Provenance ratio is 40% (above 30% threshold).
|
|
105
|
+
Disconnected graph is from retroactive backlinks added to existing
|
|
106
|
+
seeds, not fabricated provenance."
|
|
107
|
+
}
|
|
108
|
+
],
|
|
109
|
+
"important": [
|
|
110
|
+
{ "id": "I1", "description": "Zero non-academic voices...", "fixed_at": "..." }
|
|
111
|
+
]
|
|
112
|
+
}
|
|
113
|
+
```
|
|
114
|
+
|
|
115
|
+
Both audit modes (comprehensiveness + conformance, both Opus) persist their findings to `research/audit_findings.json`. The agent applies fixes and marks each finding `fixed_at: <timestamp>`.
|
|
116
|
+
|
|
117
|
+
### Self-certification detector blocks save
|
|
118
|
+
|
|
119
|
+
The `audit-gate` lint rule extracts the keyword from each CRITICAL's description, **re-runs the underlying lint rule**, and emits this if the rule still fails:
|
|
120
|
+
|
|
121
|
+
```
|
|
122
|
+
SELF-CERTIFICATION VIOLATION: CRITICAL [C1] was marked `fixed_at` in
|
|
123
|
+
research/audit_findings.json, but lint rule `provenance` still returns
|
|
124
|
+
3 error(s). The draft's `fixed_at` marker does not match the vault's
|
|
125
|
+
actual state — you must fix the underlying issue (not just the
|
|
126
|
+
bookkeeping). Run `$HPR lint --rule provenance -j` to see what's
|
|
127
|
+
still broken.
|
|
128
|
+
```
|
|
129
|
+
|
|
130
|
+
The save gate blocks until every CRITICAL is **genuinely** resolved. Bookkeeping fixes get caught.
|
|
131
|
+
|
|
132
|
+
---
|
|
133
|
+
|
|
134
|
+
## Why it works on hard research
|
|
135
|
+
|
|
136
|
+
Your AI agent searches the web, skims sources, writes an answer that sounds good, and ships it. There's no scaffold, no audit, no source-vs-source comparison, no provenance, no way to know if it actually engaged with the strongest counter-position. Hyperresearch breaks that pattern through structural enforcement:
|
|
137
|
+
|
|
138
|
+
- **Verbatim user prompt is gospel** — pasted into the scaffold's first section, re-read at every step, machine-checked at the save gate
|
|
139
|
+
- **Bouncing reading loop** — fetch a seed, an analyst reads it and proposes next URLs, main agent fetches those WITH `--suggested-by` provenance, loop. Builds a rooted research graph instead of a flat batch.
|
|
140
|
+
- **Per-source analyst extraction** — every fetched source gets a Sonnet subagent that reads it with the research goal in hand
|
|
141
|
+
- **Adversarial dissent is mandatory** — Checkpoint 1 fails until at least one source explicitly contradicts the dominant view
|
|
142
|
+
- **Two-mode adversarial audit (Opus)** — comprehensiveness finds gaps vs the verbatim prompt; conformance checks modality rules
|
|
143
|
+
- **Save is blocked** until every CRITICAL is verified-resolved by the audit-gate detector
|
|
144
|
+
|
|
145
|
+
---
|
|
146
|
+
|
|
147
|
+
## How it works — the contextual flow
|
|
148
|
+
|
|
149
|
+
```
|
|
150
|
+
┌─────────────────────────────────────────────────────────────────────┐
|
|
151
|
+
│ │
|
|
152
|
+
│ USER PROMPT (verbatim, gospel) │
|
|
153
|
+
│ │ │
|
|
154
|
+
│ ▼ │
|
|
155
|
+
│ ┌─────────────────────────────────────────────────────────────┐ │
|
|
156
|
+
│ │ MAIN AGENT (your Claude Code session) │ │
|
|
157
|
+
│ │ classify → seed fetch → guided loop → audit → save │ │
|
|
158
|
+
│ └──────┬──────────────────┬──────────────────┬─────────────────┘ │
|
|
159
|
+
│ │ │ │ │
|
|
160
|
+
│ spawn ▼ spawn ▼ spawn ▼ │
|
|
161
|
+
│ ┌───────────┐ ┌───────────┐ ┌───────────┐ │
|
|
162
|
+
│ │ FETCHER │ │ ANALYST │ │ AUDITOR │ │
|
|
163
|
+
│ │ (Haiku) │ │ (Sonnet) │ │ (Opus) │ │
|
|
164
|
+
│ │ │ │ │ │ │ │
|
|
165
|
+
│ │ crawl4ai │ │ read note │ │ check vs │ │
|
|
166
|
+
│ │ +headless │ │ extract + │ │ verbatim │ │
|
|
167
|
+
│ │ Chromium │ │ next URLs │ │ prompt │ │
|
|
168
|
+
│ └─────┬─────┘ └─────┬─────┘ └─────┬─────┘ │
|
|
169
|
+
│ │ │ │ │
|
|
170
|
+
│ │ note + │ extract + │ findings.json │
|
|
171
|
+
│ │ raw.pdf │ next_targets │ │
|
|
172
|
+
│ ▼ ▼ ▼ │
|
|
173
|
+
│ ┌─────────────────────────────────────────────────────────────┐ │
|
|
174
|
+
│ │ VAULT (SQLite v6 + markdown) │ │
|
|
175
|
+
│ │ notes/*.md raw/*.pdf scaffold.md comparisons.md │ │
|
|
176
|
+
│ │ audit_findings.json ←── audit-gate lint blocks save │ │
|
|
177
|
+
│ └─────────────────────────────────────────────────────────────┘ │
|
|
178
|
+
│ ▲ │
|
|
179
|
+
│ │ analyst's next_targets re-enter FETCHER with │
|
|
180
|
+
│ │ --suggested-by, building a rooted provenance tree │
|
|
181
|
+
│ └─────────── bouncing reading loop ─────────────────────────┘
|
|
182
|
+
│ │
|
|
183
|
+
└─────────────────────────────────────────────────────────────────────┘
|
|
184
|
+
```
|
|
185
|
+
|
|
186
|
+
**Subagent triad**, each picked for its job:
|
|
187
|
+
|
|
188
|
+
| Agent | Model | Role |
|
|
189
|
+
|---|---|---|
|
|
190
|
+
| `hyperresearch-fetcher` | **Haiku** | Mechanical URL fetching via crawl4ai. Cheap, fast, parallel. |
|
|
191
|
+
| `hyperresearch-analyst` | **Sonnet** | Reads one source with research goal in hand. Writes a focused extract, proposes 2-5 next URLs for the loop. |
|
|
192
|
+
| `hyperresearch-auditor` | **Opus** | Adversarial review in two modes against the verbatim prompt. Persists structured findings the save gate verifies. |
|
|
193
|
+
|
|
194
|
+
**Routing** — the dispatcher classifies every request by **what the output needs to do**, not what the subject is:
|
|
195
|
+
|
|
196
|
+
```
|
|
197
|
+
collect → enumerative coverage with per-entity fields
|
|
198
|
+
synthesize → defended thesis grounded in evidence
|
|
199
|
+
compare → per-entity evaluation + committed recommendation
|
|
200
|
+
forecast → committed prediction with explicit time horizon
|
|
201
|
+
```
|
|
202
|
+
|
|
203
|
+
A query about a fictional franchise can be `collect` (per-character enumeration), `synthesize` (a thesis about meaning), `compare` (this vs another), or `forecast` (will the sequel succeed). Subject doesn't decide; activity does.
|
|
204
|
+
|
|
205
|
+
---
|
|
206
|
+
|
|
207
|
+
## What's enforced
|
|
208
|
+
|
|
209
|
+
Eight invariants the protocol structurally prevents from breaking:
|
|
210
|
+
|
|
211
|
+
1. **Verbatim prompt as gospel** — `scaffold-prompt` lint blocks at Checkpoint 3 if the scaffold doesn't open with the user's exact prompt
|
|
212
|
+
2. **Rooted-tree provenance** — `--suggested-by` chain must form a real tree from at least one seed; isolated breadcrumbs flagged
|
|
213
|
+
3. **Analyst coverage** — at least 1 extract per 3 sources, no silent skipping
|
|
214
|
+
4. **Adversarial dissent** — at least one source explicitly contradicts the dominant view, named in writing
|
|
215
|
+
5. **Audit-gate self-cert detection** — CRITICAL findings marked fixed get their underlying lint rules re-run
|
|
216
|
+
6. **Save blocked** until every CRITICAL is genuinely resolved
|
|
217
|
+
7. **Schema integrity** — `tier` and `content_type` are SQLite CHECK-constrained vocabularies; corrupted frontmatter cannot poison the index
|
|
218
|
+
8. **PDF + raw artifact persistence** — fetched PDFs land in `research/raw/` and the `raw_file` frontmatter field survives every re-serialization
|
|
219
|
+
|
|
220
|
+
---
|
|
221
|
+
|
|
222
|
+
## What hyperresearch doesn't do
|
|
223
|
+
|
|
224
|
+
- It doesn't replace your judgment on which sources matter — the agent picks, you steer
|
|
225
|
+
- It can't fetch what's behind a paywall you haven't logged into (but it tries: `--visible` flag bypasses many bot-detectors, and configured login profiles work transparently)
|
|
226
|
+
- It runs on Anthropic models — Opus + Sonnet + Haiku via the subagent triad. Costs scale with corpus size; expect $5-15 per deep research session.
|
|
227
|
+
- The audit gate catches **structural** failures (missing scaffold, broken provenance, unresolved CRITICALs). It cannot guarantee factual accuracy — that's still your call.
|
|
228
|
+
- Network fetches fail. The protocol surfaces failures explicitly and walks a fallback chain (alternative URLs → visible browser → summary fallback), but some sources won't ever be fetchable.
|
|
229
|
+
|
|
230
|
+
---
|
|
231
|
+
|
|
232
|
+
## Use cases
|
|
233
|
+
|
|
234
|
+
- **Deep technical research** — "What does the literature say about ion-trap quantum scaling?" → 25+ academic sources, full provenance graph, dissenting voices, primary papers quoted directly
|
|
235
|
+
- **Comparative evaluation** — "TigerBeetle vs Postgres vs FoundationDB for write-heavy workloads" → per-entity coverage, comparison matrix, committed pick, mandatory critical voice on the leader
|
|
236
|
+
- **Forecasting + strategy** — "Will US inflation stay above 3% through 2026?" → ground-truth statistics + institutional analysis + named contrarians, probability language not hedge
|
|
237
|
+
- **Interpretive analysis** — "What does *Blood Meridian*'s violence mean?" → primary text + critical tradition + dissenting reading, every paragraph fuses fact with interpretive claim
|
|
238
|
+
- **Enumerative coverage** — "For each Napoleonic marshal, cover key campaigns and fate" → every named entity gets every requested field, no silent downgrades
|
|
239
|
+
- **Persistent knowledge base** — every source ever fetched stays searchable. Future sessions check the vault before searching the web. Knowledge compounds.
|
|
240
|
+
|
|
241
|
+
### `/research-ensemble` — 3 parallel sub-runs + Opus merger (what was benchmarked)
|
|
242
|
+
|
|
243
|
+
For queries where depth-of-corpus and argument stability matter more than wall-clock time, use `/research-ensemble <query>`. Opus orchestrates; three `hyperresearch-subrun` Sonnet agents run the full protocol in parallel against one shared vault, each with a subtly different framing (evidentiary breadth / citation-chain depth / dialectical tension). A fourth agent (`hyperresearch-merger`, Opus) scores each draft on comprehensiveness / readability / argument strength / citation quality, picks the strongest as the base, and splices in unique evidence from the other two. Cost is ~5× a normal run; the payoff is detailed in [Benchmarks](#benchmarks) below.
|
|
244
|
+
|
|
245
|
+
---
|
|
246
|
+
|
|
247
|
+
## What `hyperresearch install` wires into Claude Code
|
|
248
|
+
|
|
249
|
+
One command sets up the full integration:
|
|
250
|
+
|
|
251
|
+
- **`.claude/settings.json`** — PreToolUse hook that nudges Claude Code to check the vault before any raw web search
|
|
252
|
+
- **`.claude/skills/hyperresearch/`** — `/research` skill (dispatcher + 4 modality files: collect / synthesize / compare / forecast)
|
|
253
|
+
- **`.claude/skills/research-ensemble/`** — `/research-ensemble` skill (3× parallel sub-runs + Opus merger; see [Benchmarks](#benchmarks))
|
|
254
|
+
- **`.claude/agents/`** — six registered subagents: `hyperresearch-fetcher` (Haiku), `hyperresearch-analyst` (Sonnet), `hyperresearch-auditor` (Opus), `hyperresearch-rewriter` (Sonnet), `hyperresearch-subrun` (Sonnet, ensemble), `hyperresearch-merger` (Opus, ensemble)
|
|
255
|
+
- **`CLAUDE.md`** at the vault root — the full research workflow, automatically loaded by Claude Code on every session
|
|
256
|
+
|
|
257
|
+
hyperresearch is Claude Code-only for now. Codex, Cursor, and Gemini support was trimmed from v0.6 to focus the surface area — may return as real integrations later.
|
|
258
|
+
|
|
259
|
+
---
|
|
260
|
+
|
|
261
|
+
## Commands
|
|
262
|
+
|
|
263
|
+
```bash
|
|
264
|
+
# Research workflow
|
|
265
|
+
hyperresearch fetch <url> --tag t -j # Fetch a URL into the KB
|
|
266
|
+
hyperresearch fetch <url> --suggested-by <id> -j # Track provenance during the guided loop
|
|
267
|
+
hyperresearch fetch <url> --visible -j # Bypass bot detection with a visible browser
|
|
268
|
+
|
|
269
|
+
# Search + read
|
|
270
|
+
hyperresearch search "query" -j # Full-text search
|
|
271
|
+
hyperresearch search "query" --tier ground_truth -j # Filter by epistemic tier
|
|
272
|
+
hyperresearch search "query" --content-type paper -j # Filter by artifact kind
|
|
273
|
+
hyperresearch note show <id> -j # Read a note
|
|
274
|
+
hyperresearch note show <id> --meta -j # Frontmatter only (cheap triage)
|
|
275
|
+
hyperresearch note list --status draft -j # List notes with summaries
|
|
276
|
+
|
|
277
|
+
# Knowledge graph
|
|
278
|
+
hyperresearch link --auto -j # Auto-link related notes
|
|
279
|
+
hyperresearch graph hubs -j # Most-connected notes
|
|
280
|
+
hyperresearch graph backlinks <id> -j # What links to this note
|
|
281
|
+
|
|
282
|
+
# Health checks
|
|
283
|
+
hyperresearch lint -j # Run all rules
|
|
284
|
+
hyperresearch lint --rule scaffold-prompt -j # Verbatim prompt gospel rule
|
|
285
|
+
hyperresearch lint --rule provenance -j # Rooted-tree breadcrumb chain
|
|
286
|
+
hyperresearch lint --rule audit-gate -j # Self-certification detector
|
|
287
|
+
hyperresearch lint --rule analyst-coverage -j # Extract:source ratio
|
|
288
|
+
hyperresearch repair -j # Fix links, rebuild indexes
|
|
289
|
+
```
|
|
290
|
+
|
|
291
|
+
Every command returns `{"ok": true, "data": {...}}` with `-j`.
|
|
292
|
+
|
|
293
|
+
---
|
|
294
|
+
|
|
295
|
+
## Authenticated crawling
|
|
296
|
+
|
|
297
|
+
Fetch from LinkedIn, Twitter, paywalled sites — anything you can log into:
|
|
298
|
+
|
|
299
|
+
```bash
|
|
300
|
+
hyperresearch setup # Browser opens. Log into your sites. Done.
|
|
301
|
+
```
|
|
302
|
+
|
|
303
|
+
```toml
|
|
304
|
+
# .hyperresearch/config.toml
|
|
305
|
+
[web]
|
|
306
|
+
provider = "crawl4ai"
|
|
307
|
+
profile = "research"
|
|
308
|
+
```
|
|
309
|
+
|
|
310
|
+
LinkedIn, Twitter, Facebook, Instagram, and TikTok automatically use a visible browser to avoid session kills.
|
|
311
|
+
|
|
312
|
+
---
|
|
313
|
+
|
|
314
|
+
## Benchmarks
|
|
315
|
+
|
|
316
|
+
Hyperresearch is being evaluated on the [DeepResearch Bench](https://github.com/Ayanami0730/deep_research_bench) RACE eval (Gemini-2.5-Pro judges reports on comprehensiveness, insight, instruction-following, readability). Full per-modality scores and head-to-head comparisons vs other research harnesses will land here as the 100-query sweep completes. **Status:** in progress.
|
|
317
|
+
|
|
318
|
+
### Ensemble lift — preliminary data point
|
|
319
|
+
|
|
320
|
+
Query 91 from DeepResearch-Bench ("detailed analysis of the Saint Seiya franchise, structured around armor classes, per-character power/techniques/arcs/fate") is a deep-collect query with ~100 named entities. One data point so far:
|
|
321
|
+
|
|
322
|
+
| Variant | Overall | Comp. | Insight | Inst. | Read. | Cost | Time |
|
|
323
|
+
|---|---:|---:|---:|---:|---:|---:|---:|
|
|
324
|
+
| `/research` single-run (sonnet, v1 baseline) | **52.74** | 52.95 | 58.74 | 51.28 | 51.90 | ~$1.50 | ~8 min |
|
|
325
|
+
| `/research-ensemble` (3× sonnet + opus merger) | **54.82** | 54.52 | 58.57 | 53.30 | 56.10 | $21.98 | 57 min |
|
|
326
|
+
| **Delta** | **+2.08** | +1.57 | −0.17 | +2.02 | +4.20 | ~14× | ~7× |
|
|
327
|
+
|
|
328
|
+
Readability is the biggest single lift (+4.20) — the merger smooths splice boundaries and harmonizes voice across the three sub-runs. Instruction-following (+2.02) gains from three independent passes cross-checking the prompt's entity list; prompt-named entities the base run collapsed get restored from sibling runs. Comprehensiveness (+1.57) comes from the 3-way evidence union (167 sources fetched into the shared corpus vs ~30 for a single run). Insight is flat as expected — the merger is a compiler, not a re-thinker; it can't deepen an argument beyond what the strongest sub-run already had.
|
|
329
|
+
|
|
330
|
+
One query is not a benchmark. Full 100-query sweep coming next. The cost ceiling is honest: ~5× per query at the tool-call level, ~14× here because `/research` ran on Sonnet and `/research-ensemble` requires Opus orchestration + Opus merger. Use ensemble where the query earns it; use `/research` for everything else.
|
|
331
|
+
|
|
332
|
+
---
|
|
333
|
+
|
|
334
|
+
## Philosophy
|
|
335
|
+
|
|
336
|
+
- **Process is load-bearing.** A draft without a scaffold, comparisons, audit findings, and a clean provenance graph is unfinished — regardless of how good the prose reads.
|
|
337
|
+
- **The user's prompt is the only authority.** Activity classification, source strategy, writing constraints all serve the prompt. Substance rules never override what the user actually asked for.
|
|
338
|
+
- **No LLM calls inside the tool.** Hyperresearch stores, indexes, lints, and orchestrates. Your agent is the LLM.
|
|
339
|
+
- **Markdown is truth, SQLite is cache.** Notes are plain files. Delete the DB; `hyperresearch sync` rebuilds it.
|
|
340
|
+
- **Audit findings are artifacts, not just outputs.** They persist to JSON, get verified by lint rules, and gate the save. Self-certification is structurally prevented.
|
|
341
|
+
- **Exhaustive and deep.** v0.5.0 seeds 10-15 sources, iterates the bouncing loop 8 rounds, and typically produces drafts anchored in 40-80 fetched-and-analyst-read sources with 40+ inline citations. Depth AND breadth — not a tradeoff.
|
|
342
|
+
|
|
343
|
+
---
|
|
344
|
+
|
|
345
|
+
## Requirements
|
|
346
|
+
|
|
347
|
+
- Python 3.11+
|
|
348
|
+
- [Claude Code](https://claude.com/claude-code) with Anthropic API access
|
|
349
|
+
- API key with access to Opus, Sonnet, and Haiku — one key powers the full subagent triad
|
|
350
|
+
- Windows, macOS, Linux
|
|
351
|
+
|
|
352
|
+
---
|
|
353
|
+
|
|
354
|
+
## License
|
|
355
|
+
|
|
356
|
+
[MIT](LICENSE)
|
|
357
|
+
|
|
358
|
+
---
|
|
359
|
+
|
|
360
|
+
## Star History
|
|
361
|
+
|
|
362
|
+
[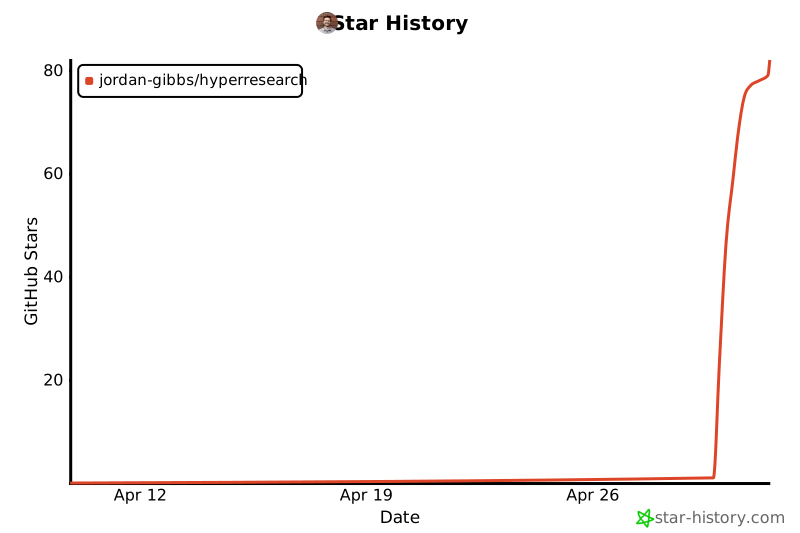](https://star-history.com/#jordan-gibbs/hyperresearch&Date)
|