hypercube-cascade 1.0.2__tar.gz → 1.0.4__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/PKG-INFO +29 -8
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/README.md +28 -7
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/hypercube_cascade/_version.py +1 -1
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/CMakeLists.txt +0 -0
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/bindings.cpp +0 -0
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/examples/README.md +0 -0
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/examples/synthetic_classification.py +0 -0
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/hypercube_cascade/__init__.py +0 -0
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/pyproject.toml +0 -0
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/tests/__init__.py +0 -0
- {hypercube_cascade-1.0.2 → hypercube_cascade-1.0.4}/tests/test_basic.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: hypercube-cascade
|
|
3
|
-
Version: 1.0.
|
|
3
|
+
Version: 1.0.4
|
|
4
4
|
Summary: Python bindings for HypercubeCascade: frozen etalon transit + frozen reservoir orbit + HypercubeCNN on end state
|
|
5
5
|
License-Expression: Apache-2.0
|
|
6
6
|
Classifier: Development Status :: 5 - Production/Stable
|
|
@@ -81,6 +81,14 @@ little to no architectural engineering is required for the CNN.
|
|
|
81
81
|
<a href="https://github.com/dliptak001/HypercubeEtalon"><strong>HypercubeEtalon</strong></a>
|
|
82
82
|
·
|
|
83
83
|
<a href="https://github.com/dliptak001/HypercubeCascade"><strong>HypercubeCascade</strong></a>
|
|
84
|
+
·
|
|
85
|
+
<a href="https://github.com/dliptak001/HypercubeLCN"><strong>HypercubeLCN</strong></a>
|
|
86
|
+
</p>
|
|
87
|
+
|
|
88
|
+
<p align="center">
|
|
89
|
+
📄 Foundational paper:
|
|
90
|
+
<a href="https://github.com/dliptak001/HypercubeCascade/blob/main/docs/Boolean_hypercubes_as_a_neural_substrate.pdf"><em>Boolean Hypercubes as a Neural Substrate</em></a>
|
|
91
|
+
(D. C. Liptak, 2026)
|
|
84
92
|
</p>
|
|
85
93
|
|
|
86
94
|
HypercubeCascade is an experiment in the **HypercubeAI** project — our quest to
|
|
@@ -199,14 +207,21 @@ techniques on spectra like these, and very likely beats them.
|
|
|
199
207
|
|
|
200
208
|
|
|
201
209
|
|
|
202
|
-
###
|
|
210
|
+
### Three hosts, one floor
|
|
203
211
|
|
|
204
212
|
The etalon-only sibling
|
|
205
213
|
([HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon))
|
|
206
|
-
is this Cascade with the reservoir removed
|
|
207
|
-
|
|
208
|
-
|
|
209
|
-
|
|
214
|
+
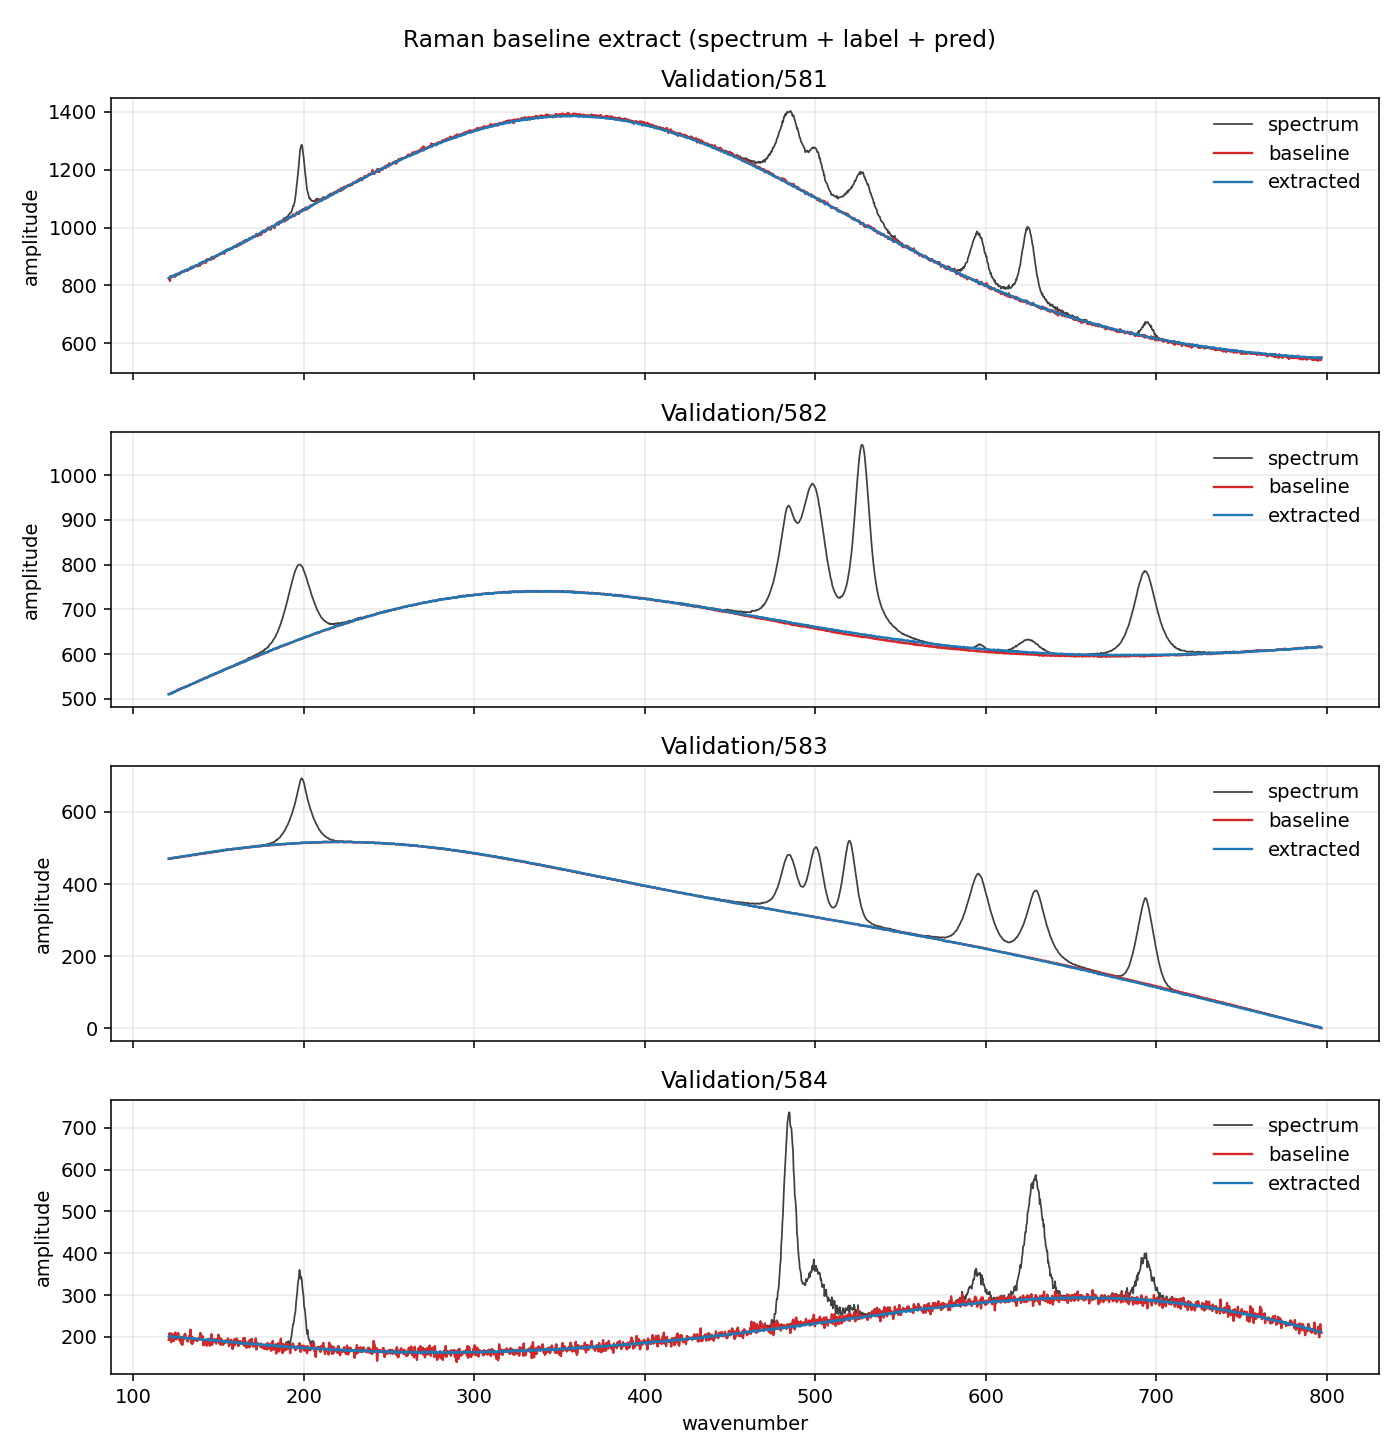
is this Cascade with the reservoir removed. The reservoir-only
|
|
215
|
+
sibling ([HypercubeWTF](https://github.com/dliptak001/HypercubeWTF))
|
|
216
|
+
is this Cascade with the transit removed: the same frozen reservoir
|
|
217
|
+
— same seed, spectral radius, history depth, and pass count — driven
|
|
218
|
+
by the normalized spectrum directly. Each of them, on its own,
|
|
219
|
+
already does everything described above. With the very same readout
|
|
220
|
+
configuration and the same 60-epoch budget, the Etalon scores 4.77
|
|
221
|
+
and WTF 4.76 against the Cascade's 4.82, and all three overlays are
|
|
222
|
+
indistinguishable from the one shown. Three preprocessors that share
|
|
223
|
+
no mechanism — a transit, an orbit, and the two in series — carry
|
|
224
|
+
the same one-layer, one-channel readout to the same floor.
|
|
210
225
|
|
|
211
226
|
Real spectra, however, are not nearly this clean. Low laser power,
|
|
212
227
|
short integration times, and weak scatterers all put noise on the
|
|
@@ -217,11 +232,16 @@ That is what the Cascade's second stage, the Reservoir, is for. On
|
|
|
217
232
|
the strength of the MNIST white-noise study
|
|
218
233
|
([`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/mnist/WhiteNoiseFilter.md)),
|
|
219
234
|
the Cascade is expected to outperform the Etalon alone in that
|
|
220
|
-
noise
|
|
235
|
+
noise — and WTF's own study
|
|
236
|
+
([`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeWTF/blob/main/examples/mnist/WhiteNoiseFilter.md))
|
|
237
|
+
found that same reservoir a filter that holds accuracy as the noise
|
|
238
|
+
rises. Whether the transit in front of it adds anything under noise,
|
|
239
|
+
or whether the reservoir is doing all of the filtering, is the open
|
|
240
|
+
question.
|
|
221
241
|
|
|
222
242
|
That is the next experiment.
|
|
223
243
|
|
|
224
|
-
Side-by-side overlays and
|
|
244
|
+
Side-by-side overlays and all three training profiles are in
|
|
225
245
|
[`examples/RamanBaselineExtraction/`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/RamanBaselineExtraction/README.md).
|
|
226
246
|
|
|
227
247
|
---
|
|
@@ -408,6 +428,7 @@ More notes:
|
|
|
408
428
|
- **[HypercubeCNN](https://github.com/dliptak001/HypercubeCNN)** — cube-native conv stack; Cascade’s trainable head.
|
|
409
429
|
- **[HypercubeESN](https://github.com/dliptak001/HypercubeESN)** — echo-state / reservoir computing on streams.
|
|
410
430
|
- **[HypercubeHopfield](https://github.com/dliptak001/HypercubeHopfield)** — Hopfield-style dynamics on the cube.
|
|
431
|
+
- **[HypercubeLCN](https://github.com/dliptak001/HypercubeLCN)** — locally connected network on the cube; every weight trained, no frozen stages.
|
|
411
432
|
|
|
412
433
|
---
|
|
413
434
|
|
|
@@ -54,6 +54,14 @@ little to no architectural engineering is required for the CNN.
|
|
|
54
54
|
<a href="https://github.com/dliptak001/HypercubeEtalon"><strong>HypercubeEtalon</strong></a>
|
|
55
55
|
·
|
|
56
56
|
<a href="https://github.com/dliptak001/HypercubeCascade"><strong>HypercubeCascade</strong></a>
|
|
57
|
+
·
|
|
58
|
+
<a href="https://github.com/dliptak001/HypercubeLCN"><strong>HypercubeLCN</strong></a>
|
|
59
|
+
</p>
|
|
60
|
+
|
|
61
|
+
<p align="center">
|
|
62
|
+
📄 Foundational paper:
|
|
63
|
+
<a href="https://github.com/dliptak001/HypercubeCascade/blob/main/docs/Boolean_hypercubes_as_a_neural_substrate.pdf"><em>Boolean Hypercubes as a Neural Substrate</em></a>
|
|
64
|
+
(D. C. Liptak, 2026)
|
|
57
65
|
</p>
|
|
58
66
|
|
|
59
67
|
HypercubeCascade is an experiment in the **HypercubeAI** project — our quest to
|
|
@@ -172,14 +180,21 @@ techniques on spectra like these, and very likely beats them.
|
|
|
172
180
|
|
|
173
181
|

|
|
174
182
|
|
|
175
|
-
###
|
|
183
|
+
### Three hosts, one floor
|
|
176
184
|
|
|
177
185
|
The etalon-only sibling
|
|
178
186
|
([HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon))
|
|
179
|
-
is this Cascade with the reservoir removed
|
|
180
|
-
|
|
181
|
-
|
|
182
|
-
|
|
187
|
+
is this Cascade with the reservoir removed. The reservoir-only
|
|
188
|
+
sibling ([HypercubeWTF](https://github.com/dliptak001/HypercubeWTF))
|
|
189
|
+
is this Cascade with the transit removed: the same frozen reservoir
|
|
190
|
+
— same seed, spectral radius, history depth, and pass count — driven
|
|
191
|
+
by the normalized spectrum directly. Each of them, on its own,
|
|
192
|
+
already does everything described above. With the very same readout
|
|
193
|
+
configuration and the same 60-epoch budget, the Etalon scores 4.77
|
|
194
|
+
and WTF 4.76 against the Cascade's 4.82, and all three overlays are
|
|
195
|
+
indistinguishable from the one shown. Three preprocessors that share
|
|
196
|
+
no mechanism — a transit, an orbit, and the two in series — carry
|
|
197
|
+
the same one-layer, one-channel readout to the same floor.
|
|
183
198
|
|
|
184
199
|
Real spectra, however, are not nearly this clean. Low laser power,
|
|
185
200
|
short integration times, and weak scatterers all put noise on the
|
|
@@ -190,11 +205,16 @@ That is what the Cascade's second stage, the Reservoir, is for. On
|
|
|
190
205
|
the strength of the MNIST white-noise study
|
|
191
206
|
([`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/mnist/WhiteNoiseFilter.md)),
|
|
192
207
|
the Cascade is expected to outperform the Etalon alone in that
|
|
193
|
-
noise
|
|
208
|
+
noise — and WTF's own study
|
|
209
|
+
([`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeWTF/blob/main/examples/mnist/WhiteNoiseFilter.md))
|
|
210
|
+
found that same reservoir a filter that holds accuracy as the noise
|
|
211
|
+
rises. Whether the transit in front of it adds anything under noise,
|
|
212
|
+
or whether the reservoir is doing all of the filtering, is the open
|
|
213
|
+
question.
|
|
194
214
|
|
|
195
215
|
That is the next experiment.
|
|
196
216
|
|
|
197
|
-
Side-by-side overlays and
|
|
217
|
+
Side-by-side overlays and all three training profiles are in
|
|
198
218
|
[`examples/RamanBaselineExtraction/`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/RamanBaselineExtraction/README.md).
|
|
199
219
|
|
|
200
220
|
---
|
|
@@ -381,6 +401,7 @@ More notes:
|
|
|
381
401
|
- **[HypercubeCNN](https://github.com/dliptak001/HypercubeCNN)** — cube-native conv stack; Cascade’s trainable head.
|
|
382
402
|
- **[HypercubeESN](https://github.com/dliptak001/HypercubeESN)** — echo-state / reservoir computing on streams.
|
|
383
403
|
- **[HypercubeHopfield](https://github.com/dliptak001/HypercubeHopfield)** — Hopfield-style dynamics on the cube.
|
|
404
|
+
- **[HypercubeLCN](https://github.com/dliptak001/HypercubeLCN)** — locally connected network on the cube; every weight trained, no frozen stages.
|
|
384
405
|
|
|
385
406
|
---
|
|
386
407
|
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|