hypercube-cascade 1.0.0__tar.gz → 1.0.2__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/PKG-INFO +142 -92
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/README.md +141 -91
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/hypercube_cascade/_version.py +1 -1
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/CMakeLists.txt +0 -0
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/bindings.cpp +0 -0
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/examples/README.md +0 -0
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/examples/synthetic_classification.py +0 -0
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/hypercube_cascade/__init__.py +0 -0
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/pyproject.toml +0 -0
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/tests/__init__.py +0 -0
- {hypercube_cascade-1.0.0 → hypercube_cascade-1.0.2}/tests/test_basic.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: hypercube-cascade
|
|
3
|
-
Version: 1.0.
|
|
3
|
+
Version: 1.0.2
|
|
4
4
|
Summary: Python bindings for HypercubeCascade: frozen etalon transit + frozen reservoir orbit + HypercubeCNN on end state
|
|
5
5
|
License-Expression: Apache-2.0
|
|
6
6
|
Classifier: Development Status :: 5 - Production/Stable
|
|
@@ -25,34 +25,44 @@ Provides-Extra: test
|
|
|
25
25
|
Requires-Dist: pytest>=7.0; extra == "test"
|
|
26
26
|
Description-Content-Type: text/markdown
|
|
27
27
|
|
|
28
|
-
#
|
|
29
|
-
|
|
30
|
-
|
|
31
|
-
spectra, sensor frames, packed images, stills. Those are the same kinds of
|
|
32
|
-
static fields people usually feed a spatial CNN, an MLP, or a similar
|
|
33
|
-
feed-forward stack. HypercubeCascade puts **two frozen hypercube
|
|
34
|
-
preprocessors in series** in front of the CNN: first an **etalon transit**
|
|
35
|
-
(the [HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon)
|
|
36
|
-
mechanism — a deterministic wave swept across every vertex/antipode cavity of
|
|
37
|
-
the cube), then a short **reservoir orbit** (the
|
|
38
|
-
[HypercubeWTF](https://github.com/dliptak001/HypercubeWTF) mechanism — a
|
|
39
|
-
frozen recurrent core driven by re-addressing the same field for T synthetic
|
|
40
|
-
passes). A small
|
|
41
|
-
[HypercubeCNN](https://github.com/dliptak001/HypercubeCNN) head trains on the
|
|
42
|
-
**end state only**. The CNN never sees the original field — it sees what the
|
|
43
|
-
transit and the orbit leave behind.
|
|
44
|
-
|
|
45
|
-
That is the product idea: take a static field, pass it through two different
|
|
46
|
-
frozen nonlinearities, and train a spatial readout on what remains. The aim is
|
|
47
|
-
a preprocessor effective enough that the readout can be a single convolutional
|
|
48
|
-
layer with a single channel and no pooling.
|
|
49
|
-
|
|
50
|
-
This package is the **Python** surface for that product
|
|
28
|
+
# Hypercube Cascade
|
|
29
|
+
|
|
30
|
+
This package is the **Python** surface for HypercubeCascade
|
|
51
31
|
(`import hypercube_cascade`).
|
|
52
32
|
Full API reference: **[docs/Python_SDK.md](https://github.com/dliptak001/HypercubeCascade/blob/main/docs/Python_SDK.md)**.
|
|
53
33
|
C++ integration guide: **[docs/CPP_SDK.md](https://github.com/dliptak001/HypercubeCascade/blob/main/docs/CPP_SDK.md)**.
|
|
54
34
|
Project home: **[github.com/dliptak001/HypercubeCascade](https://github.com/dliptak001/HypercubeCascade)**.
|
|
55
35
|
|
|
36
|
+
HypercubeCascade processes spatial data of the kind presented to a CNN.
|
|
37
|
+
It is built from four core classes.
|
|
38
|
+
|
|
39
|
+
The **Cascade** class wraps the other three and manages training and
|
|
40
|
+
prediction.
|
|
41
|
+
|
|
42
|
+
The other three form a pipeline: etalon → reservoir → readout.
|
|
43
|
+
|
|
44
|
+
The **Exciter** class is a preprocessing stage that consumes input
|
|
45
|
+
patterns, mixes them nonlinearly, and returns a field with the same
|
|
46
|
+
dimensions as the input.
|
|
47
|
+
|
|
48
|
+
The **Reservoir** class is a second preprocessing stage that consumes
|
|
49
|
+
that field, drives a short synthetic orbit on a frozen hypercube
|
|
50
|
+
reservoir, and returns a field with the same dimensions.
|
|
51
|
+
|
|
52
|
+
The **Readout** class is a small HypercubeCNN that classifies or
|
|
53
|
+
regresses that field.
|
|
54
|
+
|
|
55
|
+
This is reservoir computing, but not only reservoir computing.
|
|
56
|
+
|
|
57
|
+
The point of this experiment is to see if two preprocessing stages in
|
|
58
|
+
front of HypercubeCNN outperform HypercubeCNN by itself, and
|
|
59
|
+
outperform either stage alone. HypercubeEtalon is the etalon alone.
|
|
60
|
+
HypercubeWTF is the reservoir alone. Cascade runs them in series.
|
|
61
|
+
The aim is a hypercube preprocessor effective enough that the readout
|
|
62
|
+
can be a single layer with a single convolutional channel and no
|
|
63
|
+
pooling. Then training is fast, the memory footprint is small, and
|
|
64
|
+
little to no architectural engineering is required for the CNN.
|
|
65
|
+
|
|
56
66
|
---
|
|
57
67
|
|
|
58
68
|
<p align="center">
|
|
@@ -82,97 +92,137 @@ as a first-class computational substrate.
|
|
|
82
92
|
|
|
83
93
|
- **A topology you don’t store** — the graph is specified: connectivity is
|
|
84
94
|
implicit in the vertex indices; with a seed and a few config scalars the whole
|
|
85
|
-
|
|
95
|
+
reservoir reconstructs mathematically.
|
|
86
96
|
- **Perfect homogeneity** — every vertex has the same degree and the same local
|
|
87
97
|
world, so local dynamics mean the same thing everywhere — no structural
|
|
88
98
|
favorites baked in by a random graph.
|
|
89
99
|
- **Cheap navigation** — each neighbor is a few bit operations on the vertex
|
|
90
100
|
index, not a pointer chase through a stored edge list, so walks stay
|
|
91
101
|
arithmetic and cache-friendly.
|
|
92
|
-
- **Topology-native pairing** — the readout consumes the
|
|
93
|
-
|
|
94
|
-
|
|
95
|
-
|
|
102
|
+
- **Topology-native pairing** — the readout consumes the reservoir’s output with
|
|
103
|
+
zero geometric distortion, and the learned kernels exploit the same locality
|
|
104
|
+
that generated the dynamics. The data never leaves the hypercube it was born
|
|
105
|
+
on.
|
|
96
106
|
|
|
97
107
|
Each product in the family is a different architecture on that same foundation.
|
|
98
108
|
|
|
99
109
|
---
|
|
100
110
|
|
|
101
|
-
##
|
|
111
|
+
## The Cascade
|
|
102
112
|
|
|
103
|
-
|
|
104
|
-
|
|
105
|
-
|
|
106
|
-
static field with **one reservoir orbit**. HypercubeCascade is **both of them,
|
|
107
|
-
in series, on one cube**: the transit output, times a gain, becomes the orbit
|
|
108
|
-
drive, and the orbit's end state, times a second gain, is what the CNN head
|
|
109
|
-
trains on.
|
|
113
|
+
HypercubeEtalon and HypercubeWTF are two examples of how
|
|
114
|
+
solutions can be built on that substrate. Cascade is both of them, in
|
|
115
|
+
series, on one cube.
|
|
110
116
|
|
|
111
|
-
|
|
117
|
+
There is one cube dimension. The Exciter, the Reservoir, and the
|
|
118
|
+
Readout all use it.
|
|
112
119
|
|
|
113
|
-
|
|
114
|
-
|
|
115
|
-
|
|
120
|
+
An etalon, here, is a vertex and its antipode treated as a reflective
|
|
121
|
+
cavity. The Exciter walks every such cavity and writes one output
|
|
122
|
+
sample per start. That walk is the etalon transit. The write-up is
|
|
123
|
+
[HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon).
|
|
116
124
|
|
|
117
|
-
|
|
118
|
-
|
|
119
|
-
the
|
|
120
|
-
[
|
|
125
|
+
The Reservoir is the HypercubeWTF encoder: frozen recurrent weights,
|
|
126
|
+
a delay line, and a short synthetic orbit. Geometry stays put; the
|
|
127
|
+
registration of the field moves. The write-up is
|
|
128
|
+
[HypercubeWTF](https://github.com/dliptak001/HypercubeWTF).
|
|
121
129
|
|
|
122
|
-
|
|
130
|
+
The cascade itself goes something like this.
|
|
123
131
|
|
|
124
|
-
|
|
125
|
-
|
|
126
|
-
|
|
127
|
-
|
|
128
|
-
|
|
129
|
-
|
|
130
|
-
|
|
131
|
-
|
|
132
|
-
|
|
133
|
-
|
|
134
|
-
|
|
135
|
-
|
|
136
|
-
|
|
137
|
-
|
|
132
|
+
Copy the input field. Never write the caller's buffer.
|
|
133
|
+
|
|
134
|
+
Run one etalon transit. The cube is the same size it started as.
|
|
135
|
+
|
|
136
|
+
Multiply that field by the interstage gain.
|
|
137
|
+
|
|
138
|
+
Reload the reservoir's frozen start.
|
|
139
|
+
|
|
140
|
+
LOOP:
|
|
141
|
+
|
|
142
|
+
Remap the scaled field by xor with the pass index.
|
|
143
|
+
|
|
144
|
+
Inject that remapping. Step the reservoir.
|
|
145
|
+
|
|
146
|
+
GOTO LOOP
|
|
147
|
+
|
|
148
|
+
After T passes, the reservoir's live output is the feature field.
|
|
149
|
+
That is what the Readout sees.
|
|
150
|
+
|
|
151
|
+
The single-stage write-ups live with the siblings. This repository is
|
|
152
|
+
the two-stage host.
|
|
153
|
+
|
|
154
|
+
---
|
|
138
155
|
|
|
139
|
-
|
|
140
|
-
three stages.
|
|
141
|
-
- Only the readout trains.
|
|
142
|
-
- Everyday loop in this package:
|
|
143
|
-
`collect_batch` → `train` → `predict` / `predict_class`,
|
|
144
|
-
or one-shot `fit` (collect + train).
|
|
156
|
+
## White noise filter
|
|
145
157
|
|
|
146
|
-
|
|
147
|
-
|
|
148
|
-
|
|
158
|
+
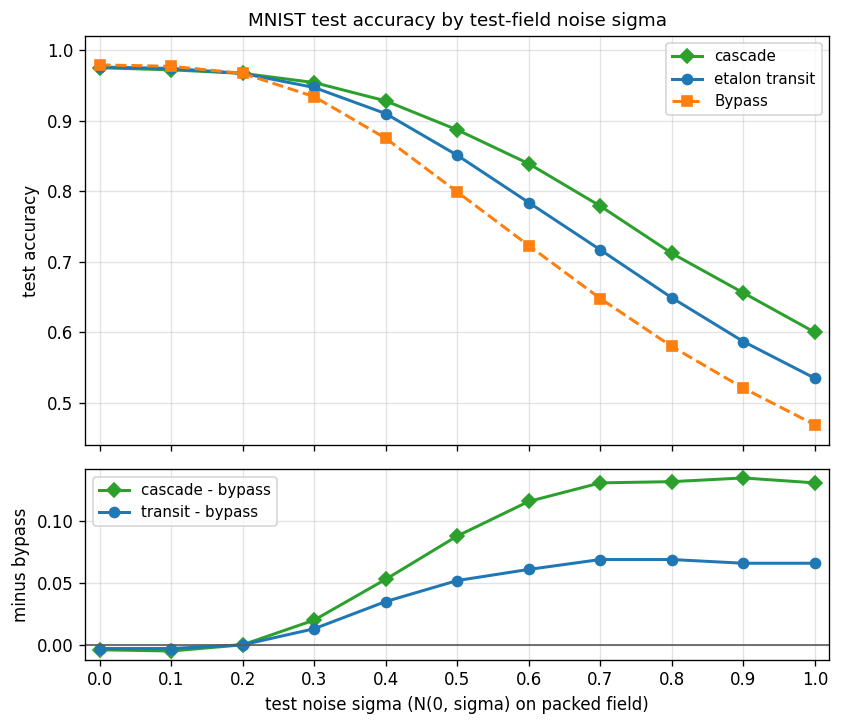
The Cascade preprocessor behaves as a near unity passthrough at low
|
|
159
|
+
to no white noise levels, and offers meaningful filtering effect
|
|
160
|
+
at moderate to high noise levels. The write-up is
|
|
161
|
+
[`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/mnist/WhiteNoiseFilter.md).
|
|
149
162
|
|
|
150
|
-
|
|
151
|
-
**[docs/Python_SDK.md](https://github.com/dliptak001/HypercubeCascade/blob/main/docs/Python_SDK.md)**.
|
|
163
|
+
|
|
152
164
|
|
|
153
165
|
---
|
|
154
166
|
|
|
155
|
-
##
|
|
156
|
-
|
|
157
|
-
|
|
158
|
-
|
|
159
|
-
|
|
160
|
-
|
|
161
|
-
|
|
162
|
-
|
|
163
|
-
|
|
164
|
-
|
|
165
|
-
|
|
166
|
-
|
|
167
|
-
|
|
168
|
-
|
|
169
|
-
|
|
170
|
-
|
|
171
|
-
|
|
172
|
-
|
|
173
|
-
|
|
174
|
-
|
|
175
|
-
|
|
167
|
+
## Raman baseline extraction (a vibrational spectroscopy application)
|
|
168
|
+
|
|
169
|
+
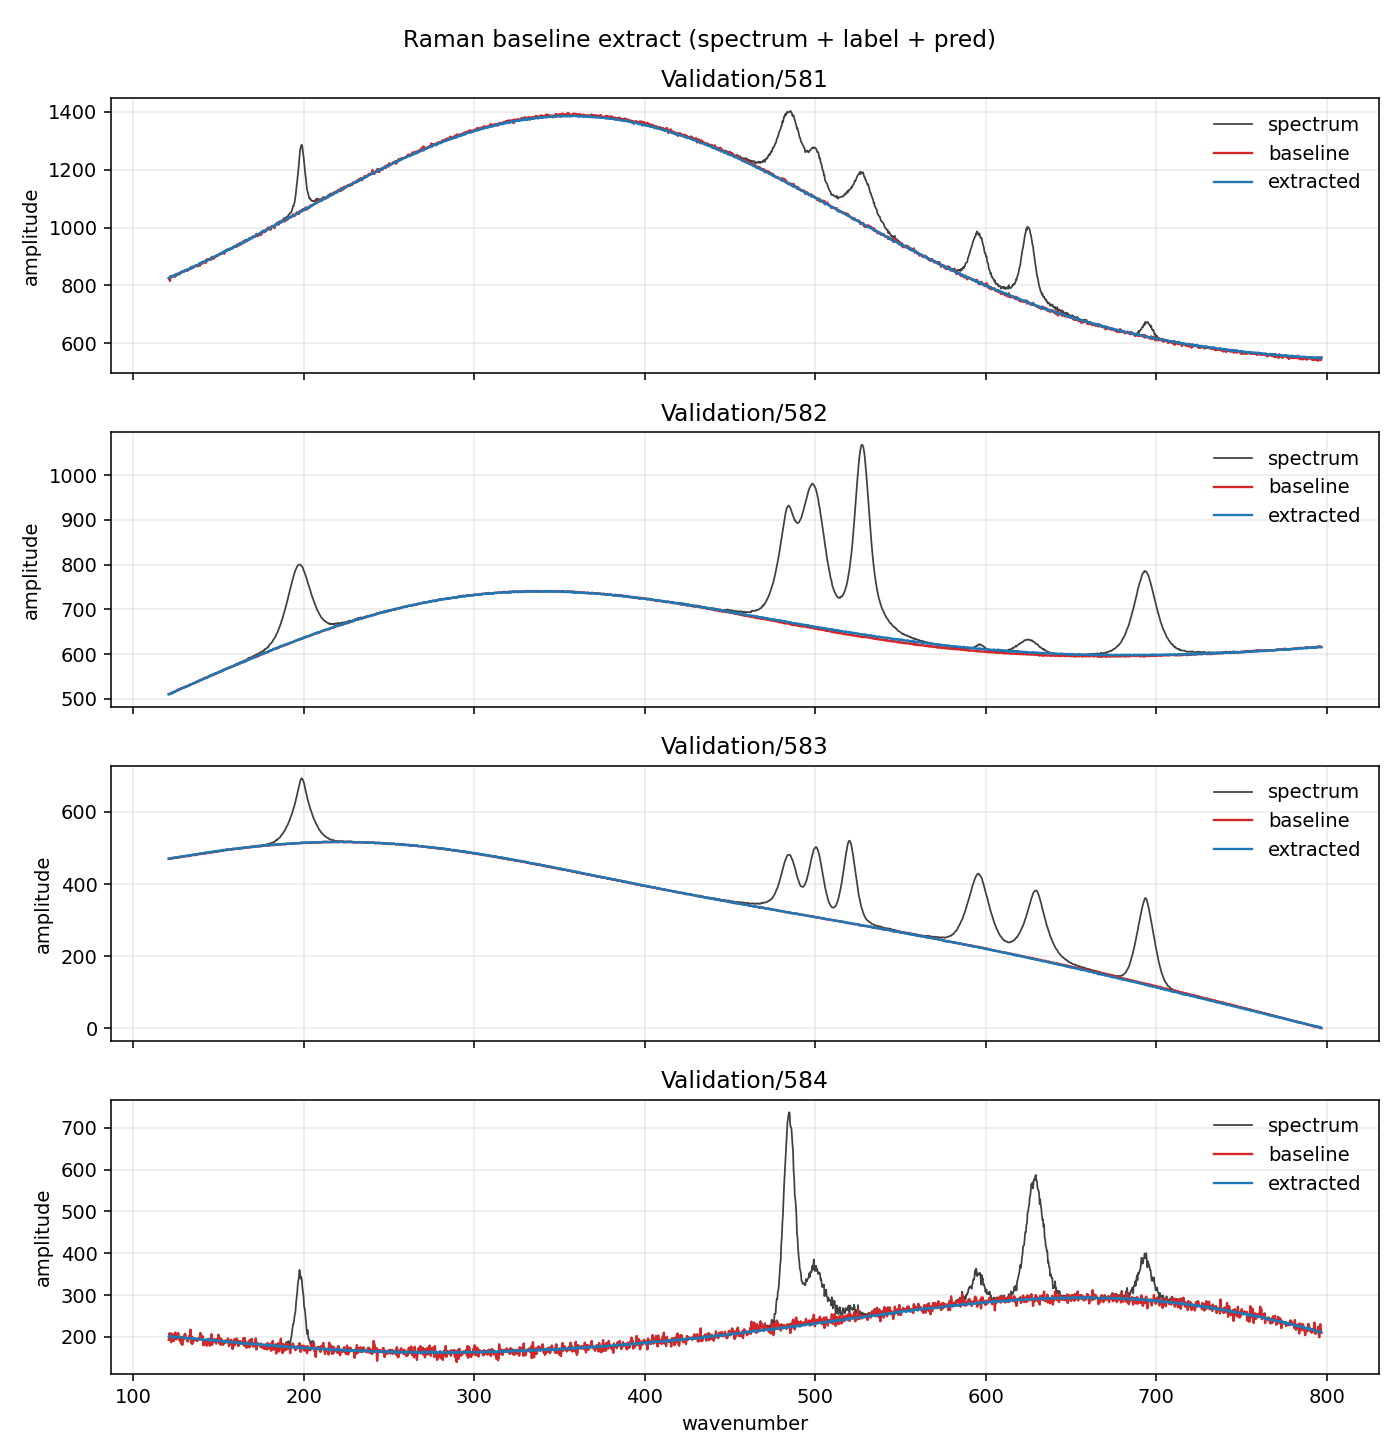
The first real-world test is Raman spectra: recover the slow
|
|
170
|
+
fluorescence background under sharp molecular peaks without
|
|
171
|
+
lifting the baseline into the bands or cutting trenches beneath
|
|
172
|
+
them. Polynomials, asymmetric least squares, and ordinary
|
|
173
|
+
convolutional nets tend to follow the empty stretches well and then
|
|
174
|
+
fail where it matters, under peaks and peak clusters. Analysts have
|
|
175
|
+
worked around that for decades with spectrum-specific cleanup,
|
|
176
|
+
because no method identifies and extracts a true baseline across a
|
|
177
|
+
broad range of peak intensities and baseline characteristics
|
|
178
|
+
without occasional, and often frequent, human intervention.
|
|
179
|
+
|
|
180
|
+
The Cascade appears to have solved that problem (albeit on synthetic
|
|
181
|
+
data only so far).
|
|
182
|
+
|
|
183
|
+
Trained for 60 epochs on the LCOHard set — 10,000 synthetic LiCoO₂
|
|
184
|
+
(lithium cobalt oxide) spectra — it scores a validation RMSE of
|
|
185
|
+
4.82 counts on 2,000 held-out spectra whose baselines span
|
|
186
|
+
hundreds of counts.
|
|
187
|
+
|
|
188
|
+
Below are four held-out validation spectra: grey is the raw
|
|
189
|
+
spectrum, red the true baseline, blue the extract. For all four
|
|
190
|
+
shown here, and for each of the remaining 1996 validation spectra
|
|
191
|
+
not shown, baseline identification is, **WITHOUT EXCEPTION**,
|
|
192
|
+
quite remarkable.
|
|
193
|
+
|
|
194
|
+
And it does this with the thin readout the project aims for: one
|
|
195
|
+
HypercubeCNN layer, one convolutional channel, no pooling.
|
|
196
|
+
|
|
197
|
+
In our judgment this at least matches the best of the established
|
|
198
|
+
techniques on spectra like these, and very likely beats them.
|
|
199
|
+
|
|
200
|
+
|
|
201
|
+
|
|
202
|
+
### Etalon sets the bar. Cascade raises it (well, maybe).
|
|
203
|
+
|
|
204
|
+
The etalon-only sibling
|
|
205
|
+
([HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon))
|
|
206
|
+
is this Cascade with the reservoir removed, and on its own it
|
|
207
|
+
already does everything described above. With the very same
|
|
208
|
+
Exciter and readout configuration, its overlays are
|
|
209
|
+
indistinguishable from the ones shown.
|
|
210
|
+
|
|
211
|
+
Real spectra, however, are not nearly this clean. Low laser power,
|
|
212
|
+
short integration times, and weak scatterers all put noise on the
|
|
213
|
+
spectrum, and that is where a baseline extractor has to earn its
|
|
214
|
+
keep.
|
|
215
|
+
|
|
216
|
+
That is what the Cascade's second stage, the Reservoir, is for. On
|
|
217
|
+
the strength of the MNIST white-noise study
|
|
218
|
+
([`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/mnist/WhiteNoiseFilter.md)),
|
|
219
|
+
the Cascade is expected to outperform the Etalon alone in that
|
|
220
|
+
noise.
|
|
221
|
+
|
|
222
|
+
That is the next experiment.
|
|
223
|
+
|
|
224
|
+
Side-by-side overlays and both training profiles are in
|
|
225
|
+
[`examples/RamanBaselineExtraction/`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/RamanBaselineExtraction/README.md).
|
|
176
226
|
|
|
177
227
|
---
|
|
178
228
|
|
|
@@ -1,31 +1,41 @@
|
|
|
1
|
-
#
|
|
2
|
-
|
|
3
|
-
|
|
4
|
-
spectra, sensor frames, packed images, stills. Those are the same kinds of
|
|
5
|
-
static fields people usually feed a spatial CNN, an MLP, or a similar
|
|
6
|
-
feed-forward stack. HypercubeCascade puts **two frozen hypercube
|
|
7
|
-
preprocessors in series** in front of the CNN: first an **etalon transit**
|
|
8
|
-
(the [HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon)
|
|
9
|
-
mechanism — a deterministic wave swept across every vertex/antipode cavity of
|
|
10
|
-
the cube), then a short **reservoir orbit** (the
|
|
11
|
-
[HypercubeWTF](https://github.com/dliptak001/HypercubeWTF) mechanism — a
|
|
12
|
-
frozen recurrent core driven by re-addressing the same field for T synthetic
|
|
13
|
-
passes). A small
|
|
14
|
-
[HypercubeCNN](https://github.com/dliptak001/HypercubeCNN) head trains on the
|
|
15
|
-
**end state only**. The CNN never sees the original field — it sees what the
|
|
16
|
-
transit and the orbit leave behind.
|
|
17
|
-
|
|
18
|
-
That is the product idea: take a static field, pass it through two different
|
|
19
|
-
frozen nonlinearities, and train a spatial readout on what remains. The aim is
|
|
20
|
-
a preprocessor effective enough that the readout can be a single convolutional
|
|
21
|
-
layer with a single channel and no pooling.
|
|
22
|
-
|
|
23
|
-
This package is the **Python** surface for that product
|
|
1
|
+
# Hypercube Cascade
|
|
2
|
+
|
|
3
|
+
This package is the **Python** surface for HypercubeCascade
|
|
24
4
|
(`import hypercube_cascade`).
|
|
25
5
|
Full API reference: **[docs/Python_SDK.md](https://github.com/dliptak001/HypercubeCascade/blob/main/docs/Python_SDK.md)**.
|
|
26
6
|
C++ integration guide: **[docs/CPP_SDK.md](https://github.com/dliptak001/HypercubeCascade/blob/main/docs/CPP_SDK.md)**.
|
|
27
7
|
Project home: **[github.com/dliptak001/HypercubeCascade](https://github.com/dliptak001/HypercubeCascade)**.
|
|
28
8
|
|
|
9
|
+
HypercubeCascade processes spatial data of the kind presented to a CNN.
|
|
10
|
+
It is built from four core classes.
|
|
11
|
+
|
|
12
|
+
The **Cascade** class wraps the other three and manages training and
|
|
13
|
+
prediction.
|
|
14
|
+
|
|
15
|
+
The other three form a pipeline: etalon → reservoir → readout.
|
|
16
|
+
|
|
17
|
+
The **Exciter** class is a preprocessing stage that consumes input
|
|
18
|
+
patterns, mixes them nonlinearly, and returns a field with the same
|
|
19
|
+
dimensions as the input.
|
|
20
|
+
|
|
21
|
+
The **Reservoir** class is a second preprocessing stage that consumes
|
|
22
|
+
that field, drives a short synthetic orbit on a frozen hypercube
|
|
23
|
+
reservoir, and returns a field with the same dimensions.
|
|
24
|
+
|
|
25
|
+
The **Readout** class is a small HypercubeCNN that classifies or
|
|
26
|
+
regresses that field.
|
|
27
|
+
|
|
28
|
+
This is reservoir computing, but not only reservoir computing.
|
|
29
|
+
|
|
30
|
+
The point of this experiment is to see if two preprocessing stages in
|
|
31
|
+
front of HypercubeCNN outperform HypercubeCNN by itself, and
|
|
32
|
+
outperform either stage alone. HypercubeEtalon is the etalon alone.
|
|
33
|
+
HypercubeWTF is the reservoir alone. Cascade runs them in series.
|
|
34
|
+
The aim is a hypercube preprocessor effective enough that the readout
|
|
35
|
+
can be a single layer with a single convolutional channel and no
|
|
36
|
+
pooling. Then training is fast, the memory footprint is small, and
|
|
37
|
+
little to no architectural engineering is required for the CNN.
|
|
38
|
+
|
|
29
39
|
---
|
|
30
40
|
|
|
31
41
|
<p align="center">
|
|
@@ -55,97 +65,137 @@ as a first-class computational substrate.
|
|
|
55
65
|
|
|
56
66
|
- **A topology you don’t store** — the graph is specified: connectivity is
|
|
57
67
|
implicit in the vertex indices; with a seed and a few config scalars the whole
|
|
58
|
-
|
|
68
|
+
reservoir reconstructs mathematically.
|
|
59
69
|
- **Perfect homogeneity** — every vertex has the same degree and the same local
|
|
60
70
|
world, so local dynamics mean the same thing everywhere — no structural
|
|
61
71
|
favorites baked in by a random graph.
|
|
62
72
|
- **Cheap navigation** — each neighbor is a few bit operations on the vertex
|
|
63
73
|
index, not a pointer chase through a stored edge list, so walks stay
|
|
64
74
|
arithmetic and cache-friendly.
|
|
65
|
-
- **Topology-native pairing** — the readout consumes the
|
|
66
|
-
|
|
67
|
-
|
|
68
|
-
|
|
75
|
+
- **Topology-native pairing** — the readout consumes the reservoir’s output with
|
|
76
|
+
zero geometric distortion, and the learned kernels exploit the same locality
|
|
77
|
+
that generated the dynamics. The data never leaves the hypercube it was born
|
|
78
|
+
on.
|
|
69
79
|
|
|
70
80
|
Each product in the family is a different architecture on that same foundation.
|
|
71
81
|
|
|
72
82
|
---
|
|
73
83
|
|
|
74
|
-
##
|
|
84
|
+
## The Cascade
|
|
75
85
|
|
|
76
|
-
|
|
77
|
-
|
|
78
|
-
|
|
79
|
-
static field with **one reservoir orbit**. HypercubeCascade is **both of them,
|
|
80
|
-
in series, on one cube**: the transit output, times a gain, becomes the orbit
|
|
81
|
-
drive, and the orbit's end state, times a second gain, is what the CNN head
|
|
82
|
-
trains on.
|
|
86
|
+
HypercubeEtalon and HypercubeWTF are two examples of how
|
|
87
|
+
solutions can be built on that substrate. Cascade is both of them, in
|
|
88
|
+
series, on one cube.
|
|
83
89
|
|
|
84
|
-
|
|
90
|
+
There is one cube dimension. The Exciter, the Reservoir, and the
|
|
91
|
+
Readout all use it.
|
|
85
92
|
|
|
86
|
-
|
|
87
|
-
|
|
88
|
-
|
|
93
|
+
An etalon, here, is a vertex and its antipode treated as a reflective
|
|
94
|
+
cavity. The Exciter walks every such cavity and writes one output
|
|
95
|
+
sample per start. That walk is the etalon transit. The write-up is
|
|
96
|
+
[HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon).
|
|
89
97
|
|
|
90
|
-
|
|
91
|
-
|
|
92
|
-
the
|
|
93
|
-
[
|
|
98
|
+
The Reservoir is the HypercubeWTF encoder: frozen recurrent weights,
|
|
99
|
+
a delay line, and a short synthetic orbit. Geometry stays put; the
|
|
100
|
+
registration of the field moves. The write-up is
|
|
101
|
+
[HypercubeWTF](https://github.com/dliptak001/HypercubeWTF).
|
|
94
102
|
|
|
95
|
-
|
|
103
|
+
The cascade itself goes something like this.
|
|
96
104
|
|
|
97
|
-
|
|
98
|
-
|
|
99
|
-
|
|
100
|
-
|
|
101
|
-
|
|
102
|
-
|
|
103
|
-
|
|
104
|
-
|
|
105
|
-
|
|
106
|
-
|
|
107
|
-
|
|
108
|
-
|
|
109
|
-
|
|
110
|
-
|
|
105
|
+
Copy the input field. Never write the caller's buffer.
|
|
106
|
+
|
|
107
|
+
Run one etalon transit. The cube is the same size it started as.
|
|
108
|
+
|
|
109
|
+
Multiply that field by the interstage gain.
|
|
110
|
+
|
|
111
|
+
Reload the reservoir's frozen start.
|
|
112
|
+
|
|
113
|
+
LOOP:
|
|
114
|
+
|
|
115
|
+
Remap the scaled field by xor with the pass index.
|
|
116
|
+
|
|
117
|
+
Inject that remapping. Step the reservoir.
|
|
118
|
+
|
|
119
|
+
GOTO LOOP
|
|
120
|
+
|
|
121
|
+
After T passes, the reservoir's live output is the feature field.
|
|
122
|
+
That is what the Readout sees.
|
|
123
|
+
|
|
124
|
+
The single-stage write-ups live with the siblings. This repository is
|
|
125
|
+
the two-stage host.
|
|
126
|
+
|
|
127
|
+
---
|
|
111
128
|
|
|
112
|
-
|
|
113
|
-
three stages.
|
|
114
|
-
- Only the readout trains.
|
|
115
|
-
- Everyday loop in this package:
|
|
116
|
-
`collect_batch` → `train` → `predict` / `predict_class`,
|
|
117
|
-
or one-shot `fit` (collect + train).
|
|
129
|
+
## White noise filter
|
|
118
130
|
|
|
119
|
-
|
|
120
|
-
|
|
121
|
-
|
|
131
|
+
The Cascade preprocessor behaves as a near unity passthrough at low
|
|
132
|
+
to no white noise levels, and offers meaningful filtering effect
|
|
133
|
+
at moderate to high noise levels. The write-up is
|
|
134
|
+
[`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/mnist/WhiteNoiseFilter.md).
|
|
122
135
|
|
|
123
|
-
|
|
124
|
-
**[docs/Python_SDK.md](https://github.com/dliptak001/HypercubeCascade/blob/main/docs/Python_SDK.md)**.
|
|
136
|
+

|
|
125
137
|
|
|
126
138
|
---
|
|
127
139
|
|
|
128
|
-
##
|
|
129
|
-
|
|
130
|
-
|
|
131
|
-
|
|
132
|
-
|
|
133
|
-
|
|
134
|
-
|
|
135
|
-
|
|
136
|
-
|
|
137
|
-
|
|
138
|
-
|
|
139
|
-
|
|
140
|
-
|
|
141
|
-
|
|
142
|
-
|
|
143
|
-
|
|
144
|
-
|
|
145
|
-
|
|
146
|
-
|
|
147
|
-
|
|
148
|
-
|
|
140
|
+
## Raman baseline extraction (a vibrational spectroscopy application)
|
|
141
|
+
|
|
142
|
+
The first real-world test is Raman spectra: recover the slow
|
|
143
|
+
fluorescence background under sharp molecular peaks without
|
|
144
|
+
lifting the baseline into the bands or cutting trenches beneath
|
|
145
|
+
them. Polynomials, asymmetric least squares, and ordinary
|
|
146
|
+
convolutional nets tend to follow the empty stretches well and then
|
|
147
|
+
fail where it matters, under peaks and peak clusters. Analysts have
|
|
148
|
+
worked around that for decades with spectrum-specific cleanup,
|
|
149
|
+
because no method identifies and extracts a true baseline across a
|
|
150
|
+
broad range of peak intensities and baseline characteristics
|
|
151
|
+
without occasional, and often frequent, human intervention.
|
|
152
|
+
|
|
153
|
+
The Cascade appears to have solved that problem (albeit on synthetic
|
|
154
|
+
data only so far).
|
|
155
|
+
|
|
156
|
+
Trained for 60 epochs on the LCOHard set — 10,000 synthetic LiCoO₂
|
|
157
|
+
(lithium cobalt oxide) spectra — it scores a validation RMSE of
|
|
158
|
+
4.82 counts on 2,000 held-out spectra whose baselines span
|
|
159
|
+
hundreds of counts.
|
|
160
|
+
|
|
161
|
+
Below are four held-out validation spectra: grey is the raw
|
|
162
|
+
spectrum, red the true baseline, blue the extract. For all four
|
|
163
|
+
shown here, and for each of the remaining 1996 validation spectra
|
|
164
|
+
not shown, baseline identification is, **WITHOUT EXCEPTION**,
|
|
165
|
+
quite remarkable.
|
|
166
|
+
|
|
167
|
+
And it does this with the thin readout the project aims for: one
|
|
168
|
+
HypercubeCNN layer, one convolutional channel, no pooling.
|
|
169
|
+
|
|
170
|
+
In our judgment this at least matches the best of the established
|
|
171
|
+
techniques on spectra like these, and very likely beats them.
|
|
172
|
+
|
|
173
|
+

|
|
174
|
+
|
|
175
|
+
### Etalon sets the bar. Cascade raises it (well, maybe).
|
|
176
|
+
|
|
177
|
+
The etalon-only sibling
|
|
178
|
+
([HypercubeEtalon](https://github.com/dliptak001/HypercubeEtalon))
|
|
179
|
+
is this Cascade with the reservoir removed, and on its own it
|
|
180
|
+
already does everything described above. With the very same
|
|
181
|
+
Exciter and readout configuration, its overlays are
|
|
182
|
+
indistinguishable from the ones shown.
|
|
183
|
+
|
|
184
|
+
Real spectra, however, are not nearly this clean. Low laser power,
|
|
185
|
+
short integration times, and weak scatterers all put noise on the
|
|
186
|
+
spectrum, and that is where a baseline extractor has to earn its
|
|
187
|
+
keep.
|
|
188
|
+
|
|
189
|
+
That is what the Cascade's second stage, the Reservoir, is for. On
|
|
190
|
+
the strength of the MNIST white-noise study
|
|
191
|
+
([`examples/mnist/WhiteNoiseFilter.md`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/mnist/WhiteNoiseFilter.md)),
|
|
192
|
+
the Cascade is expected to outperform the Etalon alone in that
|
|
193
|
+
noise.
|
|
194
|
+
|
|
195
|
+
That is the next experiment.
|
|
196
|
+
|
|
197
|
+
Side-by-side overlays and both training profiles are in
|
|
198
|
+
[`examples/RamanBaselineExtraction/`](https://github.com/dliptak001/HypercubeCascade/blob/main/examples/RamanBaselineExtraction/README.md).
|
|
149
199
|
|
|
150
200
|
---
|
|
151
201
|
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|