gpulayer 0.3.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- gpulayer-0.3.0/.gitignore +11 -0
- gpulayer-0.3.0/CHANGELOG.md +139 -0
- gpulayer-0.3.0/LICENSE +202 -0
- gpulayer-0.3.0/PKG-INFO +216 -0
- gpulayer-0.3.0/README.md +175 -0
- gpulayer-0.3.0/benchmarks/README.md +82 -0
- gpulayer-0.3.0/benchmarks/cloud/gcp.sh +191 -0
- gpulayer-0.3.0/benchmarks/cloud/worker-startup.sh +15 -0
- gpulayer-0.3.0/benchmarks/cloud/write_env.py +25 -0
- gpulayer-0.3.0/benchmarks/dispatch.py +96 -0
- gpulayer-0.3.0/benchmarks/distributed_startup.py +85 -0
- gpulayer-0.3.0/benchmarks/http_requests.py +77 -0
- gpulayer-0.3.0/benchmarks/lightning_comparison/bench.py +133 -0
- gpulayer-0.3.0/benchmarks/lightning_comparison/multinode.py +114 -0
- gpulayer-0.3.0/benchmarks/lightning_comparison/run.py +42 -0
- gpulayer-0.3.0/benchmarks/lightning_comparison/scaling.py +123 -0
- gpulayer-0.3.0/benchmarks/lightning_comparison/scaling_run.py +100 -0
- gpulayer-0.3.0/benchmarks/multi_machine.py +287 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/multi-machine/http-latency.txt +9 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/multi-machine/multi_machine.log +20 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/multi-machine/results.json +37 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/summary.json +37 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/t4/lightning-comparison.log +13 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/t4/nvidia-smi.txt +20 -0
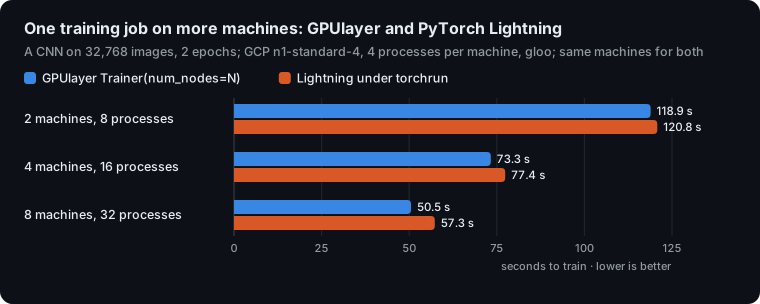
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/t4/pip-freeze.txt +62 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/t4/validate_cuda.log +39 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp/t4/validate_gpu.log +216 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp-fleet/scale-test-before-fixes.json +175 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp-fleet/scale-test-before-fixes.log +17 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp-fleet/scale-test-keyed-wakeups.log +7 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp-fleet/scale-test-served-mode.log +9 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp-fleet/scale-test-sync-normal.log +7 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp-fleet/strong-scaling.log +6 -0
- gpulayer-0.3.0/benchmarks/results/2026-10-30-gcp-fleet/summary.json +29 -0
- gpulayer-0.3.0/benchmarks/scale_test.py +319 -0
- gpulayer-0.3.0/benchmarks/submit_queue.py +60 -0
- gpulayer-0.3.0/deploy/docker/docker-compose.yml +50 -0
- gpulayer-0.3.0/deploy/docker/smoke-test.sh +51 -0
- gpulayer-0.3.0/deploy/monitoring/docker-compose.yml +22 -0
- gpulayer-0.3.0/deploy/monitoring/grafana/gpulayer-dashboard.json +776 -0
- gpulayer-0.3.0/deploy/monitoring/grafana/provisioning/dashboards/gpulayer.yml +7 -0
- gpulayer-0.3.0/deploy/monitoring/grafana/provisioning/datasources/prometheus.yml +8 -0
- gpulayer-0.3.0/deploy/monitoring/prometheus.yml +19 -0
- gpulayer-0.3.0/docs/architecture/cost-accounting.md +23 -0
- gpulayer-0.3.0/docs/architecture/distributed.md +70 -0
- gpulayer-0.3.0/docs/architecture/gpu-compatibility.md +56 -0
- gpulayer-0.3.0/docs/architecture/overview.md +105 -0
- gpulayer-0.3.0/docs/architecture/performance.md +115 -0
- gpulayer-0.3.0/docs/architecture/scheduling.md +33 -0
- gpulayer-0.3.0/docs/architecture/security.md +85 -0
- gpulayer-0.3.0/docs/assets/architecture-dark.svg +1 -0
- gpulayer-0.3.0/docs/assets/architecture-light.svg +1 -0
- gpulayer-0.3.0/docs/assets/dashboard/job-ddp-dark.png +0 -0
- gpulayer-0.3.0/docs/assets/dashboard/job-failed-dark.png +0 -0
- gpulayer-0.3.0/docs/assets/dashboard/job-running-dark.png +0 -0
- gpulayer-0.3.0/docs/assets/dashboard/overview-dark.png +0 -0
- gpulayer-0.3.0/docs/assets/dashboard/overview-light.png +0 -0
- gpulayer-0.3.0/docs/assets/dashboard/workers-dark.png +0 -0
- gpulayer-0.3.0/docs/assets/logo-mark.svg +1 -0
- gpulayer-0.3.0/docs/assets/logo.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/distributed-startup-dark.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/distributed-startup-light.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/fleet-throughput-dark.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/fleet-throughput-light.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/scale-dark.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/scale-light.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/startup-dark.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/startup-light.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/strong-scaling-dark.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/strong-scaling-light.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/training-step-dark.svg +1 -0
- gpulayer-0.3.0/docs/assets/perf/training-step-light.svg +1 -0
- gpulayer-0.3.0/docs/decisions/ADR-0001-control-plane-and-deployment-model.md +66 -0
- gpulayer-0.3.0/docs/decisions/ADR-0002-job-contracts-and-packaging.md +68 -0
- gpulayer-0.3.0/docs/decisions/ADR-0003-worker-protocol-and-authentication.md +80 -0
- gpulayer-0.3.0/docs/decisions/ADR-0004-scheduling-and-placement-policy.md +75 -0
- gpulayer-0.3.0/docs/decisions/ADR-0005-gpu-capabilities-and-runtime-profiles.md +78 -0
- gpulayer-0.3.0/docs/decisions/ADR-0006-apple-metal-mps-boundaries.md +67 -0
- gpulayer-0.3.0/docs/decisions/ADR-0007-distributed-launch-and-rendezvous.md +77 -0
- gpulayer-0.3.0/docs/decisions/ADR-0008-storage-and-artifact-management.md +55 -0
- gpulayer-0.3.0/docs/decisions/ADR-0009-security-and-workload-isolation.md +66 -0
- gpulayer-0.3.0/docs/decisions/ADR-0010-provider-adapters-and-provisioning.md +75 -0
- gpulayer-0.3.0/docs/decisions/ADR-0011-cost-accounting-and-retry-semantics.md +61 -0
- gpulayer-0.3.0/docs/decisions/ADR-0012-licensing-and-project-governance.md +49 -0
- gpulayer-0.3.0/docs/decisions/ADR-0013-website-and-documentation-stack.md +37 -0
- gpulayer-0.3.0/docs/decisions/ADR-0014-pytorch-integration.md +88 -0
- gpulayer-0.3.0/docs/decisions/ADR-0015-workload-agnostic-core.md +73 -0
- gpulayer-0.3.0/docs/decisions/ADR-0016-performance-parallelism-and-distribution.md +142 -0
- gpulayer-0.3.0/docs/decisions/ADR-0017-distribution-and-installation.md +63 -0
- gpulayer-0.3.0/docs/decisions/ADR-0018-trainer-scope.md +52 -0
- gpulayer-0.3.0/docs/decisions/README.md +63 -0
- gpulayer-0.3.0/docs/get-started/concepts.md +111 -0
- gpulayer-0.3.0/docs/get-started/installation.md +139 -0
- gpulayer-0.3.0/docs/get-started/performance-and-comparison.md +161 -0
- gpulayer-0.3.0/docs/get-started/quickstart.md +236 -0
- gpulayer-0.3.0/docs/guides/ai-agents.md +147 -0
- gpulayer-0.3.0/docs/guides/apple-silicon.md +82 -0
- gpulayer-0.3.0/docs/guides/cloud-providers.md +49 -0
- gpulayer-0.3.0/docs/guides/monitoring.md +115 -0
- gpulayer-0.3.0/docs/guides/nvidia-cuda.md +72 -0
- gpulayer-0.3.0/docs/guides/remote-workers.md +60 -0
- gpulayer-0.3.0/docs/guides/self-hosting.md +118 -0
- gpulayer-0.3.0/docs/index.md +126 -0
- gpulayer-0.3.0/docs/nav.json +179 -0
- gpulayer-0.3.0/docs/project/contributing.md +49 -0
- gpulayer-0.3.0/docs/project/status.md +133 -0
- gpulayer-0.3.0/docs/pytorch/distributed.md +89 -0
- gpulayer-0.3.0/docs/pytorch/launch.md +70 -0
- gpulayer-0.3.0/docs/pytorch/runtime.md +64 -0
- gpulayer-0.3.0/docs/pytorch/trainer.md +197 -0
- gpulayer-0.3.0/docs/reference/cli.md +69 -0
- gpulayer-0.3.0/docs/reference/environment.md +32 -0
- gpulayer-0.3.0/docs/reference/http-api.md +53 -0
- gpulayer-0.3.0/docs/reference/job-spec.md +95 -0
- gpulayer-0.3.0/docs/reference/python-api.md +66 -0
- gpulayer-0.3.0/docs/workloads/commands.md +85 -0
- gpulayer-0.3.0/docs/workloads/distributed.md +44 -0
- gpulayer-0.3.0/docs/workloads/frameworks.md +82 -0
- gpulayer-0.3.0/docs/workloads/functions.md +78 -0
- gpulayer-0.3.0/examples/README.md +31 -0
- gpulayer-0.3.0/examples/launch_ddp_script/train_ddp.py +79 -0
- gpulayer-0.3.0/examples/mlx_metal/matmul.py +40 -0
- gpulayer-0.3.0/examples/numpy_batch/estimate.py +26 -0
- gpulayer-0.3.0/examples/remote_sweep/sweep.py +42 -0
- gpulayer-0.3.0/examples/runtime_custom_loop/train.py +59 -0
- gpulayer-0.3.0/examples/shell_job/README.md +20 -0
- gpulayer-0.3.0/examples/shell_job/report.sh +11 -0
- gpulayer-0.3.0/examples/shell_job/sales.csv +6 -0
- gpulayer-0.3.0/examples/trainer_char_lm/train.py +125 -0
- gpulayer-0.3.0/examples/trainer_image_classifier/train.py +112 -0
- gpulayer-0.3.0/examples/trainer_regression/train.py +77 -0
- gpulayer-0.3.0/install.sh +80 -0
- gpulayer-0.3.0/integrations/skills/gpulayer/SKILL.md +66 -0
- gpulayer-0.3.0/pyproject.toml +97 -0
- gpulayer-0.3.0/src/gpulayer/__init__.py +45 -0
- gpulayer-0.3.0/src/gpulayer/agents/__init__.py +1 -0
- gpulayer-0.3.0/src/gpulayer/agents/mcp_server.py +447 -0
- gpulayer-0.3.0/src/gpulayer/api/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/api/auth.py +179 -0
- gpulayer-0.3.0/src/gpulayer/api/client.py +355 -0
- gpulayer-0.3.0/src/gpulayer/api/server.py +561 -0
- gpulayer-0.3.0/src/gpulayer/api/tls.py +56 -0
- gpulayer-0.3.0/src/gpulayer/api/ui/app.css +165 -0
- gpulayer-0.3.0/src/gpulayer/api/ui/app.js +566 -0
- gpulayer-0.3.0/src/gpulayer/api/ui/icon.svg +1 -0
- gpulayer-0.3.0/src/gpulayer/api/ui/index.html +14 -0
- gpulayer-0.3.0/src/gpulayer/artifacts/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/artifacts/store.py +170 -0
- gpulayer-0.3.0/src/gpulayer/cli/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/cli/main.py +1029 -0
- gpulayer-0.3.0/src/gpulayer/contracts/__init__.py +4 -0
- gpulayer-0.3.0/src/gpulayer/contracts/models.py +737 -0
- gpulayer-0.3.0/src/gpulayer/control_plane/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/control_plane/provisioning.py +414 -0
- gpulayer-0.3.0/src/gpulayer/control_plane/scheduler.py +308 -0
- gpulayer-0.3.0/src/gpulayer/control_plane/service.py +1287 -0
- gpulayer-0.3.0/src/gpulayer/errors.py +58 -0
- gpulayer-0.3.0/src/gpulayer/gpu/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/gpu/discovery.py +383 -0
- gpulayer-0.3.0/src/gpulayer/gpu/support.py +59 -0
- gpulayer-0.3.0/src/gpulayer/observability/__init__.py +1 -0
- gpulayer-0.3.0/src/gpulayer/observability/metrics.py +195 -0
- gpulayer-0.3.0/src/gpulayer/providers/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/providers/base.py +112 -0
- gpulayer-0.3.0/src/gpulayer/providers/fake.py +106 -0
- gpulayer-0.3.0/src/gpulayer/pytorch/__init__.py +35 -0
- gpulayer-0.3.0/src/gpulayer/pytorch/callbacks.py +224 -0
- gpulayer-0.3.0/src/gpulayer/pytorch/launch.py +167 -0
- gpulayer-0.3.0/src/gpulayer/pytorch/module.py +75 -0
- gpulayer-0.3.0/src/gpulayer/pytorch/runtime.py +243 -0
- gpulayer-0.3.0/src/gpulayer/pytorch/trainer.py +487 -0
- gpulayer-0.3.0/src/gpulayer/runtime/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/runtime/dist_function_runner.py +36 -0
- gpulayer-0.3.0/src/gpulayer/runtime/distributed.py +109 -0
- gpulayer-0.3.0/src/gpulayer/runtime/function_runner.py +37 -0
- gpulayer-0.3.0/src/gpulayer/runtime/process.py +116 -0
- gpulayer-0.3.0/src/gpulayer/runtime/rank_launcher.py +94 -0
- gpulayer-0.3.0/src/gpulayer/sdk/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/sdk/builders.py +135 -0
- gpulayer-0.3.0/src/gpulayer/sdk/client.py +247 -0
- gpulayer-0.3.0/src/gpulayer/sdk/home.py +34 -0
- gpulayer-0.3.0/src/gpulayer/sdk/remote.py +305 -0
- gpulayer-0.3.0/src/gpulayer/storage/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/storage/sqlite.py +201 -0
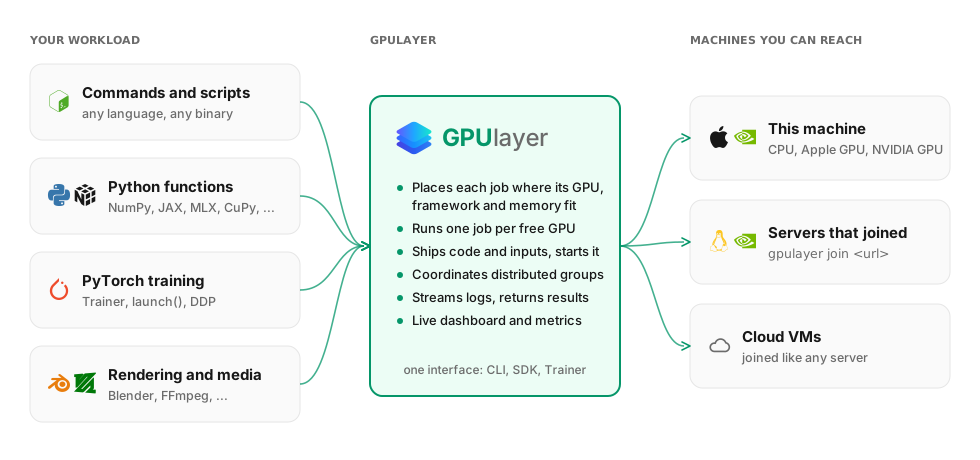
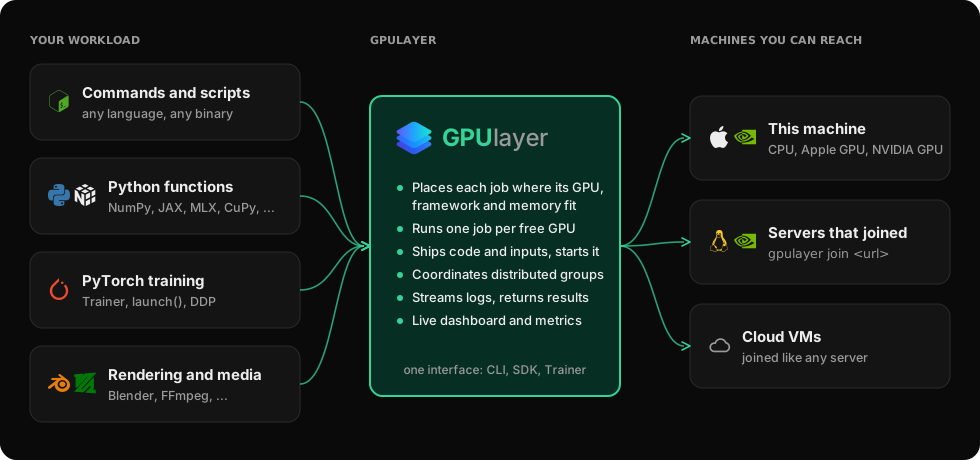
- gpulayer-0.3.0/src/gpulayer/worker/__init__.py +0 -0
- gpulayer-0.3.0/src/gpulayer/worker/agent.py +576 -0
- gpulayer-0.3.0/src/gpulayer/worker/channel.py +95 -0
- gpulayer-0.3.0/src/gpulayer/worker/telemetry.py +121 -0
- gpulayer-0.3.0/tests/conftest.py +99 -0
- gpulayer-0.3.0/tests/distributed/test_torchrun_multiprocess.py +149 -0
- gpulayer-0.3.0/tests/hardware/test_gpu_smoke.py +48 -0
- gpulayer-0.3.0/tests/integration/remote_pkg/__init__.py +0 -0
- gpulayer-0.3.0/tests/integration/remote_pkg/funcs.py +28 -0
- gpulayer-0.3.0/tests/integration/test_auth_roles.py +181 -0
- gpulayer-0.3.0/tests/integration/test_cli.py +112 -0
- gpulayer-0.3.0/tests/integration/test_http_remote.py +163 -0
- gpulayer-0.3.0/tests/integration/test_local_execution.py +170 -0
- gpulayer-0.3.0/tests/integration/test_mcp_server.py +139 -0
- gpulayer-0.3.0/tests/integration/test_metrics_dashboard.py +172 -0
- gpulayer-0.3.0/tests/integration/test_remote.py +76 -0
- gpulayer-0.3.0/tests/integration/test_up_join.py +82 -0
- gpulayer-0.3.0/tests/integration/test_worker_concurrency.py +36 -0
- gpulayer-0.3.0/tests/pytorch/test_callbacks.py +206 -0
- gpulayer-0.3.0/tests/pytorch/test_trainer.py +312 -0
- gpulayer-0.3.0/tests/unit/test_artifacts.py +15 -0
- gpulayer-0.3.0/tests/unit/test_concurrency.py +110 -0
- gpulayer-0.3.0/tests/unit/test_contracts.py +147 -0
- gpulayer-0.3.0/tests/unit/test_control_plane.py +373 -0
- gpulayer-0.3.0/tests/unit/test_discovery.py +164 -0
- gpulayer-0.3.0/tests/unit/test_gc.py +76 -0
- gpulayer-0.3.0/tests/unit/test_providers.py +243 -0
- gpulayer-0.3.0/tests/unit/test_rank_launcher.py +51 -0
- gpulayer-0.3.0/tests/unit/test_scheduler.py +263 -0
- gpulayer-0.3.0/tests/unit/test_telemetry.py +67 -0
- gpulayer-0.3.0/tests/unit/test_version.py +20 -0
|
@@ -0,0 +1,139 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to GPUlayer. Versions follow [semantic versioning](https://semver.org);
|
|
4
|
+
before 1.0, minor versions may change public APIs, with migration notes here.
|
|
5
|
+
|
|
6
|
+
## 0.3.0 (2026-10-30)
|
|
7
|
+
|
|
8
|
+
First release on PyPI (`pip install gpulayer`), under the Apache-2.0 licence. Tested on 30
|
|
9
|
+
machines in two GCP regions, with a multi-machine training comparison against PyTorch
|
|
10
|
+
Lightning.
|
|
11
|
+
|
|
12
|
+
### Scale and speed
|
|
13
|
+
|
|
14
|
+
- Scheduling no longer slows down as the queue grows: a submit costs 0.5 ms at 2,000 queued
|
|
15
|
+
jobs instead of 44 ms (`benchmarks/submit_queue.py`).
|
|
16
|
+
- Behind `gpulayer up`, idle workers wait until something changes instead of re-checking
|
|
17
|
+
every 0.2 s, and a change wakes only the workers or job waiters it concerns. On 30 workers
|
|
18
|
+
a 480-run training sweep finished in 45 s instead of 102 s.
|
|
19
|
+
- SQLite runs with `synchronous=NORMAL` (WAL): commits no longer wait for the disk (2.25 ms
|
|
20
|
+
to 0.02 ms on a GCP standard disk). Consistent after a crash; a power loss can roll back
|
|
21
|
+
the last commits.
|
|
22
|
+
- The Trainer does less work per step (0.60 to 0.585 ms on a small CPU model; a plain
|
|
23
|
+
PyTorch loop is 0.55).
|
|
24
|
+
- Validated on 30 workers in two regions: distributed jobs on up to 16 machines (32
|
|
25
|
+
processes), fail-fast across 8 machines in 4.9 s, retries after killing workers mid-run.
|
|
26
|
+
One training job on 8 machines ran 3.4x faster than on one, and 7% sooner than PyTorch
|
|
27
|
+
Lightning under torchrun (benchmarks/results/2026-10-30-gcp-fleet).
|
|
28
|
+
- Known limit: bursts of very short jobs reach about 25 jobs/s, bounded by the server using
|
|
29
|
+
one CPU core (ADR-0016, item 6).
|
|
30
|
+
|
|
31
|
+
### Features and fixes
|
|
32
|
+
|
|
33
|
+
- `--gpus 0,1|none` on `gpulayer up`, `join` and `worker start`: a worker offers only those
|
|
34
|
+
GPUs, so several workers on one machine no longer offer the same GPU (the known issue in
|
|
35
|
+
0.2.0). `--gpus none` makes a CPU-only worker on a GPU machine.
|
|
36
|
+
- CUDA jobs get `CUDA_DEVICE_ORDER=PCI_BUS_ID`, so `CUDA_VISIBLE_DEVICES` selects the GPUs
|
|
37
|
+
that were reserved (`nvidia-smi` numbering) on machines with mixed GPU models.
|
|
38
|
+
- Trainer: `max_steps`, `check_val_every_n_epoch`, `trainer.test()` with `Module.test_step`
|
|
39
|
+
and `trainer.predict()` with `Module.predict_step` (ADR-0018).
|
|
40
|
+
- `ModelCheckpoint(save_top_k=N)` keeps the N best epochs (also after remote runs), and a
|
|
41
|
+
`LearningRateMonitor` callback records each epoch's learning rate.
|
|
42
|
+
- `val_check_interval` (batches or a fraction of the epoch) and `metrics.csv` next to
|
|
43
|
+
`metrics.json`, with step, mid-epoch validation and epoch rows.
|
|
44
|
+
- A launched training run returns its metrics even with checkpointing off (`metrics.json` is
|
|
45
|
+
written every epoch).
|
|
46
|
+
- Apache-2.0 licence (ADR-0012), PyPI package metadata, and a trusted-publishing release
|
|
47
|
+
workflow (`.github/workflows/publish.yml`).
|
|
48
|
+
- Benchmarks: `benchmarks/cloud/gcp.sh` builds an image and starts a server plus a fleet of
|
|
49
|
+
workers; `benchmarks/scale_test.py`; `benchmarks/lightning_comparison/scaling_run.py` and
|
|
50
|
+
`multinode.py` compare multi-machine training with PyTorch Lightning.
|
|
51
|
+
|
|
52
|
+
## 0.2.0 (2026-10-30)
|
|
53
|
+
|
|
54
|
+
Validated on an NVIDIA GPU and across machines, faster distributed start-up and HTTP API, and
|
|
55
|
+
a measured comparison with PyTorch Lightning.
|
|
56
|
+
|
|
57
|
+
### Migration from 0.1.0
|
|
58
|
+
|
|
59
|
+
- Distributed jobs default to `launcher="direct"`. Upgrade the server and the workers
|
|
60
|
+
together: 0.1.0 workers are not chosen for `direct` jobs, and a 0.1.0 server rejects them.
|
|
61
|
+
Pass `launcher="torchrun"` (`--launcher torchrun`) to keep the old behaviour.
|
|
62
|
+
|
|
63
|
+
### Changes
|
|
64
|
+
|
|
65
|
+
- `gpulayer mcp`: a Model Context Protocol server on stdio, so AI and coding agents can list
|
|
66
|
+
resources, submit commands (with a project directory and inputs), wait, read logs, cancel
|
|
67
|
+
and download outputs; `--read-only` for monitoring. Tested with the official MCP Python SDK.
|
|
68
|
+
- Agent Skill for the CLI in `integrations/skills/gpulayer`.
|
|
69
|
+
- Guide: AI and coding agents.
|
|
70
|
+
- Trainer callbacks: `Callback` hooks, `EarlyStopping` and `ModelCheckpoint` (best checkpoint,
|
|
71
|
+
also returned from remote runs); when one DDP rank asks to stop, every rank stops after the
|
|
72
|
+
same epoch.
|
|
73
|
+
- Faster distributed jobs: `DistributedJob.launcher="direct"` is the new default. Workers
|
|
74
|
+
start the ranks themselves, with the same environment torchrun sets, instead of through
|
|
75
|
+
torchrun's elastic agent: a 2 x 2 job on one Mac takes 0.93 s instead of about 2.1 s.
|
|
76
|
+
`launcher="torchrun"` (`--launcher torchrun`) keeps the old behaviour.
|
|
77
|
+
Migration: workers and the server must both be upgraded to run `direct` jobs. v0.1.0
|
|
78
|
+
workers report only `torchrun` and are not chosen for them; a v0.1.0 server rejects the
|
|
79
|
+
new value, so submit with `launcher="torchrun"` there.
|
|
80
|
+
- Faster HTTP API: clients and workers keep their connection open, and the server sets
|
|
81
|
+
`TCP_NODELAY` and runs TLS handshakes per connection. On Linux a request dropped from 43 ms
|
|
82
|
+
to 0.6 ms, and 500 small jobs over two machines ran 7.1x faster (7.8 to 55.6 jobs/s).
|
|
83
|
+
- Validated on NVIDIA: a Tesla T4 on GCP (CUDA detection, CUDA jobs, Trainer in fp32, bf16,
|
|
84
|
+
fp16 and with `torch.compile`, GPU reservation), and on two machines over a real network
|
|
85
|
+
(distributed jobs across both, fail-fast, hundreds of jobs). `scripts/validate_gpu.sh`
|
|
86
|
+
repeats the single-machine part on any NVIDIA machine.
|
|
87
|
+
- Performance and comparison: a docs page and README section with charts
|
|
88
|
+
(`scripts/make_perf_charts.py`), the GPUlayer vs PyTorch Lightning harness
|
|
89
|
+
(`benchmarks/lightning_comparison/`), `benchmarks/multi_machine.py`, raw results in
|
|
90
|
+
`benchmarks/results/2026-10-30-gcp/`, and `benchmarks/cloud/gcp.sh` to rerun them on Google
|
|
91
|
+
Cloud.
|
|
92
|
+
- NVIDIA CUDA independent jobs are now `hardware-validated` in the support matrix.
|
|
93
|
+
|
|
94
|
+
## 0.1.0 (2026-10-29)
|
|
95
|
+
|
|
96
|
+
The first release. GPUlayer runs commands, Python functions and distributed jobs on the
|
|
97
|
+
machines you can reach, from a laptop to servers that joined a control plane.
|
|
98
|
+
|
|
99
|
+
### Run work
|
|
100
|
+
|
|
101
|
+
- Job types: commands in any language, Python functions (`@gl.remote`, `.map()`), and
|
|
102
|
+
distributed jobs launched with torchrun (static rendezvous, gang scheduling, fail-fast).
|
|
103
|
+
- PyTorch integration: `Module`, `Trainer` (in-process, multi-process DDP, multi-node,
|
|
104
|
+
remote), `Runtime` and `launch()`; gradient accumulation with DDP `no_sync`.
|
|
105
|
+
- Runtime profiles (`pytorch-cuda`, `pytorch-mps`, `jax-cuda`, `cupy-cuda`, `mlx`, ...).
|
|
106
|
+
|
|
107
|
+
### Place and run it well
|
|
108
|
+
|
|
109
|
+
- Capability-aware scheduler with per-worker reasons when a job cannot run.
|
|
110
|
+
- Several tasks per worker, each with its own reserved GPUs (default one slot per NVIDIA or
|
|
111
|
+
AMD GPU); `spread` placement keeps machines evenly busy.
|
|
112
|
+
- Event-driven dispatch: long-poll worker acquire and job waits, background log shipping.
|
|
113
|
+
One job on an idle worker: 626 ms to 31 ms; burst throughput 27 to 87 jobs/s (one Mac).
|
|
114
|
+
- Per-rank log streams for distributed jobs.
|
|
115
|
+
|
|
116
|
+
### Servers and workers
|
|
117
|
+
|
|
118
|
+
- `gpulayer up` (control plane with TLS and a pinned self-signed certificate) and
|
|
119
|
+
`gpulayer join`; named, expiring, revocable tokens with roles (admin, submitter, join,
|
|
120
|
+
metrics); rate-limited logins; worker artifact scoping; retention and `gpulayer gc`.
|
|
121
|
+
|
|
122
|
+
### Observe
|
|
123
|
+
|
|
124
|
+
- Web dashboard: jobs, live logs, placement reasons, workers, and activity charts (jobs,
|
|
125
|
+
CPU load, memory, task processes, NVIDIA GPU utilisation).
|
|
126
|
+
- Prometheus `/metrics`, a Grafana dashboard and a Prometheus/Grafana Compose setup.
|
|
127
|
+
|
|
128
|
+
### Install
|
|
129
|
+
|
|
130
|
+
- `install.sh` (curl one-liner, private virtualenv, no sudo), a Docker image for server and
|
|
131
|
+
workers (CPU or CUDA base) with Compose, and CI that tests all of it.
|
|
132
|
+
|
|
133
|
+
### Validation status
|
|
134
|
+
|
|
135
|
+
- Tested on CPU and Apple Silicon (PyTorch MPS and MLX), with several workers on one host,
|
|
136
|
+
and in Linux CI including a Docker server/worker test.
|
|
137
|
+
- NVIDIA CUDA execution and multi-machine runs are implemented but not validated on hardware.
|
|
138
|
+
- Cloud provisioning is simulated (`FakeProvider`); cloud VMs can join with `gpulayer join`.
|
|
139
|
+
- Not a sandbox for untrusted code. See docs/project/status.md.
|
gpulayer-0.3.0/LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
1
|
+
|
|
2
|
+
Apache License
|
|
3
|
+
Version 2.0, January 2004
|
|
4
|
+
http://www.apache.org/licenses/
|
|
5
|
+
|
|
6
|
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
|
7
|
+
|
|
8
|
+
1. Definitions.
|
|
9
|
+
|
|
10
|
+
"License" shall mean the terms and conditions for use, reproduction,
|
|
11
|
+
and distribution as defined by Sections 1 through 9 of this document.
|
|
12
|
+
|
|
13
|
+
"Licensor" shall mean the copyright owner or entity authorized by
|
|
14
|
+
the copyright owner that is granting the License.
|
|
15
|
+
|
|
16
|
+
"Legal Entity" shall mean the union of the acting entity and all
|
|
17
|
+
other entities that control, are controlled by, or are under common
|
|
18
|
+
control with that entity. For the purposes of this definition,
|
|
19
|
+
"control" means (i) the power, direct or indirect, to cause the
|
|
20
|
+
direction or management of such entity, whether by contract or
|
|
21
|
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
|
22
|
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
|
23
|
+
|
|
24
|
+
"You" (or "Your") shall mean an individual or Legal Entity
|
|
25
|
+
exercising permissions granted by this License.
|
|
26
|
+
|
|
27
|
+
"Source" form shall mean the preferred form for making modifications,
|
|
28
|
+
including but not limited to software source code, documentation
|
|
29
|
+
source, and configuration files.
|
|
30
|
+
|
|
31
|
+
"Object" form shall mean any form resulting from mechanical
|
|
32
|
+
transformation or translation of a Source form, including but
|
|
33
|
+
not limited to compiled object code, generated documentation,
|
|
34
|
+
and conversions to other media types.
|
|
35
|
+
|
|
36
|
+
"Work" shall mean the work of authorship, whether in Source or
|
|
37
|
+
Object form, made available under the License, as indicated by a
|
|
38
|
+
copyright notice that is included in or attached to the work
|
|
39
|
+
(an example is provided in the Appendix below).
|
|
40
|
+
|
|
41
|
+
"Derivative Works" shall mean any work, whether in Source or Object
|
|
42
|
+
form, that is based on (or derived from) the Work and for which the
|
|
43
|
+
editorial revisions, annotations, elaborations, or other modifications
|
|
44
|
+
represent, as a whole, an original work of authorship. For the purposes
|
|
45
|
+
of this License, Derivative Works shall not include works that remain
|
|
46
|
+
separable from, or merely link (or bind by name) to the interfaces of,
|
|
47
|
+
the Work and Derivative Works thereof.
|
|
48
|
+
|
|
49
|
+
"Contribution" shall mean any work of authorship, including
|
|
50
|
+
the original version of the Work and any modifications or additions
|
|
51
|
+
to that Work or Derivative Works thereof, that is intentionally
|
|
52
|
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
|
53
|
+
or by an individual or Legal Entity authorized to submit on behalf of
|
|
54
|
+
the copyright owner. For the purposes of this definition, "submitted"
|
|
55
|
+
means any form of electronic, verbal, or written communication sent
|
|
56
|
+
to the Licensor or its representatives, including but not limited to
|
|
57
|
+
communication on electronic mailing lists, source code control systems,
|
|
58
|
+
and issue tracking systems that are managed by, or on behalf of, the
|
|
59
|
+
Licensor for the purpose of discussing and improving the Work, but
|
|
60
|
+
excluding communication that is conspicuously marked or otherwise
|
|
61
|
+
designated in writing by the copyright owner as "Not a Contribution."
|
|
62
|
+
|
|
63
|
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
|
64
|
+
on behalf of whom a Contribution has been received by Licensor and
|
|
65
|
+
subsequently incorporated within the Work.
|
|
66
|
+
|
|
67
|
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
|
68
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
69
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
70
|
+
copyright license to reproduce, prepare Derivative Works of,
|
|
71
|
+
publicly display, publicly perform, sublicense, and distribute the
|
|
72
|
+
Work and such Derivative Works in Source or Object form.
|
|
73
|
+
|
|
74
|
+
3. Grant of Patent License. Subject to the terms and conditions of
|
|
75
|
+
this License, each Contributor hereby grants to You a perpetual,
|
|
76
|
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
|
77
|
+
(except as stated in this section) patent license to make, have made,
|
|
78
|
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
|
79
|
+
where such license applies only to those patent claims licensable
|
|
80
|
+
by such Contributor that are necessarily infringed by their
|
|
81
|
+
Contribution(s) alone or by combination of their Contribution(s)
|
|
82
|
+
with the Work to which such Contribution(s) was submitted. If You
|
|
83
|
+
institute patent litigation against any entity (including a
|
|
84
|
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
|
85
|
+
or a Contribution incorporated within the Work constitutes direct
|
|
86
|
+
or contributory patent infringement, then any patent licenses
|
|
87
|
+
granted to You under this License for that Work shall terminate
|
|
88
|
+
as of the date such litigation is filed.
|
|
89
|
+
|
|
90
|
+
4. Redistribution. You may reproduce and distribute copies of the
|
|
91
|
+
Work or Derivative Works thereof in any medium, with or without
|
|
92
|
+
modifications, and in Source or Object form, provided that You
|
|
93
|
+
meet the following conditions:
|
|
94
|
+
|
|
95
|
+
(a) You must give any other recipients of the Work or
|
|
96
|
+
Derivative Works a copy of this License; and
|
|
97
|
+
|
|
98
|
+
(b) You must cause any modified files to carry prominent notices
|
|
99
|
+
stating that You changed the files; and
|
|
100
|
+
|
|
101
|
+
(c) You must retain, in the Source form of any Derivative Works
|
|
102
|
+
that You distribute, all copyright, patent, trademark, and
|
|
103
|
+
attribution notices from the Source form of the Work,
|
|
104
|
+
excluding those notices that do not pertain to any part of
|
|
105
|
+
the Derivative Works; and
|
|
106
|
+
|
|
107
|
+
(d) If the Work includes a "NOTICE" text file as part of its
|
|
108
|
+
distribution, then any Derivative Works that You distribute must
|
|
109
|
+
include a readable copy of the attribution notices contained
|
|
110
|
+
within such NOTICE file, excluding those notices that do not
|
|
111
|
+
pertain to any part of the Derivative Works, in at least one
|
|
112
|
+
of the following places: within a NOTICE text file distributed
|
|
113
|
+
as part of the Derivative Works; within the Source form or
|
|
114
|
+
documentation, if provided along with the Derivative Works; or,
|
|
115
|
+
within a display generated by the Derivative Works, if and
|
|
116
|
+
wherever such third-party notices normally appear. The contents
|
|
117
|
+
of the NOTICE file are for informational purposes only and
|
|
118
|
+
do not modify the License. You may add Your own attribution
|
|
119
|
+
notices within Derivative Works that You distribute, alongside
|
|
120
|
+
or as an addendum to the NOTICE text from the Work, provided
|
|
121
|
+
that such additional attribution notices cannot be construed
|
|
122
|
+
as modifying the License.
|
|
123
|
+
|
|
124
|
+
You may add Your own copyright statement to Your modifications and
|
|
125
|
+
may provide additional or different license terms and conditions
|
|
126
|
+
for use, reproduction, or distribution of Your modifications, or
|
|
127
|
+
for any such Derivative Works as a whole, provided Your use,
|
|
128
|
+
reproduction, and distribution of the Work otherwise complies with
|
|
129
|
+
the conditions stated in this License.
|
|
130
|
+
|
|
131
|
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
|
132
|
+
any Contribution intentionally submitted for inclusion in the Work
|
|
133
|
+
by You to the Licensor shall be under the terms and conditions of
|
|
134
|
+
this License, without any additional terms or conditions.
|
|
135
|
+
Notwithstanding the above, nothing herein shall supersede or modify
|
|
136
|
+
the terms of any separate license agreement you may have executed
|
|
137
|
+
with Licensor regarding such Contributions.
|
|
138
|
+
|
|
139
|
+
6. Trademarks. This License does not grant permission to use the trade
|
|
140
|
+
names, trademarks, service marks, or product names of the Licensor,
|
|
141
|
+
except as required for reasonable and customary use in describing the
|
|
142
|
+
origin of the Work and reproducing the content of the NOTICE file.
|
|
143
|
+
|
|
144
|
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
|
145
|
+
agreed to in writing, Licensor provides the Work (and each
|
|
146
|
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
|
147
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
|
148
|
+
implied, including, without limitation, any warranties or conditions
|
|
149
|
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
|
150
|
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
|
151
|
+
appropriateness of using or redistributing the Work and assume any
|
|
152
|
+
risks associated with Your exercise of permissions under this License.
|
|
153
|
+
|
|
154
|
+
8. Limitation of Liability. In no event and under no legal theory,
|
|
155
|
+
whether in tort (including negligence), contract, or otherwise,
|
|
156
|
+
unless required by applicable law (such as deliberate and grossly
|
|
157
|
+
negligent acts) or agreed to in writing, shall any Contributor be
|
|
158
|
+
liable to You for damages, including any direct, indirect, special,
|
|
159
|
+
incidental, or consequential damages of any character arising as a
|
|
160
|
+
result of this License or out of the use or inability to use the
|
|
161
|
+
Work (including but not limited to damages for loss of goodwill,
|
|
162
|
+
work stoppage, computer failure or malfunction, or any and all
|
|
163
|
+
other commercial damages or losses), even if such Contributor
|
|
164
|
+
has been advised of the possibility of such damages.
|
|
165
|
+
|
|
166
|
+
9. Accepting Warranty or Additional Liability. While redistributing
|
|
167
|
+
the Work or Derivative Works thereof, You may choose to offer,
|
|
168
|
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
|
169
|
+
or other liability obligations and/or rights consistent with this
|
|
170
|
+
License. However, in accepting such obligations, You may act only
|
|
171
|
+
on Your own behalf and on Your sole responsibility, not on behalf
|
|
172
|
+
of any other Contributor, and only if You agree to indemnify,
|
|
173
|
+
defend, and hold each Contributor harmless for any liability
|
|
174
|
+
incurred by, or claims asserted against, such Contributor by reason
|
|
175
|
+
of your accepting any such warranty or additional liability.
|
|
176
|
+
|
|
177
|
+
END OF TERMS AND CONDITIONS
|
|
178
|
+
|
|
179
|
+
APPENDIX: How to apply the Apache License to your work.
|
|
180
|
+
|
|
181
|
+
To apply the Apache License to your work, attach the following
|
|
182
|
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
|
183
|
+
replaced with your own identifying information. (Don't include
|
|
184
|
+
the brackets!) The text should be enclosed in the appropriate
|
|
185
|
+
comment syntax for the file format. We also recommend that a
|
|
186
|
+
file or class name and description of purpose be included on the
|
|
187
|
+
same "printed page" as the copyright notice for easier
|
|
188
|
+
identification within third-party archives.
|
|
189
|
+
|
|
190
|
+
Copyright [yyyy] [name of copyright owner]
|
|
191
|
+
|
|
192
|
+
Licensed under the Apache License, Version 2.0 (the "License");
|
|
193
|
+
you may not use this file except in compliance with the License.
|
|
194
|
+
You may obtain a copy of the License at
|
|
195
|
+
|
|
196
|
+
http://www.apache.org/licenses/LICENSE-2.0
|
|
197
|
+
|
|
198
|
+
Unless required by applicable law or agreed to in writing, software
|
|
199
|
+
distributed under the License is distributed on an "AS IS" BASIS,
|
|
200
|
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
|
201
|
+
See the License for the specific language governing permissions and
|
|
202
|
+
limitations under the License.
|
gpulayer-0.3.0/PKG-INFO
ADDED
|
@@ -0,0 +1,216 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: gpulayer
|
|
3
|
+
Version: 0.3.0
|
|
4
|
+
Summary: Run any workload on every GPU and CPU you can reach: job orchestration across local, remote and cloud machines, distributed PyTorch, a web dashboard and an MCP server for AI agents.
|
|
5
|
+
Project-URL: Homepage, https://www.gpulayer.dev
|
|
6
|
+
Project-URL: Documentation, https://www.gpulayer.dev/docs/
|
|
7
|
+
Project-URL: Source, https://github.com/antonellof/gpulayer
|
|
8
|
+
Project-URL: Changelog, https://github.com/antonellof/gpulayer/blob/main/CHANGELOG.md
|
|
9
|
+
Project-URL: Issues, https://github.com/antonellof/gpulayer/issues
|
|
10
|
+
Author: Antonello
|
|
11
|
+
License-Expression: Apache-2.0
|
|
12
|
+
License-File: LICENSE
|
|
13
|
+
Keywords: apple-silicon,cuda,distributed,gpu,mcp,mlops,orchestration,pytorch,scheduler
|
|
14
|
+
Classifier: Development Status :: 3 - Alpha
|
|
15
|
+
Classifier: Intended Audience :: Developers
|
|
16
|
+
Classifier: Intended Audience :: Science/Research
|
|
17
|
+
Classifier: Operating System :: MacOS
|
|
18
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
19
|
+
Classifier: Programming Language :: Python :: 3
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
22
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
23
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
24
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
25
|
+
Classifier: Topic :: System :: Distributed Computing
|
|
26
|
+
Requires-Python: >=3.10
|
|
27
|
+
Requires-Dist: packaging>=23
|
|
28
|
+
Requires-Dist: pydantic<3,>=2.5
|
|
29
|
+
Provides-Extra: dev
|
|
30
|
+
Requires-Dist: mypy>=1.8; extra == 'dev'
|
|
31
|
+
Requires-Dist: prometheus-client>=0.20; extra == 'dev'
|
|
32
|
+
Requires-Dist: pytest>=7.4; extra == 'dev'
|
|
33
|
+
Requires-Dist: ruff>=0.4; extra == 'dev'
|
|
34
|
+
Provides-Extra: examples
|
|
35
|
+
Requires-Dist: mlx>=0.10; (sys_platform == 'darwin' and platform_machine == 'arm64') and extra == 'examples'
|
|
36
|
+
Requires-Dist: numpy>=1.20; extra == 'examples'
|
|
37
|
+
Requires-Dist: torch>=2.1; extra == 'examples'
|
|
38
|
+
Provides-Extra: torch
|
|
39
|
+
Requires-Dist: torch>=2.1; extra == 'torch'
|
|
40
|
+
Description-Content-Type: text/markdown
|
|
41
|
+
|
|
42
|
+
<p align="center">
|
|
43
|
+
<img src="https://raw.githubusercontent.com/antonellof/gpulayer/main/docs/assets/logo.svg" alt="GPUlayer" width="300">
|
|
44
|
+
</p>
|
|
45
|
+
|
|
46
|
+
<p align="center">
|
|
47
|
+
<b>Run any workload on every GPU and CPU you can reach.</b><br>
|
|
48
|
+
<a href="#install">Install</a> ·
|
|
49
|
+
<a href="#quickstart">Quickstart</a> ·
|
|
50
|
+
<a href="#for-ai-and-coding-agents">AI agents</a> ·
|
|
51
|
+
<a href="#why-gpulayer">Why GPUlayer</a> ·
|
|
52
|
+
<a href="#performance-and-comparison">Performance</a> ·
|
|
53
|
+
<a href="#architecture">Architecture</a> ·
|
|
54
|
+
<a href="https://www.gpulayer.dev/docs/">Docs</a> ·
|
|
55
|
+
<a href="https://github.com/antonellof/gpulayer/tree/main/examples">Examples</a> ·
|
|
56
|
+
<a href="https://github.com/antonellof/gpulayer/blob/main/CHANGELOG.md">Changelog</a>
|
|
57
|
+
</p>
|
|
58
|
+
|
|
59
|
+
GPUlayer sends a command, a Python function or a distributed job to machines that can run
|
|
60
|
+
it (this one, remote servers, clusters, data centers, cloud VMs, or several at once), starts
|
|
61
|
+
it there and brings back logs, outputs and results. PyTorch gets a deeper integration on top.
|
|
62
|
+
Documentation: [gpulayer.dev/docs](https://www.gpulayer.dev/docs/).
|
|
63
|
+
|
|
64
|
+
> **v0.3.0.** Tested on CPU, Apple Silicon (PyTorch MPS and MLX) and an
|
|
65
|
+
> NVIDIA Tesla T4, and on up to 30 machines on Google Cloud. Several GPUs per machine and NCCL
|
|
66
|
+
> across machines are implemented but not validated yet; cloud provisioning is simulated. See
|
|
67
|
+
> [Status and roadmap](https://github.com/antonellof/gpulayer/blob/main/docs/project/status.md).
|
|
68
|
+
|
|
69
|
+
## Install
|
|
70
|
+
|
|
71
|
+
```bash
|
|
72
|
+
pip install gpulayer
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
That's it. Check what this machine can run:
|
|
76
|
+
|
|
77
|
+
```bash
|
|
78
|
+
gpulayer resources detect
|
|
79
|
+
```
|
|
80
|
+
|
|
81
|
+
To train with PyTorch, install it too: `pip install "gpulayer[torch]"`.
|
|
82
|
+
|
|
83
|
+
<details>
|
|
84
|
+
<summary>Other ways to install</summary>
|
|
85
|
+
|
|
86
|
+
| Method | Command |
|
|
87
|
+
|---|---|
|
|
88
|
+
| As a standalone CLI with [uv](https://docs.astral.sh/uv/) | `uv tool install gpulayer` |
|
|
89
|
+
| Install script (own virtual environment, no sudo) | `curl -fsSL https://raw.githubusercontent.com/antonellof/gpulayer/main/install.sh \| sh` |
|
|
90
|
+
| Docker | `docker build -t gpulayer .` (see [deploy/docker](https://github.com/antonellof/gpulayer/tree/main/deploy/docker)) |
|
|
91
|
+
| From source, to run the examples | `git clone https://github.com/antonellof/gpulayer && cd gpulayer && pip install -e ".[dev,examples]"` |
|
|
92
|
+
|
|
93
|
+
More in [Installation](https://github.com/antonellof/gpulayer/blob/main/docs/get-started/installation.md).
|
|
94
|
+
</details>
|
|
95
|
+
|
|
96
|
+
## Quickstart
|
|
97
|
+
|
|
98
|
+
```bash
|
|
99
|
+
# Any command as a job: code and inputs shipped, outputs returned
|
|
100
|
+
gpulayer submit --accelerator cuda --source ./app -- ./render.sh
|
|
101
|
+
|
|
102
|
+
# PyTorch: the same script in this process, as 2-process DDP, or on 2 nodes
|
|
103
|
+
python examples/trainer_regression/train.py
|
|
104
|
+
python examples/trainer_regression/train.py --accelerator cpu --devices 2
|
|
105
|
+
python examples/trainer_regression/train.py --accelerator cpu --nodes 2 --devices 2
|
|
106
|
+
|
|
107
|
+
# More machines: run this on the server, then paste the printed `gpulayer join` line elsewhere
|
|
108
|
+
gpulayer up
|
|
109
|
+
|
|
110
|
+
# See what ran
|
|
111
|
+
gpulayer dashboard
|
|
112
|
+
```
|
|
113
|
+
|
|
114
|
+
```python
|
|
115
|
+
import gpulayer as gl
|
|
116
|
+
|
|
117
|
+
@gl.remote(accelerator="mps", frameworks={"mlx": ">=0.10"}) # any library, any GPU
|
|
118
|
+
def benchmark(n: int) -> dict: ...
|
|
119
|
+
|
|
120
|
+
benchmark.map([1024, 2048, 4096]) # in parallel
|
|
121
|
+
```
|
|
122
|
+
|
|
123
|
+
|
|
124
|
+
|
|
125
|
+
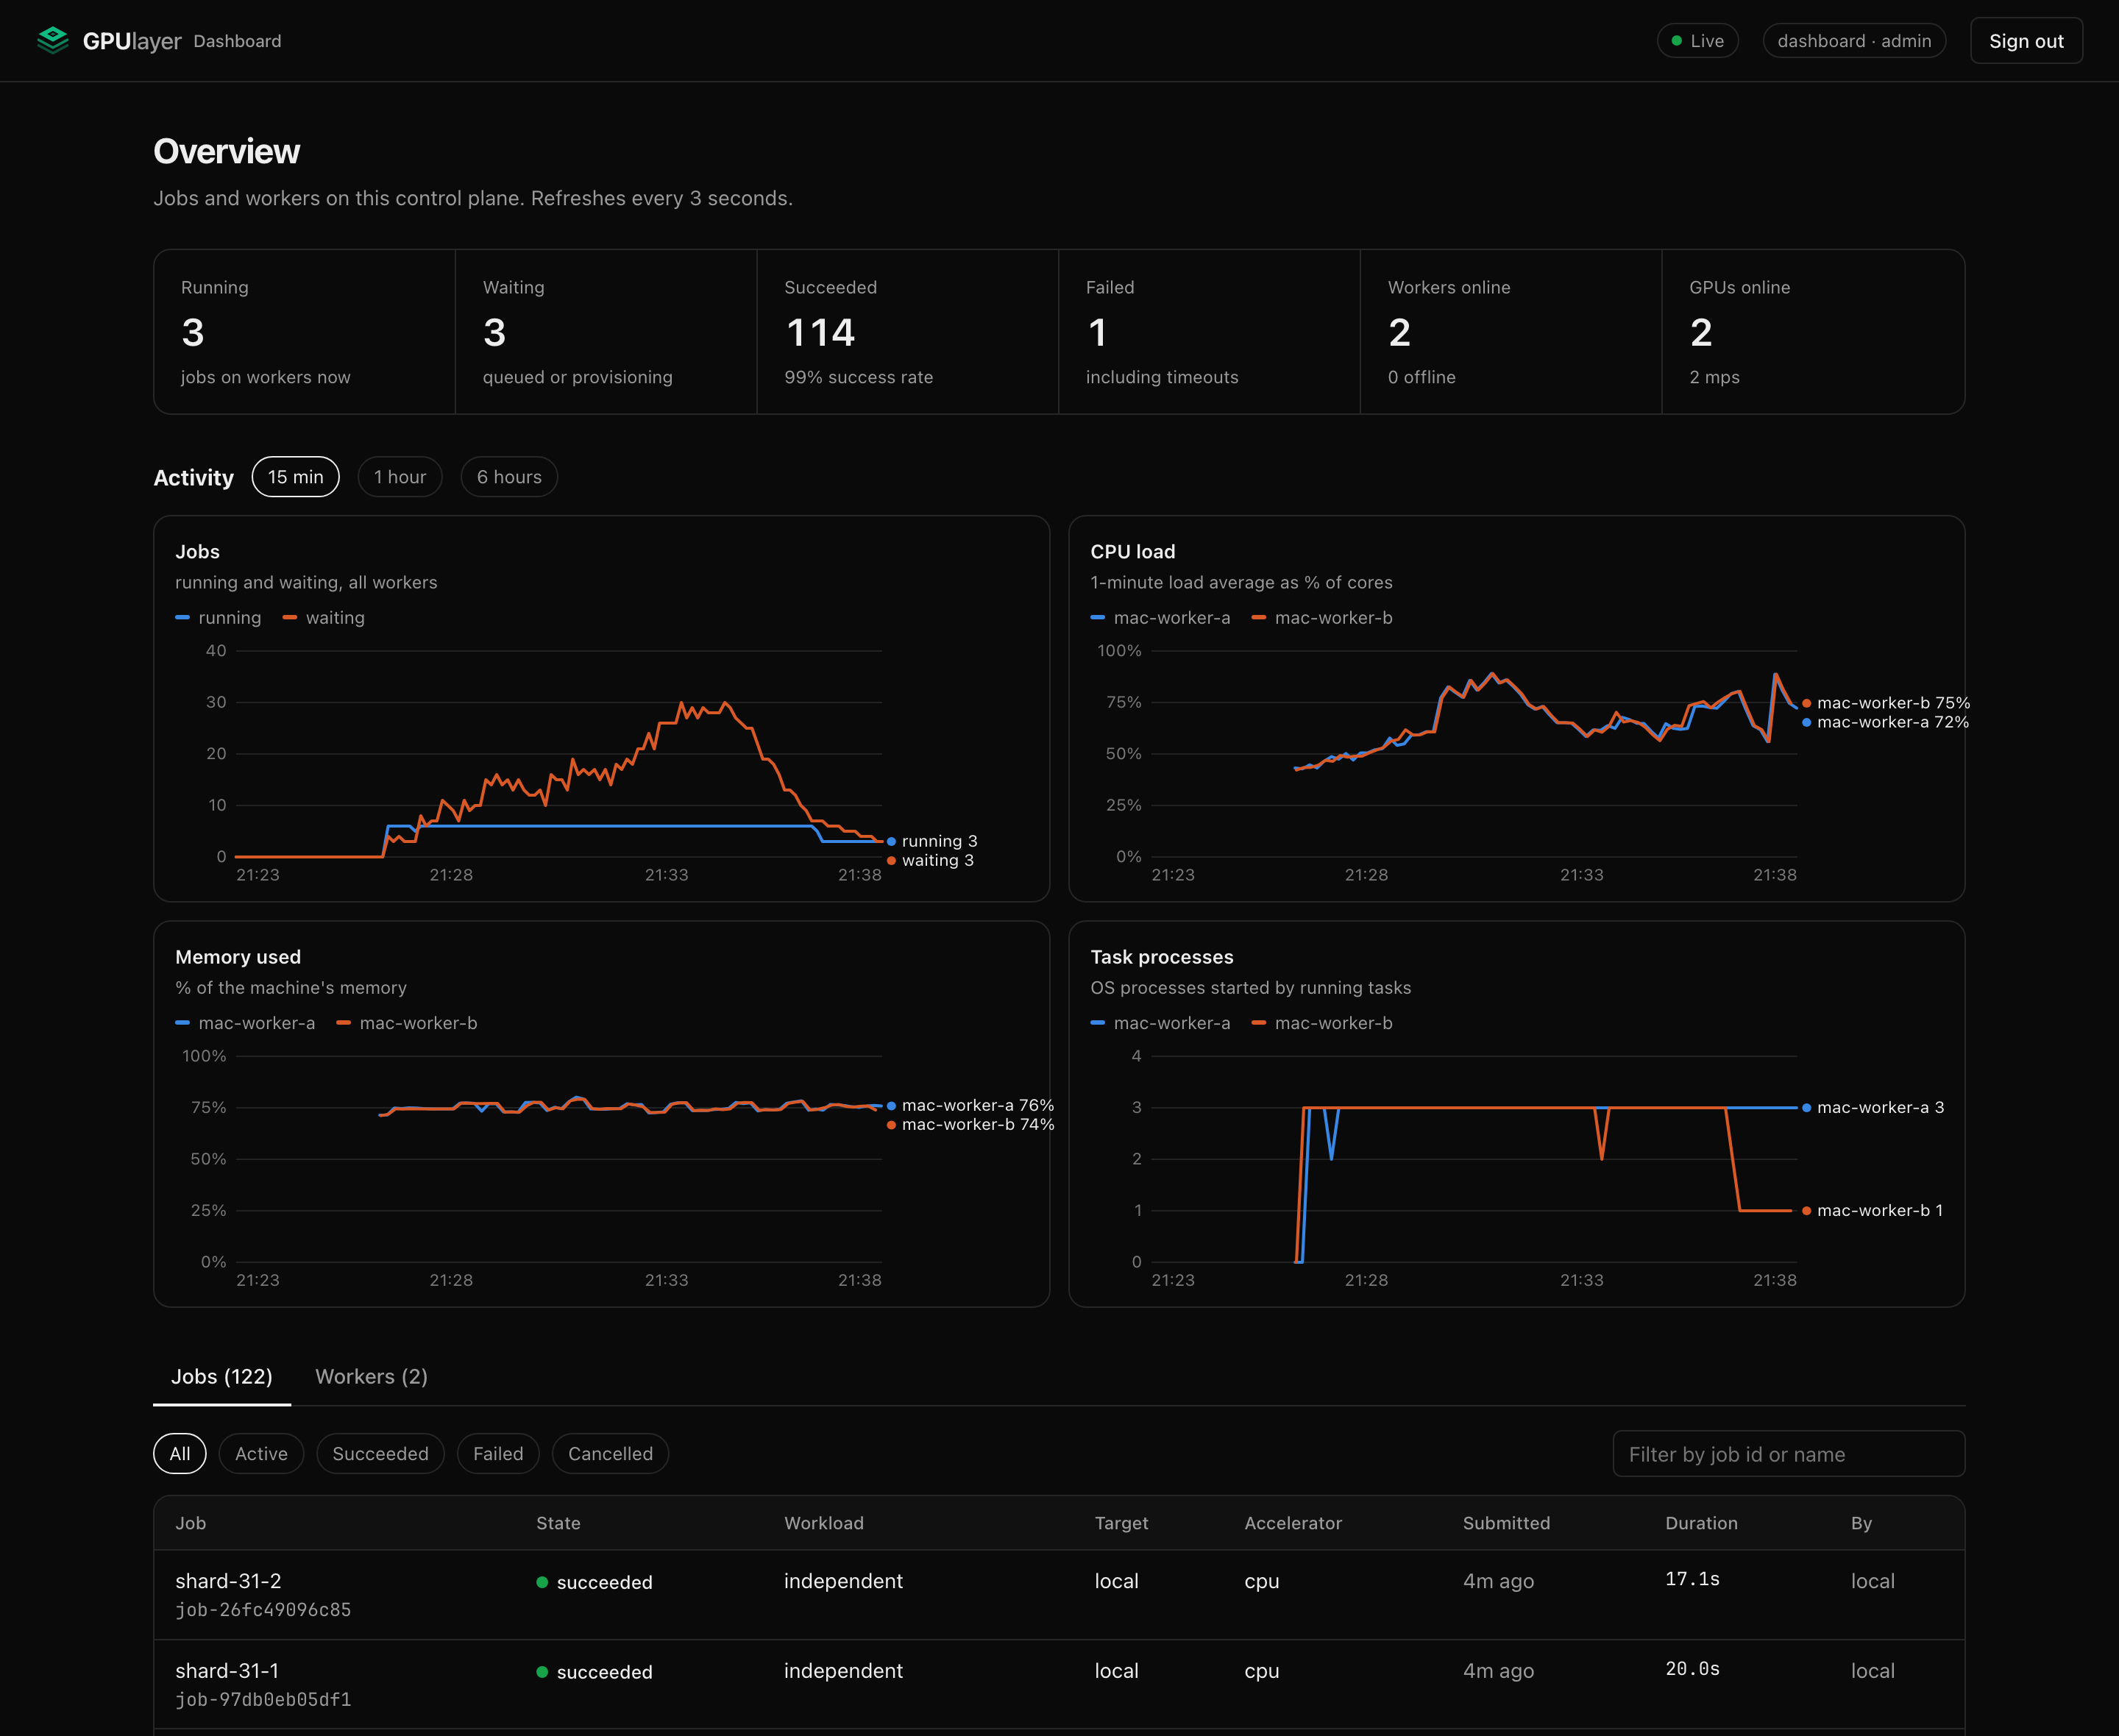
The [full quickstart](https://github.com/antonellof/gpulayer/blob/main/docs/get-started/quickstart.md) walks through each step with its output.
|
|
126
|
+
|
|
127
|
+
## For AI and coding agents
|
|
128
|
+
|
|
129
|
+
`gpulayer mcp` is an MCP server, so Claude Code, Claude Desktop, Cursor, Codex and VS Code
|
|
130
|
+
agents can list GPUs, submit jobs, wait, read logs and download outputs. An
|
|
131
|
+
[Agent Skill](https://github.com/antonellof/gpulayer/blob/main/integrations/skills/gpulayer/SKILL.md) covers agents that use the CLI.
|
|
132
|
+
|
|
133
|
+
```bash
|
|
134
|
+
claude mcp add gpulayer -- gpulayer mcp
|
|
135
|
+
```
|
|
136
|
+
|
|
137
|
+
See [AI and coding agents](https://github.com/antonellof/gpulayer/blob/main/docs/guides/ai-agents.md).
|
|
138
|
+
|
|
139
|
+
## Why GPUlayer
|
|
140
|
+
|
|
141
|
+
Most GPU code assumes the GPU is on the machine where you run it. With GPUlayer you describe
|
|
142
|
+
what a workload needs (an accelerator, GPU memory, frameworks) and it runs on a machine that
|
|
143
|
+
has it, wherever that machine is.
|
|
144
|
+
|
|
145
|
+
| Situation | Without GPUlayer | With GPUlayer |
|
|
146
|
+
|---|---|---|
|
|
147
|
+
| Code on a laptop, GPU elsewhere | ssh, copy code, rebuild the environment, tmux, copy results back | `gpulayer submit --target remote -- <cmd>` |
|
|
148
|
+
| Several GPU machines | track free machines by hand; jobs crash on the wrong GPU or library | one queue; each job lands where it can run, or is rejected with the reason |
|
|
149
|
+
| NVIDIA servers and Apple Silicon Macs | separate scripts and setup per machine | ask for `cuda` or `mps`; one interface |
|
|
150
|
+
| Many independent tasks | loops and ad hoc scripts | `fn.map([...])` across free GPUs |
|
|
151
|
+
| Multi-node training | `torchrun` on every node with matching ranks and addresses | `Trainer(num_nodes=2, devices=4)` |
|
|
152
|
+
|
|
153
|
+
On one machine with one GPU, running your code directly is simpler. GPUlayer runs jobs that
|
|
154
|
+
finish (long-running services are planned) and is not a sandbox for untrusted code. More in
|
|
155
|
+
[Why GPUlayer](https://www.gpulayer.dev/docs/#why-gpulayer).
|
|
156
|
+
|
|
157
|
+
## Performance and comparison
|
|
158
|
+
|
|
159
|
+
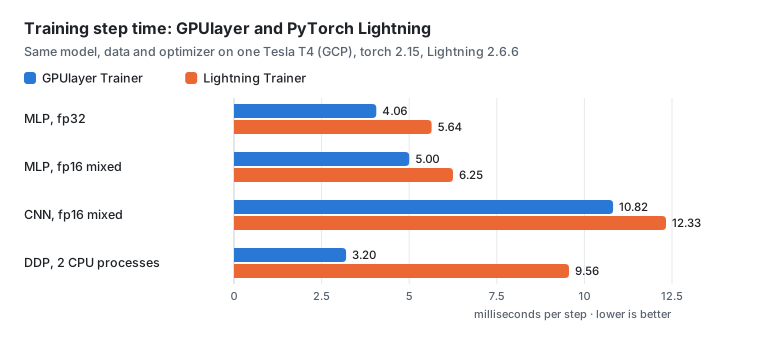
Measured on one NVIDIA Tesla T4 against PyTorch Lightning, with the same model, data and
|
|
160
|
+
optimizer:
|
|
161
|
+
|
|
162
|
+
|
|
163
|
+
|
|
164
|
+
|
|
165
|
+
- GPUlayer's Trainer is 1.3 to 1.4x faster per step on small models and the same on a
|
|
166
|
+
compute-bound CNN, and starts about 0.6 s sooner.
|
|
167
|
+
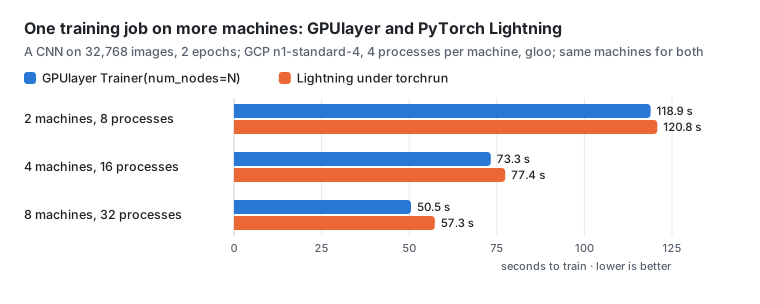
- One training job on 8 machines runs 3.4x faster than on one, and GPUlayer finishes it 7%
|
|
168
|
+
sooner than Lightning under torchrun (39.9 s vs 42.8 s; 9% sooner on one machine).
|
|
169
|
+
- Distributed jobs start 1.1 to 2.3 s faster than through torchrun; tested on up to 16
|
|
170
|
+
machines (32 processes) and 30 workers across two GCP regions.
|
|
171
|
+
- Across two machines: a distributed job spanning both, fail-fast in 2.7 s, and 55.6 small
|
|
172
|
+
jobs per second.
|
|
173
|
+
|
|
174
|
+
|
|
175
|
+
|
|
176
|
+
|
|
177
|
+
Method, all charts and raw logs:
|
|
178
|
+
[Performance and comparison](https://github.com/antonellof/gpulayer/blob/main/docs/get-started/performance-and-comparison.md). Reproduce them
|
|
179
|
+
with [`benchmarks/`](https://github.com/antonellof/gpulayer/blob/main/benchmarks/README.md).
|
|
180
|
+
|
|
181
|
+
## Architecture
|
|
182
|
+
|
|
183
|
+
|
|
184
|
+
|
|
185
|
+
|
|
186
|
+
GPUlayer has three parts:
|
|
187
|
+
|
|
188
|
+
- **Clients** submit work: the `gpulayer` CLI, the Python SDK (`@gl.remote`, `gl.Client`), the
|
|
189
|
+
PyTorch `Trainer` and `launch()`, and the MCP server for AI agents. A job states what it
|
|
190
|
+
needs (accelerator, GPU count and memory, frameworks), not which machine to use.
|
|
191
|
+
- **The control plane** keeps the job queue, picks a worker for each job and records the
|
|
192
|
+
reason when no worker fits. It stores code bundles, inputs, outputs and logs, and checks
|
|
193
|
+
tokens. For work on one machine it runs inside your process; for several machines it runs
|
|
194
|
+
as a server (`gpulayer up`).
|
|
195
|
+
- **Workers**, one per machine, report their GPUs and installed frameworks, ask the control
|
|
196
|
+
plane for tasks, run them as normal processes (one per rank for distributed jobs),
|
|
197
|
+
stream logs back and upload outputs. Workers open every connection themselves, so they can
|
|
198
|
+
sit behind NAT. A cloud VM is a worker that joined with `gpulayer join`.
|
|
199
|
+
|
|
200
|
+
A job goes from `queued` to `scheduled` when a worker fits, then `running`, and ends as
|
|
201
|
+
`succeeded`, `failed`, `cancelled` or `timed_out`. Frameworks such as PyTorch, JAX, MLX and
|
|
202
|
+
CuPy still decide how the computation uses the GPU; GPUlayer decides which GPU runs it. More in
|
|
203
|
+
[Architecture overview](https://github.com/antonellof/gpulayer/blob/main/docs/architecture/overview.md).
|
|
204
|
+
|
|
205
|
+
## Development
|
|
206
|
+
|
|
207
|
+
```bash
|
|
208
|
+
uv pip install -e '.[dev,examples]'
|
|
209
|
+
.venv/bin/pytest && .venv/bin/ruff check src tests && .venv/bin/mypy src
|
|
210
|
+
```
|
|
211
|
+
|
|
212
|
+
See [Contributing](https://github.com/antonellof/gpulayer/blob/main/docs/project/contributing.md).
|
|
213
|
+
|
|
214
|
+
## License
|
|
215
|
+
|
|
216
|
+
Apache License 2.0, see [LICENSE](https://github.com/antonellof/gpulayer/blob/main/LICENSE).
|