extractscore 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- extractscore-0.1.0/.github/ISSUE_TEMPLATE/bug.yml +22 -0
- extractscore-0.1.0/.github/ISSUE_TEMPLATE/question.yml +11 -0
- extractscore-0.1.0/.github/workflows/ci.yml +29 -0
- extractscore-0.1.0/.gitignore +38 -0
- extractscore-0.1.0/CHANGELOG.md +24 -0
- extractscore-0.1.0/LICENSE +21 -0
- extractscore-0.1.0/PKG-INFO +261 -0
- extractscore-0.1.0/README.ko.md +239 -0
- extractscore-0.1.0/README.md +239 -0
- extractscore-0.1.0/SECURITY.md +7 -0
- extractscore-0.1.0/docs/images/01-score.ko.png +0 -0
- extractscore-0.1.0/docs/images/01-score.png +0 -0
- extractscore-0.1.0/docs/images/02-gate.ko.png +0 -0
- extractscore-0.1.0/docs/images/02-gate.png +0 -0
- extractscore-0.1.0/docs/images/03-diff.ko.png +0 -0
- extractscore-0.1.0/docs/images/03-diff.png +0 -0
- extractscore-0.1.0/examples/ci.yml +24 -0
- extractscore-0.1.0/examples/compare_runs.py +16 -0
- extractscore-0.1.0/examples/quickstart.py +13 -0
- extractscore-0.1.0/pyproject.toml +43 -0
- extractscore-0.1.0/src/extractscore/__init__.py +37 -0
- extractscore-0.1.0/src/extractscore/__main__.py +5 -0
- extractscore-0.1.0/src/extractscore/align.py +111 -0
- extractscore-0.1.0/src/extractscore/cli.py +255 -0
- extractscore-0.1.0/src/extractscore/compare.py +167 -0
- extractscore-0.1.0/src/extractscore/config.py +176 -0
- extractscore-0.1.0/src/extractscore/diff.py +145 -0
- extractscore-0.1.0/src/extractscore/errors.py +32 -0
- extractscore-0.1.0/src/extractscore/gate.py +43 -0
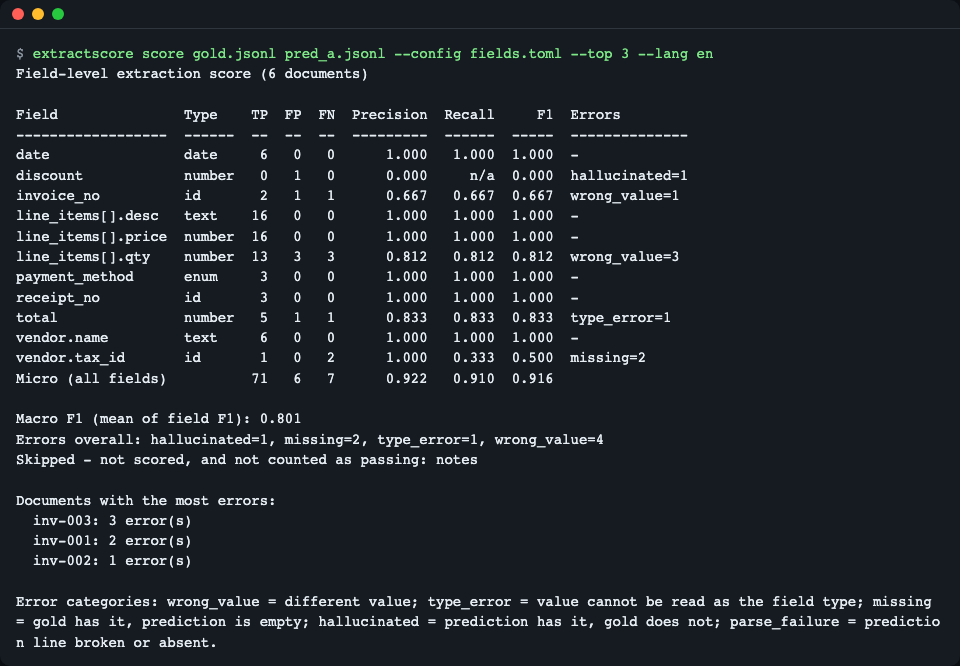
- extractscore-0.1.0/src/extractscore/i18n.py +290 -0
- extractscore-0.1.0/src/extractscore/io.py +79 -0
- extractscore-0.1.0/src/extractscore/metrics.py +119 -0
- extractscore-0.1.0/src/extractscore/py.typed +0 -0
- extractscore-0.1.0/src/extractscore/render.py +144 -0
- extractscore-0.1.0/src/extractscore/sample/README.md +29 -0
- extractscore-0.1.0/src/extractscore/sample/docs/inv-001.txt +10 -0
- extractscore-0.1.0/src/extractscore/sample/docs/inv-002.txt +9 -0
- extractscore-0.1.0/src/extractscore/sample/docs/inv-003.txt +9 -0
- extractscore-0.1.0/src/extractscore/sample/docs/rcp-001.txt +8 -0
- extractscore-0.1.0/src/extractscore/sample/docs/rcp-002.txt +9 -0
- extractscore-0.1.0/src/extractscore/sample/docs/rcp-003.txt +8 -0
- extractscore-0.1.0/src/extractscore/sample/fields.toml +27 -0
- extractscore-0.1.0/src/extractscore/sample/gold.jsonl +6 -0
- extractscore-0.1.0/src/extractscore/sample/pred_a.jsonl +6 -0
- extractscore-0.1.0/src/extractscore/sample/pred_b.jsonl +6 -0
- extractscore-0.1.0/src/extractscore/score.py +334 -0
- extractscore-0.1.0/tests/conftest.py +52 -0
- extractscore-0.1.0/tests/test_align.py +82 -0
- extractscore-0.1.0/tests/test_cli.py +101 -0
- extractscore-0.1.0/tests/test_compare.py +118 -0
- extractscore-0.1.0/tests/test_diff.py +63 -0
- extractscore-0.1.0/tests/test_i18n.py +146 -0
- extractscore-0.1.0/tests/test_metrics.py +49 -0
- extractscore-0.1.0/tests/test_packaging.py +38 -0
- extractscore-0.1.0/tests/test_robustness.py +87 -0
- extractscore-0.1.0/tests/test_score.py +81 -0
- extractscore-0.1.0/uv.lock +79 -0
|
@@ -0,0 +1,22 @@
|
|
|
1
|
+
name: 버그 / Bug
|
|
2
|
+
description: README대로 했는데 다르게 동작해요 / Something does not work as the README says
|
|
3
|
+
labels: [bug]
|
|
4
|
+
body:
|
|
5
|
+
- type: textarea
|
|
6
|
+
id: what
|
|
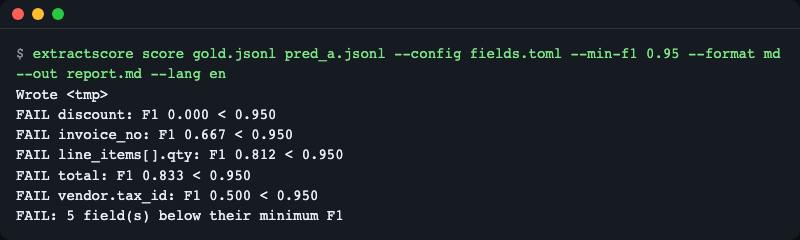
7
|
+
attributes:
|
|
8
|
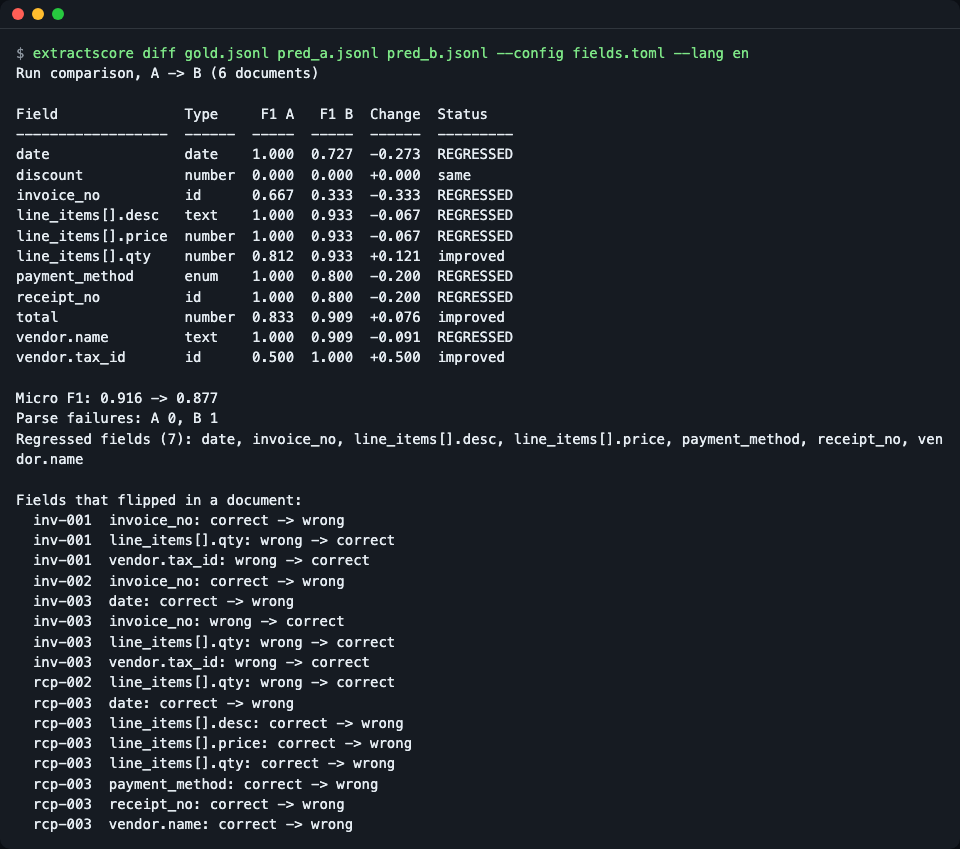
+
label: 무엇이 일어났나요? / What happened?
|
|
9
|
+
description: 실행한 명령과 나온 메시지를 그대로 붙여 주세요. / Paste the command and the output.
|
|
10
|
+
validations:
|
|
11
|
+
required: true
|
|
12
|
+
- type: textarea
|
|
13
|
+
id: expected
|
|
14
|
+
attributes:
|
|
15
|
+
label: 기대한 결과 / Expected
|
|
16
|
+
- type: input
|
|
17
|
+
id: env
|
|
18
|
+
attributes:
|
|
19
|
+
label: 환경 / Environment
|
|
20
|
+
placeholder: "macOS 15 (M3) · Ubuntu 24.04 · Windows 11 / uv 0.x / mock or real mode"
|
|
21
|
+
validations:
|
|
22
|
+
required: true
|
|
@@ -0,0 +1,11 @@
|
|
|
1
|
+
name: 질문 / Question
|
|
2
|
+
description: 이해가 안 되는 부분이나 더 알고 싶은 점 / Something unclear or worth explaining
|
|
3
|
+
labels: [question]
|
|
4
|
+
body:
|
|
5
|
+
- type: textarea
|
|
6
|
+
id: question
|
|
7
|
+
attributes:
|
|
8
|
+
label: 질문 / Question
|
|
9
|
+
description: README의 어느 부분(절 제목)에 대한 질문인지 알려 주세요. / Which README section is this about?
|
|
10
|
+
validations:
|
|
11
|
+
required: true
|
|
@@ -0,0 +1,29 @@
|
|
|
1
|
+
# Tests need no keys and no network: scoring is local and deterministic.
|
|
2
|
+
name: ci
|
|
3
|
+
on:
|
|
4
|
+
push:
|
|
5
|
+
pull_request:
|
|
6
|
+
schedule:
|
|
7
|
+
- cron: "17 3 * * 1" # every Monday - catch breakage from new Python releases
|
|
8
|
+
workflow_dispatch:
|
|
9
|
+
jobs:
|
|
10
|
+
test:
|
|
11
|
+
runs-on: ubuntu-latest
|
|
12
|
+
strategy:
|
|
13
|
+
fail-fast: false
|
|
14
|
+
matrix:
|
|
15
|
+
python-version: ["3.11", "3.13"]
|
|
16
|
+
steps:
|
|
17
|
+
- uses: actions/checkout@v4
|
|
18
|
+
- uses: astral-sh/setup-uv@v10.3.3
|
|
19
|
+
- run: uv python install ${{ matrix.python-version }}
|
|
20
|
+
- run: uv sync --locked --python ${{ matrix.python-version }}
|
|
21
|
+
- run: uv run --python ${{ matrix.python-version }} pytest -q
|
|
22
|
+
- run: uv run --python ${{ matrix.python-version }} extractscore demo --lang en
|
|
23
|
+
build:
|
|
24
|
+
runs-on: ubuntu-latest
|
|
25
|
+
steps:
|
|
26
|
+
- uses: actions/checkout@v4
|
|
27
|
+
- uses: astral-sh/setup-uv@v10.3.3
|
|
28
|
+
- run: uv build
|
|
29
|
+
- run: uv run --isolated --no-project --with ./dist/extractscore-0.1.0-py3-none-any.whl extractscore demo --lang en
|
|
@@ -0,0 +1,38 @@
|
|
|
1
|
+
# Python
|
|
2
|
+
__pycache__/
|
|
3
|
+
*.py[cod]
|
|
4
|
+
.venv/
|
|
5
|
+
.pytest_cache/
|
|
6
|
+
.ruff_cache/
|
|
7
|
+
.mypy_cache/
|
|
8
|
+
*.egg-info/
|
|
9
|
+
|
|
10
|
+
# Node
|
|
11
|
+
node_modules/
|
|
12
|
+
dist/
|
|
13
|
+
.next/
|
|
14
|
+
|
|
15
|
+
# 실행 산출물·모델·데이터 캐시
|
|
16
|
+
runs/
|
|
17
|
+
outputs/
|
|
18
|
+
.cache/
|
|
19
|
+
*.safetensors
|
|
20
|
+
*.gguf
|
|
21
|
+
*.bin
|
|
22
|
+
|
|
23
|
+
# 환경·비밀
|
|
24
|
+
.env
|
|
25
|
+
.env.*
|
|
26
|
+
!.env.example
|
|
27
|
+
|
|
28
|
+
# OS·에디터
|
|
29
|
+
.DS_Store
|
|
30
|
+
.vscode/
|
|
31
|
+
.idea/
|
|
32
|
+
|
|
33
|
+
# Flutter·Dart
|
|
34
|
+
.dart_tool/
|
|
35
|
+
build/
|
|
36
|
+
.flutter-plugins
|
|
37
|
+
.flutter-plugins-dependencies
|
|
38
|
+
coverage/
|
|
@@ -0,0 +1,24 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to this project are documented here.
|
|
4
|
+
The format follows [Keep a Changelog](https://keepachangelog.com/en/1.1.0/) and the project uses [Semantic Versioning](https://semver.org/).
|
|
5
|
+
|
|
6
|
+
## [Unreleased]
|
|
7
|
+
|
|
8
|
+
## [0.1.0] - 2026-11-14
|
|
9
|
+
|
|
10
|
+
### Added
|
|
11
|
+
- Field-level scoring of LLM-extracted JSON against a gold JSONL: per-field TP/FP/FN, precision, recall, F1, micro and macro aggregates.
|
|
12
|
+
- Error categories: `wrong_value`, `type_error`, `missing`, `hallucinated`, `parse_failure`.
|
|
13
|
+
- Typed comparators (`number`, `date`, `text`, `id`, `enum`, `bool`) with conservative type inference; ids and amounts are exact by default, fuzzy text matching only where configured.
|
|
14
|
+
- Order-independent pairing of object lists (Hungarian algorithm, pure Python), multiset comparison of scalar lists, nested lists.
|
|
15
|
+
- `diff` between two runs: per-field change, improved / regressed / same, and the documents whose fields flipped.
|
|
16
|
+
- CLI `extractscore score | diff | demo` with table, JSON and Markdown output, CI gates (`--min-f1`, `--field-min`, `--fail-on-regression`) and exit codes 0 / 1 / 2.
|
|
17
|
+
- English and Korean output (`--lang`, `EXTRACTSCORE_LANG`, `LC_ALL`/`LC_MESSAGES`/`LANG`).
|
|
18
|
+
- TOML or JSON field-rule configuration; `ignore = true` fields are reported as skipped.
|
|
19
|
+
- Python API: `evaluate`, `evaluate_files`, `compare`, `diff`, `check_gates`, `Config`, `FieldRule`, `load_jsonl`.
|
|
20
|
+
- Bundled practice mock (hand-written predictions, no model is called): `extractscore demo`, `demo --export DIR`.
|
|
21
|
+
- Zero runtime dependencies; Python 3.11 or newer.
|
|
22
|
+
|
|
23
|
+
[Unreleased]: https://github.com/LeeGyeongPil/extractscore/compare/v0.1.0...HEAD
|
|
24
|
+
[0.1.0]: https://github.com/LeeGyeongPil/extractscore/releases/tag/v0.1.0
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 LeeGyeongPil
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,261 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: extractscore
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Field-level precision/recall/F1 for LLM-extracted JSON, with before/after run comparison and CI gates.
|
|
5
|
+
Project-URL: Homepage, https://github.com/LeeGyeongPil/extractscore
|
|
6
|
+
Project-URL: Issues, https://github.com/LeeGyeongPil/extractscore/issues
|
|
7
|
+
Project-URL: Changelog, https://github.com/LeeGyeongPil/extractscore/blob/main/CHANGELOG.md
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: evaluation,information-extraction,json,llm,precision-recall,structured-output
|
|
11
|
+
Classifier: Development Status :: 4 - Beta
|
|
12
|
+
Classifier: Environment :: Console
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Programming Language :: Python :: 3
|
|
15
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
18
|
+
Classifier: Topic :: Software Development :: Testing
|
|
19
|
+
Classifier: Typing :: Typed
|
|
20
|
+
Requires-Python: >=3.11
|
|
21
|
+
Description-Content-Type: text/markdown
|
|
22
|
+
|
|
23
|
+
# extractscore
|
|
24
|
+
|
|
25
|
+
**English** | [한국어](https://github.com/LeeGyeongPil/extractscore/blob/v0.1.0/README.ko.md)
|
|
26
|
+
|
|
27
|
+
Field-level precision, recall and F1 for JSON that an LLM extracted from documents (invoices, receipts, contracts), plus a before/after comparison of two runs on the same gold set. It is a Python library with a matching CLI, has zero runtime dependencies, and needs Python 3.11 or newer.
|
|
28
|
+
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
*Per-field TP/FP/FN, precision, recall, F1 and error categories, scored against a gold JSONL.*
|
|
32
|
+
|
|
33
|
+
## Install
|
|
34
|
+
|
|
35
|
+
```bash
|
|
36
|
+
uv add git+https://github.com/LeeGyeongPil/extractscore # or: pip install git+https://github.com/LeeGyeongPil/extractscore
|
|
37
|
+
```
|
|
38
|
+
|
|
39
|
+
To try it from a clone instead: `git clone https://github.com/LeeGyeongPil/extractscore && cd extractscore && uv run extractscore demo`. If you do not have uv: `curl -LsSf https://astral.sh/uv/install.sh | sh`.
|
|
40
|
+
|
|
41
|
+
Python 3.11+ (it reads TOML with the standard library). No runtime dependencies.
|
|
42
|
+
|
|
43
|
+
## Quick start
|
|
44
|
+
|
|
45
|
+
The package ships a **practice mock**: six made-up invoices and receipts, the gold answers, and two sets of predictions that were **written by hand** to imitate typical LLM mistakes. No model is called, so it works offline. Your own data works the same way, with your gold file and your model's output.
|
|
46
|
+
|
|
47
|
+
```bash
|
|
48
|
+
uv run extractscore demo # inside a uv project or a clone; with pip: extractscore demo
|
|
49
|
+
```
|
|
50
|
+
|
|
51
|
+
That prints the score of run A, then the A to B comparison. To score one run yourself:
|
|
52
|
+
|
|
53
|
+
```bash
|
|
54
|
+
uv run extractscore demo --export my-eval # copies gold, predictions, rules and source texts
|
|
55
|
+
uv run extractscore score my-eval/gold.jsonl my-eval/pred_a.jsonl --config my-eval/fields.toml
|
|
56
|
+
```
|
|
57
|
+
|
|
58
|
+
```text
|
|
59
|
+
Field Type TP FP FN Precision Recall F1 Errors
|
|
60
|
+
------------------ ------ -- -- -- --------- ------ ----- --------------
|
|
61
|
+
date date 6 0 0 1.000 1.000 1.000 -
|
|
62
|
+
discount number 0 1 0 0.000 n/a 0.000 hallucinated=1
|
|
63
|
+
invoice_no id 2 1 1 0.667 0.667 0.667 wrong_value=1
|
|
64
|
+
line_items[].desc text 16 0 0 1.000 1.000 1.000 -
|
|
65
|
+
line_items[].price number 16 0 0 1.000 1.000 1.000 -
|
|
66
|
+
line_items[].qty number 13 3 3 0.812 0.812 0.812 wrong_value=3
|
|
67
|
+
payment_method enum 3 0 0 1.000 1.000 1.000 -
|
|
68
|
+
receipt_no id 3 0 0 1.000 1.000 1.000 -
|
|
69
|
+
total number 5 1 1 0.833 0.833 0.833 type_error=1
|
|
70
|
+
vendor.name text 6 0 0 1.000 1.000 1.000 -
|
|
71
|
+
vendor.tax_id id 1 0 2 1.000 0.333 0.500 missing=2
|
|
72
|
+
Micro (all fields) 71 6 7 0.922 0.910 0.916
|
|
73
|
+
|
|
74
|
+
Macro F1 (mean of field F1): 0.801
|
|
75
|
+
Errors overall: hallucinated=1, missing=2, type_error=1, wrong_value=4
|
|
76
|
+
Skipped - not scored, and not counted as passing: notes
|
|
77
|
+
```
|
|
78
|
+
|
|
79
|
+
(The command also prints a header, the most-wrong documents and a short error-category legend; the table above is the core of it. For Korean output add `--lang ko`.)
|
|
80
|
+
|
|
81
|
+
Read it like this: `total` has 5 correct values (TP), 1 wrong value (one FP and one FN), so precision and recall are both 5/6. `vendor.tax_id` was never wrong when present, but the model left it out twice, so precision is 1.0 and recall 0.33.
|
|
82
|
+
|
|
83
|
+
### Your own files
|
|
84
|
+
|
|
85
|
+
Gold file, one JSON object per line, with an `id` and the correct fields:
|
|
86
|
+
|
|
87
|
+
```json
|
|
88
|
+
{"id": "inv-001", "invoice_no": "INV-0042", "total": 1250.0, "line_items": [{"desc": "Widget A", "qty": 2, "price": 300.0}]}
|
|
89
|
+
```
|
|
90
|
+
|
|
91
|
+
The prediction file has the same shape, one line per document, using the same `id`. A line that is not valid JSON (for example a truncated response) is scored as a parse failure for that document, it does not stop the run.
|
|
92
|
+
|
|
93
|
+
### Compare two runs and gate CI
|
|
94
|
+
|
|
95
|
+
```bash
|
|
96
|
+
extractscore diff gold.jsonl pred_before.jsonl pred_after.jsonl --config fields.toml --fail-on-regression
|
|
97
|
+
extractscore score gold.jsonl pred.jsonl --config fields.toml --min-f1 0.95
|
|
98
|
+
```
|
|
99
|
+
|
|
100
|
+
Exit code 0 means pass, 1 means a gate failed, 2 means the input or config is invalid. A ready GitHub Actions workflow is in [`examples/ci.yml`](https://github.com/LeeGyeongPil/extractscore/blob/v0.1.0/examples/ci.yml). It calls `uvx extractscore`, which works once the package is on PyPI; until then use `uvx --from git+https://github.com/LeeGyeongPil/extractscore extractscore ...`.
|
|
101
|
+
|
|
102
|
+
|
|
103
|
+
|
|
104
|
+
*`--min-f1 0.95` lists every field below the bar and exits with code 1.*
|
|
105
|
+
|
|
106
|
+
|
|
107
|
+
|
|
108
|
+
*`diff` shows each field's F1 before and after, and which documents flipped between correct and wrong.*
|
|
109
|
+
|
|
110
|
+
Run B in the mock fixes `line_items[].qty` and `vendor.tax_id` but makes `date` and `invoice_no` worse. Most of the 7 regressed fields come from one cut-off JSON line (`rcp-003`): one broken response lowers every field of that document. That is why the comparison lists the flipped documents, not only the totals.
|
|
111
|
+
|
|
112
|
+
## Core concepts
|
|
113
|
+
|
|
114
|
+
```mermaid
|
|
115
|
+
flowchart LR
|
|
116
|
+
G[gold.jsonl] --> W[walk fields]
|
|
117
|
+
P[pred.jsonl] --> W
|
|
118
|
+
C[fields.toml] --> W
|
|
119
|
+
W --> S[TP / FP / FN per field]
|
|
120
|
+
S --> R[precision, recall, F1]
|
|
121
|
+
R --> D[diff A vs B]
|
|
122
|
+
R --> X[CI exit code]
|
|
123
|
+
```
|
|
124
|
+
|
|
125
|
+
- **Field path.** Nested objects become `vendor.name`; items in a list become `line_items[].qty`. Every path is scored on its own.
|
|
126
|
+
- **TP / FP / FN.** A correct value is a TP. A wrong value or a value that cannot be read as the field type counts as one FP and one FN. A value the model left out is an FN. A value the gold does not have is an FP. `n/a` means 0/0.
|
|
127
|
+
- **Error categories.** `wrong_value`, `type_error`, `missing`, `hallucinated`, `parse_failure`. They tell you what kind of mistake it was, not only how many.
|
|
128
|
+
- **Typed comparison.** `number`, `date`, `text`, `id`, `enum`, `bool`. `"1,250.00"`, `"$1,250"` and `1250` are the same number. Ids are always exact: `INV-215` is not `INV-0215`. Fuzzy text matching is on only for the text fields you configure.
|
|
129
|
+
- **List items.** Items are paired by content, not by position (Hungarian algorithm, pure Python), so a reordered list is still correct. An item that matches nothing counts as one missing plus one hallucinated.
|
|
130
|
+
|
|
131
|
+
Field rules (`fields.toml`, or JSON). Fields you do not list get a type inferred from the gold value:
|
|
132
|
+
|
|
133
|
+
```toml
|
|
134
|
+
date_formats = ["%Y-%m-%d", "%m/%d/%Y"] # first match wins
|
|
135
|
+
|
|
136
|
+
[fields."total"]
|
|
137
|
+
type = "number"
|
|
138
|
+
tol = 0.01
|
|
139
|
+
|
|
140
|
+
[fields."line_items[].desc"]
|
|
141
|
+
type = "text"
|
|
142
|
+
fuzzy = 0.85 # minimum similarity that still counts as a match
|
|
143
|
+
|
|
144
|
+
[fields."notes"]
|
|
145
|
+
ignore = true # reported as skipped, never as passing
|
|
146
|
+
```
|
|
147
|
+
|
|
148
|
+
## API
|
|
149
|
+
|
|
150
|
+
```python
|
|
151
|
+
from extractscore import evaluate_files, Config
|
|
152
|
+
```
|
|
153
|
+
|
|
154
|
+
| Name | What it does | Main arguments | Returns |
|
|
155
|
+
|---|---|---|---|
|
|
156
|
+
| `evaluate(gold, pred, config=None, *, id_key="id")` | Score a whole dataset held in memory | rows or `{id: dict}` | `Report` |
|
|
157
|
+
| `evaluate_files(gold_path, pred_path, config=None, *, id_key="id")` | Same, reading two JSONL files | paths | `Report` |
|
|
158
|
+
| `compare(gold, pred, config=None)` | Score one document | two dicts | `DocResult` |
|
|
159
|
+
| `diff(report_a, report_b, *, tolerance=0.0)` | Compare two reports from the same gold set | reports, allowed F1 drop | `Diff` (`.regressions`, `.improvements`, `.flips`) |
|
|
160
|
+
| `check_gates(report, *, min_f1=None, field_min=None)` | CI thresholds, overall and per field | `min_f1`, `{path: min}` | `list[GateFailure]` (empty means pass) |
|
|
161
|
+
| `Config.from_file(path)` / `Config.from_dict(data)` / `Config(...)` | Field rules | `fields`, `match_threshold`, `date_formats`, `empty_as_null` | `Config` |
|
|
162
|
+
| `FieldRule(type, tol, fuzzy, casefold, ignore)` | Rule for one field path | | `FieldRule` |
|
|
163
|
+
| `load_jsonl(path, *, strict, id_key="id")` | Read a JSONL file; with `strict=False`, broken lines become `ParseFailure` | path | `dict` of id to row |
|
|
164
|
+
|
|
165
|
+
`Report` has `.fields` (per-path `FieldStats` with `.precision`, `.recall`, `.f1`, `.counts`), `.micro`, `.macro_f1`, `.parse_failures`, `.skipped`, `.top_docs(n)`, `.to_dict()` and `.to_markdown(lang)`. Counts expose `.tp`, `.fp`, `.fn` and `.errors` (category to number). A precision or recall of 0/0 is `None`.
|
|
166
|
+
|
|
167
|
+
Errors: `InputError` (the gold data or a file cannot be read), `ConfigError` (invalid field rules), both subclasses of `ExtractScoreError`. Problems in the **predictions** are never exceptions; they are scored.
|
|
168
|
+
|
|
169
|
+
## Usage examples
|
|
170
|
+
|
|
171
|
+
Both files below are in [`examples/`](https://github.com/LeeGyeongPil/extractscore/blob/v0.1.0/examples/) and were run as written.
|
|
172
|
+
|
|
173
|
+
**Score one run** (`examples/quickstart.py`):
|
|
174
|
+
|
|
175
|
+
```python
|
|
176
|
+
from pathlib import Path
|
|
177
|
+
|
|
178
|
+
import extractscore
|
|
179
|
+
from extractscore import Config, evaluate_files
|
|
180
|
+
|
|
181
|
+
sample = Path(extractscore.__file__).parent / "sample"
|
|
182
|
+
config = Config.from_file(sample / "fields.toml")
|
|
183
|
+
report = evaluate_files(sample / "gold.jsonl", sample / "pred_a.jsonl", config)
|
|
184
|
+
|
|
185
|
+
total = report.fields["total"]
|
|
186
|
+
print(f"total: P={total.precision:.3f} R={total.recall:.3f} F1={total.f1:.3f}")
|
|
187
|
+
print("type_error:", total.counts.errors["type_error"])
|
|
188
|
+
print("micro F1:", round(report.micro.f1, 3))
|
|
189
|
+
```
|
|
190
|
+
|
|
191
|
+
```text
|
|
192
|
+
total: P=0.833 R=0.833 F1=0.833
|
|
193
|
+
type_error: 1
|
|
194
|
+
micro F1: 0.916
|
|
195
|
+
```
|
|
196
|
+
|
|
197
|
+
**Compare two runs and check gates** (`examples/compare_runs.py`):
|
|
198
|
+
|
|
199
|
+
```python
|
|
200
|
+
from pathlib import Path
|
|
201
|
+
|
|
202
|
+
import extractscore
|
|
203
|
+
from extractscore import Config, check_gates, diff, evaluate_files
|
|
204
|
+
|
|
205
|
+
sample = Path(extractscore.__file__).parent / "sample"
|
|
206
|
+
config = Config.from_file(sample / "fields.toml")
|
|
207
|
+
gold = sample / "gold.jsonl"
|
|
208
|
+
a = evaluate_files(gold, sample / "pred_a.jsonl", config)
|
|
209
|
+
b = evaluate_files(gold, sample / "pred_b.jsonl", config)
|
|
210
|
+
|
|
211
|
+
d = diff(a, b)
|
|
212
|
+
print("regressed:", ", ".join(d.regressions))
|
|
213
|
+
print("improved:", ", ".join(d.improvements))
|
|
214
|
+
for failure in check_gates(b, min_f1=0.9, field_min={"total": 0.99}):
|
|
215
|
+
print(f"FAIL {failure.path}: F1 {failure.f1:.3f} < {failure.minimum:.2f}")
|
|
216
|
+
```
|
|
217
|
+
|
|
218
|
+
```text
|
|
219
|
+
regressed: date, invoice_no, line_items[].desc, line_items[].price, payment_method, receipt_no, vendor.name
|
|
220
|
+
improved: line_items[].qty, total, vendor.tax_id
|
|
221
|
+
FAIL date: F1 0.727 < 0.90
|
|
222
|
+
FAIL discount: F1 0.000 < 0.90
|
|
223
|
+
FAIL invoice_no: F1 0.333 < 0.90
|
|
224
|
+
FAIL payment_method: F1 0.800 < 0.90
|
|
225
|
+
FAIL receipt_no: F1 0.800 < 0.90
|
|
226
|
+
FAIL total: F1 0.909 < 0.99
|
|
227
|
+
```
|
|
228
|
+
|
|
229
|
+
**Other output formats.** `--format json` (English keys, stable for scripts) and `--format md` (a Markdown table for a CI job summary), both with `--out FILE`.
|
|
230
|
+
|
|
231
|
+
**Language.** Output is English or Korean: `--lang en|ko`, else `EXTRACTSCORE_LANG`, else `LC_ALL`/`LC_MESSAGES`/`LANG`; anything not starting with `ko` is English. JSON keys do not change.
|
|
232
|
+
|
|
233
|
+
## When to use it
|
|
234
|
+
|
|
235
|
+
- Good fit: you extract JSON from documents with an LLM and want field-level precision/recall, a before/after comparison on the same gold set, and a CI gate. Scoring is deterministic and calls no model.
|
|
236
|
+
- Out of scope: it does not run your extraction, call a model, or judge free-text quality. It compares JSON to a gold file you provide.
|
|
237
|
+
- Other tools may suit you better when you need a general LLM evaluation pipeline ([promptfoo](https://github.com/promptfoo/promptfoo), [DeepEval](https://deepeval.com/docs/metrics-json-correctness), [Pydantic Evals](https://pydantic.dev/docs/ai/evals/evaluators/built-in/)), a document-QA similarity score ([anls_star](https://pypi.org/project/anls-star/)), or a benchmark for structured extraction ([ExtractBench](https://github.com/ContextualAI/extract-bench)). This project is narrower: it scores one thing, typed JSON fields with list alignment, and compares two runs. Their features change, so check their docs rather than this page.
|
|
238
|
+
|
|
239
|
+
## Limits
|
|
240
|
+
|
|
241
|
+
Read these before you trust a number.
|
|
242
|
+
|
|
243
|
+
- **Slash dates are month first.** By default `11/03/2026` is read as 2026-11-03. If your documents write day first, put that format first in `fields.toml`: `date_formats = ["%d/%m/%Y", "%Y-%m-%d"]`. The first format that parses wins, so an ambiguous date follows the order you give.
|
|
244
|
+
- **European decimal commas are not understood in 0.1.0.** `"1.250,00"` is not read as 1250, so a correct value is counted as `wrong_value`. Normalise such values before scoring.
|
|
245
|
+
- **A broken prediction line without a recoverable `id` is dropped.** If the line is cut off but the `id` can still be found, the document is scored as `parse_failure`. If it cannot, that document is scored as having no prediction at all.
|
|
246
|
+
- **Big lists are slower.** List items are paired with a pure-Python Hungarian algorithm (cubic time). A warning appears above 500 unmatched items in one list; a 600-item list took roughly 2 to 9 s across runs on the test machine.
|
|
247
|
+
|
|
248
|
+
## Version and compatibility
|
|
249
|
+
|
|
250
|
+
- Follows [Semantic Versioning](https://semver.org/). While the version is 0.x, the API can change in a minor release, and any change is listed in [CHANGELOG.md](https://github.com/LeeGyeongPil/extractscore/blob/v0.1.0/CHANGELOG.md).
|
|
251
|
+
|
|
252
|
+
## Development
|
|
253
|
+
|
|
254
|
+
```bash
|
|
255
|
+
git clone https://github.com/LeeGyeongPil/extractscore && cd extractscore
|
|
256
|
+
uv run pytest
|
|
257
|
+
```
|
|
258
|
+
|
|
259
|
+
## License
|
|
260
|
+
|
|
261
|
+
MIT.
|
|
@@ -0,0 +1,239 @@
|
|
|
1
|
+
# extractscore
|
|
2
|
+
|
|
3
|
+
[English](README.md) | **한국어**
|
|
4
|
+
|
|
5
|
+
문서(송장·영수증·계약서)에서 LLM 으로 뽑은 JSON 의 정확도를 필드 단위 정밀도·재현율·F1 로 재고, 같은 정답 세트로 두 번의 실행(모델·프롬프트 변경 전후)을 비교하는 Python 라이브러리와 CLI 입니다. 런타임 의존성이 없고 Python 3.11 이상이 필요합니다.
|
|
6
|
+
|
|
7
|
+

|
|
8
|
+
|
|
9
|
+
*정답 JSONL 과 비교한 필드별 TP/FP/FN, 정밀도, 재현율, F1, 오류 범주.*
|
|
10
|
+
|
|
11
|
+
## 설치
|
|
12
|
+
|
|
13
|
+
```bash
|
|
14
|
+
uv add git+https://github.com/LeeGyeongPil/extractscore # 또는: pip install git+https://github.com/LeeGyeongPil/extractscore
|
|
15
|
+
```
|
|
16
|
+
|
|
17
|
+
프로젝트에 추가하지 않고 clone 해서 써 보려면: `git clone https://github.com/LeeGyeongPil/extractscore && cd extractscore && uv run extractscore demo`. uv 가 없다면: `curl -LsSf https://astral.sh/uv/install.sh | sh`.
|
|
18
|
+
|
|
19
|
+
Python 3.11 이상(표준 라이브러리로 TOML 을 읽습니다). 런타임 의존성 없음.
|
|
20
|
+
|
|
21
|
+
## 빠르게 시작하기
|
|
22
|
+
|
|
23
|
+
패키지에는 **연습용 목(mock)** 이 들어 있습니다. 지어낸 송장·영수증 6건, 정답, 그리고 LLM 이 흔히 하는 실수를 흉내 내 **손으로 쓴** 예측 두 벌입니다. 모델을 호출하지 않으므로 오프라인에서 돌아갑니다. 자기 데이터도 정답 파일과 모델 출력만 바꾸면 똑같이 동작합니다.
|
|
24
|
+
|
|
25
|
+
```bash
|
|
26
|
+
uv run extractscore demo # uv 프로젝트나 clone 안에서. pip 로 설치했다면: extractscore demo
|
|
27
|
+
```
|
|
28
|
+
|
|
29
|
+
A 실행의 점수와 A→B 비교가 출력됩니다. 한 실행만 직접 채점하려면:
|
|
30
|
+
|
|
31
|
+
```bash
|
|
32
|
+
uv run extractscore demo --export my-eval # 정답·예측·규칙·원문을 복사
|
|
33
|
+
uv run extractscore score my-eval/gold.jsonl my-eval/pred_a.jsonl --config my-eval/fields.toml
|
|
34
|
+
```
|
|
35
|
+
|
|
36
|
+
```text
|
|
37
|
+
필드 형 TP FP FN 정밀도 재현율 F1 오류
|
|
38
|
+
-------------------- ------ -- -- -- ------ ------ ----- --------------
|
|
39
|
+
date date 6 0 0 1.000 1.000 1.000 -
|
|
40
|
+
discount number 0 1 0 0.000 n/a 0.000 hallucinated=1
|
|
41
|
+
invoice_no id 2 1 1 0.667 0.667 0.667 wrong_value=1
|
|
42
|
+
line_items[].desc text 16 0 0 1.000 1.000 1.000 -
|
|
43
|
+
line_items[].price number 16 0 0 1.000 1.000 1.000 -
|
|
44
|
+
line_items[].qty number 13 3 3 0.812 0.812 0.812 wrong_value=3
|
|
45
|
+
payment_method enum 3 0 0 1.000 1.000 1.000 -
|
|
46
|
+
receipt_no id 3 0 0 1.000 1.000 1.000 -
|
|
47
|
+
total number 5 1 1 0.833 0.833 0.833 type_error=1
|
|
48
|
+
vendor.name text 6 0 0 1.000 1.000 1.000 -
|
|
49
|
+
vendor.tax_id id 1 0 2 1.000 0.333 0.500 missing=2
|
|
50
|
+
마이크로 (전체 필드) 71 6 7 0.922 0.910 0.916
|
|
51
|
+
|
|
52
|
+
매크로 F1 (필드별 F1 평균): 0.801
|
|
53
|
+
전체 오류: hallucinated=1, missing=2, type_error=1, wrong_value=4
|
|
54
|
+
건너뜀 - 채점하지 않았고 통과로도 세지 않음: notes
|
|
55
|
+
```
|
|
56
|
+
|
|
57
|
+
(실제 명령은 머리말, 오류가 많은 문서 목록, 오류 범주 설명도 함께 출력하고, 위 표는 그 핵심입니다. 영어 출력은 `--lang en` 을 붙이면 됩니다.)
|
|
58
|
+
|
|
59
|
+
읽는 법: `total` 은 맞은 값 5개(TP), 틀린 값 1개(FP 1 + FN 1)라서 정밀도와 재현율이 모두 5/6 입니다. `vendor.tax_id` 는 값이 있을 때 틀린 적은 없지만 두 번 빠뜨렸으므로 정밀도 1.0, 재현율 0.33 입니다.
|
|
60
|
+
|
|
61
|
+
### 내 파일로 채점하기
|
|
62
|
+
|
|
63
|
+
정답 파일은 줄마다 JSON 객체 하나, `id` 와 정답 필드를 담습니다.
|
|
64
|
+
|
|
65
|
+
```json
|
|
66
|
+
{"id": "inv-001", "invoice_no": "INV-0042", "total": 1250.0, "line_items": [{"desc": "Widget A", "qty": 2, "price": 300.0}]}
|
|
67
|
+
```
|
|
68
|
+
|
|
69
|
+
예측 파일도 같은 모양이고 같은 `id` 를 씁니다. JSON 이 아닌 줄(응답이 잘린 경우 등)은 실행을 멈추지 않고 그 문서의 파싱 실패로 채점됩니다.
|
|
70
|
+
|
|
71
|
+
### 두 실행 비교와 CI 게이트
|
|
72
|
+
|
|
73
|
+
```bash
|
|
74
|
+
extractscore diff gold.jsonl pred_before.jsonl pred_after.jsonl --config fields.toml --fail-on-regression
|
|
75
|
+
extractscore score gold.jsonl pred.jsonl --config fields.toml --min-f1 0.95
|
|
76
|
+
```
|
|
77
|
+
|
|
78
|
+
종료 코드 0 은 통과, 1 은 게이트 실패, 2 는 입력·설정 오류입니다. 바로 쓸 수 있는 GitHub Actions 예시는 [`examples/ci.yml`](examples/ci.yml) 입니다. 이 예시는 `uvx extractscore` 를 쓰므로 PyPI 에 올라간 뒤에 동작합니다. 그 전에는 `uvx --from git+https://github.com/LeeGyeongPil/extractscore extractscore ...` 를 쓰세요.
|
|
79
|
+
|
|
80
|
+

|
|
81
|
+
|
|
82
|
+
*`--min-f1 0.95` 는 기준 미만인 필드를 모두 나열하고 종료 코드 1 로 끝납니다.*
|
|
83
|
+
|
|
84
|
+

|
|
85
|
+
|
|
86
|
+
*`diff` 는 필드별 F1 의 전후 값과, 문서에서 맞음↔틀림으로 뒤집힌 필드를 보여 줍니다.*
|
|
87
|
+
|
|
88
|
+
목의 B 실행은 `line_items[].qty` 와 `vendor.tax_id` 를 고치지만 `date` 와 `invoice_no` 는 나빠집니다. 후퇴한 7개 필드의 상당수는 잘린 JSON 한 줄(`rcp-003`) 때문입니다. 깨진 응답 하나가 그 문서의 모든 필드를 깎습니다. 그래서 비교 결과는 합계뿐 아니라 뒤집힌 문서도 보여 줍니다.
|
|
89
|
+
|
|
90
|
+
## 핵심 개념
|
|
91
|
+
|
|
92
|
+
```mermaid
|
|
93
|
+
flowchart LR
|
|
94
|
+
G[gold.jsonl] --> W[필드 순회]
|
|
95
|
+
P[pred.jsonl] --> W
|
|
96
|
+
C[fields.toml] --> W
|
|
97
|
+
W --> S[필드별 TP / FP / FN]
|
|
98
|
+
S --> R[정밀도, 재현율, F1]
|
|
99
|
+
R --> D[A와 B 비교]
|
|
100
|
+
R --> X[CI 종료 코드]
|
|
101
|
+
```
|
|
102
|
+
|
|
103
|
+
- **필드 경로.** 중첩 객체는 `vendor.name`, 목록 항목은 `line_items[].qty` 로 부릅니다. 경로마다 따로 채점합니다.
|
|
104
|
+
- **TP / FP / FN.** 맞은 값은 TP. 틀린 값, 또는 필드 형으로 읽을 수 없는 값은 FP 1 + FN 1. 모델이 빠뜨린 값은 FN. 정답에 없는데 모델이 낸 값은 FP. `n/a` 는 0/0 입니다.
|
|
105
|
+
- **오류 범주.** `wrong_value`, `type_error`, `missing`, `hallucinated`, `parse_failure`. 몇 개 틀렸는지뿐 아니라 어떤 실수인지 알려 줍니다.
|
|
106
|
+
- **형별 비교.** `number`, `date`, `text`, `id`, `enum`, `bool`. `"1,250.00"`, `"$1,250"`, `1250` 은 같은 숫자입니다. id 는 항상 정확히 일치해야 합니다(`INV-215` 와 `INV-0215` 는 다름). 유사 문자열 비교는 설정한 text 필드에만 적용됩니다.
|
|
107
|
+
- **목록 항목.** 위치가 아니라 내용으로 짝을 짓습니다(헝가리안 알고리즘, 순수 Python). 순서가 바뀌어도 정답으로 처리하고, 짝이 없는 항목은 누락 1 + 환각 1 입니다.
|
|
108
|
+
|
|
109
|
+
필드 규칙(`fields.toml` 또는 JSON). 적지 않은 필드는 정답 값에서 형을 추론합니다.
|
|
110
|
+
|
|
111
|
+
```toml
|
|
112
|
+
date_formats = ["%Y-%m-%d", "%m/%d/%Y"] # 먼저 맞는 형식을 씀
|
|
113
|
+
|
|
114
|
+
[fields."total"]
|
|
115
|
+
type = "number"
|
|
116
|
+
tol = 0.01
|
|
117
|
+
|
|
118
|
+
[fields."line_items[].desc"]
|
|
119
|
+
type = "text"
|
|
120
|
+
fuzzy = 0.85 # 이 유사도 이상이면 같은 값으로 봄
|
|
121
|
+
|
|
122
|
+
[fields."notes"]
|
|
123
|
+
ignore = true # 채점하지 않고 '건너뜀' 으로 표시(통과로 세지 않음)
|
|
124
|
+
```
|
|
125
|
+
|
|
126
|
+
## API
|
|
127
|
+
|
|
128
|
+
```python
|
|
129
|
+
from extractscore import evaluate_files, Config
|
|
130
|
+
```
|
|
131
|
+
|
|
132
|
+
| 이름 | 하는 일 | 주요 인자 | 반환 |
|
|
133
|
+
|---|---|---|---|
|
|
134
|
+
| `evaluate(gold, pred, config=None, *, id_key="id")` | 메모리에 있는 데이터셋 전체를 채점 | 행 목록 또는 `{id: dict}` | `Report` |
|
|
135
|
+
| `evaluate_files(gold_path, pred_path, config=None, *, id_key="id")` | 같은 일을 JSONL 두 파일에서 | 경로 | `Report` |
|
|
136
|
+
| `compare(gold, pred, config=None)` | 문서 하나를 채점 | dict 두 개 | `DocResult` |
|
|
137
|
+
| `diff(report_a, report_b, *, tolerance=0.0)` | 같은 정답으로 낸 두 보고서 비교 | 보고서, 허용할 F1 하락 | `Diff` (`.regressions`, `.improvements`, `.flips`) |
|
|
138
|
+
| `check_gates(report, *, min_f1=None, field_min=None)` | CI 기준(전체·필드별) | `min_f1`, `{경로: 최소값}` | `list[GateFailure]` (비어 있으면 통과) |
|
|
139
|
+
| `Config.from_file(path)` / `Config.from_dict(data)` / `Config(...)` | 필드 규칙 | `fields`, `match_threshold`, `date_formats`, `empty_as_null` | `Config` |
|
|
140
|
+
| `FieldRule(type, tol, fuzzy, casefold, ignore)` | 필드 하나의 규칙 | | `FieldRule` |
|
|
141
|
+
| `load_jsonl(path, *, strict, id_key="id")` | JSONL 읽기. `strict=False` 면 깨진 줄이 `ParseFailure` 가 됨 | 경로 | id 별 행 `dict` |
|
|
142
|
+
|
|
143
|
+
`Report` 는 `.fields`(경로별 `FieldStats`: `.precision`, `.recall`, `.f1`, `.counts`), `.micro`, `.macro_f1`, `.parse_failures`, `.skipped`, `.top_docs(n)`, `.to_dict()`, `.to_markdown(lang)` 를 가집니다. counts 는 `.tp`, `.fp`, `.fn`, `.errors`(범주별 개수)를 노출하고, 0/0 인 정밀도·재현율은 `None` 입니다.
|
|
144
|
+
|
|
145
|
+
예외: `InputError`(정답 데이터나 파일을 읽을 수 없음), `ConfigError`(필드 규칙 오류). 둘 다 `ExtractScoreError` 의 하위 클래스입니다. **예측** 쪽 문제는 예외가 아니라 점수로 처리합니다.
|
|
146
|
+
|
|
147
|
+
## 사용 예
|
|
148
|
+
|
|
149
|
+
아래 두 파일은 [`examples/`](examples/) 에 있고 그대로 실행해 확인했습니다.
|
|
150
|
+
|
|
151
|
+
**한 실행 채점** (`examples/quickstart.py`):
|
|
152
|
+
|
|
153
|
+
```python
|
|
154
|
+
from pathlib import Path
|
|
155
|
+
|
|
156
|
+
import extractscore
|
|
157
|
+
from extractscore import Config, evaluate_files
|
|
158
|
+
|
|
159
|
+
sample = Path(extractscore.__file__).parent / "sample"
|
|
160
|
+
config = Config.from_file(sample / "fields.toml")
|
|
161
|
+
report = evaluate_files(sample / "gold.jsonl", sample / "pred_a.jsonl", config)
|
|
162
|
+
|
|
163
|
+
total = report.fields["total"]
|
|
164
|
+
print(f"total: P={total.precision:.3f} R={total.recall:.3f} F1={total.f1:.3f}")
|
|
165
|
+
print("type_error:", total.counts.errors["type_error"])
|
|
166
|
+
print("micro F1:", round(report.micro.f1, 3))
|
|
167
|
+
```
|
|
168
|
+
|
|
169
|
+
```text
|
|
170
|
+
total: P=0.833 R=0.833 F1=0.833
|
|
171
|
+
type_error: 1
|
|
172
|
+
micro F1: 0.916
|
|
173
|
+
```
|
|
174
|
+
|
|
175
|
+
**두 실행 비교와 게이트 확인** (`examples/compare_runs.py`):
|
|
176
|
+
|
|
177
|
+
```python
|
|
178
|
+
from pathlib import Path
|
|
179
|
+
|
|
180
|
+
import extractscore
|
|
181
|
+
from extractscore import Config, check_gates, diff, evaluate_files
|
|
182
|
+
|
|
183
|
+
sample = Path(extractscore.__file__).parent / "sample"
|
|
184
|
+
config = Config.from_file(sample / "fields.toml")
|
|
185
|
+
gold = sample / "gold.jsonl"
|
|
186
|
+
a = evaluate_files(gold, sample / "pred_a.jsonl", config)
|
|
187
|
+
b = evaluate_files(gold, sample / "pred_b.jsonl", config)
|
|
188
|
+
|
|
189
|
+
d = diff(a, b)
|
|
190
|
+
print("regressed:", ", ".join(d.regressions))
|
|
191
|
+
print("improved:", ", ".join(d.improvements))
|
|
192
|
+
for failure in check_gates(b, min_f1=0.9, field_min={"total": 0.99}):
|
|
193
|
+
print(f"FAIL {failure.path}: F1 {failure.f1:.3f} < {failure.minimum:.2f}")
|
|
194
|
+
```
|
|
195
|
+
|
|
196
|
+
```text
|
|
197
|
+
regressed: date, invoice_no, line_items[].desc, line_items[].price, payment_method, receipt_no, vendor.name
|
|
198
|
+
improved: line_items[].qty, total, vendor.tax_id
|
|
199
|
+
FAIL date: F1 0.727 < 0.90
|
|
200
|
+
FAIL discount: F1 0.000 < 0.90
|
|
201
|
+
FAIL invoice_no: F1 0.333 < 0.90
|
|
202
|
+
FAIL payment_method: F1 0.800 < 0.90
|
|
203
|
+
FAIL receipt_no: F1 0.800 < 0.90
|
|
204
|
+
FAIL total: F1 0.909 < 0.99
|
|
205
|
+
```
|
|
206
|
+
|
|
207
|
+
**다른 출력 형식.** `--format json`(영어 키, 스크립트용)과 `--format md`(CI 요약용 Markdown 표). 둘 다 `--out FILE` 과 함께 쓸 수 있습니다.
|
|
208
|
+
|
|
209
|
+
**언어.** 출력은 영어 또는 한국어입니다: `--lang en|ko`, 없으면 `EXTRACTSCORE_LANG`, 없으면 `LC_ALL`/`LC_MESSAGES`/`LANG`. `ko` 로 시작하지 않으면 영어입니다. JSON 키는 바뀌지 않습니다.
|
|
210
|
+
|
|
211
|
+
## 언제 쓰나
|
|
212
|
+
|
|
213
|
+
- 이럴 때: 문서에서 LLM 으로 JSON 을 뽑고, 필드 단위 정밀도·재현율과 같은 정답 세트로의 전후 비교, CI 게이트가 필요할 때. 채점은 결정적이며 모델을 호출하지 않습니다.
|
|
214
|
+
- 범위 밖: 추출 자체를 실행하거나 모델을 호출하지 않고, 자유 서술의 품질도 판단하지 않습니다. 준비한 정답 파일과 JSON 을 비교할 뿐입니다.
|
|
215
|
+
- 다른 도구가 더 맞는 경우: 범용 LLM 평가 파이프라인([promptfoo](https://github.com/promptfoo/promptfoo), [DeepEval](https://deepeval.com/docs/metrics-json-correctness), [Pydantic Evals](https://pydantic.dev/docs/ai/evals/evaluators/built-in/)), 문서 질의응답 유사도 점수([anls_star](https://pypi.org/project/anls-star/)), 구조화 추출 벤치마크([ExtractBench](https://github.com/ContextualAI/extract-bench)). 이 프로젝트는 범위가 좁아서, 형이 있는 JSON 필드를 목록 짝짓기와 함께 채점하고 두 실행을 비교하는 일 하나만 합니다. 다른 도구의 기능은 바뀌므로 이 문서 대신 각 공식 문서를 확인하세요.
|
|
216
|
+
|
|
217
|
+
## 한계
|
|
218
|
+
|
|
219
|
+
숫자를 믿기 전에 읽어 두세요.
|
|
220
|
+
|
|
221
|
+
- **슬래시 날짜는 월이 먼저입니다.** 기본값에서 `11/03/2026` 은 2026-11-03 으로 읽습니다. 문서가 일을 먼저 쓴다면 `fields.toml` 에서 그 형식을 앞에 두세요: `date_formats = ["%d/%m/%Y", "%Y-%m-%d"]`. 먼저 맞는 형식이 쓰이므로 모호한 날짜는 적은 순서를 따릅니다.
|
|
222
|
+
- **유럽식 소수점 쉼표는 0.1.0 에서 인식하지 못합니다.** `"1.250,00"` 은 1250 으로 읽지 않아서, 맞은 값이 `wrong_value` 로 세어집니다. 채점 전에 값을 정리하세요.
|
|
223
|
+
- **`id` 를 건질 수 없는 깨진 예측 줄은 버려집니다.** 줄이 잘렸어도 `id` 를 찾을 수 있으면 그 문서는 `parse_failure` 로 채점됩니다. 찾을 수 없으면 그 문서는 예측이 아예 없는 것으로 채점합니다.
|
|
224
|
+
- **큰 목록은 느립니다.** 목록 항목 짝짓기는 순수 Python 헝가리안 알고리즘(세제곱 시간)입니다. 한 목록에서 짝 없는 항목이 500개를 넘으면 경고가 나오고, 600개짜리 목록은 시험 환경에서 실행마다 약 2~9초 걸렸습니다.
|
|
225
|
+
|
|
226
|
+
## 버전·호환성
|
|
227
|
+
|
|
228
|
+
- [유의적 버전(SemVer)](https://semver.org/lang/ko/)을 따릅니다. 0.x 동안은 마이너 버전에서 API 가 바뀔 수 있고, 바뀌면 [CHANGELOG.md](CHANGELOG.md) 에 적습니다.
|
|
229
|
+
|
|
230
|
+
## 개발·기여
|
|
231
|
+
|
|
232
|
+
```bash
|
|
233
|
+
git clone https://github.com/LeeGyeongPil/extractscore && cd extractscore
|
|
234
|
+
uv run pytest
|
|
235
|
+
```
|
|
236
|
+
|
|
237
|
+
## 라이선스
|
|
238
|
+
|
|
239
|
+
MIT.
|